# App Toolkit
Source: https://docs.dify.ai/en/cloud/use-dify/build/additional-features
Optional features that make your Dify apps more useful
Dify apps come with optional features you can enable to improve the end-user experience. Open the **Features** panel of the builder to see what's available for your app type.
## Conversation Opener
Set an opening message that greets users at the start of each conversation, with optional suggested questions to guide them toward what the app does well.
You can insert variables into the opening message and suggested questions to personalize the experience.
* In the opening message, type `{` or `/` to insert variables from the picker.
* In suggested questions, type variable names manually in `{{variable_name}}` format.
## Follow-up
When enabled, follow-up questions are generated after each response to help users continue the conversation.
Click **Settings** to pick the model that generates the questions, or write a custom prompt (up to 1,000 characters) to adjust the number, wording, or length of the questions.
## Text to Speech
Convert AI responses to audio. You can configure the language and voice to match your app's audience, and enable **Auto Play** to stream audio automatically as the AI responds.
**Text to Speech** uses your workspace's text-to-speech model (set in **Integrations** > **Model Provider** > **Default Models**).
The feature only appears in the **Features** panel when a default TTS model is configured.
## Speech to Text
Enable voice input for the chat interface. When enabled, your end users can dictate messages instead of typing by clicking the microphone button.
**Speech to Text** uses your workspace's speech-to-text model (set in **Integrations** > **Model Provider** > **Default Models**).
The feature only appears in the **Features** panel when a default STT model is configured.
## File Upload
Allow end users to send files at any point during a conversation. You can configure which file types to accept, the upload method, and the maximum number of files per message.
Per-file size limits:
* Images: 10 MB
* Documents: 15 MB
* Audio: 50 MB
* Video: 100 MB
## Citations and Attributions
Show the source documents behind AI responses. When enabled, responses that draw from a connected knowledge base display numbered citations linking back to the original documents and chunks.
[A new kind of Agent](/en/cloud/use-dify/build/new-agent/overview) is in beta: it works in a sandbox of its own, and you build it once to use as a chat app or inside workflows.
Agents are chat-style apps where the model can reason through a task, decide what to do next, and use tools when needed to complete the user's request.
Use it when you want the model to autonomously decide how to approach a task using available tools, without designing a multi-step workflow. For example, building a data analysis assistant that can fetch live data, generate charts, and summarize findings on its own.
Agents keep up to 500 messages or 2,000 tokens of history per conversation. If either limit is exceeded, the oldest messages will be removed to make room for new ones.
Agents support optional features like conversation openers, follow-up suggestions, and more. See [App Toolkit](/en/cloud/use-dify/build/additional-features) for details.
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow. For an agent, the prompt also guides how the model reasons through tasks and decides when to use tools, so be specific about the workflow you expect.
Here are some tips for writing effective prompts:
* **Define the persona**: Describe who the model should act as and the expertise it should draw on.
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
* **Guide tool usage**: Mention specific tools by name and describe when they should be used.
* **Outline the workflow**: Break down complex tasks into logical steps the model should follow.
#### Create Dynamic Prompts with Variables
To adapt the agent to different users or contexts without rewriting the prompt each time, add variables to collect the necessary information upfront.
Variables are placeholders in the prompt—each one appears as an input field that users fill in before the conversation starts, and their values are injected into the prompt at runtime. Users can also update variable values mid-conversation, and the prompt will adjust accordingly.
For example, a data analysis agent might use a domain variable so users can specify which area to focus on:
```text wrap theme={null}
You are a data analyst specializing in {{domain}}. Help users explore and understand their data.
When asked a question, use available data tools to fetch the relevant information. If the result suits a visual format, generate a chart. Explain your findings in plain language.
Keep responses concise. If a question is ambiguous, ask for clarification before fetching data.
```
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
Choose the variable type that matches the input you expect:
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
Displays a dropdown menu with predefined options.
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/cloud/use-dify/workspace/api-extension/api-extension) for details.
**Label Name** is what end users see for each input field.
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Extend the Agent with Dify Tools
Add [Dify tools](/en/cloud/use-dify/workspace/tools) to enable the model to interact with external services and APIs for tasks beyond text generation, such as fetching live data, searching the web, or querying databases.
The model decides when and which tools to use based on each query. To guide this more precisely, mention specific tool names in your prompt and describe when they should be used.
To change the default credential, go to **Integrations** > **Tools** > **Tool Plugin**.
#### Maximum Iterations
**Maximum Iterations** in **Agent Settings** limits how many times the model can repeat its reasoning-and-action cycle (think, call a tool, process the result) for a single request.
Increase this value for complex, multi-step tasks that require multiple tool calls. Higher values increase latency and token costs.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base.
The model evaluates each user query against your knowledge base descriptions and decides whether retrieval is needed—you don't need to mention knowledge bases in your prompt.
**The more detailed your knowledge base description, the better the model can determine relevance**, leading to more accurate and targeted retrieval.
An Agent app has no app-level retrieval settings. Each knowledge base is queried independently using its own settings you've configured. When you add several, the agent picks which to query and does not rerank results across them.
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/cloud/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
You can quickly identify a model's supported modalities by its tags.
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per message.
## Debug & Preview
In the preview panel on the right, test your agent in real time. Select a model, type a message, and send it to see how the agent responds.
You can adjust a model's parameters to control how it generates responses. Available parameters and presets vary by model.
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
We recommend selecting models that are strong at **reasoning** and **natively support tool calling**.
An agent needs to judge *when* to use a tool, *which tool* fits the task, and *how* to interpret the result—this depends on the model's reasoning ability. Models with built-in tool-call support also execute these decisions more reliably.
You can verify your model's tool-call support in **Agent Settings**, where the system automatically displays the agent mode:
* **Function Calling** for models with native support, meaning they can call tools directly.
* **ReAct** for others, so Dify guides them to use tools through a prompting strategy.
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/cloud/use-dify/publish/README) for the full list of publishing options.
# Chatbot
Source: https://docs.dify.ai/en/cloud/use-dify/build/chatbot
The simplest way to build a conversational app with a model and a prompt
Chatbots are conversational apps where users interact with the model through a chat interface.
Use it for tasks that benefit from back-and-forth interaction but don't require tool calls or a multi-step workflow—for example, building an internal Q\&A assistant grounded in your team's knowledge base.
Chatbots keep up to 500 messages or 2,000 tokens of history per conversation. If either limit is exceeded, the oldest messages will be removed to make room for new ones.
Chatbots also support optional features like conversation openers, follow-up suggestions, and more. See [App Toolkit](/en/cloud/use-dify/build/additional-features) for details.
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow. It shapes how the model behaves throughout the conversation, so think of it as defining a consistent persona rather than describing a one-off task.
Here are some tips for writing effective prompts:
* **Define the persona**: Describe who the model should act as and the tone it should use.
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
#### Create Dynamic Prompts with Variables
To adapt your chatbot to different users or contexts without rewriting the prompt each time, add variables to collect the necessary information upfront.
Variables are placeholders in the prompt—each one appears as an input field that users fill in before the conversation starts, and their values are injected into the prompt at runtime. Users can also update variable values mid-conversation, and the prompt will adjust accordingly.
For example, an onboarding assistant might use `role` and `language` to tailor its responses:
```text wrap theme={null}
You are an onboarding assistant for new {{role}} hires. Answer questions about company processes and policies. Keep answers friendly and concise, and respond in {{language}}.
```
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
Choose the variable type that matches the input you expect:
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
Displays a dropdown menu with predefined options.
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/cloud/use-dify/workspace/api-extension/api-extension) for details.
**Label Name** is what end users see for each input field.
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base.
Each time a user sends a message, it is used as the search query to retrieve relevant content from the knowledge base, which is then injected into the prompt as context for the model.
#### Configure App-Level Retrieval Settings
To fine-tune how retrieval results are processed, click **Retrieval Setting**.
There are two layers of retrieval settings—the knowledge base level and the app level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the app settings further rerank the results or narrow down the pool.
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/cloud/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
You can quickly identify a model's supported modalities by its tags.
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per message.
## Debug & Preview
In the preview panel on the right, test your chatbot in real time. Select a model that best fits your task, type a message, and send it to see how the model responds.
After selecting a model, you can adjust its parameters to control how it generates responses. Available parameters and presets vary by model.
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/cloud/use-dify/publish/README) for the full list of publishing options.
# Go to Anything
Source: https://docs.dify.ai/en/cloud/use-dify/build/goto-anything
Search and jump to apps, agents, knowledge bases, integrations, and workflow nodes from anywhere with a keyboard shortcut
The **Go to Anything** overlay is a search box for the whole console: type once to find apps, agents, knowledge bases, Marketplace integrations, and nodes on the canvas you're editing, or run quick commands.
### Open the Overlay
Press `⌘ + K` on macOS or `Ctrl + K` on Windows/Linux, or click the search button at the top of the sidebar.
If the shortcut doesn't respond, another app or browser extension may be using it. The sidebar button always works.
### Search with @
Type a keyword to search everything at once; results are grouped by category. Prefix a scope to narrow the search:
* `@app` – search your applications
* `@knowledge` or `@kb` – search knowledge bases
* `@plugin` – search integrations on the Marketplace
* `@agent` – search your agents
* `@node` – search nodes on the open canvas (available for workflows and knowledge pipelines)
Navigate results with the arrow keys and press `Enter` to open the selected item.
### Run Commands with /
Type `/` to see every command, or keep typing to filter:
| Command | What it does |
| :--------------------- | :--------------------------------------------------------------------------------------------------------------------------- |
| `/create` / `/new` | describe an app and Dify builds it as a Workflow or Chatflow; pick the type yourself or choose **Auto** to let the AI decide |
| `/refine` / `/improve` | describe a change and Dify applies it to the Workflow or Chatflow you're editing (only when one is open) |
| `/go` | jump to a main section of the console |
| `/docs` | open the help documentation |
| `/discord` | open the Discord community |
| `/models` | open the system model settings |
| `/account` | go to your account page |
| `/theme` | switch the interface theme |
| `/language` / `/lang` | change the interface language |
# Build an Agent
Source: https://docs.dify.ai/en/cloud/use-dify/build/new-agent/build
Create an agent and shape what it can do, by hand or by describing what you want
The new Agent is in beta.
## Create an Agent
From **Agents**, click **Create** > **Create from Blank** and give the agent a name; optionally add a role such as *Research Assistant* and a description. Then you shape everything else in **Configure**.
To create an agent from a shared DSL file, choose **Import DSL file**. Skills and files aren't included, so add them after importing.
Creating and managing agents requires the Editor role or above.
## Configure Its Capabilities
Set up each capability by hand, or describe what you want and build it by chatting in [Build mode](#build-by-chatting).
Everything you set up in **Configure** is saved as the agent's capabilities and used in every task later. Separately, the agent works inside its own *sandbox* with 20 GB of storage, where it runs commands and handles files as it goes.
The agent's capabilities can only be changed here: even if an end user asks a published agent to change its own prompt, skills, or tools, it won't.
### Model
Pick the chat model the agent runs on. Favor models that are strong at reasoning and natively support tool calling, since the agent has to judge when to act, which tool fits, and how to read the result.
Agent performance rises and falls with the model, so pick a recent one.
Older models often can't make full use of the sandbox: a common symptom is an agent that never runs commands or installs tools, even when the task needs it.
### Prompt
In the prompt, set the agent's role and how it should approach its work. Be specific about how it should reason, when to lean on its tools, and what to avoid.
A few things worth covering:
* **Persona and goal**: who the agent acts as and what it's trying to achieve.
* **Approach**: the steps or order you expect for a typical task.
* **Tool and file use**: when to reach for each, named explicitly.
* **Output**: the format, length, or tone you want back.
You can point the agent at a specific skill, file, or tool, or leave the choice to the agent:
* **Reference it in the prompt** with `/` to send the agent straight to it, right where you want it used. Best when a step depends on a specific one.
* **Just add it to its section** and let the agent decide on its own when to use it. Best when you'd rather trust the agent's judgment than script every move.
### Skills
A skill is a procedure the agent follows for one specific task. Unlike the prompt, which sets the agent's overall role, a skill covers just that task.
For example, a support agent's prompt might set its role as a customer helper that handles any issue, while its `refund-requests` skill covers only refunds: look up the order, refund only within 30 days, and end with a help-center link.
Click **Add** to upload a skill package: a `.zip` or `.skill` file with a `SKILL.md` inside, up to 50 MB. See [Agent Skills](https://agentskills.io/home) for the package format.
You can also have the agent create skills for you in [Build mode](#build-by-chatting).
To make a Dify tool or file part of the agent's own capabilities, add it to the agent directly rather than inside a skill package.
### Files
Files are reference documents the agent can read while it works, like specs, templates, or guidelines. Unlike a skill, a file is just material to read, not a procedure to run.
Size limits depend on file type:
| File type | Limit |
| :-------- | :----- |
| Documents | 15 MB |
| Images | 10 MB |
| Video | 100 MB |
| Audio | 50 MB |
You can also have the agent create files and save them here in [Build mode](#build-by-chatting). Files the agent creates and saves are capped at 50 MB each.
### Tools
Give the agent [Dify tools](/en/cloud/use-dify/workspace/tools) so it can act beyond the chat: plugins, custom APIs, workflows, and MCP servers from your workspace. Some tools need authentication before use.
Beyond the Dify tools you add here, the agent can also install and run command-line tools on its own inside the sandbox when it needs one. Those tools don't appear in the Tools list.
Tools the agent installs in [Build mode](#build-by-chatting) can stay available after publishing, while anything installed during a published run is temporary.
### Environment Variables
Under **Advanced Settings**, you can add **environment variables**: key-value pairs the agent can read in its sandbox while it works.
Say your agent's skills all work with the same order system: one checks stock, one files orders, one pulls reports. Store the system's address here as `ORDER_API_URL`, and every script reads it by name. To switch from the test system to the production one, update this one value, and all of them follow.
Import a `.env` file to add several at once. You can also have the agent set them up in [Build mode](#build-by-chatting).
## Build by Chatting
Instead of setting everything up by hand, you can build the agent by describing what it should do, and as you chat it sets up *skills*, *files*, and *environment variables* itself.
For example, your first message might be:
```text wrap theme={null}
Build an agent that turns raw meeting notes into structured minutes: attendees, decisions, and action items.
```
You're talking to the live agent: test it as you build, watch how it behaves, and refine it in the same build chat.
As the agent works, it edits the configuration in the panel directly, and you can see all changes listed in **Build draft**. Click **Apply** to keep them, or **Discard** to drop. Either one exits Build mode and clears the conversation.
**Discard** drops everything from this build chat: any changes to the configuration and persistent files in the [**File system**](#file-system).
While you're in Build mode, the configuration panel is read-only—just tell the agent what you want to change.
### File System
In Build mode, the agent handles real files in its sandbox: artifacts it generates, programs it installs on its own, and everything else it's working with. During a build chat, click **File system** in the top-right corner to browse them.
Since a build chat is where you shape the agent itself, whatever it adds (a template it drafted, a tool it installed) is **Persistent** by default, kept for every future conversation and workflow run. In effect, these files are part of the agent's setup, like its prompt and skills.
For one-off work, like a test file or a converter it only needs once, tell the agent in the chat, e.g. "keep this file temporary": it goes under **Temporary** and is cleared when this build chat ends.
In published runs, whatever the agent adds is always temporary, so nothing that happens in a run changes the agent itself.
### The Build Note
In build chats, the agent records what it set up in a *build note*, a `build_note.md` that appears in **Files** the first time you **Apply**.
The note is saved with the agent's setup, and it reads the note back at the start of every new conversation, combining it with your **Prompt** to form its instructions.
After you apply, open the build note and read what the agent captured:
* If it covers what you want, you're set.
* To change what it says, have the agent revise it in Build mode.
The agent maintains only the auto-generated build note: a downloaded copy you re-upload is just an ordinary file, and the next build chat creates a fresh note alongside it.
* If anything's missing, add it to the **Prompt**.
* To start over with a clean record, delete the note in **Files**.
Across build chats, the note also serves as the agent's *memory*. If you shaped the meeting-minutes agent in one chat, a later chat to add action-item owners starts from the format and decisions you already settled, not from scratch.
## Preview
Switch the right panel from **Build** to **Preview** to try the agent exactly as end users will experience it once published: clean replies and your Chat Features active.
Chatting in Preview mode never changes the agent's configuration, so use it as the final check before you publish.
## Publish
Your edits autosave as a draft. When the agent is ready, publish it to make that version live. Open the version history anytime to revisit or restore an earlier version.
Restoring a version also restores the persistent files in the agent's sandbox to that version.
To polish the chat experience, you can add extras like a welcome message, suggested questions, and voice in **Chat Features**. See [App Toolkit](/en/cloud/use-dify/build/additional-features) for details.
From the **Access Point** tab, host it as a web app at a shareable link, embed it in your site, or call it from your code through the [service API](/en/api-reference/guides/agent).
You can also invite the agent into a workflow's [Agent node](/en/cloud/use-dify/nodes/agent#new-agent) to handle a step.
To share the agent across workspaces, export it as a DSL file. Skills and files aren't included, so share them alongside.
### Run Limits
* **Time**
A single agent run is stopped after 1 hour, whichever access point it starts from (web app, service API, or a workflow), and the unfinished reply is discarded.
If a run gets cut off, try again or break the task into smaller steps.
* **Model requests**
Every call the agent makes to its model counts toward a cap of 500 per run, so heavy reasoning and frequent tool use spend it faster.
Try breaking the task into smaller steps to keep each run within the cap.
* **Reply files**
Each file the agent sends back in a reply can be up to 50 MB, and larger files aren't delivered.
## Troubleshooting
Models served through OpenAI-compatible endpoints (vLLM and similar) often lack full native tool-calling support, which the agent depends on in build chats as well as published runs.
Pick a model that supports tool calling natively. If a compatible model still errors, check **Token parameter name** in the model's settings on the provider: some newer models require `max_completion_tokens`, and auto-detection can guess wrong.
Some OpenAI models reject tool calls when reasoning is enabled over the Chat Completions protocol. For those, set the provider credential's **API Protocol** to Responses API.
Image upload can be turned on in **Chat Features** regardless of whether the agent's model supports vision. With a non-vision model, the agent may error on an image or reply as if none was sent.
Switch to a model that supports vision: look for the Vision tag when picking the model.
The agent's sandbox runs in the cloud, so hosts on your private network aren't reachable. Public URLs work; for internal material, add it to the agent's [Files](#files) instead.
# Agent
Source: https://docs.dify.ai/en/cloud/use-dify/build/new-agent/overview
Build an agent once, then put it to work as a standalone app or inside a workflow
The new Agent is in beta.
An *Agent* is an AI worker you set up once and then put to work. It's a different kind of agent than the [Legacy Agent app](/en/cloud/use-dify/build/agent):
* It works in a **sandbox of its own**: it runs commands, installs programs, and reads and writes files, so it takes on open-ended work rather than just calling the tools you configured.
* You [build](/en/cloud/use-dify/build/new-agent/build) it **once** and use it **two ways**: on its own as a chat app, or as [a step](/en/cloud/use-dify/nodes/agent#new-agent) inside a workflow.
Create, configure, and manage your agents on the **Agents** page. Open one anytime to refine it or revisit an earlier version.
## Capability and Task
An Agent separates what it *is* from what you ask it to *do*:
* **Its *capability* (think of it as the agent's soul) is who the agent is.**
The role and prompt you write, the model it runs on, and the skills, Dify tools, and files you give it. You shape it once and keep refining it as you learn what the agent needs.
* **Its *task* is what you ask it to do on a given run.**
When the agent works on its own, the task is the message you send it. When it works inside a workflow, the task is the instruction you give the node.
It's the same split as hiring someone: you choose a person for what they can do, then give them a specific task. Strong results need both: the right person for the job and a clear brief.
## Two Ways to Use an Agent
### On Its Own
The agent runs as its own chat app. You give it tasks by chatting, and you can publish it as a web app or call it through the service API.
Each conversation has its own memory: how much the agent keeps in mind depends on the model's context window, and a new conversation starts fresh.
Choose this when a single capable worker can reach the goal on its own: a support assistant that looks things up and answers, or a research agent that gathers sources and summarizes them.
### Inside a Workflow
You invite the agent into an [Agent node](/en/cloud/use-dify/nodes/agent#new-agent) to handle one step of a larger process. There you set only the task you want done. It's like asking a colleague to take care of one thing: you describe the task, and they bring their own skills to it.
Choose this when the work needs structure around it: several steps in a set order, branching on conditions, other kinds of nodes, or a few specialized agents handing off to each other.
However the agent runs, its sessions collect in one place: the **Logs** page, where each row carries its source—the agent's web app or a workflow that uses it.
# Orchestration Logic
Source: https://docs.dify.ai/en/cloud/use-dify/build/orchestrate-node
How to arrange, nest, or reuse nodes when building a Workflow or Chatflow
## Serial and Parallel Execution
A single execution path supports up to 50 nodes.
## Node Reuse
All nodes except User Input can be copied and pasted within the same workflow, across workflows, or across Dify instances, though there might be compatibility issues between Dify versions.
Pasting across workflows or Dify instances requires the Dify page to be served over HTTPS or accessed via a loopback address (such as `http://localhost` or `http://127.0.0.1`).
When you paste a node, its configuration moves with it, but the availability of anything that depends on the surrounding environment is re-evaluated at the destination:
* **Workflow-specific resources**, such as variables
* **Workspace-specific resources**, such as integrations and knowledge bases
## Iteration and Loop
For nodes that should run multiple times (once per item in a list or until a condition is met), place them inside an [Iteration](/en/cloud/use-dify/nodes/iteration) or [Loop](/en/cloud/use-dify/nodes/loop) node.
# Handle Errors
Source: https://docs.dify.ai/en/cloud/use-dify/build/predefined-error-handling-logic
The default behavior. When a node fails, the whole workflow stops. You get the original error message.
Use this when:
* You're testing and want to see what broke
* The workflow can't continue without this step
When a node fails, use a backup value instead. The workflow keeps running.
When a node fails, trigger a separate flow to handle the error.
## Error in Loop/Iteration Nodes
When child nodes fail inside loops and iterations, these control flow nodes have their own error behaviors.
**Loop nodes** always stop immediately when any child node fails. The entire loop terminates and returns the error, preventing any further iterations from running.
**Iteration nodes** let you choose how to handle child node failures through the error handling mode setting:
* `terminated` - Stops processing immediately when any item fails (default)
* `continue-on-error` - Skips the failed item and continues with the next one
* `remove-abnormal-output` - Continues processing but filters out failed items from the final output
When you set an iteration to `continue-on-error`, failed items return `null` in the output array. When you use `remove-abnormal-output`, the output array only contains successful results, making it shorter than the input array.
## Error variables
When using default value or fail branch, you get two special variables:
* `error_type` - What kind of error happened (see [Error Types](/en/cloud/use-dify/debug/error-type))
* `error_message` - The actual error details
Use these to:
* Show users helpful messages
* Send alerts to your team
* Choose different recovery strategies
* Log errors for debugging
**Example**
```
{% if error_type == "rate_limit" %}
Too many requests. Please wait a moment and try again.
{% else %}
Something went wrong. Our team has been notified.
{% endif %}
```
# Hotkeys
Source: https://docs.dify.ai/en/cloud/use-dify/build/shortcut-key
Keyboard shortcuts for building workflows faster in Dify
Speed up your workflow building with keyboard shortcuts.
**[Go to Anything](/en/cloud/use-dify/build/goto-anything)**: Press `Cmd+K` (macOS) or `Ctrl+K` (Windows) anywhere in Dify to find and jump to almost anything.
* Type `@` to search apps, integrations, knowledge bases, or workflow nodes.
* Type `/` to run a command like `/docs`, `/theme`, or `/language`.
## Selection and Editing
With one or more nodes selected on the canvas:
| Windows | macOS | Action |
| :------------- | :------------- | :------------------------------------------------- |
| `Ctrl` + `C` | `Cmd` + `C` | Copy |
| `Ctrl` + `V` | `Cmd` + `V` | Paste |
| `Ctrl` + `D` | `Cmd` + `D` | Duplicate |
| `Delete` | `Delete` | Delete selected nodes or edges |
| `Shift` (hold) | `Shift` (hold) | Highlight the selected node's variable connections |
## Canvas Modes
| Windows | macOS | Action |
| :------ | :---- | :-------------------- |
| `V` | `V` | Pointer mode (select) |
| `H` | `H` | Hand mode (pan) |
| `C` | `C` | Comment mode |
## Zoom and Layout
| Windows | macOS | Action |
| :------------ | :------------ | :------------- |
| `Ctrl` + `1` | `Cmd` + `1` | Zoom to fit |
| `Ctrl` + `=` | `Cmd` + `=` | Zoom in |
| `Ctrl` + `-` | `Cmd` + `-` | Zoom out |
| `Shift` + `1` | `Shift` + `1` | Zoom to 100% |
| `Shift` + `5` | `Shift` + `5` | Zoom to 50% |
| `Ctrl` + `O` | `Cmd` + `O` | Organize nodes |
## History
| Windows | macOS | Action |
| :--------------------- | :-------------------- | :----- |
| `Ctrl` + `Z` | `Cmd` + `Z` | Undo |
| `Ctrl` + `Y` | `Cmd` + `Y` | Redo |
| `Ctrl` + `Shift` + `Z` | `Cmd` + `Shift` + `Z` | Redo |
## Testing
| Windows | macOS | Action |
| :---------- | :------------- | :------- |
| `Alt` + `R` | `Option` + `R` | Test run |
# Snippets
Source: https://docs.dify.ai/en/cloud/use-dify/build/snippet
Reuse and share groups of nodes across workflows
Useful node patterns have a way of showing up in more than one workflow. Without a way to save and reuse them, you end up rebuilding the same logic every time: a particular chain of LLM and tool nodes, a data processing sequence, or a multi-step summarization pipeline.
Save a group of nodes as a reusable unit by turning them into a *snippet*: build the logic once, reuse it across workflows, and share it with your team to save others the effort of building the same thing from scratch.
You can also export snippets as DSL files to share them across workspaces.
## Create a Snippet
There are three ways to create a snippet:
* **From a workflow**
Select the nodes you want to reuse, then right-click and choose **Create Snippet**.
Their configurations are saved into the snippet. Any external variables they reference (outputs from nodes you didn't select, environment variables, and so on) become the snippet's [Input Variables](#edit-a-snippet).
An exception: an LLM node that takes its model from an environment variable keeps that model configuration as a fixed setting, so the snippet uses the same model wherever you add it.
* **From scratch**
In **Studio**, click **Snippets** at the top-right corner, then click **Create Snippet** > **Create from blank** to start with an empty canvas.
* **From a DSL file**
In **Studio**, click **Snippets** at the top-right corner, then click **Create Snippet** > **Import DSL file** to import an existing snippet.
A snippet you create is shared with your workspace. What each member can do with it depends on their workspace role; see [Permissions](#permissions).
## Edit a Snippet
Building a snippet works much like building a standard workflow, with two differences.
First, a few nodes aren't available. Because a snippet plugs into a workflow instead of running on its own, it has no Start node (User Input or Triggers) and no end node (Output for Workflows, Answer for Chatflows). Knowledge Retrieval and Human Input aren't supported yet either.
Second, because a snippet has no Start node to collect input, you define **Input Variables** that specify what data it expects to receive, such as a variable from an upstream node. When a snippet is added to a workflow, these input variables become the connection points.
## Publish a Snippet
As you edit, your changes save automatically as a draft, so you can pick up where you left off next time. When the draft is ready, click **Publish** to make it usable. A workflow always uses the published version, never a draft.
Every publish is kept in the snippet's version history, where you can review or restore an earlier version.
## Add a Snippet to a Workflow
Right-click on the canvas, select **Add Node** > **Snippets**, then choose one to insert. Only published snippets appear here.
The snippet is added to your canvas as a copy. In the inserted nodes, set each input variable to the appropriate variable from your workflow, so they receive the data they expect.
Editing the original snippet later won't change workflows that already use it, and vice versa.
## Permissions
What you can do with a snippet depends on your workspace role:
| Action | Roles |
| :------------------------------------ | :-------------------------------------- |
| View the snippet list | Owner, Admin, Editor |
| Create, edit, and publish snippets | Owner, Admin, Editor |
| Delete snippets | Owner, Admin |
| Add a published snippet to a workflow | Anyone who can edit the target workflow |
Members with the Normal role don't see the snippet list.
# Text Generator
Source: https://docs.dify.ai/en/cloud/use-dify/build/text-generator
Simple single-turn apps for generating text from a prompt and user inputs
Text Generators are simple single-turn apps: you write a prompt, provide inputs, and the model generates a response.
It's a good fit for tasks that don't require multi-turn conversation, tool calls, or a multi-step workflow. Just a clear input, one model call, and a ready-to-use output.
Text Generators support optional features like generating multiple outputs at once, text to speech, and content moderation. See [App Toolkit](/en/cloud/use-dify/build/additional-features) for details.
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow.
Since a Text Generator runs in a single turn with no conversation history, the prompt is the model's only source of context—include everything it needs to produce the right output in one pass.
Here are some tips for writing effective prompts:
* **Define the task clearly**: State what the model should produce (e.g., a translation, a summary, a SQL statement).
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
Because a Text Generator always requires user input to run, a paragraph-type `query` variable is automatically inserted into the prompt when you create a new app. You can rename `query` or change its type.
Variables are placeholders—each one becomes an input field that users fill in before running the app, and their values are substituted into the prompt at runtime. For example:
```text wrap theme={null}
You are a professional editor. Summarize the following text into 3 concise bullet points. Use neutral tone and avoid adding information not present in the original text.
{{query}}
```
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
Choose the variable type that matches the input you expect:
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
Displays a dropdown menu with predefined options.
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/cloud/use-dify/workspace/api-extension/api-extension) for details.
**Label Name** is what end users see for each input field.
#### Create Dynamic Prompts with Variables
To adapt your app to different users or contexts without rewriting the prompt each time, add more variables.
Each variable collects a specific piece of information upfront and injects it into the prompt at runtime.
For example, an SQL generator might use `database_type` to adapt the output dialect while `query` captures the user's natural language request:
```text wrap theme={null}
You are an SQL generator. Translate the following natural language query into a {{database_type}} SQL statement: {{query}}
```
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base and select an existing variable as the **Query Variable**.
When a user runs the app and fills in that field, its value is used as the search query to retrieve relevant content from the knowledge base. The retrieved content is then injected into the prompt as context, so the model can generate a more informed response.
For example, suppose your knowledge base contains style guides for different content types—blog posts, social media captions, product descriptions, and so on.
In a content writing app, set `content_type` as the **Query Variable**. When a user selects a content type, the app retrieves the matching style guide and generates copy that follows the corresponding writing standards.
Your prompt might look like this:
```text wrap theme={null}
You are a brand content writer. Write a {{content_type}} based on the following brief: {{brief}}
Follow the style and tone guidelines provided in the context.
```
#### Configure App-Level Retrieval Settings
To fine-tune how retrieval results are processed, click **Retrieval Setting**.
There are two layers of retrieval settings—the knowledge base level and the app level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the app settings further rerank the results or narrow down the pool.
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/cloud/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
You can quickly identify a model's supported modalities by its tags.
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per run.
## Debug & Preview
In the preview panel on the right, test your app in real time. Select a model that best fits your task, fill in the input fields, and click **Run** to see the output.
After selecting a model, you can adjust its parameters to control how it generates responses. Available parameters and presets vary by model.
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/cloud/use-dify/publish/README) for the full list of publishing options.
When running the web app, end users can save individual outputs for future reference.
Only available for Chatflow and Workflow apps right now.
## How it works
**Current Draft**: Your working version. This is where you make changes. Not live for users.
You can't delete the Current Draft or Latest Version.
**Restore a version**: Load an old version back into your draft
This replaces your current draft completely. Make sure you don't have unsaved work.
Restoring a version, exporting a specific version's DSL, and running a specific published version through the [Service API](/en/api-reference/workflow-runs/run-workflow-by-id) are available on paid plans. On the Sandbox plan, apps always run the latest published version.
## Example workflow
Here's how versions work through a typical development cycle:
### 1. Start with a draft
Chatflows support optional features like content moderation, text to speech, and more. See [App Toolkit](/en/cloud/use-dify/build/additional-features) for details.
They also start and end with different nodes:
| | Workflow | Chatflow |
| :---------- | :-------------------------------------------------------------------------------------------------------- | :-------------------------------------------------------- |
| Starts with | [User Input](/en/cloud/use-dify/nodes/user-input) or [Trigger](/en/cloud/use-dify/nodes/trigger/overview) | User Input |
| Ends with | [Output](/en/cloud/use-dify/nodes/output) node (optional) | [Answer](/en/cloud/use-dify/nodes/answer) node (required) |
A Trigger runs a workflow automatically: on a schedule, when a webhook fires, or from an integration event. Chatflows always start from a user message, so they don't have Triggers.
For how to compose either type, see [Orchestration Logic](/en/cloud/use-dify/build/orchestrate-node).
# Error Types
Source: https://docs.dify.ai/en/cloud/use-dify/debug/error-type
Each node type throws specific error classes that help you understand what went wrong and how to fix it.
## Node-specific errors
`CodeNodeError`
Your Python or JavaScript code threw an exception during execution
The data type your code returned doesn't match the output variable type you configured
`DepthLimitError`
Your code created nested data structures deeper than 5 levels
`CodeExecutionError`
The sandbox service couldn't execute your code - usually means the service is down
`VariableNotFoundError`
Your prompt template references a variable that doesn't exist in the workflow context
You passed an array or object to the context field, which only accepts strings
`NoPromptFoundError`
The prompt field is completely empty
`ModelNotExistError`
No model is selected in the LLM node configuration
`LLMModeRequiredError`
The selected model doesn't have valid API credentials configured
`InvalidVariableTypeError`
Your prompt template isn't valid Jinja2 syntax or plain text format
`AuthorizationConfigError`
Missing or invalid authentication configuration for the API endpoint
`InvalidHttpMethodError`
HTTP method must be GET, HEAD, POST, PUT, PATCH, or DELETE
`ResponseSizeError`
API response exceeded the 10MB size limit
`FileFetchError`
Couldn't retrieve a file variable referenced in the request
`InvalidURLError`
The URL format is malformed or unreachable
`ToolParameterError`
Parameters passed to the tool don't match its expected schema
`ToolFileError`
The tool couldn't access required files
`ToolInvokeError`
The external tool API returned an error during execution
`ToolProviderNotFoundError`
The tool provider isn't installed or configured properly
## System-level errors
`InvokeConnectionError`
Network connection failed to the external service
`InvokeServerUnavailableError`
External service returned a 503 status or is temporarily down
`InvokeRateLimitError`
You've hit rate limits on the API or model provider
`QuotaExceededError`
Your usage quota has been exceeded for this service
# Run History
Source: https://docs.dify.ai/en/cloud/use-dify/debug/history-and-logs
Dify records detailed Run History every time your workflow runs. You can see what happened at both the application level and for individual nodes.
For Run History from live users after publishing, see [Logs](/en/cloud/use-dify/monitor/logs).
## Application Run History
Each workflow run creates a complete log entry. Click any entry to see three sections:
Only available for Workflow applications.
### Detail
Shows the original input, final output, and system metadata from the execution.
Answer and End nodes don't support single node testing.
## Step-by-step execution
When you run nodes one at a time, their outputs are cached in the Variable Inspector. You can edit these cached variables to test different scenarios without re-running upstream nodes.
Editing variables here doesn't change the "Last run" record for the node that originally created them.
For example, if an LLM node generates SQL like `SELECT * FROM users`, you can edit it to `SELECT username FROM users` in the inspector and then re-run just the database node to see different results.
Use Dify
Your workspace is where everything happens: build AI applications, ground them in your own data, then publish and monitor them.
Build workflows and chatflows on the visual canvas, plus agents, chatbots, and more.
Import documents and data so your apps can retrieve and cite them.
Ship your app as a web app, embed it in a website, or call it over the API.
Track usage, review logs, and refine answers with annotations.
Connect model providers, tools, data sources, and external services.
Ask the community or report a problem.
# Connect to External Knowledge Base
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/connect-external-knowledge-base
Integrate external knowledge sources with Dify applications through API connections to leverage custom RAG systems or third-party knowledge services
If your team maintains its own RAG system or hosts content in a third-party knowledge service like [AWS Bedrock](https://aws.amazon.com/bedrock/), you can connect these external sources to Dify instead of migrating content into Dify's built-in knowledge base.
This lets your AI applications retrieve information directly from your existing infrastructure while you retain full control over the retrieval logic and content management.
If you're connecting to LlamaCloud, install the [LlamaCloud plugin](https://marketplace.dify.ai/plugin/langgenius/llamacloud) instead of building a custom API. See the [video walkthrough](https://www.youtube.com/watch?v=FaOzKZRS-2E) for a complete setup demo.
If you're building a plugin for another knowledge service, the LlamaCloud plugin's [source code](https://github.com/langgenius/dify-official-plugins/tree/main/extensions/llamacloud) is available for reference.
Dify only has retrieval access to external knowledge bases. It cannot modify or manage your external content. You maintain the knowledge base and its retrieval logic independently.
## Step 1: Build the Retrieval API
Build an API service that implements the [External Knowledge API specification](/en/cloud/use-dify/knowledge/external-knowledge-api). Your service needs a single `POST` endpoint that accepts a search query and returns matching text chunks with similarity scores.
## Step 2: Register an External Knowledge API
An External Knowledge API stores your endpoint URL and authentication credentials. Multiple knowledge bases can share one API connection.
1. Go to **Knowledge**, click **External Knowledge API** in the upper-right corner, then click **Add an External Knowledge API**.
2. Fill in the following fields:
* **Name**: A label to distinguish this API connection from others.
* **API Endpoint**: The base URL of your external knowledge service. Dify appends `/retrieval` automatically when sending requests.
* **API Key**: The authentication credential for your service. Dify sends this as a Bearer token in the `Authorization` header.
Dify validates the connection by sending a test request to your endpoint when you save.
## Step 3: Create an External Knowledge Base
With the API registered, connect an external knowledge source to Dify. This creates a knowledge base in Dify that is linked to your external system.
1. Go to **Knowledge** and click **Connect to an External Knowledge Base**.
The **External Knowledge API** and **External Knowledge ID** cannot be changed after creation. To use a different API or knowledge source, create a new external knowledge base.
* **Retrieval Settings**:
* **Top K**: Maximum number of chunks to retrieve per query. Higher values return more results but may include less relevant content.
* **Score Threshold**: Minimum similarity score for returned chunks. Enable this to filter out low-relevance results. Use higher value for stricter relevance or lower value to include broader matches.
When disabled, all results up to the Top K limit are returned regardless of score.
Once created, the external knowledge base is available for use in your applications just like any built-in knowledge base. See [Integrate Knowledge Within Application](/en/cloud/use-dify/knowledge/integrate-knowledge-within-application) for details.
## Troubleshoot
### API Response Format Issues
If retrieval fails or returns unexpected results, verify your API response against the [External Knowledge API specification](/en/cloud/use-dify/knowledge/external-knowledge-api#response).
Common issues:
* The `metadata` field in each record must be an object (`{}`), not `null`. A `null` value causes errors in the retrieval pipeline.
* The `content` and `score` fields must be present in every record.
# Configure the Chunk Settings
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text
## What is Chunking?
Documents imported into knowledge bases are split into smaller segments called **chunks**. Think of chunking like organizing a large book into chapters and paragraphs: you can't quickly find specific information in one massive block of text, but well-organized sections make retrieval efficient.
When users ask questions, the system searches through these chunks for relevant information and provides it to the LLM as context. Without chunking, processing entire documents for every query would be slow and inefficient.
**Key Chunk Parameters**
* **Delimiter**: The character or sequence where text is split. For example, `\n\n` splits at paragraph breaks, `\n` at line breaks.
Delimiters are removed during chunking. For example, using `A` as the delimiter splits `CBACD` into `CB` and `CD`.
To avoid information loss, use non-content characters that don't naturally appear in your documents.
* **Maximum chunk length**: The maximum size of each chunk in characters. Text exceeding this limit is force-split regardless of delimiter settings.
## Choose a Chunk Mode
The chunk mode cannot be changed once the knowledge base is created. However, chunk settings like the delimiter and maximum chunk length can be adjusted at any time.
### Mode Overview
In General mode, all chunks share the same settings. Matched chunks are returned directly as retrieval results.
**Chunk Settings**
Beyond delimiter and maximum chunk length, you can also configure **Chunk overlap** to specify how many characters overlap between adjacent chunks. This helps preserve semantic connections and prevents important information from being split across chunk boundaries.
For example, with a 50-character overlap, the last 50 characters of one chunk will also appear as the first 50 characters of the next chunk.
In Parent-child mode, text is split into two tiers: smaller **child chunks** and larger **parent chunks**. When a query matches a child chunk, its entire parent chunk is returned as the retrieval result.
This solves a common retrieval dilemma: smaller chunks enable precise query matching but lack context, while larger chunks provide rich context but reduce retrieval accuracy.
Parent-child mode balances both: retrieving with precision and responding with context.
**Parent Chunk Settings**
Parent chunks can be created in **Paragraph** or **Full Doc** mode.
The document is split into multiple parent chunks based on the specified delimiter and maximum chunk length.
Suitable for lengthy documents with well-structured sections where each section provides meaningful context independently.
The entire document serves as a single parent chunk.
Suitable for small, cohesive documents where the full context is essential for understanding any specific detail.
In **Full Doc** mode:
* Only the first 10,000 tokens are processed. Content beyond this limit will be truncated.
* The parent chunk cannot be edited once created. To modify it, you must upload a new document.
**Child Chunk Settings**
Each parent chunk is further split into child chunks using their own delimiter and maximum chunk length settings.
### Quick Comparison
| Dimension | General Mode | Parent-child Mode |
| :------------------------------------------------------------------------------------------------ | :----------------------------------------------------- | :------------------------------------------------------------------------------------------------ |
| Chunking Strategy | Single-tier: all chunks use the same settings | Two-tier: separate settings for parent and child chunks |
| Retrieval Workflow | Matched chunks are directly returned | Child chunks are used for matching queries; parent chunks are returned to provide broader context |
| Compatible [Index Method](/en/cloud/use-dify/knowledge/create-knowledge/setting-indexing-methods) | High Quality, Economical | High Quality only |
| Best For | Simple, self-contained content like glossaries or FAQs | Information-dense documents like technical manuals or research papers where context matters |
## Pre-process Text Before Chunking
Before splitting text into chunks, you can clean up irrelevant content to improve retrieval quality.
* **Replace consecutive spaces, newlines, and tabs**
* Three or more consecutive newlines → two newlines
* Multiple spaces → single space
* Tabs, form feeds, and special Unicode spaces → regular space
* **Remove all URLs and email addresses**
This setting is ignored in **Full Doc** mode.
## Preview Chunks
Click **Preview** to see how your content will be chunked. A limited number of chunks will be displayed for a quick review.
If the results don't perfectly match your expectations, choose the closest configuration; you can manually fine-tune chunks later. See [Manage Knowledge Content](/en/cloud/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents) for details.
For multiple documents, click the file name at the top of the preview panel to switch between them.
# Upload Local Files
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/create-knowledge/import-text-data/readme
Once a knowledge base is created, its data source cannot be changed later.
When creating a ready-to-use knowledge base, you can upload local files as its data source:
1. Click **Knowledge** > **Create** > **Create a ready-to-use knowledge base**.
2. Select **Import from file** as the data source, then upload your files.
Upload limits vary by plan:
| | Sandbox | Professional & Team |
| :--------------- | :------ | :------------------ |
| Files per upload | 1 | 50 |
| Size per file | 15 MB | 50 MB |
***
**For Images in Uploaded Files**
JPG, JPEG, PNG, and GIF images under 2 MB are automatically extracted as attachments to their corresponding chunks. These images can be managed independently and are returned alongside their chunks during retrieval.
URLs of extracted images remain in the chunk text, but you can safely remove these URLs to keep the text clean; this won't affect the extracted images.
If you select a multimodal embedding model (marked with a **Vision** icon) in index settings, the extracted images will also be embedded and indexed for retrieval.
Each chunk supports up to 10 image attachments; images beyond this limit will not be extracted.
The above extraction rule applies to:
* Images embedded in DOCX and XLSX files
Images embedded in other file types (e.g., PDF) can be extracted by using appropriate document extraction plugins in [knowledge pipelines](/en/cloud/use-dify/knowledge/knowledge-pipeline/readme).
* Images referenced via accessible URLs using the following Markdown syntax in any file type:
* ``
* ``
# Sync Data from Notion
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/create-knowledge/import-text-data/sync-from-notion
Dify datasets support importing from Notion and setting up **synchronization** so that data updates in Notion are automatically synced to Dify.
Notion is connected through Dify's pre-configured integration. Authorize your workspace once and you're ready to import; no Notion app setup required.
### Authorization Verification
1. When creating a dataset and selecting the data source, click **Sync from Notion Content -- Bind Now** and follow the prompts to complete the authorization verification.
2. Alternatively, you can go to **Settings -- Data Sources -- Add Data Source**, click on the Notion source **Bind**, and complete the authorization verification.
Images and files cannot be imported, and data from tables will be converted to text.
[Firecrawl](https://www.firecrawl.dev/) and [Jina Reader](https://jina.ai/reader/) are both open-source web parsing tools that can convert web pages into clean Markdown format text that is easy for LLMs to recognize, while providing easy-to-use API services.
The following sections will introduce the usage methods for Firecrawl and Jina Reader respectively.
## Firecrawl
### **1. Configure Firecrawl API credentials**
Click on the avatar in the upper right corner, then go to the **DataSource** page, and click the **Configure** button next to Firecrawl.
Once a knowledge base is created in the High Quality index method, it cannot switch to Economical later.
The High Quality index method uses an embedding model to convert content chunks into vector representations. This process is called embedding.
Think of these vectors as coordinates in a multi-dimensional space—the closer two points are, the more similar their meanings. This allows the system to find relevant information based on semantic similarity, not just exact keyword matches.
These vectors count toward your workspace's knowledge storage. See [Knowledge Data Storage Limit](/en/cloud/use-dify/knowledge/knowledge-storage-limit) for per-plan capacity and what happens at the limit.
To enable cross-modal retrieval—retrieving both text and images based on semantic relevance—select a multimodal embedding model (marked with a **Vision** icon). Images extracted from documents will then be embedded and indexed for retrieval.
Knowledge bases using such embedding models are labeled **Multimodal** on their cards.
The High-Quality index method supports three retrieval strategies: vector search, full-text search, or hybrid search. Learn more in [Configure the Retrieval Settings](#configure-the-retrieval-settings).
Using 10 keywords per chunk for retrieval, no tokens are consumed at the expense of reduced retrieval accuracy. For the retrieved blocks, only the inverted index method is provided to select the most relevant blocks.
If the performance of the economical indexing method does not meet your expectations, you can upgrade to the High-Quality indexing method in the Knowledge settings page.
## Configure the Retrieval Settings
Once the knowledge base receives a user query, it searches existing documents according to preset retrieval methods and extracts highly relevant content chunks. These chunks provide essential context for the LLM, ultimately affecting the accuracy and credibility of its answers.
Common retrieval methods include:
1. Semantic Retrieval based on vector similarity—where text chunks and queries are converted into vectors and matched via similarity scoring.
2. Keyword Matching using an inverted index (a standard search engine technique). Both methods are supported in Dify’s knowledge base.
Both retrieval methods are supported in Dify’s knowledge base. The specific retrieval options available depend on the chosen indexing method.
**High Quality**
In the **High-Quality** Indexing Method, Dify offers three retrieval settings: **Vector Search, Full-Text Search, and Hybrid Search**.
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
> The TopK and Score configurations are only effective during the Rerank phase. Therefore, to apply either of these settings, it is necessary to add and enable a Rerank model.
**Full-Text Search**
**Definition**: Indexing all terms in the document, allowing users to query any terms and return text fragments containing those terms.
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
> The TopK and Score configurations are only effective during the Rerank phase. Therefore, to apply either of these settings, it is necessary to add and enable a Rerank model.
**Hybrid Search**
**Definition**: This process combines full-text search and vector search, performing both simultaneously. It includes a reordering step to select the best-matching results from both search outcomes based on the user’s query.
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
The **"Weight Settings"** and **"Rerank Model"** settings support the following options:
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
**Economical**
In **Economical Indexing** mode, only the inverted index approach is available. An inverted index is a data structure designed for fast keyword retrieval within documents, commonly used in online search engines. Inverted indexing supports only the **TopK** setting.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
### Reference
After specifying the retrieval settings, you can refer to the following documentation to review how keywords match with content chunks in different scenarios.
Learn how to test and cite your knowledge base retrieval
# External Knowledge API
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/external-knowledge-api
API specification that your external knowledge service must implement to integrate with Dify
This page defines the API contract your external knowledge service must implement for Dify to retrieve content from it. Once your API is ready, see [Connect to External Knowledge Base](/en/cloud/use-dify/knowledge/connect-external-knowledge-base) to register it in Dify.
## Authentication
Dify sends the API Key you configured as a Bearer token in every request:
```text theme={null}
Authorization: Bearer {API_KEY}
```
You define the authentication logic on your side. Dify only passes the key—it does not validate it.
## Request
```text theme={null}
POST {your-endpoint}/retrieval
Content-Type: application/json
Authorization: Bearer {API_KEY}
```
Dify appends `/retrieval` to the endpoint URL you configured. If you registered `https://your-service.com`, Dify sends requests to `https://your-service.com/retrieval`.
### Body
| Property | Required | Type | Description |
| :------------------- | :------- | :----- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `knowledge_id` | Yes | string | The identifier of the knowledge source in your external system. This is the value you entered in the **External Knowledge ID** field when connecting. Use it to route queries to the correct knowledge source. |
| `query` | Yes | string | The user's search query. |
| `retrieval_setting` | Yes | object | Retrieval parameters. See [below](#retrieval_setting). |
| `metadata_condition` | No | object | Metadata filtering conditions. See [below](#metadata_condition). |
#### `retrieval_setting`
| Property | Required | Type | Description |
| :---------------- | :------- | :---- | :--------------------------------------------------------------------------------------------- |
| `top_k` | Yes | int | Maximum number of results to return. |
| `score_threshold` | Yes | float | Minimum similarity score (0-1). When score threshold is disabled in Dify, this value is `0.0`. |
#### `metadata_condition`
Dify passes metadata conditions to your API but does not currently provide a UI for users to configure them. This parameter is available for programmatic use only.
| Property | Required | Type | Description |
| :----------------- | :------- | :------------- | :----------------------------- |
| `logical_operator` | No | string | `and` or `or`. Default: `and`. |
| `conditions` | Yes | array\[object] | List of filter conditions. |
Each object in `conditions`:
| Property | Required | Type | Description |
| :-------------------- | :------- | :-------------------------------- | :-------------------------------------------------------- |
| `name` | Yes | string | Metadata field name to filter on. |
| `comparison_operator` | Yes | string | Comparison operator. See supported values below. |
| `value` | No | string, number, or array\[string] | Comparison value. Omit when using `empty` or `not empty`. |
| Operator | Description |
| :------------- | :--------------------------------- |
| `contains` | Contains a value |
| `not contains` | Does not contain a value |
| `start with` | Starts with a value |
| `end with` | Ends with a value |
| `is` | Equals a value |
| `is not` | Does not equal a value |
| `in` | Matches any value in a list |
| `not in` | Does not match any value in a list |
| `empty` | Is empty |
| `not empty` | Is not empty |
| `=` | Equals (numeric) |
| `≠` | Not equal (numeric) |
| `>` | Greater than |
| `<` | Less than |
| `≥` | Greater than or equal to |
| `≤` | Less than or equal to |
| `before` | Before a date |
| `after` | After a date |
### Example Request
```json theme={null}
{
"knowledge_id": "your-knowledge-id",
"query": "What is Dify?",
"retrieval_setting": {
"top_k": 3,
"score_threshold": 0.5
}
}
```
## Response
Return HTTP 200 with a JSON body containing a `records` array. If no results match the query, return an empty array: `{"records": []}`.
### `records`
| Property | Type | Description |
| :--------- | :----- | :----------------------------------------------------------------------------- |
| `content` | string | The retrieved text chunk. Dify uses this as the context passed to the LLM. |
| `score` | float | Similarity score (0–1). Used for score threshold filtering and result ranking. |
| `title` | string | Source document title. |
| `metadata` | object | Arbitrary key-value pairs preserved by Dify. |
Dify does not reject records with missing fields, but omitting `content` or `score` will produce incomplete or unranked results.
If you include `metadata` in a record, it must be an object (`{}`), not `null`. A `null` metadata value causes errors in Dify's retrieval pipeline.
### Example Response
```json theme={null}
{
"records": [
{
"content": "This is the document for external knowledge.",
"score": 0.98,
"title": "knowledge.txt",
"metadata": {
"path": "s3://dify/knowledge.txt",
"description": "dify knowledge document"
}
},
{
"content": "The Innovation Engine for GenAI Applications",
"score": 0.66,
"title": "introduce.txt",
"metadata": {}
}
]
}
```
## Error Handling
Dify checks the HTTP status code of your response. A non-200 status raises an error that surfaces to the user.
You can optionally return structured error information in JSON:
| Property | Type | Description |
| :----------- | :----- | :------------------------------------------ |
| `error_code` | int | An application-level error code you define. |
| `error_msg` | string | A human-readable error description. |
The following are suggested error codes. These are conventions, not enforced by Dify:
| Code | Suggested Usage |
| :--- | :---------------------------------- |
| 1001 | Invalid Authorization header format |
| 1002 | Authorization failed |
| 2001 | Knowledge base not found |
### Example Error Response
```json theme={null}
{
"error_code": 1002,
"error_msg": "Authorization failed. Please check your API key."
}
```
# Integrate Knowledge within Apps
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/integrate-knowledge-within-application
### Create an Application Integrated with Knowledge Base
A **"Knowledge Base"** can be used as an external information source to provide precise answers to user questions via LLM. You can associate an existing knowledge base with any [application type](/en/learn/key-concepts#dify-app) in Dify.
Taking a chat assistant as an example, the process is as follows:
1. Go to **Knowledge**, create a **ready-to-use knowledge base**, and upload your file
2. Go to **Studio**, create an application, and select **Chatbot**
3. Enter **Context**, click **Add**, and select one of the knowledge bases you created
4. Use **Metadata Filtering** to refine document search in your knowledge base
5. In **Context Settings -- Retrieval Setting**, configure the **Retrieval Setting**
6. Enable **Citation and Attribution** in **Add Features**
7. In **Debug and Preview**, input user questions related to the knowledge base for debugging
8. After debugging, click **Publish** button to make an AI application based on your own knowledge!
### Connect Knowledge and Set Retrieval Mode
In applications that utilize multiple knowledge bases, it is essential to configure the retrieval mode to enhance the precision of retrieved content. To set the retrieval mode for the knowledge bases, navigate to **Context -- Retrieval Settings -- Rerank Setting**.
#### Retrieval Setting
The retriever scans all knowledge bases linked to the application for text content relevant to the user's question. The results are then consolidated. Below is the technical flowchart for the Multi-path Retrieval mode:
Filter values are case-sensitive and require exact matches. Example: a filter `starts with "App"` or `contains "App"` will match "Apple" but not "apple" or "APPLE".
6. Set logic operators:
* `AND`: Match all conditions
* `OR`: Match any condition
The default client uses OAuth parameters that Dify pre-configures and maintains, so you can add credentials in one click without any extra setup.
The custom client lets you register your own OAuth application on the third-party platform and provide its parameters. Use it for data sources without a default client, or when you have specific security or compliance requirements.
**Process for Custom OAuth**
1. On the **Data Source** page, select an OAuth-supported data source. Click **Configure** and then the **Setting icon** on the right side of **Add OAuth**.
# Step 1: Create Knowledge Pipeline
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/knowledge-pipeline/create-knowledge-pipeline
Navigate to **Knowledge** at the top, then click **Create** > **Build a custom knowledge base**. There are three ways for you to get started.
### Build from Scratch
Data Source → Data Processing (Extractor + Chunker) → Knowledge Base Node (Chunk Structure + Retrieval Setting) → User Input Field → Test & Publish
1. **Data Source**: Content from various data sources (local files, Notion, web pages, etc.)
2. **Data Processing**: Process and transform data content
* Extractor: Parse and structure document content
* Chunker: Split structured content into manageable segments
3. **Knowledge Base**: Set up chunk structure and retrieval settings
4. **User Input Field**: Define parameters that pipeline users need to input for data processing
5. **Test & Publish**: Validate and officially activate the knowledge base
***
## Step 1: Data Source
In a knowledge base, you can choose single or multiple data sources. Currently, Dify supports 4 types of data sources: **file upload, online drive, online documents, and web crawler**.
Visit the [Dify Marketplace](https://marketplace.dify.ai) for more data sources.
### File Upload
Upload local files through drag-and-drop or file selection.
**Configuration Options**
| Item | Description |
| ------------- | ------------------------------------------------------------------------------------------------- |
| File Format | Support PDF, XLSX, DOCX, etc. Users can customize their selection |
| Upload Method | Upload local files or folders through drag-and-drop or file selection. Batch upload is supported. |
**Limitations**
| Item | Description |
| ------------- | --------------------------------------------------------------- |
| File Quantity | 1 file per upload on Sandbox; up to 50 on Professional and Team |
| File Size | 15 MB per file; 50 MB on Professional and Team |
| Storage | Total document count and knowledge storage vary by plan. |
**Output Variables**
| Output Variable | Format |
| --------------- | --------------- |
| `{x} Document` | Single document |
***
### Online Document
#### Notion
Integrate with your Notion workspace to seamlessly import pages and databases, always keeping your knowledge base automatically updated.
**Configuration Options**
| Item | Option | Output Variable | Description |
| --------- | -------- | --------------- | ------------------------------------ |
| Extractor | Enabled | `{x} Content` | Structured and processed information |
| | Disabled | `{x} Document` | Original text |
***
### Web Crawler
Transform web content into formats that can be easily read by large language models. The knowledge base supports Jina Reader and Firecrawl.
#### Jina Reader
An open-source web parsing tool providing simple and easy-to-use API services, suitable for fast crawling and processing web content.
**Parameter Configuration**
| Parameter | Type | Description |
| ---------------- | -------- | ------------------------------------ |
| URL | Required | Target webpage address |
| Crawl sub-page | Optional | Whether to crawl linked pages |
| Use sitemap | Optional | Crawl by using website sitemap |
| Limit | Required | Set maximum number of pages to crawl |
| Enable Extractor | Optional | Choose data extraction method |
#### Firecrawl
An open-source web parsing tool that provides more refined crawling control options and API services. It supports deep crawling of complex website structures, recommended for batch processing and precise control.
**Parameter Configuration**
| Parameter | Type | Description |
| ------------------------- | -------- | -------------------------------------------------------------------------- |
| URL | Required | Target webpage address |
| Limit | Required | Set maximum number of pages to crawl |
| Crawl sub-page | Optional | Whether to crawl linked pages |
| Max depth | Optional | How many levels deep the crawler will traverse from the starting URL |
| Exclude paths | Optional | Specify URL patterns that should not be crawled |
| Include only paths | Optional | Crawl specified paths only |
| Extractor | Optional | Choose data processing method |
| Extract Only Main Content | Optional | Isolate and retrieve the primary, meaningful text and media from a webpage |
***
### Online Drive
Connect your online cloud storage services (e.g., Google Drive, Dropbox, OneDrive) and let Dify automatically retrieve your files. Simply select and import the documents you need for processing, without manually downloading and re-uploading files.
Need help with authorization? Please check [Authorize Data Source](/en/cloud/use-dify/knowledge/knowledge-pipeline/authorize-data-source) for detailed guidance on authorizing different data sources.
***
## Step 2: Set Up Data Processing Tools
In this stage, these tools extract, chunk, and transform the content for optimal knowledge base storage and retrieval. Think of this step like meal preparation. We clean raw materials up, chop them into bite-sized pieces, and organize everything, so the dish can be cooked up quickly when someone orders it.
To develop a custom data processing plugin that extracts multimodal data for multimodal embedding and retrieval, see [Build Tool Plugins for Multimodal Data Processing in Knowledge Pipelines](/en/develop-plugin/dev-guides-and-walkthroughs/develop-multimodal-data-processing-tool).
### Doc Processor
Documents come in different formats - PDF, XLSX, DOCX. However, LLM can't read these files directly. That's where extractors come in. They support multiple formats and handle the conversion, so your content is ready for the next step of the LLMs.
You can choose Dify's Doc Extractor to process files, or select tools based on your needs from Marketplace which offers Dify Extractor and third-party tools such as Unstructured.
Images in documents can be extracted using appropriate document processors. Extracted images are attached to their corresponding chunks, can be managed independently, and are returned alongside those chunks during retrieval.
URLs of extracted images remain in the chunk text, but you can safely remove these URLs to keep the text clean—this won't affect the extracted images.
Each chunk supports up to 10 image attachments; images beyond this limit will not be extracted.
If no images are extracted by the selected processor, Dify will automatically extract JPG, JPEG, PNG, and GIF images under 2 MB that are referenced via accessible URLs using the following Markdown syntax:
* ``
* ``
If you select a multimodal embedding model (marked with a **Vision** icon) in index settings, the extracted images will also be embedded and indexed for retrieval.
#### Doc Extractor
For more information, please refer to the [Document Extractor](/en/cloud/use-dify/nodes/doc-extractor).
#### Dify Extractor
Dify Extractor is a built-in document parser presented by Dify. It supports multiple common file formats and is specially optimized for Doc files. It can extract and store images from documents and return image URLs.
[Unstructured](https://marketplace.dify.ai/plugin/langgenius/unstructured) transforms documents into structured, machine-readable formats with highly customizable processing strategies. It offers multiple extraction strategies (auto, hi\_res, fast, OCR-only) and chunking methods (by\_title, by\_page, by\_similarity) to handle diverse document types, offering detailed element-level metadata including coordinates, confidence scores, and layout information. It's recommended for enterprise document workflows, processing of mixed file types, and cases that require precise control over document processing parameters.
Explore more tools in the [Dify Marketplace](https://marketplace.dify.ai).
***
### Chunker
Similar to human limited attention span, large language models cannot process huge amount of information simultaneously. Therefore, after information extraction, the chunker splits large document content into smaller and manageable segments (called "chunks").
Different documents require different chunking strategies. A product manual works best when split by product features, while research papers should be divided by logical sections. Dify offers 3 types of chunkers for various document types and use cases.
#### Overview of Different Chunkers
| Chunker Type | Highlights | Best for |
| -------------------- | ----------------------------------------------------- | ----------------------------------------------------- |
| General Chunker | Fixed-size chunks with customizable delimiters | Simple documents with basic structure |
| Parent-child Chunker | Dual-layer structure: precise matching + rich context | Complex documents requiring rich context preservation |
| Q\&A Processor | Processes question-answer pairs from spreadsheets | Structured Q\&A data from CSV/Excel files |
#### Common Text Pre-processing Rules
All chunkers support these text cleaning options:
| Preprocessing Option | Description |
| --------------------------------------------- | ---------------------------------------------------------------------------------- |
| Replace consecutive spaces, newlines and tabs | Clean up formatting by replacing multiple whitespace characters with single spaces |
| Remove all URLs and email addresses | Automatically detect and remove web links and email addresses from text |
#### General Chunker
Basic document chunking processing, suitable for documents with relatively simple structures. You can configure text chunking and text preprocessing rules according to the following configuration.
**Input and Output Variable**
| Type | Variable | Description |
| --------------- | ------------------ | --------------------------------------------------------------------------- |
| Input Variable | `{x} Content` | Complete document content that the chunker will split into smaller segments |
| Output Variable | `{x} Array[Chunk]` | Array of chunked content, each segment optimized for retrieval and analysis |
**Chunk Settings**
| Configuration Item | Description |
| -------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Delimiter | Default value is `\n` (line breaks for paragraph segmentation). You can customize chunking rules following regex. The system will automatically execute segmentation when the delimiter appears in text. |
| Maximum Chunk Length | Specifies the maximum character limit within a segment. When this length is exceeded, forced segmentation will occur. |
| Chunk Overlap | When segmenting data, there is some overlap between segments. This overlap helps improve information retention and analysis accuracy, enhancing recall effectiveness. |
#### Parent-child Chunker
By using a dual-layer segmentation structure to resolve the contradiction between context and accuracy, parent-child clunker achieves the balance between precise matching and comprehensive contextual information in Retrieval Augmented Generation (RAG) systems.
**How Parent-child Chunker Works**
Child Chunks for query matching: Small, precise information segments (usually single sentences) to match user queries with high accuracy.
Parent Chunks provide rich context: Larger content blocks (paragraphs, sections, or entire documents) that contain the matching child chunks, giving the large language model (LLM) comprehensive background information.
| Type | Variable | Description |
| --------------- | ------------------------ | --------------------------------------------------------------------------- |
| Input Variable | `{x} Content` | Complete document content that the chunker will split into smaller segments |
| Output Variable | `{x} Array[ParentChunk]` | Array of parent chunks |
**Chunk Settings**
| Configuration Item | Description |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------- |
| Parent Delimiter | Set delimiter for parent chunk splitting |
| Parent Maximum Chunk Length | Set maximum character count for parent chunks |
| Child Delimiter | Set delimiter for child chunk splitting |
| Child Maximum Chunk Length | Set maximum character count for child chunks |
| Parent Mode | Choose between Paragraph (split text into paragraphs) or "Full Document" (use entire document as parent chunk) for direct retrieval |
#### Q\&A Processor
Combining extraction and chunking in one node, Q\&A Processor is specifically designed for structured Q\&A datasets from CSV and Excel files. Perfect for FAQ lists, shift schedules, and any spreadsheet data with clear question-answer pairs.
**Input and Output Variable**
| Type | Variable | Description |
| --------------- | -------------------- | ------------- |
| Input Variable | `{x} Document` | A single file |
| Output Variable | `{x} Array[QAChunk]` | QA chunk |
**Variable Configuration**
| Configuration Item | Description |
| -------------------------- | ------------------------------ |
| Column Number for Question | Set content column as question |
| Column Number for Answer | Set column answer as answer |
***
## Step 3: Configure Knowledge Base Node
Now that your documents are processed and chunked, it's time to set up how they'll be stored and retrieved. Here, you can select different indexing methods and retrieval strategies based on your specific needs.
Knowledge base node configuration includes: Input Variable, Chunk Structure, Index Method, and Retrieval Settings.
### Chunk Structure
**Important Reminder**: Chunk structure cannot be modified once saved and published. Please choose carefully.
#### General Mode
Suitable for most standard document processing scenarios. It provides flexible indexing options—you can choose appropriate indexing methods based on different quality and cost requirements.
General mode supports both high-quality and economical indexing methods, as well as various retrieval settings.
#### Parent-child Mode
It provides precise matching and corresponding contextual information during retrieval, suitable for professional documents that need to maintain complete context.
Parent-child mode supports HQ (High Quality) mode only, offering child chunks for query matching and parent chunks for contextual information during retrieval.
#### Q\&A Mode
Create documents that pair questions with answers when using structured question-answer data. These documents are indexed based on the question portion, enabling the system to retrieve relevant answers based on query similarity.
Q\&A Mode supports HQ (High Quality) mode only.
### Input Variable
Input variables receive processing results from data processing nodes as the data source for knowledge base. You need to connect the output from chunker to the knowledge base as input.
The node supports different types of standard inputs based on the selected chunk structure:
* **General Mode**: x Array\[Chunk] - General chunk array
* **Parent-child Mode**: x Array\[ParentChunk] - Parent chunk array
* **Q\&A Mode**: x Array\[QAChunk] - Q\&A chunk array
### Index Method & Retrieval Settings
The index method determines how your knowledge base builds content indexes, while retrieval settings provide corresponding retrieval strategies based on the selected index method.
Think of it in this way: the index method determines how to organize your documents, while retrieval settings tell users what methods they can use to find documents.
The knowledge base provides two index methods: **High Quality** and **Economical**, each offering different retrieval setting options.
The High Quality method uses embedding models to convert chunks into numerical vectors, helping to compress and store large amounts of information more effectively. This enables the system to find semantically relevant accurate answers even when the user's question wording doesn't exactly match the document.
To enable cross-modal retrieval—retrieving both text and images based on semantic relevance—select a multimodal embedding model (marked with a **Vision** icon). Images extracted from documents will then be embedded and indexed for retrieval.
Knowledge bases using such embedding models are labeled **Multimodal** on their cards.
In the Economical method, each block uses 10 keywords for retrieval without calling embedding models, generating no costs.
For more details, see [Specify the Index Method and Retrieval Settings](/en/cloud/use-dify/knowledge/create-knowledge/setting-indexing-methods).
| Index Method | Available Retrieval Settings | Description |
| ------------ | ---------------------------- | ----------------------------------------------------------------------- |
| High Quality | Vector Retrieval | Understand deeper meaning of queries based on semantic similarity |
| | Full-text Retrieval | Keyword-based retrieval providing comprehensive search capabilities |
| | Hybrid Retrieval | Combine both semantic and keywords |
| Economical | Inverted Index | Common search engine retrieval method, matches queries with key content |
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
You can also refer to the table below for information on configuring chunk structure, index methods, parameters, and retrieval settings.
| Chunk Structure | Index Methods | Parameters | Retrieval Settings |
| ----------------- | -------------------------------------------- | ------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
| General mode | High Quality
| Field Type | Description |
| ---------- | --------------------------------------------------------------------------------------------------- |
| Text | Short text input by knowledge base users, maximum length 256 characters |
| Paragraph | Long text input for longer character strings |
| Select | Fixed options preset by the orchestrator for users to choose from, users cannot add custom content |
| Boolean | Only true/false values |
| Number | Only accepts numerical input |
| Single | Upload a single file, supports multiple file types (documents, images, audio, and other file types) |
| File List | Batch file upload, supports multiple file types (documents, images, audio, and other file types) |
For more information about supported field types, see [User Input](/en/cloud/use-dify/nodes/user-input).
### Field Configuration Options
All input field types include: required, optional, and additional settings. You can set whether fields are required by checking the appropriate option.
| Setting | Name | Description | Example |
| ------------------------- | ------------- | ----------------------------------------------------------------------- | -------------------------------------------------------- |
| Required Settings | Variable Name | Internal system identifier, usually named using English and underscores | `user_email` |
| | Display Name | Interface display name, usually concise and readable text | User Email |
| Type-specific Settings | | Special requirements for different field types | Text field max length 100 characters |
| Additional Settings | Default Value | Default value when user hasn't provided input | Number field defaults to 0, text field defaults to empty |
| | Placeholder | Hint text displayed when input box is empty | "Please enter your email" |
| | Tooltip | Explanatory text to guide user input, usually displayed on mouse hover | "Please enter a valid email address" |
| Special Optional Settings | | Additional setting options based on different field types | Validation of email format |
After completing configuration, click the preview button in the upper right corner to browse the form preview interface. You can drag and adjust field groupings. If an exclamation mark appears, it indicates that the reference is invalid after moving.
**Important Note**: For better debugging and observation, only one file upload is allowed per test run.
3. **Fill Parameters**: After successful import, fill in corresponding parameters according to the user input form you configured earlier
4. **Start Test Run**: Click next step to start testing the entire pipeline
During testing, you can access [History Logs](/en/cloud/use-dify/monitor/logs) (track all run records with timestamps, execution status, and input/output summaries) and [Variable Inspector](/en/cloud/use-dify/debug/variable-inspect) (a dashboard at the bottom showing input/output data for each node to help identify issues and verify data flow) for efficient troubleshooting and error fixing.
Find more information in [Manage Knowledge](/en/cloud/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents).
Important reminder: Once published, the chunk structure cannot be modified.
Once it is published, you can:
**Publish as a Knowledge Pipeline** is available on Professional and Team . Sandbox accounts cannot publish pipelines as reusable templates. [Upgrade your plan](https://dify.ai/pricing) to unlock this feature.
# Build a Custom Knowledge Base
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/knowledge-pipeline/readme
To build a custom knowledge base, you design a knowledge pipeline. A knowledge pipeline is a document processing workflow that transforms raw data into searchable knowledge bases. As with orchestrating a workflow, you can visually combine and configure different processing nodes and tools to optimize data processing for better accuracy and relevance.
Every knowledge pipeline normally follows a structured flow through four key steps:
**Data Sources → Data Extraction → Data Processing → Knowledge Storage**
Each step serves a specific purpose: gathering content from various sources, converting it to processable text, refining it for search, and storing it in a format that enables fast, accurate retrieval.
Dify provides built-in pipeline templates that is optimized for certain use cases, or you can also create knowledge pipelines from scratch. In this session, we will go through creating options, general process of building knowledge pipelines, and how to manage it.
Start from built-in templates, blank knowledge pipeline or import existing pipeline.
Get to know how the knowledge pipeline works, orchestrate different nodes and make sure it’s ready to use.
Let's make it ready for document processing.
Add documents and process them into the searchable knowledge base.
Maintain documents, test retrieval, modify settings, and more.
# Step 4: Upload Files
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/knowledge-pipeline/upload-files
After publishing knowledge pipeline, there're two ways to upload files as below:
A: Click **Go to Documents** in the success notification to add or manage documents. After entering Documents page, click **Add File** to upload.
B: Click **Go to Add Documents** to add documents.
### Upload Process
1. **Select Data Source**\
Choose from the data source types configured in your pipeline. Dify currently supports 4 types of data sources: File Upload (pdf, docx, etc.), Online Drive (Google Drive, OneDrive, etc.), Online Doc (Notion), and Web Crawler (Jina Reader, Firecrawl).
Please visit [Dify Marketplace](https://marketplace.dify.ai/) to install additional data sources.
2. **Fill in Processing Parameters and Preview**\
If you configured user input fields during pipeline orchestration, users will need to fill in the required parameters and variables at this step. After completing the form, click **Preview** to see chunking results. Click **Save & Process** to complete knowledge base creation and start data processing.
Important reminder: Chunk structure remains consistent with the pipeline configuration and won't change with user input parameters.
In [Parent-child mode](/en/cloud/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text), every child chunk becomes a vector.
The embedding model matters too: each model outputs vectors of a fixed length, listed in the provider's documentation as its number of dimensions. For example, OpenAI's `text-embedding-3-large` uses nearly twice the storage per chunk of `text-embedding-3-small`.
As a result, a document can use several times its own file size in storage once indexed.
Documents indexed with the **Economical** method use keyword indexing instead of vectors and don't consume storage.
Usage reflects the actual storage your vectors occupy, measured periodically, so a delay is expected before the number changes after an upload or deletion.
## When an Upload Would Exceed the Limit
Every upload is checked before indexing. When the estimated total storage after the upload would exceed your plan's capacity, the document is kept in the document list but not indexed.
To bring it under the limit, split the file into smaller uploads, or raise the chunk size in the document's [chunk settings](/en/cloud/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text) so it produces fewer chunks, though larger chunks make each retrieved passage longer and less precise.
Alternatively, upgrade your plan for more capacity, then try again.
## When Storage Is Full
Once usage reaches your plan's limit, the workspace can no longer add knowledge content.
Uploading documents, adding or editing chunks, restoring archived documents, and re-indexing operations such as changing chunk settings are all blocked, including in knowledge bases that use **Economical** indexing.
To restore these actions, free space or upgrade your plan.
If a downgrade or an expired subscription leaves your data above the new plan's limit, nothing is deleted: your apps can still retrieve from these knowledge bases, but adding content stays blocked until usage fits the limit or you upgrade again.
## Free Up Storage
Delete the documents or knowledge bases you no longer need. Their vectors are removed, and the space returns to your quota.
The usage shown in **Settings** > **Billing** refreshes on a delay, so the number takes a while to drop after a deletion.
# Manage Knowledge Settings
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/manage-knowledge/introduction
Only the workspace owner, administrators, and editors can modify the knowledge base settings.
In a knowledge base, click the **Settings** icon in the left sidebar to enter its settings page.
| Settings | Description |
| :----------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Name & Icon | Identifies the knowledge base. |
| Description | Indicates the knowledge base's purpose and content. |
| Permissions | Defines which workspace members can access the knowledge base.Members granted access to a knowledge base have all the permissions listed in [Manage Knowledge Content](/en/cloud/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents). |
| Index Method | Defines how document chunks are processed and organized for retrieval. For more details, see [Select the Index Method](/en/cloud/use-dify/knowledge/create-knowledge/setting-indexing-methods#select-the-index-method). |
| Embedding Model | Specifies the embedding model used to convert document chunks into vector representations.Changing the embedding model will re-embed all chunks. |
| Summary Auto-Gen | Automatically generate summaries for document chunks.Once enabled, this only applies to newly added documents and chunks. For existing chunks, select the document(s) in the document list and click **Generate summary**. |
| Retrieval Settings | Defines how the knowledge base retrieves relevant content. For more details, see [Configure the Retrieval Settings](/en/cloud/use-dify/knowledge/create-knowledge/setting-indexing-methods#configure-the-retrieval-settings). |
# Manage Knowledge Content
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents
## Manage Documents
In a knowledge base, each imported item—whether a local file, a Notion page, or a web page—becomes a document.
From the document list, you can view and manage all these documents to keep your knowledge accurate, relevant, and up-to-date.
Click the knowledge base name at the top to quickly switch between knowledge bases.
Each document can have its own chunking settings, while the chunk structure is shared across the knowledge base and cannot be changed once set. |
| Delete | Permanently remove a document. **Deletion cannot be undone**. |
| Enable / Disable | Temporarily include or exclude a document from retrieval. Documents that have not been updated or retrieved for a certain period are automatically disabled to optimize performance. The inactivity period varies by subscription plan:Sandbox: 7 days Professional & Team: 30 days |
| Archive / Unarchive | Archive a document that you no longer need for retrieval but still want to keep. Archived documents are read-only and can be unarchived at any time. |
| Edit | Modify the content of a document by editing its chunks. See [Manage Chunks](#manage-chunks) for details. |
| Rename | Change the name of a document. |
## Manage Chunks
According to its chunk settings, every document is split into content chunks—the basic units for retrieval.
From the chunk list within a document, you can view and manage all its chunks to improve the retrieval efficiency and accuracy.
Click the document name in the upper-left corner to quickly switch between documents.
Adding chunks is available on Professional and Team . [Learn more](https://dify.ai/pricing). |
| Delete | Permanently remove a chunk. **Deletion cannot be undone**. |
| Enable / Disable | Temporarily include or exclude a chunk from retrieval. Disabled chunks cannot be edited. |
| Edit | Modify the content of a chunk. Edited chunks are marked **Edited**.When editing a parent chunk, you can choose to regenerate its child chunks or keep them unchanged. Editing a child chunk does not update its parent chunk. Each chunk can have up to 10 image attachments, which are returned alongside it during retrieval. Images beyond this limit will not be extracted. If you select a multimodal embedding model (marked with a **Vision** icon), the extracted images will also be embedded and indexed for retrieval. |
| Add / Edit / Delete Summary | Add, modify, or remove a summary for a chunk.Add identical summaries to multiple chunks to enable grouped retrieval, allowing related chunks to be returned together (subject to the Top K limit). |
## Best Practices
### Check Chunk Quality
After a document is chunked, carefully review each chunk to ensure it's semantically complete and appropriately sized for optimal retrieval accuracy and response relevance.
Common issues to watch for:
* Chunks are **too short**—may lack sufficient context, leading to semantic loss and inaccurate answers.
* Chunks are **too long**—may include irrelevant information, introducing semantic noise and lowering retrieval precision.
* Chunks are **semantically incomplete**—caused by forced chunking that cuts through sentences or paragraphs, resulting in missing or misleading content during retrieval.
### Use Child Chunks as Retrieval Hooks for Parent Chunks
For documents chunked with Parent-child mode, the system searches across child chunks but returns the parent chunks. Since editing a child chunk does not update its parent, you can treat child chunks as semantic tags or retrieval hints for their parent chunks.
To do this, rewrite child chunks into **keywords**, **summaries**, or **common user queries**. For example, if a parent chunk covers technical "LED Status Indicators", you could rephrase its child chunks as:
* *blinking light, won't turn on, red light, connection error, frozen* (keywords)
* *Guide to interpreting LED colors and troubleshooting hardware power or pairing issues* (summaries)
* *What does a solid red light mean?* (queries)
### Use Summaries to Bridge Query-Content Gaps
While high-quality indexing enables semantic search, raw chunks can still be hard to retrieve when they are too specific, noisy, or structurally complex to align well with user queries.
Summaries bridge this gap by providing a condensed semantic layer that makes the chunk's core intent explicit.
Use summaries when:
* **User queries differ from document language**: For technical documentation written formally, add summaries in the way users actually ask questions.
* **Concepts are implicit or buried in details**: Add high-level summaries that surface the core concepts and intent, so the chunk can be matched without relying on small details scattered across the text.
* **Raw text is non-textual**: When a chunk is primarily code, tables, logs, transcripts, or otherwise hard to match semantically, add descriptive summaries that clearly label what the chunk contains.
* **Related chunks should be retrieved together**: Apply identical summaries to a series of related chunks to enable grouped retrieval. This semantic glue allows multiple parts of a topic to be retrieved together, providing richer context.
The number of returned related chunks is subject to the Top K limit defined in the retrieval settings.
# Manage Document Metadata
Source: https://docs.dify.ai/en/cloud/use-dify/knowledge/metadata
## What is Metadata?
### Overview
Metadata is information that describes your data - essentially "data about data". Just as a book has a table of contents to help you understand its structure, metadata provides context about your data's content, origin, purpose, etc., making it easier for you to find and manage information in your knowledge base.
This guide aims to help you understand metadata and effectively manage your knowledge base.
### Core Concepts
* **Field**: The label of a metadata field (e.g., "author", "language").
* **Value**: The information stored in a metadata field (e.g., "Jack", "English").
Built-in Metadata
Custom Metadata
Location
Lower section of the Metadata panel
Upper section of the Metadata panel
Activation
Disabled by default; requires manual activation
Add as needed
Generation
System automatically extracts and generates field values
User-defined and manually added
Editing
Fields and values cannot be modified once generated
Fields and values can be edited or deleted
Scope
Applies to all existing and new documents when enabled
Stored in metadata list; requires manual assignment to documents
Fields
System-defined fields include:
document\_name (string)
uploader (string)
upload\_date (time)
last\_update\_date (time)
source (string)
No default fields; all fields must be manually created
Value Types
String: For text values
Number: For numerical values
Time: For dates and timestamps
String: For text values
Number: For numerical values
Time: For dates and timestamps
#### Create New Metadata Fields
To create a new metadata field:
1. Click **+Add Metadata** to open the **New Metadata** dialog.
Retrieval settings adjusted here are temporary and only apply to the current test session.
For more about retrieval settings, see [Configure the Retrieval Settings](/en/cloud/use-dify/knowledge/create-knowledge/setting-indexing-methods#configure-the-retrieval-settings).
The **Records** section logs all retrieval events associated with this knowledge base, including:
* Queries tested directly on the **Retrieval Testing** page
* Retrieval requests made by any linked app—whether during test runs or in production
Test retrievals and regular retrievals share the same API endpoint.
# Dashboard
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/analysis
Monitor performance, costs, and user engagement through Dify's built-in analytics dashboard
The dashboard tracks four metrics over time to show how your application performs:
Alibaba Cloud Monitor natively supports Python/Golang/Java applications through [LoongSuite](https://github.com/alibaba/loongsuite-python-agent) agents and open-source OpenTelemetry agents. In addition to one-click monitoring of Dify LLM applications, it also supports end-to-end observability of Dify components and their upstream and downstream dependencies through non-invasive agents.
For more details, please refer to the [Cloud Monitor documentation](https://www.alibabacloud.com/help/en/cms/cloudmonitor-1-0/product-overview/what-is-cloudmonitor?spm=a3c0i.63551.2277339270.1.76c7112eeKEvSr).
## How to Configure Alibaba Cloud Monitor
### 1. Get Alibaba Cloud Endpoint and License Key
1. Log in to the [ARMS console](https://account.alibabacloud.com/login/login.htm?spm=5176.12901015-2.0.0.68d74b84XRatpU), and click **Integration Center** in the left navigation bar.
2. In the **Server-side Applications** area, click the **OpenTelemetry** card.
3. In the **OpenTelemetry** panel that appears, select **gRPC** as the export protocol, and select the connection method and region according to your actual deployment.
The Endpoint does not include a port number, for example `http://tracing-cn-heyuan.arms.aliyun.com`.
### 2. Configure Cloud Monitor in Dify
1. Log in to the Dify console and navigate to the application you want to monitor.
2. Open **Monitoring** in the left navigation bar.
3. Click **Tracing app performance**, then click **Configure** in the **Cloud Monitor** area.
Workflow
Alibaba Cloud Monitor Trace
workflow\_id
Unique identifier of the Workflow
conversation\_id
Conversation ID
workflow\_run\_id
ID of this run
tenant\_id
Tenant ID
elapsed\_time
Duration of this run
status
Run status
version
Workflow version
total\_tokens
Total tokens used in this run
file\_list
List of processed files
triggered\_from
Source that triggered this run
workflow\_run\_inputs
Input data for this run
workflow\_run\_outputs
Output data for this run
error
Errors that occurred during this run
query
Query used during runtime
workflow\_app\_log\_id
Workflow application log ID
message\_id
Associated message ID
start\_time
Run start time
end\_time
Run end time
**Workflow Trace Metadata**
* workflow\_id - Unique identifier of the Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of this run
* tenant\_id - Tenant ID
* elapsed\_time - Duration of this run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in this run
* file\_list - List of processed files
* triggered\_from - Trigger source
### Message Trace Information
Message
Alibaba Cloud Monitor Trace
message\_id
Message ID
message\_data
Message data
user\_session\_id
User's session\_id
conversation\_model
Conversation model
message\_tokens
Number of tokens in the message
answer\_tokens
Number of tokens in the answer
total\_tokens
Total tokens in message and answer
error
Error information
inputs
Input data
outputs
Output data
file\_list
List of processed files
start\_time
Start time
end\_time
End time
message\_file\_data
File data associated with the message
conversation\_mode
Conversation mode
**Message Trace Metadata**
* conversation\_id - ID of the conversation to which the message belongs
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether it is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
* message\_id - Message ID
### Dataset Retrieval Trace Information
Dataset Retrieval
Alibaba Cloud Monitor Trace
message\_id
Message ID
inputs
Input content
documents
Document data
start\_time
Start time
end\_time
End time
message\_data
Message data
**Dataset Retrieval Trace Metadata**
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether it is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
### Tool Trace Information
Tool
Alibaba Cloud Monitor Trace
message\_id
Message ID
tool\_name
Tool name
start\_time
Start time
end\_time
End time
tool\_inputs
Tool inputs
tool\_outputs
Tool outputs
message\_data
Message data
error
Error information (if any)
inputs
Input content of the message
outputs
Answer content of the message
tool\_config
Tool configuration
time\_cost
Time cost
tool\_parameters
Tool parameters
file\_url
URL of associated file
**Tool Trace Metadata**
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Creator role
* created\_user\_id - Creator user ID
# Integrate with Arize
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-arize
### What is Arize
[Arize AX](https://arize.com/products/ax/) is [Arize AI](https://arize.com/?utm_source=dify-docs\&utm_medium=partner\&utm_campaign=partner-docs\&utm_content=integrate-arize)'s full-featured platform for observability, online and offline evaluation, monitoring, and experimentation in LLM and agent-driven applications. Built for production teams, AI-native companies, and enterprises, it runs as a managed cloud service or an enterprise self-hosted deployment.
If you'd rather run an open-source stack for experimentation or single-container self-hosting, set up the [Phoenix integration](/en/cloud/use-dify/monitor/integrations/integrate-phoenix) instead.
Once traces are flowing, see Arize's [agent evaluation guide](https://arize.com/guides/ai-agent-handbook/agent-evaluation/) and [LLM evaluation guide](https://arize.com/resources/llm-evaluation/) for how to use them to debug failures, evaluate agent behavior, and monitor model quality.
### How to Configure Arize
#### 1. Register/Login to [Arize](https://app.arize.com/auth/join)
#### 2. Get your Arize API Key
Retrieve your Arize API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
Workflow
Arize Trace
workflow\_app\_log\_id/workflow\_run\_id
id
user\_session\_id
- placed in metadata
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
error
error
\[workflow]
tags
"conversation\_id/none for workflow"
conversation\_id in metadata
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
Chat
Arize LLM
message\_id
id
user\_session\_id
- placed in metadata
"llm"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
\["message", conversation\_mode]
tags
conversation\_id
conversation\_id in metadata
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
Moderation
Arize Tool
user\_id
- placed in metadata
“moderation"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["moderation"]
tags
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
Suggested Question
Arize LLM
user\_id
- placed in metadata
"suggested\_question"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["suggested\_question"]
tags
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
Dataset Retrieval
Arize Retriever
user\_id
- placed in metadata
"dataset\_retrieval"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["dataset\_retrieval"]
tags
message\_id
parent\_run\_id
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
Tool
Arize Tool
user\_id
- placed in metadata
tool\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["tool", tool\_name]
tags
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
Generate Name
Arize Tool
user\_id
- placed in metadata
"generate\_conversation\_name"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["generate\_name"]
tags
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Langfuse
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-langfuse
### What is Langfuse
Langfuse is an open-source LLM engineering platform that helps teams collaborate on debugging, analyzing, and iterating their applications.
Introduction to Langfuse: [https://langfuse.com/](https://langfuse.com/)
### How to Configure Langfuse
1. Register and log in to Langfuse on the [official website](https://langfuse.com/)
2. Create a project in Langfuse. After logging in, click **New** on the homepage to create your own project. The **project** will be used to associate with **applications** in Dify for data monitoring.
Workflow
LangFuse Trace
workflow\_app\_log\_id/workflow\_run\_id
id
user\_session\_id
user\_id
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
Model token consumption
usage
metadata
metadata
error
level
error
status\_message
\[workflow]
tags
\["message", conversation\_mode]
session\_id
conversion\_id
parent\_observation\_id
**Workflow Trace Info**
* workflow\_id - Unique ID of Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - Workflow ID of this runtime
* tenant\_id - Tenant ID
* elapsed\_time - Elapsed time at this runtime
* status - Runtime status
* version - Workflow version
* total\_tokens - Total token used at this runtime
* file\_list - List of files processed
* triggered\_from - Source that triggered this runtime
* workflow\_run\_inputs - Input of this workflow
* workflow\_run\_outputs - Output of this workflow
* error - Error Message
* query - Queries used at runtime
* workflow\_app\_log\_id - Workflow Application Log ID
* message\_id - Relevant Message ID
* start\_time - Start time of this runtime
* end\_time - End time of this runtime
* workflow node executions - Workflow node runtime information
* Metadata
* workflow\_id - Unique ID of Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - Workflow ID of this runtime
* tenant\_id - Tenant ID
* elapsed\_time - Elapsed time at this runtime
* status - Operational state
* version - Workflow version
* total\_tokens - Total token used at this runtime
* file\_list - List of files processed
* triggered\_from - Source that triggered this runtime
#### Message Trace Info
**For trace llm conversation**
Message
LangFuse Generation/Trace
message\_id
id
user\_session\_id
user\_id
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
Model token consumption
usage
metadata
metadata
error
level
error
status\_message
\["message", conversation\_mode]
tags
conversation\_id
session\_id
conversion\_id
parent\_observation\_id
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - Session ID for user
* conversation\_model - Conversation model
* message\_tokens - Message tokens
* answer\_tokens - Answer Tokens
* total\_tokens - Total Tokens from Message and Answer
* error - Error Message
* inputs - Input data
* outputs - Output data
* file\_list - List of files processed
* start\_time - Start time
* end\_time - End time
* message\_file\_data - Message of relevant file data
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending account's ID
* agent\_based - Whether agent based
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message source
* message\_id - Message ID
#### Moderation Trace Information
**Used to track conversation moderation**
Moderation
LangFuse Generation/Trace
user\_id
user\_id
moderation
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
metadata
metadata
\[moderation]
tags
message\_id
parent\_observation\_id
**Message Trace Info**
* message\_id - Message ID
* user\_id - user ID
* workflow\_app\_log\_id workflow\_app\_log\_id
* inputs - Input data for review
* message\_data - Message Data
* flagged - Whether it is flagged for attention
* action - Specific actions to implement
* preset\_response - Preset response
* start\_time - Start time of review
* end\_time - End time of review
* Metadata
* message\_id - Message ID
* action - Specific actions to implement
* preset\_response - Preset response
#### Suggested Question Trace Information
**Used to track suggested questions**
Suggested Question
LangFuse Generation/Trace
user\_id
user\_id
suggested\_question
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
metadata
metadata
\[suggested\_question]
tags
message\_id
parent\_observation\_id
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input data
* outputs - Output data
* start\_time - Start time
* end\_time - End time
* total\_tokens - Total tokens
* status - Message Status
* error - Error Message
* from\_account\_id - Sending account ID
* agent\_based - Whether agent based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Message status
* Metadata
* message\_id - Message ID
* ls\_provider - Model Provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending Account ID
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message source
#### Dataset Retrieval Trace Information
**Used to track knowledge base retrieval**
Dataset Retrieval
LangFuse Generation/Trace
user\_id
user\_id
dataset\_retrieval
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
metadata
metadata
\[dataset\_retrieval]
tags
message\_id
parent\_observation\_id
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input Message
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model Provider
* ls\_model\_name - Model ID
* status - Model status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending account's ID
* agent\_based - Whether agent based
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message Source
#### Tool Trace Information
**Used to track tool invocation**
Tool
LangFuse Generation/Trace
user\_id
user\_id
tool\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
metadata
metadata
\["tool", tool\_name]
tags
message\_id
parent\_observation\_id
**Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool Name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error Message, if exist
* inputs - Input of Message
* outputs - Output of Message
* tool\_config - Tool config
* time\_cost - Time cost
* tool\_parameters - Tool Parameters
* file\_url - URL of relevant files
* Metadata
* message\_id - Message ID
* tool\_name - Tool Name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool config
* time\_cost - Time. cost
* error - Error Message
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Created by role
* created\_user\_id - Created user ID
#### Generate Name Trace
**Used to track conversation title generation**
Generate Name
LangFuse Generation/Trace
user\_id
user\_id
generate\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
input
outputs
output
metadata
metadata
\[generate\_name]
tags
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated session name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
### Langfuse Prompt Management
The [Langfuse Prompt Management Plugin](https://github.com/gao-ai-com/dify-plugin-langfuse) (community maintained) lets you use prompts that are [managed and versioned in Langfuse](https://langfuse.com/docs/prompt-management/get-started) in your Dify applications, enhancing your LLM application development workflow. Key features include:
* **Get Prompt**: Fetch specific prompts managed in Langfuse.
* **Search Prompts**: Search for prompts in Langfuse using various filters.
* **Update Prompt**: Create new versions of prompts in Langfuse and set tags/labels.
This integration streamlines the process of managing and versioning your prompts, contributing to more efficient development and iteration cycles. You can find the plugin and installation instructions [here](https://github.com/gao-ai-com/dify-plugin-langfuse).
# Integrate with LangSmith
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-langsmith
### What is LangSmith
LangSmith is a platform for building production-grade LLM applications. It is used for developing, collaborating, testing, deploying, and monitoring LLM applications.
For more details, please refer to [LangSmith](https://www.langchain.com/langsmith).
### How to Configure LangSmith
#### 1. Register/Login to [LangSmith](https://www.langchain.com/langsmith)
#### 2. Create a Project
Create a project in LangSmith. After logging in, click **New Project** on the homepage to create your own project. The **project** will be used to associate with **applications** in Dify for data monitoring.
The configured project name needs to match the project set in LangSmith. If the project names do not match, LangSmith will automatically create a new project during data synchronization.
Once successfully saved, you can view the monitoring status on the current page.
Workflow
LangSmith Chain
workflow\_app\_log\_id/workflow\_run\_id
id
user\_session\_id
- placed in metadata
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
extra
error
error
\[workflow]
tags
"conversation\_id/none for workflow"
conversation\_id in metadata
conversion\_id
parent\_run\_id
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
Chat
LangSmith LLM
message\_id
id
user\_session\_id
- placed in metadata
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
extra
error
error
\["message", conversation\_mode]
tags
conversation\_id
conversation\_id in metadata
conversion\_id
parent\_run\_id
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
Moderation
LangSmith Tool
user\_id
- placed in metadata
“moderation"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
extra
\[moderation]
tags
message\_id
parent\_run\_id
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
Suggested Question
LangSmith LLM
user\_id
- placed in metadata
suggested\_question
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
extra
\[suggested\_question]
tags
message\_id
parent\_run\_id
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
Dataset Retrieval
LangSmith Retriever
user\_id
- placed in metadata
dataset\_retrieval
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
extra
\[dataset\_retrieval]
tags
message\_id
parent\_run\_id
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
Tool
LangSmith Tool
user\_id
- placed in metadata
tool\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
extra
\["tool", tool\_name]
tags
message\_id
parent\_run\_id
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
Generate Name
LangSmith Tool
user\_id
- placed in metadata
generate\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
extra
\[generate\_name]
tags
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Opik
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-opik
### What is Opik
Opik is an open-source platform designed for evaluating, testing, and monitoring large language model (LLM) applications. Developed by Comet, it aims to facilitate more intuitive collaboration, testing, and monitoring of LLM-based applications.
For more details, please refer to [Opik](https://www.comet.com/site/products/opik/).
***
### How to Configure Opik
#### 1. Register/Login to [Opik](https://www.comet.com/signup?from=llm)
#### 2. Get your Opik API Key
Retrieve your Opik API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
Workflow
Opik Trace
workflow\_app\_log\_id/workflow\_run\_id
id
user\_session\_id
- placed in metadata
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
error
error
\[workflow]
tags
"conversation\_id/none for workflow"
conversation\_id in metadata
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
Chat
Opik LLM
message\_id
id
user\_session\_id
- placed in metadata
"llm"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
\["message", conversation\_mode]
tags
conversation\_id
conversation\_id in metadata
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
Moderation
Opik Tool
user\_id
- placed in metadata
“moderation"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["moderation"]
tags
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
Suggested Question
Opik LLM
user\_id
- placed in metadata
"suggested\_question"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["suggested\_question"]
tags
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
Dataset Retrieval
Opik Retriever
user\_id
- placed in metadata
"dataset\_retrieval"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["dataset\_retrieval"]
tags
message\_id
parent\_run\_id
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
Tool
Opik Tool
user\_id
- placed in metadata
tool\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["tool", tool\_name]
tags
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
Generate Name
Opik Tool
user\_id
- placed in metadata
"generate\_conversation\_name"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["generate\_name"]
tags
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Phoenix
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-phoenix
### What is Phoenix
[Arize Phoenix](https://arize.com/phoenix/) is the open-source, OpenTelemetry-based platform from [Arize AI](https://arize.com/?utm_source=dify-docs\&utm_medium=partner\&utm_campaign=partner-docs\&utm_content=integrate-phoenix) for observability, evaluation, prompt engineering, and experimentation with LLM workflows and agents.
Use Arize's hosted [Phoenix Cloud](#how-to-configure-phoenix-cloud), or self-host Phoenix on your own infrastructure (a single container is enough to start). Dify sends traces server-side, so a self-hosted endpoint must be reachable from the internet.
If you need the full-featured platform built for production teams, AI-native companies, and enterprises, set up [Arize AX](https://arize.com/products/ax/) through the [Arize integration](/en/cloud/use-dify/monitor/integrations/integrate-arize) instead.
Once traces are flowing, see Arize's [agent evaluation guide](https://arize.com/guides/ai-agent-handbook/agent-evaluation/) and [LLM evaluation guide](https://arize.com/resources/llm-evaluation/) for how to use them to debug failures, evaluate agent behavior, and monitor model quality.
### How to Configure Phoenix
#### 1. Register/Login to [Phoenix](https://app.arize.com/auth/phoenix/signup)
#### 2. Get your Phoenix API Key
Retrieve your Phoenix API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
Workflow
Phoenix Trace
workflow\_app\_log\_id/workflow\_run\_id
id
user\_session\_id
- placed in metadata
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
error
error
\[workflow]
tags
"conversation\_id/none for workflow"
conversation\_id in metadata
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
Chat
Phoenix LLM
message\_id
id
user\_session\_id
- placed in metadata
"llm"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
Model token consumption
usage\_metadata
metadata
metadata
\["message", conversation\_mode]
tags
conversation\_id
conversation\_id in metadata
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
Moderation
Phoenix Tool
user\_id
- placed in metadata
“moderation"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["moderation"]
tags
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
Suggested Question
Phoenix LLM
user\_id
- placed in metadata
"suggested\_question"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["suggested\_question"]
tags
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
Dataset Retrieval
Phoenix Retriever
user\_id
- placed in metadata
"dataset\_retrieval"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["dataset\_retrieval"]
tags
message\_id
parent\_run\_id
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
Tool
Phoenix Tool
user\_id
- placed in metadata
tool\_name
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["tool", tool\_name]
tags
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
Generate Name
Phoenix Tool
user\_id
- placed in metadata
"generate\_conversation\_name"
name
start\_time
start\_time
end\_time
end\_time
inputs
inputs
outputs
outputs
metadata
metadata
\["generate\_name"]
tags
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with W&B Weave
Source: https://docs.dify.ai/en/cloud/use-dify/monitor/integrations/integrate-weave
Send traces from Dify applications to W&B Weave for LLM observability
### What is W\&B Weave
Weights & Biases (W\&B) Weave is a framework for tracking, experimenting with, evaluating, deploying, and improving LLM-based applications. Designed for flexibility and scalability, Weave supports every stage of your LLM application development workflow.
For more details, please refer to [Weave](https://docs.wandb.ai/weave).
### How to Configure Weave
#### 1. Register/Login
Register/Login to [W\&B Weave](https://wandb.ai/signup) and get your API key. Then, copy your API key from [here](https://wandb.ai/authorize).
#### 2. Integrate W\&B Weave with Dify
Configure Weave in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
Logs contain complete user conversations and may include sensitive information. Ensure your application complies with local data privacy regulations: publish a privacy policy and obtain user consent where required.
Deleting conversations or cleaning up old logs does not erase the files uploaded in them.
On the Sandbox plan, logs of every type are retained for 30 days. Older entries are permanently deleted—upgrading later doesn't recover them.
On Professional and Team , retention depends on the log type:
* **Conversation logs** (Chatbot, Chatflow, Agent, and Text Generator apps): retained for the duration of the active subscription.
* **Workflow run logs** (Workflow apps): recent runs stay on the **Logs** page; runs older than about three months move to monthly archives you can download as CSV files. See [Download Archived Logs](#download-archived-logs-professional-team) for details.
## Download Archived Logs Professional Team
Archived runs aren't lost: once a month, workflow run logs that have aged past about three months are packed into a monthly archive for the whole workspace, and every archived month is available for download.
Only the workspace owner and admins can download archives in **Settings** > **Archived logs**:
1. Click **Prepare download** for the month you need. Preparation runs in the background, so you can leave the page and come back.
2. When the button turns into **Download**, click it to save the file. A prepared download stays available for 24 hours; after that, prepare it again.
Each download is a ZIP containing CSV files that cover all workflow runs in the workspace for that month:
| File | Contents |
| :-------------------------------------------------- | :------------------------------------------------------------------------ |
| `workflow_runs.csv` | One row per run: status, inputs, outputs, timing, and token usage |
| `workflow_app_logs.csv` | Links each run to its app and the end user or account that started it |
| `workflow_node_executions.csv` | Per-node execution records for each run |
| `workflow_node_execution_offload.csv` | Oversized node inputs and outputs stored separately from the main records |
| `workflow_pauses.csv`, `workflow_pause_reasons.csv` | Pause records from runs that waited for human input |
| `workflow_trigger_logs.csv` | Trigger invocations that started runs |
To pull out a single app's history, filter by the `app_id` column, present in the run and app log CSVs. An app's ID is the long identifier in its URL in **Studio**.
# Agent
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/agent
Run an agent as a step in your workflow, reasoning and using tools to complete a task
The classic Agent node gives your LLM autonomous control over tools, enabling it to iteratively decide which tools to use and when to use them. Instead of pre-planning every step, the Agent reasons through problems dynamically, calling tools as needed to complete complex tasks.
Uses the LLM's native function calling capabilities to directly pass tool definitions through the tools parameter. The LLM decides when and how to call tools using its built-in mechanism.
Best for models like GPT-4, Claude 3.5, and other models with robust function calling support.
Uses structured prompts that guide the LLM through explicit reasoning steps. Follows a **Thought → Action → Observation** cycle for transparent decision-making.
Works well with models that may not have native function calling or when you need explicit reasoning traces.
Install additional strategies from **Marketplace → Agent Strategies** or contribute custom strategies to the [community repository](https://github.com/langgenius/dify-plugins).
The new Agent node is in beta and available in Workflow apps only.
The new Agent node runs an [agent](/en/cloud/use-dify/build/new-agent/overview) as one step of a workflow. Unlike the classic node's model-with-tools setup, the agent arrives as a complete worker with its own capabilities and sandbox.
You pick the agent and tell it what to do; it works through the task on its own and hands the results back to the rest of the flow.
## Choose an Agent
When you add the node, pick who does the work:
You can invite any published agent: it arrives with its saved capabilities, and you set only its task here.
An invited agent is like a full-time employee: its capabilities are managed centrally in **Agents**. When you publish an update there, every workflow that uses the agent gets it.
* To edit its capabilities, click **Edit in Agents**.
* If you want changes for this step only, click **Make a copy**: the node switches to a one-time copy that no longer follows the original.
Create a one-time agent that lives on this node alone, and configure it right here, the same way you [build](/en/cloud/use-dify/build/new-agent/build) in **Agents**.
It's like a temp you bring in for one job. If it proves its worth, promote it to **Agents** to reuse it elsewhere.
You can always swap the agent later.
Two nodes that invite the same agent still work separately: each starts from the agent's saved setup in its own sandbox, and nothing from one node's run (files it wrote, tools it installed) carries into another.
To pass results between nodes, declare them as outputs and reference them downstream.
## Give It a Task
In **Agent task**, describe what you need at this step, the way you'd brief a colleague on one job. This is separate from the agent's own prompt and capabilities. Type `/` to pull in outputs from earlier nodes.
Say you've invited a support agent that already knows your product docs and writes in your support tone, and the workflow hands it inbound customer emails. The task covers only this step:
```text wrap theme={null}
Read the customer email in {{customer_email}} and draft a reply that answers every question in it. Keep it under 150 words.
```
Variables you pull in reach the agent as text and are truncated at 2,000 characters.
To hand over longer content in full, pass it as a file: the agent receives the whole file and reads it in its sandbox.
## Declare Its Outputs
By default, an Agent node returns a single output, `text`: the agent's reply to its task, as one block of text. When a later step needs something more specific, like a single value or a particular file, declare it as its own output.
Type `/` in the **Agent task**, choose **New output**, then name it and pick a type in place. Each declared output can be referenced by downstream nodes on its own.
A declared output sits right in the task text, so you can tell the agent exactly what to put in it. For example, in this task `{{vendor_name}}` and `{{quote_file}}` are declared outputs:
```text wrap theme={null}
Compare the three vendor quotes in {{vendor_quotes}} and write a recommendation. Put the winning vendor's name in {{vendor_name}} and its quote PDF in {{quote_file}}.
```
Each file the agent returns is capped at 50 MB.
# Answer
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/answer
Define response content in Chatflow applications
The Answer node defines what content gets delivered to users in Chatflow applications. Use it to format responses, combine text with variables, and stream multimodal content including text, images, and files.
The Answer node is only available for Chatflow applications. Workflow applications use the End node instead.
## Content Configuration
The Answer node provides a flexible text editor where you can craft responses using fixed text, variables from previous nodes, or combinations of both.
Reference variables from any previous workflow node using the `{{variable_name}}` syntax. The editor supports rich content formatting and variable insertion to create dynamic, contextual responses.
Python includes standard libraries like `json`, `math`, `datetime`, and `re`. Ideal for data analysis, mathematical operations, and text processing.
```python theme={null}
def main(data: list) -> dict:
import json
import math
average = sum(data) / len(data)
return {'result': math.ceil(average)}
```
JavaScript provides standard built-in objects and methods. Good for JSON manipulation and string operations.
```javascript theme={null}
function main(data) {
const processed = data.map(item => item.toUpperCase());
return { result: processed };
}
```
## Error Handling and Retries
Configure automatic retry behavior for failed code executions and define fallback strategies when code encounters errors.
**GET** retrieves data from servers without modifying anything. Use for fetching user profiles, searching databases, or getting current status.
**HEAD** gets response headers without the full response body. Useful for checking if resources exist or getting metadata.
**POST** sends data to servers, typically for creating new resources. Use for form submissions, file uploads, or sending JSON payloads.
**PUT** creates or completely replaces resources. Use when you want to set the entire state of a resource.
**PATCH** makes partial updates to existing resources. Use when you only need to modify specific fields.
**DELETE** removes resources from servers. Use for deleting files, user accounts, or any resource that should be removed.
## Configuration
Configure every aspect of your HTTP request including URL, headers, query parameters, request body, and authentication. Variables from previous workflow nodes can be dynamically inserted anywhere in your request configuration.
### Variable Substitution
Reference workflow variables using double curly braces: `{{variable_name}}`. Dify supports deep object access, so you can extract nested values like `{{api_response.data.items[0].id}}` from previous HTTP responses.
Secret-type environment variable values are masked in workflow run logs and in this node's request log.
### Timeout Configuration
HTTP requests have configurable timeouts to prevent hanging:
* **Connect timeout**: Maximum time to establish connection
* **Read timeout**: Maximum time to read response data
* **Write timeout**: Maximum time to send request data
Timeouts are enforced to maintain workflow performance and prevent resource exhaustion.
### Authentication
The node supports multiple authentication types:
**No Auth** (`type: "no-auth"`) - No authentication headers added
**API Key** (`type: "api-key"`) with three subtypes:
* **Basic** (`type: "basic"`) - Adds Basic Auth header with base64 encoding
* **Bearer** (`type: "bearer"`) - Adds `Authorization: Bearer ` header
* **Custom** (`type: "custom"`) - Adds custom header with specified name and value
### Request Body
Choose the appropriate body type based on your API requirements:
* **JSON** for structured data
* **Form Data** for traditional web forms
* **Binary** for file uploads
* **Raw Text** for custom content types
## File Detection
The HTTP Request node automatically detects file responses using sophisticated logic:
1. **Content-Disposition analysis** - Checks for `attachment` disposition or filename parameters
2. **MIME type evaluation** - Analyzes content types to distinguish text from binary
3. **Content sampling** - For ambiguous types, samples first 1024 bytes to detect text patterns
Text-based responses (JSON, XML, HTML, etc.) are treated as regular data, while binary content becomes file variables.
## File Operations
The HTTP Request node handles file uploads and downloads seamlessly:
For a workflow design example, see [Example: Content Review Workflow](#example-content-review-workflow).
## Configuration
Configure the following to define how the node requests and processes human input:
* **Delivery method**: How the request form reaches recipients.
* **Form content**: What information recipients will see and what they can interact with.
* **User action**: What decisions recipients can make and how the workflow proceeds accordingly.
* **Timeout strategy**: How long to wait and what happens if no recipient responds.
### Delivery Method
Choose the channel through which the request is delivered. Currently available methods:
* **Web app**: Displays the request form to the web app end user. Not available in workflows started by a Trigger.
External clients can drive the web app form lifecycle through the Service API. See [API Integration Flow](/en/api-reference/guides/human-input-flow).
* **Email**: Sends a request link via email to specific workspace members, external email addresses, or every member of the workspace. Anyone with the link can respond, no Dify account required.
The request closes after the first response regardless of delivery method.
### Form Content
Customize the form recipients see and interact with:
* **Format and structure with Markdown**
Use headings, lists, bold text, links, and other Markdown elements to present information clearly.
* **Display dynamic data with variables**
Reference workflow variables to show dynamic content, such as AI-generated text for review or a file someone uploaded at an upstream Human Input node for approval.
In web app delivery, the form itself displays to end users. Any variables you reference render their values directly in the form, so **no Answer or Output node is needed before the Human Input node**.
Reasoning models emit their thinking process alongside the final answer. Referencing the `text` output variable shows both by default.
To show only the answer, toggle on **Enable Reasoning Tag Separation** for the corresponding LLM node.
* **Collect input with form fields**
Add fields into the request form to capture different types of input from recipients. Each field becomes a variable for downstream use.
For example, in a blog review workflow, you can pass recipient feedback to a downstream LLM node for content revision.
| Field Type | Description |
| :---------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Paragraph | Text input. Can start empty, or pre-filled with variables (e.g., LLM output to refine) or static text (examples or default values). Only Paragraph is optional; Select, Single File, and File List are mandatory. The form's action buttons stay disabled until all mandatory fields are filled.
After the recipient responds, the form content with all values filled in is available downstream as the `__rendered_content` variable. File field values render as plain-text placeholders: `[file]` for Single File and `[N files]` for File List.
### User Action
Define the decision buttons that recipients can click, each routing the workflow to a different execution path.
For example, a `Post` branch might lead to nodes that trigger content publishing, while a `Regenerate` branch might loop back to an LLM node to revise the content.
Each button has a display title and an action ID. When a button is clicked, its ID is exposed downstream as `__action_id` and its title (button text) as `__action_value`.
Use preset button styles to visually distinguish actions.
For example, use a prominent style for key actions like `Approve` and a subtler one for secondary options.
### Timeout Strategy
Configure how long the request stays open before it expires. The default is 3 days.
If no recipient responds before the timeout, the workflow follows the timeout branch from the node. Wire this branch to a fallback path, such as a notification or a retry loop.
If no timeout branch is connected, the workflow ends.
## Example: Content Review Workflow
This workflow drafts a blog post from the `topic` and `language` that a workflow initiator inputs, emails the draft to a reviewer, and finalizes the output based on the reviewer's choice.
It is designed around three things the reviewer should be able to do:
1. **See the AI-generated draft**: Reference the upstream LLM node's `text` variable in the form so the rendered form displays the draft directly.
2. **Edit the draft directly if needed**: Add a Paragraph field named `edits` in the form, pre-filled with the same `text` variable, so the reviewer sees the draft as starting content and can edit in place.
Because blog posts are long, the form's Markdown display (point 1) reads better than a Paragraph field on its own. For shorter content, the pre-filled Paragraph field alone can handle both reading and editing.
3. **Provide feedback for an AI revision**:
1. Add a Paragraph field named `feedback` in the form for the reviewer's feedback.
2. Connect two downstream LLM nodes in sequence:
1. A Regenerate node that takes the original draft `text` and the reviewer's `feedback` to produce a revised draft.
2. A Check Revision node that takes `feedback` and the revised draft to verify whether the revision addresses the feedback. The verified result is what flows downstream.
On the received request form, the reviewer fills the relevant Paragraph fields (or leaves them blank) based on their judgment, then clicks the matching action button. Each action wires to a different output:
* **Approve**: the original draft from the upstream LLM
* **Apply Edit**: the reviewer's edited content from the `edits` field
* **Regenerate**: the revised draft from the downstream LLM pipeline
**System**
```text wrap theme={null}
Write a marketing blog post around the given topic in the specified language.
```
**User**
```text theme={null}
Topic: {{#user_input.topic#}}
Language: {{#user_input.language#}}
```
**System**
```text wrap theme={null}
Regenerate the draft based on user feedback.
```
**User**
```text theme={null}
Draft: {{#generate_draft.text#}}
User Feedback: {{#human_input.feedback#}}
```
**System**
```text wrap theme={null}
Check whether the draft below addresses the user's feedback. Return the draft unchanged if it does; revise it to address the feedback if it doesn't.
```
**User**
```text theme={null}
User Feedback: {{#human_input.feedback#}}
Regenerated Draft: {{#regenerate.text#}}
```
# If-Else
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/ifelse
Add conditional logic and branching to workflows
The If-Else node adds decision-making logic to your workflows by routing execution down different paths based on conditions you define. It evaluates variables and determines which branch your workflow should follow.
**Contains** / **Not contains** - Check if the value includes specific words or phrases
**Starts with** / **Ends with** - Test text beginnings or endings for pattern matching
**Is** / **Is not** - Exact value matching
**Is empty** / **Is not empty** - Check for blank, null, or missing values
**Greater than** / **Less than** - Numerical comparisons for numbers and dates
**Equals** / **Not equals** - Exact matching for any data type
## Complex Conditions
Combine multiple conditions using logical operators for sophisticated decision-making:
**Sequential Processing** - Items processed one after another in order
**Streaming Support** - Results can be output progressively using Answer nodes
**Resource Management** - Lower memory usage, predictable execution order
**Best For** - When order matters or when using streaming output
**Concurrent Processing** - Up to 10 items processed simultaneously
**Improved Performance** - Faster execution for independent operations
**Batch Processing** - Handles large arrays efficiently
**Best For** - Independent operations where order doesn't matter
Parameter extraction effectiveness depends on model capabilities and instruction quality. Use stronger models and provide examples in instructions to improve results.
## Output Processing
Iteration nodes output arrays that often need conversion for final use:
### Convert Array to Text
```python theme={null}
def main(articleSections: list):
return {
"result": "\n".join(articleSections)
}
```
```jinja theme={null}
{{ articleSections | join("\n") }}
```
# Knowledge Retrieval
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/knowledge-retrieval
Retrieve relevant content from knowledge bases and use it as context for downstream nodes
Use the Knowledge Retrieval node to integrate existing knowledge bases into your workflows. The node searches specific knowledge for information relevant to queries and outputs results as contextual content for use in downstream nodes (e.g., LLMs).
Below is an example of using the Knowledge Retrieval node in a Chatflow:
1. The **User Input** node collects the user query.
2. The **Knowledge Retrieval** node searches the selected knowledge base(s) for content related to the user query and outputs the retrieval results.
3. The **LLM** node generates a response based on both the user query and the retrieved knowledge.
4. The **Answer** node returns the LLM's response to the user.
Knowledge retrieval operations are subject to per-minute rate limits that vary by subscription plan. See [Knowledge Request Rate Limit](/en/cloud/use-dify/knowledge/knowledge-request-rate-limit) for the per-plan numbers.
## Configure the Node
To make the Knowledge Retrieval node work properly, you need to specify:
* *What* it should search for (the query)
* *Where* it should search (the knowledge base)
* *How* to process the retrieval results (the node-level retrieval settings)
You can also use document metadata to enable filter-based searches and further improve retrieval precision.
### Specify the Query
Provide the query content that the node should search for in the selected knowledge base(s).
* **Query Text**: Select a text variable. For example, use `userinput.query` to reference user input in Chatflows, or a custom text-type user input variable in Workflows.
* **Query Images**: Select an image variable, e.g., the image(s) uploaded by the user through a User Input node, to search by image. Each image must be 2 MB or smaller.
The **Query Images** option is available only when at least one multimodal knowledge base is added.
Such knowledge bases are marked with the **Vision** tag, indicating that they are using a multimodal embedding model.
### Select Knowledge to Search
Add one or more existing knowledge bases for the node to search for content relevant to the query.
When multiple knowledge bases are added, knowledge is first retrieved from all of them simultaneously, then combined and processed according to the [node-level retrieval settings](#configure-node-level-retrieval-settings).
Knowledge bases marked with the **Vision** tag support cross-modal retrieval: they return both text and images based on semantic relevance.
You can click the **Edit** icon next to any added knowledge base to modify its [settings](/en/cloud/use-dify/knowledge/manage-knowledge/introduction).
### Configure Node-Level Retrieval Settings
To fine-tune how the node processes retrieval results after they are fetched from the knowledge base(s), click **Retrieval Setting**.
Retrieval settings exist at two layers: the knowledge base level and the knowledge retrieval node level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the node settings further rerank the results or narrow down the pool.
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
### Enable Metadata Filtering
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/cloud/use-dify/knowledge/metadata).
## Output
The Knowledge Retrieval node outputs the retrieval results as a variable named `result`, which is an array of retrieved document chunks containing their content, metadata, title, and other attributes.
When the retrieval results contain image attachments, the `result` variable also includes a field named `files` containing image details.
## Use with LLM Nodes
To use the retrieval results as context in an LLM node:
1. In **Context**, select the Knowledge Retrieval node's `result` variable.
2. In the system instruction, reference the `Context` variable.
3. Optional: If the LLM is vision-capable, enable **Vision** so it can process image attachments in the retrieval results.
You don't need to specify the retrieval results as the vision input. Once **Vision** is enabled, the LLM will automatically access any retrieved images.
In chatflows, citations are shown alongside responses that reference knowledge by default. You can turn this off by disabling **[Citation and Attributions](/en/cloud/use-dify/build/additional-features#citations-and-attributions)** in **Features** at the top right corner of the canvas.
# List Operator
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/list-operator
Filter, sort, and select elements from arrays
The List Operator node processes arrays by filtering, sorting, and selecting specific elements. Use it when you need to work with mixed file uploads, large datasets, or any array data that requires separation or organization before downstream processing.
Supported input data types include `array[string]`, `array[number]`, `array[file]`, and `array[boolean]`.
**Type** - Filter by content category: image, document, audio, video
**MIME Type** - Precise content type identification (image/jpeg, application/pdf, etc.)
**Extension** - File extensions (.pdf, .jpg, .mp3, .docx, etc.)
**Size** - File size constraints for processing limits
**Name** - Filename patterns or specific names
**Transfer Method** - Distinguish between local uploads and URL-based files
### Sorting
Organize filtered results by any attribute:
**Ascending (ASC)** - Smallest to largest values, A-Z alphabetical order
**Descending (DESC)** - Largest to smallest values, Z-A reverse order
### Selection
Choose specific elements from the processed array:
**Take First N** - Select the first 1-20 items after filtering and sorting
**First Record** - Return only the first matching element as a single value
**Last Record** - Return only the last matching element as a single value
## Output Variables
**result** - Complete filtered and sorted array for bulk processing
**first\_record** - Single element from the beginning, perfect for "primary" or "latest" item selection
**last\_record** - Single element from the end, useful for "most recent" or "final" selection
## Mixed File Processing Example
Handle workflows where users upload both documents and images:
Configure at least one model provider in **Integrations** > **Model Provider** before using LLM nodes.
## Model Selection and Parameters
Choose from any model provider you've configured. Different models excel at different tasks - GPT-4 and Claude 3.5 handle complex reasoning well but cost more, while GPT-3.5 Turbo balances capability with affordability.
User-friendly interface for simple structures. Add fields with names and types, mark required fields, set descriptions. The editor generates JSON Schema automatically.
Write schemas directly for complex structures with nested objects, arrays, and validation rules.
```json theme={null}
{
"type": "object",
"properties": {
"sentiment": {
"type": "string",
"enum": ["positive", "negative", "neutral"]
}
},
"required": ["sentiment"]
}
```
Describe needs in plain language and let AI generate the schema.
Models with native JSON support handle structured outputs reliably. For others, Dify includes the schema in prompts, but results may vary.
## Memory and File Processing
... ` tags inside their response. By default, those tags are included in the `text` output, so the reasoning flows downstream together with the answer.
Turn on the **Enable reasoning tag separation** toggle to split them: the `text` output keeps only the answer, and the thinking moves to a separate `reasoning_content` output variable. While the toggle is off, `reasoning_content` stays empty.
In API calls, this toggle appears as the `reasoning_format` parameter. When the toggle is on, `reasoning_format` is `separated`, and streaming API clients receive the reasoning as dedicated `reasoning_chunk` events, outside the answer stream. For event details, see [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) and [Run Workflow](/en/api-reference/workflow-runs/run-workflow).
This setting affects only models that wrap their reasoning in `` tags.
## Error Handling
Configure retry behavior for failed LLM calls. Set maximum retry attempts, intervals between retries, and backoff multipliers. Define fallback strategies like default values, error routing, or alternative models when retries aren't sufficient.
# Loop
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/loop
Execute repetitive workflows with progressive refinement
The Loop node executes repetitive workflows where each cycle builds on the results of the previous one. Unlike iteration, which processes array elements independently, loops create progressive workflows that evolve with each repetition.
## Loop vs Iteration
Understanding when to use each repetition pattern:
**Sequential Processing** - Each cycle depends on previous results
**Progressive Refinement** - Outputs improve or evolve over iterations
**State Management** - Variables persist and accumulate across cycles
**Use Cases** - Content refinement, problem solving, quality assurance
**Independent Processing** - Each item processed separately
**Parallel Execution** - Items can be processed simultaneously
**Batch Operations** - Same operation applied to multiple data points
**Use Cases** - Data transformation, bulk processing, parallel analysis
## Configuration
### Loop Variables
Define variables that persist across loop iterations and remain accessible after the loop completes. These variables maintain state and enable progressive workflows.
### Termination Conditions
Configure when the loop should stop executing:
**Loop Termination Condition** - Expression that determines when to exit (e.g., `quality_score > 0.9`)
**Maximum Loop Count** - Safety limit to prevent infinite loops
**Exit Loop Node** - Immediate termination when this node is reached
The loop terminates when either the termination condition is met, the maximum count is reached, or an Exit Loop node executes. If no conditions are specified, the loop continues until the maximum count.
## Basic Loop Example
Generate random numbers until finding one less than 50:
The Output node was previously named *End* and was required in every workflow.
It is now optional—workflows run successfully without one, but any workflow or branch without an Output node returns no data to the caller.
Output nodes are only available in Workflows. Chatflows use the [Answer](/en/cloud/use-dify/nodes/answer) node instead.
## Configure Output Variables
Each Output node requires at least one output variable. To add a variable, assign a name and select the source from any upstream node's output.
The variable name you assign becomes the key in API responses.
You can add multiple output variables to a single Output node and reorder them by dragging.
## Supported Variable Types
Output variables support the following types:
`string`, `number`, `integer`, `boolean`, `object`, `file`, `array[string]`, `array[number]`, `array[object]`, `array[boolean]`, `array[file]`
## Multiple Output Nodes
A workflow can contain more than one Output node. The Output node does not stop workflow execution—other parallel branches (if any) continue running after it completes.
All output variables from every executed Output node are combined into one final result. Each Output node adds its variables to the result as the workflow reaches it:
* On the **same branch**, variables are added in the order the Output nodes are placed.
* On **parallel branches**, whichever Output node executes first adds its variables first.
Always use unique variable names across all Output nodes in a workflow.
When two Output nodes use the same output variable name, the later one overwrites the earlier value.
## API Response Structure
When you call a workflow through the API, output variables appear in the `outputs` object of the response.
All outputs return in a single response once the workflow completes:
```json theme={null}
{
"workflow_run_id": "...",
"status": "succeeded",
"outputs": {
"result_text": "The processed output...",
"score": 95
}
}
```
Outputs arrive in the final `workflow_finished` event:
```json theme={null}
{
"event": "workflow_finished",
"data": {
"outputs": {
"result_text": "The processed output...",
"score": 95
}
}
}
```
Each output variable name maps directly to a key in the `outputs` object.
## For Workflow Tools
When you [publish a workflow as a tool](/en/cloud/use-dify/workspace/tools#workflow), the Output node defines the tool's return schema. Each output variable name becomes a key in the tool's result, accessible to the parent workflow that invokes the tool.
# Parameter Extractor
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/parameter-extractor
Convert natural language to structured data using LLM intelligence
The Parameter Extractor node converts unstructured text into structured data using LLM intelligence. It bridges the gap between natural language input and the structured parameters that tools, APIs, and other workflow nodes require.
## Configuration
### Input and Model Selection
Select the **Input Variable** containing the text you want to extract parameters from. This typically comes from user input, LLM responses, or other workflow nodes.
Choose a **Model** with strong structured output capabilities. The Parameter Extractor relies on the LLM's ability to understand context and generate structured JSON responses.
### Parameter Definition
Define the parameters you want to extract by specifying:
* **Parameter Name** - The key that will appear in the output JSON
* **Data Type** - String, number, boolean, array, or object
* **Description** - Helps the LLM understand what to extract
* **Required Status** - Whether the parameter must be present
You can manually define parameters or **quickly import from existing tools** to match the parameter requirements of downstream nodes.
### Extraction Instructions
Write clear instructions describing what information to extract and how to format it. Providing examples in your instructions improves extraction accuracy and consistency for complex parameters.
Chatflows always start with User Input. Only Workflows can use triggers.
## Trigger
Use a [trigger](/en/cloud/use-dify/nodes/trigger/overview) when the workflow should run automatically, without anyone invoking it. Three types are available:
* **[Schedule Trigger](/en/cloud/use-dify/nodes/trigger/schedule-trigger)**: runs at specified times or intervals.
* **[Integration Trigger](/en/cloud/use-dify/nodes/trigger/plugin-trigger)**: runs when an event occurs in an external system, via a subscription through a trigger integration.
* **[Webhook Trigger](/en/cloud/use-dify/nodes/trigger/webhook-trigger)**: runs when the workflow receives an HTTP request from an external system.
## Switch Between Start Nodes
User Input and triggers are mutually exclusive on a canvas. To switch, right-click the current start node and select **Change Node**, or delete it and add a new one.
# Template
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/template
Transform and format data using Jinja2 templating
The Template node transforms and formats data from multiple sources into structured text using Jinja2 templating. Use it to combine variables, format outputs, and prepare data for downstream nodes or end users.
` | `data-format` | Container for form fields.` | `for` | Renders the inner text as a field label.` before its field in the source so it appears above. |
| `` | `name`, `placeholder`, `value` | Multi-line text input. |
| `<button>` | `data-variant`, `data-size` | Submits the form. <ul><li>Variants: `primary`, `warning`, `secondary`, `secondary-accent`, `ghost`, `ghost-accent`, `tertiary`.</li><li>Sizes: `small`, `medium`, `large`.</li></ul>Values outside these lists are ignored and the button falls back to the default styling.<br /><br />Ignores `data-message` and `data-link`, which only apply to [quick-reply buttons](#quick-reply-buttons). |
<Note>
Do not leave blank lines between tags inside `<form>`. A blank line ends the HTML block during markdown parsing, and any tags after the break will fail to render as form fields.
</Note>
### Supported Input Types
| `type` value | Renders as | Submitted as |
| :------------------------------------ | :------------------------------------------------------------------- | :----------------------------------------------------------- |
| `text`, `password`, `email`, `number` | Single-line input with matching HTML semantics | String |
| `date` | Date picker | ISO date string (e.g., `2026-01-10`) |
| `datetime` | Date picker with time selection | ISO date-time string (e.g., `2026-01-10T14:30:00.000+08:00`) |
| `time` | Time picker | String (includes a full date prefix, not just the time) |
| `checkbox` | Checkbox followed by the `data-tip` text as a label | Boolean (`true` or `false`) |
| `select` | Dropdown built from the `data-options` JSON array of strings | Selected option string |
| `hidden` | Renders as an `<input type="hidden">` element; not visible in the UI | String |
* Any other `type` value renders an "Unsupported tag" fallback in place of the field.
* HTML5 validation attributes such as `required`, `min`, `max`, and `pattern` are not enforced.
* Browsers may autofill `<input type="password">` and `<input type="email">` with saved credentials for the current site; use `<input type="text">` for fields that should not be prefilled.
### Quick-Reply Buttons
A standalone `<button>` placed outside any `<form>` renders as a clickable button in the chat. Use these to offer canned responses or external links inline with the assistant's message. For example:
```html wrap theme={null}
Would you like to see more options?
<button data-variant="primary" data-message="Yes, show me more">Yes</button> <button data-variant="secondary" data-message="No, that is enough">No</button> <button data-variant="secondary-accent" data-link="https://docs.dify.ai">Read the docs</button>
```
<Frame>
<img alt="Quick Reply Button" />
</Frame>
| Attribute | Click behavior |
| :------------- | :-------------------------------------------------- |
| `data-message` | Sends the text as the end user's next chat message. |
| `data-link` | Opens the URL in a new tab. Must be a valid URL. |
If both are set, `data-link` takes precedence. A button with neither renders but performs no action when clicked.
Apply `data-variant` and `data-size` for styling, using the same values listed for [form buttons above](#supported-tags).
<Note>
Unlike form buttons, standalone buttons pass `data-variant` and `data-size` through to the underlying component without validation. An unrecognized value can leave the button rendered as plain text rather than a styled button.
Use only the values listed above.
</Note>
## Output Limits
Template output is limited to **400,000 characters**. This prevents memory issues and ensures reasonable processing times for large template outputs.
# Tool Node
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/tools
Connect to external services and APIs
Add [Dify tools](/en/cloud/use-dify/workspace/tools) to your workflows as standalone nodes.
This lets your workflows interact with external services and APIs to access real-time data and perform actions, like web searches, database queries, or content processing.
**To add and configure a tool node**:
1. On the canvas, click **Add Node** > **Tools**, then select an action from an available tool.
2. Optional: If a tool requires authentication, select an existing credential or create a new one.
<Info>
To change the default credential, go to **Integrations** > **Tools** > **Tool Plugin**.
</Info>
3. Complete any other required tool settings.
# Trigger
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/trigger/overview
<Info>
Triggers are available for Workflow applications only.
</Info>
A trigger is a type of Start node that lets your workflow run automatically on a schedule or in response to events from external systems (such as GitHub, Gmail, or your own internal systems), rather than waiting for active initiation from a user or an API call.
Use triggers to automate repetitive tasks or synchronize data with third-party applications.
A workflow can have multiple triggers running in parallel. You can also build several independent workflows on the same canvas, each starting with its own triggers.
<Info>
Sandbox accounts are limited to 2 triggers per workflow. Higher trigger counts are available on <Badge>Professional</Badge> and <Badge>Team</Badge>. [Learn more](https://dify.ai/pricing).
</Info>
The trigger source for each workflow execution is displayed in the **Logs** section.
<Info>
Trigger events (workflow executions initiated by triggers) are subject to a monthly quota that varies by plan. For per-plan limits, see the [Plan Comparison](https://dify.ai/pricing). The workspace owner and admins can check the remaining quota in **Settings** > **Billing**.
</Info>
## Trigger Types
* [Schedule Trigger](/en/cloud/use-dify/nodes/trigger/schedule-trigger)
* Runs your workflow at specified times or intervals.
* Example: Automatically generate a daily sales report every morning at 9 AM and email it to your team.
<Info>
Each workflow can have at most one schedule trigger.
</Info>
* [Integration Trigger](/en/cloud/use-dify/nodes/trigger/plugin-trigger)
* Runs your workflow when a specific event occurs in an external system, via an event subscription through a trigger integration.
* Example: Automatically analyze and archive new messages in a specific Slack channel via a subscription to the `New Message in Channel` event through a Slack trigger integration.
* [Webhook Trigger](/en/cloud/use-dify/nodes/trigger/webhook-trigger)
* Runs your workflow when a specific event occurs in an external system via a custom webhook.
* Example: Automatically process new orders in response to an HTTP request containing the order details from your e-commerce platform.
<Tip>
Both integration triggers and webhook triggers make your workflow *event-driven*. Here's how to choose:
1. Use an **integration trigger** when a trigger integration is available for your target external system. You can simply subscribe to the supported events.
2. Use a **webhook trigger** when no trigger integration exists or when you need to capture events not covered by available trigger integrations. In such cases, you'll need to set up custom webhooks in the external system.
</Tip>
## Enable or Disable Triggers
To pause a published trigger, open the app's **Access Point** tab and switch it off on the **Trigger** card. While a trigger is off, its events are ignored.
<Note>
Only published triggers appear on the **Trigger** card. If you don't see an added trigger listed, ensure it has been published first.
</Note>
## Test Multiple Triggers
When a workflow has multiple triggers, you can click **Test Run** > **Run all triggers** to test them at once. The first trigger that activates will initiate the workflow, and the others will then be ignored.
After you click **Run all triggers**:
* Schedule triggers will run at the next scheduled execution time.
* Integration triggers will listen for subscribed events.
* Webhook triggers will listen for external HTTP requests.
# Integration Trigger
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/trigger/plugin-trigger
<Info>
Triggers are available for Workflow applications only.
</Info>
An Integration Trigger starts your workflow automatically when a specific event occurs in an external system. You subscribe to those events through an integration, then add the matching trigger to your workflow.
For example, after installing a GitHub trigger integration, you can subscribe to events such as `Pull Request`, `Push`, and `Issue`. Subscribe to `Pull Request` and add its trigger, and the workflow runs whenever someone opens a pull request in the chosen repository.
## Add and Configure an Integration Trigger
1. On the workflow canvas, right-click and select **Add Node** > **Start**, then choose the integration trigger event you want to start the workflow. To find more integrations, search the [Marketplace](https://marketplace.dify.ai/?language=en-US\&category=trigger).
<Tip>
* If no integration exists for your target system, [request one](https://github.com/langgenius/dify-plugins/issues/new?template=plugin_request.yaml), [build one yourself](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin), or use a [Webhook Trigger](/en/cloud/use-dify/nodes/trigger/webhook-trigger) instead.
* A workflow can have multiple Integration Triggers. If their branches share downstream nodes, add a [Variable Aggregator](/en/cloud/use-dify/nodes/variable-aggregator) to converge them.
</Tip>
2. Select an existing subscription or [create a new one](/en/cloud/use-dify/nodes/trigger/plugin-trigger#create-a-subscription). The trigger needs a subscription to receive events.
3. Configure any other required settings.
<Info>
The output variables of an integration trigger are defined by the integration and can't be modified.
</Info>
## Create a Subscription
A subscription is a webhook that listens for events from an external system. Each integration supports up to 10 subscriptions per workspace.
<Accordion title="What is a webhook?">
A webhook lets one system send real-time data to another. When an event occurs, the source system packages the details into an HTTP request and sends it to a URL the destination system provides.
</Accordion>
Dify supports two ways to create a subscription, depending on what the integration supports.
* **Automatic**: You pick the events to subscribe to, and Dify creates the webhook in the external system for you. This requires prior authorization, through OAuth or an API key, so Dify can set it up on your behalf.
* **Manual**: You create the webhook yourself using the callback URL Dify provides. No authorization needed.
<Tabs>
<Tab title="OAuth (Automatic)">
On Dify Cloud, many popular trigger integrations are pre-configured with default OAuth clients, so you can authorize in one click without registering your own OAuth application. To use your own OAuth application instead, choose **Custom**.
**Default**
1. Select **Create with OAuth** > **Default**, then click **Save and Authorize**.
2. On the authorization page that opens, grant Dify access.
3. Name the subscription, select the events to subscribe to, and configure any other required settings.
<Tip>
Subscribe to all available events. A trigger only fires for events its subscription covers, so a broad subscription can be reused by any trigger you add later instead of creating new ones.
</Tip>
4. Click **Create**.
**Custom**
1. Select **Create with OAuth** > **Custom**.
2. In the external system, create an OAuth application using the callback URL Dify provides.
3. Back in Dify, enter the application's client ID and client secret, then click **Save and Authorize**.
<Info>Once saved, the same credentials can be reused for future subscriptions.</Info>
4. Name the subscription, select the events to subscribe to, and configure any other required settings.
<Tip>
Subscribe to all available events. A trigger only fires for events its subscription covers, so a broad subscription can be reused by any trigger you add later instead of creating new ones.
</Tip>
5. Click **Create**.
</Tab>
<Tab title="API Key (Automatic)">
1. Select **Create with API Key**.
2. Enter the required authentication details, then click **Verify**.
3. Name the subscription, select the events to subscribe to, and configure any other required settings.
<Tip>
Subscribe to all available events. A trigger only fires for events its subscription covers, so a broad subscription can be reused by any trigger you add later instead of creating new ones.
</Tip>
4. Click **Create**.
</Tab>
<Tab title="Paste URL to create a new subscription (Manual)">
1. Select **Paste URL to create a new subscription**.
2. Name the subscription and use the callback URL Dify provides to create a webhook in the external system.
3. (Optional) Test it: trigger a subscribed event, then check the **Request Logs** at the bottom of the **Manual Setup** page for the received request and Dify's response.
<Frame>
<img alt="Request Logs" />
</Frame>
4. Click **Create**.
</Tab>
</Tabs>
## Manage Subscriptions
Manage an integration's subscriptions from **Integrations** > **Trigger**. Open the integration to see its subscriptions, including how many workflows use each one, and to edit or delete them.
## Test an Integration Trigger
To test an unpublished trigger, first click **Run this step** or test-run the whole workflow. This puts the trigger into a listening state so it can capture subscribed events; otherwise events are ignored even when they occur.
# Schedule Trigger
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/trigger/schedule-trigger
<Info>
* Triggers are available for Workflow applications only.
* Each workflow can have at most one schedule trigger.
</Info>
Schedule triggers enable your workflow to run at specified times or intervals. They are ideal for recurring tasks like generating daily reports or sending scheduled notifications.
## Add a Schedule Trigger
On the workflow canvas, right-click and select **Add Node** > **Start** > **Schedule Trigger**.
## Configure a Schedule Trigger
You can configure the schedule using either the default visual picker or a cron expression.
After configuration, you can see the next 5 scheduled execution times.
<Info>
Schedule triggers do not produce output variables, but they update the system variable `sys.timestamp` (the start time of each workflow execution) each time they initiate the workflow.
</Info>
### With the Visual Picker
Use this for simple hourly, daily, weekly, or monthly schedules. For weekly and monthly frequencies, you can select multiple days or dates.
### With a Cron Expression
Use this for more complex and precise timing patterns, such as every 15 minutes from 9 AM to 5 PM on weekdays.
<Tip>
You can use LLMs to generate cron expressions.
</Tip>
#### Standard Format
A cron expression is a string that defines the schedule for executing your workflow. It consists of five fields separated by spaces, each representing a different time unit.
<Note>
Ensure that there is a single space between each field.
</Note>
```
* * * * *
| | | | |
| | | | |── Day of week (0-7 or SUN-SAT, where both 0 and 7 = Sunday)
| | | |──── Month (1-12 or JAN-DEC)
| | |────── Day of month (1-31)
| |──────── Hour (0-23)
|────────── Minute (0-59)
```
<Info>
When both the **day-of-month** and **day-of-week** fields are specified, the trigger activates on dates that match *either* field.
For example, `1 2 3 4 4` will trigger your workflow on the 3rd of April *and* every Thursday in April, not just on Thursdays that fall on the 3rd.
</Info>
#### Special Characters
| Character | Description | Example |
| :-------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `*` | Means "every". | `*` in the **hour** field means "every hour". |
| `,` | Separates multiple values. | `1,3,5` in the **day-of-week** field means "Monday, Wednesday, and Friday". |
| `-` | Defines a range of values. | `9-17` in the **hour** field means "from 9 AM to 5 PM". |
| `/` | Specifies step values. | `*/15` in the **minute** field means "every 15 minutes". |
| `L` | Means "the last". <br /><br />In the **day-of-month** field, means "the last day of the month".<br /><br />In the **day-of-week** field:<ul><li>When used alone, means "the last day of the week".</li><li>When combined with a number, means "the last occurrence of that weekday in the month". </li></ul> | `L` in the **day-of-month** field means "Jan 31, April 30, or Feb 28 in a non-leap year".<br /><br />`L` in the **day-of-week** field means Sunday.<br /><br />`5L` in the **day-of-week** field means "the last Friday of the month". |
| `?` | Means "any" or "no specific value".<br /><br />If you specify a value for the **day-of-week** field, you can use `?` for the **day-of-month** field to ignore it, and vice versa.<br /><br />Not required, because `*` works as well. | To run a task every Monday, it's more precise to set the **day-of-month** field to `?` instead of `*`. |
#### Predefined Expressions
* `@yearly`: Run once a year at 12 AM on January 1.
* `@monthly`: Run once a month at 12 AM on the first day of the month.
* `@weekly`: Run once a week at 12 AM on Sunday.
* `@daily`: Run once a day at 12 AM.
* `@hourly`: Run at the beginning of every hour.
#### Examples
| Schedule | Cron Expression |
| :-------------------------------------- | :--------------------------------- |
| Weekdays at 9 AM | `0 9 * * MON-FRI` or `0 9 * * 1-5` |
| Every Wednesday at 2:30 PM | `30 14 * * WED` |
| Every Sunday at 12 AM | `0 0 * * 0` |
| Every 2 hours on Tuesday | `0 */2 * * 2` |
| The first day of every month at 12 AM | `0 0 1 * *` |
| At 12 PM on January 1 and June 1 | `0 12 1 JAN,JUN *` |
| The last day of every month at 5 PM | `0 17 L * *` |
| The last Friday of every month at 10 PM | `0 22 * * 5L` |
## Test a Schedule Trigger
* **Run this step**: The schedule trigger runs immediately, ignoring the configured schedule.
* **Test Run**: The schedule trigger waits for its next scheduled execution time.
# Webhook Trigger
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/trigger/webhook-trigger
<Info>
Triggers are available for Workflow applications only.
</Info>
A webhook allows one system to automatically send real-time data to another. When a certain event occurs, the source system packages the event details into an HTTP request and sends it to a designated URL provided by the destination system.
Following the same mechanism, webhook triggers enable your workflow to run in response to third-party events. Here's how you work with it:
1. When you add a webhook trigger to your workflow, Dify generates a unique webhook URL that listens for external HTTP requests. This URL is hosted on the Dify Cloud domain and is publicly reachable by external systems.
2. You use this URL to create a webhook subscribing to the events you want to monitor in an external system. Then you configure the webhook trigger to define how it processes incoming requests and extracts request data.
<Note>
For testing purposes, always use the test webhook URL to keep test data separate from production data.
<Frame>
<img alt="Test Webhook URL" />
</Frame>
</Note>
3. When a subscribed event occurs, the external system sends an HTTP request with the event data to that provided webhook URL. Once the request is received and processed successfully, your workflow is triggered, and the specified event data is extracted into variables that can be referenced by downstream nodes.
<Tip>
If there's a ready-made trigger integration for your target external system, consider using an [Integration Trigger](/en/cloud/use-dify/nodes/trigger/plugin-trigger) instead.
</Tip>
## Add a Webhook Trigger
On the workflow canvas, right-click and select **Add Node** > **Start** > **Webhook Trigger**.
<Tip>
A workflow can have multiple webhook triggers. If these trigger branches share identical downstream nodes, add a [Variable Aggregator](/en/cloud/use-dify/nodes/variable-aggregator) to converge them and avoid duplicating those nodes on each branch.
</Tip>
## Configure a Webhook Trigger
You can define how a webhook trigger handles incoming HTTP requests, including:
* The expected HTTP method for the webhook URL
* The request's content-type
* The data you wish to extract from the request
* The response sent back to the external system when your workflow is successfully triggered
<Note>
To test an unpublished webhook trigger, make sure to click **Run this step** or test-run the entire workflow first. This puts the trigger into a listening state so that it can receive external requests. Otherwise, no request will be captured.
</Note>
### HTTP Method
To ensure the incoming request can be received successfully, you need to specify which HTTP method the webhook URL accepts.
The method you select here must match the one used by the external system to send requests; otherwise, the requests will be rejected.
<Tip>
You can typically find this information in the external system's webhook documentation or setup interface.
</Tip>
### Content-Type
To ensure the request body can be properly parsed and the data you need extracted, you need to specify the expected content type of the incoming request.
The content-type you select here must match the content type of the request sent from the external system; otherwise, the request will be rejected.
### Query Parameters, Header Parameters, and Request Body Parameters
You can extract specific data from the query parameters, headers, and body of the incoming request. **Each extracted parameter becomes an output variable that can be used in your workflow.**
Some external systems provide a delivery log for each request, where you can view all the data included in the request and decide which parameters to extract.
Alternatively, you can send a test request to the webhook trigger and check the received request data in its last run logs:
1. Create a webhook in the external system using the provided test webhook URL.
2. Set the correct HTTP method and content-type in the trigger.
3. Click the **Run this step** icon. The trigger will start listening for external requests.
4. Trigger the subscribed event in the external system so it sends an HTTP request to the provided webhook URL.
5. Go to the trigger's **Last Run** tab and check the received request data in **Input**.
<Note>
The variable name you define in the trigger must match the key name of the corresponding parameter in the request.
</Note>
<Tabs>
<Tab title="Query Parameters">
* Parameters in key-value pairs added to the webhook URL (after `?`) by external systems when sending requests, each pair separated by `&`.
* Typically simple, non-sensitive identifiers or filter data about the event.
* Example: From the URL `{webhook url}?userID=u-456&source=email`, you can extract the `userID` (`u-456`) or the `source` (`email`).
</Tab>
<Tab title="Header Parameters">
* Request metadata included in the request headers.
* Technical information needed for processing the request, such as an authentication token or the request body's data format.
* Example: From headers like `Authorization: Bearer sk-abc... `and `Content-Type: application/json`, you can extract the authorization information (`Bearer sk-abc...`) or the content-type (`application/json`).
</Tab>
<Tab title="Request Body Parameters">
* The main payload where the core event data is sent, such as a customer profile, order details, or the content of a Slack message.
* Example: From the following request body, you can extract the `customerName` (`Alex`), the list of items, or the `isPriority` status (`true`).
```json theme={null}
"customerName": "Alex",
"items":
[
{ "sku": "A42", "quantity": 2 },
{ "sku": "B12", "quantity": 1 }
],
"isPriority": true
```
<Info>
The content-type determines which data types can be extracted from the request body.
| Content-Type | `String` | `Number` | `Boolean` | `Object` | `File` | `Array[String]` | `Array[Number]` | `Array[Boolean]` | `Array[Object]` | `Array[File]` |
| :-------------------------------- | :------: | :------: | :-------: | :------: | :----: | :-------------: | :-------------: | :--------------: | :-------------: | :-----------: |
| application/json | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ |
| application/x-www-form-urlencoded | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ |
| multipart/form-data | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ |
| text/plain | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
</Info>
</Tab>
</Tabs>
**Parameter Settings**
For each parameter to be extracted, you can specify the following:
* **Variable Name**: The key name of the parameter in the incoming request (e.g., `userID` in `userID=u-456`).
<Note>
For header parameters, any hyphen (`-`) in the variable name will be automatically converted to an underscore (`_`) in the output variable.
</Note>
* **Data Type**: The expected data format. Available for query and request body parameters only, as header parameters are always treated as strings.
* **Required**: Whether the parameter is required for your workflow to execute properly. If any required parameter is missing from an incoming request, your workflow will not be triggered.
### Response
When your workflow is successfully triggered by an external HTTP request, a default `200 OK` response is sent back to the external system.
If the external system requires a specific success response format, you can customize the status code and response body. The default one will be overridden.
* **Status Code**: Supports any status code in the range \[200, 399].
* **Response Body**: Supports JSON or plain text.
<Note>
In the returned response body, non-JSON content will be automatically converted to JSON.
For example, `OK` will be wrapped as `"message": "OK"`.
</Note>
<Info>
The following error responses are system-defined and cannot be customized. Error details can be found in the response body.
* 400 Bad Request
* 404 Not Found
* 413 Payload Too Large
* 500 Internal Server Error
</Info>
## Test a Webhook Trigger
To test an unpublished webhook trigger, you must first click **Run this step** or test-run the entire workflow. This puts the trigger into a listening state so that it can receive external requests. Otherwise, incoming requests will not be captured.
# User Input
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/user-input
Collects user inputs to start Workflow and Chatflow applications
The User Input node allows you to define what to collect from end users as inputs for your applications.
Applications that start with this node run *on demand* and can be initiated by direct user interaction or API calls.
You can also publish these applications as standalone web apps or MCP servers, expose them through backend service APIs, or use them as tools in other Dify applications.
<Info>
Each application canvas can contain only one User Input node.
</Info>
## Input Variable
### Preset
Preset input variables are system-defined and available by default.
* `userinput.files`: Files uploaded by end users when they run the application.
<Note>
For Workflow applications, this preset variable has been considered *legacy* and kept only for backward compatibility.
We recommend using a [custom file input field](#file-input) instead to collect user files.
</Note>
* `userinput.query` (for chatflows only): The text message automatically captured from the user's latest chat turn.
### Custom
You can configure custom input fields in a User Input node to collect different kinds of user input. Each field becomes a variable that can be referenced by downstream nodes.
<Info>
**Label Name** is displayed to your end users.
</Info>
<Tip>
If a field's value is something you already know (like a product identifier or tenant ID) and doesn't have to come from end users, mark it as **Hidden & Pre-Filled** and supply it yourself. See [Hide and Pre-Fill Input Fields](#hide-and-pre-fill-input-fields) for details.
</Tip>
#### Text Input
<Tabs>
<Tab title="Short Text">
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
</Tab>
<Tab title="Paragraph">
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed responses or descriptions.
</Tab>
</Tabs>
#### Structured Input
<Tabs>
<Tab title="Select">
Displays a dropdown menu with predefined options. Users can choose only from listed options, ensuring data consistency and preventing invalid inputs.
</Tab>
<Tab title="Number">
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
</Tab>
<Tab title="Checkbox">
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
</Tab>
<Tab title="JSON Code">
Accepts data in JSON object format, ideal for passing complex, nested data structures into your application.
You can optionally define a JSON schema to validate the input and guide end users on the expected structure and validation requirements. This also allows you to reference individual properties of the object in other nodes.
</Tab>
</Tabs>
#### File Input
<Tabs>
<Tab title="Single File">
Allows users to upload one file of any supported type, either from their device or via a file URL. The uploaded file is available as a variable containing file metadata (name, size, type, etc.).
</Tab>
<Tab title="File List">
Supports multiple file uploads at once. It's useful for handling batches of documents, images, or other files together.
<Tip>
Use a List Operator node to filter, sort, or extract specific files from the uploaded file list for further processing.
</Tip>
</Tab>
</Tabs>
**File Processing**
Since the User Input node only collects files—it does not read or parse their content—uploaded files must be processed appropriately by subsequent nodes. For example:
* Document files can be routed to a Doc Extractor node for text extraction so that LLMs can understand their content.
* Images can be sent to LLM nodes with vision capabilities or specialized image processing tool nodes.
* Structured data files such as CSV or JSON can be processed with Code nodes to parse and transform the data.
<Tip>
When users upload multiple files with mixed types (e.g., images and documents), you can use a List Operator node to separate them by file type before routing them to different processing branches.
</Tip>
## Hide and Pre-Fill Input Fields
Sometimes the workflow needs an input you already know, and asking end users to type it would be friction. Mark such a field as **Hidden & Pre-Filled**: you supply the value, end users never see the field, and the workflow still receives it.
Imagine your company runs landing pages for many different products, each featuring an AI chatbot. The workflow behind every chatbot is essentially the same; only the product identifier differs.
Rather than maintain a separate workflow per product, you keep just one (with a hidden `productName` field) and pre-fill a different value on each landing page. End users perceive each page as having its own product-specific chatbot, but behind the scenes, every page passes a different `productName` into the same workflow.
<Warning>
Hidden fields are **not secret**. Values travel in the URL query string and are visible in the browser address bar, browser history, and network traffic. For credentials and API keys, use [Environment Variables](/en/learn/key-concepts#variables) instead.
</Warning>
<Info>
Single File and File List fields do not support this feature.
</Info>
<Steps>
<Step title="Enable the Feature">
1. In the **Edit Input Field** window, uncheck **Required** if it's checked. These two options are mutually exclusive.
2. Check **Hidden & Pre-Filled**. Optionally set a default value as a fallback when no value is pre-filled at runtime.
Hidden fields still appear in the **Preview** panel so you can test the flow without publishing.
</Step>
<Step title="Pre-Fill the Field">
1. Publish your app.
2. Choose the method that fits how your end users reach the app.
<Tabs>
<Tab title="Shareable Link">
Use this when end users open the web app directly from its link.
1. In the app's publishing panel, within the **Web App** section, click the gear icon next to **Launch**.
<Frame>
<img alt="Hidden Fields Pre-Fill Icon" />
</Frame>
2. Fill in the hidden fields and click **Launch**. The web app opens with your values applied as URL query parameters; copy the URL from the address bar to share.
**To generate many links with different values**, use the same pattern to write more yourself, or have a system fill in the values automatically:
```text wrap theme={null}
{WEBAPP_URL}?{VARIABLE_NAME}={VALUE}&{VARIABLE_NAME}={VALUE}
# Example: https://udify.app/chat/abc123?productName=Acme®ion=us-east
```
<Note>
URL-encode any values that contain spaces or special characters (for example, `Acme Corp` becomes `Acme%20Corp`).
</Note>
<Accordion title="Example: A CRM Auto-Fills the Customer ID">
A support team using a CRM can add `?customerId={{customer.id}}` to the end of the web app URL in their ticket-response templates.
The CRM substitutes the real customer ID when the rep sends the link, so the chatbot knows which customer it's talking to without having to ask.
</Accordion>
</Tab>
<Tab title="Embed on Your Site">
Use this when the app is embedded as an iframe or script on your site.
<Tabs>
<Tab title="Same Value for Every Visitor">
Use this when every visitor should receive the same values (a site-wide region, the embedded page's product ID, etc.).
1. In the app's publishing panel, within the **Web App** section, click **Embedded** > **Pre-Fill Hidden Fields**.
<Frame>
<img alt="Embedded Icon" />
</Frame>
2. Fill in the hidden fields. Entered values are baked into the iframe URL and the `inputs` object of the script snippet.
</Tab>
<Tab title="Different Value Per Visitor">
Use this when each visitor should receive their own values (the logged-in user's ID, the page they're on, etc.).
In the embed snippet on your site, set each hidden field as a key in the `inputs` object of `window.difyChatbotConfig`. Each value is computed at render time from your site's context, so every visitor gets their own.
```html theme={null}
<script>
window.difyChatbotConfig = {
token: 'YOUR_TOKEN',
inputs: {
productName: getCurrentProduct(), // from the current page
tenantId: getCurrentTenant(), // from your auth system
},
};
</script>
```
</Tab>
</Tabs>
</Tab>
</Tabs>
</Step>
</Steps>
# Variable Aggregator
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/variable-aggregator
Converge exclusive workflow branches into a single output
Use the Variable Aggregator node to converge **exclusive** workflow branches into a single output, so you only need to define downstream processing once.
Nodes like If/Else and Question Classifier create exclusive branches—only one path executes per run. When these branches produce the same type of output, you would normally duplicate downstream nodes on every branch.
The Variable Aggregator eliminates this duplication. It provides a single output variable for downstream nodes to reference, regardless of which branch ran.
<Frame>
<img alt="Without Variable Aggregator" />
</Frame>
<Frame>
<img alt="With Variable Aggregator" />
</Frame>
<Note>
The Variable Aggregator is designed for exclusive branches where **only one path runs at a time**. It does not combine outputs from multiple branches that execute in parallel.
To merge results from parallel branches, use a [Code](/en/cloud/use-dify/nodes/code) or [Template](/en/cloud/use-dify/nodes/template) node.
</Note>
## Select the Variables to Converge
From each branch, add variables that need the same downstream processing. All variables must share the same data type.
Supported types: `string`, `number`, `object`, `boolean`, `array`, `file`.
The node outputs whichever variable has a value at runtime. Since only one branch executes, only one variable will have a value, and that value becomes the node's output.
## Converge Multiple Sets of Variables
When you have multiple sets of variables that each need to be converged separately, enable **Aggregation Group** to create groups within a single Variable Aggregator.
Each group converges its own set of variables and produces a separate output.
# Variable Assigner
Source: https://docs.dify.ai/en/cloud/use-dify/nodes/variable-assigner
Manage persistent conversation variables in Chatflow applications
The Variable Assigner node manages persistent data in Chatflow applications by writing to conversation variables (Understand the different types of variables [here](/en/learn/key-concepts#variables)). Unlike regular workflow variables that reset with each execution, conversation variables persist throughout an entire chat session.
<Frame>
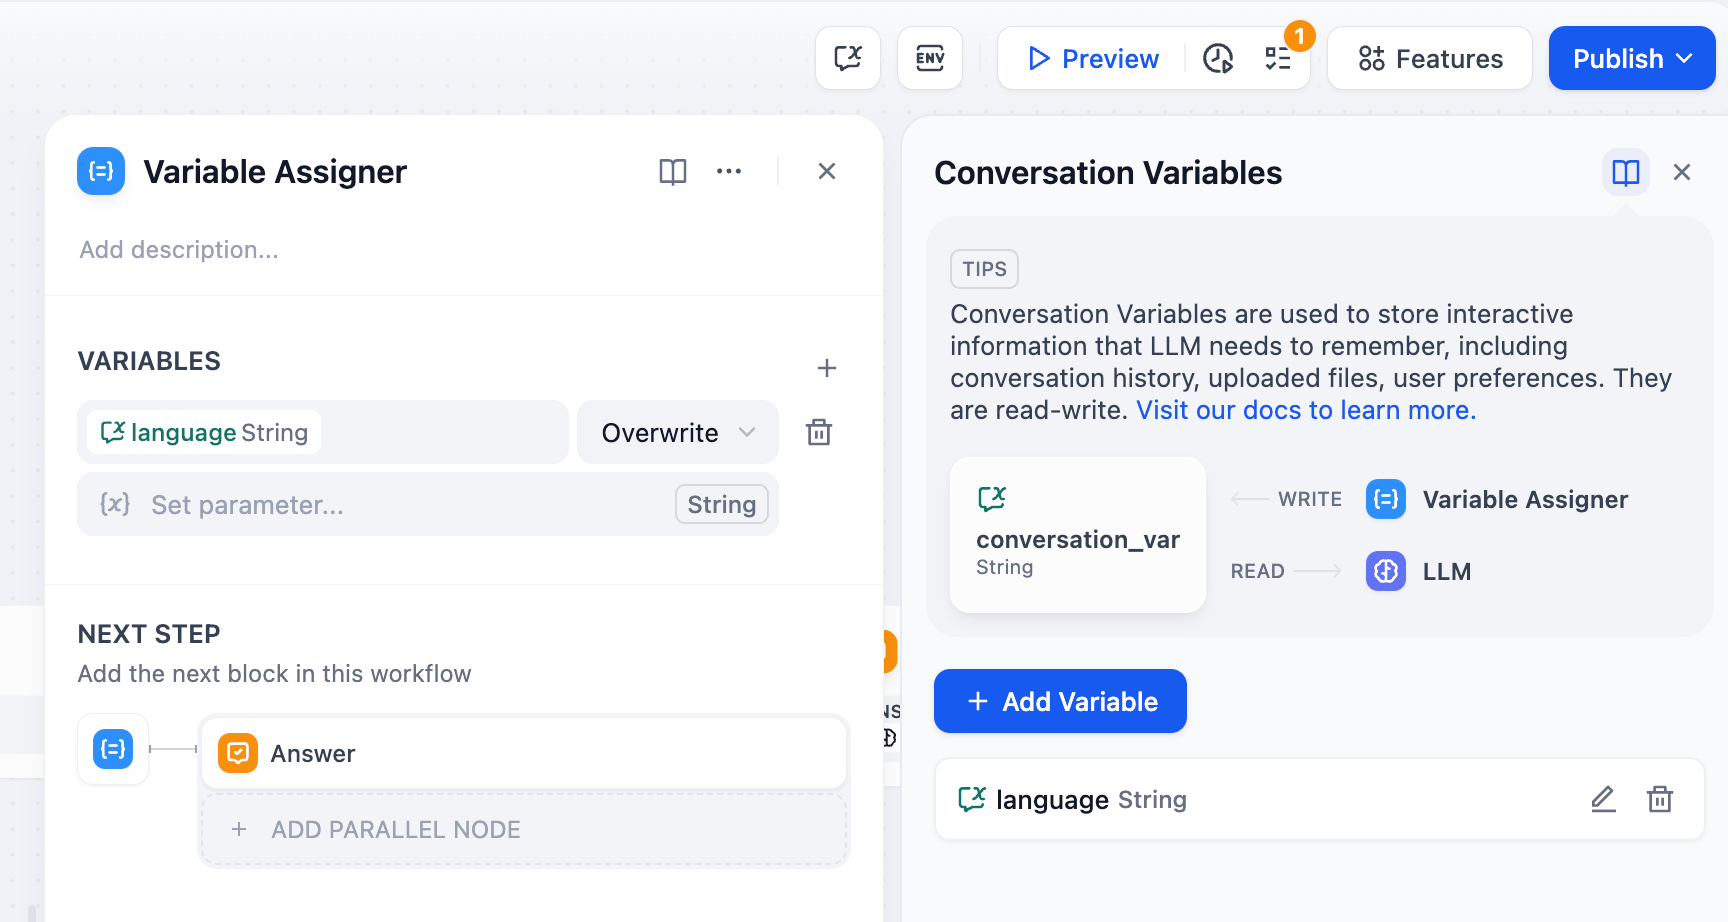
</Frame>
## Conversation Variables vs Workflow Variables
**Workflow Variables** exist only during a single workflow execution and reset when the workflow completes.
**Conversation Variables** persist across multiple conversation turns within the same chat session, enabling stateful interactions and contextual memory.
This persistence enables contextual conversations, user personalization, stateful workflows, and progress tracking across multiple user interactions.
## Configuration
Configure which conversation variables to update and specify their source data. You can assign multiple variables in a single node.
<Frame>
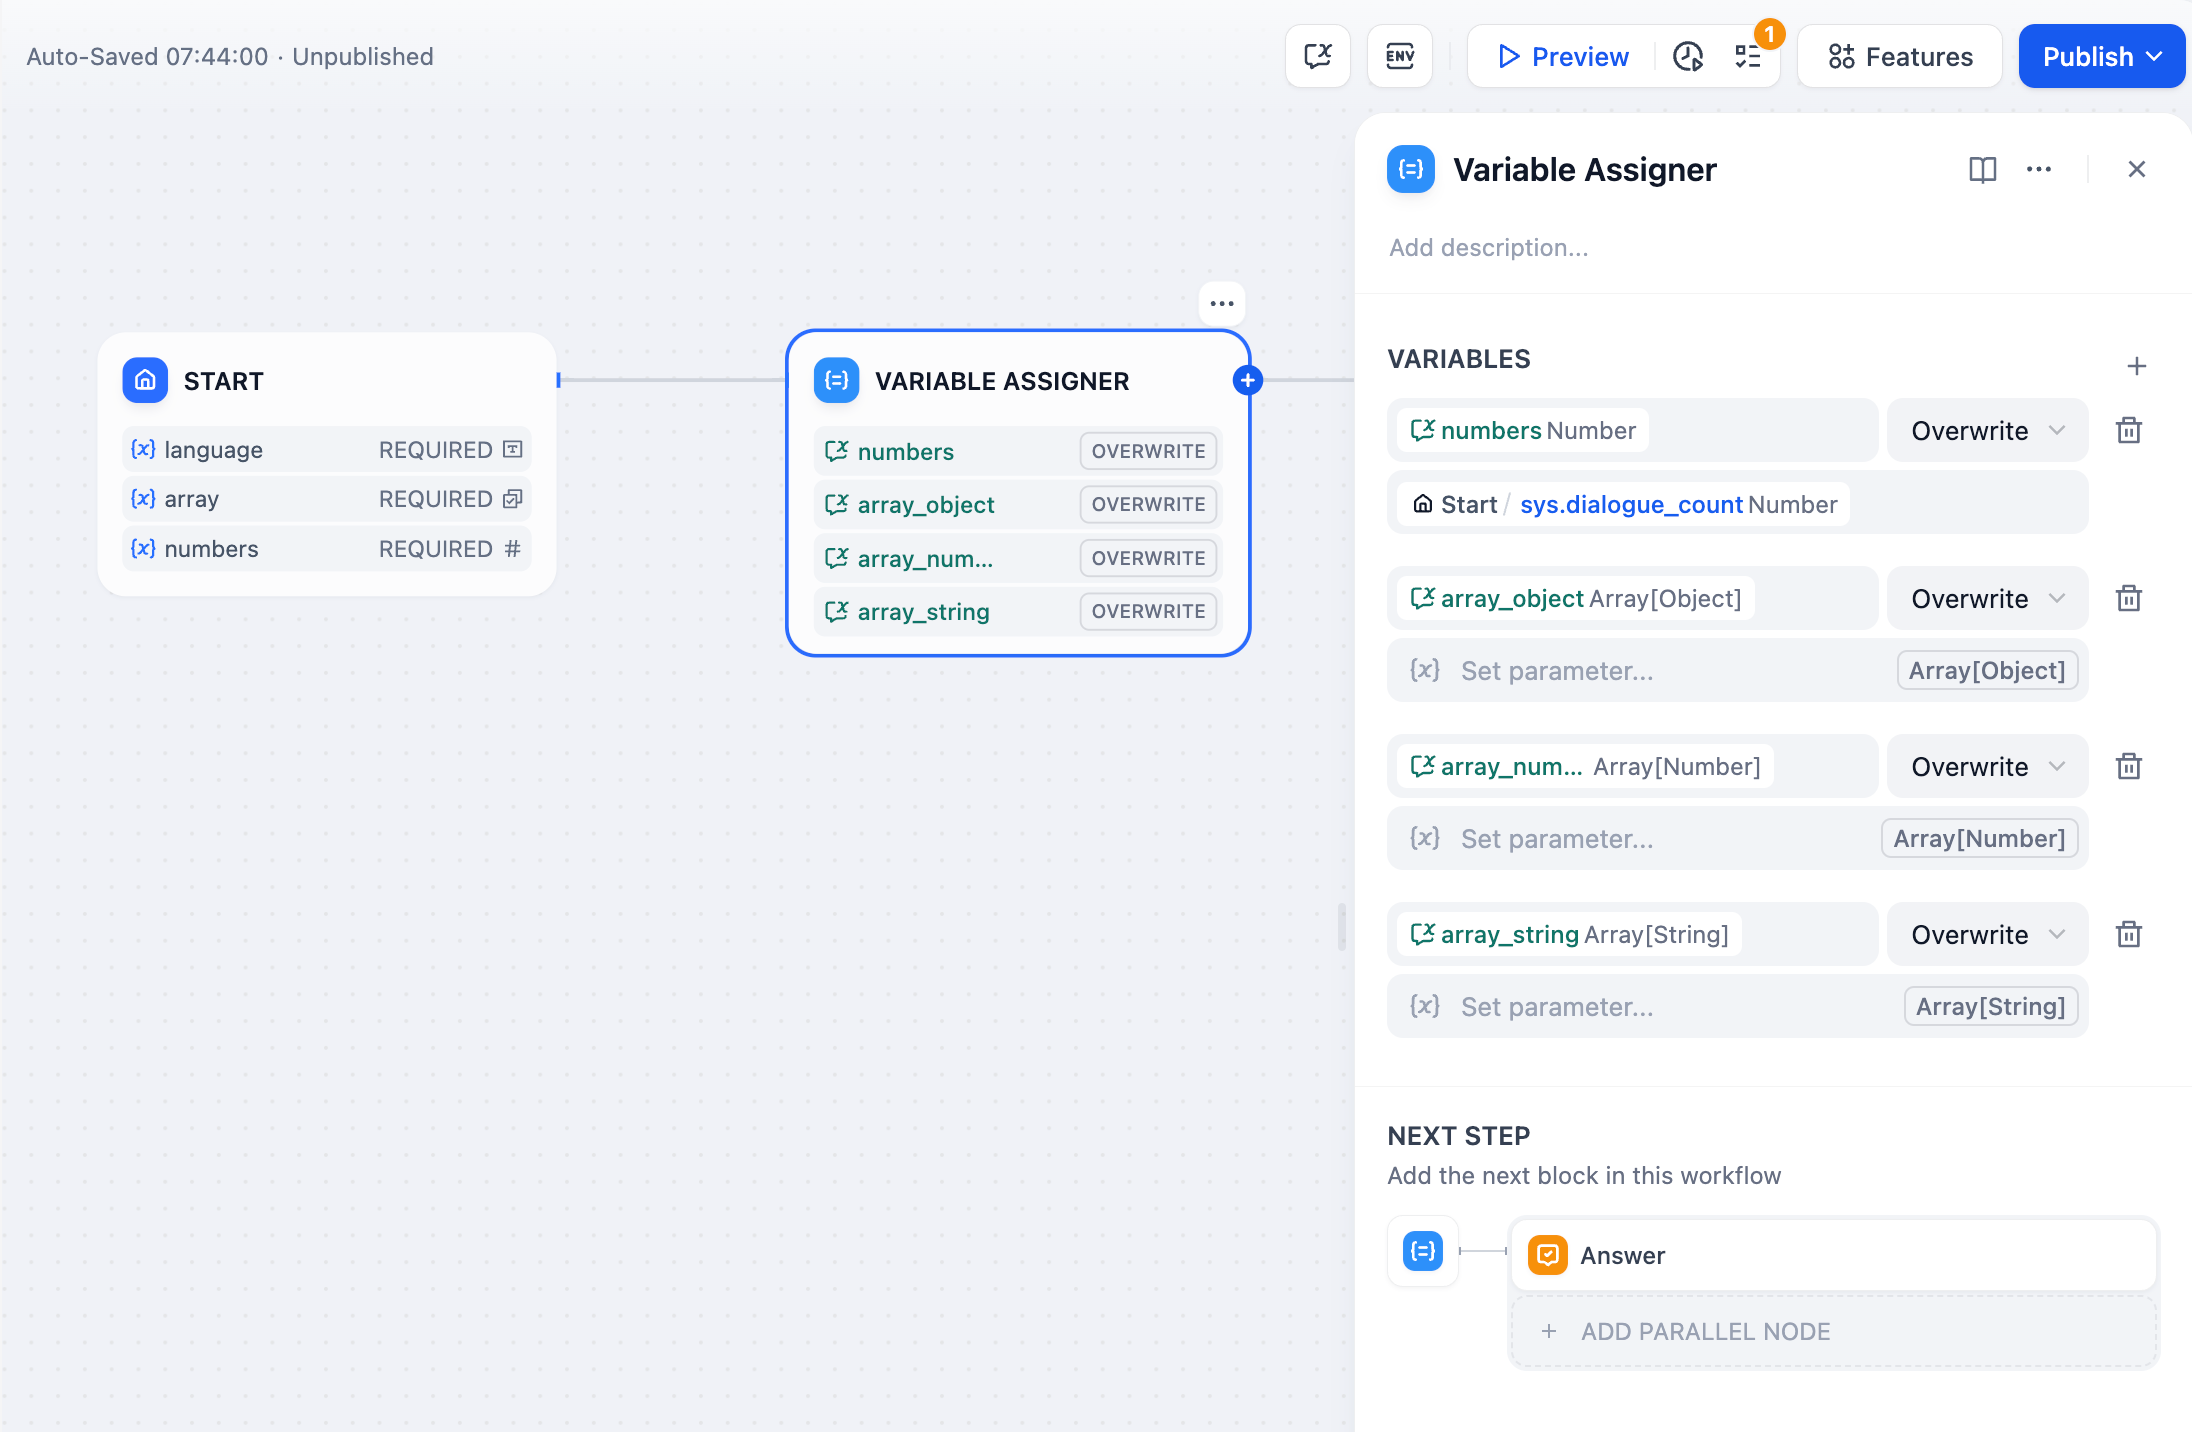
</Frame>
**Variable** - Select the conversation variable to write to
**Set Variable** - Choose the source data from upstream workflow nodes
**Operation Mode** - Determine how to update the variable (overwrite, append, clear, etc.)
## Operation Modes
Different variable types support different operations based on their data structure:
<Tabs>
<Tab title="String">
* **Overwrite** - Replace with another string variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
</Tab>
<Tab title="Number">
* **Overwrite** - Replace with another number variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
* **Arithmetic** - Add, subtract, multiply, or divide the current value by another number
</Tab>
<Tab title="Boolean">
* **Overwrite** - Replace with another boolean variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
</Tab>
<Tab title="Object">
* **Overwrite** - Replace with another object variable
* **Clear** - Remove the current value
* **Set** - Manually define the object structure and values
</Tab>
<Tab title="Array">
* **Overwrite** - Replace with another array variable of the same type
* **Clear** - Remove all elements from the array
* **Append** - Add a single element to the end of the array
* **Extend** - Add all elements from another array of the same type
* **Remove First/Last** - Remove the first or last element from the array
<Tip>
Array operations are particularly powerful for building memory systems, checklists, and conversation histories that grow over time.
</Tip>
</Tab>
</Tabs>
## Common Implementation Patterns
### Smart Memory System
Build chatbots that automatically detect and store important information from conversations:
<Frame>
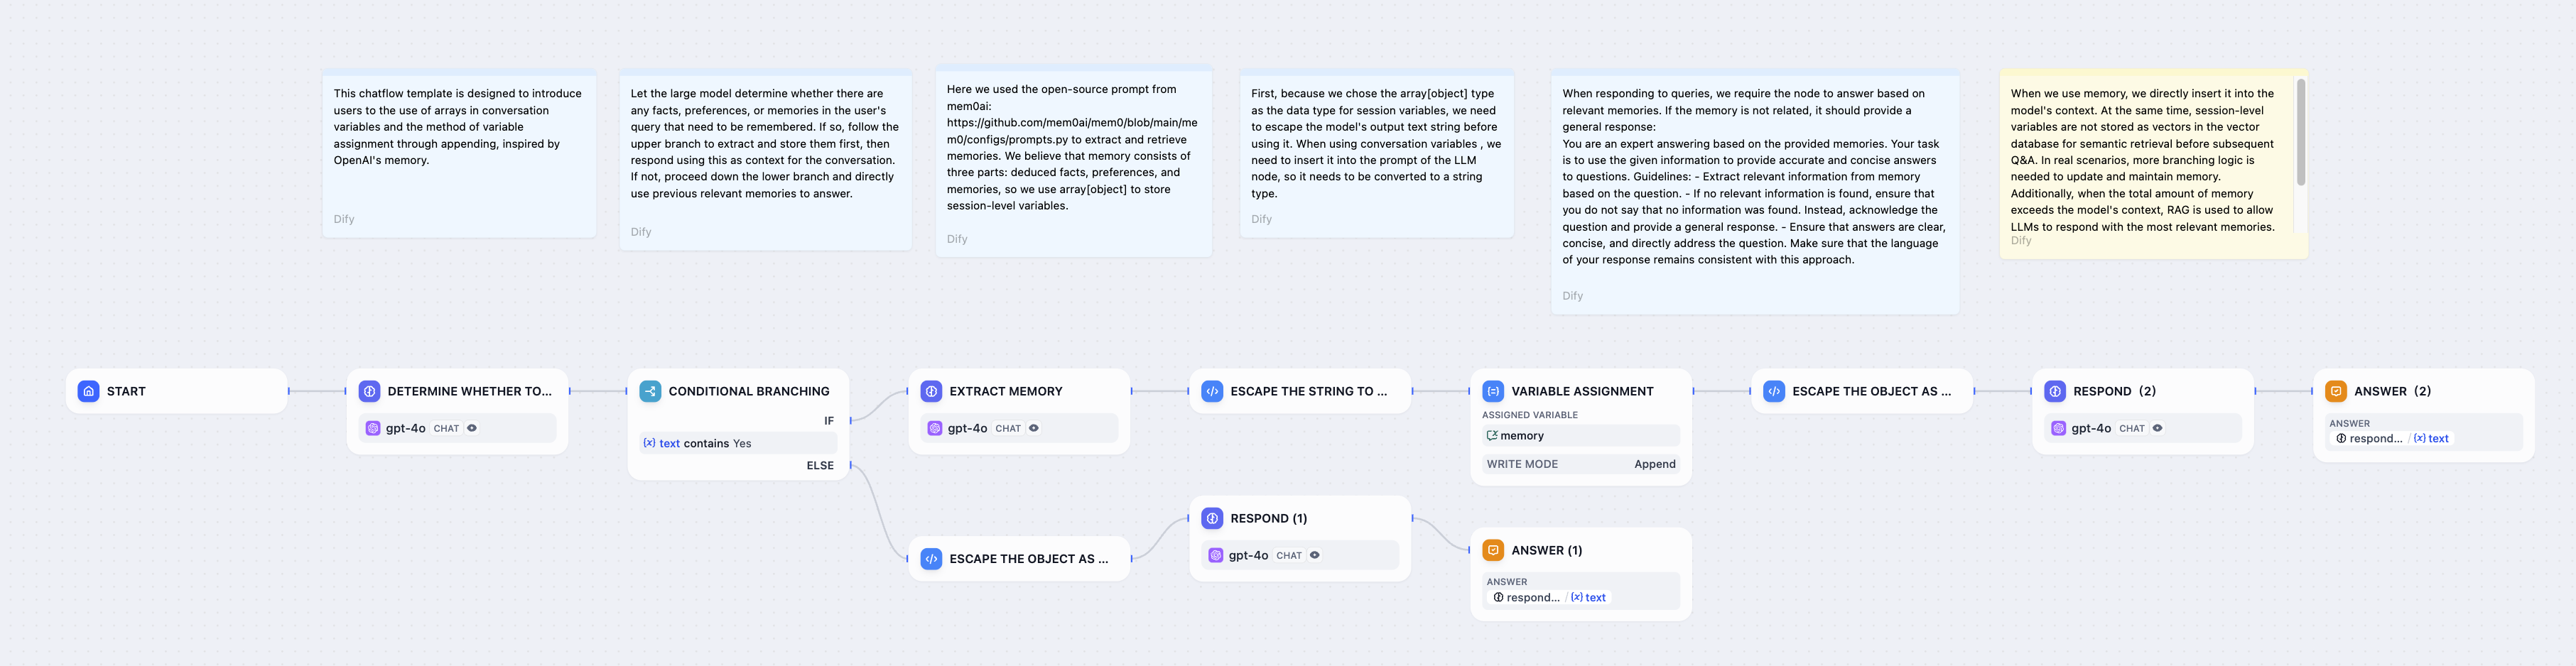
</Frame>
The system analyzes user input for memorable facts, extracts structured information, and appends it to a persistent memories array for future reference in conversations.
### User Preferences Storage
Store user preferences like language settings, notification preferences, or display options:
<Frame>
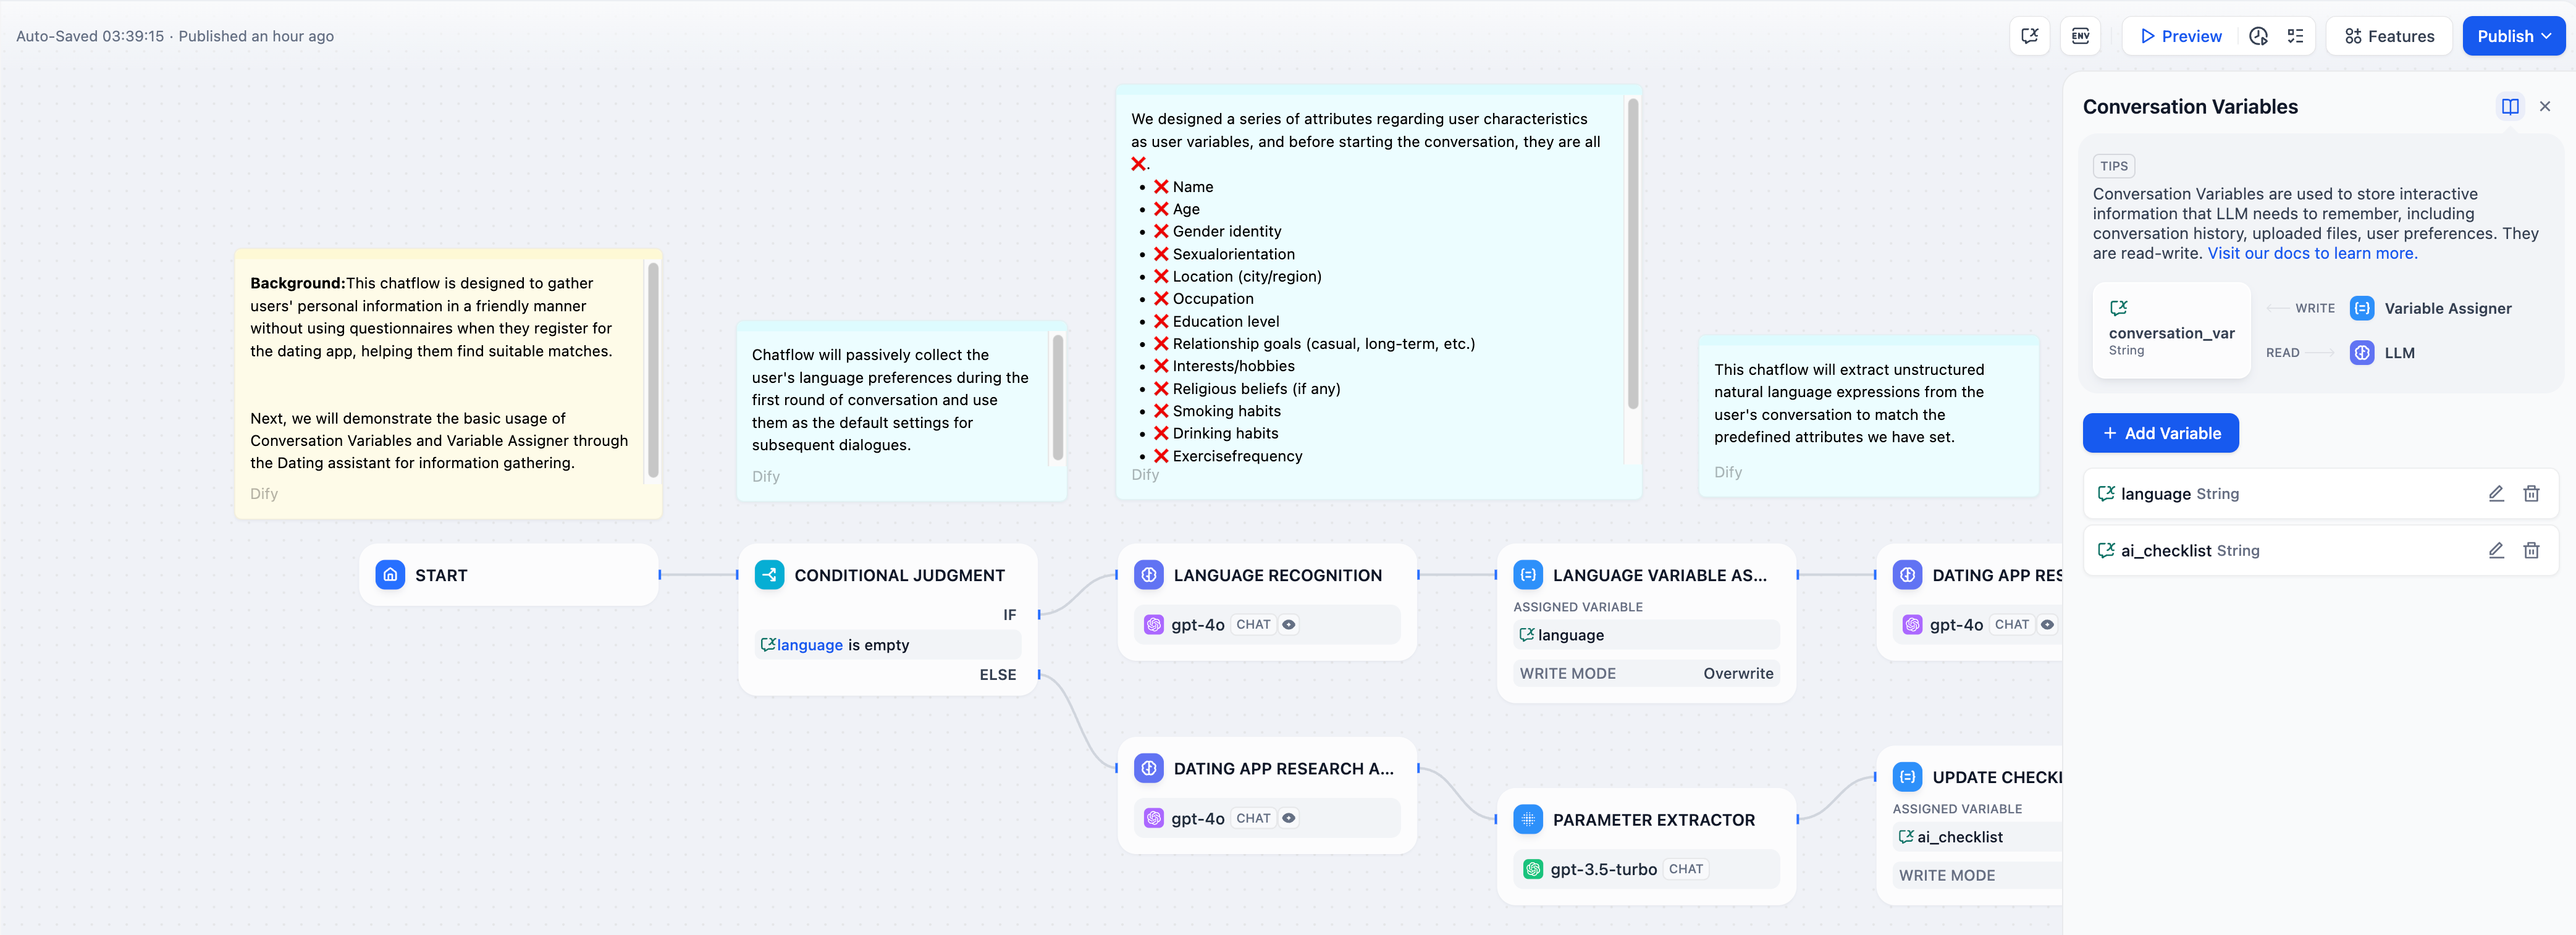
</Frame>
Use **Overwrite** mode to capture initial preferences from user input, then reference them in all subsequent LLM responses for personalized interactions.
### Progressive Checklists
Build guided workflows that track completion status across multiple conversation turns:
<Frame>
</Frame>
Use array conversation variables to track completed items. The Variable Assigner updates the checklist each turn, while the LLM references it to guide users through remaining tasks.
# Overview
Source: https://docs.dify.ai/en/cloud/use-dify/publish/README
Get your Dify applications into users' hands with web apps, APIs, embeds, and integrations
You've built something great in Dify. Now let's get it to your users. Every Dify application becomes available in multiple ways automatically—choose what works best for your situation.
## Start with Web Apps
Your fastest path to sharing is through web apps. These are generated automatically when you create any application and work immediately without setup.
<Steps>
<Step title="Hit Publish">
Click **Publish** in your app to activate the latest version.
</Step>
<Step title="Copy the URL">
Find your web app link on the app's **Access Point** tab.
</Step>
<Step title="Share immediately">
Send the link to users—they can start using your app right away.
</Step>
</Steps>
<Tip>
Web apps work on any device and automatically adapt to screen sizes. No app store approvals or installation required.
</Tip>
## Publishing Options
<CardGroup>
<Card title="Web Apps" icon="globe" href="/en/cloud/use-dify/publish/webapp/chatflow-webapp">
Instant, shareable applications. Perfect for testing ideas or serving end users directly.
</Card>
<Card title="API Integration" icon="code" href="/en/api-reference/guides/get-started">
Build AI into your existing products. Full control over user experience and data flow.
</Card>
<Card title="Embed on Websites" icon="window" href="/en/cloud/use-dify/publish/webapp/embedding-in-websites">
Deploy your web app as chat widgets or inline frames on any website.
</Card>
<Card title="MCP Server" icon="plug" href="/en/cloud/use-dify/publish/publish-mcp">
Connect to AI tools like Claude Desktop and Cursor. Great for development workflows.
</Card>
</CardGroup>
## How Publishing Works
When you publish an app, Dify creates a web app and API endpoint with your latest configuration:
* **Web apps** update immediately with new features and responses
* **API endpoints** serve the latest model and workflow configurations
* **Website embeds** (which display your web app) automatically reflect all changes
* **MCP servers** provide access to current app capabilities
<Warning>
Publishing replaces your live app with the current configuration. Users will immediately see changes in their next interaction.
</Warning>
## Choose Your Approach
<AccordionGroup>
<Accordion title="I want immediate user feedback">
Use **Web Apps**. Share a link and start collecting feedback within minutes. Perfect for validating ideas or serving non-technical users.
</Accordion>
<Accordion title="I'm building a product">
Use **API Integration**. You control the interface, user authentication, and data handling. Your app becomes part of your product ecosystem.
</Accordion>
<Accordion title="I have an existing website">
Use **Embed on Websites**. Display your web app as a chat widget or inline frame on your current site. Works with any website technology.
</Accordion>
<Accordion title="I want to extend AI tools">
Use **MCP Server**. Make your app available to Claude Desktop, Cursor, and other AI development environments as a native tool.
</Accordion>
</AccordionGroup>
## Publishing Best Practices
Before you share your app, ensure you've configured these settings:
* **App description** - Helps users understand what your app does
* **Icon and branding** - Makes your app recognizable and professional
* **Access controls** - Decide if your app should be public or require authentication
* **Rate limits** - Protect your app from overuse (especially important for API access)
<Check>
All publishing methods use the same app configuration. Set it once, publish everywhere.
</Check>
# MCP Server
Source: https://docs.dify.ai/en/cloud/use-dify/publish/publish-mcp
Expose your Dify applications as MCP servers for integration with Claude Desktop, Cursor, and other AI development tools
Dify now supports exposing your applications as [MCP](https://modelcontextprotocol.io/docs/getting-started/intro) (Model Context Protocol) servers, enabling seamless integration with AI assistants like Claude Desktop and development environments like Cursor. This allows these tools to directly interact with your Dify apps as if they were native extensions.
<Note>
If you're looking to use MCP tools within Dify workflows & agents, see [here](/en/cloud/use-dify/workspace/tools#mcp).
</Note>
## Configure Your Dify App as an MCP Server
On your app's **Access Point** tab, find the **MCP Server** card. The feature is disabled by default. When you toggle it on, Dify generates a unique MCP Server address for your application. This address serves as the connection point for external tools.
<Danger>
Your MCP Server URL contains authentication credentials, so treat it like an API key. If you suspect it's been compromised, use the regenerate button to create a new URL. The old one will immediately stop working.
</Danger>
## Integration with Claude Desktop
To connect your Dify app to Claude Desktop, you'll need to add a Claude integration. Go to your Claude Profile > Settings > Integrations > Add integration. Replace the Integration URL with your Dify app's Server URL.
## Integration with Cursor
For Cursor, create or edit the `.cursor/mcp.json` file in your project root:
```json theme={null}
{
"mcpServers": {
"your-server-name": {
"url": "your-server-url"
}
}
}
```
Simply replace the URL with your Dify app's MCP Server address. Cursor will automatically detect this configuration and make your Dify app available as a tool. You can add multiple Dify apps by including additional entries in the `mcpServers` object.
## Practical Considerations
* Descriptiveness
When designing descriptions for your tool and its input parameters, think about how an AI would interpret them. Clear, specific descriptions lead to better invocations. Instead of "input data," specify "JSON object containing user profile with required fields: name, email, preferences."
* Latency
The MCP protocol handles the communication layer, but your Dify app's performance still matters. If your app typically takes 30 seconds to process, that latency will be felt in the client application. Consider adding progress indicators or breaking complex workflows into smaller, faster operations.
# Publish Apps to Marketplace
Source: https://docs.dify.ai/en/cloud/use-dify/publish/publish-to-marketplace
Publish your apps to Dify Marketplace and share them with the world
Publish your apps as templates to Dify Marketplace, where other Dify users can discover and use them.
## Submit a Template
To publish a template, submit it through the [Creator Center](https://creators.dify.ai). After you submit, the template enters **Pending** status while we review it. Once approved, it's published to Marketplace.
While a template is **Pending**, you can withdraw it at any time. Withdrawing returns it to **Draft**, where you can edit any part of the template before resubmitting.
<Note>
Before submission:
* Make sure all plugins used in the app are **installed directly from Marketplace**.
* Run the app at least once to confirm it works as expected.
</Note>
### Submit as Individual or Organization
You can submit templates under your personal account or an organization.
* **Individual**: For independent creators. When you first log in to the Creator Center, you're signed in with your personal account by default.
* **Organization**: For teams that want to build and manage templates together. To get started, click your avatar in the top-left corner and click **Create an organization**, then invite members to collaborate.
You can switch between your personal account and organizations anytime.
### Submission Methods
<Tabs>
<Tab title="From Dify Studio">
In your app, click **Publish** > **Publish Update**, then click **Publish to Marketplace**.
This takes you to the Creator Center with your app file automatically uploaded. Fill in the template details and submit for review.
</Tab>
<Tab title="In the Creator Center">
Export your app, then go to the Creator Center and upload the export file. Fill in the template details and submit for review.
</Tab>
</Tabs>
## Update a Published Template
How you update a published template depends on what you want to change.
* **To change anything inside the app** (its prompts, tools, model settings, and so on)
Submit the updated app as a new template. This creates a separate listing rather than replacing the original, so you can manually unpublish the old version once the new one is published.
* **To change only the listing** (such as the Overview or Setup steps)
Unpublish the template to take it off Marketplace and return it to **Draft**. Make your edits, then resubmit for review.
## Template Writing Guidelines
### Language Requirements
Keep the template library consistent and searchable.
**The following fields must be written in English**:
* Template name
* Overview
* Setup steps
**Inside the app, you can use any language (e.g. Chinese) for**:
* Node names
* Prompts / system messages
* Messages shown to end-users
If your template mainly targets non-English users, you can add a tag in the title. For example, `Stock Investment Analysis Copilot [ZH]`.
### Template Name & Icon
From the name alone, users should know where it runs and what it does.
* Use a short English phrase, typically 3–7 words.
* Recommended pattern: \[Channel / target] + \[core task], for example:
* WeChat Customer Support Bot
* CSV Data Analyzer with Natural Language
* Internal Docs Q\&A Assistant
* GitHub Issue Triage Agent
* Include keywords users might search for: channel names (Slack, WeChat, Email, Notion) and task names (Summarizer, Assistant, Generator, Bot).
* Use an icon that clearly reflects the template's theme and purpose, rather than the default avatar.
### Categories
Help users discover your template when browsing or filtering by category.
* Select only **1–3** categories that best describe your template.
* Do not check every category just for exposure.
### Language
Help users discover your template via the language filter.
* Select the language your template is designed for in real usage.
* This refers to the language of the template's use case, input, or output, **not** the title or overview (which must be in English).
### Overview
In 2–4 English sentences, explain what it does and who it is for.
<Info>You don't need to list prerequisites, inputs, or outputs here.</Info>
**Recommended structure**
1. Sentence 1: **What it does**
A one-sentence summary of the main function.
2. Sentence 2–3: **Who and when**
Typical user roles or scenarios (support team, marketers, founders, individual knowledge workers, etc.).
<Accordion title="Example: Description for Stock Investment Analysis Copilot">
This template creates a stock investment analysis copilot that uses Yahoo Finance tools to fetch news, analytics, and ticker data for any listed company.
It helps investors and analysts quickly generate structured research summaries, compare companies, and prepare reports without manually switching between multiple finance websites.
</Accordion>
### Setup Steps
Write Setup steps as a numbered Markdown list (1., 2., 3.), with one short sentence per step, starting with a verb.
A new user should be able to get the template running in a few minutes just by following these steps.
**Writing principles**
1. Follow the real setup order, usually:
1. Use/import the template
2. Connect accounts / add API keys
3. Connect data sources (docs, databases, sheets, etc.)
4. Optional customization (assistant name, tone, filters)
5. Activate the workflow and run a test
2. Each step should answer:
* Where to click in the UI
* What to configure or fill in
3. Aim for 3–8 steps. Too few feels incomplete; too many feels overwhelming.
<Accordion title="Example: Setup Steps for Stock Investment Analysis Copilot (Yahoo Finance tools)">
1) Click **Use template** to copy the "Investment Analysis Copilot (Yahoo Finance)" agent into your workspace.
2) Go to **Integrations** > **Model Provider** and add your LLM API key. For example, OpenAI, Anthropic, or another supported provider.
3) Open the agent's **Orchestrate** page and make sure the Yahoo Finance tools are enabled in the **Tools** section:
* `yahoo Analytics`
* `yahoo News`
* `yahoo Ticker`
4. (Optional) Customize the analysis style:
* In the **INSTRUCTIONS** area, adjust the system prompt to match your target users. For example, tone, report length, preferred language, or risk preference.
* Update the suggested questions in the **Debug & Preview** panel if you want different example queries.
5. Click **Publish** to make the agent available, then use the preview panel to test it:
* Enter a company name or ticker (e.g., `Nvidia`, `AAPL`, `TSLA`).
* Confirm that the copilot calls the Yahoo Finance tools and returns a structured investment analysis report.
</Accordion>
### Quick Checklist Before You Submit
* The name is a short English phrase that clearly shows where it runs and what it does.
* The overview uses 2–4 English sentences to explain the value and typical use cases.
* Only 1–3 relevant categories are selected.
* Setup steps are a clear numbered list.
* Internal workflow texts and prompts are written in appropriate languages for your target users.
# Chat Web Apps
Source: https://docs.dify.ai/en/cloud/use-dify/publish/webapp/chatflow-webapp
Turn your Chatflow into a fully-featured conversation interface with persistent history and interactive features
Chat web apps transform your Chatflow into a complete conversation experience. Users get persistent chat sessions, smart interactions, and all the features you've configured—without installing anything.
## How Chat Apps Work
Your Chatflow automatically becomes a web app when you publish it. The system creates a responsive interface that:
* **Maintains conversation context** across user sessions
* **Inherits all orchestration settings** from your Chatflow configuration
* **Adapts to any screen size** from mobile to desktop
* **Handles user authentication** if you've enabled access controls
<Tip>
Unlike single-use text generators, chat apps maintain conversation memory and let users build on previous exchanges.
</Tip>
## Interactive Features
Your web app automatically includes these capabilities based on your Chatflow settings:
<CardGroup>
<Card title="Pre-conversation Forms" icon="clipboard-list">
Collect context before chatting starts—better than asking mid-conversation
</Card>
<Card title="AI Conversation Starters" icon="message">
Eliminate the blank page problem with helpful opening messages
</Card>
<Card title="Smart Follow-ups" icon="arrow-right">
System generates 3 contextual next questions after each response
</Card>
<Card title="Voice Input" icon="microphone">
Speech-to-text lets users talk instead of type
</Card>
<Card title="Source Citations" icon="quote">
References show exactly where information comes from
</Card>
<Card title="Response Feedback" icon="thumbs-up">
Users can rate responses to help improve your app
</Card>
</CardGroup>
## Pre-conversation Setup
When your Chatflow uses variables, users complete a form before chatting starts. This front-loads context gathering instead of interrupting the conversation flow.
<Frame>
</Frame>
Here's how the user experience works:
<Steps>
<Step title="User lands on your app">
They see a clean form requesting necessary context information.
</Step>
<Step title="Form completion unlocks chat">
The "Start Conversation" button activates only after required fields are filled.
</Step>
<Step title="AI has full context">
The conversation begins with all the background information it needs.
</Step>
</Steps>
<Warning>
Every form field adds friction. Only ask for information that meaningfully improves responses.
</Warning>
## Conversation Experience
Once chatting begins, users get an interface designed for natural interaction:
<Frame>
</Frame>
Every AI response includes these actions:
* **Copy button** - One-click copying for easy sharing or note-taking
* **Feedback buttons** - Like/dislike ratings to improve your app over time
* **Follow-up suggestions** - AI generates 3 contextually relevant next questions
## Session Management
Users can manage multiple conversation threads like modern messaging apps:
<Frame>
</Frame>
**Conversation Controls**:
* **Start new** - Begin fresh conversations without losing context from previous ones
* **Pin important** - Keep crucial conversations accessible at the top of the list
* **Delete finished** - Clean up conversations that are no longer relevant
<Info>
Each conversation thread maintains its own memory and context. Users can seamlessly switch between different topics or projects.
</Info>
## Conversation Openers
Enable conversation openers to eliminate the intimidating blank chat screen:
<Frame>
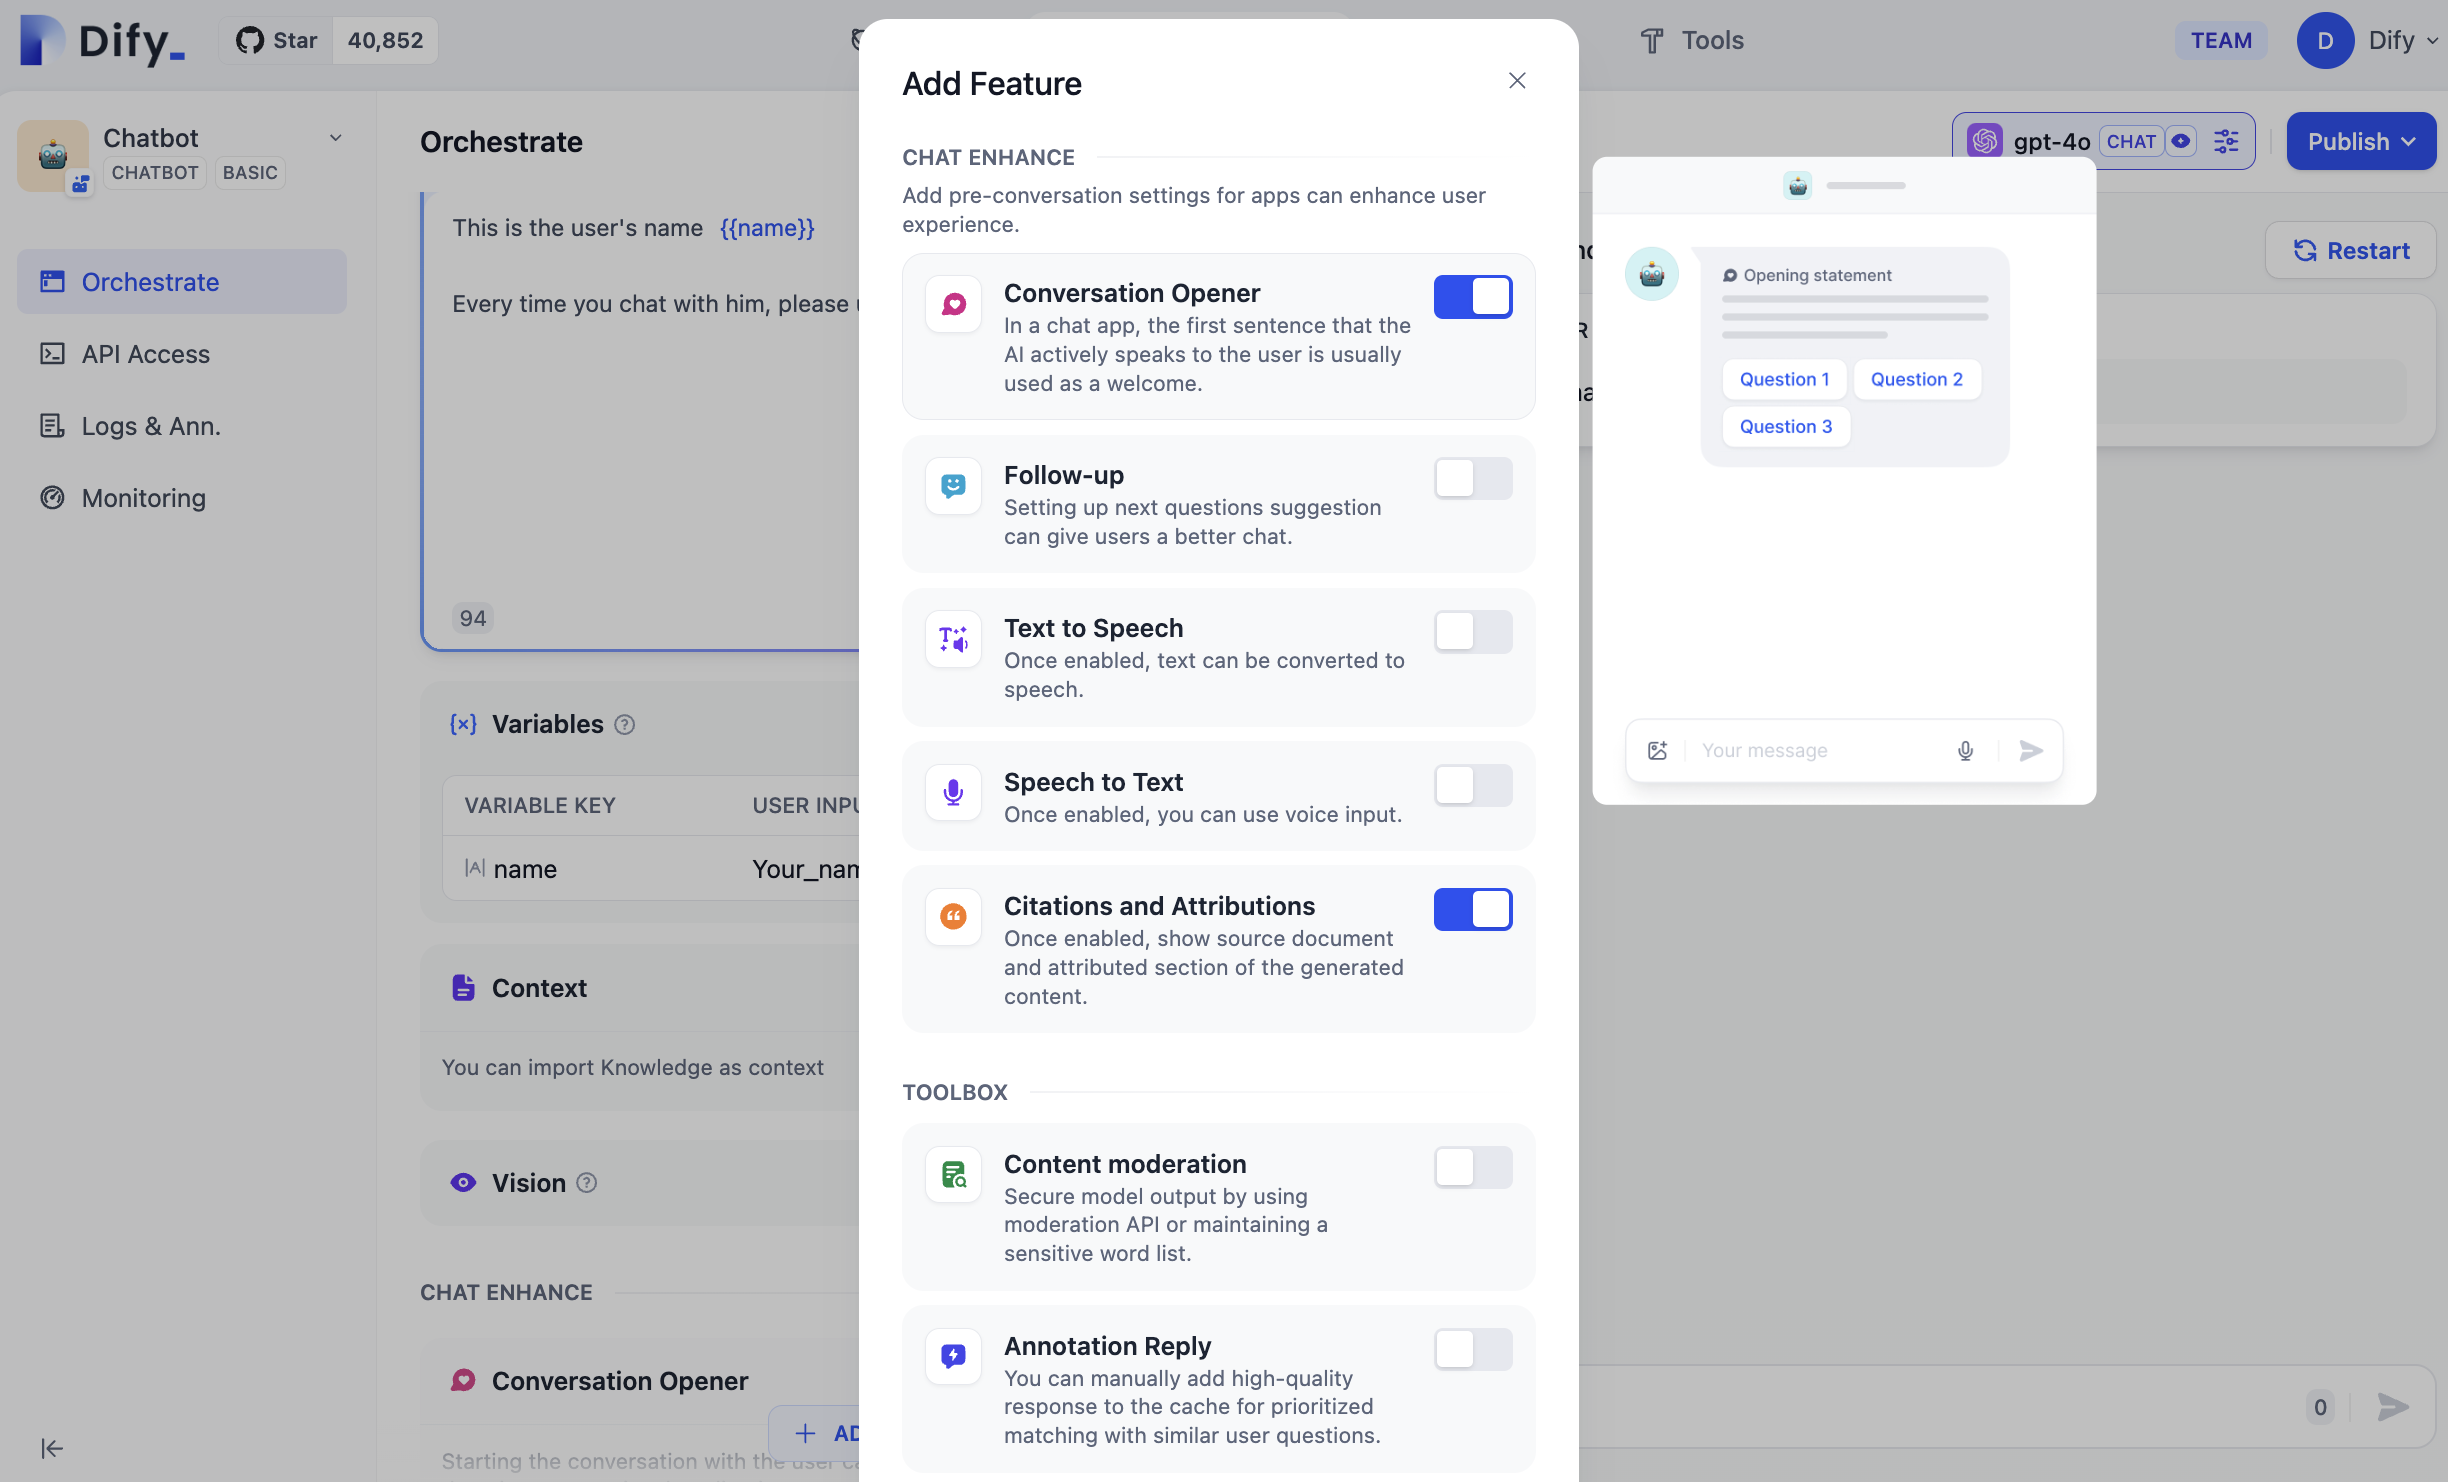
</Frame>
When users start new conversations, the AI proactively introduces itself and explains its capabilities. This immediately shows users what they can accomplish and increases engagement.
<Tip>
Conversation openers work especially well for specialized apps where users might not know all available features.
</Tip>
## Follow-up Questions
The system automatically generates contextual follow-up questions after each AI response:
<Frame>
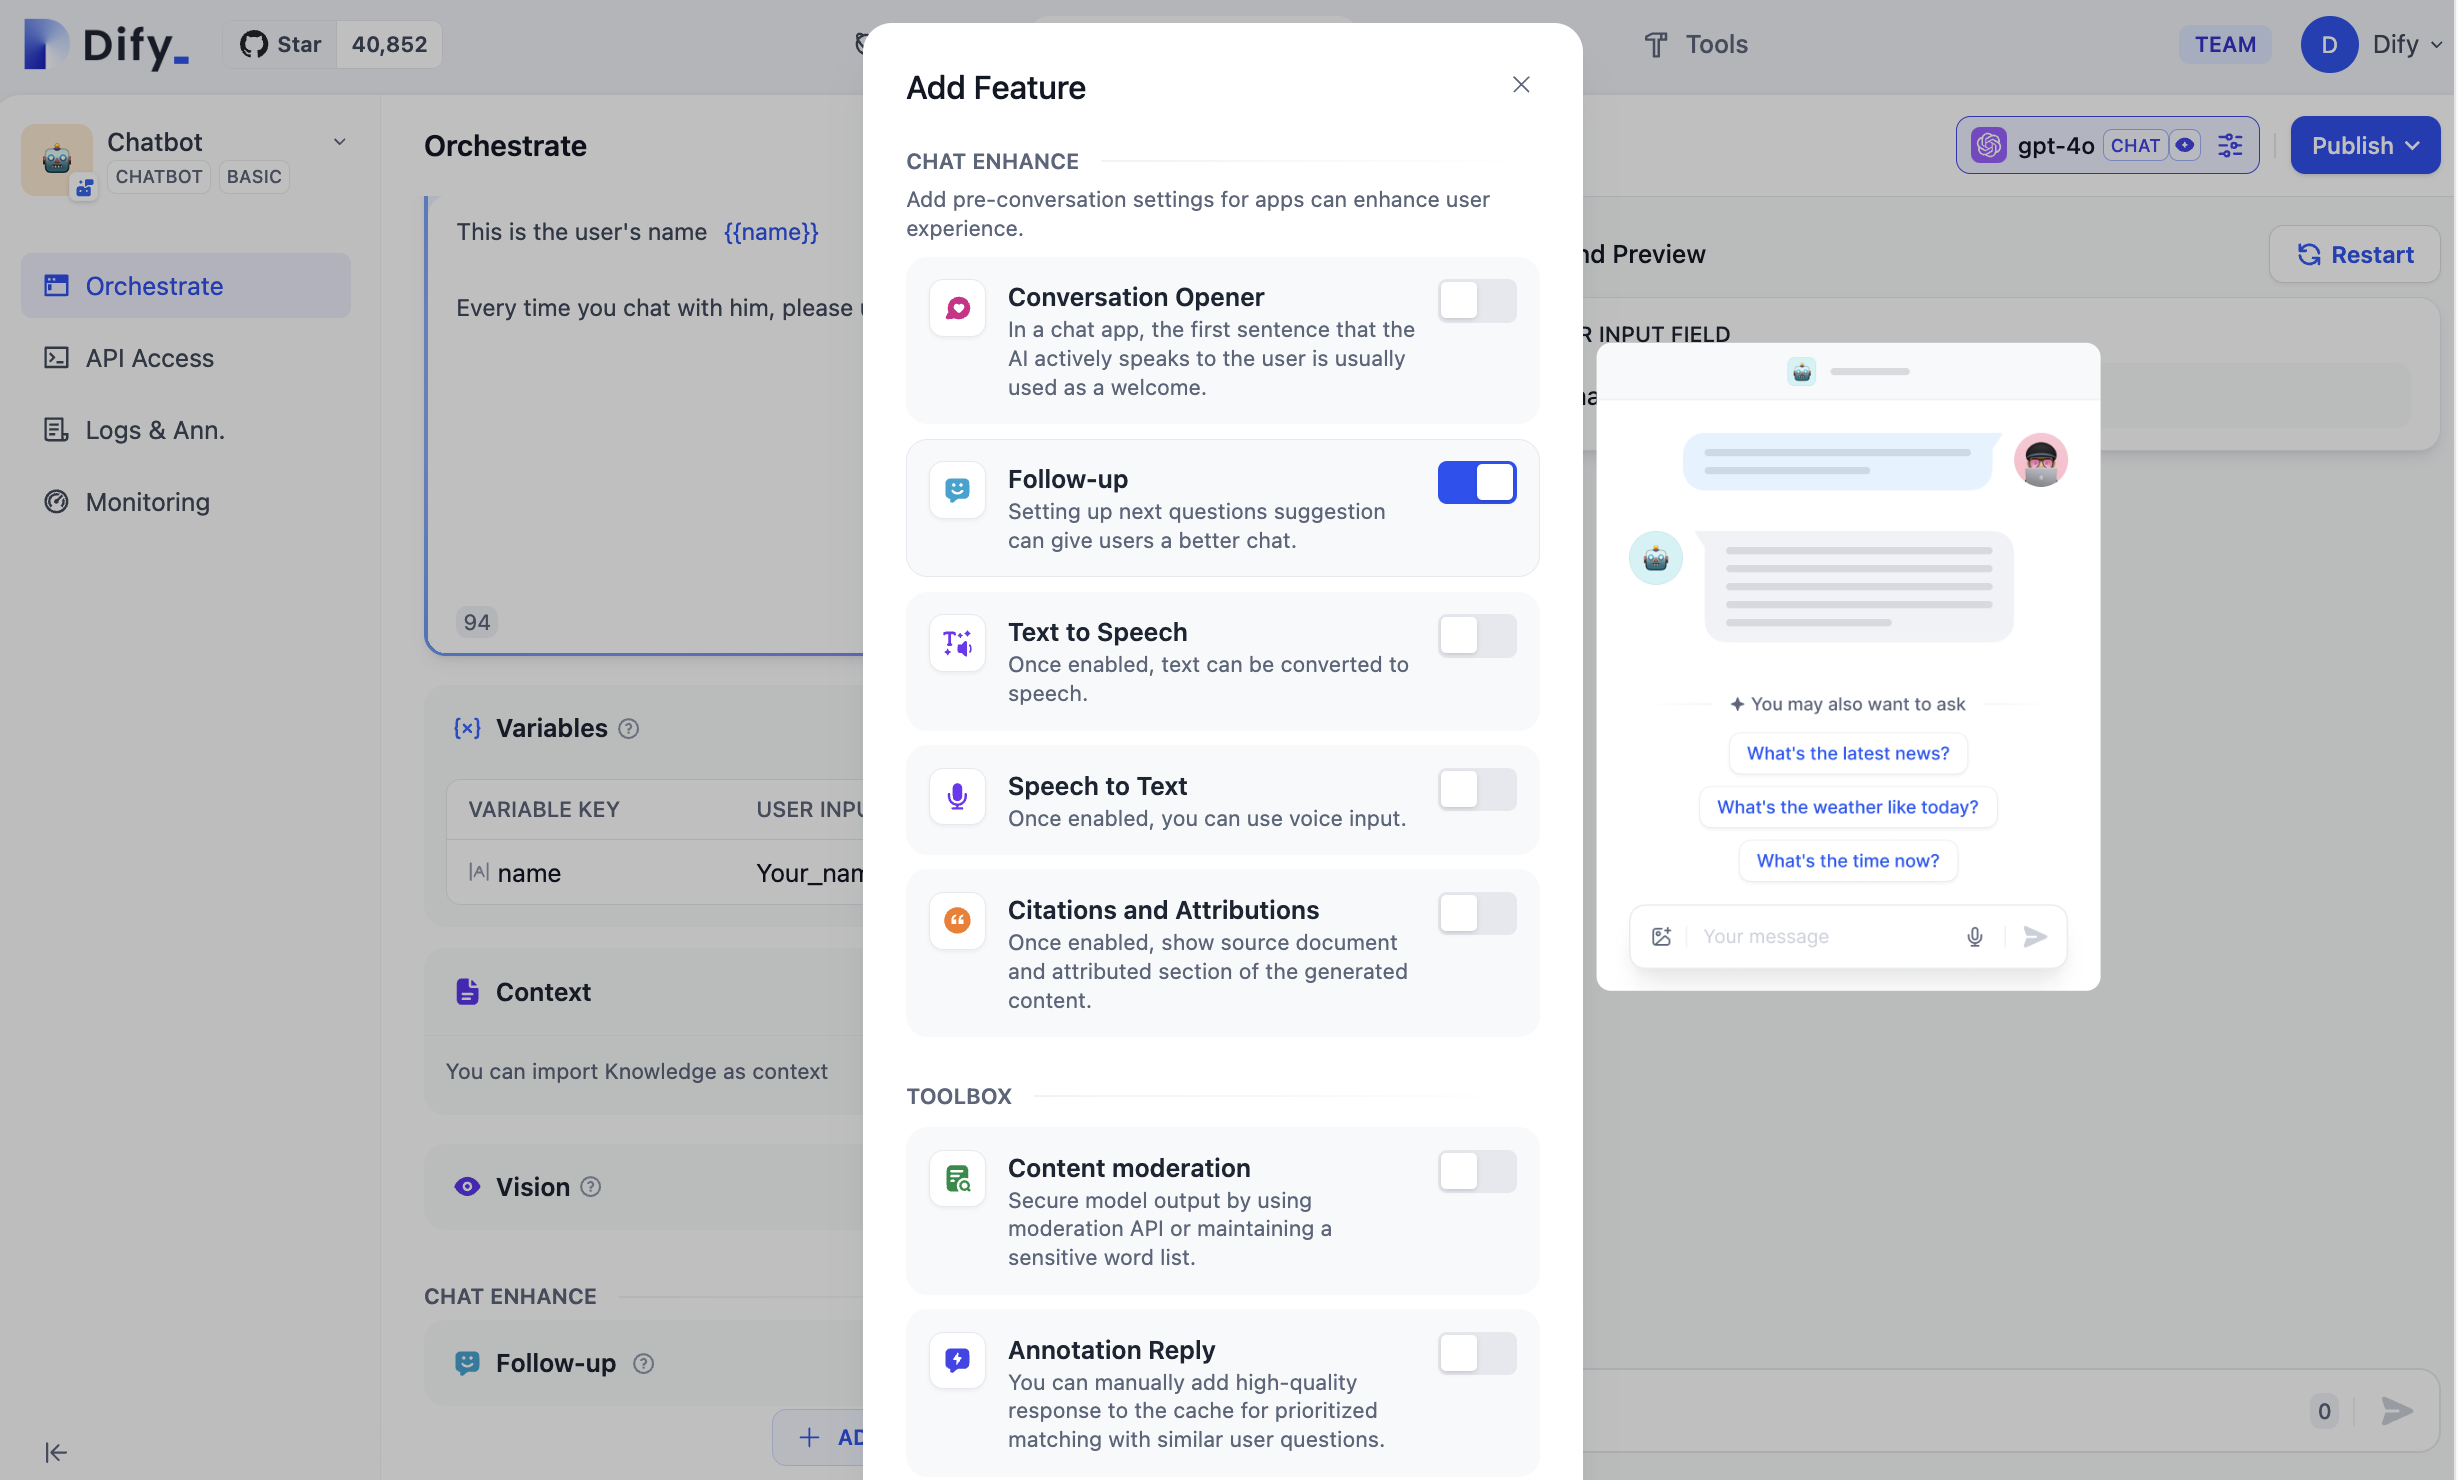
</Frame>
These suggestions are:
* **Contextually relevant** to the current conversation topic
* **Dynamically generated** based on the AI's response
* **Clickable shortcuts** that help users explore deeper or pivot to related topics
## Voice Input
Speech-to-text transforms your chat app into a voice-first experience:
<Frame>
</Frame>
**How it works**:
1. The microphone button appears when you enable speech-to-text in your Chatflow
2. Users click to start recording their question
3. Speech converts to text in real-time as they speak
4. They can edit the text before sending or send immediately
<Warning>
Users must grant microphone permissions in their browser. The app will prompt for this permission when they first try to use voice input.
</Warning>
## Citations and Attributions
When this feature is enabled, if the AI references content from the knowledge base while answering a user question, the specific knowledge sources will be displayed below the response.
Citations build user trust by providing transparency about information sources. Users can click through to verify details or explore source materials further.
# Embed Your Web App
Source: https://docs.dify.ai/en/cloud/use-dify/publish/webapp/embedding-in-websites
Deploy your published web app on any website through iframes, chat widgets, or custom integrations
Your published web app can be embedded directly into any website. This isn't a separate publishing method: it's how you deploy the same web app you've already created, just presented within your existing website instead of as a standalone page.
## How Web App Embedding Works
When you publish an app in Dify, you get a web app URL. You can share this URL directly, or embed the same app into your website using these methods:
<CardGroup>
<Card title="Chat Bubble Widget" icon="comment">
Your web app as a floating button that visitors click to open the full interface
</Card>
<Card title="Iframe Integration" icon="window">
Your web app embedded directly in page content, always visible and ready
</Card>
<Card title="JavaScript Control" icon="code">
Advanced embedding with custom styling and behavior control
</Card>
<Card title="Responsive Design" icon="mobile">
Same web app adapts automatically to any presentation format
</Card>
</CardGroup>
<Info>
All embedding methods use your published web app. Changes to your app configuration automatically apply everywhere it's embedded.
</Info>
## Chat Bubble Widget
The chat bubble presents your web app as a floating button. Visitors click it to open your app in an overlay, keeping them on your page while accessing your AI features.
### Configuration Options
The chat bubble can be customized through the `difyChatbotConfig` object:
```javascript theme={null}
window.difyChatbotConfig = {
// Required: Your app's token from Dify
token: 'YOUR_TOKEN',
// Optional: Environment settings
isDev: false,
baseUrl: 'https://udify.app', // Auto-set based on isDev
// Optional: Visual customization
containerProps: {
style: {
right: '20px',
bottom: '20px'
},
className: 'custom-chat-button'
},
// Optional: Interactive behavior
draggable: false, // Allow users to drag the button
dragAxis: 'both', // 'x', 'y', or 'both'
// Optional: Pre-fill user context
inputs: {
name: "John Doe", // Variable names from your Dify app
department: "Support"
},
// Optional: System variables for tracking
systemVariables: {
user_id: 'USER_123',
conversation_id: 'CONV_456'
},
// Optional: User profile information
userVariables: {
avatar_url: 'https://example.com/avatar.jpg',
name: 'John Doe'
}
}
```
<Steps>
<Step title="Get your embed token">
In your Dify app, open the **Access Point** tab and click **Embed Into Site** on the **Web App** card to find your unique token.
</Step>
<Step title="Add the script">
Include the configuration and Dify's embed script in your website's HTML.
</Step>
<Step title="Customize appearance">
Adjust the `containerProps` to match your website's design.
</Step>
<Step title="Test functionality">
Open your website and try the chat button to ensure everything works correctly.
</Step>
</Steps>
## Iframe Integration
Embed your web app directly into your page content. This displays your app as an integral part of your website:
```html theme={null}
<iframe
src="https://udify.app/chatbot/YOUR_APP_TOKEN"
width="100%"
height="600"
frameborder="0">
</iframe>
```
### Why Use Iframe Embedding
* **Always visible**: Your web app is immediately accessible, not hidden behind a button
* **Full functionality**: Everything from your web app works identically in the iframe
* **Page integration**: Appears as native content, not an overlay
* **Simple setup**: Just HTML, no JavaScript configuration needed
### Customization Options
**Size and Position**:
```html theme={null}
<iframe
src="https://udify.app/chatbot/YOUR_APP_TOKEN"
width="400px"
height="500px"
style="border: 1px solid #ccc; border-radius: 8px;">
</iframe>
```
**Responsive Design**:
```html theme={null}
<div style="position: relative; width: 100%; height: 0; padding-bottom: 75%;">
<iframe
src="https://udify.app/chatbot/YOUR_APP_TOKEN"
style="position: absolute; top: 0; left: 0; width: 100%; height: 100%;"
frameborder="0">
</iframe>
</div>
```
## Choose Your Embedding Method
<AccordionGroup>
<Accordion title="Customer Support Apps">
**Chat bubble** works best, staying out of the way until needed. The floating button lets visitors continue browsing while having quick access to help.
</Accordion>
<Accordion title="Form & Workflow Apps">
**Iframe embed** for dedicated pages where the app is the main content. Visitors see and use your app immediately without extra clicks.
</Accordion>
<Accordion title="Product Demonstrations">
**Iframe embed** on landing pages to let visitors try your AI capabilities instantly. No barriers between interest and engagement.
</Accordion>
<Accordion title="Multi-page Integration">
**Chat bubble** when you want the same app accessible across your entire site. One embed code provides access from every page.
</Accordion>
</AccordionGroup>
## Advanced Configuration
You can override the default button style using CSS variables or the `containerProps` option. Apply these methods based on CSS specificity to achieve your desired customizations.
### 1. Modify CSS Variables
The following CSS variables are supported for customization:
```css theme={null}
/* Button distance to bottom, default is `1rem` */
--dify-chatbot-bubble-button-bottom
/* Button distance to right, default is `1rem` */
--dify-chatbot-bubble-button-right
/* Button distance to left, default is `unset` */
--dify-chatbot-bubble-button-left
/* Button distance to top, default is `unset` */
--dify-chatbot-bubble-button-top
/* Button background color, default is `#155EEF` */
--dify-chatbot-bubble-button-bg-color
/* Button width, default is `50px` */
--dify-chatbot-bubble-button-width
/* Button height, default is `50px` */
--dify-chatbot-bubble-button-height
/* Button border radius, default is `25px` */
--dify-chatbot-bubble-button-border-radius
/* Button box shadow, default is `rgba(0, 0, 0, 0.2) 0px 4px 8px 0px)` */
--dify-chatbot-bubble-button-box-shadow
/* Button hover transform, default is `scale(1.1)` */
--dify-chatbot-bubble-button-hover-transform
```
To change the background color to #ABCDEF, add this CSS:
```css theme={null}
#dify-chatbot-bubble-button {
--dify-chatbot-bubble-button-bg-color: #ABCDEF;
}
```
### 2. Use `containerProps`
Set inline styles using the `style` attribute:
```javascript theme={null}
window.difyChatbotConfig = {
// ... other configurations
containerProps: {
style: {
backgroundColor: '#ABCDEF',
width: '60px',
height: '60px',
borderRadius: '30px',
},
// For minor style overrides, you can also use a string value for the `style` attribute:
// style: 'background-color: #ABCDEF; width: 60px;',
},
}
```
Apply CSS classes using the `className` attribute:
```javascript theme={null}
window.difyChatbotConfig = {
// ... other configurations
containerProps: {
className: 'dify-chatbot-bubble-button-custom my-custom-class',
},
}
```
### 3. Pass `inputs`
There are four types of inputs supported:
1. **`text-input`**: Accepts any value. The input string will be truncated if its length exceeds the maximum allowed length.
2. **`paragraph`**: Similar to `text-input`, it accepts any value and truncates the string if it's longer than the maximum length.
3. **`number`**: Accepts a number or a numerical string. If a string is provided, it will be converted to a number using the `Number` function.
4. **`options`**: Accepts any value, provided it matches one of the pre-configured options.
Example configuration:
```javascript theme={null}
window.difyChatbotConfig = {
// Other configuration settings...
inputs: {
name: 'apple',
},
}
```
Note: When using the embed.js script to create an iframe, each input value will be processed (compressed using GZIP and encoded in base64) before being appended to the URL.
For example, the URL with processed input values will look like this:
`http://localhost/chatbot/{token}?name=H4sIAKUlmWYA%2FwWAIQ0AAACDsl7gLuiv2PQEUNAuqQUAAAA%3D`
## Troubleshooting
**Widget not appearing**:
* Verify your app token matches what's shown under **Embed Into Site** on the app's **Access Point** tab
* Check that configuration loads before the embed script
* Look for JavaScript errors in browser console
**Iframe not loading**:
* Confirm the web app URL includes your correct token
* Ensure your site allows iframe content (check Content Security Policy)
* Both your site and Dify app should use HTTPS
<Warning>
Your web app must be published before embedding. If you update your app configuration, republish to see changes in embedded versions.
</Warning>
# Settings
Source: https://docs.dify.ai/en/cloud/use-dify/publish/webapp/web-app-settings
Configure branding, basic access controls, and user experience settings for your published web applications
Web app settings control how your published applications look and behave for end users. Every Dify application automatically generates a web interface that adapts to different devices and screen sizes.
## How Settings Work
Your web app reflects your application's current configuration. When you modify settings and click **Publish**, changes flow immediately to the live web application that users are accessing.
<Info>
Web apps are public by default. Anyone with the URL can access them, which works well for demos, public tools, and customer-facing applications.
</Info>
## Branding and Appearance
Make your web app look professional and recognizable:
<CardGroup>
<Card title="App Identity" icon="id-card">
Set your app name, description, and icon to create a clear first impression
</Card>
<Card title="Visual Design" icon="palette">
Choose colors, themes, and layout options that match your brand
</Card>
<Card title="Language Settings" icon="globe">
Configure interface language for your target audience
</Card>
<Card title="Legal Pages" icon="scale-balanced">
Add copyright information and privacy policy links for compliance
</Card>
</CardGroup>
### Essential Branding Elements
**App Icon and Name**
* Your icon appears in browser tabs and when users bookmark your app
* Choose a clear, recognizable name that explains what your app does
* Icons can be images or emojis; pick what fits your app's personality
**Description and Messaging**
* Write a concise description that helps users understand your app's purpose
* This text appears on the app's landing page and in search results
* Keep it under 160 characters for best results
**Input Placeholder**
* Replace the default hint text in the chat input box with a prompt of your own, up to 64 characters
* Available for chat-style apps (Chatbot, Agent, and Chatflow); leave it empty to keep the default
**Visual Consistency**
* Choose colors that align with your brand
* Consider your audience when selecting light or dark themes
* Test your app on different devices to ensure it looks good everywhere
## Access and Legal
Web apps are public by default. Anyone with the URL can open them, which works well for demos, public tools, and customer-facing applications.
**Privacy and Legal**:
* Add copyright information and privacy policy links
* Configure data handling preferences
* Set terms of service for compliance
## Feature Inheritance
Your web app automatically includes features you've enabled in your app configuration:
**Interactive Features**:
* Conversation openers and suggested follow-ups
* Pre-conversation forms for context gathering
* Voice input and speech-to-text capabilities
* Source citations and reference links
* Feedback collection and rating systems
**Functionality**:
* All workflow steps and AI model configurations
* Knowledge base integrations and tool connections
* Custom prompts and response formatting
* Rate limiting and usage controls
<Warning>
Disabling features in your app configuration immediately removes them from the published web app.
</Warning>
## App Types and Behavior
Your web app automatically adapts its interface based on your app type:
<Tabs>
<Tab title="Chat Apps">
**Interface**: Conversation-style with message history
**Features**: Persistent sessions, conversation management, real-time responses
**Best for**: Customer support, consulting tools, interactive assistants
</Tab>
<Tab title="Workflow Apps">
**Interface**: Form-based with result display
**Features**: Single runs, batch processing, result saving
**Best for**: Content generation, data processing, analysis tools
</Tab>
</Tabs>
## Deployment Options
Once published, your web app can be accessed in multiple ways:
<CardGroup>
<Card title="Direct Link" icon="link">
Share the web app URL for immediate access
</Card>
<Card title="Website Embedding" icon="window" href="/en/cloud/use-dify/publish/webapp/embedding-in-websites">
Deploy as chat widgets or iframes on existing websites
</Card>
</CardGroup>
## Publishing Best Practices
Before sharing your web app:
<Steps>
<Step title="Test the user experience">
Try your app on different devices and browsers to ensure it works smoothly.
</Step>
<Step title="Configure essential settings">
Set up your app name, icon, description, and any required legal information.
</Step>
<Step title="Confirm the URL is safe to share">
Web apps are public, so anyone with the link can use them. Share the URL only with the audience you intend to reach.
</Step>
<Step title="Choose deployment method">
Determine whether to share directly or embed on your website.
</Step>
</Steps>
<Tip>
Your web app configuration applies everywhere it's deployed. Changes to settings automatically update embedded versions too.
</Tip>
# Workflow Web Apps
Source: https://docs.dify.ai/en/cloud/use-dify/publish/webapp/workflow-webapp
Turn your workflows into powerful web applications with batch processing, result management, and streamlined user experiences
Workflow web apps transform your Dify workflows into production-ready applications that handle everything from single runs to large-scale batch operations. Users get a clean interface for input, real-time processing feedback, and comprehensive result management.
## How Workflow Apps Work
When you publish a workflow, Dify automatically creates a web interface that:
* **Collects input parameters** through forms based on your workflow's start variables
* **Processes requests** using your complete workflow logic
* **Handles results** with built-in saving, copying, and management features
* **Scales automatically** from single runs to batch processing hundreds of items
<Info>
Unlike chat apps that maintain conversation context, Workflow apps are designed for discrete tasks that produce specific outputs.
</Info>
<CardGroup>
<Card title="Single Execution" icon="play">
Run workflows one at a time with immediate results and feedback
</Card>
<Card title="Batch Processing" icon="layer-group">
Process hundreds of inputs simultaneously with CSV upload/download
</Card>
<Card title="Result Management" icon="bookmark">
Save, organize, and export outputs with built-in storage
</Card>
<Card title="More Like This" icon="copy">
Generate variations of successful outputs automatically
</Card>
</CardGroup>
## Single Execution
The default mode for Workflow apps handles individual requests with real-time processing:
<Frame>
</Frame>
**User Experience**:
1. **Fill input form**: Users provide parameters based on your workflow's start variables
2. **Click run**: The workflow executes with real-time progress indication
3. **View results**: Output appears with immediate access to copy, save, and feedback options
4. **Take actions**: Users can save important results, provide feedback, or generate similar outputs
Each result includes built-in actions:
* **Copy**: One-click copying to clipboard for easy sharing
* **Save**: Store results in the app's saved items for later access
* **Feedback**: Like/dislike ratings to help improve your workflow
* **More like this**: Generate variations based on the current result (if enabled)
## Batch Processing
When you need to run the same workflow on multiple inputs, batch processing handles hundreds of executions simultaneously:
<Tip>
Perfect for tasks like generating content for multiple topics, processing customer data, or analyzing large datasets.
</Tip>
### Set Up Batch Runs
<Steps>
<Step title="Switch to batch mode">
Click the **Run Batch** tab to access batch processing features.
<Frame>
</Frame>
</Step>
<Step title="Get the CSV template">
Download the template file to see the required column structure for your workflow's input variables.
<Frame>
</Frame>
</Step>
<Step title="Prepare your data">
Fill the template with your input data. Each row becomes one workflow execution.
</Step>
<Step title="Upload and run">
Upload your completed CSV file and start batch processing.
<Frame>
</Frame>
</Step>
</Steps>
### Batch Processing Benefits
* **Parallel execution**: Multiple workflow runs happen simultaneously
* **Progress tracking**: Real-time updates on completion status
* **Bulk export**: Download all results as a CSV file when finished
* **Error handling**: Failed items are clearly marked with error details
<Warning>
CSV files must use Unicode encoding to prevent import failures. When saving from Excel or similar tools, explicitly select "Unicode (UTF-8)" encoding.
</Warning>
## Result Management
Workflow apps include comprehensive result management to help users organize and reuse outputs:
### Save Results
<Frame>
</Frame>
**How saving works**:
* Users click **Save** on any result they want to keep
* Saved items appear in the dedicated **Saved** tab
* Each saved result includes the original inputs and full outputs
* Users can organize saved results and access them anytime
<Info>
Saved results persist across user sessions, making Workflow apps useful for building personal libraries of outputs.
</Info>
### Generate Variations
When you enable **More like this** in your workflow settings, users can generate variations of successful results:
<Frame>
</Frame>
**How it works**:
1. User gets a result they like
2. They click **More like this** to generate similar outputs
3. The workflow runs again with slight variations to produce different but related results
4. Users can iterate until they find the perfect output
<Tip>
**More like this** works especially well for creative workflows like content generation, where users want to explore different approaches to the same topic.
</Tip>
# Custom Endpoints
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/api-extension/api-extension
You can extend module capabilities through custom endpoints. Currently, the following extension types are supported:
* `moderation` Sensitive content moderation
* `external_data_tool` External data tools
Before extending module capabilities, you need to prepare an API and an API Key for authentication.
In addition to developing the corresponding module capabilities, you also need to follow the specifications below to ensure Dify correctly calls the API.
## API Specification
Dify will call your interface with the following specification:
```
POST {Your-API-Endpoint}
```
### Header
| Header | Value | Desc |
| --------------- | ------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `Content-Type` | application/json | The request content is in JSON format. |
| `Authorization` | Bearer \{api\_key} | The API Key is transmitted as a Token. You need to parse the `api_key` and verify that it matches the provided API Key to ensure interface security. |
### Request Body
```
{
"point": string, // Extension point, different modules may contain multiple extension points
"params": {
... // Parameters passed to each module extension point
}
}
```
### API Response
```
{
... // Content returned by the API, see the specification design of different modules for different extension point returns
}
```
## Validation
When configuring a custom endpoint in Dify, Dify will send a request to the API Endpoint to verify API availability.
When the API Endpoint receives `point=ping`, the interface should return `result=pong`, as follows:
### Header
```
Content-Type: application/json
Authorization: Bearer {api_key}
```
### Request Body
```
{
"point": "ping"
}
```
### Expected API Response
```
{
"result": "pong"
}
```
## Example
Here we use an external data tool as an example, where the scenario is to retrieve external weather information by region as context.
### API Example
```
POST https://fake-domain.com/api/dify/receive
```
**Header**
```
Content-Type: application/json
Authorization: Bearer 123456
```
**Request Body**
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
**API Response**
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
### Code Example
The code is based on the Python FastAPI framework.
1. Install dependencies
```
pip install fastapi[all] uvicorn
```
2. Write code according to the interface specification
```
from fastapi import FastAPI, Body, HTTPException, Header
from pydantic import BaseModel
app = FastAPI()
class InputData(BaseModel):
point: str
params: dict = {}
@app.post("/api/dify/receive")
async def dify_receive(data: InputData = Body(...), authorization: str = Header(None)):
"""
Receive API query data from Dify.
"""
expected_api_key = "123456" # TODO Your API key of this API
auth_scheme, _, api_key = authorization.partition(' ')
if auth_scheme.lower() != "bearer" or api_key != expected_api_key:
raise HTTPException(status_code=401, detail="Unauthorized")
point = data.point
# for debug
print(f"point: {point}")
if point == "ping":
return {
"result": "pong"
}
if point == "app.external_data_tool.query":
return handle_app_external_data_tool_query(params=data.params)
# elif point == "{point name}":
# TODO other point implementation here
raise HTTPException(status_code=400, detail="Not implemented")
def handle_app_external_data_tool_query(params: dict):
app_id = params.get("app_id")
tool_variable = params.get("tool_variable")
inputs = params.get("inputs")
query = params.get("query")
# for debug
print(f"app_id: {app_id}")
print(f"tool_variable: {tool_variable}")
print(f"inputs: {inputs}")
print(f"query: {query}")
# TODO your external data tool query implementation here,
# return must be a dict with key "result", and the value is the query result
if inputs.get("location") == "London":
return {
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind "
"Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
else:
return {"result": "Unknown city"}
```
3. Start the API service. The default port is 8000, the complete API address is: `http://127.0.0.1:8000/api/dify/receive`, and the configured API Key is `123456`.
```
uvicorn main:app --reload --host 0.0.0.0
```
4. Configure this API in Dify.
5. Select this custom endpoint in the App.
When debugging the App, Dify will request the configured API and send the following content (example):
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
The API response is:
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
## Local Debugging
Because Dify cannot reach API services on your private network, you can use [Ngrok](https://ngrok.com) to expose the API service endpoint to the public network to enable cloud debugging of local code. Steps:
1. Go to [https://ngrok.com](https://ngrok.com), register and download the Ngrok file.
<Frame>
</Frame>
2. After downloading, go to the download directory, extract the archive according to the instructions below, and execute the initialization script in the instructions.
```shell theme={null}
unzip /path/to/ngrok.zip
./ngrok config add-authtoken your-token
```
3. Check the port of your local API service:
<Frame>
</Frame>
And run the following command to start:
```shell theme={null}
./ngrok http port-number
```
A successful startup example looks like this:
<Frame>
</Frame>
4. Find the Forwarding address, as shown above: `https://177e-159-223-41-52.ngrok-free.app` (this is an example domain, please replace with your own), which is the public domain.
Following the example above, we expose the locally started service endpoint and replace the code example interface: `http://127.0.0.1:8000/api/dify/receive` with `https://177e-159-223-41-52.ngrok-free.app/api/dify/receive`
This API endpoint can now be accessed publicly. At this point, we can configure this API endpoint in Dify for local code debugging. For configuration steps, please refer to [External Data Tool](/en/cloud/use-dify/workspace/api-extension/external-data-tool-api-extension).
## Deploy Custom Endpoints Using Cloudflare Workers
We recommend using Cloudflare Workers to deploy your custom endpoints because Cloudflare Workers can conveniently provide a public network address and can be used for free.
For detailed instructions, see [Deploy Custom Endpoints Using Cloudflare Workers](/en/cloud/use-dify/workspace/api-extension/cloudflare-worker).
# Deploy Custom Endpoints Using Cloudflare Workers
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/api-extension/cloudflare-worker
## Procedure
Since Dify custom endpoints require a publicly accessible address as the API Endpoint, the endpoint needs to be deployed to a public address.
Here we use Cloudflare Workers to deploy the custom endpoint.
Clone the [Example GitHub Repository](https://github.com/crazywoola/dify-extension-workers). This repository contains a simple custom endpoint that can be modified as a starting point.
```bash theme={null}
git clone https://github.com/crazywoola/dify-extension-workers.git
cp wrangler.toml.example wrangler.toml
```
Open the `wrangler.toml` file and modify `name` and `compatibility_date` to your application name and compatibility date.
The configuration we need to pay attention to here is the `TOKEN` in `vars`. When adding a custom endpoint in Dify, we need to fill in this Token. For security reasons, we recommend using a random string as the Token. You should not write the Token directly in the source code, but pass it through environment variables. Therefore, please do not commit wrangler.toml to your code repository.
```toml theme={null}
name = "dify-extension-example"
compatibility_date = "2023-01-01"
[vars]
TOKEN = "bananaiscool"
```
This custom endpoint will return a random Breaking Bad quote. You can modify the logic of this custom endpoint in `src/index.ts`. This example demonstrates how to interact with third-party APIs.
```typescript theme={null}
// ⬇️ implement your logic here ⬇️
// point === "app.external_data_tool.query"
// https://api.breakingbadquotes.xyz/v1/quotes
const count = params?.inputs?.count ?? 1;
const url = `https://api.breakingbadquotes.xyz/v1/quotes/${count}`;
const result = await fetch(url).then(res => res.text())
// ⬆️ implement your logic here ⬆️
```
This repository simplifies all configurations except business logic. You can directly use `npm` commands to deploy your custom endpoint.
```bash theme={null}
npm install
npm run deploy
```
After successful deployment, you will get a public address that you can add in Dify as the custom endpoint. Please note not to omit the `endpoint` path. The specific definition of this path can be found in `src/index.ts`.
<Frame>
</Frame>
Alternatively, you can use the `npm run dev` command to deploy locally for testing.
```bash theme={null}
npm install
npm run dev
```
Related output:
```bash theme={null}
$ npm run dev
> dev
> wrangler dev src/index.ts
⛅️ wrangler 3.99.0
-------------------
Your worker has access to the following bindings:
- Vars:
- TOKEN: "ban****ool"
⎔ Starting local server...
[wrangler:inf] Ready on http://localhost:58445
```
After that, you can use tools like Postman for local interface debugging.
## About Bearer Auth
```typescript theme={null}
import { bearerAuth } from "hono/bearer-auth";
(c, next) => {
const auth = bearerAuth({ token: c.env.TOKEN });
return auth(c, next);
},
```
Our Bearer validation logic is in the above code. We use the `hono/bearer-auth` package to implement Bearer validation. You can use `c.env.TOKEN` in `src/index.ts` to get the Token.
## About Parameter Validation
```typescript theme={null}
import { z } from "zod";
import { zValidator } from "@hono/zod-validator";
const schema = z.object({
point: z.union([
z.literal("ping"),
z.literal("app.external_data_tool.query"),
]), // Restricts 'point' to two specific values
params: z
.object({
app_id: z.string().optional(),
tool_variable: z.string().optional(),
inputs: z.record(z.any()).optional(),
query: z.any().optional(), // string or null
})
.optional(),
});
```
We use `zod` to define parameter types here. You can use `zValidator` in `src/index.ts` to validate parameters. Use `const { point, params } = c.req.valid("json");` to get the validated parameters.
The `point` here has only two values, so we use `z.union` to define it. `params` is an optional parameter, so we use `z.optional` to define it. There will be an `inputs` parameter, which is a `Record<string, any>` type. This type represents an object with string keys and any values. This type can represent any object. You can use `params?.inputs?.count` in `src/index.ts` to get the `count` parameter.
## Get Cloudflare Workers Logs
```bash theme={null}
wrangler tail
```
***
**Reference**:
* [Cloudflare Workers](https://workers.cloudflare.com/)
* [Cloudflare Workers CLI](https://developers.cloudflare.com/workers/cli-wrangler/install-update)
* [Example GitHub Repository](https://github.com/crazywoola/dify-extension-workers)
# External Data Tool
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/api-extension/external-data-tool-api-extension
When creating AI applications, you can use external tools to obtain additional data through [Custom Endpoints](/en/cloud/use-dify/workspace/api-extension/api-extension) and assemble it into the prompt as additional information for the LLM.
## Extension Point
`app.external_data_tool.query`: Application external data tool query extension point.
This extension point passes the application variable content input by the end user and the conversation input content (fixed parameter for conversational applications) to the API as parameters.
You need to implement the corresponding tool query logic and return query results as string type.
### Request Body
```
{
"point": "app.external_data_tool.query", // Extension point type, fixed as app.external_data_tool.query
"params": {
"app_id": string, // Application ID
"tool_variable": string, // External data tool variable name, indicating the source of the corresponding variable tool call
"inputs": { // Variable values passed by end user, key is variable name, value is variable value
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Current conversation input content from end user, fixed parameter for conversational applications.
}
}
```
**Example**:
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
### API Response
```
{
"result": string
}
```
**Example**:
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
# Sensitive Content Moderation
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/api-extension/moderation-api-extension
This module is used to review the content input by end users and the content output by LLM in applications. It is divided into two extension point types.
## Extension Points
* `app.moderation.input`: End user input content review extension point
* Used to review variable content passed in by end users and conversation input content in conversational applications.
* `app.moderation.output`: LLM output content review extension point
* Used to review content output by LLM.
* When the LLM output is streaming, the output content will be segmented into 100-character chunks for API requests to avoid delayed reviews when output content is lengthy.
### app.moderation.input
When **Content Moderation > Review Input Content** is enabled in applications such as Chatflow, Agent, or Chatbot, Dify will send the following HTTP POST request to the corresponding custom endpoint:
#### Request Body
```
{
"point": "app.moderation.input", // Extension point type, fixed as app.moderation.input
"params": {
"app_id": string, // Application ID
"inputs": { // Variable values passed by end user, key is variable name, value is variable value
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Current conversation input content from end user, fixed parameter for conversational applications.
}
}
```
**Example**:
```
{
"point": "app.moderation.input",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"inputs": {
"var_1": "My SSN is 123-45-6789.",
"var_2": "My phone number is 123-456-7890."
},
"query": "Please help me update my account."
}
}
```
#### API Response
```
{
"flagged": bool, // Whether it violates validation rules
"action": string, // Action: direct_output outputs preset response; overridden overwrites input variable values
"preset_response": string, // Preset response (returned only when action=direct_output)
"inputs": { // Variable values passed by end user, key is variable name, value is variable value (returned only when action=overridden)
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Overwritten current conversation input content from end user, fixed parameter for conversational applications. (returned only when action=overridden)
}
```
**Example**:
* `action=direct_output`
```
{
"flagged": true,
"action": "direct_output",
"preset_response": "Your content violates our usage policy."
}
```
* `action=overridden`
```
{
"flagged": true,
"action": "overridden",
"inputs": {
"var_1": "My SSN is ***-**-****.",
"var_2": "My phone number is ***-***-****."
},
"query": "Please help me update my account."
}
```
### app.moderation.output
When **Content Moderation > Review Output Content** is enabled in applications such as Chatflow, Agent, or Chat Assistant, Dify will send the following HTTP POST request to the corresponding custom endpoint:
#### Request Body
```
{
"point": "app.moderation.output", // Extension point type, fixed as app.moderation.output
"params": {
"app_id": string, // Application ID
"text": string // LLM response content. When LLM output is streaming, this is content segmented into 100-character chunks.
}
}
```
**Example**:
```
{
"point": "app.moderation.output",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"text": "My SSN is 123-45-6789."
}
}
```
#### API Response
```
{
"flagged": bool, // Whether it violates validation rules
"action": string, // Action: direct_output outputs preset response; overridden overwrites input variable values
"preset_response": string, // Preset response (returned only when action=direct_output)
"text": string // Overwritten LLM response content. (returned only when action=overridden)
}
```
**Example**:
* `action=direct_output`
```
{
"flagged": true,
"action": "direct_output",
"preset_response": "Your content violates our usage policy."
}
```
* `action=overridden`
```
{
"flagged": true,
"action": "overridden",
"text": "My SSN is ***-**-****."
}
```
## Code Example
Below is a piece of `src/index.ts` code that can be deployed on Cloudflare. (For complete Cloudflare usage, please refer to [this documentation](/en/cloud/use-dify/workspace/api-extension/cloudflare-worker))
The code works by performing keyword matching to filter both Input (content entered by users) and Output (content returned by the model). Users can modify the matching logic according to their needs.
```
import { Hono } from "hono";
import { bearerAuth } from "hono/bearer-auth";
import { z } from "zod";
import { zValidator } from "@hono/zod-validator";
import { generateSchema } from '@anatine/zod-openapi';
type Bindings = {
TOKEN: string;
};
const app = new Hono<{ Bindings: Bindings }>();
// API format validation ⬇️
const schema = z.object({
point: z.union([
z.literal("ping"),
z.literal("app.external_data_tool.query"),
z.literal("app.moderation.input"),
z.literal("app.moderation.output"),
]), // Restricts 'point' to two specific values
params: z
.object({
app_id: z.string().optional(),
tool_variable: z.string().optional(),
inputs: z.record(z.any()).optional(),
query: z.any(),
text: z.any()
})
.optional(),
});
// Generate OpenAPI schema
app.get("/", (c) => {
return c.json(generateSchema(schema));
});
app.post(
"/",
(c, next) => {
const auth = bearerAuth({ token: c.env.TOKEN });
return auth(c, next);
},
zValidator("json", schema),
async (c) => {
const { point, params } = c.req.valid("json");
if (point === "ping") {
return c.json({
result: "pong",
});
}
// ⬇️ implement your logic here ⬇️
// point === "app.external_data_tool.query"
else if (point === "app.moderation.input"){
// Input check ⬇️
const inputkeywords = ["input filter test 1", "input filter test 2", "input filter test 3"];
if (inputkeywords.some(keyword => params.query.includes(keyword)))
{
return c.json({
"flagged": true,
"action": "direct_output",
"preset_response": "The input contains illegal content. Please try a different question!"
});
} else {
return c.json({
"flagged": false,
"action": "direct_output",
"preset_response": "Input is normal"
});
}
// Input check complete
}
else {
// Output check ⬇️
const outputkeywords = ["output filter test 1", "output filter test 2", "output filter test 3"];
if (outputkeywords.some(keyword => params.text.includes(keyword)))
{
return c.json({
"flagged": true,
"action": "direct_output",
"preset_response": "The output contains sensitive content and has been filtered by the system. Please try a different question!"
});
}
else {
return c.json({
"flagged": false,
"action": "direct_output",
"preset_response": "Output is normal"
});
};
}
// Output check complete
}
);
export default app;
```
# Manage Apps
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/app-management
Organize, maintain, and share your AI applications with powerful management tools and best practices
Managing your apps well is crucial for productive AI development. Dify provides comprehensive tools to organize, share, and maintain your applications throughout their lifecycle.
## App Organization
<CardGroup>
<Card title="Edit & Customize" icon="edit">
Update names, descriptions, icons, and branding for better organization
</Card>
<Card title="Duplicate & Template" icon="copy">
Create variations or use existing apps as templates for new projects
</Card>
<Card title="Import & Export" icon="right-left">
Share apps between workspaces using Dify's DSL format
</Card>
<Card title="Lifecycle Management" icon="recycle">
Safely delete apps when no longer needed
</Card>
</CardGroup>
## Edit Application Information
Keep your apps organized with clear, descriptive information:
<Frame>
</Frame>
<Steps>
<Step title="Access app settings">
Click "Edit info" in the upper left corner of your application.
</Step>
<Step title="Update details">
Modify the icon, name, or description to better reflect the app's purpose.
</Step>
<Step title="Consider your team">
Use names and descriptions that help team members understand what the app does.
</Step>
</Steps>
<Tip>
Use consistent naming conventions across your workspace. Consider prefixes like "Draft-", "Test-", or "Prod-" to indicate app status.
</Tip>
## Create App Variations
Duplication is perfect for creating variations or starting new projects from existing work:
**When to duplicate**:
* Creating A/B test versions with different prompts or models
* Adapting an app for different audiences or use cases
* Starting a new project based on successful patterns
* Creating backups before major changes
**How duplication works**:
* All configuration, prompts, and workflows are copied
* The new app gets a default name you can customize
* Original app remains unchanged
* Both apps run independently
## App Export and Import
Dify's DSL (Domain Specific Language) format lets you share apps between workspaces and teams:
<Frame>
</Frame>
### Export Applications
**Two ways to export**:
1. **From Studio page** - Click "Export DSL" in the application menu
2. **From orchestration** - Click "Export DSL" in the upper left corner
**What gets exported**:
* App configuration and metadata
* Workflow orchestration and node settings
* Model parameters and prompt templates
* Knowledge base connections (not the data itself)
**What doesn't get exported**:
* API keys for third-party tools (security measure)
* Actual knowledge base content
* Usage logs and analytics data
<Warning>
If your app uses Secret-type environment variables, you'll be asked whether to include them in the export. Be careful with sensitive information.
</Warning>
<Frame>
</Frame>
### Import Applications
<Frame>
</Frame>
**Import process**:
1. Upload your DSL file (YAML format)
2. System checks version compatibility
3. Warning appears if DSL version is older than current platform
4. App is created with all configurations from the file
**Version compatibility**: Your platform always runs the latest DSL version, so imported files are always compatible.
<Info>
Dify DSL is the AI application engineering standard (v0.6+) that captures complete app configurations in YAML format.
</Info>
## Safe App Deletion
Before deleting apps, understand the impact:
**What gets deleted**:
* All app configurations and prompts
* Workflow orchestration and settings
* Usage logs and analytics
* Published web apps and API access
* All user conversations and data
**Impact on users**:
* Published web apps stop working immediately
* API calls start returning errors
* All existing user sessions are terminated
<Steps>
<Step title="Consider alternatives">
Could you duplicate the app for backup, or just unpublish instead of deleting?
</Step>
<Step title="Notify stakeholders">
Let team members and users know about planned deletions.
</Step>
<Step title="Export if needed">
Create DSL backups of valuable configurations before deletion.
</Step>
<Step title="Confirm deletion">
Click "Delete" and confirm—this action cannot be undone.
</Step>
</Steps>
<Warning>
App deletion is permanent and cannot be undone. All associated data, logs, and user access will be lost immediately.
</Warning>
# Model Providers
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/model-providers
Use models with your AI credits, or connect your own provider accounts and keys
Every AI app you build runs on a model. Dify Cloud comes with popular models, and lets you connect your own provider accounts when you need more.
Models are shared across the workspace, so your whole team works with the same ones.
<Warning>
Only the workspace owner and admins can manage providers. Any key you add works across the whole workspace and bills to your own account with that provider.
</Warning>
## Use Models with Your AI Credits
Dify Cloud gives you AI credits to use models from a set of popular providers, so you don't need your own API key to start.
Install one of these providers from **Integrations** > **Model Provider** (or the [Marketplace](https://marketplace.dify.ai/)), and its models are ready to use. Each AI response consumes your AI credits.
An AI response is a single model call (one input and one output), and it counts as one response no matter how many tokens it uses. The number of credits a response costs depends on the model, with larger models costing more than smaller ones.
See the [Dify pricing page](https://dify.ai/pricing) for which providers AI credits support and how many credits each model costs.
## Use Your Own Account with a Supported Provider
Add your own API key to a supported provider when you want higher rate limits or billing through your own provider account.
1. In **Integrations** > **Model Provider**, install the provider if it isn't already.
2. Click **Setup** on its card, then enter your API key and any other required details. Dify checks the key before making the provider available.
Your key and AI credits can coexist. Set **Usage Priority** on the provider card to control which one Dify draws from first and falls back to the other, so a key you add can simply take over once your credits run out.
## Connect a Provider AI Credits Don't Support
To use a provider that AI credits don't support, install it first and run it on your own account. AI credits don't apply to these providers.
1. In **Integrations** > **Model Provider**, browse **Install model providers**, or open the [Marketplace](https://marketplace.dify.ai/) for the full list.
2. Install the provider, click **Setup**, and enter your API key along with any other required details.
## Add a Custom Model
A provider's models are ready as soon as you connect it, so you only add one by hand when the model you need isn't listed, such as a brand-new or fine-tuned model.
Click **Add Model** on the provider's card, then give the model a name and its credentials. Providers that serve only a fixed set of models don't offer this option.
<Info>
If the model you add matches the name and type of an existing one, Dify attaches the new key to that model instead of creating a duplicate.
</Info>
## Manage Your Keys
Add more than one key to a provider when you want to keep development and production apart or spread usage across several accounts.
* For a provider's own models, click **Configure** on its card to manage the keys they share.
<Frame>
<img alt="Manage Credentials for a Provider's Models" />
</Frame>
* For a custom model you added, click **Configure** on that model to manage its own keys.
<Columns>
<Frame>
<img alt="Custom Model Configuration" />
</Frame>
<Frame>
<img alt="Custom Model Credentials" />
</Frame>
</Columns>
<Warning>
A custom model relies on its own keys. Deleting its only key removes the model too.
</Warning>
To view every custom model's keys in one place, click **Manage Credentials** on the provider card.
<Frame>
<img alt="Manage Credentials for All Custom Models" />
</Frame>
Keys stay here even after the custom model is removed, so you can re-add the model later without re-entering its keys.
<Frame>
<img alt="Re-add a Removed Model" />
</Frame>
## Choose the Models Apps Use by Default
Apps and nodes that don't pick a model fall back to your workspace defaults. Click **Default Models** at the top-right corner to set one for each job:
* **System Reasoning Model**: the default for general LLM tasks.
* **Embedding Model**: indexes and retrieves knowledge base content.
* **Rerank Model**: reorders retrieval results by relevance.
* **Speech-to-Text Model**: turns audio into text.
* **Text-to-Speech Model**: turns text into audio.
## Spread Requests Across Keys with Load Balancing <Badge>Professional</Badge> <Badge>Team</Badge>
When one key handles many requests at once, it can hit the provider's rate limit and start failing.
Use load balancing to spread requests across several keys for the same model, so no single key becomes the bottleneck. Dify rotates through the keys in turn and rests any that hits its limit for a minute before trying it again.
1. Find the model in the list, click **Configure**, and select **Load Balancing**.
2. Click **Add credential** to add keys to the pool.
<Tip>
Add a higher-quota or faster key more than once to send more of the traffic its way.
</Tip>
<Frame>
<img alt="Add Credentials for Load Balancing" />
</Frame>
3. Turn on at least two keys, then click **Save**. A model using load balancing shows a marker in the list.
<Info>
Switch back to a single key anytime; your load balancing setup is kept for later use.
</Info>
# Personal Settings
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/personal-account-management
Manage your profile and preferences across all workspaces
Your personal account spans all workspaces you belong to. Profile settings, language preferences, and login credentials follow you everywhere, while each workspace maintains its own team dynamics and permissions.
## Account Setup
Your account is created automatically on first login. Sign in with GitHub, Google, or email verification code. Accounts with matching email addresses are linked automatically, so signing up with GitHub using `you@company.com` and later using email verification with the same address resolves to one account.
## Multi-Workspace Access
Your personal account can belong to multiple workspaces. Each workspace has its own team, applications, and billing, but your profile remains consistent across all of them.
**Switching workspaces**: Use the workspace selector in the top-left corner to switch between workspaces you have access to.
**Workspace independence**: Your role and permissions are set per workspace. You might be an Owner in one workspace and a Member in another.
## Profile Management
Update your profile information in **Settings → Account → Profile**. Changes apply across all workspaces you belong to.
**Profile picture**: Upload a custom avatar. This replaces the default initials-based avatar and appears in all workspaces.
**Display name**: How you appear to team members across all workspaces. Choose something that helps teammates identify you.
**Email address**: Your primary login credential and unique identifier. Changing your email affects every workspace using the old address.
## Language and Interface
**Display language**: Available languages include English, Simplified Chinese, and Traditional Chinese. This setting affects interface elements but not your application content.
**Change language**: Click your avatar, choose **Language**, then select your preferred language.
## Login Methods
Sign in with any of the following:
* **GitHub**: OAuth via your GitHub account.
* **Google**: OAuth via your Google account.
* **Email verification code**: One-time code delivered to your email address.
## Security
Social login (GitHub or Google) inherits the security posture of your chosen provider. Review the provider's security settings and monitor login activity through their platform.
Your personal settings follow you everywhere, but each workspace has its own roles and permissions.
<Warning>
Changing your email address affects all workspaces. If you want to change the email for just one workspace, ask that workspace to invite the new email as a separate user account.
</Warning>
# Integrations
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/plugins
Connect Dify to model providers, tools, data sources, and external services
Integrations connect your Dify apps to the outside world. They supply the model providers that power your apps, the tools your agents and workflows call, the data sources behind your knowledge bases, and the services that extend what you build.
Install an integration once, and every app in your workspace can use it. Browse and manage them all from **Integrations**.
## Integration Types
* [**Model Provider**](/en/cloud/use-dify/workspace/model-providers): The models that power your apps, from LLMs to embedding and rerank models.
* [**Tool**](/en/cloud/use-dify/workspace/tools): Capabilities your agents and workflows can call, including tool plugins, MCP servers, published workflows, and OpenAPI services.
* [**Data Source**](/en/cloud/use-dify/knowledge/knowledge-pipeline/authorize-data-source): External content for pipeline-built knowledge bases, such as Google Drive or Notion pages.
* [**Trigger**](/en/cloud/use-dify/nodes/trigger/plugin-trigger): Start a workflow automatically when an external event fires.
* **Agent Strategy**: The reasoning strategy an [Agent node](/en/cloud/use-dify/nodes/agent) follows to make decisions, select and call tools, and act on the results.
* [**Custom Endpoint**](/en/cloud/use-dify/workspace/api-extension/api-extension): Connect your own API to add content moderation or external data tools to your apps.
* **Extension**: Integrations that expose custom HTTP endpoints, extending Dify with capabilities the other categories don't cover.
## Install Integrations
Add integrations from three sources:
* [**Marketplace**](https://marketplace.dify.ai/): Official and partner integrations, tested and maintained.
* **GitHub**: Install from any public repository by URL and version.
* **Local upload**: Custom `.zip` packages for private or internal integrations.
## Permissions and Updates
The workspace owner and admins can set two workspace-wide permissions for integrations, each to **Everyone**, **Admins**, or **No one**:
* **Who can install and manage integrations**: Installing, upgrading, and removing. Defaults to **Everyone**.
* **Who can debug integrations**: Access to the debugging key. Defaults to **No one**.
Integrations can also be set to update automatically. Each category (tools, models, data sources, and so on) has its own update strategy (off, patch versions only, or always the latest), applied to every integration in the category or a chosen subset.
## Build Your Own
<Info>
Need an integration that doesn't exist yet? Build it with Dify's plugin SDK, then keep it private or publish it to the Marketplace. See [Develop a Plugin](/en/develop-plugin/getting-started/getting-started-dify-plugin).
</Info>
# Overview
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/readme
Workspaces are the foundational organizational unit in Dify—everything your team builds, configures, and manages exists within a workspace
A workspace is your team's complete AI environment in Dify. It contains and isolates everything your organization needs: applications, knowledge bases, team members, model configurations, integrations, and billing.
## The Workspace Mental Model
Every resource in Dify belongs to a workspace. When you create an app, it inherits the workspace's model configurations. When you add team members, they get access to workspace resources based on their role. When you configure models or install integrations, they become available to the entire workspace.
```
🏢 Your Organization
└── 📁 Workspace
├── 🤖 Apps (chatbots, workflows, agents)
├── 📊 Knowledge Bases (documents, embeddings)
├── 👥 Team Members (roles & permissions)
├── 🧠 Model Providers (API keys, configurations)
├── 🔧 Integrations (model providers, tools, custom code)
└── 💳 Billing (subscription, limits, usage)
```
This workspace-first design means your resources are completely isolated from other organizations, team members can only access what they're permitted to see, and you configure models and billing once for the entire workspace.
## Workspace Creation
A workspace is created automatically on your first login. You become the owner with full permissions. Each account can create only one workspace.
<Info>
Your personal account can belong to multiple workspaces. Switch between them using the workspace selector in the top-left corner.
</Info>
## How Resources Connect
Applications you build can use any model providers configured in the workspace, access all workspace knowledge bases, and use installed integrations. Team members see applications based on their workspace permissions.
Workspace roles determine access across all resources:
* **Owners** control billing, model providers, and workspace settings
* **Admins** manage team members and configure models and integrations
* **Editors** build applications and manage knowledge bases
* **Members** use published applications
# Billing
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/subscription-management
Manage your workspace subscription, plan changes, and the Dify for Education discount
Billing in Dify is workspace-scoped. Your subscription sets the team member limit, feature access, and usage quotas for the entire workspace.
For the available plans, what each includes, and pricing, see the [Dify pricing page](https://dify.ai/pricing).
## Manage Subscriptions
Only the workspace owner and admins can manage the workspace's subscription in **Settings** > **Billing**.
* **View subscription details**: see your current plan, usage, and billing history, or download invoices.
* **Upgrade**: click **Upgrade** and choose a higher plan. It takes effect immediately, once you pay the difference for the rest of the current billing period.
* **Downgrade**: click **Manage** to open the Stripe billing portal, then click **Update subscription** and choose a lower plan. It takes effect at the start of your next billing cycle; you keep your current plan until then.
* **Cancel or update billing**: click **Manage** to open the Stripe billing portal, where you can cancel the subscription or change the payment method. After cancellation, the workspace keeps its current plan until the end of the paid period, then returns to the free Sandbox plan.
## Dify for Education
Current students, teachers, and educational staff can verify their educational affiliation to use the Yearly Professional plan for free. Re-verification is required annually.
An education workspace includes all Professional plan features and resource quotas, except that AI credits stay at the Sandbox level: 200 one-time credits for built-in model usage, with no monthly refill. When the credits run out, configure your own [model provider](/en/cloud/use-dify/workspace/model-providers) API keys to keep using models.
### Prerequisites
* 18 years of age or older
* Currently enrolled at an educational institution, or employed there as a teacher or school administrator
* A Dify account registered with a school-issued email address for current students or staff
<Info>
Personal and alumni-only email addresses aren't eligible, and Dify may request proof of current enrollment or employment.
If Dify detects abuse or other risks involving multiple accounts on a school's email domain, it may restrict all new applications from that domain under the [Dify Terms of Service](https://dify.ai/terms), with no individual exceptions.
</Info>
### Steps
<Steps>
<Step title="Create Account">
Register at [cloud.dify.ai](https://cloud.dify.ai/signin) with your educational email.
</Step>
<Step title="Apply for Verification">
Go to **Settings** > **Billing** > **Get Education Verified**. Once your email domain passes the automatic check, enter your school's full name, select your role, and agree to the terms. The result appears immediately.
</Step>
<Step title="Apply Discount to Workspace">
1. After approval, select the workspace you want to use the education discount with (you must be its owner or an admin), then click **Use education discount**.
You'll be redirected to checkout with the **Yearly Professional Plan** and discount pre-applied. The discount covers the entire year, so you won't be charged.
<Note>
The education discount only applies to the Yearly Professional plan and can be used for one workspace per verification.
</Note>
2. Complete checkout to activate the subscription.
</Step>
</Steps>
### FAQ
<AccordionGroup>
<Accordion title="Why was I charged despite the education discount?">
You likely selected the Monthly Professional plan. The education discount applies only to the **Yearly** plan, so the Monthly plan charges the full price.
To resolve this, cancel the current subscription, wait for the billing cycle to end, then subscribe to the **Yearly** Professional plan with the education discount.
</Accordion>
<Accordion title="What if I already have a paid subscription?">
The education discount cannot be applied to an existing paid plan.
To resolve this, cancel your current subscription, wait for the billing cycle to end, then subscribe to the **Yearly** Professional plan with the education discount.
</Accordion>
<Accordion title="Why was my verification rejected?">
Common reasons: non-educational email, inaccurate information, or misuse of privileges. Appeal via [support@dify.ai](mailto:support@dify.ai).
If your school's email domain is under a domain-level restriction, it applies to every account on that domain and can't be lifted individually.
</Accordion>
<Accordion title="Can I use a personal email?">
No. Verification requires a school-issued email address for current students or staff. Personal and alumni-only addresses don't qualify.
</Accordion>
<Accordion title="What happens when my free year ends?">
The education subscription doesn't renew automatically, so you won't be charged. When it ends, the workspace returns to the free Sandbox plan.
To keep the discount, re-verify your educational affiliation when prompted (Dify reminds you by email before your status expires). You'll receive a new discount for the next year, which you can use to subscribe to the Yearly Professional plan again.
</Accordion>
<Accordion title="Do I keep my education status after graduating?">
Your existing verified status remains valid until it expires, as long as the verified email address remains active, unchanged, and linked to your Dify account.
Annual re-verification, however, requires current enrollment or employment, so an alumni-only email address can't be used for a new application or re-verification.
</Accordion>
<Accordion title="What if I change my Dify account email address?">
Education Verified status is tied to you and the email address you verified with, and it isn't transferable. A new email address doesn't inherit the status, and changing your account email may lead Dify to revoke it.
If the new address also meets the eligibility requirements, you can apply for verification again, or contact [support@dify.ai](mailto:support@dify.ai).
</Accordion>
</AccordionGroup>
# Manage Members
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/team-members-management
Add teammates to your workspace and manage the roles that control their access
Workspace members are added and managed in **Settings** > **Members**. Each member's access is determined by the role they hold.
## Team Size Limits
The number of members your workspace can include depends on your subscription plan:
* **Sandbox**: 1 member
* **Professional**: 3 members
* **Team**: 50 members
To raise your team size limit, upgrade your plan from **Settings** > **Billing**.
## Roles
There are four built-in roles:
* **Owner**: Full control of the workspace. One per workspace.
* **Admin**: Manage members and model providers, plus everything an Editor can do.
* **Editor**: Create, edit, and delete apps and knowledge bases.
* **Normal**: Use published apps only.
<Info>
The Owner, Admin, and Editor roles can *create* knowledge bases, while who can *see and use* an existing one is controlled in its own settings. See [Manage Knowledge Settings](/en/cloud/use-dify/knowledge/manage-knowledge/introduction) for details.
</Info>
## Add Members
The Owner and Admins can add members.
Select **Add**, enter one or more email addresses, choose a role, and send the invitation. An invitation link will be emailed to each address. The links also appear in the **Invitation sent** dialog, where you can copy and share them directly.
Invitation links expire after 72 hours; if someone doesn't accept in time, invite again to send a fresh link.
## Manage Members
**Change a role:** The Owner and Admins can change any member's role, and it takes effect on the member's next action, even if they're currently signed in. The Owner's role can only be changed through an ownership transfer.
**Remove a member:** The Owner and Admins can remove any member. This revokes the member's workspace access right away. The apps and knowledge bases they created stay in the workspace. The Owner can't be removed.
**Transfer ownership:** Only the Owner can transfer ownership. The transfer is confirmed with a verification code emailed to the Owner. Once verified, the chosen member becomes the new Owner and the previous Owner becomes an Admin.
# Dify Tools
Source: https://docs.dify.ai/en/cloud/use-dify/workspace/tools
Manage tools that enable LLMs to interact with external services and APIs
Add tools to your apps so the LLM can call external services and APIs to access real-time data or perform actions, such as web searches, database queries, or content processing.
Use tools in:
* Workflow / Chatflow apps, as standalone [Tool nodes](/en/cloud/use-dify/nodes/tools) or within [Agent nodes](/en/cloud/use-dify/nodes/agent#classic-agent)
* [Agent apps](/en/cloud/use-dify/build/new-agent/build#tools)
* [Legacy Agent apps](/en/cloud/use-dify/build/agent#extend-the-agent-with-dify-tools)
Manage all your tools from **Integrations** > **Tools**.
## Tool Types
<Tabs>
<Tab title="Tool Plugin">
Ready-to-use tools from Dify and the community for common utilities and popular services. Built-in ones like Current Time work out of the box; install more from the [Marketplace](https://marketplace.dify.ai/).
Some tool plugins, such as Google and GitHub, need authentication first. Set workspace-level credentials in **Integrations** > **Tools** > **Tool Plugin**, or in the tool's settings inside an app or node.
</Tab>
<Tab title="Swagger API">
Integrate a service that isn't available as a tool plugin by importing its OpenAPI (Swagger) specification.
Paste the schema, import it from a URL, or start from the provided example, and Dify generates the tool interface for you.
</Tab>
<Tab title="Workflow">
Turn any Workflow that starts with a User Input node into a tool, so you can reuse multi-step logic across apps. Chatflows cannot be used as tools.
<Frame>
<img alt="Workflow as Tool" />
</Frame>
</Tab>
<Tab title="MCP">
Connect an [MCP server](https://modelcontextprotocol.io/) to import its tools into Dify. An MCP server wraps external resources, such as databases, file systems, or APIs, and exposes them through a standard interface, so your apps can call them like any other tool.
<Tip>
To publish one of your own Dify apps *as* an MCP server instead, see [Publish as an MCP Server](/en/cloud/use-dify/publish/publish-mcp).
</Tip>
### Connect an MCP Server
<Info>
Only MCP servers with [HTTP transport](https://modelcontextprotocol.io/docs/learn/architecture#transport-layer) are supported.
</Info>
Add a server by providing its URL, a name, and a unique server identifier. Dify connects, authorizes if needed, and imports the server's tools so your apps can call them.
You can update the tool list later to pull the server's latest tools, though doing so can break an app if a tool it uses is removed or changed.
<Note>
* Apps reference a server by its identifier. If you change it later, the server's tools stop working in apps that used the old one; re-add the tools in each affected app to restore them.
* Exported apps reference servers by identifier too, so to run one in another workspace, recreate the same servers there with matching identifiers.
</Note>
### Authentication
**Dynamic Client Registration** (on by default) lets Dify obtain OAuth credentials from the server automatically, so you don't register an application yourself. Leave it on whenever the server supports it.
Turn it off when the server doesn't support automatic registration, or when you must use your team's existing OAuth application. Enter its **Client ID** and **Client Secret**, then register the redirect URL Dify shows.
### Advanced Options
#### Custom Headers
Send additional HTTP headers with every request to the server. Commonly used for servers that authenticate with a static token or API key (e.g., `Authorization: Bearer <token>`) rather than OAuth, but applicable whenever the server expects custom headers.
Header values can also be dynamic: `{{request.headers.X-Custom-Auth}}` is replaced at call time with the `X-Custom-Auth` header of the HTTP request that triggered the run (a Service API call, for example), letting you pass each caller's credentials through to the server.
A header the request doesn't carry resolves to an empty value; when a run has no originating HTTP request, the placeholder text is sent unchanged.
#### Timeouts
Control how long Dify waits on the server. Raise the request timeout when the server is slow to respond, and the SSE read timeout for long-running, streamed results. Change them only if you hit timeout errors.
</Tab>
</Tabs>
# Key Concepts
Source: https://docs.dify.ai/en/learn/key-concepts
Quick overview of essential Dify concepts
### Dify App
Dify is made for agentic app building. In **Studio**, you can quickly build agentic workflows via a drag & drop interface and publish them as apps. You can access published apps via API, the web, or as an [MCP server](/en/cloud/use-dify/publish/publish-mcp). Dify offers two main app types: Workflow and Chatflow. You will need to choose an app type when creating a new app.
<Info>
We recommend choosing Workflow or Chatflow your app type. But in addition to these, Dify also offers 3 more basic app types: Chatbot, Agent, and Text Generator.
<Frame>
<img alt="App Type Selector" />
</Frame>
These app types run on the same workflow engine underneath, but comes with simpler legacy interfaces:
<Frame>
<img alt="Chatbot Interface" />
</Frame>
</Info>
### Workflow
Build Workflow apps to handle single-turn tasks. The webapp interface and API provides easy access to batch execute many tasks at once.
<Info>
Underneath it all, workflow forms the basis for all other app types in Dify.
</Info>
Every workflow begins with a [start node](/en/cloud/use-dify/nodes/start): either User Input (on-demand, triggered by a user or API call) or a Trigger (automatic, on a schedule or in response to external events).
### Chatflow
Chatflow is a special type of workflow app that gets triggered at every turn of a conversation. Other than workflow features, Chatflow comes with the ability to store and update custom conversation-specific variables, enable memory in LLM nodes, and stream formatted text, images, and files at different points throughout the Chatflow run.
Chatflows always start with User Input.
### Dify DSL
All Dify apps can be exported into a YAML file in Dify's own DSL (Domain-Specific Language) and you may create Dify apps from these DSL files directly. This makes it easy to port apps to other Dify instances and share with others.
### Variables
A variable is a labeled container to store information, so you can find and use that information later by referencing its name. You'll come across different types of variables when building a Dify app:
**Inputs**: You can specify any number of input variables at the [User Input](/en/cloud/use-dify/nodes/user-input) node for your app's end users to fill in.
<Frame>
<img alt="User Input Node Variables" />
</Frame>
Additionally, the User Input node comes with a set of input variables that you can reference later in the flow. Depending on the app type (Workflow or Chatflow), different variables are provided.
<Tabs>
<Tab title="Workflow">
| Variable Name | <div>Data Type</div> | Description | Notes |
| :-------------------- | :------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------- |
| `sys.user_id` | String | User ID: A unique identifier automatically assigned by the system to each user when they use a Workflow application. It is used to distinguish different users. | |
| `sys.app_id` | String | App ID: A unique identifier automatically assigned by the system to each App. This parameter is used to record the basic information of the current application. | This parameter is used to differentiate and locate distinct Workflow applications for users with development capabilities. |
| `sys.workflow_id` | String | Workflow ID: This parameter records information about all nodes information in the current Workflow application. | This parameter can be used by users with development capabilities to track and record information about the nodes contained within a workflow. |
| `sys.workflow_run_id` | String | Workflow Run ID: Used to record the runtime status and execution logs of a Workflow application. | This parameter can be used by users with development capabilities to track the application's historical execution records. |
| `sys.timestamp` | Number | The start time of each workflow execution. | |
</Tab>
<Tab title="Chatflow">
| Variable Name | <div>Data Type</div> | Description | Notes |
| :-------------------- | :------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sys.conversation_id` | String | A unique ID for the chatting box interaction session, grouping all related messages into the same conversation, ensuring that the LLM continues the chatting on the same topic and context. | |
| `sys.dialogue_count` | Number | The number of conversations turns during the user's interaction with a Chatflow application. The count automatically increases by one after each chat round and can be combined with if-else nodes to create rich branching logic.<br /><br />For example, LLM will review the conversation history at the X conversation turn and automatically provide an analysis. | |
| `sys.user_id` | String | A unique ID is assigned for each application user to distinguish different conversation users. | The Service API does not share conversations created by the web app. This means users with the same ID will have separate conversation histories between API and web app interfaces. |
| `sys.app_id` | String | App ID: A unique identifier automatically assigned by the system to each App. This parameter is used to record the basic information of the current application. | This parameter is used to differentiate and locate distinct applications for users with development capabilities. |
| `sys.workflow_id` | String | Workflow ID: This parameter records information about all nodes information in the current application. | This parameter can be used by users with development capabilities to track and record information about the nodes contained within a workflow. |
| `sys.workflow_run_id` | String | Workflow Run ID: Used to record the runtime status and execution logs of an application. | This parameter can be used by users with development capabilities to track the application's historical execution records. |
</Tab>
</Tabs>
User inputs are set at the start of each workflow run and cannot be updated.
**Outputs**: Each node produces one or more outputs that can be referenced in subsequent nodes. For instance, the LLM node has outputs:
<Frame>
<img alt="LLM Node Output Variables" />
</Frame>
Like inputs, node outputs cannot be updated either.
**Environment Variables**: Store secrets like API keys outside the app itself, so sharing your app's DSL doesn't expose them. An environment variable can also hold a model configuration shared by multiple LLM nodes; editing the variable updates the model in every node that uses it.
**Conversation Variables (Chatflow only)**: These variables are conversation-specific -- meaning they persist over multi-turn Chatflow runs in a single conversation so you can store and access dynamic information like to-do list and token cost. You can update the value of a conversation variable via the Variable Assigner node:
<Frame>
<img alt="Conversation Variables Panel" />
</Frame>
### Variable Referencing
You can easily pass variables to any node when configuring its input field by selecting from a dropdown:
<Frame>
<img alt="Variable Picker Dropdown" />
</Frame>
You can also insert variable values into complex text inputs by typing `/` slash, and selecting the desired variable from the dropdown.
<Frame>
<img alt="Variable Slash Insert" />
</Frame>
# Lesson 1: What is a Workflow?
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-01
## 👋 Welcome to Dify 101
We are going to take you from Zero to Hero. By the end of this course, you will build your very own Advanced AI Email Assistant.
Let's leave coding behind for a second and talk about cooking.
Imagine you want to cook a dish that you haven't made before. To make that happen, you need a **Recipe**. A recipe is just like a workflow! It tells you exactly what to do, in what order, to get the dish you want.
## Meet Workflow
In Dify, you are the head chef who writes a Recipe for the AI to follow. Here're the things you need to prepare beforehand:
1. Input (Ingredients): The information you give the AI. This could be a user's question, a PDF document, or a messy email draft.
2. Process (Instructions): The steps you force the AI to take. For example: First, summarize this text. Next, translate it into Spanish. Finally, format it as a LinkedIn post.
3. Output (The Dish): The final result the AI hands back to you.
To sum up, a workflow is a flowchart that asks AI to complete tasks in a specific order.
This is a Smart ID Scanner workflow. Its job is to extract the information on front and back of an ID card, then send these texts back to you.
<Frame>
<img alt="Workflow Example" />
</Frame>
### Node
Let's have a closer look of the workflow above. That whole process is simply made up of a few connected steps: **Uploading the image, Extracting the information, and Combining the results**.
Each of these steps is called a **Node**.
Think of them like runners in a relay race: each node has a specific task. Once it finishes its turn, it passes the baton to the next node in line.
Dify offers you a box of ready-to-use nodes, such as the LLM, Knowledge Retrieval, If/Else, Tools, etc.
You can connect these nodes just by dragging and dropping—it's like building with the Lego blocks! You can easily snap them together to create a powerful automated workflow.
## It's Your Turn
1. Go [Dify](https://dify.ai/) and click **Get Started** in the upper right corner.
2. Click on Explore. This is a library which collects different workflow of different scenarios.
<Frame>
<img alt="Explore" />
</Frame>
3. Pick a template that looks like a right fit for you. Don't worry if you don't understand every setting yet—just look at how the nodes are connected.
# Lesson 2: Head and Tail (Start & Output Node)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-02
In the last lesson, we compared a Workflow to a Recipe. Today, we are stepping into the professional kitchen to prep our ingredients (Start) and get our serving plates ready (Output).
## Create the App
<Steps>
<Step title="Create from Blank">
Click on **Studio** at the top of the screen. Under Create App on the left, click **Create from Blank**.
<Frame>
<img alt="Create the App" />
</Frame>
</Step>
<Step title="Configure App Type">
Select **Workflow** as the app type, fill up **App Name & Icon**, then click **Create**.
<Frame>
<img alt="App Name & Icon" />
</Frame>
</Step>
<Step title="Choose Start Node Type">
Click User Input, and you'll see a new popup window. There are two options here that decide how your app starts running:
* **User Input**
This is **Manual Mode**. The workflow only starts working when you (the user) type something into the chat box.
Best for: Most AI apps. For example, chatbots, writing assistants, translation, etc.
* **Trigger**
This is **Automatic Mode**. It runs automatically based on a signal (like 8:00 AM every morning, or a specific event).
Best for: Repetitive task that runs on a specific time, or run this workflow after a task is completed else where. For example, daily news summary.
<Frame>
<img alt="Trigger" />
</Frame>
</Step>
</Steps>
## Meet the Orchestration Canvas
After selecting the Start node, you will see a large blank area. This is your orchestration canvas where you will design, build, and test your workflow.
<Frame>
<img alt="Orchestration Studio" />
</Frame>
Remember the Nodes we learned in Lesson 1? The user input node you see on the canvas now is where everything begins.
Every complete workflow relies on a basic skeleton: the Start Node (The Head) and the Output Node (The Tail).
## The Start Node
<Frame>
<img alt="Start Node" />
</Frame>
The Start Node is the only entrance to your entire workflow. It's like the Prep Ingredients step in cooking. Its job is to define what information the workflow needs to receive from the user to get started.
We just selected **User Input** as our Start Node.
### Core Concept: Variables
Inside the Start Node, you will see the word **Variable**. Don't panic! You can think of a variable as a **Storage Box with a Label**.
Each box is designed to hold a specific type of information:
For example, if you are building a Travel Planner, you need the user to provide two pieces of information: `Destination` and `Travel Days`.
User A might want to go to Japan for 5 days. User B might want to go to Paris for 3 days.
Every user provides different content, so every time the app runs, the stuff inside these boxes changes.
This is the meaning of a Variable—digging a hole for the user to fill, helping your workflow to handle different requests flexibly every time.
## The End Node (Output)
<Frame>
<img alt="Output" />
</Frame>
This is the finish line of the workflow. Think of it as Serving the Dish and it defines what the user actually sees at the very end.
For example, remember that Travel Planner we talked about? If the user inputs Destination: Paris and Duration: 5 Days in the User Input Node. The Output Node is where the system finally hands over the result: Here is your complete 5-Day Itinerary for Paris.
To sum up, the Start Node and End Node define the basic input and output, shaping the skeleton of your app.
## Hands-On Practice: Start Building an AI Email Assistant
Let's build the basic framework for an AI Assistant that helps you write emails.
<Steps>
<Step title="Create the App">
You can either:
* Continue on the canvas you just opened, or
* Go back to Studio → Create Blank App → select Workflow, and name it Email Assistant (Remember to select **User Input** in the popup!)
</Step>
<Step title="Configure the Start Node (Prep Ingredients)">
If you need AI to help you with a email reply, what information do you need to give it?
That's right: usually the Customer's Name and the Original Email Content.
1. Click on the **Start** node. In the panel on the right, look for **Input Field** and click the **+** button.
<Frame>
<img alt="User Input Field" />
</Frame>
2. In the popup, we will create two variables (two storage boxes):
**Variable 1 (For the Customer Name)**
<Frame>
<img alt="Add First Variable" />
</Frame>
* Field Type: Text (Short Text)
* Variable Name: `customer_name`
* Label Name: Customer Name
* Keep other options as default
**Variable 2 (For the Email Content)**
<Frame>
<img alt="Add Second Variable" />
</Frame>
* Field Type: Click the dropdown and select **Paragraph** (Since emails are usually long, a Paragraph box is bigger and holds more text)
* Variable Name: `email_content`
* Label Name: Original Email
* Max Length: Manually change this to **2000** to ensure it fits long emails
<Tip>
**Variable Name vs. Label Name**
You might notice we had to fill in two names. What's the difference?
* **Variable Name**: This is the ID card for the system. It must be unique, use English letters, and cannot have spaces.
* **Label Name**: This is the Label for the users. You can name it with any language (English, Chinese, etc.). It will be shown on the screen.
</Tip>
</Step>
<Step title="Create the End Node (Set the Goal)">
Right-click anywhere on the blank white space of the canvas. Select **Add Node** and select **Output** from the list.
<Frame>
<img alt="Create the End Node" />
</Frame>
</Step>
</Steps>
Here's everything on your canvas: a **Start Node** ready to receive a name and an email, and an **Output Node** waiting to send the final result.
<Frame>
<img alt="Start Node and Output" />
</Frame>
We have successfully built basic frame of the workflow. The empty space in the middle is where we will place the LLM (AI Brain) Node in the next lesson to process this information.
## Mini Challenge
**Task**: If you needed to create a Travel Plan Generator, what variables should the Start Node include?
<Tip>
Try exploring the Field Types in **Add Variable**.
</Tip>
# 30-Minute Quick Start
Source: https://docs.dify.ai/en/quick-start
Dive into Dify through an example app
<Info>
This quick start uses **Dify Cloud**, the fastest way to get going: free to start, AI credits included, and nothing to install. Prefer to run Dify yourself? [Self-host Dify](/en/self-host/deploy/quick-start/docker-compose), then follow the same steps on your own instance.
</Info>
This step-by-step tutorial will walk you through creating a multi-platform content generator from scratch.
Beyond basic LLM integration, you'll discover how to use powerful Dify nodes to orchestrate sophisticated AI applications faster with less effort.
By the end of this tutorial, you'll have a workflow that takes whatever content you throw at it (text, documents, or images), adds your preferred voice and tone, and spits out polished, platform-specific social media posts in your chosen language.
The complete workflow is shown below. Feel free to refer back to this as you build to stay on track and see how all the nodes work together.
<Frame>
<img alt="Workflow Overview" />
</Frame>
## Before You Start
<Steps>
<Step title="Sign Up">
Go to [cloud.dify.ai](https://cloud.dify.ai) and sign up for free.
New accounts start on the Sandbox plan, which includes 200 AI credits for calling models from providers like OpenAI, Anthropic, and Gemini.
<Info>
The Sandbox AI credits are a one-time allocation and don't renew monthly.
</Info>
</Step>
<Step title="Set Up the Model Provider">
Go to **Integrations** > **Model Provider** and install the OpenAI model provider. This tutorial uses `gpt-5.2` for the examples.
No API key is required for the models covered by your AI credits; they're ready to use once the provider is installed. You can also configure your own API key and use it instead.
</Step>
<Step title="Configure the Default Model">
1. In the top-right corner of the **Model Provider** page, click **Default Models**.
2. Set the **System Reasoning Model** to `gpt-5.2`. This becomes the default model in the workflow.
</Step>
</Steps>
## Step 1: Create a New Workflow
1. Go to **Studio**, then select **Create from Blank** > **Workflow**.
2. Name the workflow `Multi-platform content generator` and click **Create**. You'll automatically land on the workflow canvas to start building.
3. Select the User Input node to start our workflow.
## Step 2: Orchestrate & Configure
<Note>
Keep any unmentioned settings at their default values.
</Note>
<Tip>
Give nodes and variables clear, descriptive names to make them easier to identify and reference.
</Tip>
### 1. Collect User Inputs: User Input Node
<Info>
First, we need to define what information to gather from users for running our content generator, such as the draft text, target platforms, desired tone, and any reference materials.
The User Input node is where we can easily set this up. Each input field we add here becomes a variable that all downstream nodes can reference and use.
</Info>
Click the User Input node to open its configuration panel, then add the following input fields.
<Accordion title="Reference materials - text">
* Field type: `Paragraph`
* Variable Name: `draft`
* Label Name: `Draft`
* Max length: `2048`
* Required: `Yes`
</Accordion>
<Accordion title="Reference materials - files">
* Field type: `File list`
* Variable Name: `user_file`
* Label Name: `Upload File (≤ 10)`
* Support File Types: `Document`, `Image`
* Upload File Types: `Both`
* Max number of uploads: `10`
* Required: `No`
</Accordion>
<Accordion title="Voice and tone">
* Field type: `Paragraph`
* Variable Name: `voice_and_tone`
* Label Name: `Voice & Tone`
* Max length: `2048`
* Required: `No`
</Accordion>
<Accordion title="Target platform">
* Field type: `Short Text`
* Variable Name: `platform`
* Label Name: `Target Platform (≤ 10)`
* Max length: `256`
* Required: `Yes`
</Accordion>
<Accordion title="Language requirements">
* Field type: `Select`
* Variable Name: `language`
* Label Name: `Language`
* Options:
* `English`
* `日本語`
* `简体中文`
* Required: `Yes`
</Accordion>
<Frame>
<img alt="User Input" />
</Frame>
### 2. Identify Target Platforms: Parameter Extractor Node
<Info>
Since our platform field accepts free-form text input, users might type in various ways: `x and linkedIn`, `post on Twitter and LinkedIn`, or even `Twitter + LinkedIn please`.
However, we need a clean and structured list, like `["Twitter", "LinkedIn"]`, that downstream nodes can work with reliably.
This is the perfect job for the Parameter Extractor node. In our case, it uses the gpt-5.2 model to analyze users' natural language, recognize all these variations, and output a standardized array.
</Info>
After the User Input node, add a Parameter Extractor node and configure it:
1. In the **Input Variable** field, select `User Input/platform`.
2. Add an extract parameter:
* Name: `platform`
* Type: `Array[String]`
* Description: `The platform(s) for which the user wants to create tailored content.`
* Required: `Yes`
3. In the **Instruction** field, paste the following to guide the LLM in parameter extraction:
```markdown INSTRUCTION theme={null}
# TASK DESCRIPTION
Parse platform names from input and output as a JSON array.
## PROCESSING RULES
- Support multiple delimiters: commas, semicolons, spaces, line breaks, "and", "&", "|", etc.
- Standardize common platform name variants (twitter/X→Twitter, insta→Instagram, etc.)
- Remove duplicates and invalid entries
- Preserve unknown but reasonable platform names
- Preserve the original language of platform names
## OUTPUT REQUIREMENTS
- Success: ["Platform1", "Platform2"]
- No platforms found: [No platforms identified. Please enter a valid platform name.]
## EXAMPLES
- Input: "twitter, linkedin" → ["Twitter", "LinkedIn"]
- Input: "x and insta" → ["Twitter", "Instagram"]
- Input: "invalid content" → [No platforms identified. Please enter a valid platform name.]
```
<Check>
Note that we've instructed the LLM to output a specific error message for invalid inputs, which will serve as the end trigger for our workflow in the next step.
</Check>
<Frame>
<img alt="Parameter Extractor" />
</Frame>
### 3. Validate Platform Extraction Results: IF/ELSE Node
<Info>
What if a user enters an invalid platform name, like `ohhhhhh` or `BookFace`? We don't want to waste time and tokens generating useless content.
In such cases, we can use an IF/ELSE node to create a branch that stops the workflow early. We'll set a condition that checks for the error message from the Parameter Extractor node; if that message is detected, the workflow will route directly to an Output node and end.
</Info>
<Frame>
<img alt="IF Branch" />
</Frame>
1. After the Parameter Extractor node, add an IF/ELSE node.
2. On the IF/ELSE node's panel, define the **IF** condition:
**IF** `Parameter Extractor/platform` **contains** `No platforms identified. Please enter a valid platform name.`
3. After the IF/ELSE node, add an Output node to the IF branch.
4. On the Output node's panel, set `Parameter Extractor/platform` as the output variable.
### 4. Separate Uploaded Files by Type: List Operator Node
<Info>
Our users can upload both images and documents as reference materials, but these two types require different handling with `gpt-5.2`: images can be interpreted directly via its vision capability, while documents must first be converted to text before the model can process them.
To manage this, we'll use two List Operator nodes to filter and split the uploaded files into separate branches: one for images and one for documents.
</Info>
<Frame>
<img alt="List Operator" />
</Frame>
1. After the IF/ELSE node, add **two** parallel List Operator nodes to the ELSE branch.
2. Rename one node to `Image` and the other to `Document`.
3. Configure the Image node:
1. Set `User Input/user_file` as the input variable.
2. Enable **Filter Condition**: `{x}type` **in** `Image`.
4. Configure the Document node:
1. Set `User Input/user_file` as the input variable.
2. Enable **Filter Condition**: `{x}type` **in** `Doc`.
### 5. Extract Text from Documents: Doc Extractor Node
<Info>
`gpt-5.2` cannot directly read uploaded documents like PDF or DOCX, so we must first convert them into plain text.
This is exactly what a Doc Extractor node does. It takes document files as input and outputs clean, usable text for the next steps.
</Info>
<Frame>
<img alt="Doc Extractor" />
</Frame>
1. After the Document node, add a Doc Extractor node.
2. On the Doc Extractor node's panel, set `Document/result` as the input variable.
### 6. Integrate All Reference Materials: LLM Node
<Info>
When users provide multiple reference types (draft text, documents, and images) simultaneously, we need to consolidate them into a single, coherent summary.
An LLM node will handle this task by analyzing all the scattered pieces to create a comprehensive context that guides subsequent content generation.
</Info>
<Frame>
<img alt="Integrate Information" />
</Frame>
1. After the Doc Extractor node, add an LLM node.
2. Connect the Image node to this LLM node as well.
3. Click the LLM node to configure it:
1. Rename it to `Integrate Info`.
2. Enable **VISION** and set `Image/result` as the vision variable.
3. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are a content strategist. Analyze the provided draft and reference materials (if any), then create a comprehensive content foundation for multi-platform social media optimization.
# ANALYSIS PRINCIPLES
- Work exclusively with provided information—no external assumptions
- Focus on extraction, synthesis, and strategic interpretation
- Identify compelling and actionable elements
- Prepare insights adaptable across different platforms
# REQUIRED ANALYSIS
Deliver structured analysis with:
## 1. CORE MESSAGE
- Central theme, purpose, objective
- Key value or benefit being communicated
## 2. ESSENTIAL CONTENT ELEMENTS
- Primary topics, facts, statistics, data points
- Notable quotes, testimonials, key statements
- Features, benefits, characteristics mentioned
- Dates, locations, contextual details
## 3. STRATEGIC INSIGHTS
- What makes content compelling/unique
- Emotional/rational appeals present
- Credibility factors, proof points
- Competitive advantages highlighted
## 4. ENGAGEMENT OPPORTUNITIES
- Discussion points, questions emerging
- Calls-to-action, next steps suggested
- Interactive/participation opportunities
- Trending themes touched upon
## 5. PLATFORM OPTIMIZATION FOUNDATION
- High-impact: Quick, shareable formats
- Professional: Business-focused discussions
- Community: Interaction and sharing
- Visual: Enhanced with strong visuals
## 6. SUPPORTING DETAILS
- Metrics, numbers, quantifiable results
- Direct quotes, testimonials
- Technical details, specifications
- Background context available
```
4. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace `Doc Extractor/text` and `User Input/draft` with the corresponding variables from the list.
```markdown USER theme={null}
Draft: User Input/draft
Reference material: Doc Extractor/text
```
<Frame>
<img alt="User Message" />
</Frame>
### 7. Create Customized Content for Each Platform: Iteration Node
<Info>
Now that the integrated references and target platforms are ready, let's generate a tailored post for each platform using an Iteration node.
The node will loop through the list of platforms and run a sub-workflow for each: first analyze the specific platform's style guidelines and best practices, then generate optimized content based on all available information.
</Info>
<Frame>
<img alt="Iteration Node" />
</Frame>
1. After the Integrate Info node, add an Iteration node.
2. Inside the Iteration node, add an LLM node and configure it:
1. Rename it to `Identify Style`.
2. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are a social media expert. Analyze the platform and provide content creation guidelines.
# ANALYSIS REQUIRED
For the given platform, provide:
## 1. PLATFORM PROFILE
- Platform type and category
- Target audience characteristics
## 2. CONTENT GUIDELINES
- Optimal content length (characters/words)
- Recommended tone (professional/casual/conversational)
- Formatting best practices (line breaks, emojis, etc.)
## 3. ENGAGEMENT STRATEGY
- Hashtag recommendations (quantity and style)
- Call-to-action best practices
- Algorithm optimization tips
## 4. TECHNICAL SPECS
- Character/word limits
- Visual content requirements
- Special formatting needs
## 5. PLATFORM-SPECIFIC NOTES
- Unique features or recent changes
- Industry-specific considerations
- Community engagement approaches
# OUTPUT REQUIREMENTS
- For recognized platforms: Provide specific guidelines
- For unknown platforms: Base recommendations on similar platforms
- Focus on actionable, practical advice
- Be concise but comprehensive
```
3. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace `Current Iteration/item` with the corresponding variable from the list.
```markdown USER theme={null}
Platform: Current Iteration/item
```
3. After the Identify Style node, add another LLM node and configure it:
1. Rename it to `Create Content`.
2. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are an expert social media content creator. Generate publication-ready content that matches platform guidelines, incorporates source information, and follows specified voice/tone and language requirements.
# LANGUAGE REQUIREMENT
- Generate ALL content exclusively in the target language specified in the user message. You MUST write the entire post in that language, regardless of the language of any source materials.
- No mixing of languages whatsoever
- Adapt platform terminology to the target language
# CONTENT REQUIREMENTS
- Follow platform guidelines exactly (format, length, tone, hashtags)
- Integrate source information effectively (key messages, data, value props)
- Apply voice & tone consistently (if provided)
- Optimize for platform-specific engagement
- Ensure cultural appropriateness for the specified language
# OUTPUT FORMAT
- Generate ONLY the final social media post content. No explanations or meta-commentary. Content must be immediately copy-paste ready.
- Maximum heading level: ## (H2) - never use # (H1)
- No horizontal dividers: avoid ---
# QUALITY CHECKLIST
✅ Platform guidelines followed
✅ Source information integrated
✅ Voice/tone consistent (when provided)
✅ Language consistency maintained
✅ Engagement optimized
✅ Publication ready
```
3. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace all inputs with the corresponding variable from the list.
```markdown USER theme={null}
Platform Name: Current Iteration/item
Target Language: User Input/language
Platform Guidelines: Identify Style/text
Source Information: Integrate Info/text
Voice & Tone: User Input/voice_and_tone
```
4. Enable structured output.
<Info>
This allows us to extract specific pieces of information from the LLM's response in a more reliable way, which is crucial for the next step where we format the final output.
</Info>
<Frame>
<img alt="Structured Output" />
</Frame>
1. Next to **Output Variables**, toggle **Structured** on. The `structured_output` variable will appear below. Click **Configure**.
2. In the pop-up schema editor, click **Import From JSON** in the top-right corner, and paste the following:
```json theme={null}
{
"platform_name": "string",
"post_content": "string"
}
```
<Frame>
<img alt="Import from JSON" />
</Frame>
4. Click the Iteration node to configure it:
1. Set `Parameter Extractor/platform` as the input variable.
2. Set `Create Content/structured_output` as the output variable.
3. Enable **Parallel Mode** and set the maximum parallelism to `10`.
<Check>
This is why we included `(≤10)` in the label name for the target platform field back in the User Input node.
</Check>
<Frame>
<img alt="Iteration Configuration" />
</Frame>
### 8. Format the Final Output: Template Node
<Info>
The Iteration node generates a post for each platform, but its output is a raw array of data (e.g., `[{"platform_name": "Twitter", "post_content": "..."}]`) that isn't very readable. We need to present the results in a clearer format.
That's where the Template node comes in. It lets us format this raw data into well-organized text using [Jinja2](https://jinja.palletsprojects.com/en/stable/) templating, ensuring the final output is user-friendly and easy to read.
</Info>
<Frame>
<img alt="Template Node" />
</Frame>
1. After the Iteration node, add a Template node.
2. On the Template node's panel, set `Iteration/output` as the input variable and name it `output`.
3. Paste the following Jinja2 code:
```
{% for item in output %}
# 📱 {{ item.platform_name }}
{{ item.post_content }}
{% endfor %}
```
* `{% for item in output %}` / `{% endfor %}`: Loops through each platform-content pair in the input array.
* `{{ item.platform_name }}`: Displays the platform name as an H1 heading with a phone emoji.
* `{{ item.post_content }}`: Displays the generated content for that platform.
* The blank line between `{{ item.post_content }}` and `{% endfor %}` adds spacing between platforms in the final output.
<Tip>
While LLMs can handle output formatting as well, their outputs can be inconsistent and unpredictable. For rule-based formatting that requires no reasoning, the Template node gets things done in a more stable and reliable way at zero token cost.
LLMs are incredibly powerful, but knowing when to use the right tool is key to building more reliable and cost-effective AI applications.
</Tip>
### 9. Return the Results to Users: Output Node
1. After the Template node, add an Output node.
2. On the Output node's panel, set the `Template/output` as the output variable.
## Step 3: Test
Your workflow is now complete! Let's test it out.
1. Make sure your Checklist is clear.
<Frame>
<img alt="Check Checklist" />
</Frame>
2. Check your workflow against the reference diagram provided at the beginning to ensure all nodes and connections match.
3. Click **Test Run** in the top-right corner, fill in the input fields, then click **Start Run**.
If you're not sure what to enter, try these sample inputs:
* **Draft**: `We just launched a new AI writing assistant that helps teams create content 10x faster.`
* **Upload File**: Leave empty
* **Voice & Tone**: `Friendly and enthusiastic, but professional`
* **Target Platform**: `Twitter and LinkedIn`
* **Language**: `English`
A successful run produces a formatted output with a separate post for each platform, like this:
<Frame>
<img alt="Test Output" />
</Frame>
<Note>
Your results may vary depending on the model you're using. Higher-capability models generally produce better output quality.
</Note>
<Tip>
To test how a node reacts to different inputs from previous nodes, you don't need to re-run the entire workflow. Just click **View cached variables** at the bottom of the canvas, find the variable you want to change, and edit its value.
</Tip>
If you encounter any errors, check the **Last Run** logs of the corresponding node to identify the exact cause of the problem.
## Step 4: Publish & Share
Once the workflow runs as expected and you're happy with the results, click **Publish** > **Publish Update** to make it live and shareable.
<Warning>
If you make any changes later, always remember to publish again so the updates take effect.
</Warning>
# Configure Annotation Reply
Source: https://docs.dify.ai/en/api-reference/annotations/configure-annotation-reply
/en/api-reference/openapi_service.json post /apps/annotation-reply/{action}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Enables or disables annotation reply for the app. Runs asynchronously; track progress with [Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status).
The body is validated before the action runs, so `score_threshold`, `embedding_provider_name`, and `embedding_model_name` are required even for `disable`.
# Create Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/create-annotation
/en/api-reference/openapi_service.json post /apps/annotations
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Creates an annotation. Annotations are predefined question-answer pairs the app returns directly on a match, instead of generating a fresh response.
# Delete Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/delete-annotation
/en/api-reference/openapi_service.json delete /apps/annotations/{annotation_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Deletes an annotation and its associated hit history.
# Get Annotation Reply Job Status
Source: https://docs.dify.ai/en/api-reference/annotations/get-annotation-reply-job-status
/en/api-reference/openapi_service.json get /apps/annotation-reply/{action}/status/{job_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Returns the status of an annotation reply configuration job started by [Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply).
# List Annotations
Source: https://docs.dify.ai/en/api-reference/annotations/list-annotations
/en/api-reference/openapi_service.json get /apps/annotations
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Lists the app's annotations, optionally filtered by keyword.
# Update Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/update-annotation
/en/api-reference/openapi_service.json put /apps/annotations/{annotation_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Updates an annotation's question and answer.
# Get App Info
Source: https://docs.dify.ai/en/api-reference/applications/get-app-info
/en/api-reference/openapi_service.json get /info
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns basic information about the app: name, description, tags, mode, and author.
# Get App Meta
Source: https://docs.dify.ai/en/api-reference/applications/get-app-meta
/en/api-reference/openapi_service.json get /meta
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the display icons for the tools this app uses, keyed by tool name.
# Get App Parameters
Source: https://docs.dify.ai/en/api-reference/applications/get-app-parameters
/en/api-reference/openapi_service.json get /parameters
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the app's front-end configuration: the opening statement and suggested questions, feature toggles, the user input form, and file-upload limits. Use it to render the app's inputs and apply the correct upload limits.
# Get App WebApp Settings
Source: https://docs.dify.ai/en/api-reference/applications/get-app-webapp-settings
/en/api-reference/openapi_service.json get /site
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the branding and display settings for the app's hosted web app, such as its title, icon, theme colors, and default language.
# Convert Audio to Text
Source: https://docs.dify.ai/en/api-reference/audio/convert-audio-to-text
/en/api-reference/openapi_service.json post /audio-to-text
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Transcribes an uploaded audio file to text using the workspace's default speech-to-text model.
# Convert Text to Audio
Source: https://docs.dify.ai/en/api-reference/audio/convert-text-to-audio
/en/api-reference/openapi_service.json post /text-to-audio
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Converts text to speech audio. Pass `text` to synthesize arbitrary text, or `message_id` to voice an existing message's answer.
# Get Next Suggested Questions
Source: https://docs.dify.ai/en/api-reference/chat-messages/get-next-suggested-questions
/en/api-reference/openapi_service.json get /messages/{message_id}/suggested
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Returns the follow-up questions suggested for a message.
# Send Chat Message
Source: https://docs.dify.ai/en/api-reference/chat-messages/send-chat-message
/en/api-reference/openapi_service.json post /chat-messages
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Sends a message to a chat app and returns the assistant's reply. The events in the streaming response vary by app type.
# Stop Chat Message Generation
Source: https://docs.dify.ai/en/api-reference/chat-messages/stop-chat-message-generation
/en/api-reference/openapi_service.json post /chat-messages/{task_id}/stop
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Stops a chat message generation task. Only supported in `streaming` mode.
# Create Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/create-child-chunk
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks
Create a child chunk under a parent chunk. Intended for documents that use the parent-child (`hierarchical_model`) chunking mode.
# Create Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/create-chunks
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments
Create one or more chunks within a document.
# Delete Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/delete-child-chunk
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks/{child_chunk_id}
Permanently delete a child chunk from its parent chunk.
# Delete Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/delete-chunk
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Permanently delete a chunk from the document.
# Get Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/get-chunk
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Retrieve the full details of a single chunk.
# List Child Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/list-child-chunks
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks
Returns a paginated list of child chunks under a specific parent chunk.
# List Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/list-chunks
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments
Returns a paginated list of chunks within a document, optionally filtered by keyword or indexing status.
# Update Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/update-child-chunk
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks/{child_chunk_id}
Update the content of an existing child chunk.
# Update Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/update-chunk
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Update a chunk's fields. The update re-triggers indexing for that chunk.
# Send Completion Message
Source: https://docs.dify.ai/en/api-reference/completion-messages/send-completion-message
/en/api-reference/openapi_service.json post /completion-messages
**Available for**: Text Generator apps.
Sends a request to a text-generation app and returns the generated text.
# Stop Completion Message Generation
Source: https://docs.dify.ai/en/api-reference/completion-messages/stop-completion-message-generation
/en/api-reference/openapi_service.json post /completion-messages/{task_id}/stop
**Available for**: Text Generator apps.
Stops a completion message generation task. Only supported in `streaming` mode.
# Delete Conversation
Source: https://docs.dify.ai/en/api-reference/conversations/delete-conversation
/en/api-reference/openapi_service.json delete /conversations/{conversation_id}
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Deletes a conversation.
# List Conversation Messages
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversation-messages
/en/api-reference/openapi_service.json get /messages
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Returns a conversation's message history, newest first. Pass `first_id` to page backward into older messages.
# List Conversation Variables
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversation-variables
/en/api-reference/openapi_service.json get /conversations/{conversation_id}/variables
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Lists the variables stored in a conversation.
# List Conversations
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversations
/en/api-reference/openapi_service.json get /conversations
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Lists an end user's conversations, most recently active first.
# Rename Conversation
Source: https://docs.dify.ai/en/api-reference/conversations/rename-conversation
/en/api-reference/openapi_service.json post /conversations/{conversation_id}/name
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Renames a conversation, or auto-generates a name from its messages when `auto_generate` is `true`. The name is what clients display in a multi-conversation list.
# Update Conversation Variable
Source: https://docs.dify.ai/en/api-reference/conversations/update-conversation-variable
/en/api-reference/openapi_service.json put /conversations/{conversation_id}/variables/{variable_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Updates a conversation variable's value. The new value must match the variable's existing type.
# Create Document by File
Source: https://docs.dify.ai/en/api-reference/documents/create-document-by-file
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/document/create-by-file
Creates a document in a knowledge base from an uploaded file. Common formats such as PDF, TXT, and DOCX are supported. Indexing runs asynchronously; track it with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Create Document by Text
Source: https://docs.dify.ai/en/api-reference/documents/create-document-by-text
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/document/create-by-text
Creates a document in a knowledge base from raw text. Indexing runs asynchronously; track it with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Delete Document
Source: https://docs.dify.ai/en/api-reference/documents/delete-document
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}
Permanently deletes a document and all its chunks from the knowledge base.
# Download Document
Source: https://docs.dify.ai/en/api-reference/documents/download-document
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/download
Returns a signed URL for downloading a document's original uploaded file.
# Download Documents as ZIP
Source: https://docs.dify.ai/en/api-reference/documents/download-documents-as-zip
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/download-zip
Downloads one or more documents as a single ZIP archive. Only documents that were uploaded as files can be included.
# Get Document
Source: https://docs.dify.ai/en/api-reference/documents/get-document
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}
Returns detailed information for a single document.
# Get Document Indexing Status
Source: https://docs.dify.ai/en/api-reference/documents/get-document-indexing-status
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{batch}/indexing-status
Returns indexing progress for every document in a batch: the current stage and chunk completion counts. Poll until each `indexing_status` reaches `completed` or `error`. Status advances through `waiting` → `parsing` → `cleaning` → `splitting` → `indexing` → `completed`.
# List Documents
Source: https://docs.dify.ai/en/api-reference/documents/list-documents
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents
Returns a paginated list of documents in a knowledge base.
# Update Document
Source: https://docs.dify.ai/en/api-reference/documents/update-document
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/{document_id}
Updates a document by uploading a new file, then re-indexes it. This is the canonical endpoint for file-based document updates. Track progress with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Update Document by File
Source: https://docs.dify.ai/en/api-reference/documents/update-document-by-file
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/update-by-file
Deprecated. Use [Update Document](/en/api-reference/documents/update-document) instead. Updates a document by uploading a new file, then re-indexes it.
# Update Document by Text
Source: https://docs.dify.ai/en/api-reference/documents/update-document-by-text
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/update-by-text
Updates a document's text content, name, or processing configuration. Re-indexes the document when its text changes.
# Update Document Status in Batch
Source: https://docs.dify.ai/en/api-reference/documents/update-document-status-in-batch
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/status/{action}
Enables, disables, archives, or unarchives multiple documents in one request.
# Get End User Info
Source: https://docs.dify.ai/en/api-reference/end-users/get-end-user-info
/en/api-reference/openapi_service.json get /end-users/{end_user_id}
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns an end user's details by ID. Useful for resolving an end-user ID returned by another endpoint, such as `created_by` in the [Upload File](/en/api-reference/files/upload-file) response.
# List App Feedbacks
Source: https://docs.dify.ai/en/api-reference/feedback/list-app-feedbacks
/en/api-reference/openapi_service.json get /app/feedbacks
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Returns a paginated list of all feedback on the app's messages, including both end-user and admin submissions.
# Submit Message Feedback
Source: https://docs.dify.ai/en/api-reference/feedback/submit-message-feedback
/en/api-reference/openapi_service.json post /messages/{message_id}/feedbacks
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Records a `like` or `dislike` rating, plus an optional comment, on a message. Submitting `null` for `rating` revokes the message's existing feedback.
# Download File
Source: https://docs.dify.ai/en/api-reference/files/download-file
/en/api-reference/openapi_service.json get /files/{file_id}/preview
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Returns the raw bytes of a file previously returned by [Upload File](/en/api-reference/files/upload-file). A file is reachable only through the app whose messages reference it.
# Upload File
Source: https://docs.dify.ai/en/api-reference/files/upload-file
/en/api-reference/openapi_service.json post /files/upload
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Uploads a file and returns its `id` for later requests to reference. The file belongs to the uploading end user: only requests carrying the same `user` can reference it.
Which file types an app actually consumes depends on its file-upload settings; read them from [Get App Parameters](/en/api-reference/applications/get-app-parameters).
# Agent API
Source: https://docs.dify.ai/en/api-reference/guides/agent
API for Agent apps, covering streaming chat messages, conversation management, file uploads, and app configuration
<Info>
Agent here means the new Agent app type (`agent` mode). The Legacy Agent app (`agent-chat`) is covered on [Chatbot and Legacy Agent](/en/api-reference/guides/chat).
</Info>
[Agent apps](/en/self-host/use-dify/build/new-agent/overview) run in `agent` mode: you send a message, stream the reply as it generates, and keep multi-turn context in conversations.
The model reasons and calls tools autonomously, and the stream shows that work: the reply text streams incrementally as `agent_message` events, with `agent_thought` events carrying each reasoning step and tool call alongside.
The turn closes with a single `message` event carrying the complete answer, then `message_end`. Render the `agent_message` deltas live and treat the closing `message` as the final answer rather than appending it.
Each `agent_thought` event carries the step's `thought`, the `tool` it called with its `tool_input`, and the tool's `observation`. The full stream shape is on [Send Chat Message](/en/api-reference/chat-messages/send-chat-message).
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Agent app. Streaming mode only; blocking mode returns a 400 `bad_request` error.
Reply text streams as `agent_message` deltas, batched at roughly half-second intervals rather than token by token.
The closing `message_end` event reports token usage. It never includes knowledge-retrieval citations (`retriever_resources`).
Two limits end a run early, and either one closes the stream with the `agent_run_limit_exceeded` error code:
* **Time**: a run is stopped after 1 hour by default.
For longer runs on self-hosted deployments, raise `APP_MAX_EXECUTION_TIME`, `WORKFLOW_MAX_EXECUTION_TIME`, and `DIFY_AGENT_RUN_TIMEOUT_SECONDS` above the duration you need. See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
* **Model requests**: each run is capped at 500.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI. Each message's `agent_thoughts` array carries the reasoning steps for that turn.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set a conversation's name, or have one generated from its content.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation and its messages.
## Upload Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file, scoped to the uploading end user.
Files passed to [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) are surfaced to the agent as downloadable references it can fetch and inspect in its sandbox.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: app metadata; the `tool_icons` map is empty for Agent apps.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
# Chat App API
Source: https://docs.dify.ai/en/api-reference/guides/chat
API for Chatbot and Legacy Agent apps, covering chat messages, conversation management, file uploads, voice, and annotations
[Chatbot apps](/en/cloud/use-dify/build/chatbot) (`chat` mode) and [Legacy Agent apps](/en/cloud/use-dify/build/agent) (`agent-chat` mode) share the same endpoints to send messages, manage conversations, handle files, and retrieve app settings. Only the streamed reply differs: Chatbot apps stream the reply as `message` events, while Legacy Agent apps stream `agent_thought` and `agent_message` events.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Chatbot or Legacy Agent app. Blocking mode returns the full reply once it finishes; Legacy Agent apps support streaming mode only.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
Conversations created through the API stay isolated from conversations started in the app's web app.
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set or auto-generate a display name.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation.
* **[List Conversation Variables](/en/api-reference/conversations/list-conversation-variables)**: read the values the session persists across turns.
* **[Update Conversation Variable](/en/api-reference/conversations/update-conversation-variable)**: change one of those values directly.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a reply as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
## Manage Annotations
Annotations pair a question with a fixed answer that the app returns directly instead of generating a new response:
* **[Create Annotation](/en/api-reference/annotations/create-annotation)**, **[List Annotations](/en/api-reference/annotations/list-annotations)**, **[Update Annotation](/en/api-reference/annotations/update-annotation)**, **[Delete Annotation](/en/api-reference/annotations/delete-annotation)**: manage the annotation set.
* **[Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply)**: turn annotation matching on or off. The change runs asynchronously.
* **[Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status)**: poll with the returned job ID to confirm the change finished.
# Chatflow App API
Source: https://docs.dify.ai/en/api-reference/guides/chatflow
API for Chatflow apps, covering chat messages, workflow-level streaming, conversation management, and Human Input pauses
[Chatflow apps](/en/cloud/use-dify/build/workflow-chatflow) run in `advanced-chat` mode, streaming workflow-level events (node starts, finishes, iterations, and pauses) alongside the reply. Previous turns persist as context, so later messages can reference earlier ones.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Chatflow app. Streaming mode carries workflow and node events alongside the answer text; blocking mode returns once the run finishes.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set or auto-generate a display name.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation.
* **[List Conversation Variables](/en/api-reference/conversations/list-conversation-variables)**: read the values the session persists across turns.
* **[Update Conversation Variable](/en/api-reference/conversations/update-conversation-variable)**: change one of those values directly.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Pause for Human Input
When a run reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input) whose delivery method is web app, complete the pause over the API:
<Steps>
<Step title="Listen for the pause">
The event stream emits `human_input_required` carrying a `form_token` and the run's `workflow_run_id`, then ends with the `workflow_paused` event.
</Step>
<Step title="Fetch the form">
Load the form's contents with [Get Human Input Form](/en/api-reference/human-input/get-human-input-form), using the `form_token`.
</Step>
<Step title="Submit the response">
Send the recipient's input with [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form). Submitting resumes the run.
</Step>
<Step title="Resume the stream">
Open a new stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), using the `workflow_run_id` from the paused stream, and follow the remaining events through the final answer.
</Step>
</Steps>
For file-attached submissions and the full event sequence, see the [Human Input Flow](/en/api-reference/guides/human-input-flow) guide.
## Inspect Workflow Runs
* **[Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail)**: a run's status and outputs, by the `workflow_run_id` that appears in the workflow and node events streamed alongside a chat reply.
* **[List Workflow Logs](/en/api-reference/workflow-runs/list-workflow-logs)**: run-level summaries covering status, token usage, step count, and timing, rather than a node-by-node execution log.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback and Annotations
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a reply as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
Annotations pair a question with a fixed answer that the app returns directly instead of generating a new response:
* **[Create Annotation](/en/api-reference/annotations/create-annotation)**, **[List Annotations](/en/api-reference/annotations/list-annotations)**, **[Update Annotation](/en/api-reference/annotations/update-annotation)**, **[Delete Annotation](/en/api-reference/annotations/delete-annotation)**: manage the annotation set.
* **[Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply)**: turn annotation matching on or off. The change runs asynchronously.
* **[Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status)**: poll with the returned job ID to confirm the change finished.
# Completion App API
Source: https://docs.dify.ai/en/api-reference/guides/completion
API for Text Generator apps, covering completion messages, file uploads, voice, and feedback
[Text Generator apps](/en/cloud/use-dify/build/text-generator) run in `completion` mode: each call submits its own input values and returns one response, with no conversation state carried between calls.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Generate Text
* **[Send Completion Message](/en/api-reference/completion-messages/send-completion-message)**: send `inputs` to fill the app's prompt template and generate a response. Blocking mode returns the full response once it finishes; streaming mode delivers `message` events ending in `message_end`, plus `tts_message` events when the app has text-to-speech auto-play enabled.
* **[Stop Completion Message Generation](/en/api-reference/completion-messages/stop-completion-message-generation)**: interrupt a streaming response before it finishes.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Completion Message](/en/api-reference/completion-messages/send-completion-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize the generated response back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a response as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
# End User Identity
Source: https://docs.dify.ai/en/api-reference/guides/end-user-identity
What the user field identifies, what it scopes, and why it must stay consistent across calls
Most app endpoints take a `user` field: your own identifier for the end user a call acts on behalf of. Dify never authenticates it, so pick a stable value per person, such as an account ID, and send it consistently.
Dify starts tracking a new `user` the first time it appears, and one app key serves any number of end users.
## What `user` Scopes
`user` controls what each call can see and do:
* **Conversations**: listing, history, renaming, and deletion all operate on that user's conversations only.
* **Files**: an upload belongs to the uploading user, and referencing it under a different `user` fails.
* **Stopping generation**: the chat-family stop endpoints act only when `user` matches the one that started the reply. A mismatch is silently ignored—the call succeeds either way, so it isn't detectable from the response.
Workflow's Stop Workflow Task does not check `user`.
* **Resuming runs**: [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) returns a 404 when `user` doesn't match the run's creator.
Keep one `user` per person across every call in a flow—upload, send, stop, and resume all check it.
## API Users and Web App Users Stay Separate
Traffic through the API and Dify's hosted web app keep separate identities: conversations your API users create never appear in the web app, and web app conversations never appear through the API.
## Resolve an End-User ID
Some responses carry an end-user ID instead of full details, such as `created_by` in the Upload File response. [Get End User Info](/en/api-reference/end-users/get-end-user-info) resolves it.
# Handle Errors and Rate Limits
Source: https://docs.dify.ai/en/api-reference/guides/errors
The error envelope, what each status class means, and which failures are worth retrying
Every documented error uses the same three-field JSON envelope:
```json theme={null}
{
"code": "invalid_param",
"message": "user is required",
"status": 400
}
```
`status` mirrors the HTTP status; `code` is the stable identifier to branch on; `message` is human-readable detail. Each endpoint page lists exactly which codes it can raise.
## Status Classes at a Glance
| Status | Meaning | Typical codes |
| :-------- | :---------------------------------------------------------------- | :------------------------------------------------------------------------- |
| 400 | The request or the app's configuration is invalid | `invalid_param`, `bad_request`, `app_unavailable`, provider errors (below) |
| 401 | Missing or invalid API key | `unauthorized` |
| 403 | The key can't act here: access restrictions or plan limits | `forbidden` |
| 404 | The resource doesn't exist or isn't visible to this key or `user` | `not_found` |
| 413 / 415 | A file is too large or of an unsupported type | `file_too_large`, `unsupported_file_type` |
| 429 | Too many requests right now, or a quota is exhausted | `too_many_requests`, `rate_limit_error` |
| 500 | Something failed on Dify's side | `internal_server_error` |
## Provider Errors Are Configuration Errors
Four common 400 codes point at the app's model setup rather than your request:
* `provider_not_initialize`: no valid model credentials
* `provider_quota_exceeded`: the model provider's own quota ran out
* `model_currently_not_support`: the model isn't currently supported
* `completion_request_error`: an error occurred while making a completion request
For these errors, retrying won't help. Fix the app's model configuration in Dify.
## Rate Limits and Quotas
The two 429 codes mean different things:
* `too_many_requests` is a concurrency ceiling—too many simultaneous requests for the app right now. Back off and retry.
* `rate_limit_error` is a plan quota on Dify Cloud, such as workflow executions. Retrying won't clear it; it resets with the quota period or a plan change.
On Dify Cloud, knowledge write endpoints also enforce plan limits as `403` responses. These carry the same `forbidden` code as access restrictions—the `message` is what tells you it's a plan limit, so don't build a switch on `code` alone for 403s.
## Errors Inside Streams
Once a stream opens, the HTTP status is already `200`: failures arrive as an `error` event and end the stream. The event's `code` values are the same ones documented here—classify them with the same rules. See [Consume Streaming Responses](/en/api-reference/guides/streaming) for details.
## What to Retry
* **Retry with backoff**: `too_many_requests`, `500`, and network failures.
* **Don't retry as-is**: validation errors (fix the request first), authorization failures, or quota errors (they won't clear until the quota does).
* **Fix, don't retry**: a `404` from a resume call means the wrong `user` or a run that doesn't exist. Correct the identifier instead.
# Get Started with the Dify API
Source: https://docs.dify.ai/en/api-reference/guides/get-started
Get an API key, make your first call, and find the endpoints for your app type
Every app you publish in Dify doubles as a REST API, and so do your knowledge bases. You call the same app your end users interact with, from your own backend, with an API key.
## Get an API Key
<Warning>
Call the API from your backend only. A key embedded in frontend code or a client app can be extracted and abused.
</Warning>
* For an app, create an API key from inside the app itself. The key is scoped to that one app, and one key serves all your end users.
<Info>
Your calls tell people apart with a per-person `user` value. See [End User Identity](/en/api-reference/guides/end-user-identity) for details.
</Info>
* For knowledge bases, go to **Knowledge** and click **Service API** in the top-right corner.
A knowledge API key is broader: it can reach every knowledge base visible to the account that created the key, so treat it with extra care. See [Knowledge API](/en/api-reference/guides/knowledge) for details.
## Make Your First Call
Every request carries the key as a Bearer token. For Dify Cloud, the base URL is `https://api.dify.ai/v1`; for self-hosted deployments, use your own instance's API base URL.
The fastest first call needs no code: open [Get App Info](/en/api-reference/applications/get-app-info), click **Try it**, paste your key into the **Authorization** field, and press **Send**. It works for every app type.
The same call from a terminal:
```bash theme={null}
curl https://api.dify.ai/v1/info \
-H "Authorization: Bearer $DIFY_API_KEY"
```
A response like this confirms the key works and shows which app it belongs to:
```json theme={null}
{
"name": "My Chat App",
"description": "A helpful assistant",
"tags": ["assistant"],
"mode": "chat",
"author_name": "Dify Team"
}
```
Using a knowledge API key? Its endpoints are a separate family: start with [List Knowledge Bases](/en/api-reference/knowledge-bases/list-knowledge-bases) instead.
## Find Your App Type's Endpoints
See each app type's own overview page for its full API surface:
* [Chatflow](/en/api-reference/guides/chatflow) (`advanced-chat`)
* [Workflow](/en/api-reference/guides/workflow) (`workflow`)
* [Agent](/en/api-reference/guides/agent) (`agent`)
* [Chatbot and Legacy Agent](/en/api-reference/guides/chat) (`chat`, `agent-chat`)
* [Text Generator](/en/api-reference/guides/completion) (`completion`)
* [Knowledge](/en/api-reference/guides/knowledge)
# Human Input API Integration Flow
Source: https://docs.dify.ai/en/api-reference/guides/human-input-flow
End-to-end sequence for handling a paused Human Input form via the API
When a workflow reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input), it pauses and emits a `human_input_required` event in the streaming response. The event carries a `form_token` that your integration uses to drive the form lifecycle until the workflow resumes.
For per-endpoint reference, see the [Human Input API](/en/api-reference/human-input/get-human-input-form).
## Steps
The sequence below applies to both Workflow and Chatflow apps. Only the entry endpoint in Step 1 differs between the two.
<Steps>
<Step title="Start the app in streaming mode">
1. Call [Run Workflow](/en/api-reference/workflow-runs/run-workflow) (Workflow apps) or [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) (Chatflow apps), passing your end user's `user` identifier.
2. Watch the SSE stream for the `human_input_required` event and capture its `form_token`.
If `form_token` is `null`, the form uses Email delivery and can't be driven via the API (see [Delivery Method Requirement](#delivery-method-requirement)).
The `human_input_required` event also carries the run's `workflow_run_id`; keep it in case you need to resume listening in Step 5.
</Step>
<Step title="Get the form definition">
Call [Get Human Input Form](/en/api-reference/human-input/get-human-input-form) with `form_token`. The response includes the rendered Markdown, input field definitions, available actions, pre-filled default values, and an `expiration_time` after which the form can no longer be submitted. Render the form for the recipient.
If the form expires before it is submitted, the paused run follows the node's configured timeout behavior; a resumed stream then carries `human_input_form_timeout` rather than `human_input_form_filled`.
</Step>
<Step title="(File inputs only) Upload local files">
If the recipient attaches a local file to a `file` or `file-list` input, upload it first with [Upload File](/en/api-reference/files/upload-file). It returns an `id` you reference as `upload_file_id` in the submit payload. Use one consistent `user` across the run, upload, and submit calls (see [End User Identity](/en/api-reference/guides/end-user-identity) for details).
A remote file needs no upload step: attach it inline in the submit as a `{transfer_method: remote_url, url}` mapping.
</Step>
<Step title="Submit the response">
Call [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form) with the recipient's input values, the selected `action`, and your `user`. The `action` must be one of the actions from the form definition in Step 2.
File inputs accept either a `{transfer_method: local_file, upload_file_id}` mapping (from Step 3) or an inline `{transfer_method: remote_url, url}` mapping. See [Upload First vs. Inline Remote URL](#upload-first-vs-inline-remote-url) for the trade-off.
A successful submit is final: it closes the form and resumes the run along the matching action branch, so the same `form_token` can't be submitted again.
A rejected submit (an invalid action, a missing required input, or a failed remote-file fetch) leaves the form unchanged—fix the inputs and resubmit with the same `form_token`.
</Step>
<Step title="Resume listening to the workflow">
If the original SSE stream closed, reopen it via [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) with the `workflow_run_id` from Step 1 and the same `user` that started the run—a different `user` gets a 404.
The resumed stream includes `human_input_form_filled` confirming the submission (or `human_input_form_timeout` if the form expired), then the remaining node events through to completion, like a run that never paused.
Add `include_state_snapshot=true` to first replay the status of nodes that already executed. If the workflow has more than one Human Input node in sequence, the stream closes at each pause by default; pass `continue_on_pause=true` to keep one stream open across all of them.
</Step>
</Steps>
## Upload First vs. Inline Remote URL
Both patterns work for file inputs:
* **Pre-upload, then reference `upload_file_id`** (recommended)
[Upload File](/en/api-reference/files/upload-file) enforces the file size limits at upload time, so the recipient gets immediate feedback and can retry before committing the whole submission.
* **Submit inline with `transfer_method: remote_url`**
The backend fetches the file at submit time. Faster to integrate, but any size, type, or fetch failure rejects the entire submission, forcing the recipient to redo other fields.
<Tip>
For interactive forms with recipient feedback, prefer the pre-upload pattern. The trade-off only pays off when the integration is fully programmatic and no human is waiting to retype anything.
</Tip>
## Delivery Method Requirement
The Human Input API works only with forms delivered via the Human Input node's web app method. Email-only delivery doesn't expose a `form_token`.
## Example: File-Attached Submission
This example uses a form with a `feedback` paragraph input, an `attachments` file-list input, and `approve` / `reject` actions.
1. Call [Get Human Input Form](/en/api-reference/human-input/get-human-input-form) to get the form definition:
```http theme={null}
GET /form/human_input/<form_token>
Authorization: Bearer {api-key}
```
Returns the form definition:
```json theme={null}
{
"form_content": "Please review the draft and confirm or request changes.",
"inputs": [
{
"type": "paragraph",
"output_variable_name": "feedback",
"default": {
"type": "constant",
"selector": [],
"value": ""
}
},
{
"type": "file-list",
"output_variable_name": "attachments",
"allowed_file_types": [
"image",
"document"
],
"allowed_file_extensions": [],
"allowed_file_upload_methods": [
"local_file",
"remote_url"
],
"number_limits": 5
}
],
"resolved_default_values": {},
"user_actions": [
{
"id": "approve",
"title": "Approve",
"button_style": "primary"
},
{
"id": "reject",
"title": "Request changes",
"button_style": "default"
}
],
"expiration_time": 1745510400
}
```
2. For each local file, call [Upload File](/en/api-reference/files/upload-file):
```http theme={null}
POST /files/upload
Authorization: Bearer {api-key}
Content-Type: multipart/form-data
file=<binary>
user=abc-123
```
Returns `{"id": "1a77f0df-...", ...}`.
3. Call [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form) with the recipient's input and selected action:
```http theme={null}
POST /form/human_input/<form_token>
Authorization: Bearer {api-key}
Content-Type: application/json
{
"inputs": {
"feedback": "Looks good to ship",
"attachments": [
{"transfer_method": "local_file", "upload_file_id": "1a77f0df-..."}
]
},
"action": "approve",
"user": "abc-123"
}
```
Returns `{}`. The workflow resumes along the `approve` branch.
4. Reconnect to the run's stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) to follow it through to completion, as in Step 5 of the sequence above.
# Knowledge API
Source: https://docs.dify.ai/en/api-reference/guides/knowledge
API for managing knowledge bases, documents, chunks, metadata, tags, and knowledge pipelines
Build and maintain [knowledge bases](/en/cloud/use-dify/knowledge/readme) from your own code, without going through the Dify console: create a knowledge base, load documents and chunks into it, organize them with metadata and tags, and query it directly for search or RAG.
<Note>
A single Knowledge Base API key has access to every knowledge base visible to the account that created the key. Handle your keys carefully to avoid unintended data exposure.
</Note>
## Get Your API Endpoint and Key
In **Knowledge**, click **Service API** in the top-right corner to open the API configuration panel. From here:
* Copy the Service API endpoint, the base URL for every Knowledge API request.
* Click **API Key** to create and manage keys.
<Warning>
Store your API key securely on the server side. Never expose it in client-side code or public repositories.
</Warning>
## Manage API Access for a Knowledge Base
Every knowledge base is reachable through the API by default. To restrict a specific knowledge base, open it, click **API Access** in the bottom-left corner, and turn the toggle off.
## Create and Manage Knowledge Bases
* **[Create an Empty Knowledge Base](/en/api-reference/knowledge-bases/create-an-empty-knowledge-base)**: create a knowledge base with no documents yet.
* **[List Knowledge Bases](/en/api-reference/knowledge-bases/list-knowledge-bases)**: a paginated list, filterable by keyword or tag.
* **[Get Knowledge Base](/en/api-reference/knowledge-bases/get-knowledge-base)**: one knowledge base's embedding model, retrieval configuration, and document statistics.
* **[Update Knowledge Base](/en/api-reference/knowledge-bases/update-knowledge-base)**: change the name, permissions, embedding model, or retrieval settings; only the fields you provide are updated.
* **[Delete Knowledge Base](/en/api-reference/knowledge-bases/delete-knowledge-base)**: permanently remove a knowledge base and every document inside it.
* **[Retrieve Chunks from a Knowledge Base / Test Retrieval](/en/api-reference/knowledge-bases/retrieve-chunks-from-a-knowledge-base-test-retrieval)**: search a knowledge base and return the most relevant chunks—the same endpoint serves production retrieval and retrieval testing.
## Add and Update Documents
Document creation is asynchronous. Create the document, then poll until indexing finishes:
<Steps>
<Step title="Create a knowledge base">
Call [Create an Empty Knowledge Base](/en/api-reference/knowledge-bases/create-an-empty-knowledge-base), or use an existing knowledge base.
</Step>
<Step title="Add a document">
Call [Create Document by Text](/en/api-reference/documents/create-document-by-text) or [Create Document by File](/en/api-reference/documents/create-document-by-file); both return a `batch` ID.
If you didn't set `indexing_technique` (how content is indexed for search) when creating the knowledge base, set it on this first document; later documents inherit it automatically.
</Step>
<Step title="Poll the indexing status">
Poll [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status) with the `batch` ID until `indexing_status` reaches `completed` or `error`; it progresses through `waiting`, `parsing`, `cleaning`, `splitting`, and `indexing` along the way.
</Step>
</Steps>
* **[List Documents](/en/api-reference/documents/list-documents)**: a paginated list, filterable by keyword or indexing status.
* **[Get Document](/en/api-reference/documents/get-document)**: one document's indexing status, metadata, and processing statistics; the `metadata` query parameter includes, omits, or returns only the metadata fields.
* **[Download Document](/en/api-reference/documents/download-document)**: a signed URL for the document's original uploaded file.
* **[Download Documents as ZIP](/en/api-reference/documents/download-documents-as-zip)**: bundle up to 100 uploaded-file documents into a single archive.
* **[Update Document](/en/api-reference/documents/update-document)**: replace a document's content by uploading a new file, re-triggering indexing; the canonical way to update a file-based document.
* **[Update Document by Text](/en/api-reference/documents/update-document-by-text)**: update a document's text content, name, or processing configuration inline; re-triggers indexing when the content changes.
* **[Update Document by File](/en/api-reference/documents/update-document-by-file)**: deprecated alias for uploading a replacement file; use Update Document instead.
* **[Update Document Status in Batch](/en/api-reference/documents/update-document-status-in-batch)**: enable, disable, archive, or unarchive multiple documents at once.
* **[Delete Document](/en/api-reference/documents/delete-document)**: permanently remove a document and every chunk inside it.
## Manage Chunks and Child Chunks
* **[Create Chunks](/en/api-reference/chunks/create-chunks)**: add chunks to a document by hand—indexing already chunks uploaded content automatically. Each chunk requires `content`; documents in Q\&A mode also require `answer`.
* **[List Chunks](/en/api-reference/chunks/list-chunks)**: a paginated list, filterable by keyword or status.
* **[Get Chunk](/en/api-reference/chunks/get-chunk)**: one chunk's content, keywords, and indexing status.
* **[Update Chunk](/en/api-reference/chunks/update-chunk)**: change a chunk's content, keywords, or answer; re-triggers indexing for that chunk.
* **[Delete Chunk](/en/api-reference/chunks/delete-chunk)**: permanently remove a chunk.
For documents in Parent-child mode (`hierarchical_model`), child chunks nest under a parent chunk. Child chunks you create or update through the API are always typed `customized`, unlike the `automatic` ones the indexing pipeline generates.
* **[Create Child Chunk](/en/api-reference/chunks/create-child-chunk)**: add a child chunk under a parent chunk.
* **[List Child Chunks](/en/api-reference/chunks/list-child-chunks)**: a paginated list of one parent chunk's child chunks.
* **[Update Child Chunk](/en/api-reference/chunks/update-child-chunk)**: change a child chunk's content.
* **[Delete Child Chunk](/en/api-reference/chunks/delete-child-chunk)**: permanently remove a child chunk.
## Manage Metadata Fields
Metadata fields annotate documents with structured information that retrieval can filter on:
* **[Create Metadata Field](/en/api-reference/metadata/create-metadata-field)**: add a custom field to the knowledge base, typed `string`, `number`, or `time`.
* **[List Metadata Fields](/en/api-reference/metadata/list-metadata-fields)**: every field, custom and built-in, with a count of documents using each.
* **[Update Metadata Field](/en/api-reference/metadata/update-metadata-field)**: rename a custom field.
* **[Delete Metadata Field](/en/api-reference/metadata/delete-metadata-field)**: remove a custom field; documents lose their values for it.
* **[Get Built-in Metadata Fields](/en/api-reference/metadata/get-built-in-metadata-fields)**: the system-provided fields, such as `document_name`, `uploader`, and `upload_date`.
* **[Update Built-in Metadata Field](/en/api-reference/metadata/update-built-in-metadata-field)**: enable or disable built-in fields for the knowledge base.
* **[Update Document Metadata in Batch](/en/api-reference/metadata/update-document-metadata-in-batch)**: set metadata key-value pairs across multiple documents in a single call.
Metadata also works as a stable external key: store your source system's ID on each document, then filter on it in later sync runs to find and update the same documents.
## Organize Knowledge Bases with Tags
Tags live at the workspace level, independent of any single knowledge base:
* **[Create Knowledge Tag](/en/api-reference/tags/create-knowledge-tag)**: create a tag for organizing knowledge bases.
* **[List Knowledge Tags](/en/api-reference/tags/list-knowledge-tags)**: every tag in the workspace.
* **[Update Knowledge Tag](/en/api-reference/tags/update-knowledge-tag)**: rename a tag.
* **[Delete Knowledge Tag](/en/api-reference/tags/delete-knowledge-tag)**: remove a tag from every knowledge base it was bound to, without deleting those knowledge bases.
* **[Create Tag Binding](/en/api-reference/tags/create-tag-binding)**: bind one or more tags to a knowledge base; a knowledge base can carry multiple tags.
* **[Delete Tag Binding](/en/api-reference/tags/delete-tag-binding)**: remove tags from a knowledge base.
* **[Get Knowledge Base Tags](/en/api-reference/tags/get-knowledge-base-tags)**: the tags currently bound to one knowledge base.
## Look Up Available Models
* **[Get Available Models](/en/api-reference/models/get-available-models)**: the models available for a given `model_type`; query `text-embedding` for embedding models or `rerank` for reranking models when configuring a knowledge base.
## Run the Knowledge Pipeline
A knowledge pipeline is a workflow that ingests data from a datasource and turns it into documents:
* **[Upload Pipeline File](/en/api-reference/knowledge-pipeline/upload-pipeline-file)**: upload a file for the pipeline to process.
* **[List Datasource Plugins](/en/api-reference/knowledge-pipeline/list-datasource-plugins)**: the datasource nodes configured in the pipeline—published by default, or the draft version with `is_published=false`.
* **[Run Datasource Node](/en/api-reference/knowledge-pipeline/run-datasource-node)**: execute a single datasource node and stream its results, useful for testing one step in isolation.
* **[Run Pipeline](/en/api-reference/knowledge-pipeline/run-pipeline)**: execute the full pipeline in `streaming` or `blocking` response mode; `is_published` picks the published version or the current draft.
# Consume Streaming Responses
Source: https://docs.dify.ai/en/api-reference/guides/streaming
Choose a response mode, parse the SSE stream, dispatch events, and recover when a connection drops
Generation endpoints return either one complete response or a Server-Sent Events (SSE) stream, chosen per request with `response_mode`. Streaming is the usual choice: the reply renders as it generates, and long runs aren't cut off mid-flight.
## Choose a Response Mode
`blocking` returns a single JSON body once generation finishes. It's the simpler integration for short, non-interactive calls, but long generations risk interruption: proxies cut long requests, and on Dify Cloud the edge proxy may end the connection if the upstream response doesn't arrive within its timeout.
`streaming` delivers the reply as SSE events. Use it for anything user-facing, for long runs, and for every flow that pauses for [Human Input](/en/api-reference/guides/human-input-flow).
<Info>
Legacy Agent and Agent apps stream only.
</Info>
## Parse the Stream
Every event except `ping` arrives as a `data: ` line holding one JSON object, terminated by a blank line.
Read the `event` field to decide what to do, and skip anything that isn't a `data: ` line: the keep-alive `ping` arrives as a bare `event: ping` line with no `data:` payload.
Chatflow and Workflow app streams open with a `ping` as the very first frame, and more arrive roughly every 10 seconds during the run. Treat the first `data:` event (`workflow_started`), not the first frame, as the signal that the run was accepted.
```python theme={null}
import json
import requests
body = {
"query": "What are this month's top issues?",
"inputs": {},
"user": "customer-4821",
"response_mode": "streaming",
}
with requests.post(url, headers=headers, json=body, stream=True) as r:
for line in r.iter_lines(decode_unicode=True):
if not line or not line.startswith("data: "):
continue # skips blank separators and ping lines
event = json.loads(line[len("data: "):])
handle(event)
```
On the wire, a stream looks like this:
```text theme={null}
event: ping
data: {"event": "workflow_started", "task_id": "c3800678-…", "workflow_run_id": "fb47b2e6-…", "data": {…}}
data: {"event": "node_finished", "task_id": "c3800678-…", "workflow_run_id": "fb47b2e6-…", "data": {…}}
```
<Tip>
When testing with curl, pass `-N` (`--no-buffer`) so events print as they arrive instead of after the run completes.
</Tip>
## Dispatch by Event Type
Which events arrive depends on the app type. See the event tables on [Send Chat Message](/en/api-reference/chat-messages/send-chat-message), [Run Workflow](/en/api-reference/workflow-runs/run-workflow), and [Send Completion Message](/en/api-reference/completion-messages/send-completion-message) for the contract.
The typical minimum:
1. Concatenate reply chunks in order:
* `message` events for Chatbot and Chatflow apps
* `agent_message` events for Legacy Agent and Agent apps
For Agent apps, a single closing `message` event repeats the complete answer; treat it as the final answer, not extra text to append.
2. Close on the right terminal event:
* `message_end` for Chatbot, Legacy Agent, and Agent apps
* `message_end` then `workflow_finished` (both arrive, in that order) for Chatflow apps
* `workflow_finished` for Workflow apps
3. Surface `error`.
## Handle Errors Mid-Stream
A failure after the stream opens doesn't change the HTTP status: the connection stays `200`. How the failure surfaces depends on where it happens:
* A workflow node failure arrives as `node_finished` and `workflow_finished` events with `status: "failed"`.
* Other failures end the stream with an `error` event carrying `status`, `code`, and `message`.
Handle both, and treat either as terminal for that request.
## Reconnect and Resume
Two identifiers matter, and they're easy to mix up:
* `task_id` controls the in-flight generation and is what the stop endpoints ([Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation) / [Stop Workflow Task](/en/api-reference/workflow-runs/stop-workflow-task)) take.
* `workflow_run_id` names the persistent run record.
Both arrive on the stream itself: every event except `error` carries `task_id`, and workflow and node events carry `workflow_run_id`. Save `workflow_run_id` as soon as it arrives: if the connection drops mid-run, it's the only handle you have for reconnecting or checking the outcome.
For workflow-backed runs (Workflow and Chatflow apps), a dropped connection isn't fatal. Reopen the stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), passing the `workflow_run_id` and the same `user` that started the run. A mismatch returns 404.
Add `include_state_snapshot=true` to first replay the status of nodes that already ran, and `continue_on_pause=true` to keep one stream open across multiple Human Input pauses.
After reconnecting to a still-running workflow, confirm completion with [Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail) rather than relying on the reconnected stream's final event alone.
Other replies have no resume endpoint: if the connection drops mid-reply, issue a new request. For chat-style apps, [List Conversation Messages](/en/api-reference/conversations/list-conversation-messages) shows what was saved to the conversation.
## Keep the Connection Alive
Set your client's read timeout comfortably above the 10-second `ping` interval so idle stretches between events don't kill the connection. The pings themselves need no handling beyond being skipped.
# Workflow App API
Source: https://docs.dify.ai/en/api-reference/guides/workflow
API for Workflow apps, covering workflow execution, run control and streaming, Human Input pauses, and run history
[Workflow apps](/en/cloud/use-dify/build/workflow-chatflow) run in `workflow` mode, executing the published workflow once per call and returning its outputs. There's no conversation state between calls, so each run is independent of any previous one.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Run a Workflow
* **[Run Workflow](/en/api-reference/workflow-runs/run-workflow)**: execute the app's currently published workflow with the input variables you provide.
Streaming mode delivers events live as nodes execute; blocking mode returns once the run finishes.
* **[Run Workflow by ID](/en/api-reference/workflow-runs/run-workflow-by-id)**: execute a specific published version instead, identified by the `workflow_id` from an earlier run response or run detail lookup.
## Follow and Control a Run
Whichever mode you run in, the response carries two IDs: `task_id` controls the run while it's active, and `workflow_run_id` identifies the persisted record afterward.
* **[Stop Workflow Task](/en/api-reference/workflow-runs/stop-workflow-task)**: cancel an active run by its `task_id`. Works in streaming mode only; a blocking call has already finished by the time it returns.
* **[Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events)**: resume a run's event stream from its `workflow_run_id` after a dropped connection or a pause.
Pass `include_state_snapshot=true` to replay the status of already-executed nodes first, or `continue_on_pause=true` to stay open across multiple Human Input pauses.
## Pause for Human Input
When a run reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input) whose delivery method is web app, complete the pause over the API:
<Steps>
<Step title="Listen for the pause">
The run's event stream emits `human_input_required` carrying a `form_token` and the run's `workflow_run_id`, then ends with the `workflow_paused` event.
</Step>
<Step title="Fetch the form">
Load the form's contents with [Get Human Input Form](/en/api-reference/human-input/get-human-input-form), using the `form_token`.
</Step>
<Step title="Submit the response">
Send the recipient's input with [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form). Submitting resumes the run.
</Step>
<Step title="Resume the stream">
Open a new stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), using the `workflow_run_id` from the paused stream, and follow the remaining events through to the run's finish.
</Step>
</Steps>
For file-attached submissions and the full event sequence, see the [Human Input Flow](/en/api-reference/guides/human-input-flow) guide.
## Inspect Past Runs
* **[Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail)**: a run's status and outputs, by its `workflow_run_id`.
* **[List Workflow Logs](/en/api-reference/workflow-runs/list-workflow-logs)**: run-level summaries covering status, token usage, step count, and timing, rather than a node-by-node execution log; filter by keyword, status, date range, or who triggered the run.
For node-level events, stream the run instead of listing its logs: call [Run Workflow](/en/api-reference/workflow-runs/run-workflow) in streaming mode for a run you're starting, or [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) for one already in progress.
## Work with Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file, then pass the returned `id` as `upload_file_id` in a file-type input variable when you run the workflow. Files are scoped to the uploading end user.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak an input value instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a workflow's text output back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
# Get Human Input Form
Source: https://docs.dify.ai/en/api-reference/human-input/get-human-input-form
/en/api-reference/openapi_service.json get /form/human_input/{form_token}
**Available for**: Chatflow, Workflow apps.
Returns the contents of a paused Human Input form. Requires web app delivery.
For the full sequence of Human Input calls, see [Human Input Flow](/en/api-reference/guides/human-input-flow).
# Submit Human Input Form
Source: https://docs.dify.ai/en/api-reference/human-input/submit-human-input-form
/en/api-reference/openapi_service.json post /form/human_input/{form_token}
**Available for**: Chatflow, Workflow apps.
Submits the recipient's response to a paused Human Input form. On acceptance the workflow resumes; follow the resumed run via [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events). Requires web app delivery.
# Create an Empty Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/create-an-empty-knowledge-base
/en/api-reference/openapi_service.json post /datasets
Creates an empty knowledge base. Add documents to it with [Create Document by Text](/en/api-reference/documents/create-document-by-text) or [Create Document by File](/en/api-reference/documents/create-document-by-file).
# Delete Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/delete-knowledge-base
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}
Permanently deletes a knowledge base and all of its documents.
# Get Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/get-knowledge-base
/en/api-reference/openapi_service.json get /datasets/{dataset_id}
Returns detailed information about a knowledge base, including its embedding model, retrieval configuration, and document statistics.
# List Knowledge Bases
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/list-knowledge-bases
/en/api-reference/openapi_service.json get /datasets
Returns a paginated list of knowledge bases, optionally filtered by keyword or tags.
# Retrieve Chunks from a Knowledge Base / Test Retrieval
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/retrieve-chunks-from-a-knowledge-base-test-retrieval
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/retrieve
Searches a knowledge base and returns the chunks most relevant to the query, for both production retrieval and test retrieval.
# Update Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/update-knowledge-base
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}
Updates a knowledge base. Only the fields included in the request body are changed.
# Create Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/create-metadata-field
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/metadata
Create a custom metadata field for annotating documents in the knowledge base with structured information.
# Delete Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/delete-metadata-field
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/metadata/{metadata_id}
Permanently delete a custom metadata field. Documents that used the field lose their values for it.
# Get Built-in Metadata Fields
Source: https://docs.dify.ai/en/api-reference/metadata/get-built-in-metadata-fields
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/metadata/built-in
Returns the built-in metadata fields provided by the system.
# List Metadata Fields
Source: https://docs.dify.ai/en/api-reference/metadata/list-metadata-fields
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/metadata
Returns all metadata fields for the knowledge base, both custom and built-in, with the count of documents using each field.
# Update Built-in Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/update-built-in-metadata-field
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/metadata/built-in/{action}
Enable or disable built-in metadata fields for the knowledge base.
# Update Document Metadata in Batch
Source: https://docs.dify.ai/en/api-reference/metadata/update-document-metadata-in-batch
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/metadata
Update metadata values for multiple documents in a single request.
# Update Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/update-metadata-field
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/metadata/{metadata_id}
Rename a custom metadata field.
# Create Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/create-knowledge-tag
/en/api-reference/openapi_service.json post /datasets/tags
Create a tag for organizing knowledge bases.
# Create Tag Binding
Source: https://docs.dify.ai/en/api-reference/tags/create-tag-binding
/en/api-reference/openapi_service.json post /datasets/tags/binding
Bind one or more tags to a knowledge base. A knowledge base can have multiple tags.
# Delete Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/delete-knowledge-tag
/en/api-reference/openapi_service.json delete /datasets/tags
Permanently delete a knowledge base tag. Does not delete the knowledge bases that were tagged.
# Delete Tag Binding
Source: https://docs.dify.ai/en/api-reference/tags/delete-tag-binding
/en/api-reference/openapi_service.json post /datasets/tags/unbinding
Remove one or more tags from a knowledge base.
# List Knowledge Tags
Source: https://docs.dify.ai/en/api-reference/tags/list-knowledge-tags
/en/api-reference/openapi_service.json get /datasets/tags
Returns all knowledge base tags in the workspace.
# Update Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/update-knowledge-tag
/en/api-reference/openapi_service.json patch /datasets/tags
Rename a knowledge base tag.
# Get Workflow Run Detail
Source: https://docs.dify.ai/en/api-reference/workflow-runs/get-workflow-run-detail
/en/api-reference/openapi_service.json get /workflows/run/{workflow_run_id}
**Available for**: Chatflow, Workflow apps.
Get a single workflow run's status, inputs, outputs, and execution metrics.
# List Workflow Logs
Source: https://docs.dify.ai/en/api-reference/workflow-runs/list-workflow-logs
/en/api-reference/openapi_service.json get /workflows/logs
**Available for**: Chatflow, Workflow apps.
List past workflow runs with optional filters. Each entry is a run-level summary (status, token usage, step count, and timing), not a node-by-node execution log.
To follow a run's node-level events, stream it instead:
- **A run you start**: use [Run Workflow](/en/api-reference/workflow-runs/run-workflow) in streaming mode, which emits `node_started` and `node_finished` as the run executes.
- **A run already in progress**: call [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) with `include_state_snapshot=true` to replay each executed node's status, then stream the rest.
A finished run's node-level logs aren't available through the Service API.
# Run Workflow
Source: https://docs.dify.ai/en/api-reference/workflow-runs/run-workflow
/en/api-reference/openapi_service.json post /workflows/run
**Available for**: Workflow apps.
Run the app's published workflow and return its outputs, either in a single `blocking` response or as a `streaming` Server-Sent Events feed. Requires a published workflow.
# Run Workflow by ID
Source: https://docs.dify.ai/en/api-reference/workflow-runs/run-workflow-by-id
/en/api-reference/openapi_service.json post /workflows/{workflow_id}/run
**Available for**: Workflow apps.
Run a specific published workflow version, identified by the `workflow_id` in the path. Request body, response, and streaming behavior match [Run Workflow](/en/api-reference/workflow-runs/run-workflow); only the executed version differs.
# Stop Workflow Task
Source: https://docs.dify.ai/en/api-reference/workflow-runs/stop-workflow-task
/en/api-reference/openapi_service.json post /workflows/tasks/{task_id}/stop
**Available for**: Workflow apps.
Stop a running workflow task. Only supported in `streaming` mode.
# Stream Workflow Events
Source: https://docs.dify.ai/en/api-reference/workflow-runs/stream-workflow-events
/en/api-reference/openapi_service.json get /workflow/{workflow_run_id}/events
**Available for**: Chatflow, Workflow apps.
Resume the [Server-Sent Events stream](/en/api-reference/guides/streaming) for a workflow run after a pause or a dropped SSE connection. For runs that have already finished, the stream emits a single `workflow_finished` event and closes.
To check an in-progress run's node-level status and progress, call it with `include_state_snapshot=true`: the stream replays each already-executed node's status before streaming new events.
# Article Reader Using File Upload
Source: https://docs.dify.ai/en/learn/tutorials/article-reader
In Dify, you can use the knowledge base to allow agent to obtain accurate information from a large amount of text content. However, in many cases, the local files provided are not large enough to warrant the use of the knowledge base. In such cases, you can use the file upload feature to directly provide local files as context for the LLM to read.
In this experiment, we will build the article reader as a case study. This assistant will ask questions based on the uploaded document, helping users to read papers and other materials with those questions in mind.
## You Will Learn
* File upload usage
* Basic usage of Chatflow
* Prompt writing skill
* Iteration node usage
* Doc extractor and list operator usage
## **Prerequisites**
Create a Chatflow in Dify. Make sure you have added a model provider and have sufficient quota.
## **Add Nodes**
In this experiment, at least four types of nodes are required: start node, document extractor node, LLM node, and answer node.
### **Start Node**
In the start node, you need to add a file variable. File upload is supported in v0.10.0 Dify, allowing you to add files as variable.
In the start node, you need to add a file variable and check the document in the supported file types.
Some readers might notice the `sys.files` in the system variables, which are files or file lists uploaded by users in the dialog box.
The difference between creating your own file variables is that this feature requires enabling file upload in the functions and setting the upload file types, and each time a new file is uploaded in the dialog, this variable will be overwritten.
Please choose the appropriate file upload method according to your business scenario.
### **Doc Extractor**
**LLM cannot read files directly.** This is a common misconception among many users when they first use file upload, as they might think simply using the file as a variable in an LLM node would work. However, in reality, the LLM reads nothing from file variables.
Thus, Dify introduced the **doc extractor** node, which can extract text from the file variable and output it as a text variable.
The **doc extractor** node takes the file variable from the **start** node as input and converts document files into text output.
<Frame>
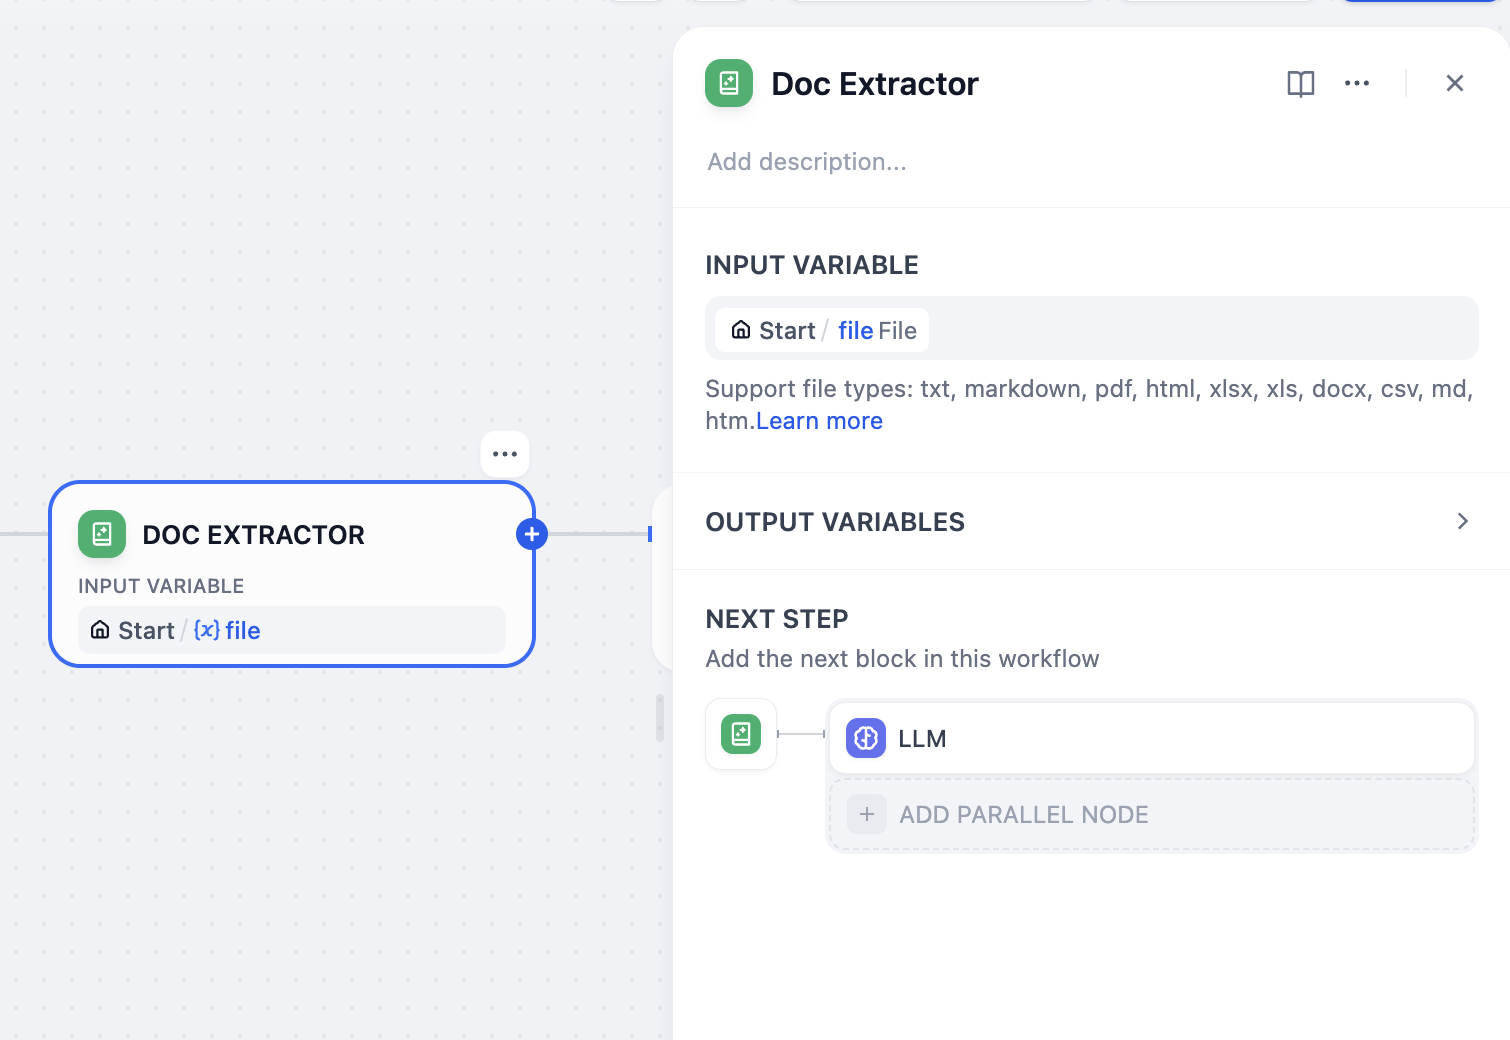
</Frame>
### **LLM**
In this experiment, two LLM nodes need to be designed: structure extraction and question generation.
#### **Structure Extraction**
The structure extraction node can extract the structure of the original text, summarizing key content.
The prompts are as follow:
```
Read the following article content and perform the task
{{Result variable of the document extractor}}
# Task
- **Main Objective**: Thoroughly analyze the structure of the article.
- **Objective**: Detail the content of each part of the article.
- **Requirements**: Analyze as detailed as possible.
- **Restrictions**: No specific format restrictions, but the analysis must be organized and logical.
- **Expected Output**: A detailed analysis of the article structure, including the main content and role of each part.
# Reasoning Order
- **Reasoning Part**: By carefully reading the article, identify and analyze its structure.
- **Conclusion Part**: Provide specific content and role for each part.
# Output Format
- **Analysis Format**: Each part should be listed in a headline format, followed by a detailed explanation of that part's content.
- **Structure Form**: Markdown, to enhance readability.
- **Specific Description**: The content and role of each part, including but not limited to the introduction, body, conclusion, citations, etc.
```
#### **Question Generation**
The question generation node can summarize the issues of the article from the content summarized by the structure extraction node, assisting the reader in thinking through the questions during the reading process.
The prompts are as follow:
```
Read the following article content and perform the task
{{Output of the structure extraction}}
# Task
- **Main Objective**: Thoroughly read the above text, and propose as many questions as possible for each part of the article.
- **Requirements**: Questions should be meaningful and valuable, worthy of consideration.
- **Restrictions**: No specific restrictions.
- **Expected Output**: A series of questions for each part of the article, each question should have depth and thinking value.
# Reasoning Order
- **Reasoning Part**: Thoroughly read the article, analyze the content of each part, and consider the deep questions each part may raise.
- **Conclusion Part**: Pose meaningful and valuable questions, ensuring they provoke in-depth thought.
# Output Format
- **Format**: Each question should be listed separately, numbered.
- **Content**: Propose questions for each part of the article (such as introduction, background, methods, results, discussion, conclusion, etc.).
- **Quantity**: As many as possible, but each question should be meaningful and valuable.
```
## **Question 1: Handling Multiple Uploaded Files**
To handle multiple uploaded files, an iterative node is needed.
The iterative node is similar to the while loop in many programming languages, except that Dify has no conditional restrictions, and the **input variable can only be of type `array` (list)**. The reason is that Dify will execute all the content in the list until it is done.
<Frame>
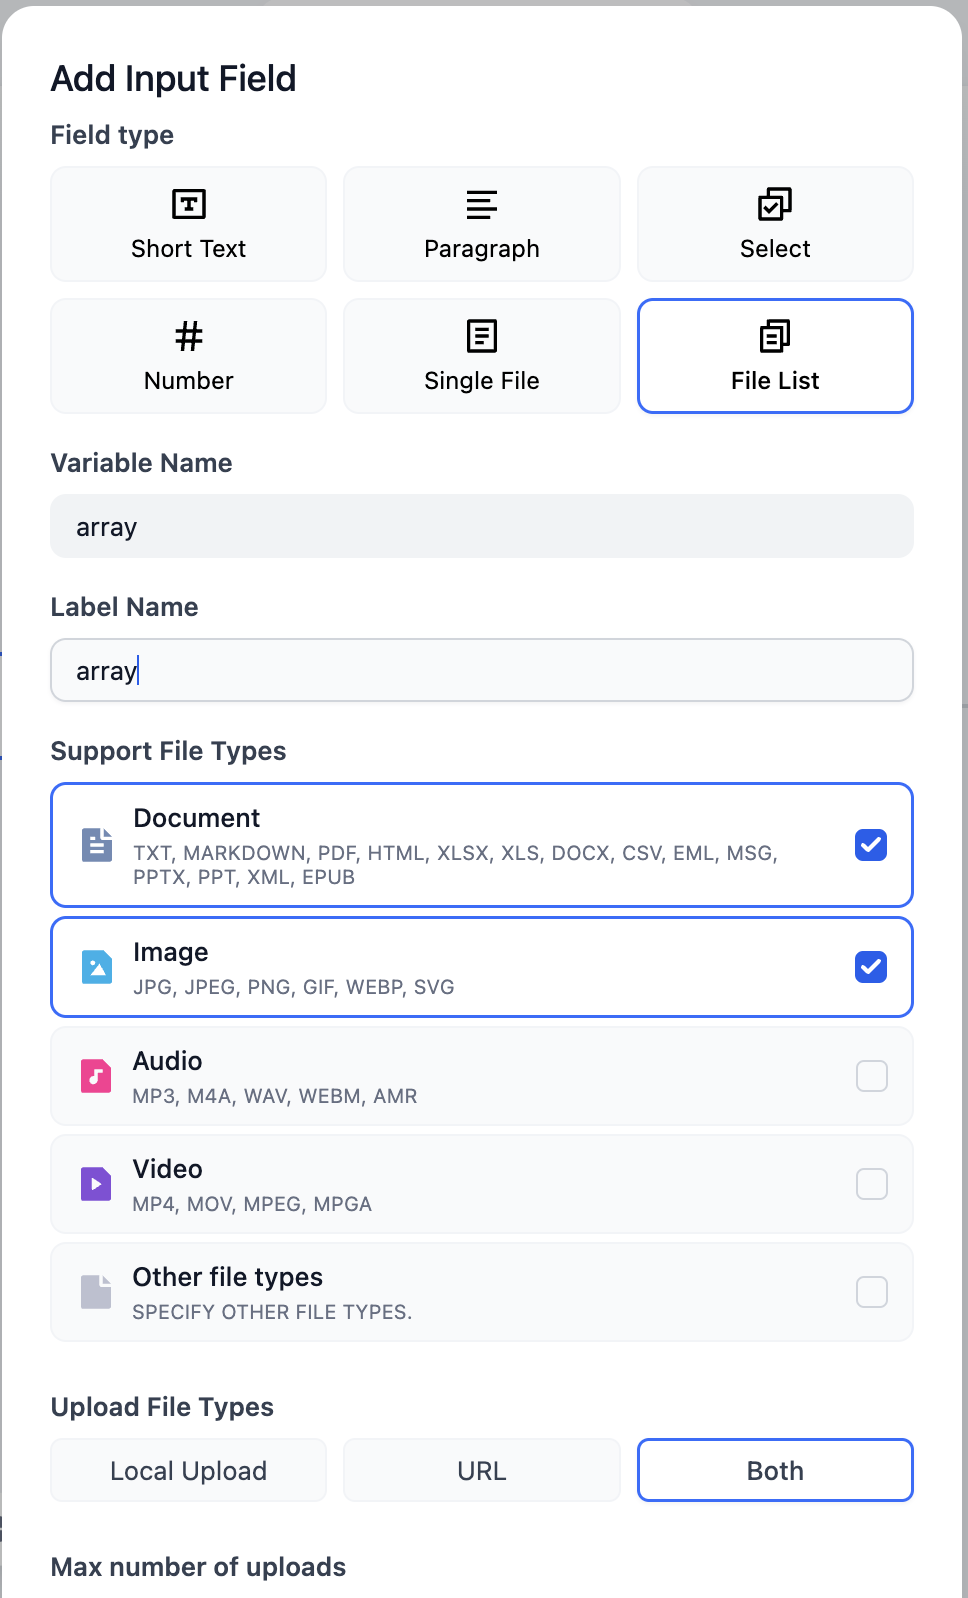
</Frame>
Therefore, you need to adjust the file variable in the start node to an `array` type, i.e., a file list.
<Frame>
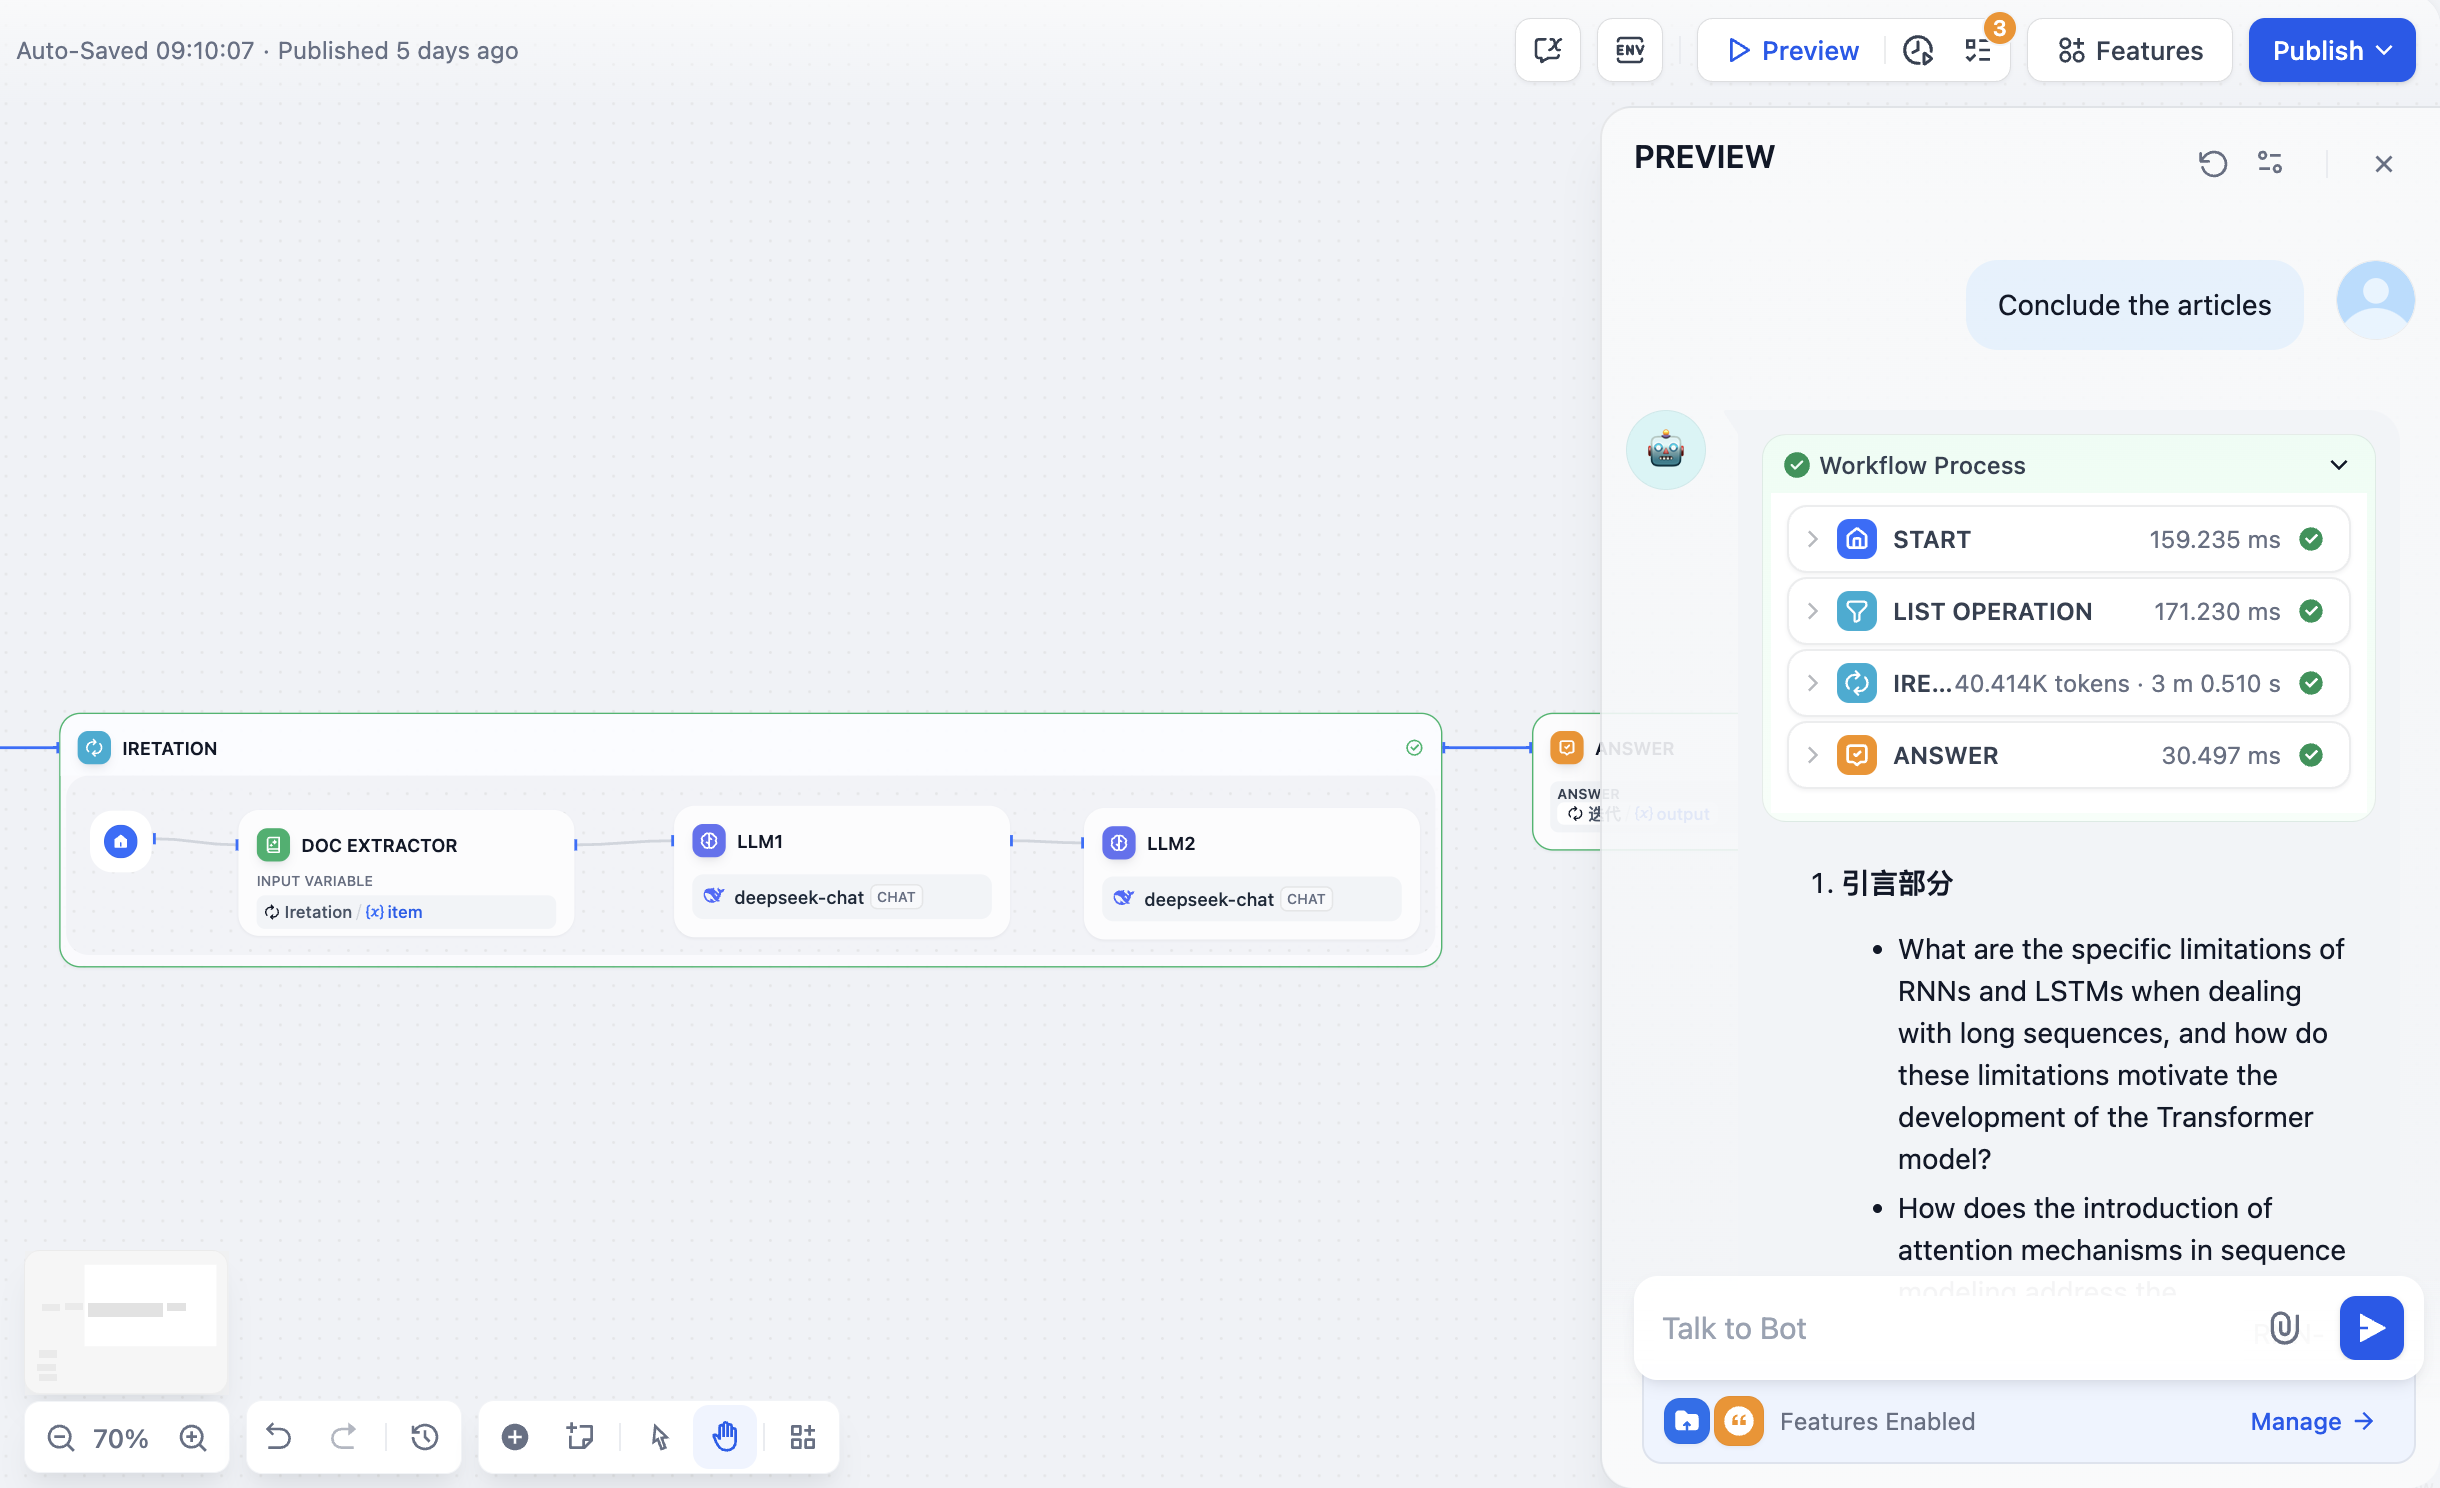
</Frame>
## **Question 2: Handling Specific Files from a File List**
In Question 1, some readers might notice that Dify will process all files before ending the loop, while in some cases, only a part of the files need to be operated on, not all. For this issue, you can process the file list in Dify using the **list operation** node. List operations can operate on all array-type variables, not just file lists.
For example, limit the analysis to only document-type files and sort the files to be processed in order of file names.
Before the iterative node, add a list operation, adjust the **filter condiftion** and **order by**, then change the input of the iterative node to the output of the list operation node.
<Frame>
</Frame>
# AI Image Generation App
Source: https://docs.dify.ai/en/learn/tutorials/build-ai-image-generation-app
With the rise of image generation, many excellent image generation products have emerged, such as Dall-e, Flux, Stable Diffusion, etc.
In this article, you will learn how to develop an AI image generation app using Dify.
<Frame>

</Frame>
## You Will Learn
* Methods for building an Agent using Dify
* Basic concepts of Agent
* Fundamentals of prompt engineering
* Tool usage
* Concepts of large model hallucinations
## 1. Set Stability API Key
[Click here](https://platform.stability.ai/account/keys) to go to the Stability API key management page.
If you haven't registered yet, you will be asked to register before entering the API management page.
After entering the management page, click `copy` to copy the key.
<Frame>

</Frame>
Next, fill in the key under **Tools** > **Stability** in your Dify instance by following these steps:
* Log in to Dify
* Enter Tools
* Select Stability
* Click `Authorize`
<Frame>

</Frame>
* Fill in the key and save
## 2. Configure Model Providers
To optimize interaction, we need an LLM to concretize user instructions, i.e., to write prompts for generating images. Next, we will configure model providers in Dify following these steps.
Add a model provider by following the steps in the image below:
Go to **Integrations** > **Model Provider**
<Frame>
</Frame>
If you haven't found a suitable model provider, the groq platform provides free call credits for LLMs like Llama.
Log in to [groq API Management Page](https://console.groq.com/keys)
Click **Create API Key**, set a desired name, and copy the API Key.
Back to **Dify - Model Providers**, select **groqcloud**, and click **Setup**.
<Frame>

</Frame>
Paste the API Key and save.
<Frame>
</Frame>
## 3. Build an Agent
Back to **Dify - Studio**, select **Create from Blank**.
<Frame>

</Frame>
In this experiment, we only need to understand the basic usage of Agent.
<Info>
**What is an Agent**
An Agent is an AI system that simulates human behavior and capabilities. It interacts with the environment through natural language processing, understands input information, and generates corresponding outputs. The Agent also has "perception" capabilities, can process and analyze various forms of data, and can call and use various external tools and APIs to complete tasks, extending its functional scope. This design allows the Agent to handle complex situations more flexibly and simulate human thinking and behavior patterns to some extent.
</Info>
Select **Agent**, fill in the name.
<Frame>
</Frame>
Next, you will enter the Agent orchestration interface as shown below.
<Frame>
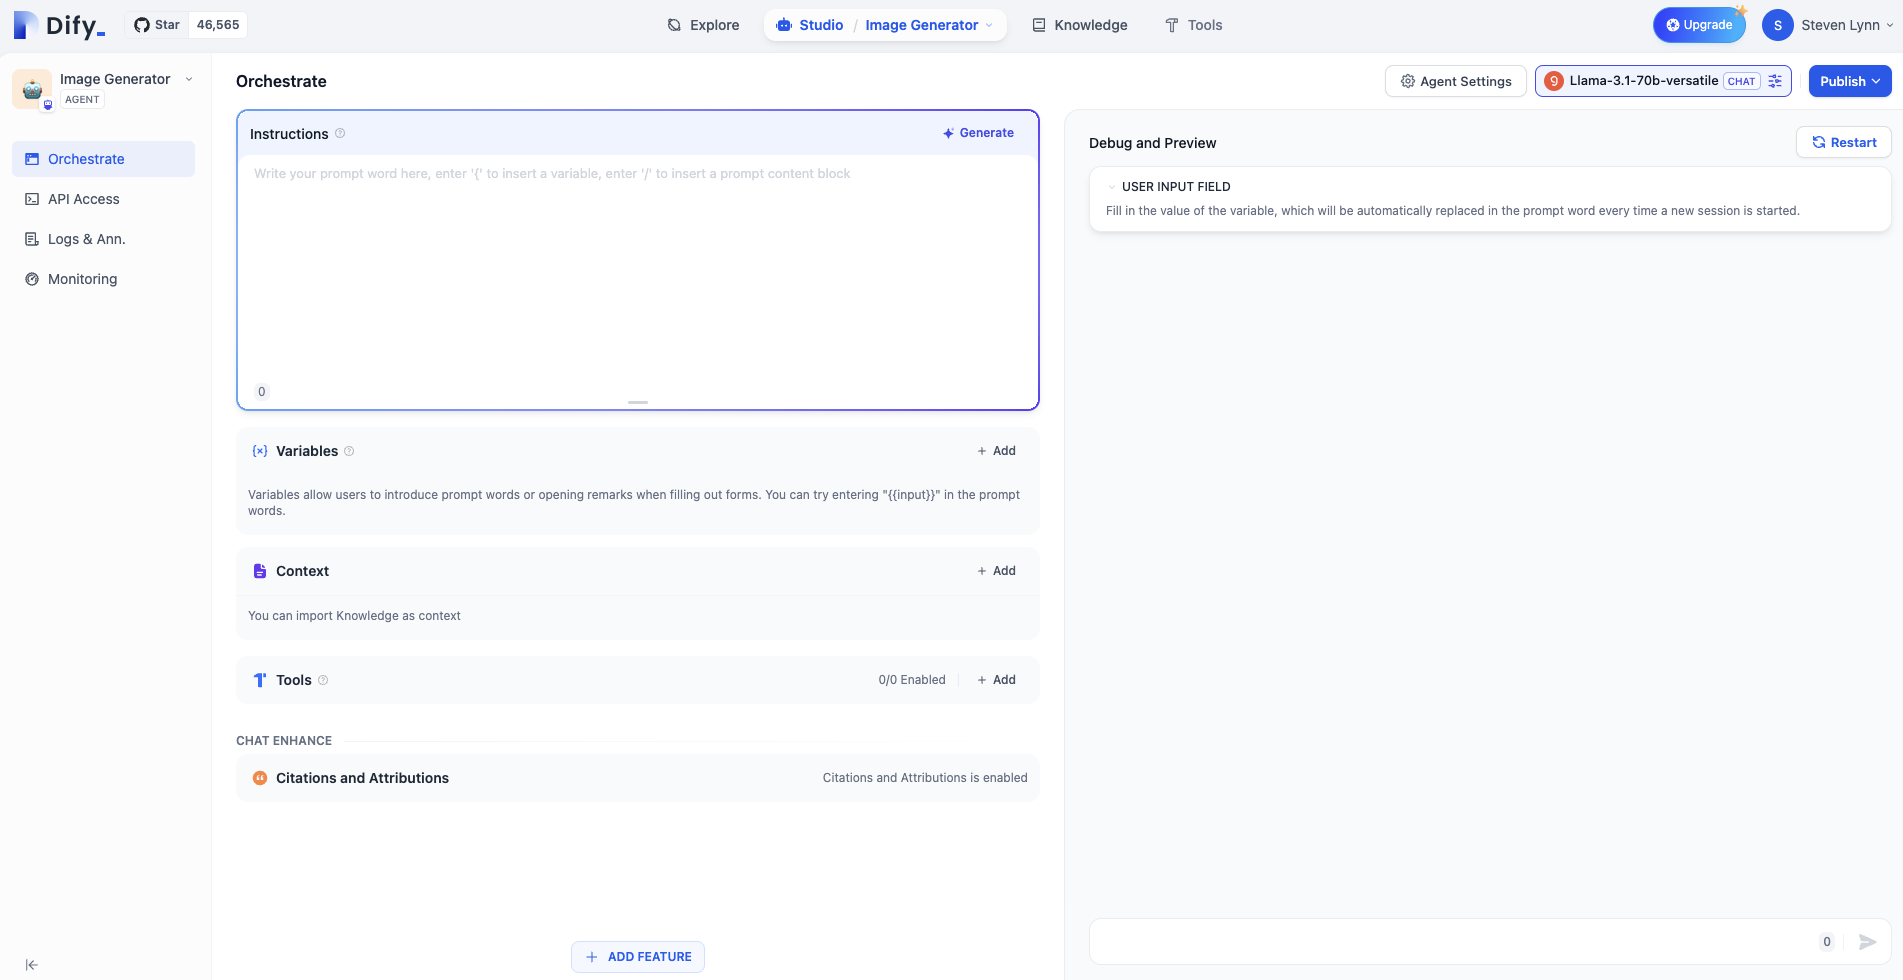
</Frame>
Select the LLM. Here we use Llama-3.1-70B provided by groq as an example:
<Frame>
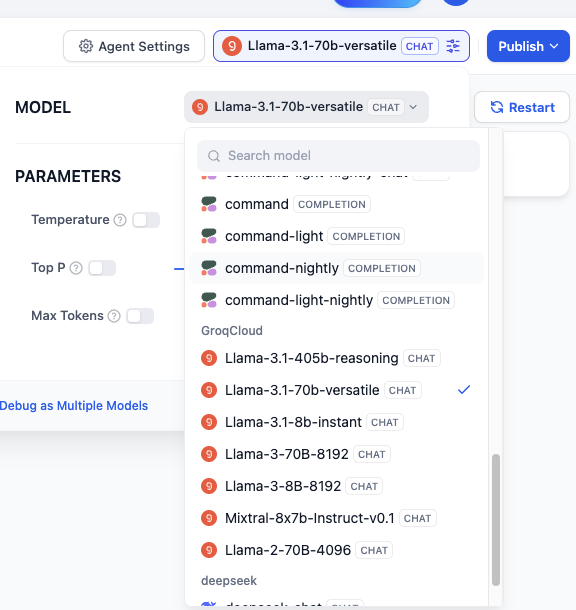
</Frame>
Select Stability in **Tools**:
<Frame>
</Frame>
<Frame>
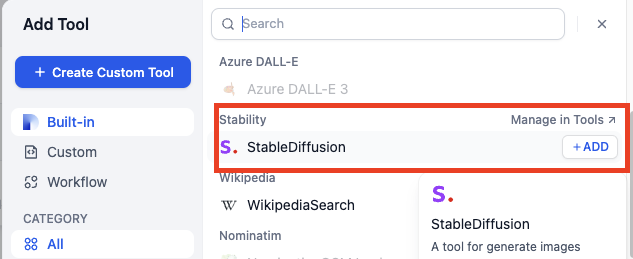
</Frame>
### Write Prompts
Prompts are the soul of the Agent and directly affect the output effect. Generally, the more specific the prompts, the better the output, but overly lengthy prompts can also lead to negative effects.
The engineering of adjusting prompts is called Prompt Engineering.
In this experiment, you don't need to worry about not mastering Prompt Engineering; we will learn it step by step later.
Let's start with the simplest prompts:
```
Draw the specified content according to the user's prompt using stability_text2image.
```
Each time the user inputs a command, the Agent will know this system-level instruction, thus understanding that when executing a user's drawing task, it needs to call stability tool.
For example: Draw a girl holding an open book.
<Frame>

</Frame>
### Don't want to write prompts? Of course you can!
Click **Generate** in the upper right corner of Instructions.
<Frame>
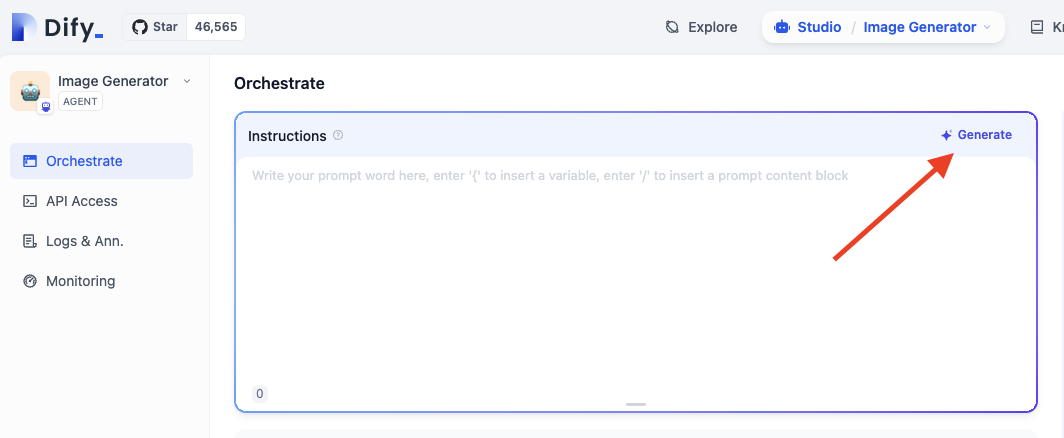
</Frame>
Enter your requirements in the **Instructions** and click **Generate**. The generated prompts on the right will show AI-generated prompts.
<Frame>
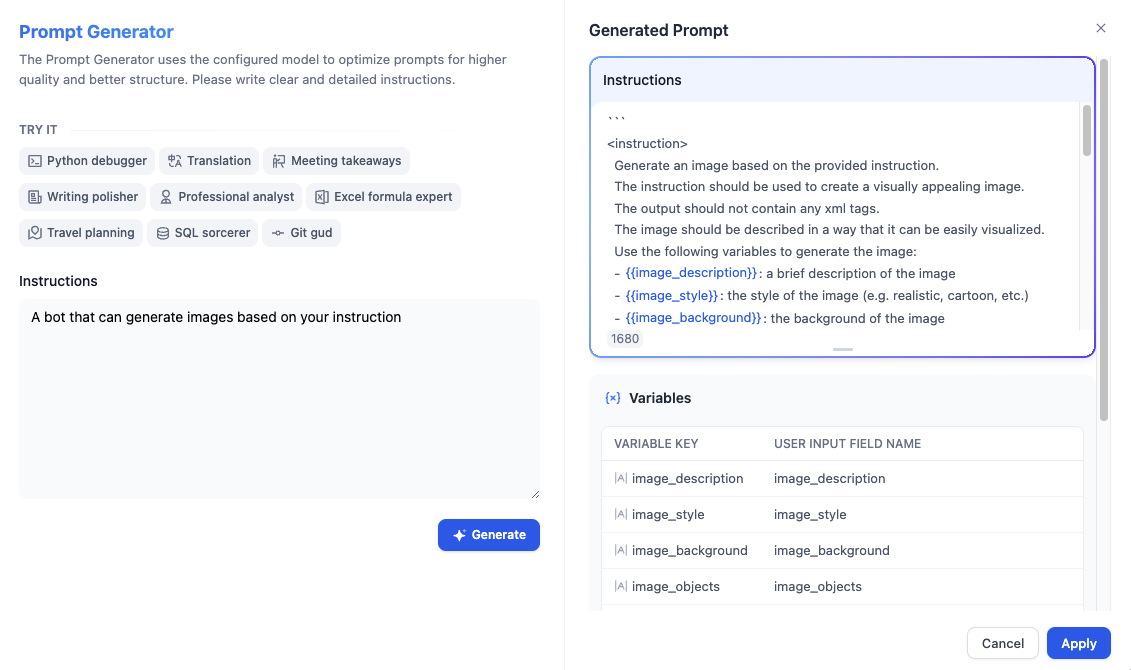
</Frame>
However, to develop a good understanding of prompts, we should not rely on this feature in the early stages.
## Publish
Click the publish button in the upper right corner, and after publishing, click **Open web app** to get a web page for an online running Agent.
<Frame>

</Frame>
Copy the URL of this web page to share with other friends.
## Question 1: How to Specify the Style of Generated Images?
We can add style instructions in the user's input command, for example: Anime style, draw a girl holding an open book.
<Frame>
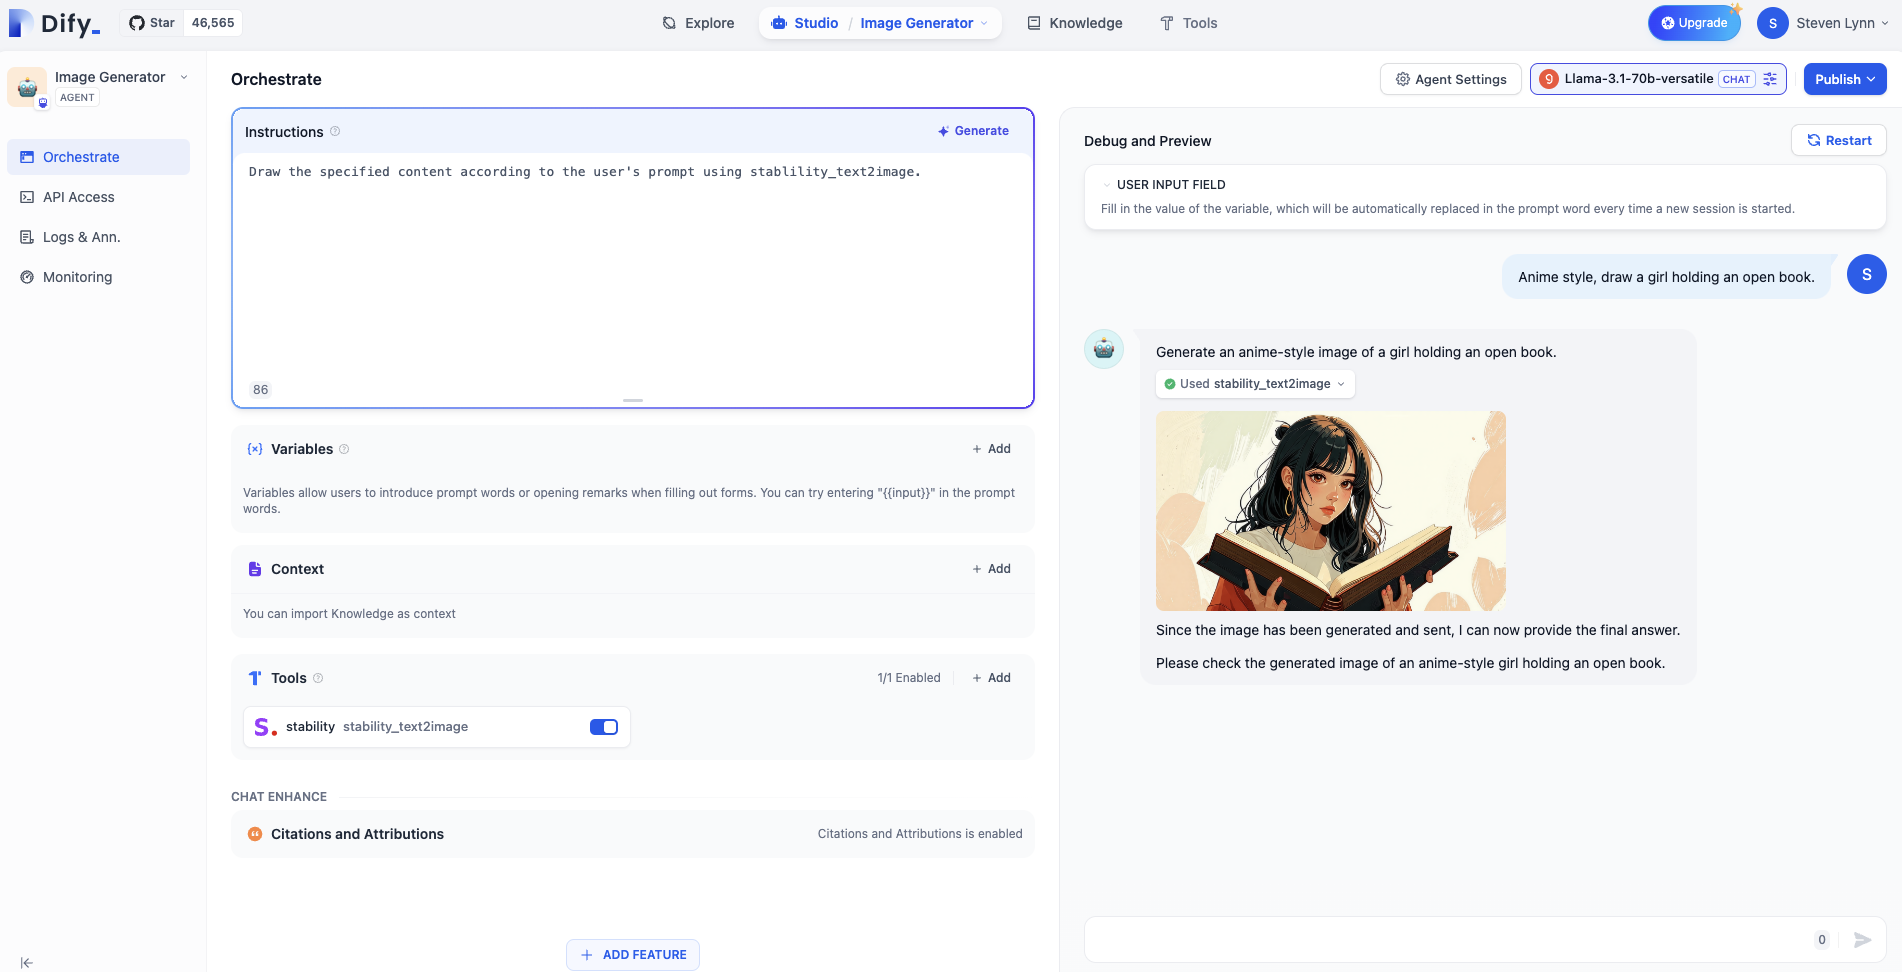
</Frame>
But if we want set the default style to anime style, we can add it to the system prompt because we previously learned that the system prompt is known each time the user command is executed and has a higher priority.
```
Draw the specified content according to the user's prompt using stability_text2image, the picture is in anime style.
```
## Question 2: How to Reject Certain Requests from Some Users?
In many business scenarios, we need to avoid outputting some unreasonable content, but LLMs are often "dumb" and will follow user instructions without question, even if the output content is wrong. This phenomenon of the model trying hard to answer users by fabricating false content is called **model hallucinations**. Therefore, we need the model to refuse user requests when necessary.
Additionally, users may also ask some content unrelated to the business, and we also need the Agent to refuse such requests.
We can use markdown format to categorize different prompts, writing the prompts that teach the Agent to refuse unreasonable content under the "Constraints" title. Of course, this format is just for standardization, and you can have your own format.
```
## Task
Draw the specified content according to the user's prompt using stability_text2image, the picture is in anime style.
## Constraints
If the user requests content unrelated to drawing, reply: "Sorry, I don't understand what you're saying."
```
For example, let's ask: What's for dinner tonight?
<Frame>

</Frame>
In some more formal business scenarios, we can call a sensitive word library to refuse user requests.
Add the keyword "dinner" in **Add Feature - Content Moderation**. When the user inputs the keyword, the Agent app outputs "Sorry, I don't understand what you're saying."
<Frame>

</Frame>
# Customer Service Bot With Knowledge Base
Source: https://docs.dify.ai/en/learn/tutorials/customer-service-bot
Build a Chatflow that answers customer questions from a knowledge base
In the last experiment, we learned the basic usage of file uploads. However, when the text we need to read exceeds the LLM's context window, we need to use a knowledge base.
<Info>
**What is context?**
The context window refers to the range of text that the LLM can "see" and "remember" when processing text. It determines how much previous text information the model can refer to when generating responses or continuing text. The larger the window, the more contextual information the model can utilize, and the generated content is usually more accurate and coherent.
</Info>
Previously, we learned about the concept of LLM hallucinations. In many cases, an LLM knowledge base allows the Agent to locate accurate information, thus accurately answering questions. It has applications in specific fields such as customer service and search tools.
Traditional customer service bots are often based on keyword retrieval. When users input questions outside of the keywords, the bot cannot solve the problem. The knowledge base is designed to solve this problem, enabling semantic-level retrieval and reducing the burden on human agents.
Before starting the experiment, remember that the core of the knowledge base is retrieval, not the LLM. The LLM enhances the output process, but the real need is still to generate answers.
### What You Will Learn in This Experiment
* Basic usage of Chatflow
* Usage of knowledge bases and external knowledge bases
* The concept of embeddings
### Prerequisites
#### Create an Application
In Dify, select **Create from Blank** > **Chatflow**.
<Frame>
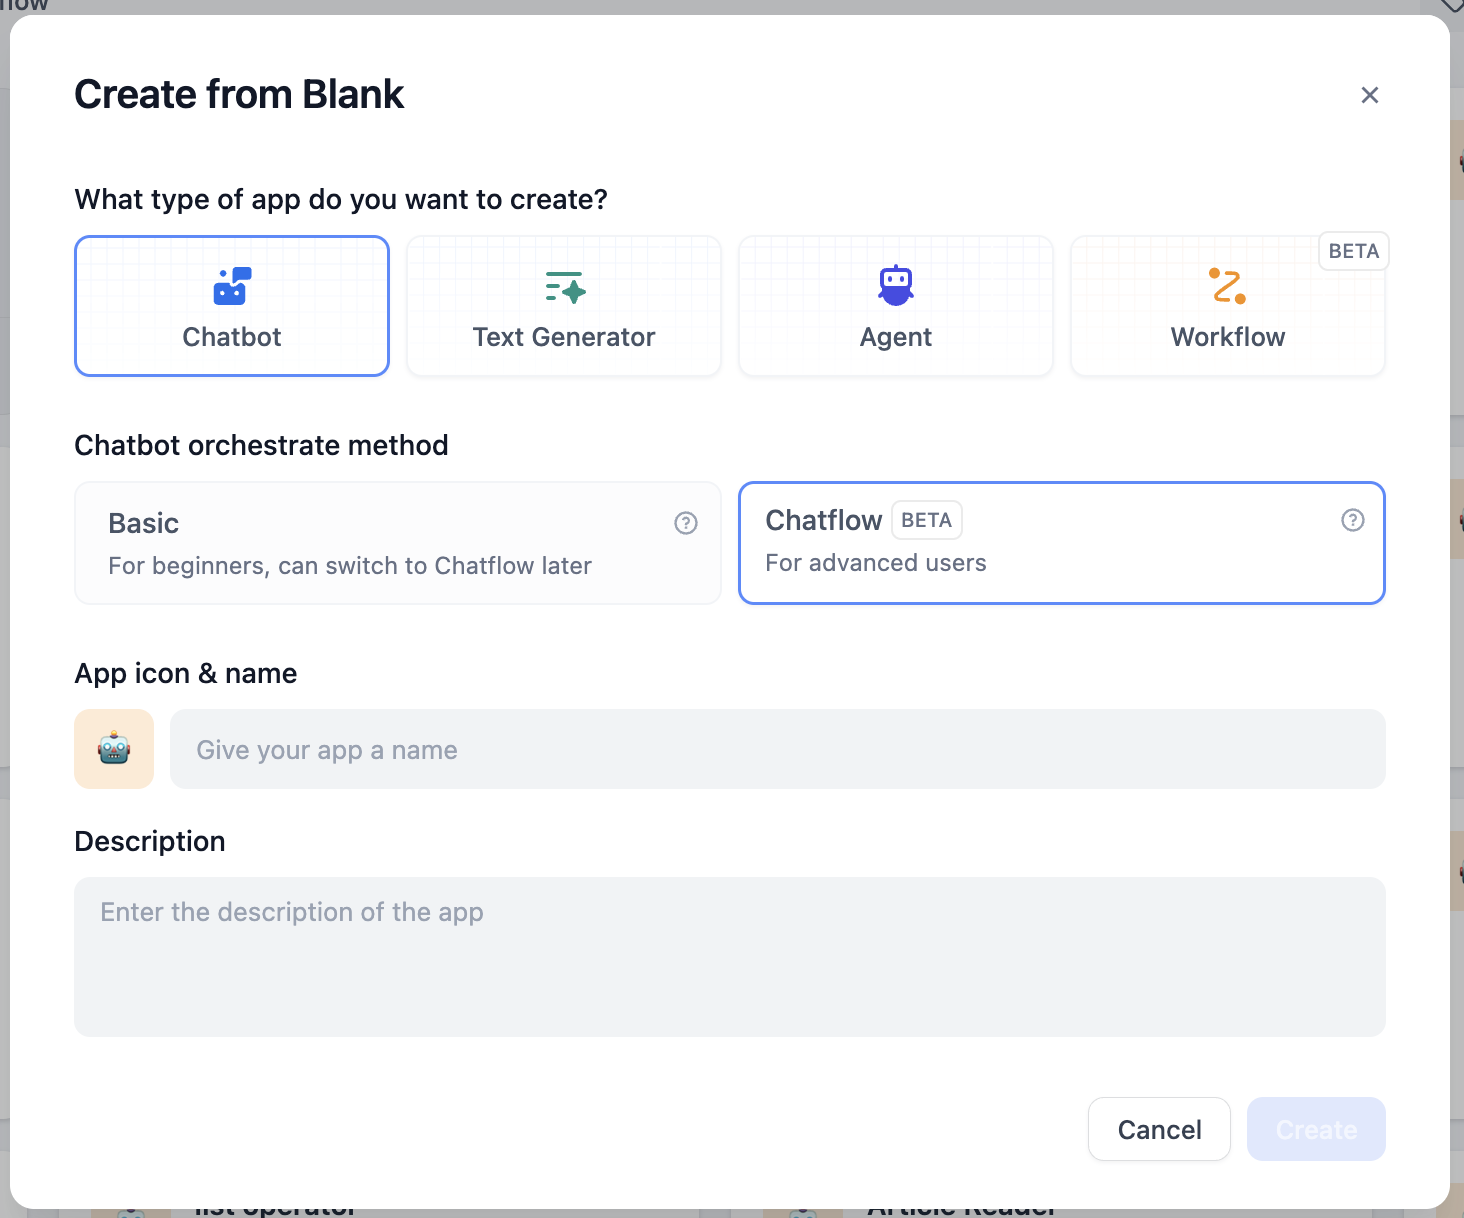
</Frame>
#### Add a Model Provider
This experiment involves using embedding models. Currently, supported embedding model providers include OpenAI and Cohere. In Dify's model providers, those with the `TEXT EMBEDDING` label are supported. Ensure you have added at least one and have sufficient balance.
<Frame>
</Frame>
<Info>
**What is embedding?**
"Embedding" is a technique that converts discrete variables (such as words, sentences, or entire documents) into continuous vector representations.
Simply put, when we process natural language into data, we convert text into vectors. This process is called embedding. Vectors of semantically similar texts will be close together, while vectors of semantically opposite texts will be far apart. LLMs use this data for training, predicting subsequent vectors, and thus generating text.
</Info>
### Create a Knowledge Base
Go to **Knowledge** > **Create Knowledge**.
Dify supports three data sources: documents, Notion, and web pages.
For local text files, note the file type and size limitations; syncing Notion content requires binding a Notion account; syncing a website requires using the **Jina** or **Firecrawl API**.
We will start with uploading a local document as an example.
#### Chunk Settings
After uploading the document, you will enter the following page:
<Frame>
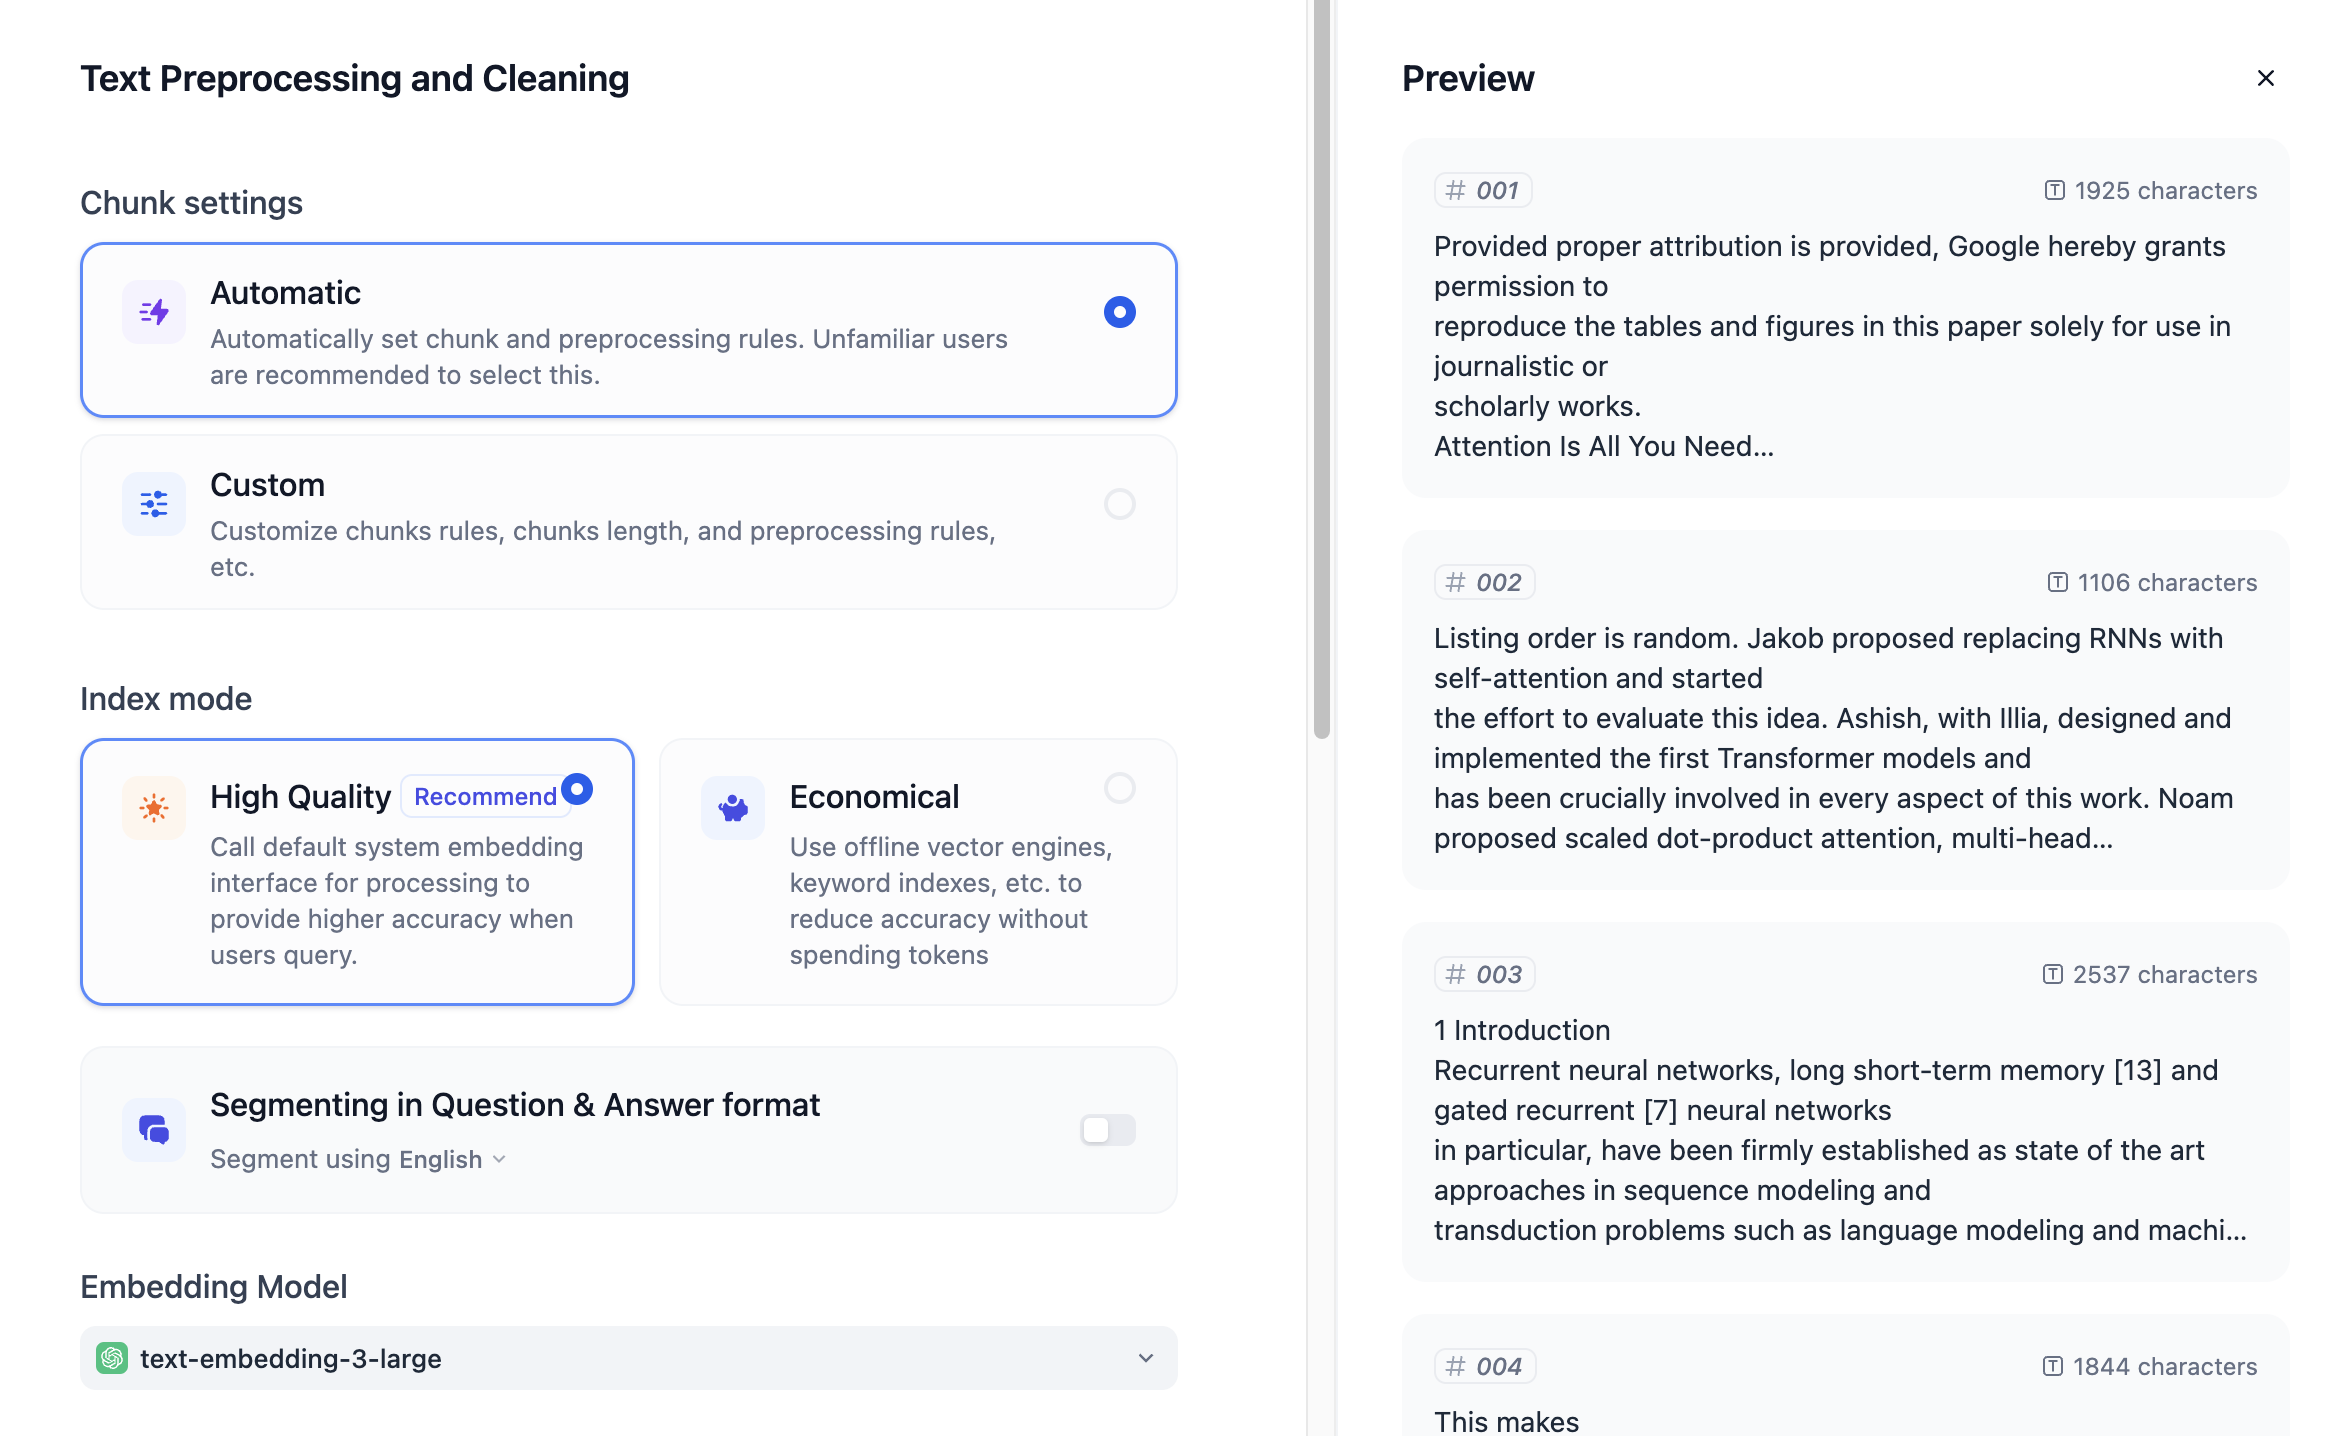
</Frame>
You can see a segmentation preview on the right. The default selection is automatic segmentation and cleaning. Dify will automatically divide the article into many paragraphs based on the content. You can also set other segmentation rules in the custom settings.
#### Index Method
Normally we prefer to select **High Quality**, but this will consume extra tokens. Selecting **Economical** will not consume any tokens.
#### Embedding Model
Please refer to the model provider's documentation and pricing information before use.
Different embedding models are suitable for different scenarios. For example, Cohere's `embed-english` is suitable for English documents, and `embed-multilingual` is suitable for multilingual documents.
#### Retrieval Settings
Dify provides three retrieval functions: vector retrieval, full-text retrieval, and hybrid retrieval. Hybrid retrieval is the most commonly used.
In hybrid retrieval, you can set weights or use a reranking model. When setting weights, you can set whether the retrieval should focus more on semantics or keywords. For example, in the image below, semantics account for 70% of the weight, and keywords account for 30%.
<Frame>
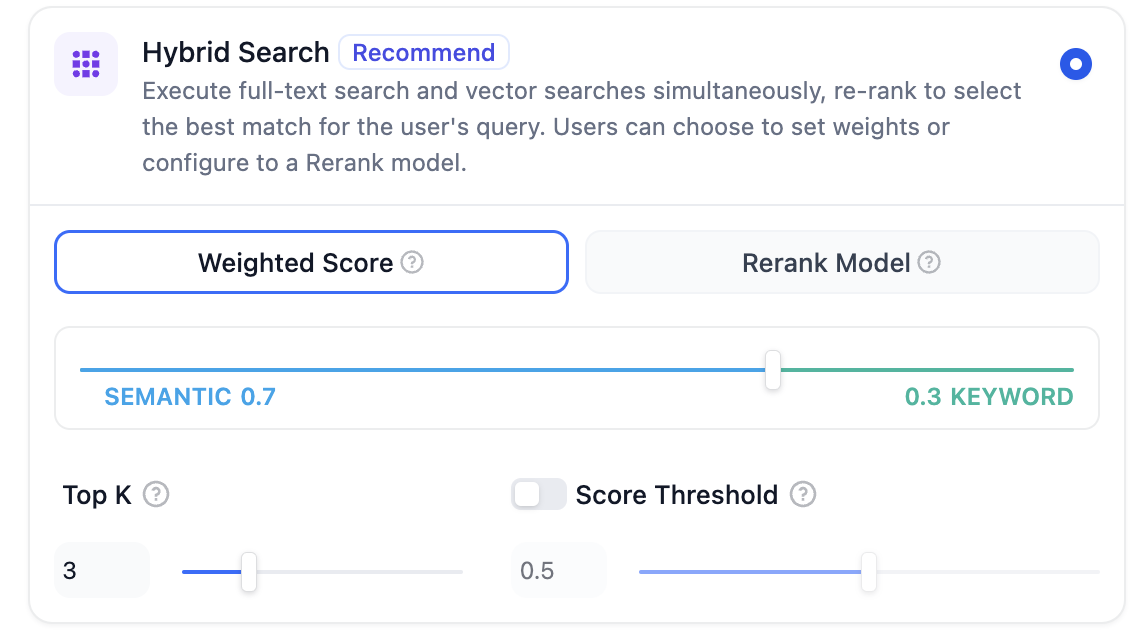
</Frame>
Clicking **Save and Process** will process the document. After processing, the document can be used in the application.
<Frame>
</Frame>
#### Sync from a Website
In many cases, we need to build a smart customer service bot based on help documentation. Taking Dify as an example, we can convert the [Dify help documentation](https://docs.dify.ai) into a knowledge base.
Currently, Dify supports processing up to 50 pages. Please pay attention to the quantity limit. If exceeded, you can create a new knowledge base.
<Frame>
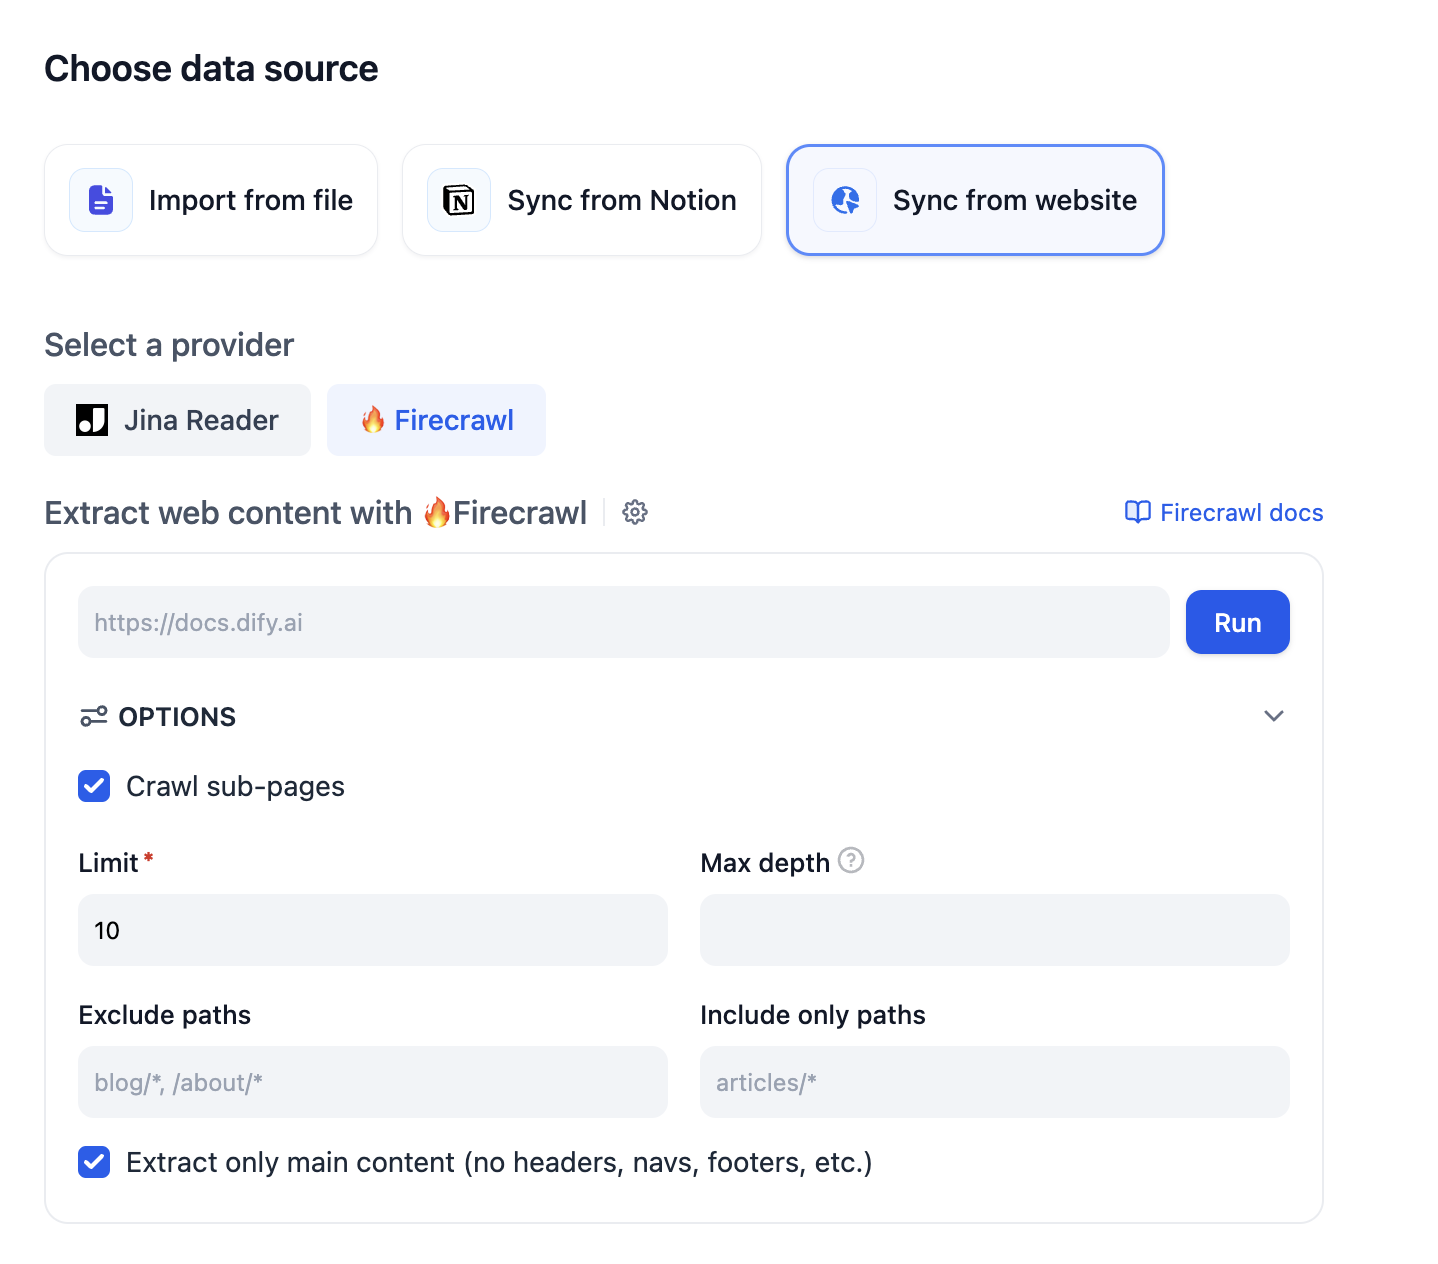
</Frame>
#### Adjust Knowledge Base Content
After the knowledge base has processed all documents, it is best to check the coherence of the segmentation in the knowledge base. Incoherence will affect the retrieval effect and needs to be manually adjusted.
Click on the document content to browse the segmented content. If there is irrelevant content, you can disable or delete it.
If content is segmented into another paragraph, it also needs to be adjusted back.
#### Recall Test
In the document page of the knowledge base, click **Retrieval Testing** in the left sidebar to input keywords to test the accuracy of the retrieval results.
### Add Nodes
Enter the created app, and let's start building the smart customer service bot.
#### Question Classification Node
You need to use a Question Classifier node to separate different user needs. In some cases, users may even chat about irrelevant topics, so you need to set a classification for this as well.
To make the classification more accurate, you need to choose a better LLM, and the classification needs to be specific enough with sufficient distinction.
Here is a reference classification:
* User asks irrelevant questions
* User asks Dify-related questions
* User requests explanation of technical terms
* User asks about joining the community
<Frame>
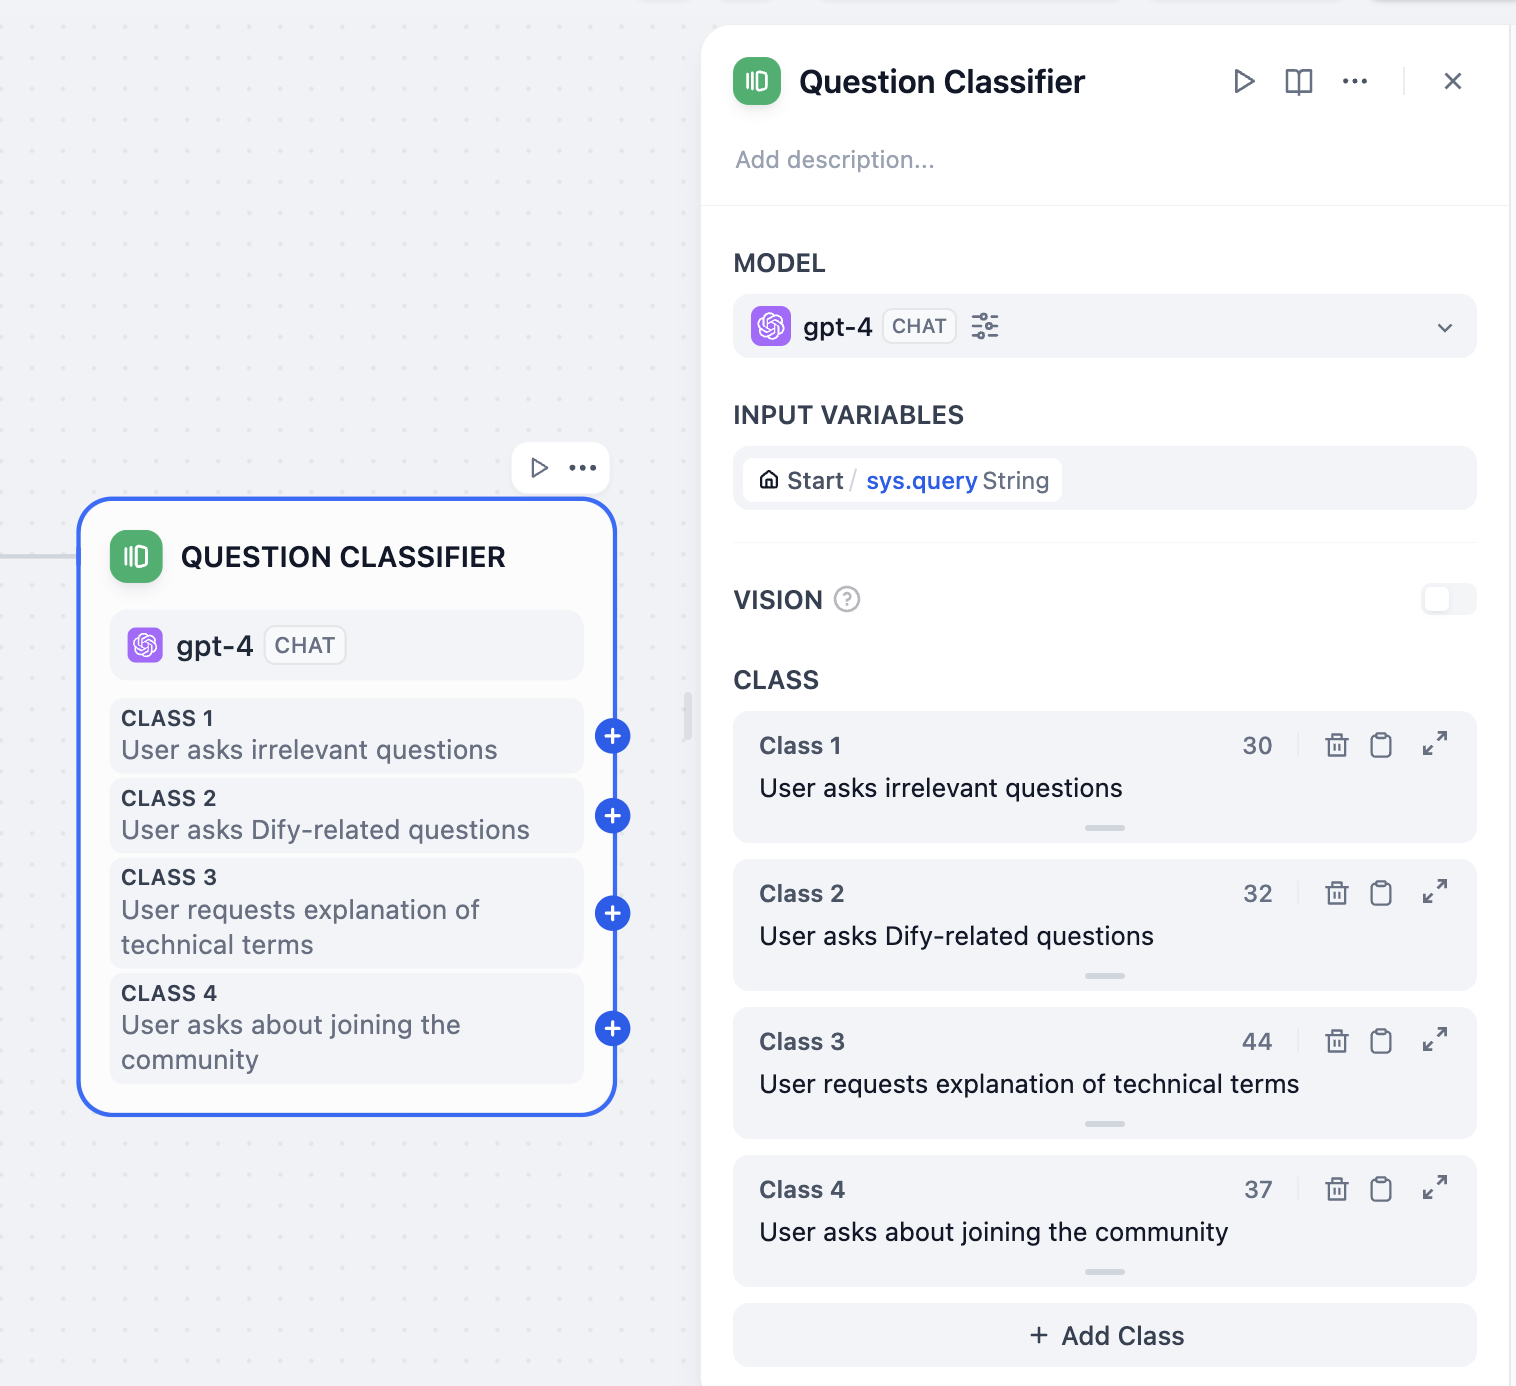
</Frame>
#### Direct Reply Node
In the question classification, "User asks irrelevant questions" and "User asks about joining the community" do not need LLM processing to reply. Therefore, you can directly connect an Answer node after these two questions.
For "User asks irrelevant questions", you can guide the user to the help documentation, allowing them to try to solve the problem themselves, for example:
```text theme={null}
I'm sorry, I can't answer your question. If you need more help, please check the [help documentation](https://docs.dify.ai).
```
Dify supports Markdown formatted text output. You can use Markdown to enrich the text format in the output. You can even insert images in the text using Markdown.
#### Knowledge Retrieval Node
Add a Knowledge Retrieval node after "User asks Dify-related questions" and check the knowledge base to be used.
#### LLM Node
In the next node after the Knowledge Retrieval node, you need to select an LLM node to organize the content retrieved from the knowledge base.
The LLM needs to adjust the reply based on the user's question to make the reply more appropriate.
Context: You need to use the output of the Knowledge Retrieval node as the context of the LLM node.
System prompt: Based on `{{context}}`, answer `{{user question}}`.
<Frame>
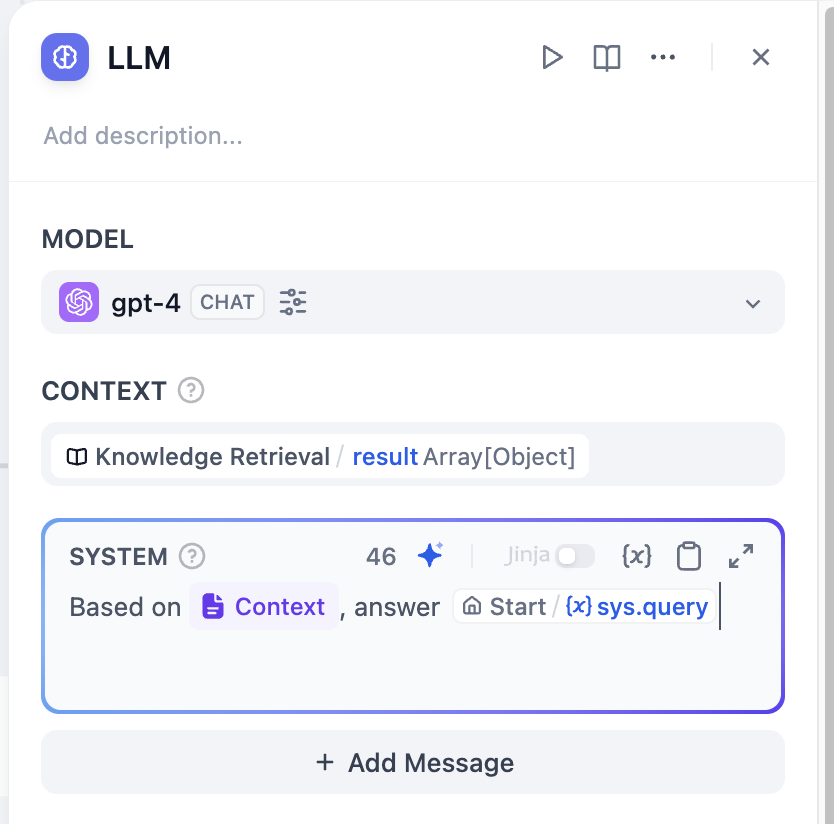
</Frame>
You can use `/` or `{` to reference variables in the prompt writing area. Variables starting with `sys.` are system variables.
In addition, you can enable LLM memory to make the user's conversation experience more coherent.
### Question 1: How to Connect External Knowledge Bases
In the knowledge base function, you can connect external knowledge bases through external knowledge base APIs, such as the AWS Bedrock knowledge base.
<Frame>
</Frame>
### Question 2: How to Manage Knowledge Bases Through APIs
You can add, delete, and query the status of knowledge bases through the knowledge base API.
<Frame>
</Frame>
In the knowledge base detail page, go to **API Access** and create an API key. Please keep the API key safe.
### Question 3: How to Embed the Customer Service Bot into a Webpage
After publishing the application, open its **Access Point** tab and select **Embed Into Site** on the **Web App** card. Choose a suitable embedding method, and paste the code into the appropriate location on the webpage.
# Simple Chatbot
Source: https://docs.dify.ai/en/learn/tutorials/simple-chatbot
Hello World
The real value of Dify lies in how easily you can build, deploy, and scale an idea no matter how complex. It's built for fast prototyping, smooth iteration, and reliable deployment at any level.
Let's start by learning reliable LLM integration into your applications. In this guide, you'll build a simple chatbot that classifies the user's question, respond directly using the LLM, and enhance the response with a country-specific fun fact.
<iframe title="Dify Quick Start Video" />
## Step 1: Create a New Workflow (2 min)
1. Go to **Studio** > **Workflow** > **Create from Blank** > **Orchestrate** > **New Chatflow** > **Create**
## Step 2: Add Workflow Nodes (6 min)
<Tip>
When you want to reference any variable, type `{` or `/` first and you can see the different variables available in your workflow.
</Tip>
### 1. LLM Node and Output: Understand and Answer the Question
<Info>
`LLM` node sends a prompt to a language model to generate a response based on user input. It abstracts away the complexity of API calls, rate limits, and infrastructure, so you can just focus on designing logic.
</Info>
<Steps>
<Step title="Create LLM Node">
Create an LLM node using the `Add Node` button and connect it to your Start node
</Step>
<Step title="Configure Model">
Choose a default model
</Step>
<Step title="Set System Prompt">
Paste this into the System Prompt field:
```text theme={null}
The user will ask a question about a country. The question is {{sys.query}}
Tasks:
1. Identify the country mentioned.
2. Rephrase the question clearly.
3. Answer the question using general knowledge.
Respond in the following JSON format:
{
"country": "<country name>",
"question": "<rephrased question>",
"answer": "<direct answer to the question>"
}
```
</Step>
<Step title="Enable Structured Output">
**Enable Structured Output** allows you to easily control what the LLM will return and ensure consistent, machine-readable outputs for downstream use in precise data extraction or conditional logic.
* Toggle Output Variables Structured ON > `Configure` and click `Import from JSON`
* Paste:
```json theme={null}
{
"country": "string",
"question": "string",
"answer": "string"
}
```
</Step>
</Steps>
### 2. Code Block: Get Fun Fact
<Info>
`Code` node executes custom logic using code. It lets you inject code exactly where needed—within a visual workflow—saving you from wiring up an entire backend.
</Info>
<Steps>
<Step title="Create Code Node">
Create a `Code` Node using the `Add Node` button and connect to LLM block
</Step>
<Step title="Configure Input Variable">
Change one `Input Variable` name to "country" and set the variable to `structured_output` > `country`
</Step>
<Step title="Add Python Code">
Paste this code into `PYTHON3`:
```python theme={null}
def main(country: str) -> dict:
country_name = country.lower()
fun_facts = {
"japan": "Japan has more than 5 million vending machines.",
"france": "France is the most visited country in the world.",
"italy": "Italy has more UNESCO World Heritage sites than any other country."
}
fun_fact = fun_facts.get(country_name, f"No fun fact available for {country.title()}.")
return {"fun_fact": fun_fact}
```
</Step>
<Step title="Rename Output Variable">
Change output variable `result` to `fun_fact` to have a better labeled variable
</Step>
</Steps>
### 3. Answer Node: Final Answer to User
<Info>
`Answer` Node creates a clean final output to return.
</Info>
<Steps>
<Step title="Create Answer Node">
Create an `Answer` Node using the `Add Node` button
</Step>
<Step title="Configure Answer Field">
Paste into the Answer Field:
```text theme={null}
Q: {{ structured_output.question }}
A: {{ structured_output.answer }}
Fun Fact: {{ fun_fact }}
```
</Step>
</Steps>
End Workflow:
<Frame>
<img alt="Complete workflow diagram showing LLM, Code, and Answer nodes connected" />
</Frame>
***
## Step 3: Test the Bot (3 min)
Click `Preview`, then ask:
* "What is the capital of France?"
* "Tell me about Japanese cuisine"
* "Describe the culture in Italy"
* Any other questions
Make sure your Bot works as expected!
## You've Completed the Bot!
This guide showed how to integrate language models reliably and scalably without reinventing infrastructure. With Dify's visual workflows and modular nodes, you're not just building faster, you're adopting a clean, production-ready architecture for LLM-powered apps.
# Twitter Account Analyzer
Source: https://docs.dify.ai/en/learn/tutorials/twitter-chatflow
Build a Chatflow that scrapes a Twitter profile via Crawlbase and analyzes the user's tweets with an LLM
## Introduction
In Dify, you can use some crawler tools, such as Jina, which can convert web pages into markdown format that LLMs can read.
Recently, [wordware.ai](https://www.wordware.ai/) has brought to our attention that we can use crawlers to scrape social media for LLM analysis, creating more interesting applications.
However, knowing that X (formerly Twitter) stopped providing free API access on February 2, 2023, and has since upgraded its anti-crawling measures. Tools like Jina are unable to access X's content directly.
> Starting February 9, we will no longer support free access to the Twitter API, both v2 and v1.1. A paid basic tier will be available instead 🧵
>
> — Developers (@XDevelopers) [February 2, 2023](https://twitter.com/XDevelopers/status/1621026986784337922?ref_src=twsrc%5Etfw)
Fortunately, Dify also has an HTTP tool, which allows us to call external crawling tools by sending HTTP requests. Let's get started!
## Prerequisites
### Register Crawlbase
Crawlbase is an all-in-one data crawling and scraping platform designed for businesses and developers. Crawlbase Scraper can pull data from social platforms like X, Facebook, and Instagram.
Register at [crawlbase.com](https://crawlbase.com).
### Sign in to Dify
Open Dify in your browser and sign in. You'll need access to a running Dify instance to follow along.
### Configure LLM Providers
Go to **Integrations** > **Model Provider**, install at least one model provider (for example, OpenAI), and configure its credentials.
<Frame>
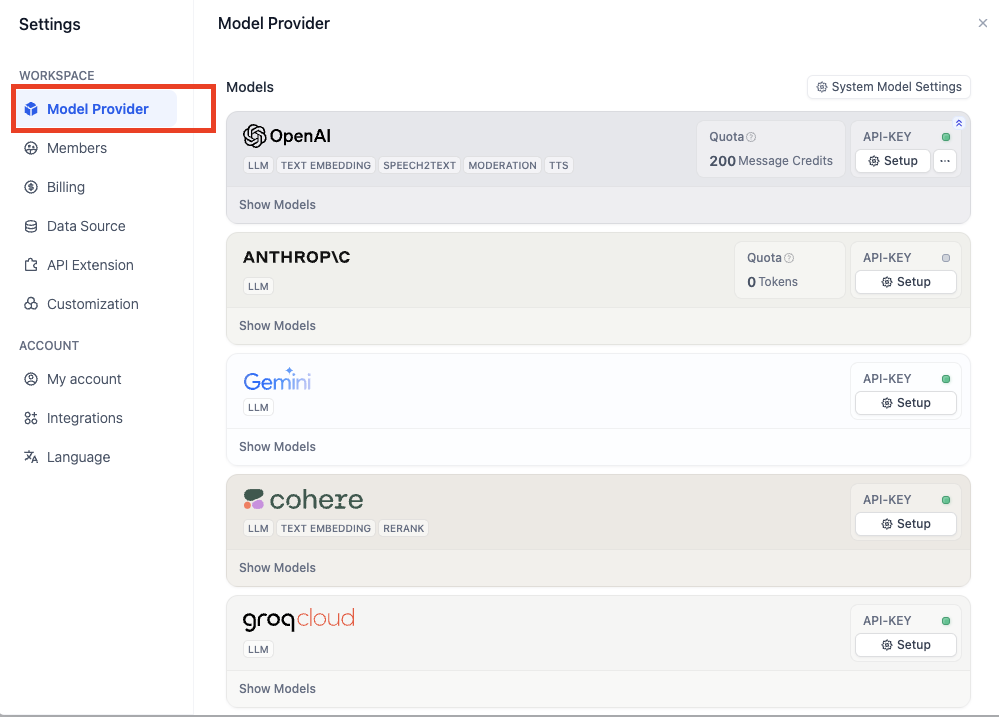
</Frame>
## Create a Chatflow
Now, let's get started on the Chatflow.
Click on `Create from Blank` to start:
<Frame>
</Frame>
The initialized Chatflow should be like:
<Frame>
</Frame>
## Add nodes to Chatflow
<Frame>

</Frame>
### Start node
In start node, we can add some system variables at the beginning of a chat. In this article, we need a Twitter user's ID as a string variable. Let's name it `id`.
Click on Start node and add a new variable:
<Frame>
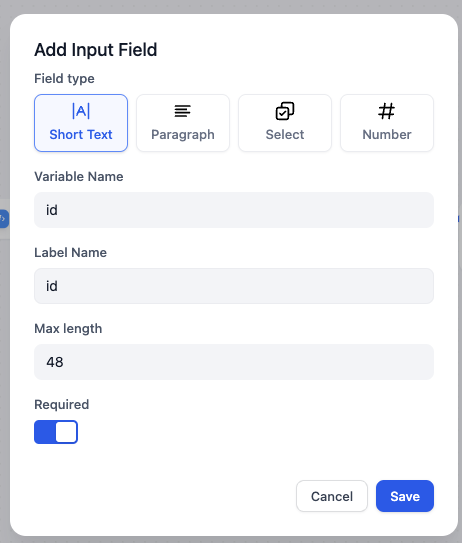
</Frame>
### Code node
According to [Crawlbase docs](https://crawlbase.com/docs/crawling-api/scrapers/#twitter-profile), the variable `url` (this will be used in the following node) should be `https://twitter.com/` + `user id`, such as `https://twitter.com/elonmusk` for Elon Musk.
To convert the user ID into a complete URL, we can use the following Python code to integrate the prefix `https://twitter.com/` with the user ID:
```python theme={null}
def main(id: str) -> dict:
return {
"url": "https://twitter.com/"+id,
}
```
Add a code node and select python, and set input and output variable names:
<Frame>

</Frame>
### HTTP request node
Based on the [Crawlbase docs](https://crawlbase.com/docs/crawling-api/scrapers/#twitter-profile), to scrape a Twitter user's profile in http format, we need to complete HTTP request node in the following format:
<Frame>
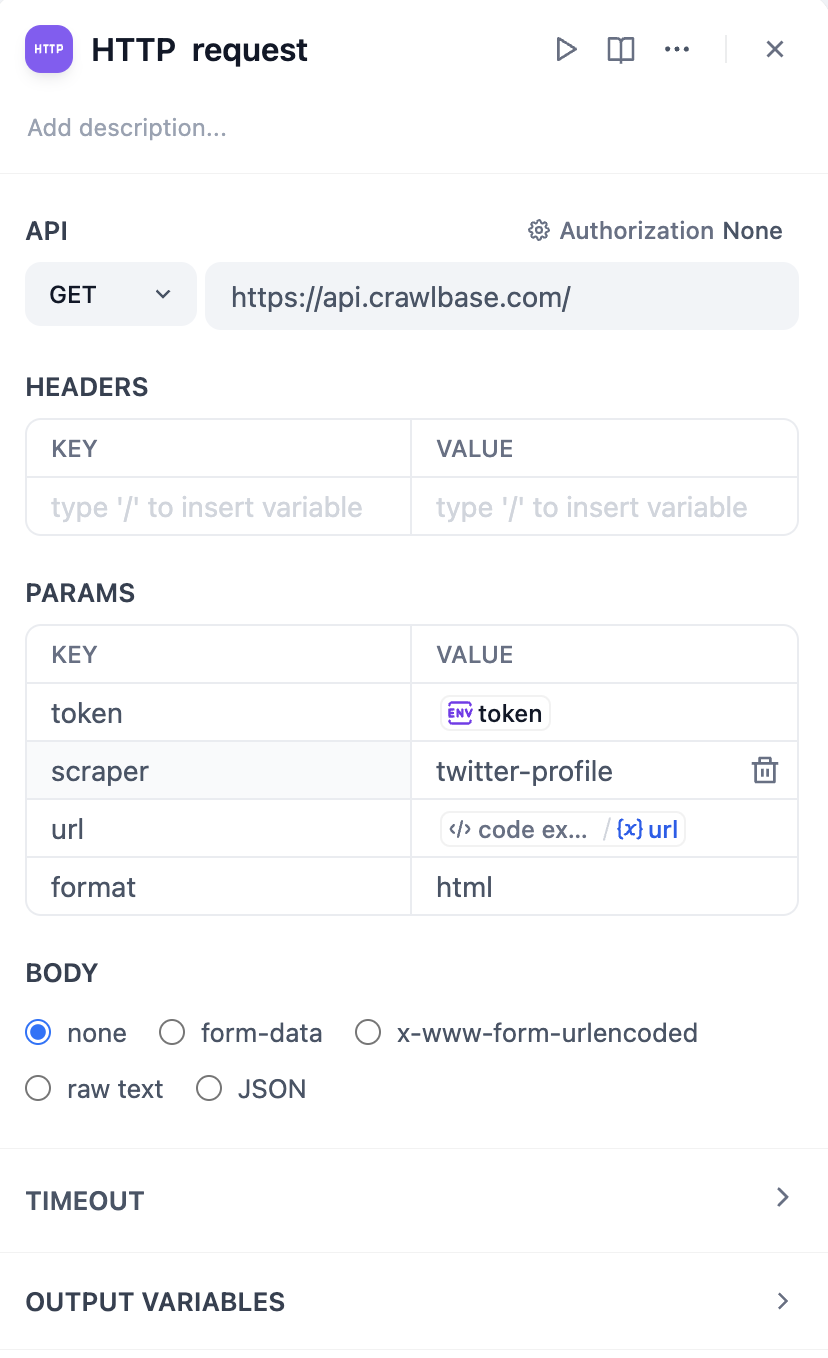
</Frame>
Importantly, it is best not to directly enter the token value as plain text for security reasons, as this is not a good practice. Actually, in the latest version of Dify, we can set token values in **`Environment Variables`**. Click `env` - `Add Variable` to set the token value, so plain text will not appear in the node.
Check [https://crawlbase.com/dashboard/account/docs](https://crawlbase.com/dashboard/account/docs) for your crawlbase API Key.
<Frame>

</Frame>
By typing `/`, you can easily insert the API Key as a variable.
<Frame>
</Frame>
Tap the start button of this node to check whether it works correctly:
<Frame>
</Frame>
### LLM node
Now, we can use LLM to analyze the result scraped by crawlbase and execute our command.
The value `context` should be `body` from HTTP Request node.
The following is a sample system prompt.
<Frame>

</Frame>
## Test run
Click `Preview` to start a test run and input twitter user id in `id`.
<Frame>

</Frame>
For example, I want to analyze Elon Musk's tweets and write a tweet about global warming in his tone.
<Frame>
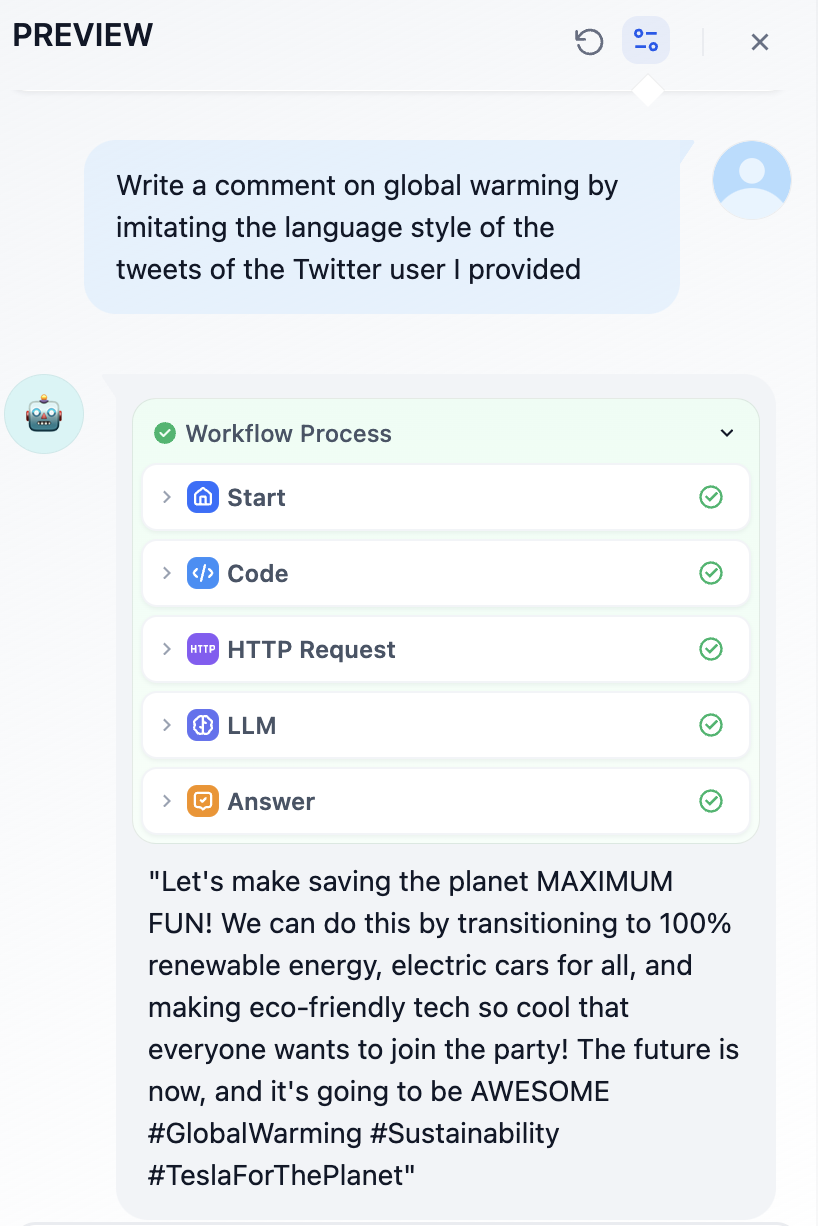
</Frame>
Does this sound like Elon? lol
Click `Publish` in the upper right corner and add it in your website.
Have fun!
## Lastly...
### Other X(Twitter) Crawlers
In this article, I've introduced crawlbase. It should be the cheapest Twitter crawler service available, but sometimes it cannot correctly scrape the content of user tweets.
The Twitter crawler service used by [wordware.ai](https://www.wordware.ai/) mentioned earlier is **Tweet Scraper V2**, but the subscription for the hosted platform **apify** is \$49 per month.
## Links
* [X@dify\_ai](https://x.com/dify_ai)
* Dify's repo on GitHub: [https://github.com/langgenius/dify](https://github.com/langgenius/dify)
# Lesson 3: The Brain of the Workflow (LLM Node)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-03
<Frame>
<img alt="LLM Node" />
</Frame>
In Lesson 2, we set up the Ingredients (Start Node) and the Serving Plate (Output Node).
If the Start Node is the prep cook, the LLM Node is the Master Chef. It is the brain and core of your workflow.
It handles all the thinking, analyzing, and creative writing. Whether you want to summarize an article, write code, or draft an email, this is the node that does the heavy lifting.
## Configure the Model
Before getting started, we need to connect to a model provider.
<Steps>
<Step title="Open Integrations">
Go to **Integrations** > **Model Provider**.
<Frame>
<img alt="Model Provider" />
</Frame>
</Step>
<Step title="Install OpenAI Provider">
Find OpenAI, and click **Install**.
<Frame>
<img alt="Choose OpenAI" />
</Frame>
<Frame>
<img alt="Install OpenAI" />
</Frame>
</Step>
<Step title="Return to the Canvas">
Once installed, you are ready to go! Click **ESC** (or the **X**) in the upper right corner to return to your canvas.
</Step>
</Steps>
## Understand the Tags
A pastry chef is great at cakes but terrible at sushi. Similarly, different AI models have different strengths.
When selecting a model in Dify, you will see tags next to their names. Here's how to read them so you can pick the right one for you.
<AccordionGroup>
<Accordion title="CHAT (The Conversationalist)">
This is the bread and butter of AI. It's best for:
* Dialogue
* Writing articles
* Summarizing text
* Answering questions
</Accordion>
<Accordion title="128K (The Great Memory)">
This number represents the **Context Window**. You can think of it as short-term memory.
Here, K stands for thousand. **128K** means the model can hold 128,000 tokens (roughly equals to a word or a syllable). The bigger the number is, the better its memory is.
<Info>
If you need to analyze a massive PDF report or a whole book, you need a model with a big number here.
</Info>
</Accordion>
<Accordion title="Multi-modal (The Evolved Senses)">
Modal just means **Type of Information**. Most early AI models could only read text. Multi-modal models are evolved—they have senses like eyes and ears.
**VISION (The Eyes)**
Models with this tag can do more than read; they can see! You can upload a photo of a sunset and ask, What colors are in this? or upload a picture of your fridge ingredients and ask, What can I cook with this?
**AUDIO (The Ears)**
Models with this tag can hear. You can upload an audio recording of a meeting or a lecture, and the model can transcribe it into text or write a summary for you.
**VIDEO (The Movie Analyst)**
These models can watch and understand video content. They can analyze what is happening in a video clip, just like a human watching a movie.
**DOCUMENT (The Reader)**
These models are expert readers. Instead of copying and pasting text, you can just upload a file (like a PDF or Word document). The model will read the file directly and answer questions based on what is written inside.
</Accordion>
</AccordionGroup>
For our Email Assistant, the LLM with the **CHAT** tag is exactly what we need.
## Hands-On 1: Add the LLM Node
Let's put the brain into our workflow.
<Steps>
<Step title="Open your App">
Go back to the **AI Email Assistant** workflow we created in Lesson 2.
</Step>
<Step title="Add the Node">
Right-click in the empty space between Start and Output node. Click on the new **LLM** block. In the right-side panel, look for **Model**. Select **gpt-4o-mini**.
<Frame>
<img alt="Add the Node" />
</Frame>
</Step>
<Step title="Connect the Nodes">
Drag a line from the Start node to the LLM node. Drag a line from the LLM node to the Output node. Your flow should look like this: **Start → LLM → Output**.
<Frame>
<img alt="Connect the Nodes" />
</Frame>
</Step>
</Steps>
Now we need to tell LLM exactly what to do by sending instructions which is called a **Prompt**.
<Frame>
<img alt="Add Prompt" />
</Frame>
### Key Concept: The Prompt (The Instructions)
**What is a Prompt?** Think of the Prompt as the specific note you attach to the order ticket. It tells the AI exactly **what to do** and **how to do it**.
The most critical part is the ability to use **Variables** from the Start Node directly within your Prompt. This allows the AI to adapt its output based on the different raw materials you provide each time.
In Dify, when you insert a variable like `customer_name` into the prompt, you are telling the AI: Go and look in the box labeled Customer Name and use the text inside.
## Hands-On 2: Write the Prompt
Now, let's apply this. We are going to write a prompt that mixes instructions with our variables.
<Steps>
<Step title="Draft the Instructions">
Click the LLM Node to open the panel and find the **system** box. **System instructions** set the rules for how the model should respond—its role, tone, and behavioral guidelines.
Let's start by writing out the instructions. You can copy and paste the text below.
```plaintext wrap theme={null}
You are a professional customer service manager. Based on the customer's email, please draft a professional reply.
Requirements:
1. Start by addressing the customer name with a friendly tone.
2. Thank them for their email.
3. Let them know we have received it.
4. Sign off as Anne.
```
</Step>
<Step title="Add User Messages">
User messages are what you send to the model—a question, request, or task for the model to work on.
In this workflow, the customer's name and the email content change every single time. Instead of typing them out manually, we add Variables in user messages.
1. Click **Add Message** button below system box.
2. In the User Message box, type **customer name**:.
3. Press `/` on your keyboard.
4. The Variable Selection menu pops out, and click `customer_name`.
5. Press Enter to start a new line, and type **email content:.** Then, Press the / key again and click on `email_content`.
<Frame>
<img alt="Add User Message" />
</Frame>
<Tip>
You don't need to type out those curly brackets manually! Just hit `/`, then pick your variable from the menu.
</Tip>
4. Finally, your final Prompt will look like this:
<Frame>
<img alt="Final Prompt" />
</Frame>
</Step>
</Steps>
<Check>
**Hooray!** You've finished your first AI workflow in Dify!
</Check>
## Run and Test
The ingredients are prepared, the chef is stand-by, and the instructions are ready. But does the dish taste good? Before we serve it to the customer, let's do a recipe testing.
Testing is the secret sauce to a stable workflow. It helps us catch those sneaky little issues before they are put into work.
### Quick Concept: The Checklist
Think of the **Checklist** as your workflow's personal Health Check Doctor.
It monitors your work in real-time, automatically spotting incomplete settings or mistakes (like a node that isn't connected to anything).
Glancing at the Checklist before you hit **Publish** button is the best way to catch unnecessary errors early.
### Hands-On 3: Test & Debug
<Steps>
<Step title="The Pre-flight Check">
Look at the top right corner of your canvas. Do you see the **Checklist** icon with a little number **1** on it? This is Dify telling you: Wait a second! There's one small thing missing here\_.\_
<Frame>
<img alt="Checklist" />
</Frame>
</Step>
<Step title="Analyze the Warning">
Click on it, and you will see a warning: **output variable is required**. It means that the output node receives nothing.
Imagine your Head Chef (the LLM) has finished cooking the food, but the Waiter (the Output Node) has empty hands.
</Step>
<Step title="Fix the Issue">
1. Click on the **Output Node**
2. Look for **Output Variable** and click the **Plus (+)** icon next to it
3. Type `email_reply` in the **Variable Name** field
4. Select the value: Click the variable selector and choose `{x} text` from the LLM Node
<Frame>
<img alt="Fix the Issue" />
</Frame>
</Step>
<Step title="Make a Test Run">
Now, there's no pop-up number on checklist. Let's do a test run.
Click **Test Run** at the top right corner of the canvas. Enter the customer's name and the email, then click **Start Run**.
<Frame>
<img alt="Test Run" />
</Frame>
<CodeGroup>
```text Sample Email for Testing theme={null}
Customer Name: Amanda
Original Email:
Hi there,
I'm writing to ask for more information about Dify. Could you please tell me more on it?
Best regards,
Amanda
```
</CodeGroup>
</Step>
<Step title="Success!">
This time, you will see green checkmarks ✅ on each of the nodes and the generated reply from AI.
</Step>
</Steps>
<Check>
**Great job!**
You didn't just build a workflow, but also know how to use the checklist and check before it goes live.
</Check>
## Mini Challenge
Use the same structure to build a travel planner.
<Tip>
Explore the **Prompt Generator** to help you craft better prompts!
<Frame>
<img alt="Prompt Generator" />
</Frame>
</Tip>
# Lesson 4: The Cheat Sheet (Knowledge Retrieval)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-04
In the previous lessons, our AI email assistant can draft basic emails. But what if a customer asks about specific pricing plans or refund policy, the AI might start Hallucinating—which is a fancy way of saying it's confidently making things up.
How do we stop the AI from hallucination? We give it a Cheat Sheet.
## What is Retrieval Augmented Generation (RAG)
The technical name for this is RAG (Retrieval-Augmented Generation). Think of it as turning the AI from a chef who memorizes general recipes into a chef who has a Specific Cookbook right on the counter.
It happens in three simple steps:
**1. Retrieval (Find the Recipe)**
When a user asks a question, the AI flips through your Cookbook (the files you uploaded) to find the most relevant pages.
Example: Someone asks for Grandma's Special Apple Pie. You go find that specific recipe page.
**2. Augmentation (Prepare the Ingredients)**
The AI takes that specific recipe and puts it right in front of its eyes so it doesn't have to rely on memory.
Example: You lay the recipe on the counter and get the exact apples and cinnamon ready.
**3. Generation (The Baking)**
The AI writes the answer based only on the facts it just found.
Example: You bake the pie exactly as the recipe says, ensuring it tastes like Grandma's, not a generic store-bought version.
## The Knowledge Retrieval Node
Think of this as placing a stack of reference materials right next to your AI Assistant. When a user asks a question, the AI first flips through this Cheat Sheet to find the most relevant pages. Then, it combines those findings with the user's original question to think of the best answer.
In this practice, we will use the Knowledge Retrieval node to provide our AI Assistant with official Cheat Sheets, ensuring its answers are always backed by facts!
### Hands-On 1: Create the Knowledge Base
<Steps>
<Step title="Enter the Library">
Click **Knowledge** in the top navigation bar and click **Create Knowledge**.
<Frame>
<img alt="Create Knowledge" />
</Frame>
In Dify, you can sync from Notion or a website, but for today, let's upload a file from your device. Click [here](https://drive.google.com/file/d/1imExB0-rtwASbmKjg3zdu-FAqSSI7-7K/view) to download Dify Intro for the upload later.
</Step>
<Step title="Upload the File">
Click **Import from file**. Then, select the file we just downloaded for upload.
<Frame>
<img alt="Import from File" />
</Frame>
</Step>
<Step title="The 'Chopping' Step (Text Segmentation)">
High-relevance chunks are crucial for AI applications to provide precise and comprehensive responses. Imagine a long book. It's hard to find one sentence in 500 pages. Dify chops the book into different Knowledge Cards so it can find the right answer faster.
**Chunk Structure**
Here, Dify automatically splits your long text into smaller, easier-to-retrieve chunks. We'll just stick with the General Mode here.
<Frame>
<img alt="Chunk Structure" />
</Frame>
**Index Method**
* **High Quality**: Use LLM model to process documents for more precise retrieval helps LLM generate high-quality answers
* **Economical**: Using 10 keywords per chunk for retrieval, no tokens are consumed at the expense of reduced retrieval accuracy
<Frame>
<img alt="Index Method" />
</Frame>
</Step>
<Step title="Retrieval Settings">
After the document has been processed, we need to do one final check on the retrieval settings. Here, you can configure how Dify looks up the information.
In Economical mode, only the inverted index approach is available.
<Frame>
<img alt="Retrieval Setting" />
</Frame>
* **Inverted Index**
This is the default structure Dify uses. Think of it like the Index at the back of a book—it lists key terms and tells Dify exactly which pages they appear on.
This allows Dify to instantly jump to the right knowledge card based on keywords, rather than reading the whole book from start.
* **Top K**
You'll see a slider set to 3. This tells Dify: When the user asks a question, find the top 3 most relevant Knowledge Cards from the cookbook to show the AI.
If you set it higher, the AI gets more context to read, but if it's too high, it might get overwhelmed with too much information.
For now, let's just keep the default settings—they are already perfectly suited for our needs.
<Frame>
<img alt="Document Processing" />
</Frame>
</Step>
<Step title="Save and Process">
Click **Save and Process**. Your knowledge base is ready!
</Step>
</Steps>
<Check>
**Awesome!**
You have successfully created your first Knowledge Base. Next, we'll use this Knowledge Base to upgrade our AI Email Assistant.
</Check>
### Hands-On 2: Add the Knowledge Retrieval Node
<Steps>
<Step title="Add the Node">
1. Go back to your Email Assistant Workflow.
2. Hover over the line between the Start and LLM nodes.
3. Click the **Plus (+)** icon and select the **Knowledge Retrieval** node.
<Frame>
<img alt="Add Knowledge Retrieval Node" />
</Frame>
</Step>
<Step title="Connect Knowledge Base">
1. Click the node, and head to the right panel.
2. Click the **plus (+)** button next to **Knowledge** to add knowledge.
<Frame>
<img alt="Add Knowledge" />
</Frame>
3. Choose **What's Dify**, and click **Add**.
<Frame>
<img alt="Select Knowledge" />
</Frame>
</Step>
<Step title="Configure Query Text">
Now the knowledge base is ready, how can we make sure that AI is looking through the knowledge base to search the answer with the email?
Stay at the panel, navigate to **Query text** above, and select `email_content`.
By doing this, we are telling AI: Take the customer's message and use it as a search keyword to flip through our cookbook and find the matching info. Without a query, the AI is just staring at a closed book.
<Frame>
<img alt="Query Text" />
</Frame>
</Step>
</Steps>
In this way, the Email Assistant will use the customer's original email as a search keyword to find the most relevant answers in the Knowledge Base.
### Hands-On 3: Upgrade the Email Assistant
Now, the knowledge base is ready. We need to tell the LLM node to actually read the knowledge as context before generating the reply.
<Steps>
<Step title="Add Context">
1. Click the **LLM Node**. You'll see a new section called **Context**.
2. Click it and select **result** from the Knowledge Retrieval node.
<Frame>
<img alt="Add Context" />
</Frame>
</Step>
<Step title="Update the Prompt">
We need to tell the AI to generate reply based on the context.
In **System**, add additional requirement **Generate response based on** `/` and select **Context**.
<Frame>
<img alt="Update Prompt" />
</Frame>
</Step>
</Steps>
**Whoo!** You've just completed the most challenging part. Now, your email assistant has a knowledge base to check when generating responses. Let's see how it works.
Feel free to use the sample texts below to do the testing.
<CodeGroup>
```text Sample Email for Testing theme={null}
Customer Name: Amanda
Original Email:
Hi,
What does the name 'Dify' actually stand for, and what can it do for my business?
Best regards,
Amanda
```
</CodeGroup>
Check on the result and you'll find that instead of a generic guess, the AI will look at the knowledge base and explain what Dify stands for.
<Frame>
<img alt="Test Result" />
</Frame>
## Mini Challenge
1. What happens if a customer asks a question that isn't in the knowledge base?
2. What kind of information could you upload as a knowledge base?
3. Explore Chunk Structure, Index Method, and Retrieval Setting.
# Lesson 5: The Crossroads of Your Workflow (Sorting and Executing)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-05
Right now, our Email Assistant treats every message following the same path of the workflow. That's not smart enough. An email asking about Dify's price should be handled differently than an email on bug reporting.
To make our assistant truly intelligent, we need to teach it how to Read the Room. We're going to set up a Crossroads that sends different types of emails down different tracks.
## The If/Else Node
<Frame>
<img alt="If/Else Node" />
</Frame>
If/Else node is just like a traffic light. It checks a condition (like Does this email mention pricing? ) and sends the flow left or right based on the result.
### Hands-On 1: Set up the Crossroads
Let's upgrade our assistant so it can tell the difference between Dify-related emails and Everything else.
<Steps>
<Step title="Insert the Node">
Hover over the line between the Start and Knowledge Retrieval nodes. Click the **Plus (+)** icon and select the **If/Else** node.
</Step>
<Step title="Set the Rules">
1. Click the node to open the panel
2. Click **+ Add Condition** in the IF section. Choose the variable: `{x} email_content`
<Frame>
<img alt="Add Condition" />
</Frame>
3. The Logic: Keep it as **Contains**. Type **Dify** in the input box
<Frame>
<img alt="Contains" />
</Frame>
Now, the complete logic for the IF branch is: `If the email content contains the word Dify`.
</Step>
</Steps>
<Info>
**Understanding the Traffic Light**
When setting conditions, Dify offers several ways to judge information, much like the different signals at a crossroads:
* **Is / Is Not**
Like a perfect key for a lock. The content must match your value exactly.
* **Contains / Not Contains**
Like a magnifying glass. It checks if a specific keyword exists anywhere in the text. This is what we are using today.
* **Starts with / Ends with**
Check if the text begins or ends with specific characters.
* **Is Empty / Is Not Empty**
Check if the variable has any content. For example: Checking if a user actually uploaded an attachment. Understanding these helps you set accurate and flexible rules, building a much smarter workflow!
</Info>
### Hands-On 2: Plan Different Paths
Now that we have the crossroad here, we need to decide what happens on each road.
#### A. The Dify-Related Email Track (IF Branch)
Click the **plus (+)** icon on the right side of the IF branch, drag out a line, and connect it to **Knowledge Retrieval** node.
What this means: When the email contains the word Dify, the flow will execute the professional reply process we built in the last lesson (which looks up information in the Knowledge Base).
<Frame>
<img alt="Connect IF Branch" />
</Frame>
#### B. The Unrelated Email Track (ELSE Branch)
For emails that are not related or mention Dify, we want to create a simple, polite, and general reply process.
<Steps>
<Step title="Create a new Node">
Click the **(+)** next to ELSE and select a new **LLM Node (LLM 2)**
</Step>
<Step title="Add Prompt to this LLM node">
Copy and paste the prompt below
```plaintext wrap theme={null}
You are a professional customer service manager. Based on the customer's email, kindly inform the user that no relevant information was found and provide relevant guidance.
Requirements:
1. Address the customer name in a friendly tone.
2. Thank them for their letter.
3. Keep the tone professional and friendly.
4. Sign off as "Anne."
```
</Step>
<Step title="Add User Message">
1. Click **Add Message** button below system.
2. In the User Message box, type **customer name**:.
3. Press `/` on your keyboard.
4. You can see the Variable Selection menu pops out, and click `customer_name`.
5. Press Enter to start a new line, and type **email content**:
6. Press the / key again and click on `email_content`.
<Frame>
<img alt="Prompt for LLM 2" />
</Frame>
</Step>
</Steps>
Now we have two tracks generating two different replies. Imagine if we had 10 tracks, our workflow would look like a messy plate of spaghetti.
To keep things clean, we use a Variable Aggregator. Think of it as a Traffic Hub where all the different roads merge back into one main highway.
## Variable Aggregator
<Frame>
<img alt="Variable Aggregator" />
</Frame>
Variable Aggregator is like a traffic hub where all the different roads merge back into one main highway.
### Hands-On 3: Add Variable Aggregator
<Steps>
<Step title="Add the Aggregator">
1. Select the connection line between the End Node and the LLM node and delete it.
2. Right-click on the canvas, select **Add Node**, and choose the **Variable Aggregator** node.
<Frame>
<img alt="Add Variable Aggregator" />
</Frame>
</Step>
<Step title="Merge the Paths">
Connect LLM and LLM 2 node to the Variable Aggregator.
</Step>
<Step title="Assign the Output">
1. Click the Variable Aggregator node.
2. Click the **plus (+)** icon next to **Assign Variables**.
3. Select the **text** from LLM 1 AND the **text** from LLM 2.
<Frame>
<img alt="Assign Variable" />
</Frame>
Now, no matter which LLM node generates the response, the Variable Aggregator node gathers the content and hands it to the Output Node.
</Step>
<Step title="The Final Step">
1. Connect the Variable Aggregator to the Output node.
2. Update the Output Variable to the Variable Aggregator's result instead of previous LLM results.
<Frame>
<img alt="Update Output Variable" />
</Frame>
Here's how the workflow looks:
<Frame>
<img alt="Final Workflow" />
</Frame>
</Step>
<Step title="Test and Run">
Click **Test Run**, enter a customer name, and try testing with inputs that both include and exclude the keyword Dify to see the different results.
</Step>
</Steps>
## Mini Challenge
For business inquiry emails, how should we edit this workflow to generate proper response?
<Tip>
Don't forget to update knowledge base with business-related files.
</Tip>
# Lesson 6: Handle Multiple Tasks (Parameter Extraction & Iteration)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-06
Imagine you get an email saying:
> Hi! What exactly is Dify? Also, which models does it support? And do you have a free plan?
If we send this to our current AI assistant, it might only answer the first question or give a vague response to both.
We need a way to identify every question first, and then loop through our Knowledge Base to answer them one by one.
## Parameter Extractor
<Frame>
<img alt="Parameter Extractor" />
</Frame>
You can take Parameter Extractor as a highly organized scout. It reads a paragraph of texts (like an email) and picks out the specific piece of information you asked for, putting them into a neat and organized list.
### Hands-On 1: Add Parameter Extractor
Before we upgrade the email assistant, let's remove these nodes: Knowledge Retrieval, If/Else, LLM, LLM 2, and Variable Aggregator.
<Steps>
<Step title="Add the Node">
Right after the Start node, add the **Parameter Extractor** node.
<Frame>
<img alt="Add Parameter Extractor" />
</Frame>
</Step>
<Step title="Set the Input">
Click Parameter Extractor, and in the **Input Variable** section on the right panel, choose `email_content`.
<Frame>
<img alt="Set the Input" />
</Frame>
Since AI doesn't automatically know which specific information we need from the email, we must tell it to collect all the questions.
</Step>
<Step title="Add Extract Parameter">
Click the **plus (+)** icon next to **Extract Parameters** to start defining what the AI should look for. Let's call it `question_list`.
<Frame>
<img alt="Add Extract Parameter" />
</Frame>
<Info>
**Parameter Types**
If Parameter Extractor is a scout, then Type is the bucket they use to carry the info. You need the right bucket for the right information.
**Single Items (The Small Buckets)**
* **String (Text)**: For a single piece of text, e.g. customer's name
* **Number**: For a single digit, e.g. order quantity
* **Boolean**: A simple Yes or No (True/False), good for a judgement result or a decision
**List Items (The Arrays)**
* **Array\[String]**: Array means List, and String means Text. So, `Array[String]` means we are using a basket that can hold multiple pieces of text—like all the separate questions in an email
* **Array\[Number]**: A container that holds different numbers, e.g. a list of prices or commodities
* **Array\[Boolean]**: Used to store multiple Yes/No judgment results. For example, checking a list containing multiple to-do items and returning whether each item is completed, such as `[Yes, No, Yes]`
* **Array\[Object]**: An advanced folder that holds sets of data (like a contact list where each entry has a Name and a Phone Number)
</Info>
</Step>
<Step title="Finish Adding Extract Parameter">
1. Based on our needs, choose `Array[String]` for the email content.
2. Add description for providing additional context. You can write: All the questions raised by the user in the email. After that, click **Add**.
<Frame>
<img alt="Finish Adding Extract Parameter" />
</Frame>
</Step>
<Step title="Add Instructions">
In the **Instructions** box below the extracted parameters, type a clear command to tell the AI how to act.
For example: Extract all questions from the email, and make each question as a single item on the list.
</Step>
</Steps>
By doing this, the node will be able to find all the questions in the email. Now that our scout has successfully gathered the Golden Nuggets, we need to move to the next step: teaching the AI to process each question.
## Iteration
<Frame>
<img alt="Iteration" />
</Frame>
With iteration, your assistant has a team of identical twins. When you hand over a list (like questions in the mail list), a twin appears for every single item on that list.
Each twin takes their assigned item and performs the exact same task you've set up, ensuring nothing gets missed.
### Hands-On 2: Set up Iteration Node
<Steps>
<Step title="Add the Node">
1. Add an Iteration node after the Parameter Extractor.
2. Click on the Iteration node and navigate to the Input panel on the right.
3. Select `{x} question_list` from the Parameter Extractor. Leave the output variable blank for now.
<Frame>
<img alt="Add Iteration Node" />
</Frame>
**Advanced Options in Iteration**
In the Iteration panel, you'll see more settings. Let's have a quick walk-through.
<Frame>
<img alt="Advanced Options in Iteration" />
</Frame>
**Parallel Mode**: OFF (Default)
* When disabled, the workflow processes each item in the list one after another (finish Question 1, then move to Question 2).
* When enabled, the workflow attempts to process all items in the list simultaneously (similar to 5 chefs cooking 5 different dishes at the same time).
**Error Response Method**: Terminate on error by default.
* **Terminate**: This means if any single item in the list (e.g., the 2nd question) fails during the sub-process, the entire workflow will stop immediately
* **Ignore Error and Continue**: This means even if the 2nd question fails, the workflow will skip it and move on to process the remaining questions
* **Remove Abnormal Output**: Similar to ignore, but it also removes that specific failed item from the final output list results
Back to the workflow, you'll see a sub-process area under the Iteration node. Every node inside this box will run once for every question.
</Step>
<Step title="Add Knowledge Retrieval Node">
1. Inside the Iteration box, add a Knowledge Retrieval node.
2. Set the query text to `{x} item`. In Iteration, item always refers to the question that is currently being processed.
<Frame>
<img alt="Add Knowledge Retrieval Node and Set Query Text" />
</Frame>
</Step>
<Step title="Add LLM Node">
1. Add an LLM node after Knowledge Retrieval.
2. Configure it to answer the question based on the retrieved context.
<Tip>
Remember Lesson 4? Use those Prompt skills and don't forget context!
</Tip>
Feel free to use the prompt below:
**System**:
```plaintext wrap theme={null}
You are a professional Dify Customer Service Manager. Please provide a response to questions strictly based on the `Context`.
```
**User**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="Add LLM Prompt" />
</Frame>
Since the iteration node generates an answer for each individual question, we need to gather all these answers to create one complete reply email.
</Step>
<Step title="Set Iteration Output">
1. Click the Iteration node.
2. In the **Output Variable**, select the variable representing the LLM's answer inside the loop. Now, the Iteration node will collect every answer and gather them into a new list.
<Frame>
<img alt="Set Iteration Output" />
</Frame>
</Step>
<Step title="Add Final LLM Node">
Finally, connect one last LLM node. This final editor will take all the collected answers and polish them into one professional email.
Don't forget to add prompt in system and user message. Feel free to refer the prompt below.
```plaintext wrap theme={null}
You are a professional customer service assistant. Please organize the answers prepared for customer into a clear and complete email reply.
Sign the email as Anne.
```
**User**:
```plaintext wrap theme={null}
answers: Iteration/{x}output
customer: User Input/{x}customer_name
```
<Frame>
<img alt="Add Final LLM Node" />
</Frame>
</Step>
<Step title="Final Check">
1. Click on the checklist to see if there's any missing spot. According to the notes, we need to connect Output node while fix the invalid variable issue.
2. Connect Output node with LLM 2 node before it, remove its previous variable, then select text in LLM 2 as the output variable.
<Frame>
<img alt="Select Output Variable" />
</Frame>
</Step>
</Steps>
Now, you can write a test email with 3 different questions and check on the generated reply.
## Mini Challenge
What else could Parameter Extractor find?
<Tip>
Try exploring the parameter type in it.
</Tip>
# Lesson 7: Enhance Workflows (Tools)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-07
Our email assistant can now flip through our knowledge base. But what if a customer asks a beyond-knowledge-base question, like: What is in the latest Dify release?
If the knowledge base hasn't been updated yet, the workflow will be at a loss. To fix this, we need to equip it with a Live Search skill!
## Tools
<Frame>
<img alt="Tools" />
</Frame>
Tools are the superpower for your AI workflow.
The [Dify Marketplace](https://marketplace.dify.ai/) is like a supermarket of ready-made tools—searching Google, checking the weather, drawing images, or calculating complex math. You just install and plug them into your workflow with several clicks.
Now, let's continue to upgrade on current workflow.
### Hands-On 1: Upgrade the Sub-process Area in Iteration
We are going to add a new logic to our assistant: Check the Knowledge Base first; if the answer isn't there, go search Google.
To focus on the new logic, let's keep only these nodes: **User input, Parameter Extractor, and Iteration**.
#### Step 1: Knowledge Query and the Judge
<Steps>
<Step title="Enter the Iteration">
1. Click to enter the sub-process area of the Iteration node.
2. Keep Knowledge Retrieval node, and make sure the query variable is `{x} item`.
3. Delete the previous LLM node.
</Step>
<Step title="Add the Judge (LLM Node)">
Add an LLM node right after Knowledge Retrieval node. Its job is to decide if the Knowledge Base info can actually respond to the questions.
* **For Context session**: Select the `Knowledge Retrieval / {x} result Array [Object]` from Knowledge Retrieval
* **System Prompt**:
```plaintext wrap theme={null}
Based on the `Context`, determine if the answer contains enough information to answer the questions. If the information is insufficient, you MUST reply with: "Information not found in knowledge base".
```
* **User Message**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="LLM Settings" />
</Frame>
</Step>
</Steps>
Here's what it looks like on the canvas.
<Frame>
<img alt="Workflow Preview" />
</Frame>
#### Step 2: Setting the Crossroads
<Steps>
<Step title="Add If/Else Node">
After LLM node, let's add If/Else node. Set the rule: If LLM Output **Contains** **Information not found in knowledge base**.
This means, when we can't respond with the information in knowledge base.
<Frame>
<img alt="Add if/Else Node" />
</Frame>
</Step>
<Step title="Add Tool for Searching">
Let's connect a search tool after the IF branch. This indicates that when the knowledge base cannot find relevant answer information, we use web search to find the answers.
1. After the IF node, click plus(+) icon and select Tool.
2. In the search box, type Google. Hover over Google, click Install on the right, and then click Install again in the pop-up window.
<Frame>
<img alt="Install Tool" />
</Frame>
</Step>
<Step title="Install Google Search">
Click Google Search in Google.
<Frame>
<img alt="Install Google Search" />
</Frame>
</Step>
<Step title="Get Your API Key">
Using Google Search for the first time requires authorization—it's like needing a Wi-Fi password.
<Frame>
<img alt="Google Search Setup" />
</Frame>
1. Click API Key Authorization Configuration, then click Get your SerpApi API key from SerpApi. Sign in to get your private API key.
<Note>
Your API Key is your passport to the outside world. Keep it safe and avoid sharing it with others.
</Note>
<Frame>
<img alt="API Key Authorization Configuration" />
</Frame>
2. Copy and paste the API key in SerpApi API key. Click **Save**.
3. Once the API key is successfully authorized, the settings panel shows up immediately. Head to Query string field, and select `Iteration/{x} item`.
<Frame>
<img alt="Add Query String" />
</Frame>
</Step>
<Step title="Configure the Two Paths">
Now, we need different ways to answer depending on which path we're looking at.
**The Search Answer Path**
Add a new LLM node to answer the question based on the search results. Connect it to the Google Search node.
**System**:
```plaintext wrap theme={null}
You are a Web Research Specialist. Based on Google Search, concisely answer the user's questions. Please do not mention the knowledge base in your response.
```
**User Message**:
```plaintext wrap theme={null}
results: GOOGLESEARCH/{x} text
questions: Iteration/{x} item
```
<Frame>
<img alt="Prompt for LLM 2" />
</Frame>
**The Knowledge Searching Path**
After the Else node, add a new LLM node to handle answers based on the knowledge base.
**System**:
```plaintext wrap theme={null}
You are a professional Dify Customer Service Manager. Strictly follow the `Context` to reply to questions.
```
**User Message**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="Prompt for LLM 3" />
</Frame>
</Step>
<Step title="Combine the Information">
1. In the sub-process (inside the Iteration box), add a Variable Aggregator node that connects both LLM 2 and LLM 3 at the very end.
2. In the Variable Aggregator panel, select the variables `LLM 2/{x}text String` and `LLM 3/{x}text String` as the Assign Variables.
In this way, we're merging the two possible answers into a single path.
<Frame>
<img alt="Variable Aggregator Setup" />
</Frame>
</Step>
</Steps>
This is how the current workflow looks.
<Frame>
<img alt="Workflow Preview 2" />
</Frame>
#### Step 3: The Final Email Assembly
Now that our logic branches have finished processing, let's combine all the answers into a single, polished email.
<Steps>
<Step title="Configure Iteration Output">
Click on the Iteration node, and set `{x}Variable Aggregator/{x}output String` as the output variables.
<Frame>
<img alt="Iteration Output" />
</Frame>
</Step>
<Step title="Connect the Summary LLM">
After the Iteration node, connect a new LLM node to summarize all outputs. Feel free to use the prompt below.
**System**:
```plaintext wrap theme={null}
You are a professional Customer Service Manager. Summarize all the answers of the questions, and organize a clear and complete email reply for the customer.
Do not include content where the knowledge base could not find relevant information.
Signature: Anne.
```
**User Message**:
```plaintext wrap theme={null}
questions: Iteration/ {x} output
customer: User Input / {x} customer_name
```
<Frame>
<img alt="Prompt for LLM 4" />
</Frame>
</Step>
<Step title="Finalize with the Output Node">
After the LLM node, add an End node. Set the output variable as `LLM 4/{x}text String`.
<Frame>
<img alt="Output Setup" />
</Frame>
</Step>
</Steps>
We have now completed the entire setup and configuration of the workflow. Our email assistant can now answer questions based on the Knowledge Base and use Google Search for supplementary answers when needed.
<Frame>
<img alt="Final Workflow Preview" />
</Frame>
Try sending an email with question that definitely isn't in the knowledge base. Let's see if the AI successfully uses Google to find the related answers.
## Mini Challenge
1. What are other conditions you can choose in If/Else node?
2. Browse marketplace to see if you can add another tool for this workflow?
# Lesson 8: The Agent Node
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-08
Let's look back at the upgrades we've made for our email assistant.
* Learned to Read: It can search a Knowledge Base
* Learned to Choose: It uses Conditions to make decisions
* Learned to Multitask: It handles multiple questions via Iteration
* Learned to Use Tools: It can access the Internet via Google Search
These nodes work, but we have had to describe every step in advance. What if we could give the job to an AI teammate that already knows how to reason, use its resources, and improve over time?
Meet your AI teammate: the **Agent**.
## From Workflow to Agentic Workflow
A traditional workflow follows a path designed by its builder. An Agentic workflow combines that dependable structure with an Agent that can decide how to complete a task inside the boundaries you set.
Think of the workflow as the shared operating procedure and the Agent as the teammate performing part of it:
* The **workflow** supplies inputs, order, checks, fallbacks, and outputs.
* The **Agent** works toward a goal, uses its available knowledge and tools, and returns a result.
* The **Agent node** is where that Agent appears in this particular workflow.
The same Agent can be invited into several workflows, or even appear more than once in one workflow. Its core identity and capabilities belong to the Agent. The instructions you add in an Agent node describe only its job at that point in the workflow.
You do not need to install or select a reasoning strategy. The Agent manages its own reasoning loop. Your job is to give it the right assignment, inputs, and expected outputs.
## Agent & Agent Node
There are two ways to add an Agent to a workflow:
* **Invite an Agent**: Reuse an existing Agent that you or your team has already built.
* **Start from Scratch**: Create a one-time Agent directly on the canvas. This is useful for a role that exists only in this workflow. You can save it to **Agents** later if it becomes reusable.
In the earlier lessons, we did not create an agent, so we will start from scratch and this tutorial works from a clean workspace. At the end, you can save it to the **Agents** page and reuse it elsewhere.
After this lesson, the whole workflow is: `Start → Knowledge Retrieval → Product Support Agent → Output`
## Hands-on 1: Create an Agent
Our goal is to replace the entire manually orchestrated middle section with one Agent. The Agent will receive the complete customer email, identify and answer every question, and return one coherent email body.
<Steps>
<Step title="Remove Extra Nodes">
Starting from Lesson 7's workflow, delete the Parameter Extractor and the Iteration node (everything inside it goes with it), leaving only Start and Output.
</Step>
<Step title="Add Knowledge Retrieval">
After Start, click **+** and add a Knowledge Retrieval node. Select the Dify product Knowledge Base used in the previous lessons.
<Frame>
<img alt="Add a Knowledge Retrieval Node" />
</Frame>
</Step>
<Step title="Add an Agent Node">
After Knowledge Retrieval, click **+**, choose **Agent**, and select **Start from Scratch**.
<Frame>
<img alt="Add an Agent Node and Start from Scratch" />
</Frame>
This opens the agent's setup over the workflow canvas:
* The **Configure** panel on the left contains the model, prompt, skills, files, tools, etc. You can set them up manually.
* **Build** on the right lets you build your agent by chatting, and the configuration is filled automatically.
* **Preview** lets you try the Agent before returning to the workflow.
<Frame>
<img alt="The Agent Setup with Build Mode" />
</Frame>
</Step>
<Step title="Connect to the Required Resources">
Before entering Build mode, do a quick setup:
* **Model**: select a compatible model if the current model is missing or marked incompatible.
* **Tools**: add Google Search.
</Step>
<Step title="Build the Agent by Chatting">
In Build mode, enter the following request.
```text wrap theme={null}
Create a Dify Product Support Agent.
Configure the Agent to use context provided by the workflow first and search only when that context is insufficient or current information is required.
Do not create duplicate search capabilities.
```
<Frame>
<img alt="Describe the Agent in Build Mode" />
</Frame>
After the build finishes, the agent has set up its own assets:
* `product-support`: an embedded skill carrying the Agent's support behavior and source-use rules.
* `build_note.md`: a note recording what was set up during the build chat.
</Step>
<Step title="Add the Main Prompt">
After you click **Apply**, Build mode closes and the **Configure** panel becomes editable again. Add the following instruction to **Prompt**:
```text wrap theme={null}
Answer accurately using the context provided with each assignment. Treat that context as the primary source. Use Google Search only when the context is insufficient, irrelevant, or outdated.
```
The generated skill defines the Agent's reusable product-support expertise. The prompt adds a clear rule for when the Agent should use Google Search.
<Frame>
<img alt="The Generated Skill and Prompt in Configure" />
</Frame>
</Step>
<Step title="Preview the Agent">
Switch to **Preview** and ask a Dify product question to confirm the agent answers concisely and searches only when necessary.
When the setup looks correct, close it and return to the workflow canvas.
</Step>
</Steps>
<Check>
🎉 The Agent is ready now.
</Check>
## Hands-on 2: Assign the Workflow Task
Now the Agent has a reusable role, support expertise, and a search tool. Next, let's give it an assignment of what to do in this workflow.
<Steps>
<Step title="Provide the Email and Retrieved Knowledge">
Select the Agent node. In **Agent task**, describe this step's assignment:
```text wrap theme={null}
Answer every question or request in {{email_content}}.
Use the retrieved product knowledge in {{result}} first.
Combine all answers into one email body.
```
Type `/` to insert `email_content` from User Input and `result` from Knowledge Retrieval, so they arrive as variables rather than plain text.
<Frame>
<img alt="Describe the Assignment in Agent Task" />
</Frame>
</Step>
<Step title="Connect the Output Node">
Click the Output node and set its variable to the Agent's `text` output. This way, the workflow returns the generated email reply.
<Frame>
<img alt="Set the Output to the Agent's Text" />
</Frame>
</Step>
</Steps>
Here comes the final workflow.
<Frame>
<img alt="The Final Four-Node Workflow" />
</Frame>
Click **Test Run** and input a customer email with a few questions. The Agent answers from the retrieved knowledge and searches only when it needs to.
## Optionally Save the Agent
The Product Support Agent is already stored as part of this workflow. You do not need to save it separately to continue to the next lesson.
To reuse it in other workflows: click the Agent node to open its setup, then in **Configure**, click **⋯** and select **Save to Agents**.
<Frame>
<img alt="Save the Agent to Agents" />
</Frame>
Give the agent a name, an icon, and a description.
<Frame>
<img alt="Name the Saved Agent" />
</Frame>
## Mini Challenge
1. Add a requirement that the Agent clearly labels information obtained from an Internet search.
2. Ask one question that cannot be answered from either the retrieved knowledge or Google Search. Confirm that the Agent acknowledges the limitation instead of omitting the question.
# Lesson 9: Layout Designer (Template)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-09
In Lesson 8, we simplified the workflow to one Product Support Agent.
The content may be accurate and well written, but generated formatting can still vary. A greeting may change, a divider may disappear, or a signature may be phrased differently from one run to the next.
For elements that must remain consistent, we can use a Template node.
## Template
It takes the original data (like your list of answers), follows a strict design template/standards you provide, and generates a perfectly formatted block of text, ensuring consistency every single time.
## Hands-On: Polish the Email Layout
<Steps>
<Step title="Check the Product Support Agent">
Select **Product Support** on the workflow canvas. Its assignment should require it to handle the complete email but return only the substantive body. Add the text below in **Agent task**:
```text wrap theme={null}
Return the body only, without a greeting, divider, or signature.
```
This separation matters: the Agent controls delivery and tone, while the Template controls the fixed layout.
<Frame>
<img alt="Add the Body-Only Rule to Agent Task" />
</Frame>
</Step>
<Step title="Add a Template Node">
Insert a Template node after the Agent node and before Output.
<Frame>
<img alt="Insert a Template Node Before Output" />
</Frame>
</Step>
<Step title="Set the Input Variables">
Open the Template node and add these variables:
* `customer`: `User Input /{x} customer_name`
* `body`: `Agent /{x} text`
Using the Agent's `text` output makes the handoff easy to understand and inspect.
<Frame>
<img alt="Add the Customer and Body Variables" />
</Frame>
</Step>
<Step title="Format the Email with Jinja">
**What is Jinja2?**
In simple terms, Jinja2 is a tool that allows you to format variables (like your list of answers) into a text template exactly how you want. It uses simple symbols to mark where variables go and perform basic logic. With it, we can turn a raw list of data into a neat, standardized text block.
Here, we can put together opening, signatures, and email body to make sure the email is professional and consistent every time.
Copy and paste this exact layout into the Template code box:
```text wrap theme={null}
Hi {{ customer }},
Thank you for reaching out. We are happy to help with your questions.
{{ body }}
---
Best regards,
Dify Support Team
```
The values of `customer` and `body` can change with every workflow run. Everything around them remains fixed. This gives the Agent freedom to write the answer while ensuring that the final email always follows the required layout.
</Step>
<Step title="Update the Output Node">
Open Output. Replace the previous value with the Template node's output.
<Frame>
<img alt="Point the Output at the Template" />
</Frame>
</Step>
</Steps>
Here's the final workflow.
<Frame>
<img alt="The Final Workflow with the Template Node" />
</Frame>
Click **Test Run**. Ask multiple questions in one email. Notice how your final output has a perfectly written custom intro, the LLM's beautifully summarized answers in the middle, and a standard, professional signature at the bottom.
## Mini Challenge
1. Add a conditional fallback when `customer` is empty, such as `Hi there,`.
2. Add a fixed support disclaimer that the Agent cannot change or omit.
# Lesson 10: Publish and Monitor Your AI App
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-10
After building and tuning, your Email Assistant is now fully ready. It can read knowledge bases, use search tools, and generate beautifully formatted replies. But right now, it's still sitting inside your Dify Studio and only you can see it.
How do we share it with others? How do we know if it's working correctly when we aren't watching?
It's time for the final two critical steps: Publish and Monitor.
## Publish Your Application
1. Move your mouse to the top right corner of the canvas and click the **Publish** button. You'll see other buttons light up.
<Note>
Whenever you make changes to your workflow, you must click **Publish** > **Publish Update** to save them.
If you don't update, the live version will remain the old one.
</Note>
2. Once published, the grayed-out buttons become clickable.
1. **Share Your App**
Click **Open web app**. Dify automatically generates a web app for you. This is a ready-to-use chat interface for your Email Assistant.
You can send this URL to colleagues or friends. They don't need to log in to Dify to use the email assistant.
<Frame>
<img alt="Web App" />
</Frame>
2. **Run Batch**
If you have 100 emails to reply, copying and pasting them one by one will drag you down.
In Dify, all you need to do is to prepare a CSV file with the 100 emails. Upload it on the **Run Batch** tab. Dify processes all 100 emails automatically and gives you back a spreadsheet with all the generated replies.
Since we set specific variables (like `email_content`), your CSV must match that format. Dify provides a template you can download to make this easy.
<Frame>
<img alt="Download Template" />
</Frame>
3. **Others**
* **Access Point**: Manage every way your app can be reached—the web app, the API, an MCP server, and triggers. If you know coding, get an API Key here to integrate this workflow directly into your own website or mobile app
* **Workflow as Tool**: Package your workflow as a tool so other Agents can use your Email Assistant
## Monitor Your App
As the creator, you need to understand the status of this assistant. By monitoring and using logs, you can check the health, performance, and costs.
### The Command Center: Monitoring
Click **Monitoring** on the left sidebar to see how your app is performing.
| Name | Explanation |
| :--------------------- | :----------------------------------------------------------------------------------- |
| Total Messages | How many times users interacted with the AI today. It shows how popular your app is. |
| Active Users | The number of unique people engaging with the AI. |
| Token Usage | How much tokens the AI used. Watch for sudden spikes to control costs. |
| Avg. User Interactions | Do the users ask follow-up questions? |
### The Magnifying Glass: Logs
Logs record the details of every single run: time, input, duration, and output. To access detailed records, click Logs in the left sidebar.
**Why Logs?**
* **Debugging**: User says *It doesn't work*? Check the logs to replay the *crime scene* and see exactly which node failed.
* **Performance**: See how long each node took. Find the blocker that is slowing things down.
* **Understand Users**: Read what users are actually asking. Use this real data to update your Knowledge Base or improve your Prompts.
* **Cost Control**: Check exactly how many tokens a specific run cost.
| Name | Explanation |
| :------------------ | :---------------------------------------------------------- |
| Start Time | The time when the workflow was triggered |
| Status | Success or Failure. |
| Run Time | How long the whole process took. |
| Tokens | The tokens consumed by this run. |
| End User or Account | The specific user ID or account that initiated the session. |
| Triggered By | Web app interface or called via API. |
You can click on each log entry to view more details. For example, you can identify frequently asked user questions and use them to timely update and modify your Knowledge Base.
Building AI app is a new starting point, and this is the core of **LLMOps** (Large language model operations).
1. **Observe**: Look at the Logs. What are users asking? Are they happy with the answers?
2. **Analyze**: Hallucination happens on certain questions or some tools run out often
3. **Optimize**: Go back to the Canvas. Edit the Prompt, add a document to the Knowledge Base, or tweak the workflow logic
4. **Publish**: Release the upgraded version
By repeating this cycle, your Email Assistant gets smarter and faster.
## Thank You
**Thank you for your time and you're now a Dify builder with a new way of thinking**:
```plaintext wrap theme={null}
Break down the task → Choose Nodes and Tools → Connect them with the right logic → Monitor and upgrade
```
Now, feel free to open a template in Dify explore. Break it down, analyze it, or start building a workflow that solves a task in your daily work from the scratch.
May your workload get lighter and your imagination goes higher. Happy building with Dify.
# List Datasource Plugins
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/list-datasource-plugins
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/pipeline/datasource-plugins
Returns the datasource nodes configured in the knowledge pipeline, each with the plugin it uses and the metadata needed to run it.
# Run Datasource Node
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/run-datasource-node
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/pipeline/datasource/nodes/{node_id}/run
Runs a single datasource node in the knowledge pipeline and streams its execution events.
# Run Pipeline
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/run-pipeline
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/pipeline/run
Runs the full knowledge pipeline over one or more datasources. `response_mode` selects a streaming or blocking response.
# Upload Pipeline File
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/upload-pipeline-file
/en/api-reference/openapi_service.json post /datasets/pipeline/file-upload
Uploads a file for use in a knowledge pipeline. Use the returned `id` as the `reference` of a `local_file` item in [Run Pipeline](/en/api-reference/knowledge-pipeline/run-pipeline).
# Get Available Models
Source: https://docs.dify.ai/en/api-reference/models/get-available-models
/en/api-reference/openapi_service.json get /workspaces/current/models/model-types/{model_type}
Returns the available models of a given type. Use it to find the `text-embedding` and `rerank` models to configure on a knowledge base.
# Get Knowledge Base Tags
Source: https://docs.dify.ai/en/api-reference/tags/get-knowledge-base-tags
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/tags
Returns the tags bound to a knowledge base.
# Authenticate
Source: https://docs.dify.ai/en/cli/authenticate
Sign in to your Dify host from the CLI, see where your token is stored, and manage your session
You sign in through your browser, using the OAuth 2.0 device flow; `difyctl` never sees your password.
## Sign In
<Note>
On a self-hosted deployment, set both `OPENAPI_ENABLED` and `ENABLE_OAUTH_BEARER` to `true` before you sign in. See [Dify CLI and Programmatic API](/en/self-host/deploy/configuration/environments#dify-cli-and-programmatic-api) for the full variable reference.
</Note>
<Steps>
<Step title="Run the login command">
Pass your Dify host's URL. For Dify Cloud, use `https://cloud.dify.ai`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
`difyctl` prints a one-time code, opens the verification URL in your default browser, and waits:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
<Tip>
To skip the auto-open, pass `--no-browser`.
</Tip>
If no browser opens (normal over SSH and in headless sessions), open the URL yourself on any device.
</Step>
<Step title="Approve the sign-in in your browser">
In the browser tab that opens, sign in with your Dify credentials and enter the one-time code.
The code expires after 15 minutes. If it expired, re-run `difyctl auth login` to get a fresh one.
</Step>
<Step title="Confirm the session">
Back in the terminal:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
The second line is your workspace.
</Step>
</Steps>
## Sign In Again
If a command fails with `auth_expired` (exit code 4), the server has expired or revoked your session.
Run `difyctl auth login` again. You don't need to sign out first, and the new sign-in refreshes your stored token.
## Check Who You're Signed In As
```bash theme={null}
difyctl auth whoami
```
```text theme={null}
<your-email> (<your-name>)
```
To read the identity from a script, add `--json`:
```bash theme={null}
difyctl auth whoami --json
```
You'll get the same fields as a JSON object, plus your account ID:
```json theme={null}
{"id":"3c90c3cc-0d44-4b50-8888-8dd25736052a","email":"<your-email>","name":"<your-name>"}
```
## Sign Out
```bash theme={null}
difyctl auth logout
```
```text theme={null}
✓ Logged out of cloud.dify.ai
```
This revokes the session on the server and deletes the token and session entry from your machine. If the server-side revocation fails, your local credentials are cleared anyway.
## Where Your Token Lives
Signing in stores an OAuth bearer token, recognizable by its `dfoa_` prefix. It represents you: whatever your account can do in your workspace, the token can do from the CLI.
`difyctl` keeps the token in your operating system's credential store when one is available: Keychain on macOS, Credential Manager on Windows, Secret Service on Linux. If no credential store responds, it falls back to a `tokens.yml` file with `0600` permissions in the `difyctl` config directory.
`difyctl` picks the store once when you sign in, and the session uses it from then on. Session metadata (hosts, accounts, workspaces) lives alongside the token in `hosts.yml`.
The config directory is `~/.config/difyctl` on macOS and Linux (Linux honors `XDG_CONFIG_HOME`) and `%APPDATA%\difyctl` on Windows. Set [`DIFY_CONFIG_DIR`](/en/cli/reference/environment-variables) to override it.
## Troubleshooting
| Problem | What to do |
| :---------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| The browser never opens | Copy the URL from the terminal and open it on any device. |
| The host is rejected | Only `https://` hosts are accepted; a host without a scheme defaults to `https://`. For a plain `http://` host, or an `https://` host with a self-signed or invalid TLS certificate (local development only), add `--insecure`. |
| A later command fails with `auth_expired` | Your session expired or was revoked. [Sign in again](#sign-in-again). |
For everything else, see the full [Troubleshooting](/en/cli/troubleshooting) page.
# Common Tasks
Source: https://docs.dify.ai/en/cli/common-tasks
Copy-paste commands for the difyctl tasks you'll run most often
All commands below assume you're [signed in](/en/cli/authenticate).
## Send a Message
Send a message to a Chatbot, Chatflow, Agent, or Text Generator app by passing it as a positional argument to [`difyctl run app`](/en/cli/reference/apps#run-an-app). The reply prints to stdout.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
# save just the reply to a file; hints and errors go to stderr, not stdout
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "Summarize this week's tickets" > reply.txt
```
## Run a Workflow
Pass the inputs as a single JSON object with [`--inputs`](/en/cli/reference/apps#run-an-app) instead of a positional message. The outputs print to stdout as JSON.
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report"}'
# read large input sets from a file instead
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs-file inputs.json
```
## Find Your Apps
List the apps in your workspace with [`difyctl get app`](/en/cli/reference/apps#list-your-apps). Narrow the list with `--name` or `--mode`.
```bash theme={null}
difyctl get app
# filter by name substring or mode
difyctl get app --name report --mode workflow
# list apps from every workspace you belong to
difyctl get app -A
```
## Stream a Long Response
Add [`--stream`](/en/cli/reference/apps#run-an-app) to print the response as it's generated instead of all at once at the end.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "Draft a launch announcement" --stream
```
## Continue a Conversation
Copy the conversation ID from the hint that follows each Chatbot or Chatflow reply, then pass it back with [`--conversation`](/en/cli/reference/apps#run-an-app) to continue the same conversation.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
# hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "And on weekends?" --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
## Get JSON Output for Scripts
Add [`-o json`](/en/cli/reference/output-formats-and-exit-codes) to any command to get the raw response as pipe-friendly JSON.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?" -o json | jq -r '.answer'
# extract fields from list output the same way
difyctl get app -o json | jq -r '.data[].id'
# get just the IDs, one per line, no jq needed
difyctl get app -o name
```
## Switch Your Workspace <Badge>Cloud</Badge>
Change your active workspace with [`difyctl use workspace`](/en/cli/reference/workspaces#switch-your-workspace-cloud). List available workspaces with `get workspace`.
```bash theme={null}
difyctl get workspace
difyctl use workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
# ✓ Switched to Marketing (9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c)
# one-off: run a single command against another workspace without switching
difyctl get app --workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
## Inspect an App's Inputs
Before running an unfamiliar app, check its app type and input schema with [`difyctl describe app`](/en/cli/reference/apps#inspect-an-app): names, types, and which inputs are required.
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
# get the schema as JSON to build --inputs programmatically
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b -o json
```
# Install difyctl
Source: https://docs.dify.ai/en/cli/install
Install difyctl with a one-line script or a manual binary download
`difyctl` is a standalone binary with no runtime dependencies. The install script detects your platform, downloads the matching build from Dify's GitHub Releases, verifies its checksum, and puts the binary in place.
<Note>
`difyctl` was introduced with Dify 1.15.0. Each build targets a specific Dify version, so install the one that matches your server (see `DIFY_VERSION` below).
</Note>
## Install
<Steps>
<Step title="Run the Installer">
`difyctl` ships a build with each Dify release, and the installer fetches the latest by default.
<Tabs>
<Tab title="macOS / Linux">
Supported platforms: macOS and Linux, x64 and arm64.
```bash theme={null}
curl -fsSL https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install-cli.sh | sh
```
The script installs to `~/.local/bin/difyctl` and tells you if that directory isn't on your `PATH`.
</Tab>
<Tab title="Windows">
Supported platform: x64.
```powershell theme={null}
irm https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install.ps1 | iex
```
The script installs to `%LOCALAPPDATA%\difyctl\bin\difyctl.exe` and prints the command to add that directory to your `PATH` if it isn't already there.
</Tab>
<Tab title="Manual Download">
1. From [Dify's GitHub Releases](https://github.com/langgenius/dify/releases), pick the release that matches your server's Dify version and download two assets:
* The binary for your platform (`difyctl-v<version>-<os>-<arch>`)
* The checksum manifest (`difyctl-v<version>-checksums.txt`)
2. Compute the binary's SHA-256 hash and compare it with the matching entry in the checksums file.
If the values differ, the download is corrupted or was tampered with; delete it and download again.
<CodeGroup>
```bash macOS / Linux theme={null}
shasum -a 256 difyctl-v<version>-<os>-<arch>
```
```powershell Windows theme={null}
Get-FileHash difyctl-v<version>-windows-x64.exe
```
</CodeGroup>
3. Put the binary on your `PATH`:
<CodeGroup>
```bash macOS / Linux theme={null}
chmod +x difyctl-v<version>-<os>-<arch>
mv difyctl-v<version>-<os>-<arch> ~/.local/bin/difyctl
```
```powershell Windows theme={null}
New-Item -ItemType Directory -Force "$env:LOCALAPPDATA\difyctl\bin" | Out-Null
Move-Item difyctl-v<version>-windows-x64.exe "$env:LOCALAPPDATA\difyctl\bin\difyctl.exe"
```
</CodeGroup>
</Tab>
</Tabs>
<Tip>
To customize the install, set any of these environment variables on the install command.
| Variable | Description | Example |
| ----------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------- |
| `DIFY_VERSION` | The Dify release tag to install `difyctl` from, matching a tag on [Dify's Releases](https://github.com/langgenius/dify/releases).<br /><br />Defaults to the latest release; set it to your server's release tag when your server isn't on the latest. | `1.16.1` |
| `DIFYCTL_VERSION` | Pin a specific `difyctl` build. Used only when `DIFY_VERSION` is unset. | `0.2.0-alpha` |
| `DIFYCTL_PREFIX` | The install directory (default `~/.local`). The binary lands in `<prefix>/bin`. | `/usr/local` |
For example:
<CodeGroup>
```bash macOS / Linux theme={null}
curl -fsSL https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install-cli.sh | DIFY_VERSION=1.16.1 sh
```
```powershell Windows theme={null}
# PowerShell has no inline form; this applies for the rest of your session
$env:DIFY_VERSION = "1.16.1"
irm https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install.ps1 | iex
```
</CodeGroup>
</Tip>
</Step>
<Step title="Verify the Install">
```bash theme={null}
difyctl version
```
You should see a `Client:` block with the version and platform.
If you get `command not found` instead, the install directory isn't on your `PATH`. Add it:
<CodeGroup>
```bash macOS / Linux theme={null}
# add to ~/.zshrc or ~/.bashrc; running it inline only lasts until the session ends
export PATH="$HOME/.local/bin:$PATH"
```
```powershell Windows theme={null}
[Environment]::SetEnvironmentVariable('PATH', "$env:LOCALAPPDATA\difyctl\bin;$env:PATH", 'User')
```
</CodeGroup>
</Step>
</Steps>
## Update
To update `difyctl`, re-run the install script; it replaces the binary in place. To move to a specific Dify version, set `DIFY_VERSION` as above.
## Uninstall
<CodeGroup>
```bash macOS / Linux theme={null}
rm ~/.local/bin/difyctl
```
```powershell Windows theme={null}
Remove-Item -Recurse "$env:LOCALAPPDATA\difyctl"
```
</CodeGroup>
To sign out before uninstalling, run [`difyctl auth logout`](/en/cli/reference/auth-and-contexts#sign-out).
## Next Steps
With `difyctl` installed, head to the [Quick Start](/en/cli/quick-start) to sign in and run your first app.
# Authenticate Where Your Agent Runs
Source: https://docs.dify.ai/en/cli/integrate-agents/auth-for-agent-deployments
Put a difyctl session on the server or container where your agent runs, so it can call Dify apps unattended
Your agent never logs in. It reuses the `difyctl` session on the machine where it runs. How you get it there depends on the machine:
* **Your own machine**: [sign in](/en/cli/authenticate) and you're set.
* **A server or VM you can log into**: sign in on it (Option 1).
* **A container, CI runner, or prebaked image**: copy a session in (Option 2).
## Option 1: Sign In on the Machine
Sign in on the target machine as the account the agent should act as. The agent inherits everything that account can reach.
For Dify Cloud, use `https://cloud.dify.ai` for `--host`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url). Pass `--no-browser` when the machine has no browser:
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai --no-browser
```
`difyctl` prints a one-time code and a verification URL. Open the URL on any device, sign in, and enter the code. The session is written to the machine the moment you approve. For the full walkthrough, see [Authenticate](/en/cli/authenticate#sign-in).
Confirm it landed:
```bash theme={null}
difyctl auth whoami
```
```text theme={null}
<your-email> (<your-name>)
```
## Option 2: Copy a Session You Already Have
Use this when you can't sign in on the target itself, like a prebaked image or an ephemeral container.
<Steps>
<Step title="Sign in on a machine without an OS keychain">
Use a headless Linux server or a container. Without a keychain, `difyctl` saves the token to `tokens.yml` in the [config directory](/en/cli/authenticate#where-your-token-lives), making the entire directory portable.
Before copying, confirm `tokens.yml` exists in the config directory (`~/.config/difyctl` by default). If it's missing, a keychain captured the token instead, and there's no supported way to export it. Sign in directly on the target with [Option 1](#option-1-sign-in-on-the-machine).
</Step>
<Step title="Copy the config directory to the target">
After copying, point `difyctl` at it with [`DIFY_CONFIG_DIR`](/en/cli/reference/environment-variables). For a container, mount the directory at runtime instead of baking it into the image:
```bash theme={null}
docker run \
-v /path/to/difyctl-config:/config:ro \
-e DIFY_CONFIG_DIR=/config \
your-agent-image
```
`tokens.yml` is a live credential. Keep its `0600` permissions and keep it out of images and version control. The mount is read-only because an agent that only runs apps never writes to the config directory.
</Step>
</Steps>
## When the Session Expires
A server-expired or revoked session surfaces as exit code 4 with `error.code` `auth_expired`. The agent can't recover on its own: a new session takes a person approving the sign-in, the same one-time-code step as Option 1.
So it should stop and surface the failure for a human to [sign in again](/en/cli/authenticate#sign-in-again), not retry. See [Handle Errors and Retries](/en/cli/integrate-agents/error-handling-and-retries-for-agents#branch-on-the-exit-code) for how to branch on it.
To revoke a session you suspect is compromised, run [`auth devices revoke`](/en/cli/reference/auth-and-contexts#revoke-sessions) from any signed-in machine.
# Handle Errors and Retries
Source: https://docs.dify.ai/en/cli/integrate-agents/error-handling-and-retries-for-agents
Make your agent fail safely on difyctl errors: branch on exit codes, parse the error, detect paused workflows, and retry only what's safe
Your agent needs four pieces of failure logic to drive `difyctl` safely: read the right channel, branch on the exit code, treat a paused workflow as success, and retry only what's safe to retry.
## Read the Right Channel
Run every programmatic invocation with `-o json`. The channel discipline is strict and you can build on it:
* **Success**: the payload is on stdout as parseable JSON with no ANSI codes, and stderr is empty.
* **Failure**: stdout is empty, and stderr is a structured JSON object. The entire trimmed stderr parses as JSON.
* **Paused**: a Workflow that stops for human input also exits `0` on the success channel, with `"status": "paused"` on stdout. [Treat it as success](#a-pause-is-success-not-an-error), not failure.
So the parse rule is: exit code first, then `JSON.parse(stdout)` on success and `JSON.parse(stderr)` on failure. See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes#errors) for the error object's fields and a full sample.
## Branch on the Exit Code
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes#exit-codes) for the full exit-code table. For an agent, the branches that matter:
* **Exit `7`—rate limited**: The server returned a 429. Back off and retry.
* **Exit `4`—auth**: No session, or the session expired. Re-establish the session before doing anything else. Don't retry the same command as-is, which just burns calls. See [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments).
* **Exit `1`—generic or server error**: Network failure, server error, app not found, or an unknown flag or command. Parse the error object and inspect `error.code`. Don't blindly retry.
* **Exit `2`—invalid input**: The CLI rejected a value before any request went out: malformed `--inputs` JSON, a non-UUID app ID, or an out-of-range flag such as `--limit 0`. Fix the call; retrying it unchanged fails the same way.
* **A paused run is exit `0`**: A workflow that hit a human-input step exits `0` with `"status": "paused"` on stdout, not an error. It's [handled separately](#a-pause-is-success-not-an-error).
## A Pause Is Success, Not an Error
A Workflow or Chatflow app with a human-input step pauses mid-run. The command exits `0` and reports the pause on stdout. There is nothing on stderr to catch. An agent that only checks exit codes will mistake the pause for a completed run, so the completion check must read the payload:
```python theme={null}
import json, subprocess
r = subprocess.run(
["difyctl", "run", "app", app_id, "--inputs", json.dumps(inputs), "-o", "json"],
capture_output=True, text=True,
)
if r.returncode == 0:
payload = json.loads(r.stdout)
if payload.get("status") == "paused":
# Success-with-pending: collect input, then resume with
# payload["form_token"] and payload["workflow_run_id"].
...
```
See [When a Workflow Pauses](/en/cli/reference/apps#when-a-workflow-pauses) for the full paused payload, the resume command, and the expiry rules. A resumed run can pause again at a later step, so run the same check after every `resume app`.
## Branch on `error.code`
The error object's `error.code` is a stable machine identifier: the same failure produces the same code across calls, so you write the branching logic once. Group your branches by recovery action rather than enumerating every code:
* **Re-authenticate, then retry**: `not_logged_in`, `auth_expired`. Both exit 4.
* **Retry with backoff**: `network_connection`, `server_5xx`. Transient infrastructure trouble.
* **Don't retry, inspect**: `server_4xx_other`. The server rejected the request: wrong app ID, bad inputs, or insufficient permissions. The `message` carries the server's reason.
* **Fix the invocation**: the usage codes that arrive with exit 2.
The error object also carries a human-readable `hint` with a suggested recovery action. Log it to speed up debugging.
When the failure came from the server, the error object may also include `error.server`, the server's own error body. Its `server.code` (for example `not_found`) distinguishes rejection reasons more finely than `server_4xx_other` if your loop needs that granularity.
## Retry Deliberately
`difyctl` already retries idempotent requests (GET, PUT, DELETE) on transient failures with exponential backoff. See [Global Flags](/en/cli/reference/global-flags#http-retries) for the budget and the `--http-retry` override.
What it never retries automatically is POST, and that's the call that matters: every `run app` is a POST. When `run app` fails mid-flight, the CLI doesn't know whether the server already started executing, so by default it won't re-send.
The one opt-in is [`run app --retry-on-limit`](/en/cli/reference/apps#run-an-app), which retries specifically on a 429 with bounded backoff. It stays off by default because an app run isn't idempotent.
The same applies to your agent's logic: re-running a failed `run app` is a new execution, not a resume of the old one. For a Chatbot, that's usually acceptable (re-ask the question). For a Workflow with side effects, gate the retry on what the workflow does.
Keep agent-side retries for the transient errors above, cap the attempts, and log every retry decision. An agent that silently re-runs writes is the failure mode the [`effect` labels](/en/cli/reference/help#machine-readable-help) exist to prevent. Every command in `difyctl help -o json` is tagged `read`, `write`, or `destructive`, so your loop can gate auto-retry on the tag and never re-send a `write` blindly.
# Install the difyctl Skill
Source: https://docs.dify.ai/en/cli/integrate-agents/install-the-difyctl-skill
Give your coding agent access to your Dify apps by installing one skill file
Run [`difyctl skills install`](/en/cli/reference/skills#install-the-skill) to write a skill file for the coding agents on your machine. The agent picks it up and onboards itself from there.
The installed `SKILL.md` is a bootstrap, not a manual. It tells the agent the one thing that matters: run [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help) and treat that output as the source of truth.
At runtime, the agent reads the full command surface from the installed `difyctl`.
## When to Use the Skill
* Your agent runtime reads skills: Claude Code, Codex, OpenCode, Cursor, pi, or anything else that picks up `SKILL.md` files from a skill directory.
* The agent can run shell commands. The skill drives `difyctl` through the agent's shell tool.
* You want zero maintenance: the skill never goes stale, because it lists no commands.
If your runtime doesn't read skills, your agent can still drive `difyctl` directly by reading [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help) at runtime.
## Prerequisites
* [Install](/en/cli/install) `difyctl` and [sign in](/en/cli/authenticate) on the machine the agent runs on, so it can reuse your session. For a server or container, see [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments).
* Use a coding agent that reads skills and can run shell commands. A sandboxed agent with no shell access can't use the skill.
* Launch the agent at least once before installing, so its config directory exists for `difyctl skills install` to find.
## Steps
<Steps>
<Step title="Preview where the skill will land">
Without `--yes`, the command is a dry run:
```bash theme={null}
difyctl skills install
```
```text theme={null}
Detected 1 agent: claude-code
would write to claude-code: /Users/you/.claude/skills/difyctl/SKILL.md
Re-run with --yes to write.
Agent not listed? Install into its directory with `difyctl skills install <dir>`.
```
</Step>
<Step title="Write the skill">
`--yes` writes to every detected agent. Pass `--agent <name>` to write to just one.
```bash theme={null}
difyctl skills install --yes
```
```text theme={null}
wrote /Users/you/.claude/skills/difyctl/SKILL.md
```
</Step>
<Step title="Start a fresh agent session">
Start a new session so the agent indexes the skill it just received.
</Step>
</Steps>
<Info>
See the [Skills reference page](/en/cli/reference/skills) for detection, target paths per agent, and the `--agent`, `--stdout`, and explicit-directory forms.
</Info>
## Test
The install prints the path it wrote; open that file to confirm the skill is there. Then check that the agent actually uses it:
1. **Discovery**: In a fresh session, ask the agent: *"What can you do with `difyctl`?"* A correctly onboarded agent runs `difyctl help -o json` and answers from its output rather than guessing commands.
2. **End to end**: Ask the agent to list your Dify apps and run one. Watch for `difyctl get app -o json` followed by a `describe`/`run` sequence with real IDs from the list.
3. **Pause handling**: If you have a Workflow or Chatflow app with a human-input step, ask the agent to run it. A paused run [exits 0 and reports `"status": "paused"` on stdout](/en/cli/reference/apps#when-a-workflow-pauses). The agent should recognize the pause and offer to resume, not report a failure or retry the run.
## Troubleshooting
| Problem | What to do |
| :---------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| The agent isn't detected | Its config directory (for example `~/.claude`) doesn't exist until the agent has run at least once. Launch it once, or target the directory explicitly with `difyctl skills install <dir> --yes`. |
| The skill is installed but the agent ignores it | Most agents index skills at session start, so start a new session. If it still doesn't load, point the installer at the directory your agent reads skills from. |
| Commands fail with exit code 4 | The agent has no session to reuse. Sign in on its machine first: see [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments). |
| The skill is older than the CLI | The skill carries a version stamp and tells the agent to compare it against `difyctl version`. If they differ, re-run `difyctl skills install --yes` to overwrite it. |
For everything else, see the full [Troubleshooting](/en/cli/troubleshooting) page.
# Integrate Your Agents with Dify Apps
Source: https://docs.dify.ai/en/cli/integrate-agents/overview
Call your Dify apps from any coding agent through difyctl, with no API to integrate or SDK to install
Your agent can call your Dify apps as tools. It runs `difyctl` as an ordinary subprocess and reads the JSON it prints back. `difyctl` describes itself, so the agent discovers your apps, runs them, and reads the results on its own.
## What the Agent Does on Its Own
The agent drives a four-step loop, with no glue code from you:
1. **Discover** the apps in your workspace.
2. **Inspect** one to learn the inputs it expects.
3. **Run** it with those inputs.
4. **Parse** the JSON result.
The agent doesn't work from a hard-coded command list. `difyctl` describes itself through [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help), and the agent reads that at runtime, so it always tracks the current CLI.
## Before You Start: Sign In Where the Agent Runs
The agent doesn't log in. It runs `difyctl` and reuses whatever session exists on the machine where it runs, so get a session onto that machine first:
* **On your own machine**: a one-time browser [sign-in](/en/cli/authenticate).
* **On a server or in a container**: sign in on the machine, or copy a session onto it. See [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments) for details.
## Onboard Your Agent
The agent learns `difyctl` from `difyctl help -o json`. Pointing it there is the only setup, and how depends on the agent:
* **Reads skills** (Claude Code, Codex, and similar): [install the `difyctl` skill](/en/cli/integrate-agents/install-the-difyctl-skill). One command writes a small file that points the agent at `difyctl help -o json`, and it onboards itself from there. No integration code.
* **Doesn't read skills**: point it there yourself. Add a line to the agent's system prompt or instructions, such as "to work with Dify, run `difyctl help -o json` and use the commands it lists." That's the hand-off the skill otherwise does for you.
# Overview
Source: https://docs.dify.ai/en/cli/overview
Run your Dify apps from terminals, scripts, CI pipelines, and AI agents with the official Dify command-line interface `difyctl`
You build Dify apps in the browser, but the work that needs them often lives somewhere else: a shell script, a CI pipeline, an AI agent deciding which tool to call.
Dify CLI (difyctl) closes that gap: anything that can run a shell command can run your Dify apps.
## What You Can Do
* Run any Dify app from your terminal and capture its output.
* List the apps in your workspace and inspect the inputs each one expects.
* Stream long responses live, or get structured JSON for scripting.
* Sign in once with OAuth, then automate without storing passwords or API keys in scripts.
* Let your AI agents discover and call your Dify apps as tools.
## Get Started
First, [install `difyctl`](/en/cli/install). Then follow the [Quick Start](/en/cli/quick-start) to sign in and run your first app.
<Tip>
Want an AI agent to run your Dify apps as tools? Once `difyctl` is installed, start with [Integrate Your Agents with Dify](/en/cli/integrate-agents/overview).
</Tip>
# Quick Start
Source: https://docs.dify.ai/en/cli/quick-start
Run your first Dify app from the command line in under 5 minutes
Before you start, make sure `difyctl` is [installed](/en/cli/install).
<Note>
On a self-hosted deployment, set both `OPENAPI_ENABLED` and `ENABLE_OAUTH_BEARER` to `true` before you sign in. See [Dify CLI and Programmatic API](/en/self-host/deploy/configuration/environments#dify-cli-and-programmatic-api) for the full variable reference.
</Note>
## Step 1: Sign In
1. Sign in to your Dify host.
For Dify Cloud, use `https://cloud.dify.ai`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
`difyctl` prints a one-time code and a verification URL, then waits:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
2. Open the URL in a browser, enter the code, and sign in. Return to the terminal and you'll see:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
## Step 2: Find Your App
List the apps in your workspace:
```bash theme={null}
difyctl get app
```
You should see something like this:
```text theme={null}
NAME ID MODE UPDATED
Customer FAQ 0a1b2c3d-4e5f-6789-abcd-ef0123456789 chat 2026-06-08T03:14:27.521839
Daily Report 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b workflow 2026-06-05T22:41:09.812016
```
Copy the ID of the app you want to run. The examples below use the two IDs from this table.
## Step 3: Run Your App
How you pass input depends on the app type.
<Tabs>
<Tab title="Chatbot / Chatflow / Agent / Text Generator">
Pass your message as a positional argument:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
```
The reply prints to stdout. For Chatbot, Chatflow, and Agent apps, a hint also prints to stderr so you can continue the same conversation later:
```text theme={null}
Our business hours are Monday through Friday, 9am to 6pm PT.
hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
</Tab>
<Tab title="Workflow">
Pass inputs as a single JSON object with `--inputs`:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report","audience":"executives"}'
```
The workflow's outputs print to stdout as JSON:
```json theme={null}
{"summary":"Q3 revenue grew 14% YoY...","sections":["revenue","costs","outlook"]}
```
</Tab>
</Tabs>
## Next Steps
* **The everyday commands, copy-paste ready**: [Common Tasks](/en/cli/common-tasks)
* **Where your token lives and how sessions work**: [Authenticate](/en/cli/authenticate)
* **Everything else you can do with `difyctl`**: [Command Index](/en/cli/reference/command-index)
# Apps
Source: https://docs.dify.ai/en/cli/reference/apps
List, inspect, run, resume, export, and import your Dify apps from the CLI
Every app task maps to one command, and all of them accept the [global flags](/en/cli/reference/global-flags).
* [`difyctl get app`](#list-your-apps) lists your apps
* [`describe app`](#inspect-an-app) shows one app's details and inputs
* [`run app`](#run-an-app) invokes one
* [`resume app`](#resume-a-paused-workflow) continues a workflow that [paused for human input](#when-a-workflow-pauses)
* [`export studio-app`](#export-an-app) / [`import studio-app`](#import-an-app) exports / imports apps as DSL files
## List Your Apps
```text theme={null}
difyctl get app [app-id] [flags]
```
<Tip>
For the everyday invocations, see [Find Your Apps](/en/cli/common-tasks#find-your-apps) in Common Tasks.
</Tip>
### Arguments
* `[app-id]`: optional. The ID of one app to show. Omit it to list every app in your workspace.
### Flags
| Flag | Type | Default | Description |
| :------------------------------------------ | :------ | :--------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--name <substring>` | string | none | Filter to apps whose name contains this text. |
| `--mode <mode>` | string | none | Filter by app type, named by its API mode: <ul><li>`chat` (Chatbot)</li><li>`advanced-chat` (Chatflow)</li><li>`agent-chat` (Agent)</li><li>`workflow` (Workflow)</li><li>`completion` (Text Generator)</li></ul> |
| `--page <n>` | integer | `1` | Page number. |
| `--limit <n>` | integer | `20` | Page size, 1 to 200. The flag wins, then [`DIFY_LIMIT`](/en/cli/reference/environment-variables). |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
| `-A, --all-workspaces` <Badge>Cloud</Badge> | boolean | `false` | List apps across every workspace your token can see. |
| `-o <format>` | string | none | Output format: `json`, `yaml`, `name`, or `wide`. Omit the flag for the default table. |
### Examples
List the apps in your workspace:
```bash theme={null}
difyctl get app
```
List apps across every workspace you belong to:
```bash theme={null}
difyctl get app -A
```
Find Workflow apps whose name contains "report":
```bash theme={null}
difyctl get app --name report --mode workflow
```
Print app IDs only, one per line, for shell loops:
```bash theme={null}
difyctl get app -o name
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default | An aligned table. The `MODE` column is each app's API mode name (see [`--mode`](#list-your-apps) for the mapping to app types). |
| `-o wide` | The table plus a `WORKSPACE` column. |
| `-o json`, `-o yaml` | A `data` array of the apps, plus the paging fields `page` (current page), `limit` (page size), `total` (apps matched), and `has_more` (whether more pages remain). |
| `-o name` | The app IDs, one per line. |
Default table:
```text theme={null}
NAME ID MODE UPDATED
Customer FAQ 0a1b2c3d-4e5f-6789-abcd-ef0123456789 chat 2026-06-08T03:14:27.521839
Daily Report 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b workflow 2026-06-05T22:41:09.812016
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------ |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as a `--limit` outside 1 to 200 |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Inspect an App
```text theme={null}
difyctl describe app <app-id> [flags]
```
`describe app` answers the question you have before running an unfamiliar app: what type of app is it, is its API enabled, and what inputs does it expect.
### Arguments
* `<app-id>`: required. The ID of the app to inspect.
### Flags
| Flag | Type | Default | Description |
| :------------ | :------ | :------ | :----------------------------------------------------------------------------------------- |
| `--refresh` | boolean | `false` | Bypass the local app-info cache and fetch fresh details. Use after an app was republished. |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Inspect an app before running it:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Extract the input schema for building `--inputs` programmatically:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b -o json | jq '.input_schema'
```
Re-fetch after republishing the app:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --refresh
```
### Output
| Format | What stdout gets |
| :------------------- | :--------------------------------------------------------------------------------- |
| default (`text`) | An aligned field block, then the app's parameters (including the user input form). |
| `-o json`, `-o yaml` | Three top-level keys: `info`, `parameters`, and `input_schema` (detailed below). |
Default text view:
```text theme={null}
Name: Daily Report
ID: 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
Mode: workflow
Updated: 2026-06-05T22:41:09.812016
Service API: true
Parameters:
{
"opening_statement": null,
"suggested_questions": [],
"user_input_form": [
{
"text-input": {
"label": "topic",
"variable": "topic",
"required": true,
"default": ""
}
}
],
"file_upload": null,
"system_parameters": {
"file_size_limit": 15,
"image_file_size_limit": 10,
"audio_file_size_limit": 50,
"video_file_size_limit": 100,
"workflow_file_upload_limit": 10
}
}
```
A `Description:` row appears when the app has one, and an `Agent: true` row when the app is agentic.
Under `-o json`, the three keys are:
* `info` - the metadata fields shown above, from `Name` to `Service API`
* `parameters` - the parameters block shown above
* `input_schema` - a normalized list of the app's inputs, the field the `jq '.input_schema'` example reads
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------- |
| `0` | Success |
| `1` | Network or server error, including app not found |
| `2` | Usage error, including a non-UUID `<app-id>` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Run an App
```text theme={null}
difyctl run app <app-id> [message] [flags]
```
`run app` is one command for all app types. The CLI reads the app's type and dispatches to the right endpoint. What changes is how you pass input and the response shape:
* **Chatbot, Chatflow, Agent**: take a positional message, print the reply to stdout, and print a conversation hint to stderr.
* **Text Generator**: takes a positional message and prints the completion to stdout. No conversational state, no hint.
* **Workflow**: takes a JSON object via `--inputs` and prints its outputs to stdout. A workflow whose output is a single string prints it raw. Anything else prints as compact JSON.
### Arguments
* `<app-id>`: required. The ID of the app to run, from [`get app`](#list-your-apps).
* `[message]`: the user message, for Chatbot, Chatflow, Agent, and Text Generator apps. Workflow apps reject a positional message, so pass their inputs with `--inputs`.
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :----------------- | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `--inputs <json>` | string | none | Input variables as one JSON object, e.g. `--inputs '{"topic":"Q3"}'`. Required for Workflow apps. Mutually exclusive with `--inputs-file`. |
| `--inputs-file <path>` | string | none | Read the inputs object from a JSON file instead. |
| `--file <key=value>` | string, repeatable | none | Named file input. `key=@path` uploads a local file. `key=https://…` passes a remote URL without uploading. The key is the input variable name. |
| `--conversation <id>` | string | none | Continue an existing conversation. The ID comes from the stderr hint or the JSON response of an earlier run. |
| `--workflow-id <id>` | string | none | Pin the run to a specific published workflow version. Workflow and Chatflow apps only. |
| `--stream` | boolean | `false` | Print the output live as it's generated, instead of all at once at the end. |
| `--think` | boolean | `false` | Print the model's thinking to stderr when the model exposes it, whether as inline `<think>` blocks or a separate reasoning stream.<br /><br />Without this flag, that thinking is hidden. |
| `--retry-on-limit` | boolean | `false` | On a 429 rate limit, wait and retry the run instead of failing with exit `7`. Off by default, since a run isn't idempotent. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Send a message to a Chatbot, Chatflow, Agent, or Text Generator app:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
```
Run a Workflow app with structured inputs:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report","audience":"executives"}'
```
Attach a local file to a file-type input variable:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"contract review"}' --file document=@./contract.pdf
```
Continue an earlier conversation:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "And on weekends?" --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
Get the raw response as JSON for scripts and agents:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?" -o json | jq -r '.answer'
```
### Output
| Format | What stdout gets |
| :------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default (`text`) | The reply (Chatbot, Chatflow, Agent, Text Generator) or the workflow's output, as plain text. |
| `-o json`, `-o yaml` | The full server payload, including `answer` and `conversation_id` for conversational apps, plus the model's reasoning under `metadata.reasoning` when present. |
The response body goes to stdout. Everything else (hints, progress, errors) goes to stderr, so piping and redirection stay clean. After a reply from a Chatbot, Chatflow, or Agent app, stderr carries the conversation hint:
```text theme={null}
hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
With `--stream`, output prints incrementally as the server produces it. If a run fails with HTTP 422 right after an app was republished, the CLI clears its app-metadata cache and hints to run the command again.
Errors print to stderr. Under `-o json` they arrive as a structured JSON object with a stable `code` field. See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the error shape.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------------------- |
| `0` | Success, including a workflow that [paused for human input](#when-a-workflow-pauses) |
| `1` | Network or server error, including app not found |
| `2` | Usage error: invalid `--inputs` JSON, or a positional message passed to a Workflow app |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
### When a Workflow Pauses
Workflow and Chatflow apps can include human-input steps. When a run reaches one, it pauses instead of finishing: the command **exits 0** (a pause is not a failure), prints the pause to stdout, and prints a ready-to-run resume command to stderr:
```text theme={null}
! Workflow paused — input required
Node: Review draft
Message: Approve the report before it is published.
Actions: [approve] Approve [reject] Reject
Inputs: - comment — Reviewer comment
! workflow paused — resume with:
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --action approve
```
With `-o json`, stdout gets the pause as a JSON object instead:
```json theme={null}
{
"status": "paused",
"app_id": "7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b",
"task_id": "c4a8e2f6-1b3d-4a5c-9e7f-2d8b6c0a4e1f",
"workflow_run_id": "8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b",
"form_id": "5d9c3b7a-2e4f-4c6d-8b0a-1f3e5d7c9b2a",
"node_id": "1749876543210",
"node_title": "Review draft",
"form_token": "k3J9mQ2xWv8pL5nR7tY4bA",
"form_content": "Approve the report before it is published.",
"inputs": [
{
"output_variable_name": "comment",
"label": "Reviewer comment",
"type": "text-input",
"required": false
}
],
"actions": [
{ "id": "approve", "title": "Approve" },
{ "id": "reject", "title": "Reject" }
],
"display_in_ui": true,
"resolved_default_values": {},
"expiration_time": 1781712000
}
```
For scripts and agents: a paused run and a completed run both exit 0, so don't branch on the exit code. Run workflows with `-o json` and check stdout for `"status": "paused"`. Three fields drive the resume: `form_token`, `workflow_run_id`, and (when the form offers more than one action) the action `id`. Forms expire at `expiration_time` (Unix epoch seconds).
When the workflow delivers its form through email or another external channel, `form_token` is `null` and the run can't be resumed from the CLI.
## Resume a Paused Workflow
```text theme={null}
difyctl resume app <app-id> <form-token> --workflow-run-id <id> [flags]
```
`resume app` submits the form a paused workflow is waiting on, then attaches to the run and prints its output exactly like `run app`.
### Arguments
* `<app-id>`: required. The `app_id` from the pause payload.
* `<form-token>`: required. The `form_token` from the pause payload. Tokens are single-use, so resuming with an already-consumed token returns an error.
### Flags
| Flag | Type | Default | Description |
| :----------------------- | :------ | :------------ | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--workflow-run-id <id>` | string | required | The `workflow_run_id` from the pause payload. |
| `--action <id>` | string | auto-selected | Which form action to take, by `id` from the pause payload's `actions`.<br /><br />Optional when the form has exactly one action, required when it has several. |
| `--inputs <json>` | string | none | Values for the form's inputs as one JSON object, keyed by each input's `output_variable_name`.<br /><br />Mutually exclusive with `--inputs-file`. |
| `--inputs-file <path>` | string | none | Read the form values from a JSON file instead. |
| `--with-history` | boolean | `false` | Replay the output of already-executed nodes before attaching to the live stream. |
| `--stream` | boolean | `false` | Print the output live as it's generated, instead of all at once at the end. |
| `--think` | boolean | `false` | Print the model's thinking to stderr when the model exposes it, whether as inline `<think>` blocks or a separate reasoning stream.<br /><br />Without this flag, that thinking is hidden. |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Approve a single-action form, providing its input values:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --inputs '{"comment":"Looks good"}'
```
Pick an action when the form offers several:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --action reject --inputs '{"comment":"Numbers need a re-check"}'
```
Read the form values from a file:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --inputs-file form.json
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------- |
| default (`text`) | The workflow's output as the run completes. stderr confirms the submission and the finish. |
| `-o json`, `-o yaml` | The run result as one document, just like `run app` (a pause payload if it pauses again). |
In the default text output, stderr confirms the submission, the workflow's output prints to stdout as the run completes, and stderr confirms the finish:
```text theme={null}
✓ form submitted
workflow execution resumed
✓ workflow finished
```
A resumed workflow can pause again at a later human-input node. You then get a new pause payload and resume again with the new token.
### Exit Codes
| Code | Meaning |
| :--- | :-------------------------------------------------------------------------------------------- |
| `0` | Success, including the run pausing again at a later node |
| `1` | Error, including a consumed form token, or omitting `--action` on a form with several actions |
| `2` | Usage error |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Export an App
```text theme={null}
difyctl export studio-app <app-id> [flags]
```
`export studio-app` writes the app's full definition as a DSL YAML document, for versioning, backup, or [importing](#import-an-app) elsewhere.
For Workflow and Chatflow apps, export returns the current draft, not the published version that `run app` executes. Use `--workflow-id` to export a specific published version instead. Chatbot, Agent, and Text Generator apps export the published version.
### Arguments
* `<app-id>`: required. The ID of the app to export, from [`get app`](#list-your-apps).
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :------ | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `-o, --output <path>` | string | none | Write the DSL to this file instead of stdout.<br /><br />On this command, `-o` is the output file path, not the output-format selector. |
| `--include-secret` | boolean | `false` | Include encrypted secret values in the exported DSL. |
| `--workflow-id <id>` | string | none | Export a specific published workflow version by ID, instead of the default draft.<br /><br />Workflow and Chatflow apps only. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
### Examples
Print an app's DSL to stdout:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Write it to a file:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --output ./daily-report.yaml
```
Export a specific published version:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --workflow-id c7e4a1b9-3f82-4d6a-9e15-0b8c2d7f4a63
```
Export with secret values included:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --include-secret
```
### Output
The DSL YAML document prints to stdout: a `kind: app` header, a `version` field, and the full app definition. With `--output`, the same content is written to the file and stderr confirms it:
```text theme={null}
DSL written to ./daily-report.yaml
```
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------- |
| `0` | Success |
| `1` | Network or server error, including app not found |
| `2` | Usage error, including a missing `<app-id>` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Import an App
```text theme={null}
difyctl import studio-app (--from-file <path> | --from-url <url>) [flags]
```
`import studio-app` creates an app from a DSL YAML document, or overwrites an existing one with `--app-id`.
For Workflow and Chatflow apps, it writes the definition to the app's draft. `run app` uses the published version, so publish the app in Dify after importing for the change to take effect.
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :----- | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `-f, --from-file <path>` | string | none | Import DSL from a local file. Exactly one of `--from-file` or `--from-url` is required. |
| `--from-url <url>` | string | none | Import DSL from an HTTP(S) URL. |
| `--name <name>` | string | from DSL | Override the app name. |
| `--description <text>` | string | from DSL | Override the app description. |
| `--app-id <id>` | string | none | Overwrite an existing app instead of creating a new one.<br /><br />Workflow and Chatflow apps only. |
| `--icon-type <type>` | string | from DSL | Override the icon type. |
| `--icon <icon>` | string | from DSL | Override the icon. |
| `--icon-background <color>` | string | from DSL | Override the icon background color. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Import into another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
### Examples
Import an app from a local DSL file:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml
```
Import under a different name:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml --name "Daily Report (staging)"
```
Overwrite an existing app with an updated DSL:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml --app-id 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Import directly from a URL:
```bash theme={null}
difyctl import studio-app --from-url https://example.com/templates/daily-report.yaml
```
### Output
All status lines go to stderr; stdout stays empty. On success, stderr reports the new app's ID:
```text theme={null}
Import completed: app 9b4f2c8e-6a1d-4e3f-b7a5-0c8d2e6f4a9b
```
If the DSL was written for a different DSL version, the CLI confirms it for you and notes both versions on stderr.
If the app depends on plugins that aren't installed in the workspace, stderr lists them under `Missing plugin dependencies` after the import. Install them before using the app.
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------------------------------------------------- |
| `0` | Success, including imports with warnings |
| `1` | Error, including a missing or conflicting `--from-file`/`--from-url`, or a failed import |
| `2` | Usage error, including a `--from-file` path that doesn't exist |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
# Auth and Contexts
Source: https://docs.dify.ai/en/cli/reference/auth-and-contexts
Sign in, manage sessions, and switch between saved hosts and accounts
`difyctl` can hold sign-ins for several Dify hosts and accounts at once. Each host and account pair is a context: its metadata lives in `hosts.yml` in the [config directory](/en/cli/reference/environment-variables), and its bearer token lives in your OS credential store (with a protected file fallback).
Each task maps to one command:
* [`difyctl auth login`](#sign-in) signs you in to a host
* [`auth whoami`](#check-your-active-identity) prints the identity you're signed in as
* [`auth list`](#list-your-saved-contexts) lists your saved contexts
* [`auth logout`](#sign-out) signs you out of the active host
* [`use host`](#switch-the-active-host) / [`use account`](#switch-the-active-account) switch the active context
* [`auth devices list`](#list-your-active-sessions) lists your active sessions
* [`auth devices revoke`](#revoke-sessions) revokes sessions you don't recognize
For the step-by-step sign-in walkthrough, see [Authenticate](/en/cli/authenticate).
## Sign In
```text theme={null}
difyctl auth login [flags]
```
`auth login` runs the OAuth 2.0 device flow: it prints a one-time code and a verification URL, opens the URL in your browser, and waits for you to approve the sign-in there. The CLI never sees your password.
### Flags
| Flag | Type | Default | Description |
| :------------- | :------ | :------ | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--host <url>` | string | none | The Dify host to sign in to: <ul><li>For Dify Cloud, use `https://cloud.dify.ai`. </li><li>On self-hosted Dify, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).</li></ul>A URL without a scheme gets `https://`.<br /><br />In a terminal, omit it and enter your host; in a non-interactive session (script, CI, pipe), the flag is required. |
| `--no-browser` | boolean | false | Don't auto-open the browser; print the verification URL only. |
| `--insecure` | boolean | false | Allow `http://` hosts, and accept `https://` hosts whose TLS certificate is self-signed or invalid (local development only). |
### Examples
Sign in to your Dify host:
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
Sign in from an SSH session, opening the verification URL on another device:
```bash theme={null}
difyctl auth login --no-browser
```
### Output
The code prompt goes to stderr, then a spinner waits for the browser-side approval:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
On success, the confirmation goes to stdout:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
The `Workspace:` line is your default workspace.
Each sign-in also registers a server-side session, labeled `difyctl on <hostname>`. Run [`auth devices list`](#list-your-active-sessions) to see all your sessions. Signing in to a host you're already signed in to refreshes that context's stored token.
### Exit Codes
| Code | Meaning |
| :--- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `0` | Signed in |
| `1` | Network or server error |
| `2` | Usage error, such as a missing `--host` outside a terminal or a non-`https` host without `--insecure` |
| `4` | The sign-in was denied (`access_denied`), or the code expired before you approved it (`expired_token`) |
| `6` | A version mismatch: the server is too old for this `difyctl` (checked before the session is saved), or this `difyctl` is too old for the server (HTTP `426`). Also when the server has no device-flow sign-in endpoint (`unsupported_endpoint`) |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Check Your Active Identity
```text theme={null}
difyctl auth whoami [flags]
```
`auth whoami` prints who the active context belongs to. It reads the stored context without contacting the server, so it answers "which identity is active", not "is the token still valid". It exits `0` even if the session has expired server-side.
### Flags
| Flag | Type | Default | Description |
| :------- | :------ | :------ | :---------------------------------------- |
| `--json` | boolean | false | Emit JSON instead of the plain-text line. |
### Examples
```bash theme={null}
difyctl auth whoami
```
For scripts:
```bash theme={null}
difyctl auth whoami --json
```
### Output
```text theme={null}
<your-email> (<your-name>)
```
The `--json` output is a single line with `id`, `email`, and `name`:
```json theme={null}
{"id":"3c90c3cc-0d44-4b50-8888-8dd25736052a","email":"<your-email>","name":"<your-name>"}
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------ |
| `0` | An active context exists |
| `4` | Not signed in (`not_logged_in`) |
## List Your Saved Contexts
```text theme={null}
difyctl auth list [flags]
```
`auth list` shows every stored host and account pair and marks the active one. Like `auth whoami`, it is purely local and never contacts the server.
### Flags
| Flag | Type | Default | Description |
| :------------ | :----- | :------ | :----------------------------------------------------------------------------- |
| `-o <format>` | string | none | Output format: `json`, `yaml`, or `name`. Omit the flag for the default table. |
### Examples
```bash theme={null}
difyctl auth list
```
### Output
| Format | What stdout gets |
| :------------------- | :--------------------------------------------------------------------------- |
| default | A table of your contexts: host, account, and an active marker. |
| `-o json`, `-o yaml` | A `contexts` array, each entry with `host`, `account`, `name`, and `active`. |
| `-o name` | The account emails, one per line. |
Default table:
```text theme={null}
HOST ACCOUNT ACTIVE
cloud.dify.ai you@company.com (Your Name) *
dify.internal.acme.com you@acme.com (Your Name)
```
`-o json`:
```json theme={null}
{
"contexts": [
{
"host": "cloud.dify.ai",
"account": "you@company.com",
"name": "Your Name",
"active": true
},
{
"host": "dify.internal.acme.com",
"account": "you@acme.com",
"name": "Your Name",
"active": false
}
]
}
```
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------- |
| `0` | Success, including when no contexts are stored |
| `2` | Usage error, such as an unsupported `-o` value |
## Sign Out
```text theme={null}
difyctl auth logout
```
`auth logout` revokes the active context's session on the server, then deletes its token and `hosts.yml` entry from your machine. Other saved contexts are untouched.
The local cleanup always happens. If the server-side revoke fails, `difyctl` prints a warning on stderr and clears your credentials anyway.
The same applies when the token sits in an OS keychain that can't be read at sign-out (locked, or no desktop session): the revoke is skipped and the local cleanup still runs.
### Flags
None.
### Examples
```bash theme={null}
difyctl auth logout
```
### Output
```text theme={null}
✓ Logged out of cloud.dify.ai
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------ |
| `0` | Signed out |
| `4` | Not signed in (`not_logged_in`) |
## Switch the Active Host
```text theme={null}
difyctl use host [flags]
```
`use host` changes which stored host subsequent commands run against. It is local: it only re-points the active context among the sign-ins you already have. To add a new host, run [`auth login --host`](#sign-in) instead.
### Flags
| Flag | Type | Default | Description |
| :---------------- | :----- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--domain <host>` | string | none | The stored host to switch to, written as its bare domain (`cloud.dify.ai`), without a scheme.<br /><br />In a terminal, omit it and pick from your stored hosts. In a non-interactive session (script, CI, pipe), the flag is required. |
### Examples
Switch to a stored host by its domain:
```bash theme={null}
difyctl use host --domain dify.internal.acme.com
```
### Output
On success, the new active host is confirmed:
```text theme={null}
✓ Active host is now dify.internal.acme.com
```
A domain you haven't signed into fails as a usage error that lists your known hosts.
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------------------------------- |
| `0` | Switched |
| `2` | Usage error: an unknown host, or a missing `--domain` outside a terminal |
| `4` | No stored sign-ins (`not_logged_in`) |
## Switch the Active Account
```text theme={null}
difyctl use account [flags]
```
`use account` changes which stored account is active on the current host. Like `use host`, it is local and only switches between sign-ins you already have.
### Flags
| Flag | Type | Default | Description |
| :---------------- | :----- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--email <email>` | string | none | The account to switch to.<br /><br />In a terminal, omit it and pick from your stored accounts; in a non-interactive session (script, CI, pipe), the flag is required. |
### Examples
Switch to another account on the active host:
```bash theme={null}
difyctl use account --email teammate-bot@company.com
```
### Output
On success, the new active account is confirmed:
```text theme={null}
✓ Active account on cloud.dify.ai is now teammate-bot@company.com
```
An email that isn't stored on the active host fails as a usage error that lists your known accounts. An account whose stored token is gone (revoked, or cleared by a [session revoke](#revoke-sessions)) fails with a not-logged-in error and a hint to sign in again.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------- |
| `0` | Switched |
| `2` | Usage error: an unknown account, or a missing `--email` outside a terminal |
| `4` | No stored sign-in on this host, or no credential for the chosen account |
## List Your Active Sessions
```text theme={null}
difyctl auth devices list [flags]
```
Every device-flow sign-in registers a server-side session, labeled `difyctl on <hostname>` by default. `auth devices list` shows the sessions active for your account so you can spot and [revoke](#revoke-sessions) ones you don't recognize.
### Flags
| Flag | Type | Default | Description |
| :------------ | :------ | :------ | :------------------------------------------------------------------------------------------------ |
| `--json` | boolean | false | Emit JSON instead of the table. |
| `--page <n>` | integer | 1 | Page number. |
| `--limit <n>` | integer | 20 | Page size, 1 to 200. The flag wins, then [`DIFY_LIMIT`](/en/cli/reference/environment-variables). |
### Examples
List the sessions active for your account:
```bash theme={null}
difyctl auth devices list
```
### Output
```text theme={null}
DEVICE CREATED LAST USED CURRENT
difyctl on Yours-MacBook-Pro 2026-06-02T09:14:31Z 2026-06-11T08:02:17Z *
difyctl on build-runner-3 2026-05-28T11:40:09Z 2026-06-10T22:51:44Z
```
The table marks the session your current sign-in uses with `*`. `LAST USED` is empty for a session you haven't used since signing in.
`--json` prints a single line of JSON: a `data` array with one entry per session, plus the paging fields `page`, `limit`, `total`, and `has_more`. Each entry carries `id`, `prefix`, `client_id`, `device_label`, `created_at`, `last_used_at`, and `expires_at`.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------- |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as `--limit 0` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Revoke Sessions
```text theme={null}
difyctl auth devices revoke [<target>] [flags]
```
`auth devices revoke` ends sessions server-side. The target matches by exact label first, then by exact session ID, then by case-insensitive label substring. A target that matches more than one session fails with the candidates listed, so pass an exact ID to disambiguate.
In a terminal, `difyctl` first asks you to confirm; pass `-y`/`--yes` to skip the prompt. Outside a terminal (a script or pipe), it revokes without prompting.
If you revoke the session your current sign-in uses, `difyctl` also clears that context's local credentials: you are signed out on this machine.
### Arguments
* `<target>`: a device label or session ID from [`auth devices list`](#list-your-active-sessions). Required unless `--all` is passed.
### Flags
| Flag | Type | Default | Description |
| :---------- | :------ | :------ | :------------------------------------------- |
| `--all` | boolean | false | Revoke every session except the current one. |
| `-y, --yes` | boolean | false | Skip the confirmation prompt. |
### Examples
Revoke one session by its label:
```bash theme={null}
difyctl auth devices revoke "difyctl on build-runner-3"
```
Sign out everywhere else, keeping this machine's session:
```bash theme={null}
difyctl auth devices revoke --all
```
### Output
On success, `difyctl` prints `✓ Revoked <N> session(s)`. A named target that matches nothing fails with `no session matches "<target>"`. `--all` with no other sessions prints `no sessions to revoke` and exits `0`.
### Exit Codes
| Code | Meaning |
| :--- | :-------------------------------------------------------------------------------------------------------------------- |
| `0` | Revoked, or nothing to revoke under `--all` |
| `1` | Network or server error |
| `2` | Usage error: no target and no `--all`, an ambiguous target, no matching session, or declining the confirmation prompt |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Command Index
Source: https://docs.dify.ai/en/cli/reference/command-index
Find any difyctl command by name, with a link to its full reference
| Command | What it does |
| :----------------------------------------------------------------------------------------------- | :--------------------------------------------------------- |
| [`auth devices list`](/en/cli/reference/auth-and-contexts#list-your-active-sessions) | List the active sessions for your account. |
| [`auth devices revoke`](/en/cli/reference/auth-and-contexts#revoke-sessions) | Revoke one session, or all but the current one. |
| [`auth list`](/en/cli/reference/auth-and-contexts#list-your-saved-contexts) | List your saved sign-in contexts. |
| [`auth login`](/en/cli/reference/auth-and-contexts#sign-in) | Sign in to a Dify host with the OAuth device flow. |
| [`auth logout`](/en/cli/reference/auth-and-contexts#sign-out) | Sign out of the active host. |
| [`auth whoami`](/en/cli/reference/auth-and-contexts#check-your-active-identity) | Print the identity you're signed in as. |
| [`describe app`](/en/cli/reference/apps#inspect-an-app) | Inspect one app's metadata and inputs. |
| [`env list`](/en/cli/reference/environment-variables#see-whats-set) | List the environment variables difyctl recognizes. |
| [`export studio-app`](/en/cli/reference/apps#export-an-app) | Export a studio app's DSL configuration as YAML. |
| [`get app`](/en/cli/reference/apps#list-your-apps) | List apps, or look up one app. |
| [`get workspace`](/en/cli/reference/workspaces#list-your-workspaces) | List the workspaces you belong to. |
| [`help`](/en/cli/reference/help) | Get help in the terminal, including machine-readable JSON. |
| [`import studio-app`](/en/cli/reference/apps#import-an-app) | Import a studio app from a DSL file or URL. |
| [`resume app`](/en/cli/reference/apps#resume-a-paused-workflow) | Resume a paused workflow run. |
| [`run app`](/en/cli/reference/apps#run-an-app) | Run an app and print the response. |
| [`skills install`](/en/cli/reference/skills#install-the-skill) | Install the difyctl skill into detected coding agents. |
| [`use account`](/en/cli/reference/auth-and-contexts#switch-the-active-account) | Switch the active account on the current host. |
| [`use host`](/en/cli/reference/auth-and-contexts#switch-the-active-host) | Switch the active Dify host. |
| [`use workspace`](/en/cli/reference/workspaces#switch-your-workspace-cloud) <Badge>Cloud</Badge> | Switch your active workspace. |
| [`version`](/en/cli/reference/version) | Show client and server versions and compatibility. |
[Global flags](/en/cli/reference/global-flags) work across commands.
For the output formats, errors, and exit codes, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
# Environment Variables
Source: https://docs.dify.ai/en/cli/reference/environment-variables
Set difyctl defaults for the current shell session with environment variables
Environment variables set defaults for the current shell session: every `difyctl` command you run in it picks them up. A command flag wins, then an environment variable. They're shell-scoped and last only as long as the session.
## Variables difyctl Reads
| Variable | What it controls | Default |
| :------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------ |
| `DIFY_CONFIG_DIR` | Where `difyctl` keeps its configuration (`hosts.yml`). | macOS and Linux: `~/.config/difyctl` (Linux honors `XDG_CONFIG_HOME`)<br /><br />Windows: `%APPDATA%\difyctl` |
| `DIFY_LIMIT` | Default page size, 1 to 200, for list commands (`get app`, `auth devices list`). The `--limit` flag wins, then this variable. | `20` |
| `DIFY_WORKSPACE_ID` | The workspace `difyctl` commands run against. Must be a UUID. See [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace) for the resolution order. | none |
| `DIFYCTL_HTTP_RETRY` | Retry attempts for idempotent requests on transient failures (`0` disables retries). [`--http-retry`](/en/cli/reference/global-flags#http-retries) overrides it. | `3` |
An invalid value fails as a usage error (exit code `2`) rather than being silently ignored, for example a non-UUID `DIFY_WORKSPACE_ID`.
<Info>
Only the variables above change `difyctl`'s behavior. The others reported by the `env list` command are recognized but currently have no effect.
</Info>
## See What's Set
```text theme={null}
difyctl env list [flags]
```
`env list` shows the current value of each `difyctl` environment variable in your shell. It reads only your local environment and never calls the server, so it works before you sign in.
### Flags
| Flag | Type | Default | Description |
| :------- | :------ | :------ | :------------------------------------------------------ |
| `--json` | boolean | `false` | Print the inventory as a JSON array instead of a table. |
<Note>
`env list` takes `--json`, not the [`-o` global flag](/en/cli/reference/global-flags).
</Note>
### Examples
Check which variables are set in the current shell:
```bash theme={null}
difyctl env list
```
Get the same inventory as JSON:
```bash theme={null}
difyctl env list --json
```
### Output
Unset variables show `<unset>`, and sensitive variables never print their value (only `<set>` or `<unset>`). With `DIFY_LIMIT=50` exported:
```text theme={null}
NAME VALUE DESCRIPTION
DIFY_CONFIG_DIR <unset> Override the config-dir resolution (precedes XDG_CONFIG_HOME on Linux).
DIFY_FORMAT <unset> Default output format for list commands (table | json | yaml | wide | name).
DIFY_HOST <unset> Default Dify host (overridden by --host).
DIFY_LIMIT 50 Default page size for list commands (1..200).
DIFY_NO_PROGRESS <unset> Suppress progress spinners. Truthy values: 1, true, yes.
DIFY_PLAIN <unset> Disable ANSI colors and decorative output. Truthy values: 1, true, yes.
DIFY_TOKEN <unset> Bearer token for non-interactive auth.
DIFY_WORKSPACE_ID <unset> Workspace ID used for difyctl commands.
DIFYCTL_HTTP_RETRY <unset> HTTP retry count for GET/PUT/DELETE. 0 disables. Overrides --http-retry flag.
```
`--json` prints a JSON array, one entry per variable, masked the same way:
```json theme={null}
[
{
"name": "DIFY_CONFIG_DIR",
"description": "Override the config-dir resolution (precedes XDG_CONFIG_HOME on Linux).",
"sensitive": false,
"value": "<unset>"
}
]
```
### Exit Codes
| Code | Meaning |
| :--- | :------ |
| `0` | Success |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Global Flags
Source: https://docs.dify.ai/en/cli/reference/global-flags
Use these flags across difyctl commands to control output format, verbosity, and retry behavior
The flags below work across `difyctl` commands. `-v` and `-h` are universal, while `-o` and `--http-retry` are accepted by most but not all. Check a command's [reference](/en/cli/reference/command-index) for the flags it accepts.
| Flag | What it does |
| :---------------------------------------- | :-------------------------------------------------------------------- |
| [`-o, --output <format>`](#output-format) | Selects the output format: `json`, `yaml`, `name`, `wide`, or `text`. |
| [`-v, --verbose`](#verbose-mode) | Turns on verbose diagnostics on stderr. |
| [`--http-retry <n>`](#http-retries) | Sets the retry budget for idempotent requests. |
| [`-h, --help`](/en/cli/reference/help) | Show the command's help instead of running it. |
<Note>
Flags always follow the command: `difyctl get app -o json` works; `difyctl -o json get app` is read as an unknown command.
</Note>
## Output Format
To see which of the five formats a command supports, check its `--help` or the flags table on its reference page. If you repeat the flag, the last value wins.
`-o` also changes how failures render: under `-o json`, errors arrive as a machine-readable JSON object on stderr.
For the format schemas, defaults, and channel rules, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
<Note>
On [`export studio-app`](/en/cli/reference/apps#export-an-app), `-o` is the output file path, not a format selector.
</Note>
## Verbose Mode
`-v` adds verbose HTTP logging to stderr and includes the `raw_response` field (the raw server response, bearer tokens redacted) in error output.
Use it when a request fails and the normal error doesn't explain why.
## HTTP Retries
`difyctl` retries idempotent requests (GET, PUT, DELETE) on transient failures: network errors and HTTP 408, 413, 500, 502, 503, and 504 responses. POST requests are never retried. A 429 (rate limited) is handled separately and exits `7`, not retried by this budget.
The default budget is 3 attempts with exponential backoff (300 ms, doubling, capped at 30 s). Use `--http-retry 0` to disable retries.
The [`DIFYCTL_HTTP_RETRY`](/en/cli/reference/environment-variables) environment variable sets the same budget; if both are set, the flag takes priority.
## `--workspace` Is Not Global <Badge>Cloud</Badge>
`--workspace <id>` is per-command: it appears on commands that target workspace data and applies to that invocation only.
For where the flag sits in the precedence chain (flag, environment variable, stored default), see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace).
# Help
Source: https://docs.dify.ai/en/cli/reference/help
Get help in the terminal with per-command docs, guide topics, and machine-readable JSON
The `difyctl` help system covers four surfaces: the [top-level overview](#get-help), [per-command and group help](#help-for-one-command-or-group), [guide topics](#guide-topics), and a [machine-readable form](#machine-readable-help) of all of them. All help prints to stdout and exits `0`.
## Get Help
Four invocations show the same top-level overview:
```bash theme={null}
difyctl
difyctl help
difyctl --help
difyctl -h
```
The overview lists every command with its one-liner, three getting-started examples, the [global flags](/en/cli/reference/global-flags), and the [guide topics](#guide-topics). For the same inventory with links into this reference, see the [Command Index](/en/cli/reference/command-index).
## Help for One Command or Group
Append `--help` to any command, or put `help` in front of it:
```bash theme={null}
difyctl run app --help
difyctl help run app
```
Per-command help shows the command's description, usage line, arguments, flags with defaults, and examples.
Name a command group instead of a command to list the group's subcommands:
```bash theme={null}
difyctl auth --help
```
```text theme={null}
COMMANDS
auth devices list List active sessions for the current bearer
auth devices revoke Revoke one or all session devices
auth list List all authenticated contexts (host + account pairs)
auth login Sign in to Dify via OAuth device flow
auth logout Log out of the active Dify host
auth whoami Print the active subject's identity
```
A name that matches neither a command, a topic, nor a group fails with `unknown help topic: <name>`, suggestions, and exit code `1`.
## Guide Topics
Long-form topics ship inside the CLI, read with `difyctl help <topic>`:
| Topic | What it covers |
| :------------ | :---------------------------------------------------------------- |
| `account` | Onboarding guidance. |
| `environment` | The CLI's own descriptions of the `DIFY_*` environment variables. |
| `agent` | The cross-command contract for agents driving `difyctl`. |
These topics are built into the CLI. For which variables `difyctl` actually reads, see [Environment Variables](/en/cli/reference/environment-variables).
## Machine-Readable Help
Every help surface accepts `-o json` and `-o yaml`. The top-level form emits the complete command surface in one document:
```bash theme={null}
difyctl help -o json
```
The document has four top-level keys:
* `bin`, `contract`: exit codes, output formats, the shape of error output, and cross-command rules
* `commands`: one descriptor per command
* `topics`: the available guide topics by name, with each topic's text read via `difyctl help <topic>`
Per-command help in JSON returns just that command's descriptor:
```bash theme={null}
difyctl auth whoami --help -o json
```
```json theme={null}
{
"command": "auth whoami",
"description": "Print the active subject's identity",
"effect": "read",
"args": [],
"flags": [
{
"name": "json",
"char": null,
"type": "boolean",
"default": false,
"multiple": false,
"options": null,
"description": "emit JSON"
}
],
"examples": [
"difyctl auth whoami",
"difyctl auth whoami --json"
],
"agentGuide": null
}
```
Each descriptor carries the command's arguments and flags with types and defaults, an `effect` label (`read`, `write`, or `destructive`), and an `agentGuide` string where one exists. This is how coding agents discover `difyctl`.
## Exit Codes
| Code | Meaning |
| :--- | :--------------------------------- |
| `0` | Help printed |
| `1` | Unknown help topic or command name |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Output Formats and Exit Codes
Source: https://docs.dify.ai/en/cli/reference/output-formats-and-exit-codes
What each difyctl output format emits, how stdout and stderr split, how errors are structured, and what every exit code means
`difyctl` is built to be scripted: data goes to stdout while everything else goes to stderr, the [`-o` global flag](/en/cli/reference/global-flags) selects the output format, and failures exit with a predictable code.
## Output Formats
`-o <format>` selects how a command renders its result on stdout. Each command supports a subset of the five formats, listed in its `--help` and the Flags table on its reference page.
| Format | What stdout gets |
| :----- | :------------------------------------------------------------------------------------------------------------------------------------------ |
| `json` | The result as pretty-printed JSON (2-space indent). Unicode characters appear as-is, and null fields are an explicit `null`, never omitted. |
| `yaml` | The same data as YAML. |
| `name` | Bare resource IDs, one per line. Built for shell loops; no parsing needed. |
| `wide` | The default table plus extra columns. For example, `get app -o wide` adds a `WORKSPACE` column. |
| `text` | Human-readable text. The default for single-resource commands such as `describe app` and `run app`. |
Without `-o`, list commands such as `get app` print an aligned text table and other commands print text.
The JSON shapes are stable: list commands such as `get app` print a JSON object with the rows in an array, and two runs of the same command return the same top-level structure. For a command's exact JSON shape, see its reference page.
## Output Channels
| Channel | What lands there |
| :------ | :------------------------------------------------------------------------------------------------------------------------------ |
| stdout | Data: tables, JSON and YAML documents, IDs, run output, exported DSL |
| stderr | Everything else: errors, hints, progress spinners, status lines such as `✓ form submitted`, and reasoning streamed by `--think` |
The rules worth scripting against:
* On failure, stdout stays empty. You never have to filter error text out of captured data.
* On success, `get` and `describe` commands leave stderr empty; `run app` and `resume app` may print hints there.
* Progress spinners appear only in a terminal, on stderr, and are suppressed under `-o json`, `-o yaml`, and `-o name`.
* Piped output carries no ANSI color codes.
* If the consumer of a pipe exits early (`difyctl get app -o name | head -2`), `difyctl` exits `0` rather than failing on the broken pipe.
## Errors
Errors go to stderr. In the default human format, an error is a `code: message` line plus optional detail lines:
```text theme={null}
not_logged_in: not logged in
hint: run 'difyctl auth login'
```
When an HTTP request was involved, `request: <METHOD> <url>` and `http_status: <n>` lines follow.
When the server's reply carries Dify's standard error body, the header line shows the server's more specific code (`not_found`, `invalid_param`) instead of the CLI's transport-level code.
Per-field validation details follow as indented lines, and the server's hint appears when `difyctl` has none of its own.
Under `-o json`, the same error becomes a single-line JSON object on stderr:
```json theme={null}
{"error":{"code":"not_logged_in","message":"not logged in","hint":"run 'difyctl auth login'"}}
```
Only `-o json` switches error rendering: `-o yaml` failures print the human format.
| Field | Present | Meaning |
| :-------------- | :------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `code` | always | Stable machine-readable error code. Branch on this, never on message text. |
| `message` | always | Human-readable description. |
| `hint` | when known | The fastest fix, often a copy-pasteable command. |
| `http_status` | on HTTP failures | Status code of the failed request. |
| `method`, `url` | on HTTP failures | The request that failed. |
| `raw_response` | only with `-v` | The raw server response body, bearer tokens redacted. |
| `server` | on HTTP failures, when the reply is Dify's standard error body | The server's own error: `code`, `message`, `status`, plus optional `hint` and `details`. <br /><br />The top-level `code` stays the CLI's stable transport-level code; `server.code` carries the server's finer-grained reason. |
For what each code means and how to fix it, see [Troubleshooting](/en/cli/troubleshooting).
## Exit Codes
| Code | Meaning | Examples |
| :--- | :----------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `0` | Success | Also `--help`, `version`, and a workflow run that [paused for human input](#a-paused-workflow-run-exits-0). |
| `1` | Generic failure | Network and server errors (`network_connection`, `server_5xx`, `server_4xx_other`), unknown commands, unknown flags, an unreachable OS keychain (`keyring_unavailable`). |
| `2` | Usage error | An invalid flag value (`-o table`, `--limit 0`), a missing argument, a non-UUID app or workspace ID, `--inputs` that isn't a JSON object. |
| `4` | Authentication error | `not_logged_in`, `auth_expired`, `token_expired`, `access_denied`. |
| `6` | Version or compatibility error | `version_skew` (the server is older than this `difyctl` supports, or the server rejected this `difyctl` as too old with HTTP 426), `unsupported_endpoint` (the server lacks an endpoint this build needs), or an unreadable config file (`config_schema_unsupported`). |
| `7` | Rate limited | An HTTP 429 (`rate_limited`), kept distinct from `1` so a script can back off and retry. |
| `64` | Compatibility gate failed | Only [`version --check-compat`](/en/cli/reference/version#gate-scripts-on-compatibility): the server was not confirmed compatible. |
One nuance for strict scripts: parser-level mistakes (an unknown command, an unknown flag, a flag missing its value) exit `1` with a plain-text message, while an invalid value for a known flag exits `2`.
### A Paused Workflow Run Exits 0
A Workflow or Chatflow app can pause mid-run to collect human input. The pause is a successful outcome, not a failure: `run app` and `resume app` exit `0` and print a paused payload to stdout.
To detect a pause in a script or an agent, run with `-o json` and check stdout for `"status": "paused"`; don't branch on the exit code.
For the payload shape and the resume protocol, see [When a Workflow Pauses](/en/cli/reference/apps#when-a-workflow-pauses) on the Apps reference.
# Skills
Source: https://docs.dify.ai/en/cli/reference/skills
Install the agent skill so coding agents can drive difyctl
[`skills install`](#install-the-skill) writes the `difyctl` skill (a `SKILL.md` file) into the skill directories of the coding agents on your machine.
The skill deliberately lists no commands: it points the agent at `difyctl help -o json` and lets it discover the live command surface itself.
See the [help reference](/en/cli/reference/help#machine-readable-help) for that discovery surface, and [Install the difyctl Skill](/en/cli/integrate-agents/install-the-difyctl-skill) for the full integration.
## Install the Skill
```text theme={null}
difyctl skills install [dir] [flags]
```
This command is fully local: it needs no sign-in and never contacts a server.
### Arguments
* `dir`: optional. Install into this single directory, bypassing agent detection. The skill lands at `<dir>/SKILL.md`. Cannot be combined with `--agent`.
### Flags
| Flag | Type | Default | Description |
| :---------- | :----------------- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `-y, --yes` | boolean | `false` | Write the skill. Without it, the command is a dry run: it lists where the skill would land and writes nothing. |
| `--agent` | string, repeatable | none | Restrict the install to specific detected agents, using the names from [Agent Detection](#agent-detection).<br /><br />With no `--agent`, the skill installs into every detected agent. To install into several agents but not all, repeat the flag or pass a comma-separated list.<br /><br />Naming an agent that isn't detected is a usage error. |
| `--stdout` | boolean | `false` | Print the skill to stdout and write nothing. Cannot be combined with `--yes`, `--agent`, or `dir`. |
### Examples
Preview where the skill would be installed (dry run, the default):
```bash theme={null}
difyctl skills install
```
Install into every detected agent:
```bash theme={null}
difyctl skills install --yes
```
Install into one agent only:
```bash theme={null}
difyctl skills install --yes --agent claude-code
```
Install into several specific agents (repeat the flag or comma-separate):
```bash theme={null}
difyctl skills install --yes --agent claude-code --agent cursor
```
Install into an explicit directory, for an agent the CLI doesn't detect:
```bash theme={null}
difyctl skills install ./my-skills/difyctl --yes
```
Print the skill without writing anything:
```bash theme={null}
difyctl skills install --stdout
```
### Agent Detection
Detection checks whether each agent's configuration directory exists. The CLI never probes `PATH` or launches anything. The skill is written to each agent's documented user-level skill location:
| Agent | Detected when | Skill lands in |
| :------------ | :-------------------------- | :------------------------------------------- |
| `claude-code` | `~/.claude` exists | `~/.claude/skills/difyctl/SKILL.md` |
| `codex` | `~/.codex` exists | `~/.agents/skills/difyctl/SKILL.md` |
| `opencode` | `~/.config/opencode` exists | `~/.config/opencode/skills/difyctl/SKILL.md` |
| `cursor` | `~/.cursor` exists | `~/.cursor/skills/difyctl/SKILL.md` |
| `pi` | `~/.pi` exists | `~/.pi/agent/skills/difyctl/SKILL.md` |
An agent that's installed but has never been launched may not have its configuration directory yet. Install into its skill directory explicitly with `difyctl skills install <dir>`.
### Output
A dry run lists the detected agents and the target paths, then tells you how to proceed:
```text theme={null}
Detected 2 agents: claude-code, cursor
would write to claude-code: /Users/you/.claude/skills/difyctl/SKILL.md
would write to cursor: /Users/you/.cursor/skills/difyctl/SKILL.md
Re-run with --yes to write all, or --agent <name> to write only some.
Agent not listed? Install into its directory with `difyctl skills install <dir>`.
```
With `--yes`, each write is confirmed:
```text theme={null}
wrote /Users/you/.claude/skills/difyctl/SKILL.md
wrote /Users/you/.cursor/skills/difyctl/SKILL.md
```
When nothing is detected, the command explains the alternatives and exits 0:
```text theme={null}
No agents detected (looked for ~/.claude, ~/.codex, ~/.config/opencode, ~/.cursor, ~/.pi).
Install into a directory manually with `difyctl skills install <dir>`, or
print the skill with `difyctl skills install --stdout`.
```
The installed skill carries a version stamp matching the CLI that wrote it. Re-running `skills install --yes` after upgrading replaces the file with the current version. Re-running is always safe.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------------------------------------------------------------------ |
| `0` | Success, including a dry run and the nothing-detected case |
| `1` | Local failure, such as a target directory that isn't writable |
| `2` | Usage error: `--stdout` combined with a write option, `dir` combined with `--agent`, or `--agent` naming an agent that isn't detected |
# Version
Source: https://docs.dify.ai/en/cli/reference/version
Check your difyctl build and its compatibility with your Dify server
Run [`difyctl version`](#check-client-and-server-versions) to see which `difyctl` build you have and whether it works with your Dify server. It prints the client build, probes your active host, and reports a [compatibility verdict](#compatibility-verdicts).
In a script, [`--check-compat`](#gate-scripts-on-compatibility) turns that verdict into an exit code.
## Check Client and Server Versions
```text theme={null}
difyctl version [flags]
```
### Flags
| Flag | Type | Default | Description |
| :--------------- | :------ | :------ | :------------------------------------------------------- |
| `--short` | boolean | false | Print only the client semver (no server probe) and exit. |
| `--client` | boolean | false | Skip the server probe, so the verdict reports `unknown`. |
| `--check-compat` | boolean | false | Exit `64` unless the verdict is `compatible`. |
| `-o <format>` | string | text | Output format: `text`, `json`, or `yaml`. |
### Examples
Print the full report:
```bash theme={null}
difyctl version
```
Print just the client version, for scripts and bug reports:
```bash theme={null}
difyctl version --short
```
### Output
| Format | What stdout gets |
| :------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default (`text`) | The full report: a `Client` block, a `Server` block, and a one-line `Compatibility` verdict. Builds on any channel other than `stable` append a warning recommending the stable channel. |
| `-o json`, `-o yaml` | The same report as three objects: <ul><li>`client` (`version`, `commit`, `buildDate`, `channel`, `platform`, `arch`)</li><li>`server` (`endpoint`, `reachable`, and on success `version` and `edition`)</li><li>`compat` (`minDify`, `maxDify`, `status`, `detail`)</li></ul> |
The default `text` report:
```text theme={null}
Client:
Version: 0.2.0-alpha (channel: alpha)
Commit: 9f3c2ab (built 2026-06-05)
Platform: darwin/arm64
Compat: dify >=1.16.0, <=1.16.0
Server:
Endpoint: https://cloud.dify.ai
Version: 1.16.0 (cloud)
Compatibility: ok — server 1.16.0 in [1.16.0, 1.16.0]
```
`--short` prints only the client semver:
```text theme={null}
0.2.0-alpha
```
`-o json`:
```json theme={null}
{
"client": {
"version": "0.2.0-alpha",
"commit": "9f3c2ab",
"buildDate": "2026-06-05",
"channel": "alpha",
"platform": "darwin",
"arch": "arm64"
},
"server": {
"endpoint": "https://cloud.dify.ai",
"reachable": true,
"version": "1.16.0",
"edition": "CLOUD"
},
"compat": {
"minDify": "1.16.0",
"maxDify": "1.16.0",
"status": "compatible",
"detail": "server 1.16.0 in [1.16.0, 1.16.0]"
}
}
```
This command exits `0` even when the server is unreachable or incompatible: the verdict is the report, not an error. Pass `--check-compat` (below) to turn it into an exit code. Other commands act on the verdict; see [How Commands React to an Incompatible Server](#how-commands-react-to-an-incompatible-server).
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------ |
| `0` | Report printed, whatever the verdict |
| `64` | With `--check-compat`: the verdict was not `compatible` |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Compatibility Verdicts
`difyctl version` compares your build against the server's version and reports one of four verdicts. You don't need to be signed in, but you do need a stored host to probe.
The `text` report prints the **Shown as** label on its `Compatibility:` line; `-o json` reports the verdict name in `status`.
| Verdict | Shown as | Meaning |
| :----------- | :------------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------- |
| `compatible` | `ok` | The server version is inside the range this build supports. |
| `too_old` | `incompatible (server too old)` | The server is older than the minimum this build supports. |
| `too_new` | `incompatible (server too new)` | The server is newer than the maximum this build was tested against. |
| `unknown` | `unknown` | No verdict: no host configured, the server is unreachable, the probe was skipped with `--client`, or the server's version didn't parse. |
The `detail` field spells out the case, for example `server 1.14.0 is older than the minimum 1.16.0` or `server 1.16.0 in [1.16.0, 1.16.0]`.
## How Commands React to an Incompatible Server
`difyctl version` only reports the verdict. Every command that contacts the server acts on it before running, so a `too_old` server stops those commands until you resolve the mismatch:
* **`too_old`**: the command stops with exit [`6`](/en/cli/reference/output-formats-and-exit-codes) before doing its work, and tells you to upgrade the Dify server to at least the minimum this build supports (or [install the `difyctl` that matches your server](/en/cli/install)).
* **`too_new`**: the command runs; in an interactive terminal with text output, it also prints a throttled one-line warning to stderr.
* **`unknown`**: the command runs; there is nothing to gate on.
A server that clears the minimum version (`compatible` or `too_new`) is cached for about an hour per host, so the block check isn't repeated on every command. A `too_old` server is never cached, so it's re-checked each time and starts working as soon as you upgrade it.
Signing in with [`auth login`](/en/cli/reference/auth-and-contexts) runs the same check before it stores a session, so a mismatch surfaces at sign-in rather than on your first command.
The checks run in both directions: the verdicts above are `difyctl` judging your server, and your server also judges `difyctl`.
If your client is older than the server accepts, the server rejects the request with HTTP `426` and `difyctl` exits `6` with an upgrade message. This is why upgrading your Dify server can break an older `difyctl`: the server refuses the old client, even though that client's own verdict on a newer server is only a warning.
So the reliable path is to keep `difyctl` matched to your server: a newer server is tolerated with a warning, but an older one is refused.
## Gate Scripts on Compatibility
`--check-compat` makes the verdict scriptable: anything other than `compatible`, including every `unknown` case, exits `64`. `difyctl version` always probes the server live and never reads the compatibility cache, so a scripted gate reflects the current version; the flag only turns that verdict into an exit code.
The full report still goes to stdout in your chosen format, and the one-line reason goes to stderr, so `difyctl version -o json --check-compat | jq` works the same on both outcomes.
```bash theme={null}
difyctl version --check-compat || echo "difyctl and this Dify server are not a confirmed match"
```
Exit code `64` is specific to this flag. No other `difyctl` failure uses it.
# Workspaces
Source: https://docs.dify.ai/en/cli/reference/workspaces
List your workspaces, switch the active one, and understand how difyctl resolves which workspace to use
`difyctl` works in one active workspace at a time, taken from a flag, an environment variable, or your stored default. For the order those take priority, see [How difyctl Picks a Workspace](#how-difyctl-picks-a-workspace).
* [`difyctl get workspace`](#list-your-workspaces) lists the workspaces you belong to
* [`use workspace`](#switch-your-workspace-cloud) switches the active one <Badge>Cloud</Badge>
Both accept the [global flags](/en/cli/reference/global-flags).
## List Your Workspaces
```text theme={null}
difyctl get workspace [flags]
```
### Flags
| Flag | Type | Default | Description |
| :------------ | :----- | :------ | :------------------------------------------------------------------------------------- |
| `-o <format>` | string | none | Output format: `json`, `yaml`, `name`, or `wide`. Omit the flag for the default table. |
### Examples
See your workspaces and which one is active:
```bash theme={null}
difyctl get workspace
```
Get the full list as JSON for scripts:
```bash theme={null}
difyctl get workspace -o json
```
Print workspace IDs only, one per line:
```bash theme={null}
difyctl get workspace -o name
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------------------- |
| default | An aligned table. `CURRENT` marks your active workspace with `*`, and `ROLE` is your role in each one. |
| `-o wide` | The same columns. Workspaces have no wide-only columns. |
| `-o json`, `-o yaml` | A `workspaces` array, each entry carrying `id`, `name`, `role`, `status`, and `current`. |
| `-o name` | The workspace IDs, one per line. |
Default table:
```text theme={null}
ID NAME ROLE STATUS CURRENT
b4e8d2a6-7c3f-4a1e-9d5b-8f2c6e0a4d7b Acme Team owner normal *
9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c Marketing normal normal
```
`-o json`:
```json theme={null}
{
"workspaces": [
{
"id": "b4e8d2a6-7c3f-4a1e-9d5b-8f2c6e0a4d7b",
"name": "Acme Team",
"role": "owner",
"status": "normal",
"current": true
},
{
"id": "9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c",
"name": "Marketing",
"role": "normal",
"status": "normal",
"current": false
}
]
}
```
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------- |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as an unsupported `-o` value |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Switch Your Workspace <Badge>Cloud</Badge>
```text theme={null}
difyctl use workspace [workspace-id] [flags]
```
`use workspace` switches your active workspace on the server first, then updates the stored default in `hosts.yml`. If the switch fails (the workspace doesn't exist, or you're not a member), your local state is left untouched.
<Tip>
For the everyday invocation, see [Switch Your Workspace](/en/cli/common-tasks#switch-your-workspace-cloud) in Common Tasks.
</Tip>
### Arguments
* `workspace-id`: the workspace to switch to, from [`get workspace`](#list-your-workspaces). In a terminal, omit it to pick from your workspaces, the current one marked `*`. In a non-interactive session (script, CI, pipe), it's required.
### Flags
Only the [global flags](/en/cli/reference/global-flags).
### Examples
Pick interactively from your workspaces:
```bash theme={null}
difyctl use workspace
```
Or look up the target yourself, then switch by ID (the form that works in scripts):
```bash theme={null}
difyctl get workspace
difyctl use workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
For a single command against another workspace, skip switching and pass `--workspace` instead:
```bash theme={null}
difyctl get app --workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
### Output
On success, the new active workspace is confirmed on stdout:
```text theme={null}
✓ Switched to Marketing (9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c)
```
The switch persists: every subsequent command runs against the new workspace until you switch again.
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------------------------------------------------- |
| `0` | Success |
| `1` | Workspace not found, or another server error |
| `2` | Usage error, such as omitting `workspace-id` where there's no terminal to pick in |
| `4` | Authentication failure, or no workspaces available when `use workspace` opens its picker |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## How difyctl Picks a Workspace
Apps live in exactly one workspace, so every command that targets one needs a workspace to run against. `difyctl` resolves it in this order, taking the first value it finds:
1. The `--workspace <id>` flag on the command itself. Applies to that invocation only.
2. The [`DIFY_WORKSPACE_ID`](/en/cli/reference/environment-variables) environment variable.
3. Your stored default, written to `hosts.yml` in the config directory when you sign in and updated by [`use workspace`](#switch-your-workspace-cloud).
If none of these yields a workspace, the command fails with exit code `2`.
Workspace IDs are UUIDs, so pass an ID from [`get workspace`](#list-your-workspaces), not a workspace name. A value that isn't a UUID fails as a usage error.
# Troubleshooting
Source: https://docs.dify.ai/en/cli/troubleshooting
Fix common difyctl errors with their explanations, exit codes, and solutions
When `difyctl` encounters an error, it writes a message to stderr. With `-o json` active, errors are also single-line JSON with a stable `code` field and an actionable `hint`.
For the full exit-code table and error object shape, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
## Version Compatibility
### `version_skew` (difyctl and the server don't match)
`difyctl` ships with each Dify release and is matched to a server version, so a version change on either side can leave the two out of sync. It surfaces in two ways, both exiting `6`:
* **Your Dify server was upgraded** and your existing `difyctl` is now too old. The server rejects it with HTTP `426` and prints an upgrade message.
* **Your `difyctl` is newer than your server**, so it stops before sending the request, reporting that the server is older than it supports.
1. Confirm it's a version mismatch:
```bash theme={null}
difyctl version
```
A `Compatibility: incompatible …` line, or an upgrade message, confirms it.
2. Reinstall `difyctl` so it matches your server: set `DIFY_VERSION` to your server's Dify release tag (or omit it if your server runs the latest release), then re-run the install script. See [Install](/en/cli/install) for details.
Exit code: `6`.
## Authentication Errors
### `auth_expired`
Your session has expired and `difyctl` can no longer make authenticated requests.
1. Re-authenticate:
```bash theme={null}
difyctl auth login
```
2. Re-run the failed command.
Exit code: `4`.
### `not_logged_in`
No active session exists for the requested host.
1. Sign in:
```bash theme={null}
difyctl auth login --host <url>
```
2. Re-run the failed command.
Exit code: `4`.
### `access_denied`
You denied the sign-in request, or canceled it before approving, so nothing was authorized.
Re-run and approve the request:
```bash theme={null}
difyctl auth login
```
Exit code: `4`.
## App Errors
### App not found (HTTP 404)
The App ID you specified doesn't exist or isn't accessible to your token. Surfaces as `server_4xx_other` with HTTP status 404.
1. List apps you can access:
```bash theme={null}
difyctl get app
```
2. Verify the ID and re-run.
Exit code: `1`.
### Service API disabled (HTTP 403 from server)
The app exists, but its Service API is turned off in the Dify console. The app owner must enable it. A 403 surfaces as `server_4xx_other`.
Exit code: `1`.
## Workflow Errors
### Workflow validation error (HTTP 422)
A Workflow app rejected your inputs. The error message lists which required inputs are missing or invalid.
1. Inspect the app's input schema:
```bash theme={null}
difyctl describe app <id>
```
2. Update your `--inputs` JSON to match.
Exit code: `1`.
# Agent Strategy Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin
Build a Function Calling agent strategy from scratch, with a worked example showing how to give an LLM tools and let it autonomously fetch the current time
An **Agent Strategy Plugin** gives an LLM the reasoning and decision-making logic to choose tools, call them, and handle their results, so it can solve problems autonomously.
This guide walks through building a **Function Calling** strategy that lets the model fetch the current time on its own.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
For details on preparing the plugin development tool, see [CLI](/en/develop-plugin/getting-started/cli).
<Tip>
Run `dify version` in your terminal to confirm that the scaffolding tool is installed.
</Tip>
***
## 1. Initialize the Plugin Template
Run the following command to create a development template for your Agent plugin:
```bash theme={null}
dify plugin init
```
Follow the on-screen prompts; the comments below explain each choice.
```bash theme={null}
➜ Dify Plugins Developing dify plugin init
Edit profile of the plugin
Plugin name (press Enter to next step): # Enter the plugin name
Author (press Enter to next step): Author name # Enter the plugin author
Description (press Enter to next step): Description # Enter the plugin description
---
Select the language you want to use for plugin development, and press Enter to con
BTW, you need Python 3.12+ to develop the Plugin if you choose Python.
-> python # Select Python environment
go (not supported yet)
---
Based on the ability you want to extend, we have divided the Plugin into four type
- Tool: It's a tool provider, but not only limited to tools, you can implement an
- Model: Just a model provider, extending others is not allowed.
- Extension: Other times, you may only need a simple http service to extend the fu
- Agent Strategy: Implement your own logics here, just by focusing on Agent itself
What's more, we have provided the template for you, you can choose one of them b
tool
-> agent-strategy # Select Agent strategy template
llm
text-embedding
---
Configure the permissions of the plugin, use up and down to navigate, tab to sel
Backwards Invocation:
Tools:
Enabled: [✔] You can invoke tools inside Dify if it's enabled # Enabled by default
Models:
Enabled: [✔] You can invoke models inside Dify if it's enabled # Enabled by default
LLM: [✔] You can invoke LLM models inside Dify if it's enabled # Enabled by default
Text Embedding: [✘] You can invoke text embedding models inside Dify if it'
Rerank: [✘] You can invoke rerank models inside Dify if it's enabled
...
```
Initialization creates a folder with everything you need for plugin development:
```text theme={null}
├── GUIDE.md # User guide and documentation
├── PRIVACY.md # Privacy policy and data handling guidelines
├── README.md # Project overview and setup instructions
├── _assets/ # Static assets directory
│ └── icon.svg # Agent strategy provider icon/logo
├── main.py # Main application entry point
├── manifest.yaml # Basic plugin configuration
├── provider/ # Provider configurations directory
│ └── basic_agent.yaml # Your agent provider settings
├── requirements.txt # Python dependencies list
└── strategies/ # Strategy implementation directory
├── basic_agent.py # Basic agent strategy implementation
└── basic_agent.yaml # Basic agent strategy configuration
```
All key functionality for this plugin is in the `strategies/` directory.
***
## 2. Develop the Plugin
Agent Strategy Plugin development revolves around two files:
* **Plugin Declaration**: `strategies/basic_agent.yaml`
* **Plugin Implementation**: `strategies/basic_agent.py`
### 2.1 Define Parameters
Start by declaring the plugin's parameters in `strategies/basic_agent.yaml`. These parameters power the plugin's core features, such as calling an LLM or using tools.
We recommend starting with these four parameters:
* **`model`**: The large language model to call (e.g., GPT-4, GPT-4o-mini).
* **`tools`**: A list of tools that enhance your plugin's functionality.
* **`query`**: The user input or prompt content sent to the model.
* **`maximum_iterations`**: The maximum iteration count, which prevents excessive computation.
Example:
```yaml theme={null}
identity:
name: basic_agent # the name of the agent_strategy
author: novice # the author of the agent_strategy
label:
en_US: BasicAgent # the English label of the agent_strategy
description:
en_US: BasicAgent # the English description of the agent_strategy
parameters:
- name: model # the name of the model parameter
type: model-selector # model-type
scope: tool-call&llm # the scope of the parameter
required: true
label:
en_US: Model
zh_Hans: 模型
pt_BR: Model
- name: tools # the name of the tools parameter
type: array[tools] # the type of tool parameter
required: true
label:
en_US: Tools list
zh_Hans: 工具列表
pt_BR: Tools list
- name: query # the name of the query parameter
type: string # the type of query parameter
required: true
label:
en_US: Query
zh_Hans: 查询
pt_BR: Query
- name: maximum_iterations
type: number
required: false
default: 5
label:
en_US: Maxium Iterations
zh_Hans: 最大迭代次数
pt_BR: Maxium Iterations
max: 50 # if you set the max and min value, the display of the parameter will be a slider
min: 1
extra:
python:
source: strategies/basic_agent.py
```
Dify automatically renders a configuration interface from these parameter declarations:
<Frame>
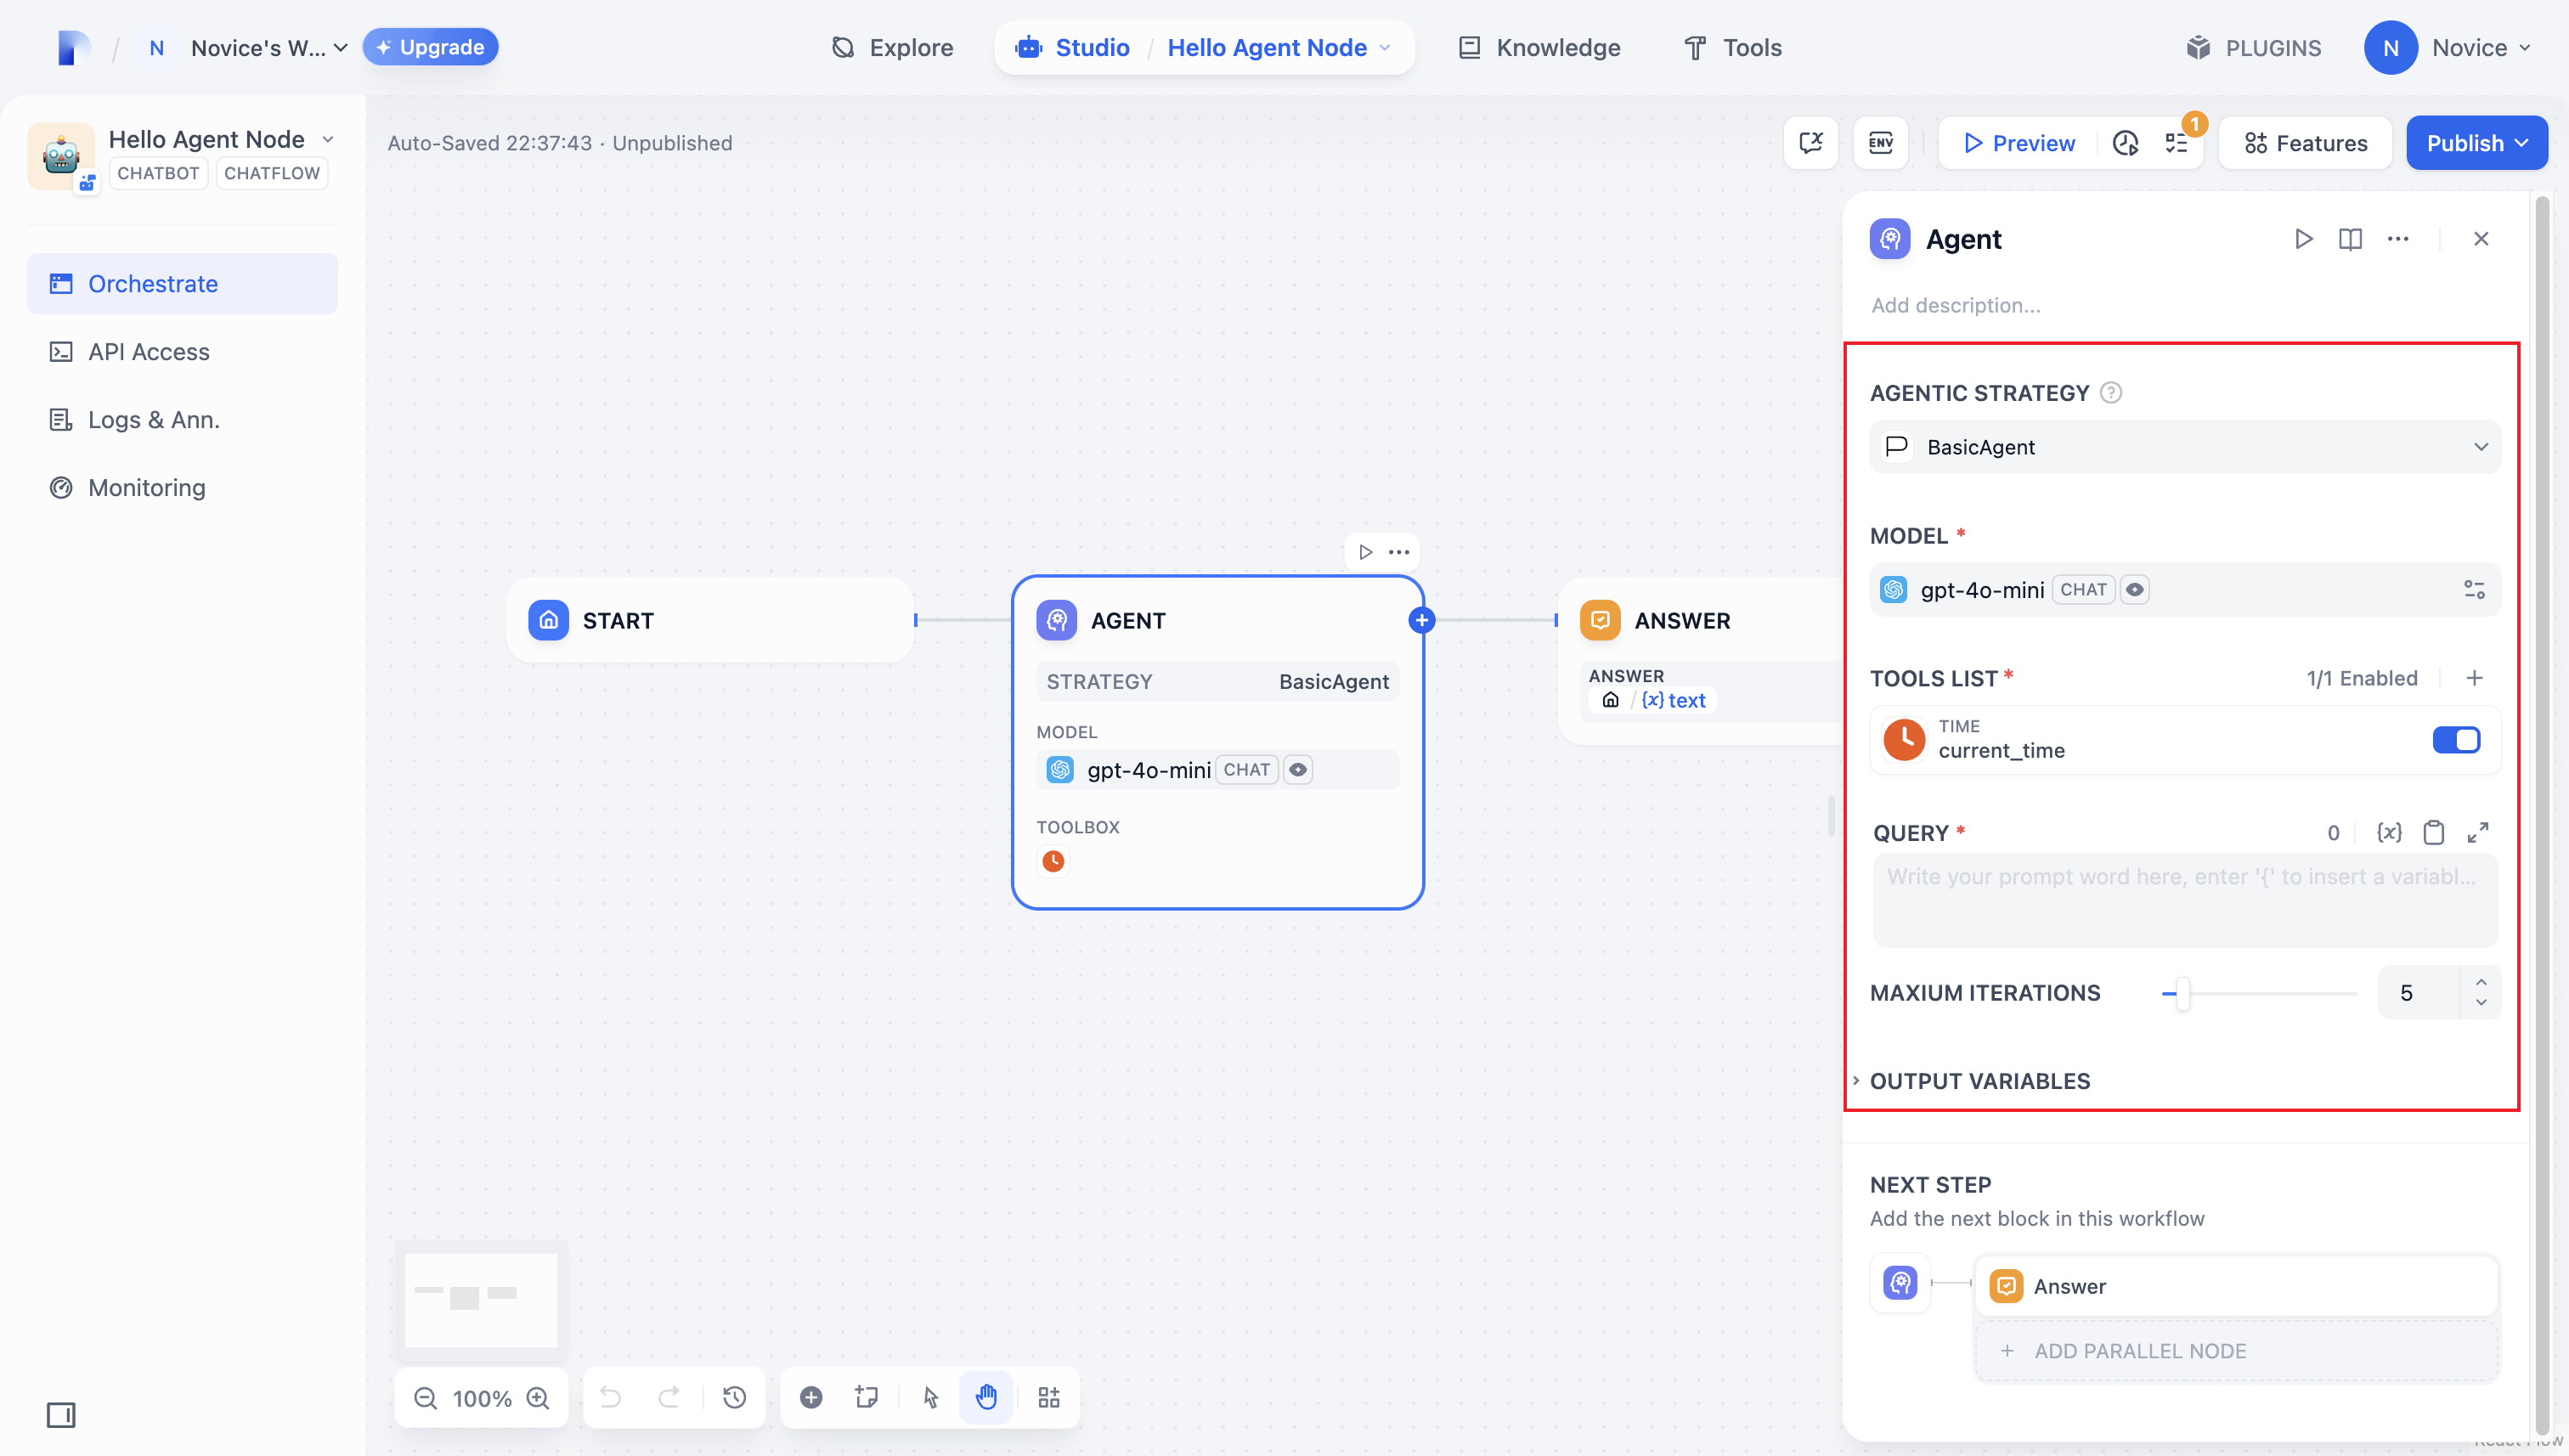
</Frame>
### 2.2 Retrieve Parameters and Execute
When users fill out these fields, your plugin receives the submitted values. In `strategies/basic_agent.py`, define a Pydantic model that validates the incoming parameters:
```python theme={null}
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
```
Then parse the parameters in `_invoke` and run your strategy logic:
```python theme={null}
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
```
## 3. Invoke the Model
Invoking the model is central to an Agent strategy. Use `session.model.llm.invoke()` from the SDK to call an LLM for text generation, dialogue, and similar tasks.
For the LLM to drive tool calls, it must output structured arguments that match each tool's interface—input the tool can accept, derived from the user's instructions.
The method takes the following parameters:
* `model`
* `prompt_messages`
* `tools`
* `stop`
* `stream`
Method signature:
```python theme={null}
def invoke(
self,
model_config: LLMModelConfig,
prompt_messages: list[PromptMessage],
tools: list[PromptMessageTool] | None = None,
stop: list[str] | None = None,
stream: bool = True,
) -> Generator[LLMResultChunk, None, None] | LLMResult:...
```
For the full implementation, see the **Invoke Model** tab in the [sample code](#sample-code) below.
With this in place, the plugin calls the LLM whenever a user enters a command, builds tool-invocation parameters from the model's output, and lets the model dispatch the configured tools to complete complex tasks.
<Frame>
</Frame>
## 4. Invoke Tools
Once the model has produced tool parameters, the plugin must actually call the tools. Use `session.tool.invoke()` to make those requests.
The method takes the following parameters:
* `provider`
* `tool_name`
* `parameters`
Method signature:
```python theme={null}
def invoke(
self,
provider_type: ToolProviderType,
provider: str,
tool_name: str,
parameters: dict[str, Any],
) -> Generator[ToolInvokeMessage, None, None]:...
```
To let the LLM generate the tool-call parameters itself, feed the model's extracted tool calls into your invocation code:
```python theme={null}
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
```
Your plugin can now perform Function Calling automatically—for instance, retrieving the current time.
<Frame>
</Frame>
## 5. Create Logs
Complex tasks usually take multiple steps, and you need to track each step's result to analyze decisions and refine your strategy. The SDK's `create_log_message` and `finish_log_message` let you record state before and after each call, which speeds up problem diagnosis.
For example:
* Log a "starting model call" message before calling the model to show execution progress.
* Log a "call succeeded" message once the model responds, so its output can be traced end to end.
```python theme={null}
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
)
yield model_log
self.session.model.llm.invoke(...)
yield self.finish_log_message(
log=model_log,
data={
"output": response,
"tool_name": tool_call_names,
"tool_input": tool_call_inputs,
},
metadata={
"started_at": model_started_at,
"finished_at": time.perf_counter(),
"elapsed_time": time.perf_counter() - model_started_at,
"provider": params.model.provider,
},
)
```
Once set up, the workflow log shows the execution results:
<Frame>
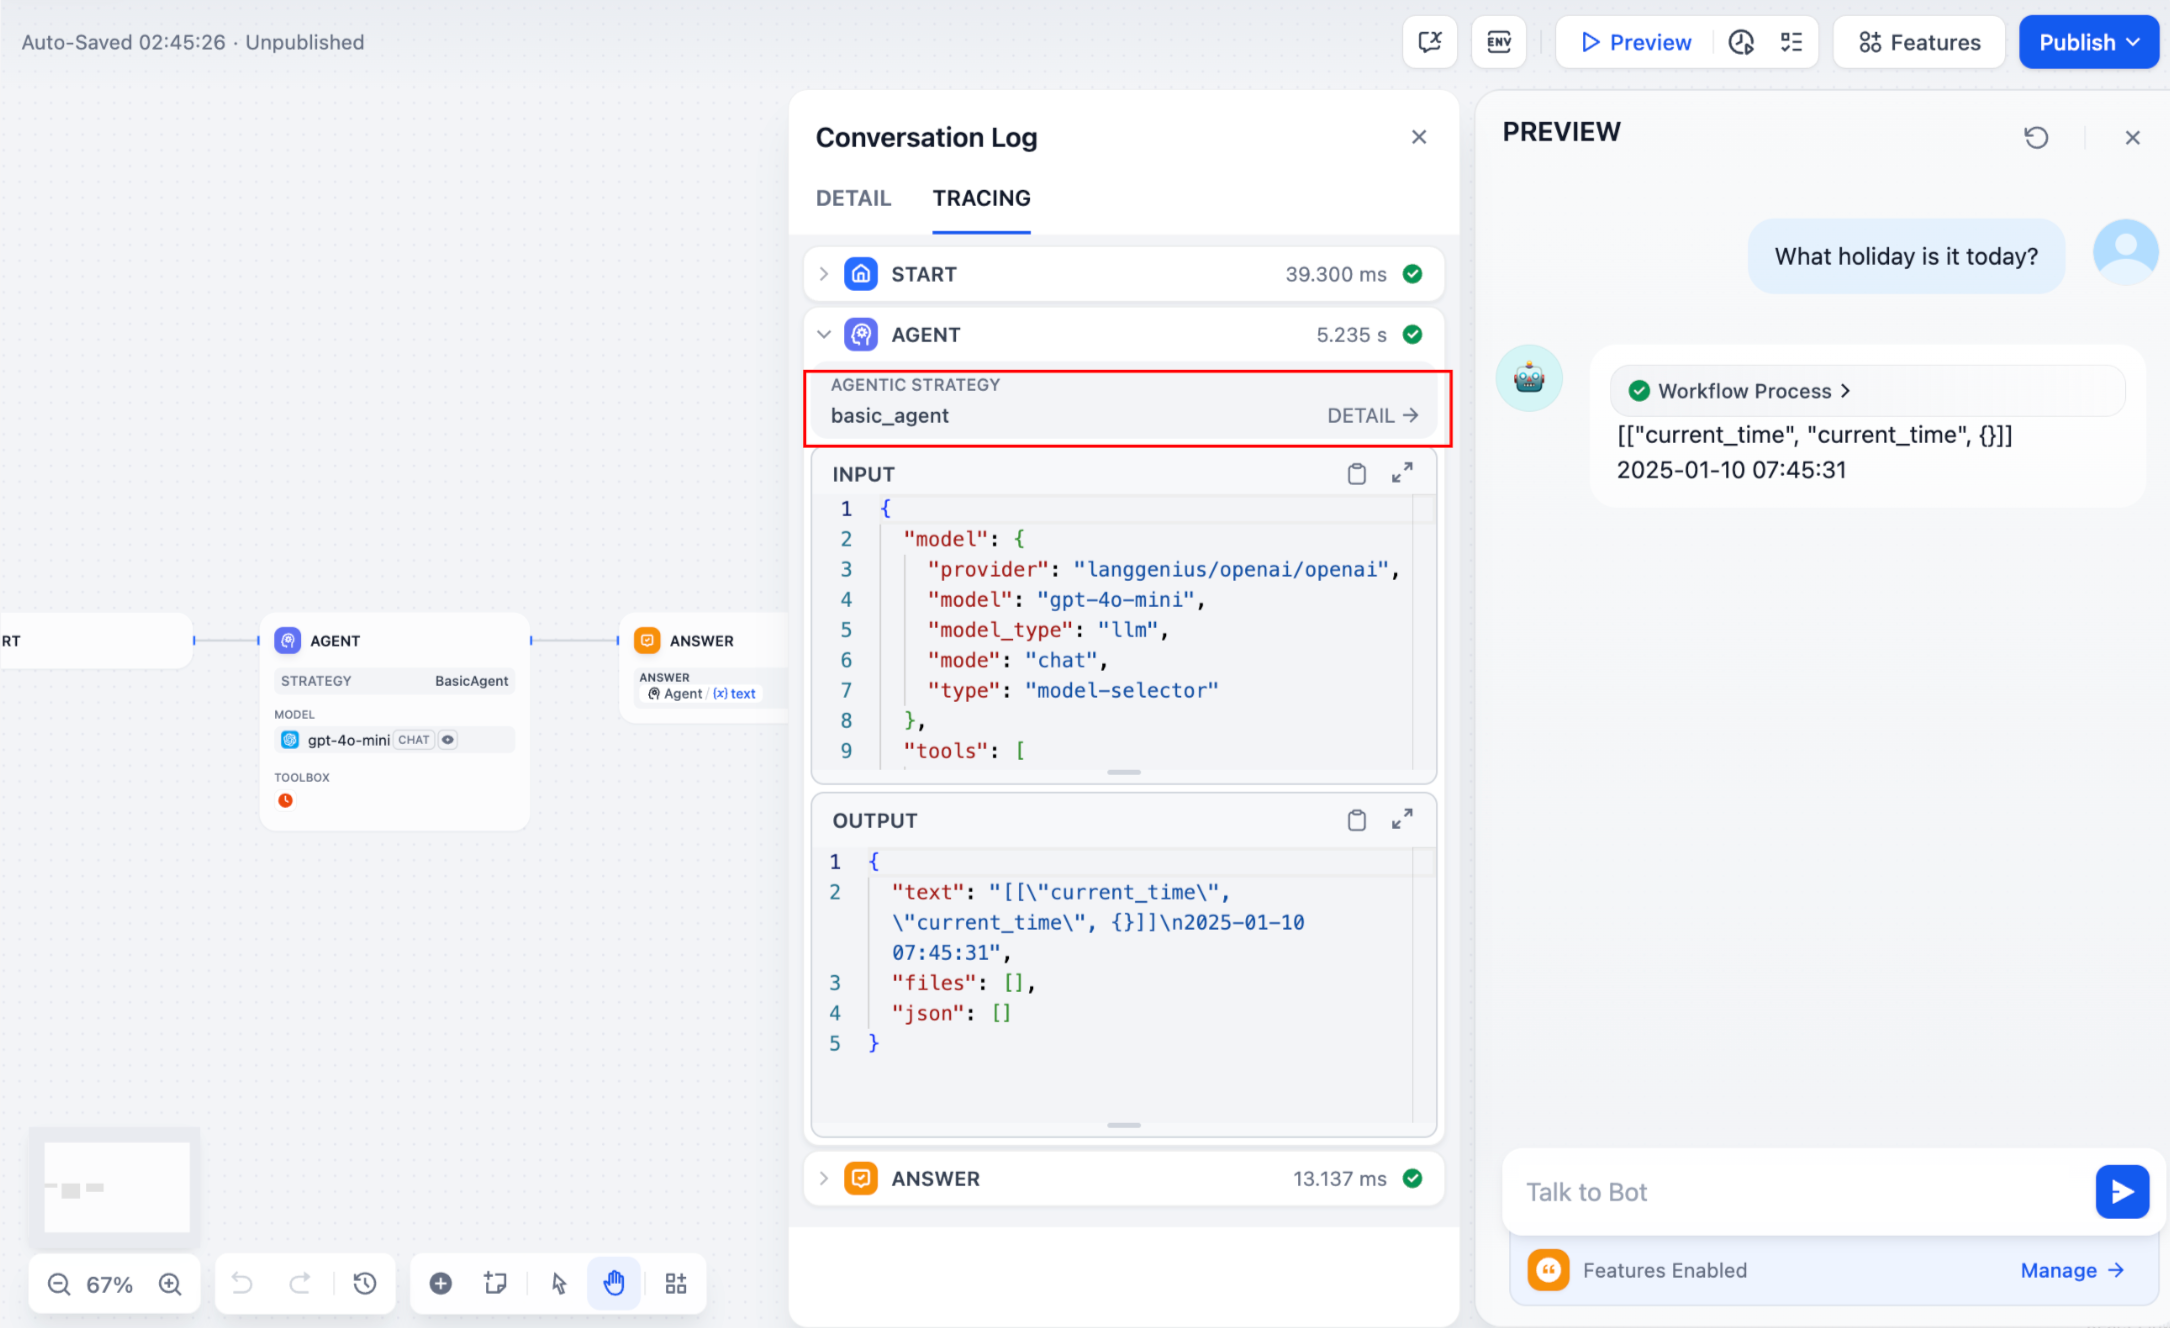
</Frame>
When a task spans multiple rounds, set the `parent` parameter in your log calls to nest the logs hierarchically and keep them easy to follow:
```python theme={null}
function_call_round_log = self.create_log_message(
label="Function Call Round1 ",
data={},
metadata={},
)
yield function_call_round_log
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
# add parent log
parent=function_call_round_log,
)
yield model_log
```
### Sample Code
<Tabs>
<Tab title="Invoke Model">
The following code gives the Agent strategy plugin the ability to invoke the model:
```python theme={null}
import json
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
<Tab title="Handle Tools">
The following code invokes the model and sends well-formed requests to the tools it selects:
```python theme={null}
import json
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
<Tab title="Complete Example">
A complete sample that covers model invocation, tool handling, and multi-round logging:
```python theme={null}
import json
import time
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
function_call_round_log = self.create_log_message(
label="Function Call Round1 ",
data={},
metadata={},
)
yield function_call_round_log
model_started_at = time.perf_counter()
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
parent=function_call_round_log,
)
yield model_log
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
tool_call_names = ""
tool_call_inputs = ""
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.finish_log_message(
log=model_log,
data={
"output": response,
"tool_name": tool_call_names,
"tool_input": tool_call_inputs,
},
metadata={
"started_at": model_started_at,
"finished_at": time.perf_counter(),
"elapsed_time": time.perf_counter() - model_started_at,
"provider": params.model.provider,
},
)
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
</Tabs>
## 6. Debug the Plugin
With the declaration file and implementation code complete, verify that the plugin runs correctly. Dify supports remote debugging: go to **Plugin Management** to obtain your debug key and remote server address.
<Frame>
</Frame>
In your plugin project, copy `.env.example` to `.env` and fill in the remote server address and debug key.
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Then run:
```bash theme={null}
python -m main
```
The plugin appears in your workspace, where team members can also access it.
<Frame>
</Frame>
## Package the Plugin (Optional)
Once everything works, package your plugin by running:
```bash theme={null}
# Replace ./basic_agent/ with your actual plugin project path.
dify plugin package ./basic_agent/
```
A file named `basic_agent.difypkg` (matching your plugin name) appears in your current folder. This is your final plugin package.
Congratulations! You've developed, tested, and packaged your Agent Strategy Plugin.
## Publish the Plugin (Optional)
You can now upload the package to the [Dify Plugins repository](https://github.com/langgenius/dify-plugins). Before doing so, ensure it meets the [Plugin Publishing Guidelines](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). Once approved, your code merges into the main branch, and the plugin automatically goes live on the [Dify Marketplace](https://marketplace.dify.ai/).
***
## Further Exploration
Complex tasks often need multiple rounds of thinking and tool calls, repeating the model invoke → tool use cycle until the task ends or the iteration limit is reached. Managing prompts well is crucial in this process. See the [complete Function Calling implementation](https://github.com/langgenius/dify-official-plugins/blob/main/agent-strategies/cot_agent/strategies/function_calling.py) for a standardized approach to letting models call external tools and handle their outputs.
# Cheatsheet
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet
A quick reference for Dify plugin development, covering environment setup, installation, the development process, and plugin types
## Environment Requirements
* Python version 3.12
* Dify plugin scaffold tool (`dify-plugin-daemon`)
For setup instructions, see [Initializing Development Tools](/en/develop-plugin/getting-started/cli).
## Obtain the Dify Plugin Development Package
Download the [Dify Plugin CLI](https://github.com/langgenius/dify-plugin-daemon/releases) from the GitHub releases page.
### Installation Methods for Different Platforms
**macOS [Brew](https://github.com/langgenius/homebrew-dify) (Global Installation)**:
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
After installation, open a new terminal window and enter the `dify version` command. If it outputs the version information, the installation was successful.
**macOS ARM (M Series Chips)**:
```bash theme={null}
# Download dify-plugin-darwin-arm64
chmod +x dify-plugin-darwin-arm64
./dify-plugin-darwin-arm64 version
```
**macOS Intel**:
```bash theme={null}
# Download dify-plugin-darwin-amd64
chmod +x dify-plugin-darwin-amd64
./dify-plugin-darwin-amd64 version
```
**Linux**:
```bash theme={null}
# Download dify-plugin-linux-amd64
chmod +x dify-plugin-linux-amd64
./dify-plugin-linux-amd64 version
```
**Global Installation (Recommended)**:
```bash theme={null}
# Rename and move to system path
# Example (macOS ARM)
mv dify-plugin-darwin-arm64 dify
sudo mv dify /usr/local/bin/
dify version
```
## Run the Development Package
The following examples use `dify` as the command. If you installed locally, replace the command accordingly—for example, `./dify-plugin-darwin-arm64 plugin init`.
## Plugin Development Process
### 1. Create a New Plugin
```bash theme={null}
./dify plugin init
```
Follow the prompts to configure the basic plugin information.
For a full walkthrough, see [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
### 2. Run in Development Mode
Configure the `.env` file, then run the following command in the plugin directory:
```bash theme={null}
python -m main
```
For debugging details, see [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin).
### 3. Package and Deploy
Package the plugin:
```bash theme={null}
cd ..
dify plugin package ./yourapp
```
For publishing details, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Plugin Categories
### Tool Labels
Category tags are defined in [`ToolLabelEnum`](https://github.com/langgenius/dify-plugin-sdks/blob/main/python/dify_plugin/entities/tool.py):
```python theme={null}
class ToolLabelEnum(Enum):
SEARCH = "search"
IMAGE = "image"
VIDEOS = "videos"
WEATHER = "weather"
FINANCE = "finance"
DESIGN = "design"
TRAVEL = "travel"
SOCIAL = "social"
NEWS = "news"
MEDICAL = "medical"
PRODUCTIVITY = "productivity"
EDUCATION = "education"
BUSINESS = "business"
ENTERTAINMENT = "entertainment"
UTILITIES = "utilities"
OTHER = "other"
```
## Plugin Type Reference
Dify supports several plugin types:
* **Tool plugin**: Integrate third-party APIs and services. See [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
* **Model plugin**: Integrate AI models. See [Model Plugin](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) and [Quick Integration of a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
* **Agent strategy plugin**: Customize Agent thinking and decision-making strategies. See [Agent Strategy Plugin](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
* **Extension plugin**: Extend Dify platform functionality, such as Endpoints and web apps. See [Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint).
* **Data source plugin**: Serve as the document data source and starting point for knowledge pipelines. See [Data Source Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin).
* **Trigger plugin**: Automatically trigger workflow execution on third-party events. See [Trigger Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin).
# Model Provider Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider
Build a model provider plugin, from project setup and provider configuration to model implementation, debugging, and publishing
## Prerequisites
* [Dify Plugin CLI](/en/develop-plugin/getting-started/cli)
* Basic Python programming skills and understanding of object-oriented programming
* Familiarity with the API documentation of the model provider you want to integrate
## Step 1: Create and Configure a New Plugin Project
### Initialize the Project
```bash theme={null}
dify plugin init
```
### Choose Model Plugin Template
Select the `LLM` type plugin template from the available options. This template provides a complete code structure for model integration.
<Frame>

</Frame>
### Configure Plugin Permissions
For a model provider plugin, configure the following essential permissions:
* **Models**: Base permission for model operations.
* **LLM**: Permission for large language model functionality.
* **Storage**: Permission for file operations (if needed).
<Frame>

</Frame>
### Directory Structure Overview
After initialization, your plugin project has a directory structure similar to this (assuming a provider named `my_provider` that supports LLM and Embedding):
```bash theme={null}
models/my_provider/
├── models # Model implementation and configuration directory
│ ├── llm # LLM type
│ │ ├── _position.yaml (Optional, controls sorting)
│ │ ├── model1.yaml # Configuration for specific model
│ │ └── llm.py # LLM implementation logic
│ └── text_embedding # Embedding type
│ ├── _position.yaml
│ ├── embedding-model.yaml
│ └── text_embedding.py
├── provider # Provider-level code directory
│ └── my_provider.py # Provider credential validation
└── manifest.yaml # Plugin manifest file
```
## Step 2: Understand Model Configuration Methods
Dify supports two model configuration methods that determine how users interact with your provider's models:
### Predefined Models (`predefined-model`)
Predefined models require only unified provider credentials. Once a user configures their API key or other authentication details for the provider, they can immediately access all predefined models.
**Example**: The OpenAI provider offers predefined models like `gpt-3.5-turbo-0125` and `gpt-4o-2024-05-13`. A user only needs to configure their OpenAI API key once to access all these models.
### Custom Models (`customizable-model`)
Custom models require additional configuration for each model instance. This approach is useful when models need individual parameters beyond the provider-level credentials.
**Example**: Xinference supports both LLM and Text Embedding, but each model has a unique `model_uid`. Users must configure this `model_uid` separately for each model they want to use.
The two configuration methods can coexist within a single provider. For instance, a provider might offer some predefined models while also allowing users to add custom models with specific configurations.
## Step 3: Create Model Provider Files
Creating a new model provider involves two main components:
* **Provider configuration YAML file**: Defines the provider's basic information, supported model types, and credential requirements.
* **Provider class implementation**: Implements authentication validation and other provider-level functionality.
### 3.1 Create the Model Provider Configuration File
The provider configuration is a YAML file that declares the provider's basic information, supported model types, configuration methods, and credential rules. Place it in the root directory of your plugin project.
Here's an annotated example of the `anthropic.yaml` configuration file:
```yaml theme={null}
# Basic provider identification
provider: anthropic # Provider ID (must be unique)
label:
en_US: Anthropic # Display name in UI
description:
en_US: Anthropic's powerful models, such as Claude 3.
zh_Hans: Anthropic 的强大模型,例如 Claude 3。
icon_small:
en_US: icon_s_en.svg # Small icon for provider (displayed in selection UI)
icon_large:
en_US: icon_l_en.svg # Large icon (displayed in detail views)
background: "#F0F0EB" # Background color for provider in UI
# Help information for users
help:
title:
en_US: Get your API Key from Anthropic
zh_Hans: 从 Anthropic 获取 API Key
url:
en_US: https://console.anthropic.com/account/keys
# Supported model types and configuration approach
supported_model_types:
- llm # This provider offers LLM models
configurate_methods:
- predefined-model # Uses predefined models approach
# Provider-level credential form definition
provider_credential_schema:
credential_form_schemas:
- variable: anthropic_api_key # Variable name for API key
label:
en_US: API Key
type: secret-input # Secure input for sensitive data
required: true
placeholder:
zh_Hans: 在此输入你的 API Key
en_US: Enter your API Key
- variable: anthropic_api_url
label:
en_US: API URL
type: text-input # Regular text input
required: false
placeholder:
zh_Hans: 在此输入你的 API URL
en_US: Enter your API URL
# Model configuration
models:
llm: # Configuration for LLM type models
predefined:
- "models/llm/*.yaml" # Pattern to locate model configuration files
position: "models/llm/_position.yaml" # File defining display order
# Implementation file locations
extra:
python:
provider_source: provider/anthropic.py # Provider class implementation
model_sources:
- "models/llm/llm.py" # Model implementation file
```
### Custom Model Configuration
If your provider supports custom models, add a `model_credential_schema` section defining the additional fields users must configure for each model. This is typical for providers that support fine-tuned models or require model-specific parameters.
Here's an example from the OpenAI provider:
```yaml theme={null}
model_credential_schema:
model: # Fine-tuned model name field
label:
en_US: Model Name
zh_Hans: 模型名称
placeholder:
en_US: Enter your model name
zh_Hans: 输入模型名称
credential_form_schemas:
- variable: openai_api_key
label:
en_US: API Key
type: secret-input
required: true
placeholder:
zh_Hans: 在此输入你的 API Key
en_US: Enter your API Key
- variable: openai_organization
label:
zh_Hans: 组织 ID
en_US: Organization
type: text-input
required: false
placeholder:
zh_Hans: 在此输入你的组织 ID
en_US: Enter your Organization ID
# Additional fields as needed...
```
For the complete model provider YAML specification, see [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema).
### 3.2 Write the Model Provider Code
Next, create a Python file for your provider class in the `/provider` directory, named after your provider (e.g., `anthropic.py`).
The provider class must inherit from `ModelProvider` and implement at least the `validate_provider_credentials` method:
```python theme={null}
import logging
from dify_plugin.entities.model import ModelType
from dify_plugin.errors.model import CredentialsValidateFailedError
from dify_plugin import ModelProvider
logger = logging.getLogger(__name__)
class AnthropicProvider(ModelProvider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
Validate provider credentials by testing them against the API.
This method should attempt to make a simple API call to verify
that the credentials are valid.
:param credentials: Provider credentials as defined in the YAML schema
:raises CredentialsValidateFailedError: If validation fails
"""
try:
# Get an instance of the LLM model type and use it to validate credentials
model_instance = self.get_model_instance(ModelType.LLM)
model_instance.validate_credentials(
model="claude-3-opus-20240229",
credentials=credentials
)
except CredentialsValidateFailedError as ex:
# Pass through credential validation errors
raise ex
except Exception as ex:
# Log and re-raise other exceptions
logger.exception(f"{self.get_provider_schema().provider} credentials validate failed")
raise ex
```
Dify calls `validate_provider_credentials` whenever a user saves provider credentials, so it should:
1. Attempt to validate the credentials by making a simple API call.
2. Return silently if validation succeeds.
3. Raise `CredentialsValidateFailedError` with a helpful message if validation fails.
#### For Custom Model Providers
For providers that exclusively use custom models (where each model requires its own configuration), you can implement a simpler provider class. For example, with Xinference:
```python theme={null}
from dify_plugin import ModelProvider
class XinferenceProvider(ModelProvider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
For custom-only model providers, validation happens at the model level.
This method exists to satisfy the abstract base class requirement.
"""
pass
```
## Step 4: Implement Model-Specific Code
After setting up your provider, implement the model-specific code that handles API calls for each model type you support. This involves:
1. Creating model configuration YAML files for each specific model.
2. Implementing the model type classes that handle API communication.
For detailed instructions, see:
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): Standards for integrating predefined models.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Standards for model configuration files.
### 4.1 Define Model Configuration (YAML)
For each specific model, create a YAML file in the appropriate model type directory (e.g., `models/llm/`) to define its properties, parameters, and features.
**Example (`claude-3-5-sonnet-20240620.yaml`)**:
```yaml theme={null}
model: claude-3-5-sonnet-20240620 # API identifier for the model
label:
en_US: claude-3-5-sonnet-20240620 # Display name in UI
model_type: llm # Must match directory type
features: # Special capabilities
- agent-thought
- vision
- tool-call
- stream-tool-call
- document
model_properties: # Inherent model properties
mode: chat # "chat" or "completion"
context_size: 200000 # Maximum context window
parameter_rules: # User-adjustable parameters
- name: temperature
use_template: temperature # Reference predefined template
- name: top_p
use_template: top_p
- name: max_tokens
use_template: max_tokens
required: true
default: 8192
min: 1
max: 8192
pricing: # Optional pricing information
input: '3.00'
output: '15.00'
unit: '0.000001' # Per million tokens
currency: USD
```
### 4.2 Implement Model Calling Code (Python)
Create a Python file for each model type you support (e.g., `llm.py` in the `models/llm/` directory). This class handles API communication, parameter transformation, and result formatting.
Here's an example implementation structure for an LLM:
```python theme={null}
import logging
from typing import Union, Generator, Optional, List
from dify_plugin.provider_kits.llm import LargeLanguageModel # Base class
from dify_plugin.provider_kits.llm import LLMResult, LLMResultChunk, LLMUsage # Result classes
from dify_plugin.provider_kits.llm import PromptMessage, PromptMessageTool # Message classes
from dify_plugin.errors.provider_error import InvokeError, InvokeAuthorizationError # Error classes
logger = logging.getLogger(__name__)
class MyProviderLargeLanguageModel(LargeLanguageModel):
def _invoke(self, model: str, credentials: dict, prompt_messages: List[PromptMessage],
model_parameters: dict, tools: Optional[List[PromptMessageTool]] = None,
stop: Optional[List[str]] = None, stream: bool = True,
user: Optional[str] = None) -> Union[LLMResult, Generator[LLMResultChunk, None, None]]:
"""
Core method for invoking the model API.
Parameters:
model: The model identifier to call
credentials: Authentication credentials
prompt_messages: List of messages to send
model_parameters: Parameters like temperature, max_tokens
tools: Optional tool definitions for function calling
stop: Optional list of stop sequences
stream: Whether to stream responses (True) or return complete response (False)
user: Optional user identifier for API tracking
Returns:
If stream=True: Generator yielding LLMResultChunk objects
If stream=False: Complete LLMResult object
"""
# Prepare API request parameters
api_params = self._prepare_api_params(
credentials, model_parameters, prompt_messages, tools, stop
)
try:
# Call appropriate helper method based on streaming preference
if stream:
return self._invoke_stream(model, api_params, user)
else:
return self._invoke_sync(model, api_params, user)
except Exception as e:
# Handle and map errors
self._handle_api_error(e)
def _invoke_stream(self, model: str, api_params: dict, user: Optional[str]) -> Generator[LLMResultChunk, None, None]:
"""Helper method for streaming API calls"""
# Implementation details for streaming calls
pass
def _invoke_sync(self, model: str, api_params: dict, user: Optional[str]) -> LLMResult:
"""Helper method for synchronous API calls"""
# Implementation details for synchronous calls
pass
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate that the credentials work for this specific model.
Called when a user tries to add or modify credentials.
"""
# Implementation for credential validation
pass
def get_num_tokens(self, model: str, credentials: dict,
prompt_messages: List[PromptMessage],
tools: Optional[List[PromptMessageTool]] = None) -> int:
"""
Estimate the number of tokens for given input.
Optional but recommended for accurate cost estimation.
"""
# Implementation for token counting
pass
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Define mapping from vendor-specific exceptions to Dify standard exceptions.
This helps standardize error handling across different providers.
"""
return {
InvokeAuthorizationError: [
# List vendor-specific auth errors here
],
# Other error mappings
}
```
The most important method to implement is `_invoke`, which handles the core API communication. This method should:
1. Transform Dify's standardized inputs into the format required by the provider's API.
2. Make the API call with proper error handling.
3. Transform the API response into Dify's standardized output format.
4. Handle both streaming and non-streaming modes.
## Step 5: Debug and Test Your Plugin
Dify supports remote debugging, so you can test your plugin during development:
1. In your Dify instance, go to **Plugin Management** and click **Debug Plugin** to get your debug key and server address.
2. Configure your local environment with these values in a `.env` file:
```dotenv theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=<your-dify-host>:5003
REMOTE_INSTALL_KEY=****-****-****-****-****
```
3. Run your plugin locally with `python -m main` and test it in Dify.
## Step 6: Package and Publish
When your plugin is ready:
1. Package it using the scaffolding tool:
```bash theme={null}
dify plugin package models/<provider_name>
```
2. Test the packaged plugin locally before submitting.
3. Submit a pull request to the [Dify official plugins repository](https://github.com/langgenius/dify-official-plugins).
For more details on the publishing process, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Reference Resources
* [Quick Integration of a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): How to add new models to existing providers.
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin): Return to the plugin development getting started guide.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Detailed model configuration specifications.
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Plugin manifest file configuration.
* [Dify Plugin SDK Reference](https://github.com/langgenius/dify-plugin-sdks): Base classes, data structures, and error types.
# Data Source Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin
Build a Dify 1.9.0+ data source plugin that feeds documents into the knowledge pipeline
Data source plugins, introduced in Dify 1.9.0, supply documents to a knowledge pipeline and serve as the starting point for the entire pipeline.
This guide covers the plugin architecture, code examples, and debugging methods you need to build and launch a data source plugin.
## Prerequisites
You should have a basic understanding of the knowledge pipeline and plugin development:
* [Step 2: Knowledge Pipeline Orchestration](/en/cloud/use-dify/knowledge/knowledge-pipeline/knowledge-pipeline-orchestration)
* [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)
## Data Source Plugin Types
Dify supports three types of data source plugins: web crawler, online document, and online drive. Each type corresponds to a different parent class, and the class that implements your plugin's functionality must inherit from it.
<Info>
To learn how to inherit from a parent class to implement plugin functionality, see [Tool Plugin: Write the Tool Code](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin#4-write-the-tool-code).
</Info>
Each data source plugin type supports multiple data sources. For example:
* **Web Crawler**: Jina Reader, FireCrawl
* **Online Document**: Notion, Confluence, GitHub
* **Online Drive**: OneDrive, Google Drive, Box, AWS S3, Tencent COS
The relationship between data source types and data source plugin types is illustrated below.
<Frame>
<img alt="Data Source Type" />
</Frame>
## Develop a Data Source Plugin
### Create a Data Source Plugin
Create a data source plugin with the scaffolding command-line tool by selecting the `datasource` type. After you complete the setup, the tool generates the plugin project code.
```bash theme={null}
dify plugin init
```
<Frame>
<img alt="Datasource Plugin Init" />
</Frame>
<Info>
Typically, a data source plugin does not need to use other features of the Dify platform, so no additional permissions are required.
</Info>
#### Data Source Plugin Structure
A data source plugin consists of three main components:
* The `manifest.yaml` file: Describes the basic information about the plugin.
* The `provider` directory: Contains the plugin provider's description and authentication implementation code.
* The `datasources` directory: Contains the description and core logic for fetching data from the data source.
```text theme={null}
├── _assets
│ └── icon.svg
├── datasources
│ ├── your_datasource.py
│ └── your_datasource.yaml
├── main.py
├── manifest.yaml
├── PRIVACY.md
├── provider
│ ├── your_datasource.py
│ └── your_datasource.yaml
├── README.md
└── requirements.txt
```
#### Set the Correct Version and Tag
* In the `manifest.yaml` file, set the minimum supported Dify version:
```yaml theme={null}
minimum_dify_version: 1.9.0
```
* In the same file, add the following tag so the plugin appears under the data source category in the Dify Marketplace:
```yaml theme={null}
tags:
- rag
```
* In the `requirements.txt` file, set the plugin SDK version:
```text theme={null}
dify-plugin>=0.5.0,<0.6.0
```
### Add the Data Source Provider
#### Create the Provider YAML File
The content of a provider YAML file is essentially the same as that for tool plugins, with only the following two differences:
```yaml theme={null}
# Specify the provider type for the data source plugin: online_drive, online_document, or website_crawl
provider_type: online_drive # online_document, website_crawl
# Specify data sources
datasources:
- datasources/PluginName.yaml
```
<Info>
For more about creating a provider YAML file, see [Tool Plugin: Add Third-Party Service Credentials](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin#2-add-third-party-service-credentials).
</Info>
<Info>
Data source plugins support authentication via OAuth 2.0 or API Key.
To configure OAuth, see [Add OAuth Support to Your Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth).
</Info>
#### Create the Provider Code File
* With API Key authentication, the provider code file is identical to that of a tool plugin. You only need to change the provider class's parent class to `DatasourceProvider`.
```python theme={null}
class YourDatasourceProvider(DatasourceProvider):
def _validate_credentials(self, credentials: Mapping[str, Any]) -> None:
try:
"""
IMPLEMENT YOUR VALIDATION HERE
"""
except Exception as e:
raise ToolProviderCredentialValidationError(str(e))
```
* With OAuth authentication, data source plugins differ slightly from tool plugins: when obtaining access via OAuth, they can also return the username and avatar to display on the frontend. `_oauth_get_credentials` and `_oauth_refresh_credentials` must therefore return a `DatasourceOAuthCredentials` object containing `name`, `avatar_url`, `expires_at`, and `credentials`.
The `DatasourceOAuthCredentials` class is defined as follows:
```python theme={null}
class DatasourceOAuthCredentials(BaseModel):
name: str | None = Field(None, description="The name of the OAuth credential")
avatar_url: str | None = Field(None, description="The avatar url of the OAuth")
credentials: Mapping[str, Any] = Field(..., description="The credentials of the OAuth")
expires_at: int | None = Field(
default=-1,
description="""The expiration timestamp (in seconds since Unix epoch, UTC) of the credentials.
Set to -1 or None if the credentials do not expire.""",
)
```
The function signatures for `_oauth_get_authorization_url`, `_oauth_get_credentials`, and `_oauth_refresh_credentials` are as follows:
<Tabs>
<Tab title="_oauth_get_authorization_url">
```python theme={null}
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
"""
Generate the authorization URL for {{ .PluginName }} OAuth.
"""
try:
"""
IMPLEMENT YOUR AUTHORIZATION URL GENERATION HERE
"""
except Exception as e:
raise DatasourceOAuthError(str(e))
return ""
```
</Tab>
<Tab title="_oauth_get_credentials">
```python theme={null}
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> DatasourceOAuthCredentials:
"""
Exchange code for access_token.
"""
try:
"""
IMPLEMENT YOUR CREDENTIALS EXCHANGE HERE
"""
except Exception as e:
raise DatasourceOAuthError(str(e))
return DatasourceOAuthCredentials(
name="",
avatar_url="",
expires_at=-1,
credentials={},
)
```
</Tab>
<Tab title="_oauth_refresh_credentials">
```python theme={null}
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> DatasourceOAuthCredentials:
"""
Refresh the credentials
"""
return DatasourceOAuthCredentials(
name="",
avatar_url="",
expires_at=-1,
credentials={},
)
```
</Tab>
</Tabs>
### Add the Data Source
The YAML file format and data source code format vary across the three types of data sources.
#### Web Crawler
In the provider YAML file for a web crawler data source plugin, `output_schema` must always return four parameters: `source_url`, `content`, `title`, and `description`.
```yaml theme={null}
output_schema:
type: object
properties:
source_url:
type: string
description: the source url of the website
content:
type: string
description: the content from the website
title:
type: string
description: the title of the website
"description":
type: string
description: the description of the website
```
In the main logic code for a web crawler plugin, the class must inherit from `WebsiteCrawlDatasource` and implement the `_get_website_crawl` method, using the `create_crawl_message` method to return the crawl results.
To crawl multiple web pages and return them in batches, set `WebSiteInfo.status` to `processing` and call `create_crawl_message` for each batch of crawled pages. After all pages have been crawled, set `WebSiteInfo.status` to `completed`.
```python theme={null}
class YourDataSource(WebsiteCrawlDatasource):
def _get_website_crawl(
self, datasource_parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
crawl_res = WebSiteInfo(web_info_list=[], status="", total=0, completed=0)
crawl_res.status = "processing"
yield self.create_crawl_message(crawl_res)
### your crawl logic
...
crawl_res.status = "completed"
crawl_res.web_info_list = [
WebSiteInfoDetail(
title="",
source_url="",
description="",
content="",
)
]
crawl_res.total = 1
crawl_res.completed = 1
yield self.create_crawl_message(crawl_res)
```
#### Online Document
The return value for an online document data source plugin must include at least a `content` field to represent the document's content. For example:
```yaml theme={null}
output_schema:
type: object
properties:
workspace_id:
type: string
description: workspace id
page_id:
type: string
description: page id
content:
type: string
description: page content
```
In the main logic code for an online document plugin, the class must inherit from `OnlineDocumentDatasource` and implement two methods: `_get_pages` and `_get_content`.
When a user runs the plugin, it first calls the `_get_pages` method to retrieve a list of documents. After the user selects a document from the list, it then calls the `_get_content` method to fetch the document's content.
<Tabs>
<Tab title="_get_pages">
```python theme={null}
def _get_pages(self, datasource_parameters: dict[str, Any]) -> DatasourceGetPagesResponse:
# your get pages logic
response = requests.get(url, headers=headers, params=params, timeout=30)
pages = []
for item in response.json().get("results", []):
page = OnlineDocumentPage(
page_name=item.get("title", ""),
page_id=item.get("id", ""),
type="page",
last_edited_time=item.get("version", {}).get("createdAt", ""),
parent_id=item.get("parentId", ""),
page_icon=None,
)
pages.append(page)
online_document_info = OnlineDocumentInfo(
workspace_name=workspace_name,
workspace_icon=workspace_icon,
workspace_id=workspace_id,
pages=[page],
total=pages.length(),
)
return DatasourceGetPagesResponse(result=[online_document_info])
```
</Tab>
<Tab title="_get_content">
```python theme={null}
def _get_content(self, page: GetOnlineDocumentPageContentRequest) -> Generator[DatasourceMessage, None, None]:
# your fetch content logic, example
response = requests.get(url, headers=headers, params=params, timeout=30)
...
yield self.create_variable_message("content", "")
yield self.create_variable_message("page_id", "")
yield self.create_variable_message("workspace_id", "")
```
</Tab>
</Tabs>
#### Online Drive
An online drive data source plugin returns a file, so it must adhere to the following specification:
```yaml theme={null}
output_schema:
type: object
properties:
file:
$ref: "https://dify.ai/schemas/v1/file.json"
```
In the main logic code for an online drive plugin, the class must inherit from `OnlineDriveDatasource` and implement two methods: `_browse_files` and `_download_file`.
When a user runs the plugin, it first calls `_browse_files` to get a file list. At this point, `prefix` is empty, indicating a request for the root directory's file list. The list contains both folder and file entries. If the user opens a folder, `_browse_files` is called again, and the `prefix` in `OnlineDriveBrowseFilesRequest` is the folder ID used to retrieve the file list within that folder.
After a user selects a file, the plugin uses the `_download_file` method and the file ID to get the file's content. You can use the `_get_mime_type_from_filename` method to get the file's MIME type, allowing the pipeline to handle different file types appropriately.
When the file list contains multiple files, you can set `OnlineDriveFileBucket.is_truncated` to `True` and `OnlineDriveFileBucket.next_page_parameters` to the parameters needed to fetch the next page, such as the next page's request ID or URL, depending on the service provider.
<Tabs>
<Tab title="_browse_files">
```python theme={null}
def _browse_files(
self, request: OnlineDriveBrowseFilesRequest
) -> OnlineDriveBrowseFilesResponse:
credentials = self.runtime.credentials
bucket_name = request.bucket
prefix = request.prefix or "" # Allow empty prefix for root folder; When you browse the folder, the prefix is the folder id
max_keys = request.max_keys or 10
next_page_parameters = request.next_page_parameters or {}
files = []
files.append(OnlineDriveFile(
id="",
name="",
size=0,
type="folder" # or "file"
))
return OnlineDriveBrowseFilesResponse(result=[
OnlineDriveFileBucket(
bucket="",
files=files,
is_truncated=False,
next_page_parameters={}
)
])
```
</Tab>
<Tab title="_download_file">
```python theme={null}
def _download_file(self, request: OnlineDriveDownloadFileRequest) -> Generator[DatasourceMessage, None, None]:
credentials = self.runtime.credentials
file_id = request.id
file_content = bytes()
file_name = ""
mime_type = self._get_mime_type_from_filename(file_name)
yield self.create_blob_message(file_content, meta={
"file_name": file_name,
"mime_type": mime_type
})
def _get_mime_type_from_filename(self, filename: str) -> str:
"""Determine MIME type from file extension."""
import mimetypes
mime_type, _ = mimetypes.guess_type(filename)
return mime_type or "application/octet-stream"
```
</Tab>
</Tabs>
For storage services like AWS S3, the `prefix`, `bucket`, and `id` variables have special uses and can be applied flexibly as needed during development:
* `prefix`: Represents the file path prefix. For example, `prefix=container1/folder1/` retrieves the files or file list from the `folder1` folder in the `container1` bucket.
* `bucket`: Represents the file bucket. For example, `bucket=container1` retrieves the files or file list in the `container1` bucket. This field can be left blank for non-standard S3 protocol drives.
* `id`: Since the `_download_file` method does not use the `prefix` variable, the full file path must be included in the `id`. For example, `id=container1/folder1/file1.txt` indicates retrieving the `file1.txt` file from the `folder1` folder in the `container1` bucket.
<Tip>
For reference implementations, see the [official Google Drive plugin](https://github.com/langgenius/dify-official-plugins/blob/main/datasources/google_cloud_storage/datasources/google_cloud_storage.py) and the [official AWS S3 plugin](https://github.com/langgenius/dify-official-plugins/blob/main/datasources/aws_s3_storage/datasources/aws_s3_storage.py).
</Tip>
## Debug the Plugin
Data source plugins support two debugging methods: remote debugging and installing the plugin locally. Note the following:
* If the plugin uses OAuth authentication, the `redirect_uri` for remote debugging differs from that of a local plugin. Update the relevant configuration in your service provider's OAuth App accordingly.
* While data source plugins support single-step debugging, we still recommend testing them in a complete knowledge pipeline to ensure full functionality.
## Final Checks
Before packaging and publishing, make sure you've completed all of the following:
* Set the minimum supported Dify version to `1.9.0`.
* Set the SDK version to `dify-plugin>=0.5.0,<0.6.0`.
* Write the `README.md` and `PRIVACY.md` files.
* Include only English content in the code files.
* Replace the default icon with the data source provider's logo.
## Package and Publish
In the plugin directory, run the following command to generate a `.difypkg` plugin package:
```bash theme={null}
dify plugin package . -o your_datasource.difypkg
```
Next, you can:
* Import and use the plugin in your Dify environment.
* Publish the plugin to Dify Marketplace by submitting a pull request.
<Info>
For the plugin publishing process, see [Publishing Plugins](/en/develop-plugin/publishing/marketplace-listing/release-overview).
</Info>
# Slack Bot
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin
Build a Slack Bot plugin that connects a Dify app to Slack, from project setup through debugging and packaging
In this guide, you'll build an AI-powered Slack Bot that answers user questions right inside Slack. If you haven't developed a plugin before, read the [Plugin Development Quick Start Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) first.
## Project Background
A Slack Bot plugin lets your team chat with an LLM directly in Slack, putting AI where conversations already happen.
Slack is an open, real-time communication platform with a robust API, including a webhook-based event system that is straightforward to build on. This guide uses that system to create the Slack Bot plugin, illustrated in the diagram below:
<Frame>
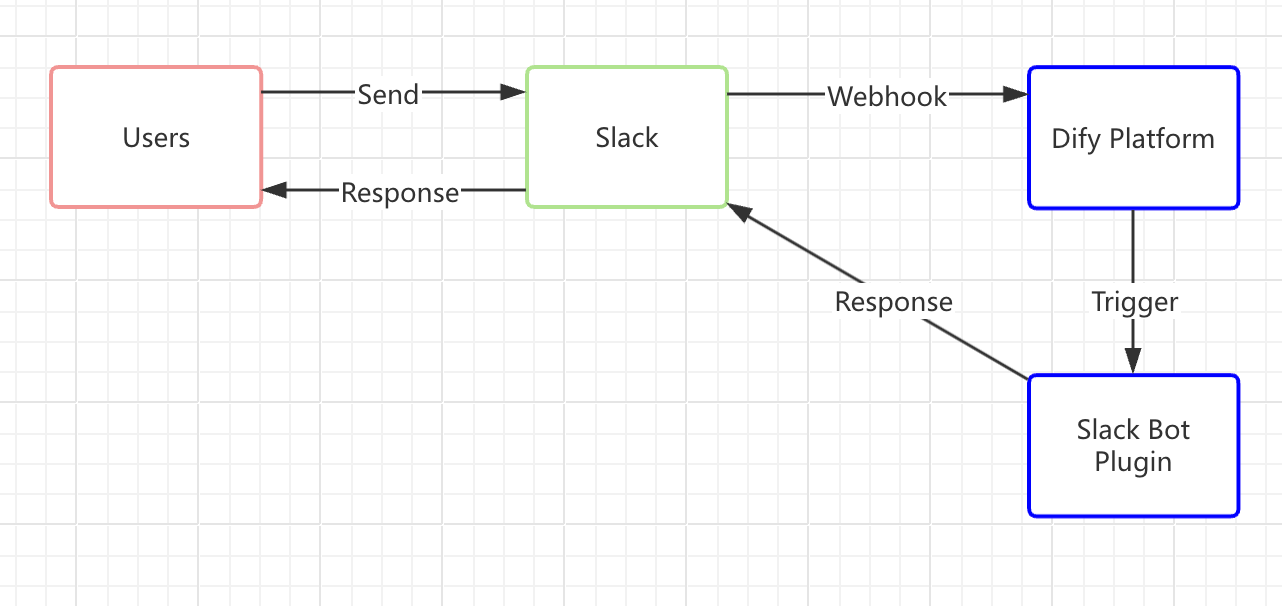
</Frame>
<Note>
Two similar terms appear throughout this guide:
* **Slack Bot**: A chatbot on the Slack platform—a virtual user you can interact with in real time.
* **Slack Bot plugin**: A plugin in the Dify Marketplace that connects a Dify application with Slack. This guide shows you how to build it.
</Note>
### How It Works
1. **A user messages the Slack Bot**
When a user in Slack sends a message to the Bot, the Slack Bot immediately issues a webhook request to the Dify platform.
2. **Slack forwards the message to the Slack Bot plugin**
The Dify platform triggers the Slack Bot plugin, which relays the message to the Dify application—much like an email system delivering to a recipient's address. You establish this connection by setting up a Slack webhook address through Slack's API and entering it in the plugin. The plugin processes the Slack request and forwards it to the Dify application, where the LLM analyzes the input and generates a response.
3. **The plugin returns the response to Slack**
Once the plugin receives the reply from the Dify application, it sends the LLM's answer back along the same route to the Slack Bot, so users get the response right where they're chatting.
## Prerequisites
* **Dify plugin development tool**: See [Initializing the Development Tool](/en/develop-plugin/getting-started/cli).
* **Python environment (version 3.12)**: See the [Python official downloads page](https://www.python.org/downloads/).
* **A Slack App with an OAuth token**: See the steps below.
To create the Slack App, go to the [Slack API platform](https://api.slack.com/apps), create an app from scratch, and pick the workspace where it will be deployed.
<Frame>
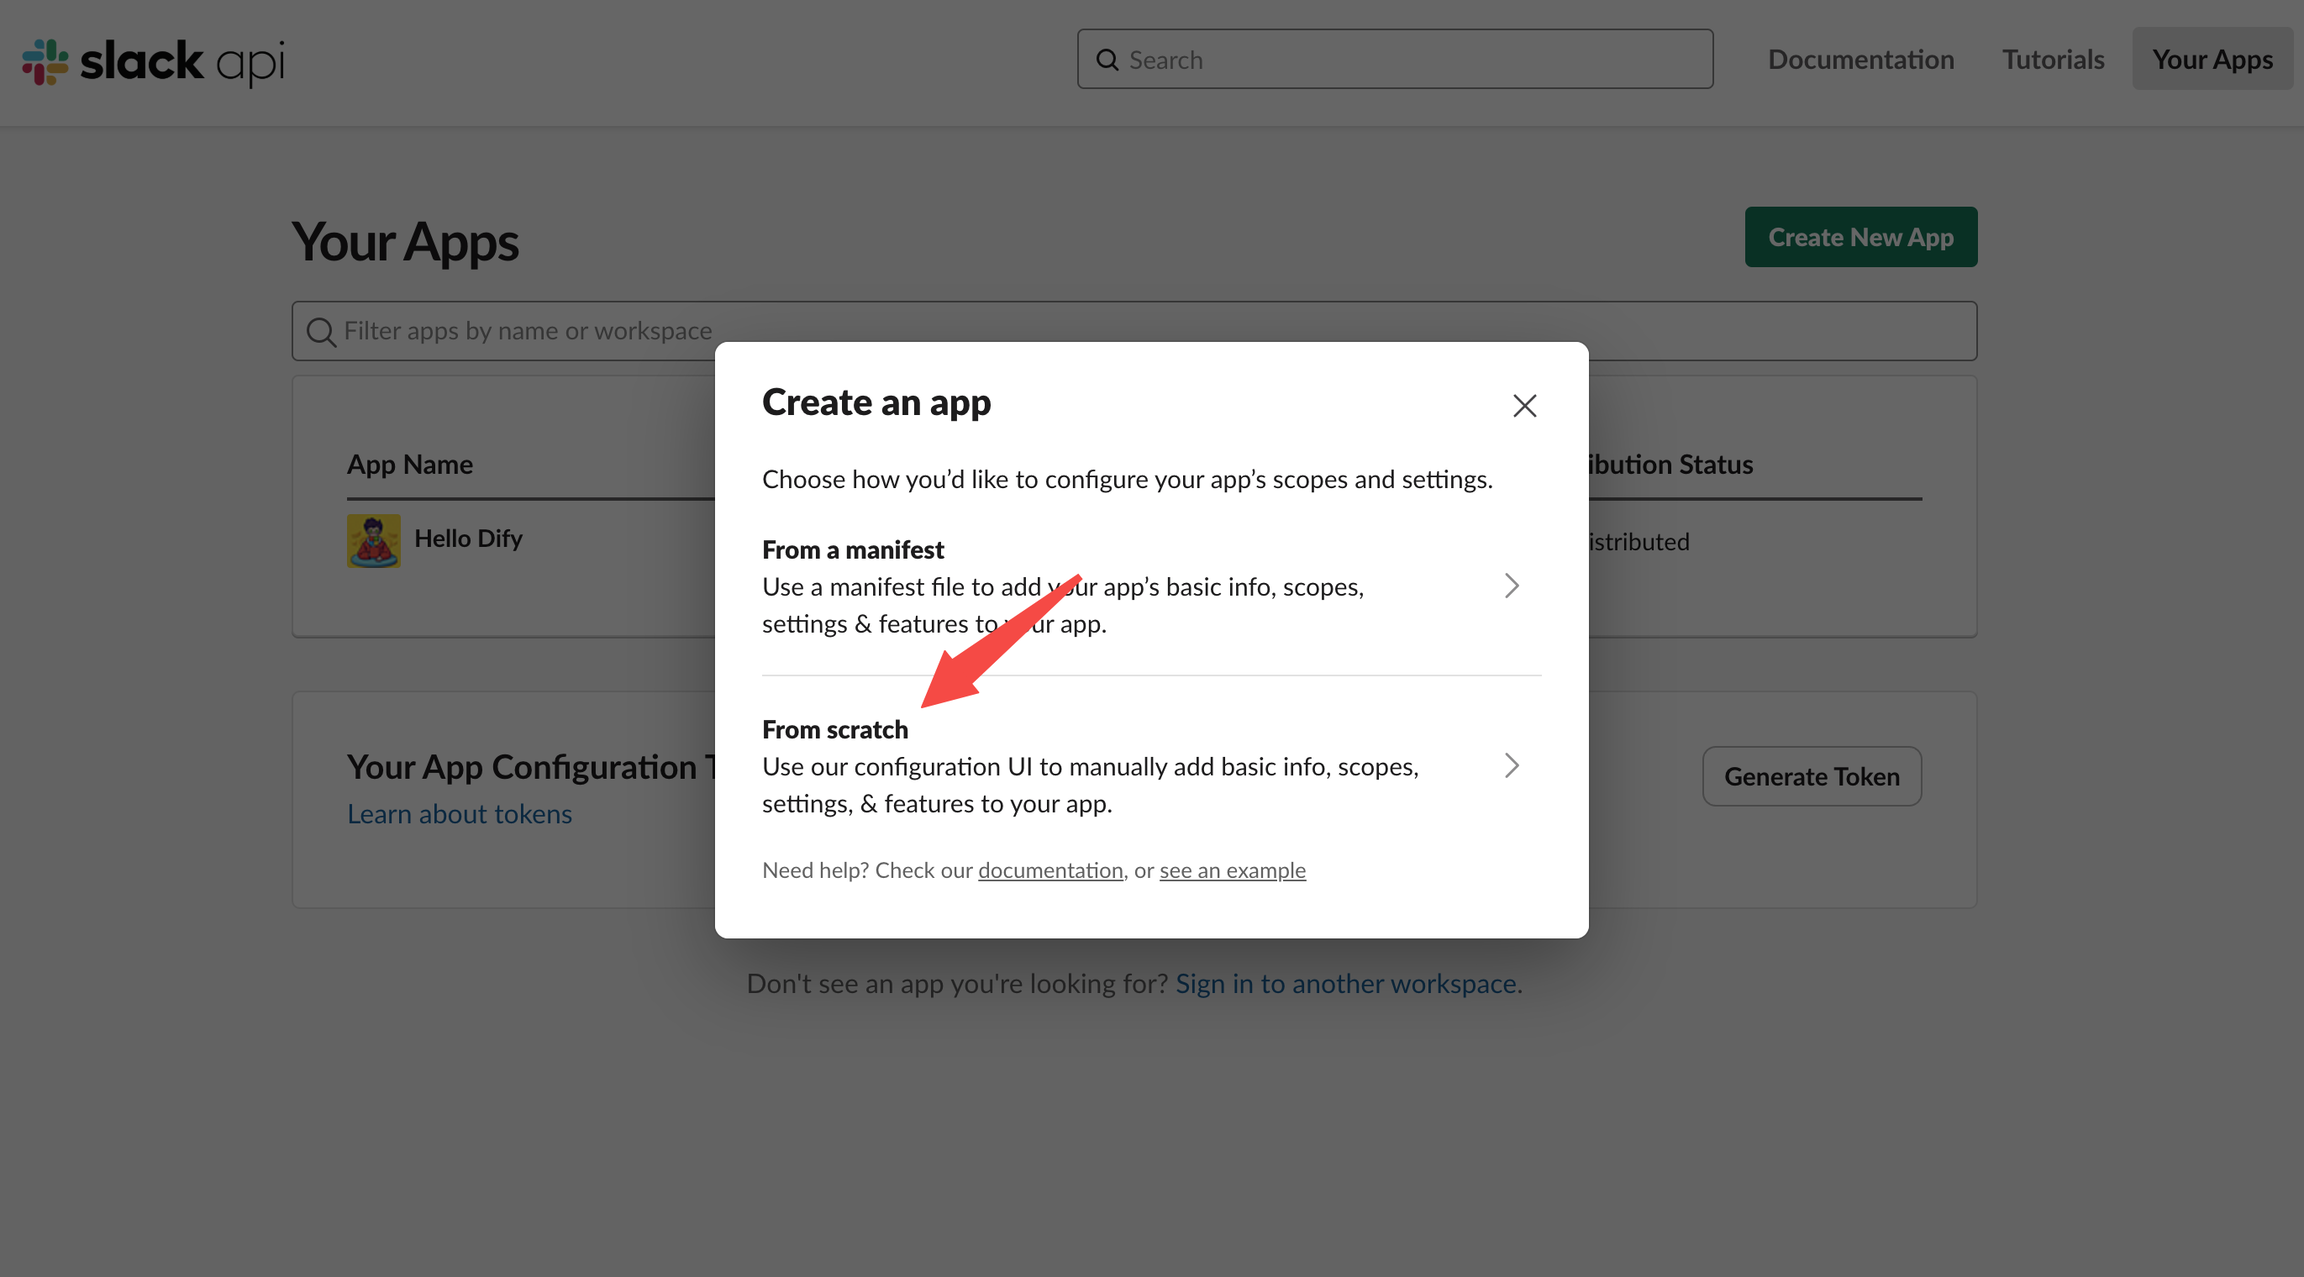
</Frame>
1. **Enable Webhooks**:
<Frame>
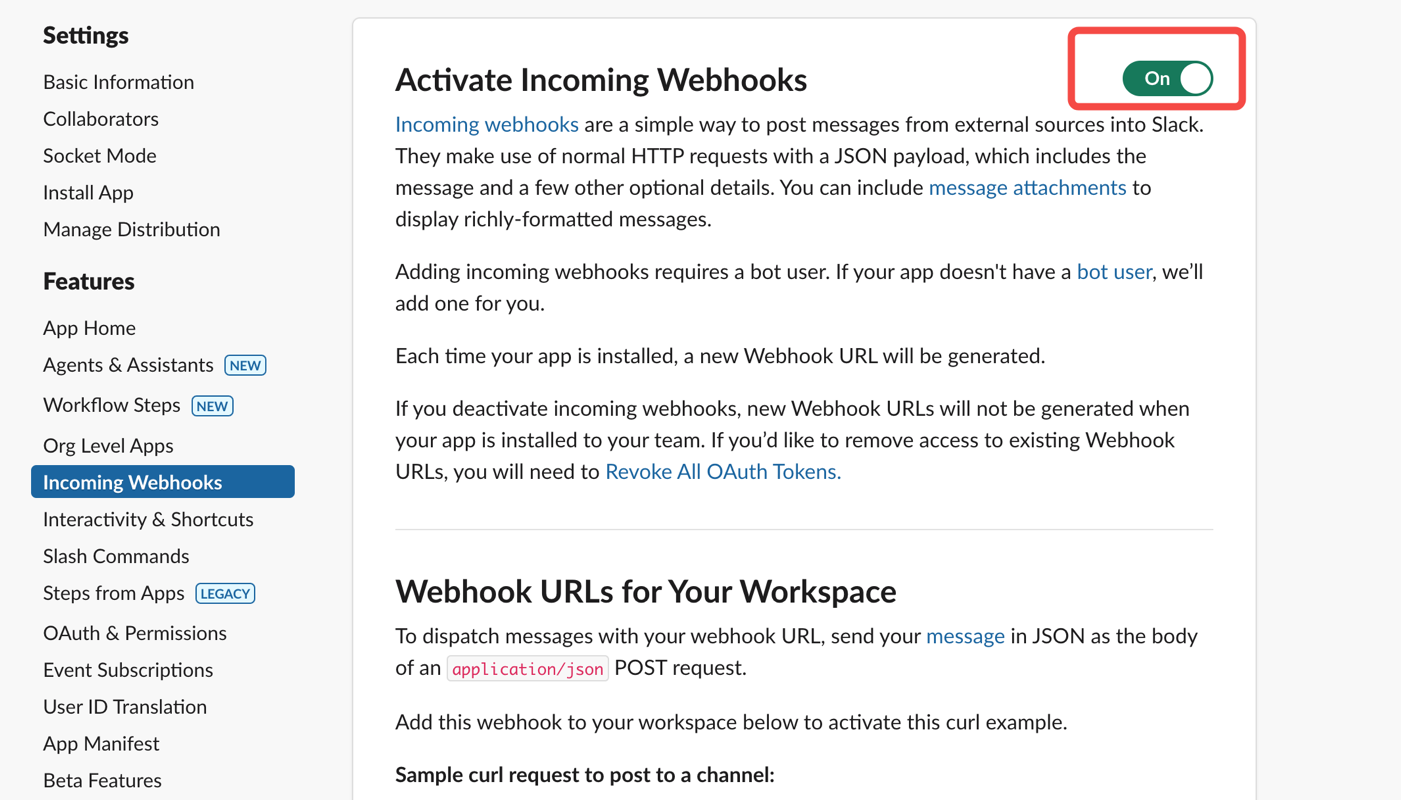
</Frame>
2. **Install the App in Your Slack Workspace**:
<Frame>
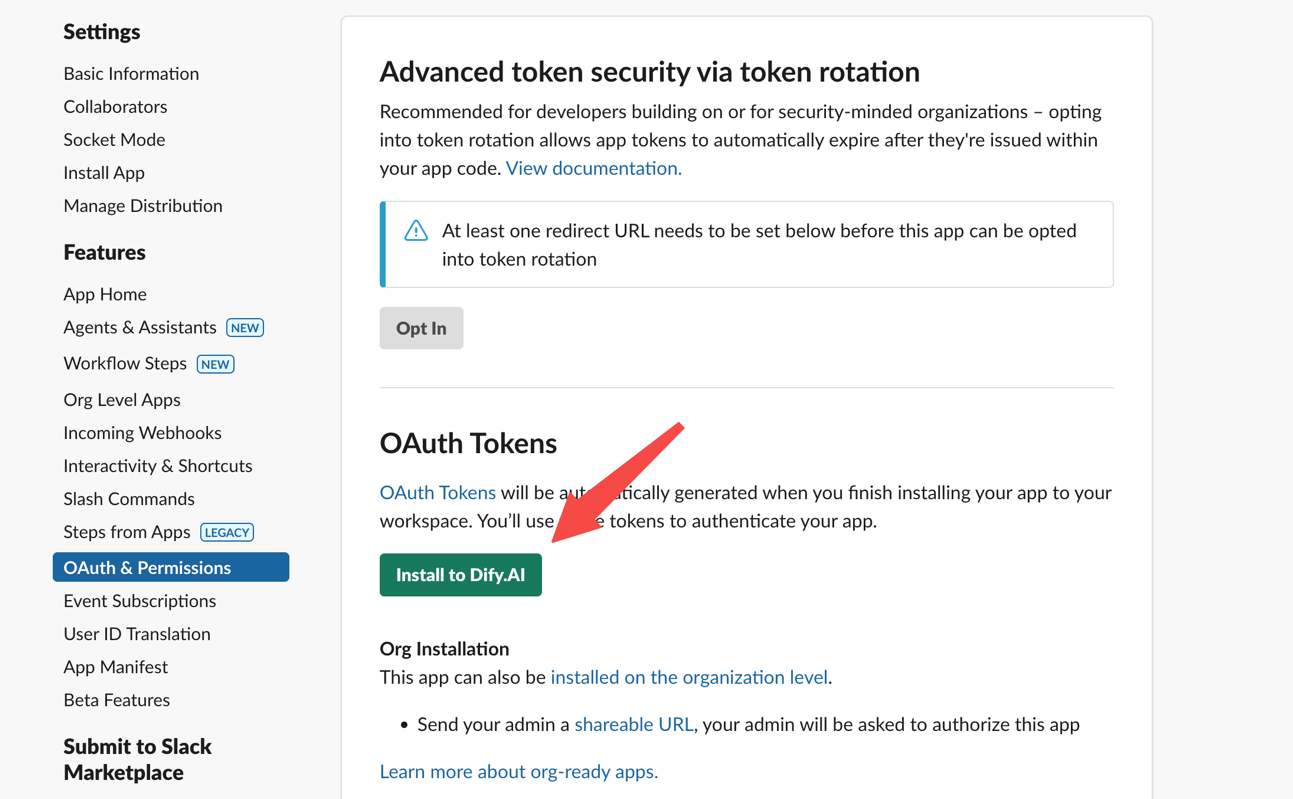
</Frame>
3. **Obtain an OAuth Token** for plugin development:
<Frame>
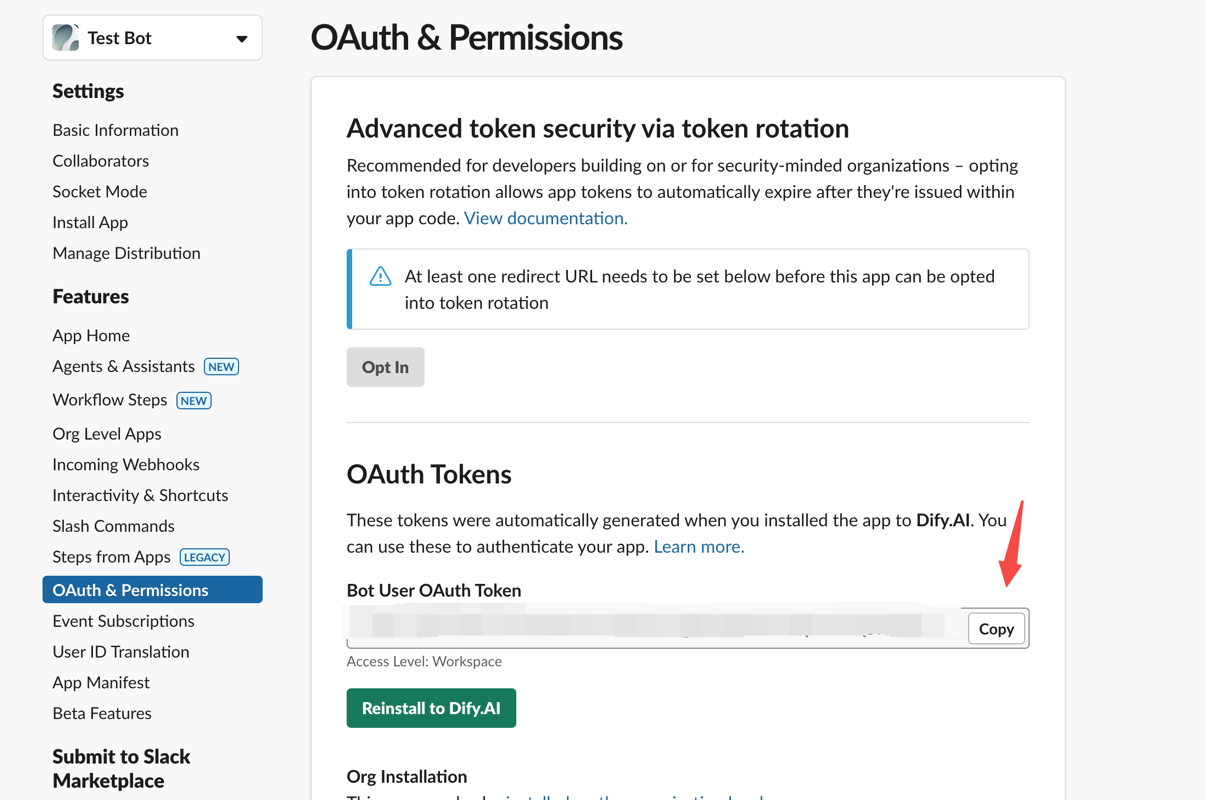
</Frame>
## 1. Develop the Plugin
Before you start coding, make sure you've read [Quick Start: Developing an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) or have built a Dify plugin before.
### 1.1 Initialize the Project
Run the following command to set up your plugin development environment:
```bash theme={null}
dify plugin init
```
Follow the prompts to provide basic project info. Select the `extension` template, and grant both `Apps` and `Endpoints` permissions.
For additional details on reverse-invoking Dify services within a plugin, see [Reverse Invocation: App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app).
<Frame>
</Frame>
### 1.2 Edit the Configuration Form
The plugin needs two pieces of information: which Dify app handles the replies, and the Slack App token that authenticates the bot's responses. Add both fields to the plugin's form.
Modify the YAML file in the `group` directory (for example, `group/slack.yaml`). The form's filename comes from the information you provided when creating the plugin, so adjust the path accordingly.
**Sample Code**:
`slack.yaml`
```yaml theme={null}
settings:
- name: bot_token
type: secret-input
required: true
label:
en_US: Bot Token
zh_Hans: Bot Token
pt_BR: Token do Bot
ja_JP: Bot Token
placeholder:
en_US: Please input your Bot Token
zh_Hans: 请输入你的 Bot Token
pt_BR: Por favor, insira seu Token do Bot
ja_JP: ボットトークンを入力してください
- name: allow_retry
type: boolean
required: false
label:
en_US: Allow Retry
zh_Hans: 允许重试
pt_BR: Permitir Retentativas
ja_JP: 再試行を許可
default: false
- name: app
type: app-selector
required: true
label:
en_US: App
zh_Hans: 应用
pt_BR: App
ja_JP: アプリ
placeholder:
en_US: the app you want to use to answer Slack messages
zh_Hans: 你想要用来回答 Slack 消息的应用
pt_BR: o app que você deseja usar para responder mensagens do Slack
ja_JP: あなたが Slack メッセージに回答するために使用するアプリ
endpoints:
- endpoints/slack.yaml
```
Two configuration fields deserve a closer look:
```yaml theme={null}
- name: app
type: app-selector
scope: chat
```
* **`type`**: Set to `app-selector`, which lets users forward messages to a specific Dify app when using this plugin.
* **`scope`**: Set to `chat`, meaning the plugin can only interact with app types such as agent, chatbot, or Chatflow.
Finally, in the `endpoints/slack.yaml` file, change the request method to `POST` so the endpoint can handle incoming Slack messages.
**Sample Code**:
`endpoints/slack.yaml`
```yaml theme={null}
path: "/"
method: "POST"
extra:
python:
source: "endpoints/slack.py"
```
## 2. Edit the Function Code
Modify the `endpoints/slack.py` file and add the following code:
```python theme={null}
import json
import traceback
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
from slack_sdk import WebClient
from slack_sdk.errors import SlackApiError
class SlackEndpoint(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
retry_num = r.headers.get("X-Slack-Retry-Num")
if (not settings.get("allow_retry") and (r.headers.get("X-Slack-Retry-Reason") == "http_timeout" or ((retry_num is not None and int(retry_num) > 0)))):
return Response(status=200, response="ok")
data = r.get_json()
# Handle Slack URL verification challenge
if data.get("type") == "url_verification":
return Response(
response=json.dumps({"challenge": data.get("challenge")}),
status=200,
content_type="application/json"
)
if (data.get("type") == "event_callback"):
event = data.get("event")
if (event.get("type") == "app_mention"):
message = event.get("text", "")
if message.startswith("<@"):
message = message.split("> ", 1)[1] if "> " in message else message
channel = event.get("channel", "")
blocks = event.get("blocks", [])
blocks[0]["elements"][0]["elements"] = blocks[0].get("elements")[0].get("elements")[1:]
token = settings.get("bot_token")
client = WebClient(token=token)
try:
response = self.session.app.chat.invoke(
app_id=settings["app"]["app_id"],
query=message,
inputs={},
response_mode="blocking",
)
try:
blocks[0]["elements"][0]["elements"][0]["text"] = response.get("answer")
result = client.chat_postMessage(
channel=channel,
text=response.get("answer"),
blocks=blocks
)
return Response(
status=200,
response=json.dumps(result),
content_type="application/json"
)
except SlackApiError as e:
raise e
except Exception as e:
err = traceback.format_exc()
return Response(
status=200,
response="Sorry, I'm having trouble processing your request. Please try again later." + str(err),
content_type="text/plain",
)
else:
return Response(status=200, response="ok")
else:
return Response(status=200, response="ok")
else:
return Response(status=200, response="ok")
```
## 3. Debug the Plugin
Go to the Dify platform and obtain the remote debugging address and key for your plugin.
<Frame>
</Frame>
Back in your plugin project, copy the `.env.example` file, rename it to `.env`, and fill in the debugging details:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Start the plugin:
```bash theme={null}
python -m main
```
You should now see the plugin installed in your Workspace on Dify's plugin management page, where other team members can also access it.
### Configure the Plugin Endpoint
On Dify's plugin management page, locate the newly installed test plugin and create a new endpoint. Enter a name and your **Bot Token**, then select the app you want to connect.
<Frame>
</Frame>
After saving, a **POST** request URL is generated:
<Frame>
</Frame>
Next, complete the Slack App setup:
1. **Enable Event Subscriptions**
<Frame>
</Frame>
Paste the POST request URL you generated above.
<Frame>
</Frame>
2. **Grant Required Permissions**
<Frame>
</Frame>
***
## 4. Verify the Plugin
The plugin calls the Dify application through `self.session.app.chat.invoke`, passing in parameters such as `app_id` and `query`, and returns the response to the Slack Bot. Run `python -m main` again to restart the plugin, then check that Slack displays the Dify app's reply:
<Frame>
</Frame>
***
## 5. Package the Plugin (Optional)
Once you confirm the plugin works correctly, package it with the following command. The command produces a `slack_bot.difypkg` file in the current directory—your final plugin package. For detailed packaging steps, see [Package as a Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file).
```bash theme={null}
# Replace ./slack_bot with your actual plugin project path.
dify plugin package ./slack_bot
```
Congratulations—you've developed, tested, and packaged a plugin!
***
## 6. Publish the Plugin (Optional)
You can now upload it to the [Dify Marketplace repository](https://github.com/langgenius/dify-plugins) for public release. Before publishing, ensure your plugin meets the [Publishing to Dify Marketplace Guidelines](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). Once approved, your code is merged into the main branch, and the plugin goes live on the [Dify Marketplace](https://marketplace.dify.ai/).
***
## Related Resources
* [Plugin Development Basics](/en/develop-plugin/getting-started/getting-started-dify-plugin): Comprehensive overview of Dify plugin development
* [Plugin Development Quick Start Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin): Start developing plugins from scratch
* [Develop an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Extension plugin development
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): How to call Dify platform capabilities
* [Reverse Invocation: App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app): How to call apps within the platform
* [Publishing Plugins](/en/develop-plugin/publishing/marketplace-listing/release-overview): The publishing process
* [Publishing to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace): Marketplace publishing guide
* [Endpoint Detailed Definition](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Endpoint reference
## Further Reading
For a complete Dify plugin project example, visit the [GitHub repository](https://github.com/langgenius/dify-plugins). You'll also find additional plugins with full source code and implementation details.
To explore more about plugin development, see the following:
**Quick Starts**:
* [Develop an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint)
* [Develop a Model Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)
* [Bundle Plugins: Packaging Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
**Plugin Interface Docs**:
* [Defining Plugin Information via Manifest File](/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest): Manifest structure
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Endpoint reference
* [Reverse Invocation](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Calling Dify capabilities from a plugin
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Tool specifications
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Model schema reference
# Flomo Tool (10-min)
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-flomo-plugin
Build a functional Dify tool plugin that connects to the Flomo note-taking service end-to-end in about ten minutes
## What You'll Build
By the end of this guide, you'll have created a Dify plugin that:
* Connects to the Flomo note-taking API
* Allows users to save notes from AI conversations directly to Flomo
* Handles authentication and error states properly
* Is ready for distribution in the Dify Marketplace
<CardGroup>
<Card title="Time required" icon="clock">
10 minutes
</Card>
<Card title="Prerequisites" icon="list-check">
Basic Python knowledge and a Flomo account
</Card>
</CardGroup>
## Step 1: Install the Dify Plugin CLI and Create a Project
<Steps>
<Step title="Install Dify Plugin CLI">
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Download the latest binary from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases). Pick `dify-plugin-linux-amd64` for x86\_64 or `dify-plugin-linux-arm64` for ARM.
```bash theme={null}
chmod +x dify-plugin-linux-amd64
sudo mv dify-plugin-linux-amd64 /usr/local/bin/dify
```
</Tab>
</Tabs>
Verify the installation:
```bash theme={null}
dify version
```
</Step>
<Step title="Initialize a plugin project">
Create a new plugin project using:
```bash theme={null}
dify plugin init
```
Follow the prompts to set up your plugin:
* Name it `flomo`
* Select `tool` as the plugin type
* Complete the other required fields
</Step>
<Step title="Navigate to the project">
```bash theme={null}
cd flomo
```
The project contains the basic structure for your plugin with all necessary files.
</Step>
</Steps>
## Step 2: Define Your Plugin Manifest
<Info>
The `manifest.yaml` file defines your plugin's metadata, permissions, and capabilities.
</Info>
Create a `manifest.yaml` file:
```yaml theme={null}
version: 0.0.4
type: plugin
author: yourname
label:
en_US: Flomo
zh_Hans: Flomo 浮墨笔记
created_at: "2023-10-01T00:00:00Z"
icon: icon.png
resource:
memory: 67108864 # 64MB
permission:
storage:
enabled: false
plugins:
tools:
- provider/flomo.yaml
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: 3.12
entrypoint: main
```
## Step 3: Create the Tool Definition
A tool plugin uses two YAML files: a **provider** file that declares credentials and lists the tools, and one **tool** file per callable tool. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the full schema.
Create `provider/flomo.yaml`:
```yaml theme={null}
identity:
author: yourname
name: flomo
label:
en_US: Flomo Note
zh_Hans: Flomo 浮墨笔记
description:
en_US: Add notes to your Flomo account directly from Dify.
zh_Hans: 直接从 Dify 添加笔记到您的 Flomo 账户。
icon: icon.png
credentials_for_provider:
api_url:
type: secret-input
required: true
label:
en_US: API URL
zh_Hans: API URL
placeholder:
en_US: https://flomoapp.com/iwh/{token}/{secret}/
help:
en_US: Flomo API URL from your Flomo account settings.
zh_Hans: 从您的 Flomo 账户设置中获取的 API URL。
tools:
- tools/flomo.yaml
extra:
python:
source: provider/flomo.py
```
Create `tools/flomo.yaml`:
```yaml theme={null}
identity:
name: flomo
author: yourname
label:
en_US: Save to Flomo
zh_Hans: 保存到 Flomo
description:
human:
en_US: Save the conversation content as a Flomo note.
zh_Hans: 将对话内容保存为 Flomo 笔记。
llm: >
Saves content to the user's Flomo account. Use this tool when the user
asks to save, capture, or remember the current message. Takes a single
`content` parameter containing the text to save.
parameters:
- name: content
type: string
required: true
label:
en_US: Note content
zh_Hans: 笔记内容
human_description:
en_US: Content to save as a note in Flomo.
zh_Hans: 要保存为 Flomo 笔记的内容。
llm_description: The text to save as a Flomo note.
form: llm
extra:
python:
source: tools/flomo.py
```
## Step 4: Implement Core Utility Functions
Create a utility module in `utils/flomo_utils.py` for API interaction:
<CodeGroup>
```python utils/flomo_utils.py theme={null}
import requests
def send_flomo_note(api_url: str, content: str) -> None:
"""
Send a note to Flomo via the API URL. Raises requests.RequestException on network errors,
and ValueError on invalid status codes or input.
"""
api_url = api_url.strip()
if not api_url:
raise ValueError("API URL is required and cannot be empty.")
if not api_url.startswith('https://flomoapp.com/iwh/'):
raise ValueError(
"API URL should be in the format: https://flomoapp.com/iwh/{token}/{secret}/"
)
if not content:
raise ValueError("Content cannot be empty.")
headers = {'Content-Type': 'application/json'}
response = requests.post(api_url, json={"content": content}, headers=headers, timeout=10)
if response.status_code != 200:
raise ValueError(f"API URL is not valid. Received status code: {response.status_code}")
```
</CodeGroup>
## Step 5: Implement the Tool Provider
The Tool Provider handles credential validation. Create `provider/flomo.py`:
<CodeGroup>
```python provider/flomo.py theme={null}
from typing import Any
from dify_plugin import ToolProvider
from dify_plugin.errors.tool import ToolProviderCredentialValidationError
import requests
from utils.flomo_utils import send_flomo_note
class FlomoProvider(ToolProvider):
def _validate_credentials(self, credentials: dict[str, Any]) -> None:
try:
api_url = credentials.get('api_url', '').strip()
# Use utility for validation and sending test note
send_flomo_note(api_url, "Hello, #flomo https://flomoapp.com")
except ValueError as e:
raise ToolProviderCredentialValidationError(str(e))
except requests.RequestException as e:
raise ToolProviderCredentialValidationError(f"Connection error: {str(e)}")
```
</CodeGroup>
## Step 6: Implement the Tool
The Tool class handles actual API calls when the user invokes the plugin. Create `tools/flomo.py`:
<CodeGroup>
```python tools/flomo.py theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
import requests
from utils.flomo_utils import send_flomo_note
class FlomoTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
content = tool_parameters.get("content", "")
api_url = self.runtime.credentials.get("api_url", "")
try:
send_flomo_note(api_url, content)
except ValueError as e:
yield self.create_text_message(str(e))
return
except requests.RequestException as e:
yield self.create_text_message(f"Connection error: {str(e)}")
return
# Return success message and structured data
yield self.create_text_message(
"Note created successfully! Your content has been sent to Flomo."
)
yield self.create_json_message({
"status": "success",
"content": content,
})
```
</CodeGroup>
<Warning>
Always handle exceptions gracefully and return user-friendly error messages. Remember that your plugin represents your brand in the Dify ecosystem.
</Warning>
## Step 7: Test Your Plugin
<Steps>
<Step title="Set up debug environment">
Copy the example environment file:
```bash theme={null}
cp .env.example .env
```
Edit the `.env` file with your Dify environment details:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=your_debug_key
```
You can find your debug URL and key in the Dify dashboard: click the **Plugins** icon in the top-right corner, then click the debug icon. Copy the **API Key** and **Host Address** (the host already includes the port).
</Step>
<Step title="Install dependencies and run">
```bash theme={null}
pip install -r requirements.txt
python -m main
```
Your plugin will connect to your Dify instance in debug mode.
</Step>
<Step title="Test functionality">
In your Dify instance, open the **Plugins** page and find your plugin (marked as **debugging**). Add your Flomo API credentials and test sending a note.
</Step>
</Steps>
## Step 8: Package and Distribute
When you're ready to share your plugin:
```bash theme={null}
dify plugin package ./
```
This creates a `plugin.difypkg` file you can upload to the Dify Marketplace.
## FAQ and Troubleshooting
<AccordionGroup title="Common issues and troubleshooting">
<Accordion title="Plugin doesn't appear in debug mode">
Make sure your `.env` file is properly configured and you're using the correct debug key.
</Accordion>
<Accordion title="API authentication errors">
Double-check your Flomo API URL format. It should be in the form: `https://flomoapp.com/iwh/{token}/{secret}/`
</Accordion>
<Accordion title="Packaging fails">
Ensure all required files are present and the `manifest.yaml` structure is valid.
</Accordion>
</AccordionGroup>
## Summary
You've built a functioning Dify plugin that connects with an external API service. The same pattern works for integrating with thousands of services—from databases and search engines to productivity tools and custom APIs.
<CardGroup>
<Card title="Documentation" icon="book">
Write your `README.md` in English (en\_US) describing functionality, setup, and usage examples
</Card>
<Card title="Localization" icon="language">
Create additional README files like `readme/README_zh_Hans.md` for other languages
</Card>
</CardGroup>
<CheckList>
<CheckListItem>
Add a privacy policy (PRIVACY.md) if publishing your plugin
</CheckListItem>
<CheckListItem>
Include comprehensive examples in documentation
</CheckListItem>
<CheckListItem>
Test thoroughly with various document sizes and formats
</CheckListItem>
</CheckList>
# Markdown Exporter
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-md-exporter
Learn how to create a plugin that exports conversations to different document formats
## What You'll Build
You'll build a practical Dify plugin that exports conversations into popular document formats. By the end, your plugin will:
* Convert markdown text to Word documents (.docx)
* Export conversations as PDF files
* Handle file creation with proper formatting
* Provide a clean user experience for document exports
<CardGroup>
<Card title="Time required" icon="clock">
15 minutes
</Card>
<Card title="Prerequisites" icon="list-check">
Basic Python knowledge and familiarity with document manipulation libraries
</Card>
</CardGroup>
## Step 1: Set Up Your Environment
<Steps>
<Step title="Install the Dify Plugin CLI">
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Get the latest Dify Plugin CLI from the [Dify GitHub releases page](https://github.com/langgenius/dify-plugin-daemon/releases).
```bash theme={null}
# Download appropriate version
chmod +x dify-plugin-linux-amd64
mv dify-plugin-linux-amd64 dify
sudo mv dify /usr/local/bin/
```
</Tab>
</Tabs>
Verify installation:
```bash theme={null}
dify version
```
</Step>
<Step title="Create the plugin project">
Initialize a new plugin project:
```bash theme={null}
dify plugin init
```
Follow the prompts:
* **Name**: `md_exporter`
* **Type**: `tool`
* Complete the remaining details as prompted.
</Step>
</Steps>
## Step 2: Define the Plugin Manifest
Create the `manifest.yaml` file to define your plugin's metadata:
```yaml theme={null}
version: 0.0.4
type: plugin
author: your_username
label:
en_US: Markdown Exporter
zh_Hans: Markdown导出工具
created_at: "2025-09-30T00:00:00Z"
icon: icon.png
resource:
memory: 134217728 # 128MB
permission:
storage:
enabled: true # We need storage for temp files
plugins:
tools:
- word_export.yaml
- pdf_export.yaml
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: 3.12
entrypoint: main
```
## Step 3: Define the Word Export Tool
Create a `word_export.yaml` file to define the Word document export tool:
```yaml theme={null}
identity:
author: your_username
name: word_export
label:
en_US: Export to Word
zh_Hans: 导出为Word文档
description:
human:
en_US: Export conversation content to a Word document (.docx)
zh_Hans: 将对话内容导出为Word文档(.docx)
llm: >
A tool that converts markdown text to a Word document (.docx) format.
Use this tool when the user wants to save or export the conversation
content as a Word document. The input text should be in markdown format.
credential_schema: {} # No credentials needed
tool_schema:
markdown_content:
type: string
required: true
label:
en_US: Markdown Content
zh_Hans: Markdown内容
human_description:
en_US: The markdown content to convert to Word format
zh_Hans: 要转换为Word格式的Markdown内容
document_name:
type: string
required: false
label:
en_US: Document Name
zh_Hans: 文档名称
human_description:
en_US: Name for the exported document (without extension)
zh_Hans: 导出文档的名称(无需扩展名)
```
## Step 4: Define the PDF Export Tool
Create a `pdf_export.yaml` file for PDF exports:
```yaml theme={null}
identity:
author: your_username
name: pdf_export
label:
en_US: Export to PDF
zh_Hans: 导出为PDF文档
description:
human:
en_US: Export conversation content to a PDF document
zh_Hans: 将对话内容导出为PDF文档
llm: >
A tool that converts markdown text to a PDF document.
Use this tool when the user wants to save or export the conversation
content as a PDF file. The input text should be in markdown format.
credential_schema: {} # No credentials needed
tool_schema:
markdown_content:
type: string
required: true
label:
en_US: Markdown Content
zh_Hans: Markdown内容
human_description:
en_US: The markdown content to convert to PDF format
zh_Hans: 要转换为PDF格式的Markdown内容
document_name:
type: string
required: false
label:
en_US: Document Name
zh_Hans: 文档名称
human_description:
en_US: Name for the exported document (without extension)
zh_Hans: 导出文档的名称(无需扩展名)
```
## Step 5: Install Required Dependencies
Create or update `requirements.txt` with the necessary libraries:
```text theme={null}
python-docx>=0.8.11
markdown>=3.4.1
weasyprint>=59.0
beautifulsoup4>=4.12.2
```
## Step 6: Implement the Word Export
Create a utility module in `utils/docx_utils.py`:
<CodeGroup>
```python utils/docx_utils.py theme={null}
import os
import tempfile
import uuid
from docx import Document
from docx.shared import Pt
from docx.enum.text import WD_PARAGRAPH_ALIGNMENT
import markdown
from bs4 import BeautifulSoup
def convert_markdown_to_docx(markdown_text, document_name=None):
"""
Convert markdown text to a Word document and return the file path
"""
if not document_name:
document_name = f"exported_document_{uuid.uuid4().hex[:8]}"
# Convert markdown to HTML
html = markdown.markdown(markdown_text)
soup = BeautifulSoup(html, 'html.parser')
# Create a new Word document
doc = Document()
# Process HTML elements and add to document
for element in soup.find_all(['h1', 'h2', 'h3', 'h4', 'p', 'ul', 'ol']):
if element.name == 'h1':
heading = doc.add_heading(element.text.strip(), level=1)
heading.alignment = WD_PARAGRAPH_ALIGNMENT.CENTER
elif element.name == 'h2':
doc.add_heading(element.text.strip(), level=2)
elif element.name == 'h3':
doc.add_heading(element.text.strip(), level=3)
elif element.name == 'h4':
doc.add_heading(element.text.strip(), level=4)
elif element.name == 'p':
paragraph = doc.add_paragraph(element.text.strip())
elif element.name in ('ul', 'ol'):
for li in element.find_all('li'):
doc.add_paragraph(li.text.strip(), style='ListBullet')
# Create temp directory if it doesn't exist
temp_dir = tempfile.gettempdir()
if not os.path.exists(temp_dir):
os.makedirs(temp_dir)
# Save the document
file_path = os.path.join(temp_dir, f"{document_name}.docx")
doc.save(file_path)
return file_path
```
</CodeGroup>
## Step 7: Implement the PDF Export
Create a utility module in `utils/pdf_utils.py`:
<CodeGroup>
```python utils/pdf_utils.py theme={null}
import os
import tempfile
import uuid
import markdown
from weasyprint import HTML, CSS
from weasyprint.text.fonts import FontConfiguration
def convert_markdown_to_pdf(markdown_text, document_name=None):
"""
Convert markdown text to a PDF document and return the file path
"""
if not document_name:
document_name = f"exported_document_{uuid.uuid4().hex[:8]}"
# Convert markdown to HTML
html_content = markdown.markdown(markdown_text)
# Add basic styling
styled_html = f"""
<!DOCTYPE html>
<html>
<head>
<meta charset="UTF-8">
<title>{document_name}</title>
<style>
body {{ font-family: Arial, sans-serif; margin: 40px; line-height: 1.6; }}
h1 {{ text-align: center; color: #333; }}
h2, h3, h4 {{ color: #444; margin-top: 20px; }}
p {{ margin-bottom: 15px; }}
ul, ol {{ margin-left: 20px; }}
</style>
</head>
<body>
{html_content}
</body>
</html>
"""
# Create temp directory if it doesn't exist
temp_dir = tempfile.gettempdir()
if not os.path.exists(temp_dir):
os.makedirs(temp_dir)
# Output file path
file_path = os.path.join(temp_dir, f"{document_name}.pdf")
# Configure fonts
font_config = FontConfiguration()
# Render PDF
HTML(string=styled_html).write_pdf(
file_path,
stylesheets=[],
font_config=font_config
)
return file_path
```
</CodeGroup>
## Step 8: Create the Tool Implementations
First, create the Word export tool in `tools/word_export.py`:
<CodeGroup>
```python tools/word_export.py theme={null}
import os
import base64
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from utils.docx_utils import convert_markdown_to_docx
class WordExportTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Extract parameters
markdown_content = tool_parameters.get("markdown_content", "")
document_name = tool_parameters.get("document_name", "exported_document")
if not markdown_content:
yield self.create_text_message("Error: No content provided for export.")
return
try:
# Convert markdown to Word
file_path = convert_markdown_to_docx(markdown_content, document_name)
# Read the file as binary
with open(file_path, 'rb') as file:
file_content = file.read()
# Encode as base64
file_base64 = base64.b64encode(file_content).decode('utf-8')
# Return success message and file
yield self.create_text_message(
f"Document exported successfully as Word (.docx) format."
)
yield self.create_file_message(
file_name=f"{document_name}.docx",
file_content=file_base64,
mime_type="application/vnd.openxmlformats-officedocument.wordprocessingml.document"
)
except Exception as e:
yield self.create_text_message(f"Error exporting to Word: {str(e)}")
return
```
</CodeGroup>
Next, create the PDF export tool in `tools/pdf_export.py`:
<CodeGroup>
```python tools/pdf_export.py theme={null}
import os
import base64
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from utils.pdf_utils import convert_markdown_to_pdf
class PDFExportTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Extract parameters
markdown_content = tool_parameters.get("markdown_content", "")
document_name = tool_parameters.get("document_name", "exported_document")
if not markdown_content:
yield self.create_text_message("Error: No content provided for export.")
return
try:
# Convert markdown to PDF
file_path = convert_markdown_to_pdf(markdown_content, document_name)
# Read the file as binary
with open(file_path, 'rb') as file:
file_content = file.read()
# Encode as base64
file_base64 = base64.b64encode(file_content).decode('utf-8')
# Return success message and file
yield self.create_text_message(
f"Document exported successfully as PDF format."
)
yield self.create_file_message(
file_name=f"{document_name}.pdf",
file_content=file_base64,
mime_type="application/pdf"
)
except Exception as e:
yield self.create_text_message(f"Error exporting to PDF: {str(e)}")
return
```
</CodeGroup>
## Step 9: Create the Entrypoint
Create a `main.py` file at the root of your project:
<CodeGroup>
```python main.py theme={null}
from dify_plugin import PluginRunner
from tools.word_export import WordExportTool
from tools.pdf_export import PDFExportTool
plugin = PluginRunner(
tools=[
WordExportTool(),
PDFExportTool(),
],
providers=[] # No credential providers needed
)
```
</CodeGroup>
## Step 10: Test Your Plugin
<Steps>
<Step title="Set up your debug environment">
First, create your `.env` file from the template:
```bash theme={null}
cp .env.example .env
```
Configure it with your Dify environment details:
```dotenv theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=your_debug_key
```
</Step>
<Step title="Install dependencies">
```bash theme={null}
pip install -r requirements.txt
```
</Step>
<Step title="Start the plugin in debug mode">
```bash theme={null}
python -m main
```
</Step>
</Steps>
## Step 11: Package for Distribution
When you're ready to share your plugin:
```bash theme={null}
dify plugin package ./
```
This creates a `plugin.difypkg` file for distribution.
## Creative Use Cases
<CardGroup>
<Card title="Report generation" icon="file-lines">
Use this plugin to convert analysis summaries into professional reports for clients
</Card>
<Card title="Session documentation" icon="book">
Export coaching or consulting session notes as formatted documents
</Card>
</CardGroup>
## Beyond the Basics
Here are some interesting ways to extend this plugin:
* **Custom templates**: Add company branding or personalized styles.
* **Multi-format support**: Expand to export as HTML, Markdown, or other formats.
* **Image handling**: Process and include images from conversations.
* **Table support**: Implement proper formatting for data tables.
* **Collaborative editing**: Add integration with Google Docs or similar platforms.
<Accordion title="Technical Insights">
The core challenge in document conversion is maintaining formatting and structure. This plugin first converts markdown to HTML as an intermediate format, then processes that HTML into the target format.
The two-step process provides flexibility: you can support additional formats by adding new output modules that work with the HTML representation.
For PDF generation, the plugin uses WeasyPrint because it offers high-quality PDF rendering with CSS support. For Word documents, python-docx provides granular control over document structure.
</Accordion>
## Summary
You've built a practical plugin that lets users export conversations in professional document formats, bridging the gap between AI conversations and traditional document workflows.
<CardGroup>
<Card title="Documentation" icon="book">
Write your README.md in English (en\_US) describing functionality, setup, and usage examples
</Card>
<Card title="Localization" icon="language">
Create additional README files like `readme/README_zh_Hans.md` for other languages
</Card>
</CardGroup>
<CheckList>
<CheckListItem>
Add a privacy policy (PRIVACY.md) if publishing your plugin
</CheckListItem>
<CheckListItem>
Include comprehensive examples in documentation
</CheckListItem>
<CheckListItem>
Test thoroughly with various document sizes and formats
</CheckListItem>
</CheckList>
# Multimodal Tool
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-multimodal-data-processing-tool
Configure a tool plugin to emit images, audio, or video so the Knowledge Base node can embed multimodal outputs alongside text
In knowledge pipelines, the Knowledge Base node supports input in two multimodal data formats: `multimodal-Parent-Child` and `multimodal-General`.
For the Knowledge Base node to recognize and embed a tool plugin's multimodal output (such as text, images, audio, or video), complete two configurations:
* **In the tool code file**: Call the tool session interface to upload files and construct the `files` object.
* **In the tool provider YAML file**: Declare the `output_schema` as either `multimodal-Parent-Child` or `multimodal-General`.
## Upload Files and Construct File Objects
When processing multimodal data such as images, first upload the file through Dify's tool session to obtain the file metadata.
The following example, taken from the official **Dify Extractor** plugin, shows how to upload a file and construct a `files` object.
```python theme={null}
# Upload the file using the tool session
file_res = self._tool.session.file.upload(
file_name, # filename
file_blob, # file binary data
mime_type, # MIME type, e.g., "image/png"
)
# Generate a Markdown image reference using the file preview URL
image_url = f""
```
The upload interface returns an `UploadFileResponse` object containing the file information:
```python theme={null}
from enum import Enum
from pydantic import BaseModel
class UploadFileResponse(BaseModel):
class Type(str, Enum):
DOCUMENT = "document"
IMAGE = "image"
VIDEO = "video"
AUDIO = "audio"
@classmethod
def from_mime_type(cls, mime_type: str):
if mime_type.startswith("image/"):
return cls.IMAGE
if mime_type.startswith("video/"):
return cls.VIDEO
if mime_type.startswith("audio/"):
return cls.AUDIO
return cls.DOCUMENT
id: str
name: str
size: int
extension: str
mime_type: str
type: Type | None = None
preview_url: str | None = None
```
Map the file information (`name`, `size`, `extension`, `mime_type`, and so on) to the `files` field in the multimodal output structure.
<CodeGroup>
```json multimodal_parent_child_structure highlight={22-62} expandable theme={null}
{
"$id": "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json",
"$schema": "http://json-schema.org/draft-07/schema#",
"version": "1.0.0",
"type": "object",
"title": "Multimodal Parent-Child Structure",
"description": "Schema for multimodal parent-child structure (v1)",
"properties": {
"parent_mode": {
"type": "string",
"description": "The mode of parent-child relationship"
},
"parent_child_chunks": {
"type": "array",
"items": {
"type": "object",
"properties": {
"parent_content": {
"type": "string",
"description": "The parent content"
},
"files": {
"type": "array",
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"description": "file name"
},
"size": {
"type": "number",
"description": "file size"
},
"extension": {
"type": "string",
"description": "file extension"
},
"type": {
"type": "string",
"description": "file type"
},
"mime_type": {
"type": "string",
"description": "file mime type"
},
"transfer_method": {
"type": "string",
"description": "file transfer method"
},
"url": {
"type": "string",
"description": "file url"
},
"related_id": {
"type": "string",
"description": "file related id"
}
},
"required": ["name", "size", "extension", "type", "mime_type", "transfer_method", "url", "related_id"]
},
"description": "List of files"
},
"child_contents": {
"type": "array",
"items": {
"type": "string"
},
"description": "List of child contents"
}
},
"required": ["parent_content", "child_contents"]
},
"description": "List of parent-child chunk pairs"
}
},
"required": ["parent_mode", "parent_child_chunks"]
}
```
```json multimodal_general_structure highlight={18-56} expandable theme={null}
{
"$id": "https://dify.ai/schemas/v1/multimodal_general_structure.json",
"$schema": "http://json-schema.org/draft-07/schema#",
"version": "1.0.0",
"type": "array",
"title": "Multimodal General Structure",
"description": "Schema for multimodal general structure (v1) - array of objects",
"properties": {
"general_chunks": {
"type": "array",
"items": {
"type": "object",
"properties": {
"content": {
"type": "string",
"description": "The content"
},
"files": {
"type": "array",
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"description": "file name"
},
"size": {
"type": "number",
"description": "file size"
},
"extension": {
"type": "string",
"description": "file extension"
},
"type": {
"type": "string",
"description": "file type"
},
"mime_type": {
"type": "string",
"description": "file mime type"
},
"transfer_method": {
"type": "string",
"description": "file transfer method"
},
"url": {
"type": "string",
"description": "file url"
},
"related_id": {
"type": "string",
"description": "file related id"
}
},
"description": "List of files"
}
}
},
"required": ["content"]
},
"description": "List of content and files"
}
}
}
```
</CodeGroup>
## Declare Multimodal Output Structure
Dify's official JSON schemas define the structure of multimodal data.
To let the Knowledge Base node recognize the plugin's multimodal output type, point the `result` field under `output_schema` in the plugin's provider YAML file to the corresponding official schema URL.
```yaml theme={null}
output_schema:
type: object
properties:
result:
# multimodal-Parent-Child
$ref: "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json"
# multimodal-General
# $ref: "https://dify.ai/schemas/v1/multimodal_general_structure.json"
```
For example, a complete YAML configuration using `multimodal-Parent-Child` looks like this:
```yaml expandable theme={null}
identity:
name: multimodal_tool
author: langgenius
label:
en_US: multimodal tool
zh_Hans: 多模态提取器
pt_BR: multimodal tool
description:
human:
en_US: Process documents into multimodal-Parent-Child chunk structures
zh_Hans: 将文档处理为多模态父子分块结构
pt_BR: Processar documentos em estruturas de divisão pai-filho
llm: Processes documents into hierarchical multimodal-Parent-Child chunk structures
parameters:
- name: input_text
human_description:
en_US: The text you want to chunk.
zh_Hans: 输入文本
pt_BR: Conteúdo de Entrada
label:
en_US: Input Content
zh_Hans: 输入文本
pt_BR: Conteúdo de Entrada
llm_description: The text you want to chunk.
required: true
type: string
form: llm
output_schema:
type: object
properties:
result:
$ref: "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json"
extra:
python:
source: tools/parent_child_chunk.py
```
# Endpoint Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/endpoint
Define, configure, and implement HTTP Endpoints in a Dify plugin, using the Neko Cat project as an example
Endpoints are HTTP interfaces exposed by a plugin for integration with external systems. This guide explains their structure using the [Neko Cat](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/neko) project as an example. For the complete plugin code, see the [GitHub repository](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/neko).
## Group Definition
An Endpoint group is a collection of multiple Endpoints. When you create a new Endpoint in a Dify plugin, you may need to fill in the following configuration.
<Frame>
</Frame>
Besides the **Endpoint Name**, you can add form items by writing the group's configuration. After saving, you can see the multiple interfaces the group contains, all sharing the same configuration.
<Frame>
</Frame>
### Structure
* **`settings`** (map\[string] [ProviderConfig](/en/develop-plugin/features-and-specs/plugin-types/general-specifications#providerconfig)): Endpoint configuration definition.
* **`endpoints`** (list\[string], required): Points to the specific `endpoint` interface definitions.
```yaml theme={null}
settings:
api_key:
type: secret-input
required: true
label:
en_US: API key
zh_Hans: API key
ja_Jp: API key
pt_BR: API key
placeholder:
en_US: Please input your API key
zh_Hans: 请输入你的 API key
ja_Jp: あなたの API key を入れてください
pt_BR: Por favor, insira sua chave API
endpoints:
- endpoints/duck.yaml
- endpoints/neko.yaml
```
## Interface Definition
* **`path`** (string): Follows the Werkzeug interface standard.
* **`method`** (string): Interface method; supports only `HEAD`, `GET`, `POST`, `PUT`, `DELETE`, and `OPTIONS`.
* **`extra`** (object): Configuration information beyond the basic details.
* **`python`** (object)
* **`source`** (string): The source code that implements this interface.
```yaml theme={null}
path: "/duck/<app_id>"
method: "GET"
extra:
python:
source: "endpoints/duck.py"
```
## Interface Implementation
Implement a subclass of `dify_plugin.Endpoint` and its `_invoke` method.
* **Input parameters**
* **`r`** (Request): The `Request` object from `werkzeug`.
* **`values`** (Mapping): Path parameters parsed from the path.
* **`settings`** (Mapping): Configuration information for this Endpoint.
* **Return**
* A `Response` object from `werkzeug`; streaming responses are supported.
* Returning a string directly is not supported.
Example code:
```python theme={null}
import json
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
class Duck(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
app_id = values["app_id"]
def generator():
yield f"{app_id} <br>"
return Response(generator(), status=200, content_type="text/html")
```
## Notes
* Endpoints are only instantiated when the plugin is called; they are not long-running services.
* Pay attention to security when developing Endpoints, and avoid executing dangerous operations.
* Endpoints can handle webhook callbacks or provide interfaces for other systems to connect to.
If you're new to plugin development, start with [Getting Started with Plugin Development](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) and the [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet).
## Related Resources
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin): The overall architecture of plugin development.
* [Neko Cat Example](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): An example of extension plugin development.
* [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Common structures like ProviderConfig.
* [Develop a Slack Bot Plugin Example](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin): Another plugin development example.
* [Getting Started with Plugin Development](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin): Develop a plugin from scratch.
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app): Use the reverse invocation feature.
# Tool OAuth
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth
Replace manual API-key entry with an OAuth authorization flow so users grant access to third-party services with one click
<Frame>
<img alt="OAuth Authorize Example" />
</Frame>
This guide teaches you how to build [OAuth](https://oauth.net/2/) support into your tool plugin.
OAuth is a better way to authorize tool plugins that need to access user data from third-party services, like Gmail or GitHub. Instead of requiring the user to manually enter API keys, OAuth lets the tool act on behalf of the user with their explicit consent.
## Background
OAuth in Dify involves **two separate flows** that developers should understand and design for.
```mermaid theme={null}
sequenceDiagram
autonumber
participant Admin as Admin / Developer
participant Service as Third-party Service
participant Dify
participant User
rect rgb(235, 245, 255)
Note over Admin,Dify: Flow 1: One-time OAuth client setup
Admin->>Service: Register OAuth app
Service-->>Admin: client_id + client_secret
Admin->>Dify: Configure plugin OAuth client
end
rect rgb(245, 255, 235)
Note over User,Service: Flow 2: Per-user authorization
User->>Dify: Click "Authorize"
Dify->>Service: Redirect to consent screen
User->>Service: Approve
Service-->>Dify: Authorization code
Dify->>Service: Exchange for access token
Service-->>Dify: Access + refresh tokens
Dify-->>User: Tool ready to use
end
```
### Flow 1: OAuth Client Setup (Admin / Developer Flow)
<Note>
On Dify Cloud, the Dify team creates OAuth apps for popular tool plugins and sets up OAuth clients, so users don't need to configure this themselves.
Admins of self-hosted Dify instances must go through this setup flow.
</Note>
Admins or developers of a Dify instance first register an OAuth app with the third-party service as a trusted application. This provides the credentials needed to configure the Dify tool provider as an OAuth client.
As an example, here are the steps to set up an OAuth client for Dify's Gmail tool provider:
<AccordionGroup>
<Accordion title="Create a Google Cloud Project">
1. Go to [Google Cloud Console](https://console.cloud.google.com) and create a new project, or select an existing one.
2. Enable the required APIs (e.g., Gmail API).
</Accordion>
<Accordion title="Configure the OAuth Consent Screen">
1. Navigate to **APIs & Services** > **OAuth consent screen**.
2. Choose the **External** user type for public plugins.
3. Fill in the application name, user support email, and developer contact.
4. Add authorized domains if needed.
5. For testing, add test users in the **Test users** section.
</Accordion>
<Accordion title="Create OAuth 2.0 Credentials">
1. Go to **APIs & Services** > **Credentials**.
2. Click **Create Credentials** > **OAuth 2.0 Client IDs**.
3. Choose the **Web application** type.
4. A `client_id` and a `client_secret` will be generated. Save these as the credentials.
</Accordion>
<Accordion title="Enter Credentials in Dify">
Enter the `client_id` and `client_secret` in the OAuth Client configuration popup to set up the tool provider as a client.
<Frame>
<img alt="OAuth Client Settings Dialog" />
</Frame>
</Accordion>
<Accordion title="Authorize Redirect URI">
Register the redirect URI generated by Dify on the Google OAuth Client's page:
<Frame>
<img alt="OAuth Google Redirect URI" />
</Frame>
<Info>
Dify displays the `redirect_uri` in the OAuth Client configuration popup. It usually follows the format:
```bash theme={null}
https://{your-dify-domain}/console/api/oauth/plugin/{plugin-id}/{provider-name}/{tool-name}/callback
```
For self-hosted Dify, `your-dify-domain` should match `CONSOLE_WEB_URL`.
</Info>
</Accordion>
</AccordionGroup>
<Tip>
Each service has unique requirements, so always consult the specific OAuth documentation for the services you're integrating with.
</Tip>
### Flow 2: User Authorization (Dify User Flow)
After configuring OAuth clients, individual Dify users can now authorize your plugin to access their personal accounts.
<Frame>
<img alt="OAuth User Authorization" />
</Frame>
## Implementation
### 1. Define OAuth Schema in Provider Manifest
The `oauth_schema` section of the provider manifest tells Dify what credentials your plugin's OAuth setup needs and what the OAuth flow produces. Setting up OAuth requires two schemas:
#### client\_schema
Defines the input for OAuth client setup:
```yaml gmail.yaml theme={null}
oauth_schema:
client_schema:
- name: "client_id"
type: "secret-input"
required: true
url: "https://developers.google.com/identity/protocols/oauth2"
- name: "client_secret"
type: "secret-input"
required: true
```
<Info>
The `url` field links to the third-party service's help documentation, giving admins and developers a reference during setup.
</Info>
#### credentials\_schema
Specifies what the user authorization flow produces (Dify manages these automatically):
```yaml theme={null}
# also under oauth_schema
credentials_schema:
- name: "access_token"
type: "secret-input"
- name: "refresh_token"
type: "secret-input"
- name: "expires_at"
type: "secret-input"
```
<Info>
Include `oauth_schema` and `credentials_for_provider` together to offer both OAuth and API key authentication options.
</Info>
### 2. Complete Required OAuth Methods in Tool Provider
Add these imports where your `ToolProvider` is implemented:
```python theme={null}
from dify_plugin.entities.oauth import ToolOAuthCredentials
from dify_plugin.errors.tool import ToolProviderCredentialValidationError, ToolProviderOAuthError
```
Your `ToolProvider` class must implement these three OAuth methods (using `GmailProvider` as an example):
<Warning>
Never return the `client_secret` in the credentials of `ToolOAuthCredentials`; doing so could lead to security issues.
</Warning>
<CodeGroup>
```python _oauth_get_authorization_url expandable theme={null}
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
"""
Generate the authorization URL using credentials from OAuth Client Setup Flow.
This URL is where users grant permissions.
"""
# Generate random state for CSRF protection (recommended for all OAuth flows)
state = secrets.token_urlsafe(16)
# Define Gmail-specific scopes - request minimal necessary permissions
scope = "read:user read:data" # Replace with your required scopes
# Assemble Gmail-specific payload
params = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"redirect_uri": redirect_uri, # Dify generates this - DON'T modify
"scope": scope,
"response_type": "code", # Standard OAuth authorization code flow
"access_type": "offline", # Critical: gets refresh token (if supported)
"prompt": "consent", # Forces reauth when scopes change (if supported)
"state": state, # CSRF protection
}
return f"{self._AUTH_URL}?{urllib.parse.urlencode(params)}"
```
```python _oauth_get_credentials expandable theme={null}
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> ToolOAuthCredentials:
"""
Exchange authorization code for access token and refresh token. This is called
to create ONE credential set for one account connection.
"""
# Extract authorization code from OAuth callback
code = request.args.get("code")
if not code:
raise ToolProviderOAuthError("Authorization code not provided")
# Check for authorization errors from OAuth provider
error = request.args.get("error")
if error:
error_description = request.args.get("error_description", "")
raise ToolProviderOAuthError(f"OAuth authorization failed: {error} - {error_description}")
# Exchange authorization code for tokens using OAuth Client Setup credentials
# Assemble Gmail-specific payload
data = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"client_secret": system_credentials["client_secret"], # From OAuth Client Setup
"code": code, # From user's authorization
"grant_type": "authorization_code", # Standard OAuth flow type
"redirect_uri": redirect_uri, # Must exactly match authorization URL
}
headers = {"Content-Type": "application/x-www-form-urlencoded"}
try:
response = requests.post(
self._TOKEN_URL,
data=data,
headers=headers,
timeout=10
)
response.raise_for_status()
token_data = response.json()
# Handle OAuth provider errors in response
if "error" in token_data:
error_desc = token_data.get('error_description', token_data['error'])
raise ToolProviderOAuthError(f"Token exchange failed: {error_desc}")
access_token = token_data.get("access_token")
if not access_token:
raise ToolProviderOAuthError("No access token received from provider")
# Build credentials dict matching your credentials_schema
credentials = {
"access_token": access_token,
"token_type": token_data.get("token_type", "Bearer"),
}
# Include refresh token if provided (critical for long-term access)
refresh_token = token_data.get("refresh_token")
if refresh_token:
credentials["refresh_token"] = refresh_token
# Handle token expiration - some providers don't provide expires_in
expires_in = token_data.get("expires_in", 3600) # Default to 1 hour
expires_at = int(time.time()) + expires_in
return ToolOAuthCredentials(credentials=credentials, expires_at=expires_at)
except requests.RequestException as e:
raise ToolProviderOAuthError(f"Network error during token exchange: {str(e)}")
except Exception as e:
raise ToolProviderOAuthError(f"Failed to exchange authorization code: {str(e)}")
```
```python _oauth_refresh_credentials theme={null}
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> ToolOAuthCredentials:
"""
Refresh the credentials using the refresh token.
Dify calls this automatically when tokens expire.
"""
refresh_token = credentials.get("refresh_token")
if not refresh_token:
raise ToolProviderOAuthError("No refresh token available")
# Standard OAuth refresh token flow
data = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"client_secret": system_credentials["client_secret"], # From OAuth Client Setup
"refresh_token": refresh_token, # From previous authorization
"grant_type": "refresh_token", # OAuth refresh flow
}
headers = {"Content-Type": "application/x-www-form-urlencoded"}
try:
response = requests.post(
self._TOKEN_URL,
data=data,
headers=headers,
timeout=10
)
response.raise_for_status()
token_data = response.json()
# Handle refresh errors
if "error" in token_data:
error_desc = token_data.get('error_description', token_data['error'])
raise ToolProviderOAuthError(f"Token refresh failed: {error_desc}")
access_token = token_data.get("access_token")
if not access_token:
raise ToolProviderOAuthError("No access token received from provider")
# Build new credentials, preserving existing refresh token
new_credentials = {
"access_token": access_token,
"token_type": token_data.get("token_type", "Bearer"),
"refresh_token": refresh_token, # Keep existing refresh token
}
# Handle token expiration
expires_in = token_data.get("expires_in", 3600)
# update refresh token if new one provided
new_refresh_token = token_data.get("refresh_token")
if new_refresh_token:
new_credentials["refresh_token"] = new_refresh_token
# Calculate new expiration timestamp for Dify's token management
expires_at = int(time.time()) + expires_in
return ToolOAuthCredentials(credentials=new_credentials, expires_at=expires_at)
except requests.RequestException as e:
raise ToolProviderOAuthError(f"Network error during token refresh: {str(e)}")
except Exception as e:
raise ToolProviderOAuthError(f"Failed to refresh credentials: {str(e)}")
```
</CodeGroup>
### 3. Access Tokens in Your Tools
Use OAuth credentials to make authenticated API calls in your `Tool` implementation:
```python theme={null}
class YourTool(BuiltinTool):
def _invoke(self, user_id: str, tool_parameters: dict[str, Any]) -> ToolInvokeMessage:
if self.runtime.credential_type == CredentialType.OAUTH:
access_token = self.runtime.credentials["access_token"]
response = requests.get("https://api.service.com/data",
headers={"Authorization": f"Bearer {access_token}"})
return self.create_text_message(response.text)
```
`self.runtime.credentials` automatically provides the current user's tokens. Dify handles refresh automatically.
For plugins that support both OAuth and `API_KEY` authentication, use `self.runtime.credential_type` to differentiate between the two authentication types.
### 4. Specify the Correct Versions
OAuth requires a recent SDK and Dify version. Pin the plugin SDK in `requirements.txt`:
```text theme={null}
dify_plugin>=0.5.0
```
In `manifest.yaml`, add the minimum Dify version:
```yaml theme={null}
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: "3.12"
entrypoint: main
minimum_dify_version: 1.7.1
```
# Tool Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin
Develop a Dify tool plugin from initialization to packaging, using Google Search as a worked example
Tools are third-party services that Chatflow, Workflow, and Agent applications can call. They extend Dify applications with capabilities such as online search and image generation.
<Frame>
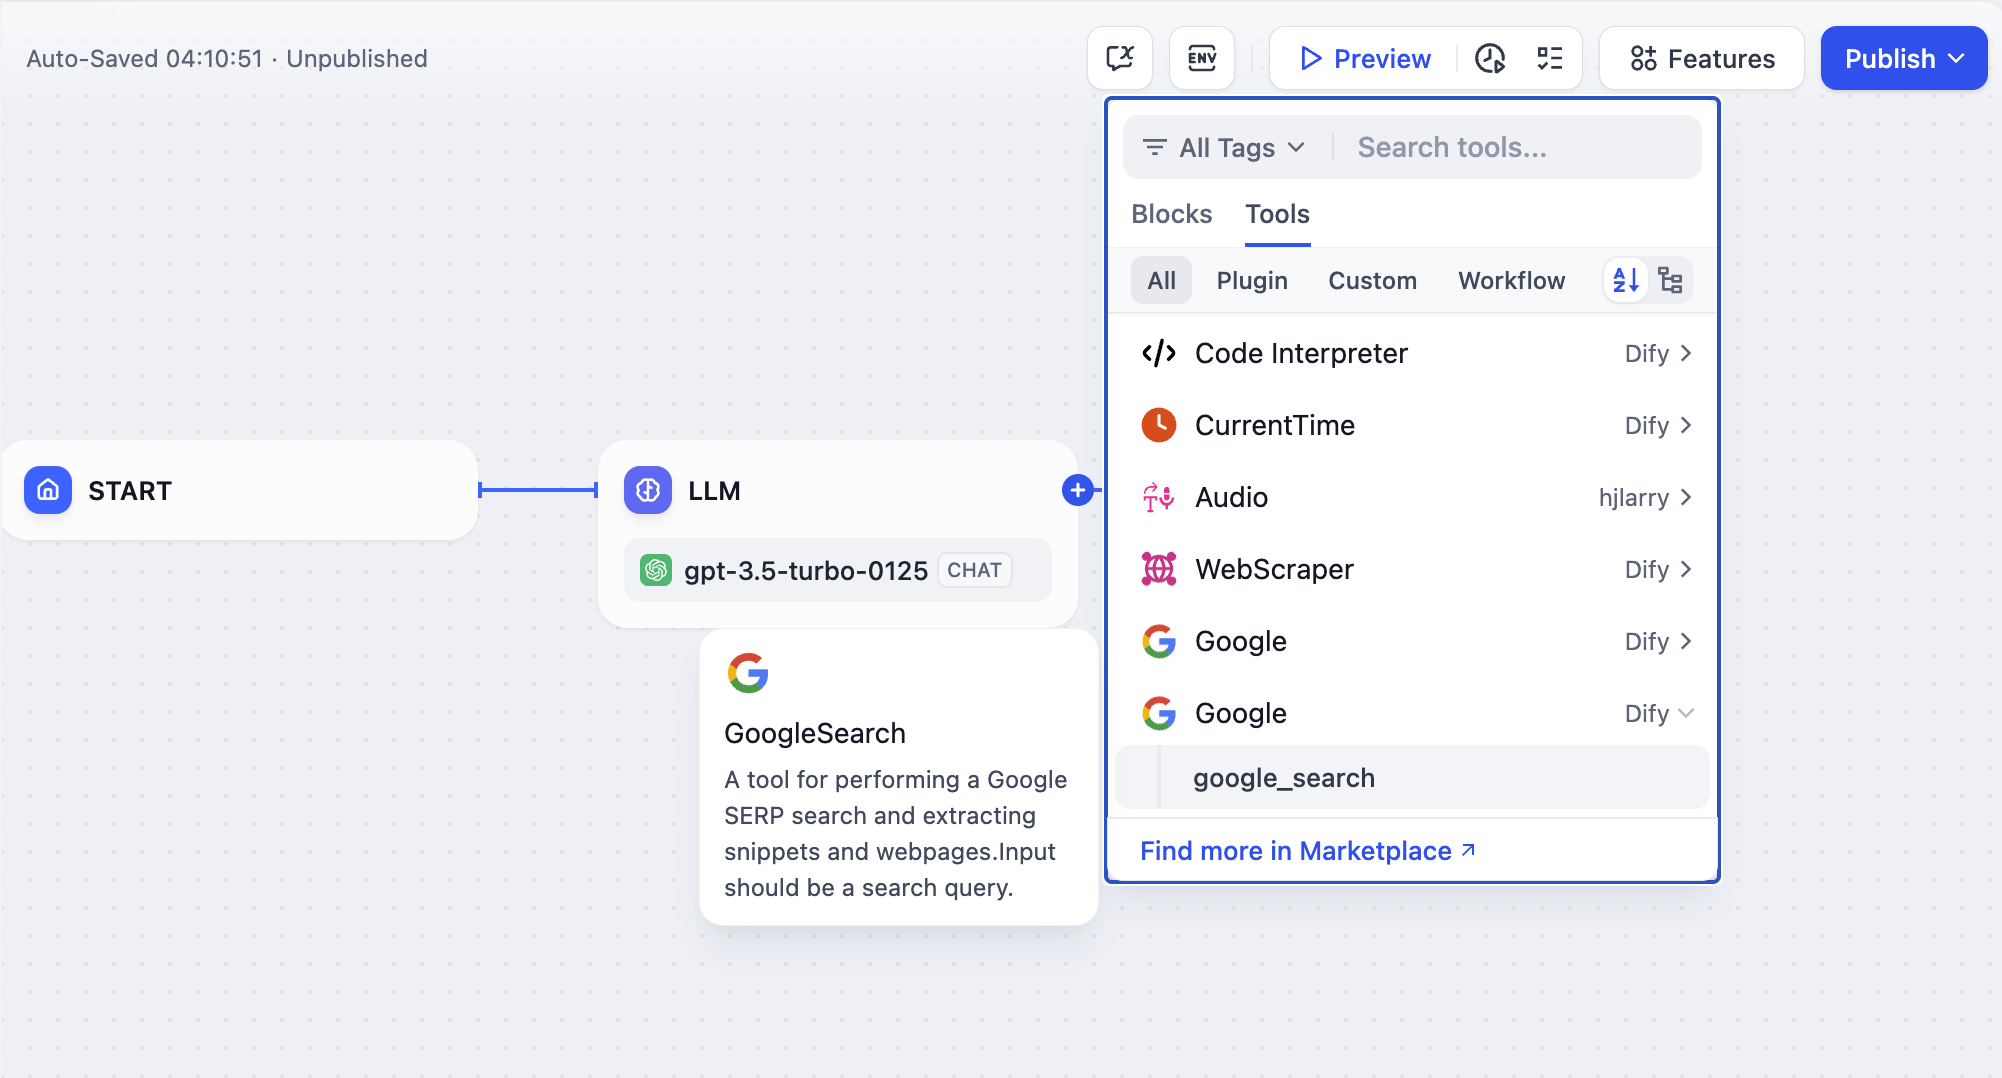
</Frame>
In this guide, a *tool plugin* is a complete project that includes tool provider files, functional code, and supporting structures. A tool provider can bundle multiple tools, each offering a distinct capability:
```text theme={null}
- Tool Provider
- Tool A
- Tool B
```
<Frame>
</Frame>
This guide uses Google Search as an example to walk through tool plugin development.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
To set up the scaffolding tool, see [Initializing Development Tools](/en/develop-plugin/getting-started/cli).
## Create a New Project
Run the scaffolding command line tool to create a new Dify plugin project.
```bash theme={null}
./dify-plugin-darwin-arm64 plugin init
```
If you have renamed the binary file to `dify` and copied it to the `/usr/local/bin` path, you can run the following command to create a new plugin project:
```bash theme={null}
dify plugin init
```
<Note>
The following examples use `dify` as the command. If you run into issues, replace `dify` with the path to your command-line tool.
</Note>
## Choose Plugin Type and Template
Each template in the scaffolding tool is a complete code project. For this example, select the `Tool` plugin.
<Tip>
If you are already familiar with plugin development and don't need a template, see the [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) guide to build any plugin type.
</Tip>
<Frame>
</Frame>
### Configure Plugin Permissions
The plugin also needs permissions to read from the Dify platform. Grant this example plugin the following permissions:
* Tools
* Apps
* Enable persistent storage, with the default storage size
* Allow registering Endpoints
<Tip>
In the terminal, use the arrow keys to select permissions and the Tab key to grant them.
</Tip>
After checking all permission items, press Enter to complete the plugin creation. The system generates the plugin project code automatically.
<Frame>
</Frame>
## Develop the Tool Plugin
### 1. Create the Tool Provider File
The tool provider file is a YAML file that serves as the plugin's base configuration, supplying the authorization information the tool needs.
In the plugin template project, go to the `/provider` directory and rename the YAML file to `google.yaml`. This file describes the tool provider: name, icon, author, and other details shown when the plugin is installed.
Example code:
```yaml theme={null}
identity: # Basic information about the tool provider
author: Your-name # Author
name: google # Unique name; must not duplicate another provider's name
label: # Label shown in the frontend
en_US: Google # English label
zh_Hans: Google # Chinese label
description: # Description shown in the frontend
en_US: Google # English description
zh_Hans: Google # Chinese description
icon: icon.svg # Tool icon; must be placed in the _assets folder
tags: # Tags shown in the frontend
- search
```
Make sure the file path is in the `/tools` directory, with the complete path as follows:
```yaml theme={null}
plugins:
tools:
- 'google.yaml'
```
`google.yaml` must be referenced by its absolute path within the plugin project; in this example, it sits in the project root directory. In the YAML file, `identity` holds the tool provider's basic information: author, name, label, description, and icon.
* The icon must be an attachment resource placed in the `_assets` folder in the project root directory.
* Tags help users find plugins by category. These are all the currently supported tags:
```python theme={null}
class ToolLabelEnum(Enum):
SEARCH = 'search'
IMAGE = 'image'
VIDEOS = 'videos'
WEATHER = 'weather'
FINANCE = 'finance'
DESIGN = 'design'
TRAVEL = 'travel'
SOCIAL = 'social'
NEWS = 'news'
MEDICAL = 'medical'
PRODUCTIVITY = 'productivity'
EDUCATION = 'education'
BUSINESS = 'business'
ENTERTAINMENT = 'entertainment'
UTILITIES = 'utilities'
OTHER = 'other'
```
### 2. Add Third-Party Service Credentials
For convenience, this example uses the Google Search API provided by the third-party service SerpApi. SerpApi requires an API key, so add a `credentials_for_provider` field to the YAML file.
The complete code:
```yaml theme={null}
identity:
author: Dify
name: google
label:
en_US: Google
zh_Hans: Google
pt_BR: Google
description:
en_US: Google
zh_Hans: GoogleSearch
pt_BR: Google
icon: icon.svg
tags:
- search
credentials_for_provider: # Add the credentials_for_provider field
serpapi_api_key:
type: secret-input
required: true
label:
en_US: SerpApi API key
zh_Hans: SerpApi API key
placeholder:
en_US: Please input your SerpApi API key
zh_Hans: Please enter your SerpApi API key
help:
en_US: Get your SerpApi API key from SerpApi
zh_Hans: Get your SerpApi API key from SerpApi
url: https://serpapi.com/manage-api-key
tools:
- tools/google_search.yaml
extra:
python:
source: google.py
```
* The sub-level structure of `credentials_for_provider` must meet the requirements in [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications).
* Specify which tools the provider includes. This example includes only one file, `tools/google_search.yaml`.
* Besides its basic information, a provider needs code logic, so specify its implementation file. This example uses `google.py`, but leave it unimplemented for now and write the `google_search` tool code first.
### 3. Fill in the Tool YAML File
A tool plugin can contain multiple tools, each described by its own YAML file covering basic information, parameters, and output.
Continuing with the `GoogleSearch` tool, create a new `google_search.yaml` file in the `/tools` folder.
```yaml theme={null}
identity:
name: google_search
author: Dify
label:
en_US: GoogleSearch
zh_Hans: Google Search
pt_BR: GoogleSearch
description:
human:
en_US: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
zh_Hans: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
pt_BR: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
llm: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
parameters:
- name: query
type: string
required: true
label:
en_US: Query string
zh_Hans: Query string
pt_BR: Query string
human_description:
en_US: used for searching
zh_Hans: used for searching web content
pt_BR: used for searching
llm_description: key words for searching
form: llm
extra:
python:
source: tools/google_search.py
```
* **`identity`**: Basic information about the tool, including name, author, label, and description.
* **`parameters`**: The parameter list.
* **`name`** (required): Parameter name; must be unique among the tool's parameters.
* **`type`** (required): Parameter type. Values fall into three groups:
* **Plain values**: `string`, `number`, `boolean`, `any`.
* **Choices**: `select` for a fixed dropdown built from `options`, `dynamic-select` for a dropdown whose options the plugin supplies at configuration time, and `checkbox`.
* **Pickers and uploads**:
* `secret-input` for sensitive values, which renders as an encrypted input box
* `file` and `files` for uploads
* `app-selector` and `model-selector` for choosing an app or a model from the workspace
* `date` for a single date, which renders as a date picker and is passed as a `YYYY-MM-DD` string
* `date-range` for a start and end date, which renders as a date range picker and is passed as an object with `start` and `end` date strings
Two further values, `array` and `object`, exist for MCP server tools rather than plugin-declared parameters, and `system-files` is deprecated.
* **`label`** (required): Parameter label, shown in the frontend.
* **`form`** (required): Form type, either `llm` or `form`.
* In Agent applications, `llm` means the LLM infers the parameter itself, while `form` means the parameter can be preset before using the tool.
* In Workflow applications, both `llm` and `form` parameters are filled in via the frontend, but `llm` parameters are used as input variables for the tool node.
* **`required`** (optional): Whether the parameter is required.
* In `llm` mode, a required parameter must be inferred by the Agent.
* In `form` mode, a required parameter must be filled in on the frontend before the conversation begins.
* **`options`** (optional): Parameter options.
* In `llm` mode, Dify passes all options to the LLM, which can infer based on them.
* In `form` mode, the frontend displays the options when `type` is `select`.
* **`multiple`** (optional): For `select` and `dynamic-select` parameters, set `true` to let users pick more than one option. The value is passed as a list of option values, and `default`, if set, must then be a list.
```yaml theme={null}
- name: formats
type: select
multiple: true
form: form
label:
en_US: Formats
options:
- label:
en_US: Markdown
value: markdown
- label:
en_US: Links
value: links
default:
- markdown
```
* **`default`** (optional): Default value.
* **`min`** (optional): Minimum value; applies when the parameter type is `number`.
* **`max`** (optional): Maximum value; applies when the parameter type is `number`.
* **`human_description`** (optional): Description shown in the frontend; supports multiple languages.
* **`placeholder`** (optional): Hint text for the input field; applies when the form type is `form` and the parameter type is `string`, `number`, or `secret-input`. Supports multiple languages.
* **`llm_description`** (optional): Description passed to the LLM. Write it in as much detail as possible so the LLM understands the parameter.
### 4. Write the Tool Code
With the tool configuration in place, write the code that implements the tool's logic. Create `google_search.py` in the `/tools` directory with the following content:
```python theme={null}
from collections.abc import Generator
from typing import Any
import requests
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
SERP_API_URL = "https://serpapi.com/search"
class GoogleSearchTool(Tool):
def _parse_response(self, response: dict) -> dict:
result = {}
if "knowledge_graph" in response:
result["title"] = response["knowledge_graph"].get("title", "")
result["description"] = response["knowledge_graph"].get("description", "")
if "organic_results" in response:
result["organic_results"] = [
{
"title": item.get("title", ""),
"link": item.get("link", ""),
"snippet": item.get("snippet", ""),
}
for item in response["organic_results"]
]
return result
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
params = {
"api_key": self.runtime.credentials["serpapi_api_key"],
"q": tool_parameters["query"],
"engine": "google",
"google_domain": "google.com",
"gl": "us",
"hl": "en",
}
response = requests.get(url=SERP_API_URL, params=params, timeout=5)
response.raise_for_status()
valuable_res = self._parse_response(response.json())
yield self.create_json_message(valuable_res)
```
This code sends a request to `serpapi` and uses `self.create_json_message` to return formatted JSON data. To learn more about return data types, see [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) and [Persistent Storage KV](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv).
### 5. Complete the Tool Provider Code
Finally, implement the provider's credential validation logic. If validation fails, the code raises a `ToolProviderCredentialValidationError` exception; once validation succeeds, the `google_search` tool service is requested correctly.
Create a `google.py` file in the `/provider` directory with the following content:
```python theme={null}
from typing import Any
from dify_plugin import ToolProvider
from dify_plugin.errors.tool import ToolProviderCredentialValidationError
from tools.google_search import GoogleSearchTool
class GoogleProvider(ToolProvider):
def _validate_credentials(self, credentials: dict[str, Any]) -> None:
try:
for _ in GoogleSearchTool.from_credentials(credentials).invoke(
tool_parameters={"query": "test", "result_type": "link"},
):
pass
except Exception as e:
raise ToolProviderCredentialValidationError(str(e))
```
## Debug the Plugin
After development, test whether the plugin works correctly. Dify provides remote debugging so you can quickly verify the plugin's functionality in a test environment.
Go to the [Plugin Management](https://cloud.dify.ai/plugins) page to get the remote server address and debug key.
<Frame>

</Frame>
Back in the plugin project, copy the `.env.example` file, rename it to `.env`, and fill in the remote server address and debug key.
`.env` file:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Run `python -m main` to start the plugin. On the **Plugins** page, you can see the plugin installed in the workspace, where other team members can also access it.
<Frame>
</Frame>
## Package the Plugin (Optional)
Once the plugin runs correctly, package and name it with the following command. It produces a `google.difypkg` file in the current folder—the final plugin package.
```bash theme={null}
# Replace ./google with the actual path of the plugin project
dify plugin package ./google
```
Congratulations—you've developed, debugged, and packaged a tool plugin!
## Publish the Plugin (Optional)
To publish the plugin to the Dify Marketplace, make sure it follows the specifications in [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). After the review passes, the code is merged into the main branch and automatically released on the [Dify Marketplace](https://marketplace.dify.ai/).
For the full process, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Explore More
### Quick Start
* [Developing Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint)
* [Developing Model Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)
* [Bundle Plugins: Packaging Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
### Plugin Interface Documentation
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Manifest structure and tool specifications.
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Detailed Endpoint definition.
* [Reverse Invocation](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Reverse invocation of Dify capabilities.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Models.
* [Agent Plugins](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Extending Agent strategies.
## Next Steps
* [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin): Learn more advanced debugging techniques.
* [Persistent Storage](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv): Use data storage in plugins.
* [Slack Bot Plugin Development Example](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin): A more complex plugin development case.
* [Tool Plugin](/en/develop-plugin/features-and-specs/plugin-types/tool): Advanced features of tool plugins.
# Trigger Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin
Build a Dify 1.10.0+ trigger plugin that turns third-party webhook events into workflow start signals
## What Is a Trigger Plugin?
Triggers were introduced in Dify v1.10.0 as a new type of start node. Unlike functional nodes such as Code, Tool, or Knowledge Retrieval, a trigger **converts third-party events into an input format that Dify can recognize and process**.
<Frame>
<img alt="Trigger Plugin Intro" />
</Frame>
For example, if you configure Dify as the `new email` event receiver in Gmail, Gmail automatically sends an event to Dify every time you receive a new email, and that event can trigger a workflow. However:
* Gmail's original event format is not compatible with Dify's input format.
* There are thousands of platforms worldwide, each with its own unique event format.
Trigger plugins close this gap: they define and parse events from different platforms and unify them into an input format that Dify can accept.
## Technical Overview
Dify triggers are built on webhooks, a widely adopted mechanism across the web. Mainstream SaaS platforms such as GitHub, Slack, and Linear support webhooks and document them thoroughly.
A webhook is an HTTP-based event dispatcher: once you configure an event-receiving address, the platform automatically pushes event data to that address whenever a subscribed event occurs.
To handle webhook events from different platforms in a unified way, Dify defines two core concepts: **Subscription** and **Event**.
* **Subscription**: The configuration that registers Dify's network address as the target server in a third-party platform's developer console.
* **Event**: A platform may send multiple types of events (such as *email received*, *email deleted*, or *email marked as read*), all pushed to the registered address. A trigger plugin can handle multiple event types, and each event corresponds to a Plugin Trigger node in a Dify workflow.
## Plugin Development
Developing a trigger plugin follows the same process as other plugin types (Tool, Data Source, Model, and so on).
Create a development template with the `dify plugin init` command. The generated file structure follows the standard plugin format specification.
```text theme={null}
├── _assets
│ └── icon.svg
├── events
│ └── star
│ ├── star_created.py
│ └── star_created.yaml
├── main.py
├── manifest.yaml
├── provider
│ ├── github.py
│ └── github.yaml
├── README.md
├── PRIVACY.md
└── requirements.txt
```
* `manifest.yaml`: Describes the plugin's basic metadata.
* `provider` directory: Contains the provider's metadata, the code for creating subscriptions, and the code for classifying events after receiving webhook requests.
* `events` directory: Contains the code for event handling and filtering, which supports local event filtering at the node level. You can create subdirectories to group related events.
<Note>
For trigger plugins, set the minimum required Dify version to `1.10.0` and the SDK version to `>= 0.6.0`.
</Note>
The following sections use GitHub as an example to walk through the development process.
### Create a Subscription
Webhook configuration methods vary significantly across mainstream SaaS platforms:
* Some platforms (such as GitHub) support API-based webhook configuration. For these platforms, once OAuth authentication is completed, Dify can automatically set up the webhook.
* Other platforms (such as Notion) do not provide a webhook configuration API and may require users to perform manual authentication.
To accommodate these differences, we divide the subscription process into two parts: the **Subscription Constructor** and the **Subscription** itself.
For platforms like Notion, creating a subscription requires the user to manually copy the callback URL provided by Dify and paste it into their Notion workspace to complete the webhook setup. This process corresponds to the **Paste URL to create a new subscription** option in the Dify interface.
<Frame>
<img alt="Paste URL to Create a New Subscription" />
</Frame>
To support subscription creation via manual URL pasting, modify two files: `github.yaml` and `github.py`.
<Tabs>
<Tab title="github.yaml">
GitHub webhooks use an encryption mechanism, so a secret key is required to decrypt and validate incoming requests. Declare `webhook_secret` in `github.yaml`.
```yaml theme={null}
subscription_schema:
- name: "webhook_secret"
type: "secret-input"
required: false
label:
zh_Hans: "Webhook Secret"
en_US: "Webhook Secret"
ja_JP: "Webhookシークレット"
help:
en_US: "Optional webhook secret for validating GitHub webhook requests"
ja_JP: "GitHub Webhookリクエストの検証用のオプションのWebhookシークレット"
zh_Hans: "可选的用于验证 GitHub webhook 请求的 webhook 密钥"
```
</Tab>
<Tab title="github.py">
First, implement the `dispatch_event` interface. All requests sent to the callback URL are processed by this interface, and the processed events appear in the **Request Logs** section for debugging and verification.
<Frame>
<img alt="Manual Setup" />
</Frame>
In the code, you can retrieve the `webhook_secret` declared in `github.yaml` via `subscription.properties`.
The `dispatch_event` method determines the event type from the request content. In the example below, the `_dispatch_trigger_event` method handles this extraction.
<Tip>
For the complete code sample, see [Dify's GitHub trigger plugin](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/github_trigger).
</Tip>
```python theme={null}
class GithubTrigger(Trigger):
"""Handle GitHub webhook event dispatch."""
def _dispatch_event(self, subscription: Subscription, request: Request) -> EventDispatch:
webhook_secret = subscription.properties.get("webhook_secret")
if webhook_secret:
self._validate_signature(request=request, webhook_secret=webhook_secret)
event_type: str | None = request.headers.get("X-GitHub-Event")
if not event_type:
raise TriggerDispatchError("Missing GitHub event type header")
payload: Mapping[str, Any] = self._validate_payload(request)
response = Response(response='{"status": "ok"}', status=200, mimetype="application/json")
event: str = self._dispatch_trigger_event(event_type=event_type, payload=payload)
return EventDispatch(events=[event] if event else [], response=response)
```
</Tab>
</Tabs>
### Handle Events
Once an event is extracted, the corresponding implementation must filter the original HTTP request and transform it into an input format that Dify workflows can accept.
Taking the Issue event as an example, define the event in `events/issues/issues.yaml` and its implementation in `events/issues/issues.py`. Define the event's output in the `output_schema` section of `issues.yaml`, which follows the same JSON Schema specification as tool plugins.
<Tabs>
<Tab title="issues.yaml">
```yaml theme={null}
identity:
name: issues
author: langgenius
label:
en_US: Issues
zh_Hans: 议题
ja_JP: イシュー
description:
en_US: Unified issues event with actions filter
zh_Hans: 带 actions 过滤的统一 issues 事件
ja_JP: アクションフィルタ付きの統合イシューイベント
output_schema:
type: object
properties:
action:
type: string
issue:
type: object
description: The issue itself
extra:
python:
source: events/issues/issues.py
```
</Tab>
<Tab title="issues.py">
```python theme={null}
from collections.abc import Mapping
from typing import Any
from werkzeug import Request
from dify_plugin.entities.trigger import Variables
from dify_plugin.errors.trigger import EventIgnoreError
from dify_plugin.interfaces.trigger import Event
class IssuesUnifiedEvent(Event):
"""Unified Issues event. Filters by actions and common issue attributes."""
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
payload = request.get_json()
if not payload:
raise ValueError("No payload received")
allowed_actions = parameters.get("actions") or []
action = payload.get("action")
if allowed_actions and action not in allowed_actions:
raise EventIgnoreError()
issue = payload.get("issue")
if not isinstance(issue, Mapping):
raise ValueError("No issue in payload")
return Variables(variables={**payload})
```
</Tab>
</Tabs>
### Filter Events
To filter out certain events (for example, to focus only on Issue events with a specific label), add `parameters` to the event definition in `issues.yaml`. Then, in the `_on_event` method, raise an `EventIgnoreError` exception for events that don't meet the configured criteria.
<Tabs>
<Tab title="issues.yaml">
```yaml theme={null}
parameters:
- name: added_label
label:
en_US: Added Label
zh_Hans: 添加的标签
ja_JP: 追加されたラベル
type: string
required: false
description:
en_US: "Only trigger if these specific labels were added (e.g., critical, priority-high, security, comma-separated). Leave empty to trigger for any label addition."
zh_Hans: "仅当添加了这些特定标签时触发(例如:critical, priority-high, security,逗号分隔)。留空则对任何标签添加触发。"
ja_JP: "これらの特定のラベルが追加された場合のみトリガー(例: critical, priority-high, security,カンマ区切り)。空の場合は任意のラベル追加でトリガー。"
```
</Tab>
<Tab title="issues.py">
```python theme={null}
def _check_added_label(self, payload: Mapping[str, Any], added_label_param: str | None) -> None:
"""Check if the added label matches the allowed labels"""
if not added_label_param:
return
allowed_labels = [label.strip() for label in added_label_param.split(",") if label.strip()]
if not allowed_labels:
return
# The payload contains the label that was added
label = payload.get("label", {})
label_name = label.get("name", "")
if label_name not in allowed_labels:
raise EventIgnoreError()
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
# ...
# Apply all filters
self._check_added_label(payload, parameters.get("added_label"))
return Variables(variables={**payload})
```
</Tab>
</Tabs>
### Create Subscriptions via OAuth or API Key
To enable automatic subscription creation via OAuth or API key, modify the `github.yaml` and `github.py` files.
<Tabs>
<Tab title="github.yaml">
In `github.yaml`, add the following fields.
```yaml theme={null}
subscription_constructor:
parameters:
- name: "repository"
label:
en_US: "Repository"
zh_Hans: "仓库"
ja_JP: "リポジトリ"
type: "dynamic-select"
required: true
placeholder:
en_US: "owner/repo"
zh_Hans: "owner/repo"
ja_JP: "owner/repo"
help:
en_US: "GitHub repository in format owner/repo (e.g., microsoft/vscode)"
zh_Hans: "GitHub 仓库,格式为 owner/repo(例如:microsoft/vscode)"
ja_JP: "GitHubリポジトリは owner/repo 形式で入力してください(例: microsoft/vscode)"
credentials_schema:
access_tokens:
help:
en_US: Get your Access Tokens from GitHub
ja_JP: GitHub からアクセストークンを取得してください
zh_Hans: 从 GitHub 获取您的 Access Tokens
label:
en_US: Access Tokens
ja_JP: アクセストークン
zh_Hans: Access Tokens
placeholder:
en_US: Please input your GitHub Access Tokens
ja_JP: GitHub のアクセストークンを入力してください
zh_Hans: 请输入你的 GitHub Access Tokens
required: true
type: secret-input
url: https://github.com/settings/tokens?type=beta
extra:
python:
source: provider/github.py
```
`subscription_constructor` is a concept abstracted by Dify to define how a subscription is constructed. It includes the following fields:
* `parameters` (optional): Defines the parameters required to create a subscription, such as the event types to subscribe to or the target GitHub repository.
* `credentials_schema` (optional): Declares the credentials required to create a subscription with an API key or access token, such as `access_tokens` for GitHub.
* `oauth_schema` (optional): Required for subscription creation via OAuth. For details on how to define it, see [Add OAuth Support to Your Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth).
</Tab>
<Tab title="github.py">
In `github.py`, create a `Constructor` class to implement the automatic subscription logic.
```python theme={null}
class GithubSubscriptionConstructor(TriggerSubscriptionConstructor):
"""Manage GitHub trigger subscriptions."""
def _validate_api_key(self, credentials: Mapping[str, Any]) -> None:
# ...
def _create_subscription(
self,
endpoint: str,
parameters: Mapping[str, Any],
credentials: Mapping[str, Any],
credential_type: CredentialType,
) -> Subscription:
repository = parameters.get("repository")
if not repository:
raise ValueError("repository is required (format: owner/repo)")
try:
owner, repo = repository.split("/")
except ValueError:
raise ValueError("repository must be in format 'owner/repo'") from None
events: list[str] = parameters.get("events", [])
webhook_secret = uuid.uuid4().hex
url = f"https://api.github.com/repos/{owner}/{repo}/hooks"
headers = {
"Authorization": f"Bearer {credentials.get('access_tokens')}",
"Accept": "application/vnd.github+json",
}
webhook_data = {
"name": "web",
"active": True,
"events": events,
"config": {"url": endpoint, "content_type": "json", "insecure_ssl": "0", "secret": webhook_secret},
}
try:
response = requests.post(url, json=webhook_data, headers=headers, timeout=10)
except requests.RequestException as exc:
raise SubscriptionError(f"Network error while creating webhook: {exc}", error_code="NETWORK_ERROR") from exc
if response.status_code == 201:
webhook = response.json()
return Subscription(
expires_at=int(time.time()) + self._WEBHOOK_TTL,
endpoint=endpoint,
parameters=parameters,
properties={
"external_id": str(webhook["id"]),
"repository": repository,
"events": events,
"webhook_secret": webhook_secret,
"active": webhook.get("active", True),
},
)
response_data: dict[str, Any] = response.json() if response.content else {}
error_msg = response_data.get("message", "Unknown error")
error_details = response_data.get("errors", [])
detailed_error = f"Failed to create GitHub webhook: {error_msg}"
if error_details:
detailed_error += f" Details: {error_details}"
raise SubscriptionError(
detailed_error,
error_code="WEBHOOK_CREATION_FAILED",
external_response=response_data,
)
```
</Tab>
</Tabs>
***
Once you have modified these two files, you'll see the **Create with API Key** option in the Dify interface.
The same `Constructor` class also supports automatic subscription creation via OAuth: add an `oauth_schema` field under `subscription_constructor` to enable OAuth authentication.
<Frame>
<img alt="OAuth & API Key Options" />
</Frame>
## Explore More
The interface definitions for the core classes in trigger plugin development are as follows.
### Trigger
```python theme={null}
class Trigger(ABC):
@abstractmethod
def _dispatch_event(self, subscription: Subscription, request: Request) -> EventDispatch:
"""
Internal method to implement event dispatch logic.
Subclasses must override this method to handle incoming webhook events.
Implementation checklist:
1. Validate the webhook request:
- Check the signature/HMAC using the properties stored in subscription.properties when the subscription was created
- Verify the request is from the expected source
2. Extract event information:
- Parse event type from headers or body
- Extract relevant payload data
3. Return EventDispatch with:
- events: List of Event names to invoke (can be single or multiple)
- response: Appropriate HTTP response for the webhook
Args:
subscription: The Subscription object with endpoint and properties fields
request: Incoming webhook HTTP request
Returns:
EventDispatch: Event dispatch routing information
Raises:
TriggerValidationError: For security validation failures
TriggerDispatchError: For parsing or routing errors
"""
raise NotImplementedError("This plugin should implement `_dispatch_event` method to enable event dispatch")
```
### TriggerSubscriptionConstructor
```python theme={null}
class TriggerSubscriptionConstructor(ABC, OAuthProviderProtocol):
# OPTIONAL
def _validate_api_key(self, credentials: Mapping[str, Any]) -> None:
raise NotImplementedError(
"This plugin should implement `_validate_api_key` method to enable credentials validation"
)
# OPTIONAL
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_get_authorization_url` method"
)
# OPTIONAL
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> TriggerOAuthCredentials:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_get_credentials` method"
)
# OPTIONAL
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> OAuthCredentials:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_refresh_credentials` method"
)
@abstractmethod
def _create_subscription(
self,
endpoint: str,
parameters: Mapping[str, Any],
credentials: Mapping[str, Any],
credential_type: CredentialType,
) -> Subscription:
"""
Internal method to implement subscription logic.
Subclasses must override this method to handle subscription creation.
Implementation checklist:
1. Use the endpoint parameter provided by Dify
2. Register webhook with external service using their API
3. Store all necessary information in Subscription.properties for future operations (e.g., dispatch_event)
4. Return Subscription with:
- expires_at: Set appropriate expiration time
- endpoint: The webhook endpoint URL allocated by Dify for receiving events, same as the endpoint parameter
- parameters: The parameters of the subscription
- properties: All configuration and external IDs
Args:
endpoint: The webhook endpoint URL allocated by Dify for receiving events
parameters: Subscription creation parameters
credentials: Authentication credentials
credential_type: The type of the credentials, e.g., "api-key", "oauth2", "unauthorized"
Returns:
Subscription: Subscription details with metadata for future operations
Raises:
SubscriptionError: For operational failures (API errors, invalid credentials)
ValueError: For programming errors (missing required params)
"""
raise NotImplementedError(
"This plugin should implement `_create_subscription` method to enable event subscription"
)
@abstractmethod
def _delete_subscription(
self, subscription: Subscription, credentials: Mapping[str, Any], credential_type: CredentialType
) -> UnsubscribeResult:
"""
Internal method to implement unsubscription logic.
Subclasses must override this method to handle subscription removal.
Implementation guidelines:
1. Extract necessary IDs from subscription.properties (e.g., external_id)
2. Use credentials and credential_type to call external service API to delete the webhook
3. Handle common errors (not found, unauthorized, etc.)
4. Always return UnsubscribeResult with detailed status
5. Never raise exceptions for operational failures - use UnsubscribeResult.success=False
Args:
subscription: The Subscription object with endpoint and properties fields
Returns:
UnsubscribeResult: Always returns result, never raises for operational failures
"""
raise NotImplementedError(
"This plugin should implement `_delete_subscription` method to enable event unsubscription"
)
@abstractmethod
def _refresh_subscription(
self, subscription: Subscription, credentials: Mapping[str, Any], credential_type: CredentialType
) -> Subscription:
"""
Internal method to implement subscription refresh logic.
Subclasses must override this method to handle simple expiration extension.
Implementation patterns:
1. For webhooks without expiration (e.g., GitHub):
- Update the Subscription.expires_at=-1 then Dify will never call this method again
2. For lease-based subscriptions (e.g., Microsoft Graph):
- Use the information in Subscription.properties to call service's lease renewal API if available
- Handle renewal limits (some services limit renewal count)
- Update Subscription.properties and Subscription.expires_at for the next renewal if needed
Args:
subscription: Current subscription with properties
credential_type: The type of the credentials, e.g., "api-key", "oauth2", "unauthorized"
credentials: Current authentication credentials from credentials_schema.
For API key auth, according to `credentials_schema` defined in the YAML.
For OAuth auth, according to `oauth_schema.credentials_schema` defined in the YAML.
For unauthorized auth, there is no credentials.
Returns:
Subscription: Same subscription with extended expiration
or new properties and expires_at for the next renewal
Raises:
SubscriptionError: For operational failures (API errors, invalid credentials)
"""
raise NotImplementedError("This plugin should implement `_refresh` method to enable subscription refresh")
# OPTIONAL
def _fetch_parameter_options(
self, parameter: str, credentials: Mapping[str, Any], credential_type: CredentialType
) -> list[ParameterOption]:
"""
Fetch the parameter options of the trigger.
Implementation guidelines:
When you need to fetch parameter options from an external service, use the credentials
and credential_type to call the external service API, then return the options to Dify
for user selection.
Args:
parameter: The parameter name for which to fetch options
credentials: Authentication credentials for the external service
credential_type: The type of credentials (e.g., "api-key", "oauth2", "unauthorized")
Returns:
list[ParameterOption]: A list of available options for the parameter
Examples:
GitHub Repositories:
>>> result = provider.fetch_parameter_options(parameter="repository")
>>> print(result) # [ParameterOption(label="owner/repo", value="owner/repo")]
Slack Channels:
>>> result = provider.fetch_parameter_options(parameter="channel")
>>> print(result)
```
### Event
```python theme={null}
class Event(ABC):
@abstractmethod
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
"""
Transform the incoming webhook request into structured Variables.
This method should:
1. Parse the webhook payload from the request
2. Apply filtering logic based on parameters
3. Extract relevant data matching the output_schema
4. Return a structured Variables object
Args:
request: The incoming webhook HTTP request containing the raw payload.
Use request.get_json() to parse JSON body.
parameters: User-configured parameters for filtering and transformation
(e.g., label filters, regex patterns, threshold values).
These come from the subscription configuration.
payload: The decoded payload from previous step `Trigger.dispatch_event`.
It will be delivered into `_on_event` method.
Returns:
Variables: Structured variables matching the output_schema
defined in the event's YAML configuration.
Raises:
EventIgnoreError: When the event should be filtered out based on parameters
ValueError: When the payload is invalid or missing required fields
Example:
>>> def _on_event(self, request, parameters):
... payload = request.get_json()
...
... # Apply filters
... if not self._matches_filters(payload, parameters):
... raise EventIgnoreError()
...
... # Transform data
... return Variables(variables={
... "title": payload["issue"]["title"],
... "author": payload["issue"]["user"]["login"],
... "url": payload["issue"]["html_url"],
... })
"""
def _fetch_parameter_options(self, parameter: str) -> list[ParameterOption]:
"""
Fetch the parameter options of the trigger.
To be implemented by subclasses.
Implementing it is optional, which is why it's not an abstract method.
"""
raise NotImplementedError(
"This plugin should implement `_fetch_parameter_options` method to enable dynamic select parameter"
)
```
# Bundle Plugin Package
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/bundle
Package multiple plugins into a Bundle with Marketplace, GitHub, and Package dependencies
A Bundle plugin package is a collection of multiple plugins packaged together, so users can install them all in one step.
Use the Dify Plugin CLI to package multiple plugins into a Bundle. Bundle dependencies come in three types:
* **`Marketplace`**: Stores the plugin's ID and version. During import, Dify downloads the plugin package from the Dify Marketplace.
* **`GitHub`**: Stores the GitHub repository address, release version number, and asset filename. During import, Dify downloads the plugin package from the corresponding GitHub repository.
* **`Package`**: Stores the plugin package directly within the Bundle. No reference source is stored, but this can make the Bundle file larger.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
To set up the plugin development scaffolding tool, see [Initialize Development Tools](/en/develop-plugin/getting-started/cli).
## Create a Bundle Project
In the current directory, run the scaffolding command-line tool to create a new plugin package project:
```bash theme={null}
./dify-plugin-darwin-arm64 bundle init
```
If you have renamed the binary to `dify` and copied it to `/usr/local/bin`, run:
```bash theme={null}
dify bundle init
```
### 1. Fill in Plugin Information
Follow the prompts to configure the plugin name, author information, and plugin description. If you are collaborating as a team, you can also enter the organization name as the author.
<Note>
The name must be 1–128 characters long and can only contain letters, numbers, hyphens, and underscores.
</Note>
<Frame>
</Frame>
Press Enter, and the Bundle plugin project directory is created automatically.
<Frame>
</Frame>
### 2. Add Dependencies
#### Marketplace
```bash theme={null}
dify-plugin bundle append marketplace . --marketplace_pattern=langgenius/openai:0.0.1
```
`marketplace_pattern` is the reference to the plugin in the Marketplace, in the format `organization_name/plugin_name:version_number`.
#### GitHub
```bash theme={null}
dify-plugin bundle append github . --repo_pattern=langgenius/openai:0.0.1/openai.difypkg
```
`repo_pattern` is the reference to the plugin on GitHub, in the format `organization_name/repository_name:release/asset_name`.
#### Package
```bash theme={null}
dify-plugin bundle append package . --package_path=./openai.difypkg
```
`package_path` is the path to the plugin package.
## Package the Bundle Project
Run the following command to package the Bundle plugin:
```bash theme={null}
dify-plugin bundle package ./bundle
```
This creates a `bundle.difybndl` file in the current directory—the final packaged result.
# Integrate Custom Models
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/customizable-model
Integrate a custom model into Dify, using Xinference as an example
A **custom model** is an LLM that you deploy or configure yourself. This guide uses [Xinference](https://inference.readthedocs.io/en/latest/) as an example to show how to integrate a custom model into your **model plugin**.
By default, a custom model automatically includes two parameters, its **model type** and **model name**, so the provider YAML file needs no additional definitions.
You do not need to implement `validate_provider_credential` in your provider configuration file. At runtime, Dify calls the corresponding model layer's `validate_credentials` method based on the model type and model name the user selects.
## Integrate a Custom Model Plugin
Integrating a custom model takes four steps:
1. **Create a model provider file**: Identify the model types your custom model will include.
2. **Create code files by model type**: Create separate code files for each model type (e.g., `llm` or `text_embedding`). Keeping each model type in its own logical layer simplifies maintenance and future expansion.
3. **Develop the model invocation logic**: Within each model-type module, create a Python file named for that model type (for example, `llm.py`). Define a class in the file that implements the model logic, conforming to the system's model interface specifications.
4. **Debug the plugin**: Write unit and integration tests for the new provider functionality, ensuring that all components work as intended.
### 1. Create the Model Provider File
In your plugin’s `/provider` directory, create a `xinference.yaml` file.
The `Xinference` family of models supports **LLM**, **Text Embedding**, and **Rerank** model types, so your `xinference.yaml` must include all three.
**Example**:
```yaml theme={null}
provider: xinference # Identifies the provider
label: # Display name; can set both en_US (English) and zh_Hans (Chinese). If zh_Hans is not set, en_US is used by default.
en_US: Xorbits Inference
icon_small: # Small icon; store in the _assets folder of this provider’s directory. The same multi-language logic applies as with label.
en_US: icon_s_en.svg
icon_large: # Large icon
en_US: icon_l_en.svg
help: # Help information
title:
en_US: How to deploy Xinference
zh_Hans: 如何部署 Xinference
url:
en_US: https://github.com/xorbitsai/inference
supported_model_types: # Model types Xinference supports: LLM/Text Embedding/Rerank
- llm
- text-embedding
- rerank
configurate_methods: # Xinference is locally deployed and does not offer predefined models. Refer to its documentation to learn which model to use. Thus, we choose a customizable-model approach.
- customizable-model
provider_credential_schema:
credential_form_schemas:
```
Next, define the `provider_credential_schema`. Since `Xinference` supports text-generation, embeddings, and reranking models, you can configure it as follows:
```yaml theme={null}
provider_credential_schema:
credential_form_schemas:
- variable: model_type
type: select
label:
en_US: Model type
zh_Hans: 模型类型
required: true
options:
- value: text-generation
label:
en_US: Language Model
zh_Hans: 语言模型
- value: embeddings
label:
en_US: Text Embedding
- value: reranking
label:
en_US: Rerank
```
Every model in Xinference requires a `model_name`:
```yaml theme={null}
- variable: model_name
type: text-input
label:
en_US: Model name
zh_Hans: 模型名称
required: true
placeholder:
zh_Hans: 填写模型名称
en_US: Input model name
```
Because Xinference is locally deployed, users must also supply the server address (`server_url`) and model UID:
```yaml theme={null}
- variable: server_url
label:
zh_Hans: 服务器 URL
en_US: Server url
type: text-input
required: true
placeholder:
zh_Hans: 在此输入 Xinference 的服务器地址,如 https://example.com/xxx
en_US: Enter the url of your Xinference, for example https://example.com/xxx
- variable: model_uid
label:
zh_Hans: 模型 UID
en_US: Model uid
type: text-input
required: true
placeholder:
zh_Hans: 在此输入你的 Model UID
en_US: Enter the model uid
```
This completes the YAML configuration for your custom model provider. Next, create the code files for each model defined in the configuration.
### 2. Develop the Model Code
Xinference supports `llm`, `rerank`, `speech2text`, and `tts`, so create a corresponding directory under `/models` for each type, each containing its feature code.
Below is an example for an `llm` type model. Create a file named `llm.py`, then define a class such as `XinferenceAILargeLanguageModel` that extends `__base.large_language_model.LargeLanguageModel`. The class must implement the following methods.
#### LLM Invocation
The core method for invoking the LLM, supporting both streaming and synchronous responses:
```python theme={null}
def _invoke(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
model_parameters: dict,
tools: Optional[list[PromptMessageTool]] = None,
stop: Optional[list[str]] = None,
stream: bool = True,
user: Optional[str] = None
) -> Union[LLMResult, Generator]:
"""
Invoke the large language model.
:param model: model name
:param credentials: model credentials
:param prompt_messages: prompt messages
:param model_parameters: model parameters
:param tools: tools for tool calling
:param stop: stop words
:param stream: determines if response is streamed
:param user: unique user id
:return: full response or a chunk generator
"""
```
Implement streaming and synchronous responses as separate functions. Python treats any function containing `yield` as a generator that returns `Generator`, so splitting them keeps the return types clean:
```python theme={null}
def _invoke(self, stream: bool, **kwargs) -> Union[LLMResult, Generator]:
if stream:
return self._handle_stream_response(**kwargs)
return self._handle_sync_response(**kwargs)
def _handle_stream_response(self, **kwargs) -> Generator:
for chunk in response:
yield chunk
def _handle_sync_response(self, **kwargs) -> LLMResult:
return LLMResult(**response)
```
#### Pre-calculate Input Tokens
If your model doesn't provide a token-counting interface, return `0`:
```python theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
tools: Optional[list[PromptMessageTool]] = None
) -> int:
"""
Get the number of tokens for the given prompt messages.
"""
return 0
```
Alternatively, you can call `self._get_num_tokens_by_gpt2(text: str)` from the `AIModel` base class, which uses a GPT-2 tokenizer. Remember this is an approximation and may not match your model exactly.
#### Validate Model Credentials
Similar to provider-level credential checks, but scoped to a single model:
```python theme={null}
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate model credentials.
"""
```
#### Dynamic Model Parameters Schema
Unlike [predefined models](/en/develop-plugin/features-and-specs/plugin-types/model-schema), no YAML file defines which parameters a model supports, so you must generate the parameter schema dynamically.
For example, Xinference supports `max_tokens`, `temperature`, and `top_p`. Other providers (e.g., `OpenLLM`) may support parameters like `top_k` only for certain models, so the schema must adapt to each model's capabilities:
```python theme={null}
def get_customizable_model_schema(self, model: str, credentials: dict) -> AIModelEntity | None:
"""
used to define customizable model schema
"""
rules = [
ParameterRule(
name='temperature', type=ParameterType.FLOAT,
use_template='temperature',
label=I18nObject(
zh_Hans='温度', en_US='Temperature'
)
),
ParameterRule(
name='top_p', type=ParameterType.FLOAT,
use_template='top_p',
label=I18nObject(
zh_Hans='Top P', en_US='Top P'
)
),
ParameterRule(
name='max_tokens', type=ParameterType.INT,
use_template='max_tokens',
min=1,
default=512,
label=I18nObject(
zh_Hans='最大生成长度', en_US='Max Tokens'
)
)
]
# if model is A, add top_k to rules
if model == 'A':
rules.append(
ParameterRule(
name='top_k', type=ParameterType.INT,
use_template='top_k',
min=1,
default=50,
label=I18nObject(
zh_Hans='Top K', en_US='Top K'
)
)
)
# ... additional ParameterRule entries omitted for brevity ...
entity = AIModelEntity(
model=model,
label=I18nObject(
en_US=model
),
fetch_from=FetchFrom.CUSTOMIZABLE_MODEL,
model_type=model_type,
model_properties={
ModelPropertyKey.MODE: ModelType.LLM,
},
parameter_rules=rules
)
return entity
```
#### Error Mapping
When an error occurs during model invocation, map it to one of the runtime's `InvokeError` types so Dify can handle different errors consistently:
* `InvokeConnectionError`
* `InvokeServerUnavailableError`
* `InvokeRateLimitError`
* `InvokeAuthorizationError`
* `InvokeBadRequestError`
```python theme={null}
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Map model invocation errors to unified error types.
The key is the error type thrown to the caller.
The value is the error type thrown by the model, which needs to be mapped to a
unified Dify error for consistent handling.
"""
# return {
# InvokeConnectionError: [requests.exceptions.ConnectionError],
# ...
# }
```
For more details on interface methods, see the [Model Documentation](https://docs.dify.ai/zh/develop-plugin/features-and-specs/plugin-types/model-schema).
For the complete code files discussed in this guide, see the [GitHub repository](https://github.com/langgenius/dify-official-plugins/tree/main/models/xinference).
### 3. Debug the Plugin
After development, test the plugin to make sure it runs correctly. For details, see:
<Card title="Debug Plugin" icon="link" href="/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet" />
### 4. Publish the Plugin
To list the plugin on the Dify Marketplace, see Publish to Dify Marketplace.
## Explore More
**Quick Start**:
* [Develop Extension Plugin](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
* [Develop Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)
* [Bundle Plugins: Package Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
**Plugins Endpoint Docs**:
* [Manifest](/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest) Structure
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) Definitions
* [Reverse-Invocation of the Dify Service](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation)
* [Tools](/en/develop-plugin/features-and-specs/plugin-types/tool)
* [Models](/en/develop-plugin/features-and-specs/plugin-types/model-schema)
# Reverse Invocation of Dify Services
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation
Call App, Model, Tool, and Node services in the Dify platform from your plugin
Through reverse invocation, plugins can call services within the main Dify platform to extend their capabilities.
## Callable Dify Modules
* **[App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app)**: Access data from Apps within the Dify platform.
* **[Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model)**: Invoke LLM capabilities within the Dify platform, including all model types and functions such as TTS and Rerank.
* **[Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool)**: Call other tool-type plugins within the Dify platform.
* **[Node](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-node)**: Call nodes within a specific Chatflow/Workflow application in the Dify platform.
## Related Resources
* [Develop Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) - Learn how to develop plugins that integrate with external systems
* [Develop a Slack Bot Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) - An example of using reverse invocation to integrate with the Slack platform
* [Bundle Type Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle) - Learn how to package multiple plugins that use reverse invocation
* [Using Persistent Storage](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv) - Enhance plugin capabilities through KV storage
# App
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app
Call the Chat, Workflow, and Completion interfaces of Dify Apps from your plugin
A plugin can reverse invoke an App within Dify to access its data, with both streaming and non-streaming calls. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
**Interface Types**:
* **Chat Interface**: `Chatbot`, `Agent`, and `Chatflow` applications are all chat-based and share the same input and output parameter types, so they share this interface.
* **Workflow Interface**: Used by Workflow applications.
* **Completion Interface**: Used by Completion (text generation) applications.
Plugins can only access Apps within the Workspace where the plugin resides.
## Call the Chat Interface
### Entry Point
```python theme={null}
self.session.app.chat
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
query: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "streaming",
conversation_id: str | None = None,
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
When `response_mode` is `streaming`, this interface returns `Generator[dict]`; otherwise it returns `dict`. For the specific interface fields, see the return results of `ServiceApi`.
### Use Case
This example calls a Chat type App within an `Endpoint` and returns the result directly:
```python theme={null}
import json
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
class Duck(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
app_id = values["app_id"]
def generator():
response = self.session.app.chat.invoke(
app_id=app_id,
query="Hello from the plugin",
inputs={},
response_mode="streaming",
conversation_id="some-conversation-id",
)
for data in response:
yield f"{json.dumps(data)} <br>"
return Response(generator(), status=200, content_type="text/html")
```
## Call the Workflow Interface
### Entry Point
```python theme={null}
self.session.app.workflow
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "blocking",
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
## Call the Completion Interface
### Entry Point
```python theme={null}
self.session.app.completion
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "blocking",
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model) - Learn how to call model capabilities within the platform
* [Reverse Invocation Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool) - Learn how to call other plugins
* [Develop a Slack Bot Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) - A practical application case using reverse invocation
* [Develop Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) - Learn how to develop extension plugins
# Reverse Invocation Model
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model
Invoke LLM, embedding, rerank, TTS, speech-to-text, and moderation models from your plugin
A plugin can reverse invoke Dify's internal LLM capabilities, including all model types and functions within the platform, such as TTS and Rerank. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
Every model invocation takes a `ModelConfig` type parameter. Its structure is defined in the [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) and varies slightly by model type.
For example, `LLM` type models also require `completion_params` and `mode` parameters. You can construct this structure manually or use `model-selector` type parameters or configurations.
## Invoke LLM
### Entry Point
```python theme={null}
self.session.model.llm
```
### Interface
```python theme={null}
def invoke(
self,
model_config: LLMModelConfig,
prompt_messages: list[PromptMessage],
tools: list[PromptMessageTool] | None = None,
stop: list[str] | None = None,
stream: bool = True,
) -> Generator[LLMResultChunk, None, None] | LLMResult:
pass
```
If the model you are invoking does not have `tool_call` capability, the `tools` passed here will not take effect.
### Use Case
This example invokes OpenAI's `gpt-4o-mini` model within a `Tool`:
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.model.llm import LLMModelConfig
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.model.message import SystemPromptMessage, UserPromptMessage
class LLMTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
response = self.session.model.llm.invoke(
model_config=LLMModelConfig(
provider='openai',
model='gpt-4o-mini',
mode='chat',
completion_params={}
),
prompt_messages=[
SystemPromptMessage(
content='you are a helpful assistant'
),
UserPromptMessage(
content=tool_parameters.get('query')
)
],
stream=True
)
for chunk in response:
if chunk.delta.message:
assert isinstance(chunk.delta.message.content, str)
yield self.create_text_message(text=chunk.delta.message.content)
```
Note that the code passes the `query` parameter from `tool_parameters`.
### Best Practice
Avoid constructing `LLMModelConfig` manually. Instead, let users select the model they want in the UI by adding a `model` parameter to the tool's parameter list:
```yaml theme={null}
identity:
name: llm
author: Dify
label:
en_US: LLM
zh_Hans: LLM
pt_BR: LLM
description:
human:
en_US: A tool for invoking a large language model
zh_Hans: 用于调用大型语言模型的工具
pt_BR: A tool for invoking a large language model
llm: A tool for invoking a large language model
parameters:
- name: prompt
type: string
required: true
label:
en_US: Prompt string
zh_Hans: 提示字符串
pt_BR: Prompt string
human_description:
en_US: used for searching
zh_Hans: 用于搜索网页内容
pt_BR: used for searching
llm_description: key words for searching
form: llm
- name: model
type: model-selector
scope: llm
required: true
label:
en_US: Model
zh_Hans: 使用的模型
pt_BR: Model
human_description:
en_US: Model
zh_Hans: 使用的模型
pt_BR: Model
llm_description: which Model to invoke
form: form
extra:
python:
source: tools/llm.py
```
Because the `scope` of the `model` parameter is `llm`, users can only select `llm` type models. The previous use case then becomes:
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.model.llm import LLMModelConfig
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.model.message import SystemPromptMessage, UserPromptMessage
class LLMTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
response = self.session.model.llm.invoke(
model_config=tool_parameters.get('model'),
prompt_messages=[
SystemPromptMessage(
content='you are a helpful assistant'
),
UserPromptMessage(
content=tool_parameters.get('prompt')
)
],
stream=True
)
for chunk in response:
if chunk.delta.message:
assert isinstance(chunk.delta.message.content, str)
yield self.create_text_message(text=chunk.delta.message.content)
```
## Invoke Summary
This interface summarizes a piece of text using the system model within your current workspace.
### Entry Point
```python theme={null}
self.session.model.summary
```
### Interface
```python theme={null}
def invoke(
self, text: str, instruction: str,
) -> str:
```
* **`text`**: The text to summarize.
* **`instruction`**: Additional instructions, letting you control the style of the summary.
## Invoke TextEmbedding
### Entry Point
```python theme={null}
self.session.model.text_embedding
```
### Interface
```python theme={null}
def invoke(
self,
model_config: TextEmbeddingModelConfig,
texts: list[str],
input_type: EmbeddingInputType = EmbeddingInputType.QUERY,
) -> TextEmbeddingResult:
pass
```
## Invoke Rerank
### Entry Point
```python theme={null}
self.session.model.rerank
```
### Interface
```python theme={null}
def invoke(
self, model_config: RerankModelConfig, docs: list[str], query: str
) -> RerankResult:
pass
```
## Invoke TTS
### Entry Point
```python theme={null}
self.session.model.tts
```
### Interface
```python theme={null}
def invoke(
self, model_config: TTSModelConfig, content_text: str
) -> Generator[bytes, None, None]:
pass
```
The `bytes` stream returned by the `tts` interface is an `mp3` audio byte stream, and each iteration returns a complete audio segment. For more in-depth processing, choose an appropriate audio library.
## Invoke Speech2Text
### Entry Point
```python theme={null}
self.session.model.speech2text
```
### Interface
```python theme={null}
def invoke(
self, model_config: Speech2TextModelConfig, file: IO[bytes]
) -> str:
pass
```
Here, `file` is an audio file encoded in `mp3` format.
## Invoke Moderation
### Entry Point
```python theme={null}
self.session.model.moderation
```
### Interface
```python theme={null}
def invoke(self, model_config: ModerationModelConfig, text: str) -> bool:
pass
```
A return value of `true` indicates that the `text` contains sensitive content.
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation of App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app) - Learn how to invoke Apps within the platform
* [Reverse Invocation of Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool) - Learn how to invoke other plugins
* [Model Plugin Development Guide](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) - Learn how to develop custom model plugins
* [Model Designing Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) - Understand the design principles of model plugins
# Node
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-node
Invoke the Parameter Extractor and Question Classifier nodes from your plugin
A plugin can reverse invoke the capabilities of certain nodes within a Dify Chatflow/Workflow application.
Plugins can call the `ParameterExtractor` and `QuestionClassifier` nodes. Both encapsulate complex prompt and code logic, using LLMs to handle tasks that are difficult to solve with hardcoded rules.
## Call the Parameter Extractor Node
### Entry Point
```python theme={null}
self.session.workflow_node.parameter_extractor
```
### Interface
```python theme={null}
def invoke(
self,
parameters: list[ParameterConfig],
model: ModelConfig,
query: str,
instruction: str = "",
) -> NodeResponse
pass
```
* **`parameters`**: The list of parameters to extract.
* **`model`**: Conforms to the `LLMModelConfig` specification.
* **`query`**: The source text for parameter extraction.
* **`instruction`**: Any additional instructions the LLM might need.
For the structure of `NodeResponse`, see the [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications#noderesponse).
### Use Case
This example extracts a person's name from a conversation:
```python theme={null}
from collections.abc import Generator
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.workflow_node import ModelConfig, NodeResponse, ParameterConfig
class ParameterExtractorTool(Tool):
def _invoke(
self, tool_parameters: dict
) -> Generator[ToolInvokeMessage, None, None]:
response: NodeResponse = self.session.workflow_node.parameter_extractor.invoke(
parameters=[
ParameterConfig(
name="name",
description="name of the person",
required=True,
type="string",
)
],
model=ModelConfig(
provider="langgenius/openai/openai",
name="gpt-4o-mini",
completion_params={},
),
query="My name is John Doe",
instruction="Extract the name of the person",
)
extracted_name = response.outputs.get("name", "Name not found")
yield self.create_text_message(extracted_name)
```
`NodeResponse` is a Pydantic model defined in `dify_plugin.entities.workflow_node` with three dictionary fields: `process_data`, `inputs`, and `outputs`. Extracted values live under `response.outputs`.
## Call the Question Classifier Node
### Entry Point
```python theme={null}
self.session.workflow_node.question_classifier
```
### Interface
```python theme={null}
def invoke(
self,
classes: list[ClassConfig],
model: ModelConfig,
query: str,
instruction: str = "",
) -> NodeResponse:
pass
```
`ClassConfig` is also exported from `dify_plugin.entities.workflow_node`. The interface parameters match those of `ParameterExtractor`, and the final result is stored in `response.outputs["class_name"]`.
# Tool
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool
Call installed tools, Workflow as Tool, and custom tools from your plugin
A plugin can reverse invoke other tool-type plugins within the Dify platform. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
Consider the following scenarios:
* A tool-type plugin implements a function, but the result is not as expected and the data needs post-processing.
* A task requires a web scraper, and you want the flexibility to choose the scraping service.
* You need to aggregate results from multiple tools, which is difficult to handle in a Workflow application.
In these cases, your plugin needs to call other existing tools: tools from the marketplace, a self-built Workflow as a Tool, or a custom tool. All of them are available through the plugin's `self.session.tool` field.
## Call Installed Tools
Call any tool installed in the current Workspace, including other tool-type plugins.
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_builtin_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The plugin ID plus the tool provider name, formatted like `langgenius/google/google`.
* **`tool_name`**: The specific tool name.
* **`parameters`**: The arguments passed to the tool.
## Call Workflow as Tool
See the [Tool Plugin documentation](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) for more information on Workflow as Tool.
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_workflow_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The ID of this tool.
* **`tool_name`**: The name specified when the tool was created.
## Call Custom Tool
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_api_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The ID of this tool.
* **`tool_name`**: The `operation_id` from the OpenAPI specification. If no `operation_id` exists, this is the `tool_name` automatically generated by Dify, which you can find on the tool management page.
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app) - Learn how to call Apps within the platform
* [Reverse Invocation Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model) - Learn how to call model capabilities within the platform
* [Tool Plugin Development Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) - Learn how to develop tool plugins
* [Advanced Tool Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) - Learn about advanced features like Workflow as Tool
# General Specs
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/general-specifications
Common data structures shared across plugin types, including I18nObject, ProviderConfig, ModelConfig, NodeResponse, and ToolSelector
This page covers structures common to all plugin types. Read it alongside [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin) and the [Developer Cheatsheet](/en/develop-plugin/getting-started/cli) for a picture of the overall architecture.
## Path Specifications
File paths in the manifest or any YAML file follow two rules, depending on the file type:
* Multimedia files such as images and videos (for example, the plugin's `icon`) go in the `_assets` folder under the plugin's root directory.
* Regular text files, such as `.py` or `.yaml` code files, are referenced by their absolute path within the plugin project.
## Common Structures
Some data structures are shared between tools, models, and Endpoints. They are defined here.
### I18nObject
`I18nObject` is an internationalization structure that conforms to the [IETF BCP 47](https://tools.ietf.org/html/bcp47) standard. Four languages are supported:
<ParamField type="string">
English (United States).
</ParamField>
<ParamField type="string">
Simplified Chinese.
</ParamField>
<ParamField type="string">
Japanese.
</ParamField>
<ParamField type="string">
Portuguese (Brazil).
</ParamField>
### ProviderConfig
`ProviderConfig` is a common provider form structure used by both `Tool` and `Endpoint`.
<ParamField type="string">
Form item name.
</ParamField>
<ParamField type="I18nObject">
Display labels, following the [IETF BCP 47](https://tools.ietf.org/html/bcp47) standard.
</ParamField>
<ParamField type="provider_config_type">
Form field type. Determines how the field is rendered in the UI.
</ParamField>
<ParamField type="provider_config_scope">
Optional range specification. Varies based on the value of `type`.
</ParamField>
<ParamField type="boolean">
Whether the field must not be empty.
</ParamField>
<ParamField type="any">
Default value. Only supports basic types: `float`, `int`, `string`.
</ParamField>
<ParamField type="array[provider_config_option]">
Available options. Only used when `type` is `select`.
</ParamField>
<ParamField type="object">
Help document link label, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
<ParamField type="string">
Help document link.
</ParamField>
<ParamField type="object">
Placeholder text in multiple languages, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
### ProviderConfigOption (object)
<ParamField type="string">
Option value.
</ParamField>
<ParamField type="object">
Option display label, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
### ProviderConfigType (string)
<ParamField type="string">
Configuration information that will be encrypted.
</ParamField>
<ParamField type="string">
Plain text input field.
</ParamField>
<ParamField type="string">
Dropdown selection field.
</ParamField>
<ParamField type="boolean">
Switch/toggle control.
</ParamField>
<ParamField type="object">
Model configuration selector, including provider name, model name, and model parameters.
</ParamField>
<ParamField type="object">
Application ID selector.
</ParamField>
<ParamField type="object">
Tool configuration selector, including tool provider, name, and parameters.
</ParamField>
<ParamField type="string">
Dataset selector (TBD).
</ParamField>
### ProviderConfigScope (string)
When `type` is `model-selector`:
<ParamField type="string">
All model types.
</ParamField>
<ParamField type="string">
Large language models only.
</ParamField>
<ParamField type="string">
Text embedding models only.
</ParamField>
<ParamField type="string">
Reranking models only.
</ParamField>
<ParamField type="string">
Text-to-speech models only.
</ParamField>
<ParamField type="string">
Speech-to-text models only.
</ParamField>
<ParamField type="string">
Content moderation models only.
</ParamField>
<ParamField type="string">
Vision models only.
</ParamField>
When `type` is `app-selector`:
<ParamField type="string">
All application types.
</ParamField>
<ParamField type="string">
Chat applications only.
</ParamField>
<ParamField type="string">
Workflow applications only.
</ParamField>
<ParamField type="string">
Completion applications only.
</ParamField>
When `type` is `tool-selector`:
<ParamField type="string">
All tool types.
</ParamField>
<ParamField type="string">
Plugin tools only.
</ParamField>
<ParamField type="string">
API tools only.
</ParamField>
<ParamField type="string">
Workflow tools only.
</ParamField>
### ModelConfig
<ParamField type="string">
Model provider name containing the `plugin_id`, in the form `langgenius/openai/openai`.
</ParamField>
<ParamField type="string">
Specific model name.
</ParamField>
<ParamField type="enum">
Model type enumeration; see [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules#modeltype).
</ParamField>
### NodeResponse
<ParamField type="dict">
Variables ultimately passed into the node.
</ParamField>
<ParamField type="dict">
Output results of the node.
</ParamField>
<ParamField type="dict">
Data generated during node execution.
</ParamField>
### ToolSelector
<ParamField type="string">
Tool provider name.
</ParamField>
<ParamField type="string">
Tool name.
</ParamField>
<ParamField type="string">
Tool description.
</ParamField>
<ParamField type="dict[string, any]">
Tool configuration information.
</ParamField>
<ParamField type="dict[string, dict]">
Parameters that require LLM reasoning.
<ParamField type="string">
Parameter name.
</ParamField>
<ParamField type="string">
Parameter type.
</ParamField>
<ParamField type="boolean">
Whether the parameter is required.
</ParamField>
<ParamField type="string">
Parameter description.
</ParamField>
<ParamField type="any">
Default value.
</ParamField>
<ParamField type="array[string]">
Available options for the parameter.
</ParamField>
</ParamField>
## Related Resources
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin)—an overview of Dify plugin development
* [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet)—quick reference for common commands and concepts
* [Tool Plugin Development Details](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)—defining plugin information and the tool plugin development process
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules)—standards for model configuration
# Model Specs
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules
Reference for the entities that define a Dify model plugin, including Provider, AIModelEntity, model types, configuration methods, parameter rules, and credential schemas
A model plugin describes itself with two entities: a [Provider](#provider) that handles authentication and lists supported models, and one [AIModelEntity](#aimodelentity) per model declaring its type, features, and parameters.
<Note>
All entities below are `Pydantic BaseModel` subclasses from the `dify_plugin.entities.model` module.
</Note>
## Quick Decision
<CardGroup>
<Card title="Authentication only: predefined models" icon="key">
User pastes an API key, gets your full model list. Set `configurate_methods: [predefined-model]` and define each model's AIModelEntity in YAML.
</Card>
<Card title="User-supplied models" icon="user-pen">
User configures their own model name and base URL (OpenAI-compatible endpoints, custom deployments). Use `configurate_methods: [customizable-model]` and see [Customizable Model](/en/develop-plugin/features-and-specs/advanced-development/customizable-model).
</Card>
<Card title="Mixed" icon="layer-group">
Built-in catalog plus user-added custom models. Combine both `configurate_methods` values.
</Card>
<Card title="Walkthrough" icon="route">
For an end-to-end example, see [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
</Card>
</CardGroup>
## Provider
<ParamField type="string">
Provider identifier, for example `openai`.
</ParamField>
<ParamField type="object">
Provider display name (i18n). Supports `en_US` (English) and `zh_Hans` (Chinese).
<ParamField type="string">
Chinese label. Falls back to `en_US` if not set.
</ParamField>
<ParamField type="string">
English label
</ParamField>
</ParamField>
<ParamField type="object">
Provider description (i18n).
<ParamField type="string">
Chinese description.
</ParamField>
<ParamField type="string">
English description.
</ParamField>
</ParamField>
<ParamField type="object">
Small provider icon, stored in the `_assets` directory under the provider implementation directory.
<ParamField type="string">
Chinese icon.
</ParamField>
<ParamField type="string">
English icon.
</ParamField>
</ParamField>
<ParamField type="object">
Large provider icon, stored in the `_assets` directory under the provider implementation directory.
<ParamField type="string">
Chinese icon.
</ParamField>
<ParamField type="string">
English icon.
</ParamField>
</ParamField>
<ParamField type="string">
Background color value, for example `#FFFFFF`. If empty, the frontend default color is used.
</ParamField>
<ParamField type="object">
Help information.
<ParamField type="object">
Help title (i18n).
<ParamField type="string">
Chinese title.
</ParamField>
<ParamField type="string">
English title.
</ParamField>
</ParamField>
<ParamField type="object">
Help link (i18n).
<ParamField type="string">
Chinese link.
</ParamField>
<ParamField type="string">
English link.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="array[ModelType]">
Supported model types.
</ParamField>
<ParamField type="array[ConfigurateMethod]">
Configuration methods.
</ParamField>
<ParamField type="ProviderCredentialSchema">
Provider credential specification.
</ParamField>
<ParamField type="ModelCredentialSchema">
Model credential specification.
</ParamField>
## AIModelEntity
<ParamField type="string">
Model identifier, for example `gpt-3.5-turbo`.
</ParamField>
<ParamField type="object">
Model display name (i18n). Supports `en_US` (English) and `zh_Hans` (Chinese).
<ParamField type="string">
Chinese label.
</ParamField>
<ParamField type="string">
English label.
</ParamField>
</ParamField>
<ParamField type="ModelType">
Model type.
</ParamField>
<ParamField type="array[ModelFeature]">
Supported features.
</ParamField>
<ParamField type="object">
Model properties.
<ParamField type="LLMMode">
Mode (model type `llm`).
</ParamField>
<ParamField type="integer">
Context size (model types `llm` and `text-embedding`).
</ParamField>
<ParamField type="integer">
Maximum number of chunks (model types `text-embedding` and `moderation`).
</ParamField>
<ParamField type="integer">
Maximum file upload size in MB (model type `speech2text`).
</ParamField>
<ParamField type="string">
Supported file extensions, for example `mp3,mp4` (model type `speech2text`).
</ParamField>
<ParamField type="string">
Default voice; one of `alloy`, `echo`, `fable`, `onyx`, `nova`, `shimmer` (model type `tts`).
</ParamField>
<ParamField type="array">
Available voices (model type `tts`).
<ParamField type="string">
Voice model.
</ParamField>
<ParamField type="string">
Voice model display name.
</ParamField>
<ParamField type="string">
Languages the voice model supports.
</ParamField>
</ParamField>
<ParamField type="integer">
Word limit per conversion; defaults to splitting by paragraph (model type `tts`).
</ParamField>
<ParamField type="string">
Supported audio file extensions, for example `mp3,wav` (model type `tts`).
</ParamField>
<ParamField type="integer">
Number of concurrent text-to-audio conversion tasks (model type `tts`).
</ParamField>
<ParamField type="integer">
Maximum characters per chunk (model type `moderation`).
</ParamField>
</ParamField>
<ParamField type="array[ParameterRule]">
Rules for model call parameters.
</ParamField>
<ParamField type="PriceConfig">
Pricing information.
</ParamField>
<ParamField type="boolean">
Whether the model is deprecated. Deprecated models no longer appear in the model list, but existing configurations keep working. Defaults to `False`.
</ParamField>
## ModelType
<ParamField type="string">
Text generation model.
</ParamField>
<ParamField type="string">
Text embedding model.
</ParamField>
<ParamField type="string">
Rerank model.
</ParamField>
<ParamField type="string">
Speech to text.
</ParamField>
<ParamField type="string">
Text to speech.
</ParamField>
<ParamField type="string">
Content moderation.
</ParamField>
## ConfigurateMethod
<ParamField type="string">
Predefined model. The user configures unified provider credentials once to use all predefined models under the provider.
</ParamField>
<ParamField type="string">
Customizable model. The user adds a credential configuration for each model.
</ParamField>
<ParamField type="string">
Fetch from remote. Like `predefined-model`, only unified provider credentials are needed, but the model list is fetched from the provider using those credentials.
</ParamField>
## ModelFeature
<ParamField type="string">
Agent reasoning. Generally, models over 70B have chain-of-thought capabilities.
</ParamField>
<ParamField type="string">
Vision (image understanding).
</ParamField>
<ParamField type="string">
Tool calling.
</ParamField>
<ParamField type="string">
Multiple tool calling.
</ParamField>
<ParamField type="string">
Streaming tool calling.
</ParamField>
## FetchFrom
<ParamField type="string">
Predefined model.
</ParamField>
<ParamField type="string">
Remote model.
</ParamField>
## LLMMode
<ParamField type="string">
Text completion.
</ParamField>
<ParamField type="string">
Chat.
</ParamField>
## ParameterRule
<ParamField type="string">
Actual parameter name used in the model call.
</ParamField>
<ParamField type="string">
Template to use.
</ParamField>
Five parameter templates are predefined:
* `temperature`
* `top_p`
* `frequency_penalty`
* `presence_penalty`
* `max_tokens`
Set one of these names in `use_template` to inherit the default configuration from `entities.defaults.PARAMETER_RULE_TEMPLATE`; you then only need `name` and `use_template`. Any additional parameters you set override the template defaults. See `openai/llm/gpt-3.5-turbo.yaml` and the examples in [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
<ParamField type="object">
Label (i18n).
<ParamField type="string">
Chinese label.
</ParamField>
<ParamField type="string">
English label.
</ParamField>
</ParamField>
<ParamField type="string">
Parameter type.
<ParamField type="string">
Integer.
</ParamField>
<ParamField type="string">
Floating point.
</ParamField>
<ParamField type="string">
String.
</ParamField>
<ParamField type="string">
Boolean.
</ParamField>
</ParamField>
<ParamField type="object">
Help information (i18n).
<ParamField type="string">
Chinese help text.
</ParamField>
<ParamField type="string">
English help text.
</ParamField>
</ParamField>
<ParamField type="boolean">
Whether the parameter is required. Defaults to `False`.
</ParamField>
<ParamField type="int/float/string/boolean">
Default value.
</ParamField>
<ParamField type="int/float">
Minimum value. Numeric types only.
</ParamField>
<ParamField type="int/float">
Maximum value. Numeric types only.
</ParamField>
<ParamField type="integer">
Number of decimal places to keep. Numeric types only.
</ParamField>
<ParamField type="array[string]">
Dropdown option values. Only applies when `type` is `string`. If not set or null, values are unrestricted.
</ParamField>
## PriceConfig
<ParamField type="float">
Input (prompt) unit price.
</ParamField>
<ParamField type="float">
Output (returned content) unit price.
</ParamField>
<ParamField type="float">
Price unit. For example, if pricing is per 1M tokens, the unit token count corresponding to the unit price is `0.000001`.
</ParamField>
<ParamField type="string">
Currency unit.
</ParamField>
## ProviderCredentialSchema
<ParamField type="array[CredentialFormSchema]">
Credential form specification.
</ParamField>
## ModelCredentialSchema
<ParamField type="object">
Model identifier. The default variable name is `model`.
<ParamField type="object">
Display name of the model form item.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="object">
Placeholder text for the model form item.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="array[CredentialFormSchema]">
Credential form specification.
</ParamField>
## CredentialFormSchema
<ParamField type="string">
Form item variable name.
</ParamField>
<ParamField type="object">
Form item label.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="FormType">
Form item type.
</ParamField>
<ParamField type="boolean">
Whether the form item is required.
</ParamField>
<ParamField type="string">
Default value.
</ParamField>
<ParamField type="array[FormOption]">
Dropdown content. Specific to the `select` and `radio` types.
</ParamField>
<ParamField type="object">
Form item placeholder. Specific to the `text-input` type.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="integer">
Maximum input length. Specific to the `text-input` type. `0` means no limit.
</ParamField>
<ParamField type="array[FormShowOnObject]">
Show this item only when other form item values meet the given conditions. Empty means always show.
</ParamField>
### FormType
<ParamField type="string">
Text input component.
</ParamField>
<ParamField type="string">
Password input component.
</ParamField>
<ParamField type="string">
Single-select dropdown.
</ParamField>
<ParamField type="string">
Radio component.
</ParamField>
<ParamField type="string">
Switch component. Only supports `true` and `false`.
</ParamField>
### FormOption
<ParamField type="object">
Label.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="string">
Dropdown option value.
</ParamField>
<ParamField type="array[FormShowOnObject]">
Show this option only when other form item values meet the given conditions. Empty means always show.
</ParamField>
### FormShowOnObject
<ParamField type="string">
Variable name of the other form item.
</ParamField>
<ParamField type="string">
Variable value of the other form item.
</ParamField>
## Related Resources
* [Model Architecture Details](/en/develop-plugin/features-and-specs/plugin-types/model-schema)—architecture specifications for model plugins
* [Quickly Integrate a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)—apply these rules to add new models
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)—plugin manifest configuration
* [Create a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)—develop a new model provider plugin
# Model API Interface
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/model-schema
Interfaces and data structures for implementing Dify model plugins, covering LLM, TextEmbedding, Rerank, Speech2Text, Text2Speech, and Moderation models
## Introduction
This page is the technical reference for the interfaces and data structures you implement when integrating AI models with Dify through a model plugin.
<Note>
Before diving into this API reference, we recommend reading [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) for the conceptual model and [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) for a step-by-step walkthrough.
</Note>
### Quick Decision: Which Method Do I Implement?
| If your model is a... | Implement |
| :-------------------- | :---------------------------------------------- |
| Chat/completion LLM | `LargeLanguageModel._invoke`, `_get_num_tokens` |
| Embedding model | `TextEmbeddingModel._invoke`, `_get_num_tokens` |
| Rerank model | `RerankModel._invoke` |
| Speech-to-text | `Speech2TextModel._invoke` |
| Text-to-speech | `Text2SpeechModel._invoke` |
| Moderation | `ModerationModel._invoke` |
Every provider also implements `validate_provider_credentials` (provider-level auth) and, if the model is user-configurable, `validate_credentials` per model type.
<CardGroup>
<Card title="Provider Implementation" icon="plug" href="#model-provider">
Learn how to implement model provider classes for different AI service providers
</Card>
<Card title="Model Types" icon="layer-group" href="#models">
Implementation details for the five supported model types: LLM, Embedding, Rerank, Speech2Text, and Text2Speech
</Card>
<Card title="Data Structures" icon="database" href="#entities">
Comprehensive reference for all data structures used in the model API
</Card>
<Card title="Error Handling" icon="triangle-exclamation" href="#common-interfaces">
Guidelines for proper error mapping and exception handling
</Card>
</CardGroup>
## Model Provider
Every model provider must inherit from the `__base.model_provider.ModelProvider` base class and implement the credential validation interface.
### Provider Credential Validation
<CodeGroup>
```python Core Implementation theme={null}
def validate_provider_credentials(self, credentials: dict) -> None:
"""
Validate provider credentials by making a test API call
Parameters:
credentials: Provider credentials as defined in `provider_credential_schema`
Raises:
CredentialsValidateFailedError: If validation fails
"""
try:
# Example implementation: validate using an LLM model instance
model_instance = self.get_model_instance(ModelType.LLM)
model_instance.validate_credentials(
model="example-model",
credentials=credentials
)
except Exception as ex:
logger.exception(f"Credential validation failed")
raise CredentialsValidateFailedError(f"Invalid credentials: {str(ex)}")
```
```python Custom Model Provider theme={null}
class XinferenceProvider(Provider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
For custom-only model providers, a simple implementation is sufficient
as validation happens at the model level
"""
pass
```
</CodeGroup>
<ParamField type="dict">
Credential information as defined in the provider's YAML configuration under `provider_credential_schema`, typically fields such as `api_key` and `organization_id`.
</ParamField>
<Warning>
If validation fails, your implementation must raise a `CredentialsValidateFailedError` exception. This ensures proper error handling in the Dify UI.
</Warning>
<Tip>
For predefined model providers, implement a thorough validation method that verifies the credentials against your API. For custom model providers (where each model has its own credentials), a simplified implementation is sufficient.
</Tip>
## Models
Dify supports five distinct model types, each with its own interface. All model types share the common requirements below.
### Common Interfaces
Every model implementation, regardless of type, must implement these two fundamental methods:
#### 1. Model Credential Validation
<CodeGroup>
```python Implementation theme={null}
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate that the provided credentials work with the specified model
Parameters:
model: The specific model identifier (e.g., "gpt-4")
credentials: Authentication details for the model
Raises:
CredentialsValidateFailedError: If validation fails
"""
try:
# Make a lightweight API call to verify credentials
# Example: List available models or check account status
response = self._api_client.validate_api_key(credentials["api_key"])
# Verify the specific model is available if applicable
if model not in response.get("available_models", []):
raise CredentialsValidateFailedError(f"Model {model} is not available")
except ApiException as e:
raise CredentialsValidateFailedError(str(e))
```
</CodeGroup>
<ParamField type="string">
The specific model identifier to validate (e.g., "gpt-4", "claude-3-opus")
</ParamField>
<ParamField type="dict">
Credential information as defined in the provider's configuration
</ParamField>
#### 2. Error Mapping
<CodeGroup>
```python Implementation theme={null}
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Map provider-specific exceptions to standardized Dify error types
Returns:
Dictionary mapping Dify error types to lists of provider exception types
"""
return {
InvokeConnectionError: [
requests.exceptions.ConnectionError,
requests.exceptions.Timeout,
ConnectionRefusedError
],
InvokeServerUnavailableError: [
ServiceUnavailableError,
HTTPStatusError
],
InvokeRateLimitError: [
RateLimitExceededError,
QuotaExceededError
],
InvokeAuthorizationError: [
AuthenticationError,
InvalidAPIKeyError,
PermissionDeniedError
],
InvokeBadRequestError: [
InvalidRequestError,
ValidationError
]
}
```
</CodeGroup>
<Accordion title="Available Error Types">
<ParamField type="class">
Network connection failures, timeouts
</ParamField>
<ParamField type="class">
Service provider is down or unavailable
</ParamField>
<ParamField type="class">
Rate limits or quota limits reached
</ParamField>
<ParamField type="class">
Authentication or permission issues
</ParamField>
<ParamField type="class">
Invalid parameters or requests
</ParamField>
</Accordion>
<Tip>
You can alternatively raise these standardized error types directly in your code instead of relying on the error mapping. This approach gives you more control over error messages.
</Tip>
### LLM Implementation
To implement a Large Language Model provider, inherit from the `__base.large_language_model.LargeLanguageModel` base class and implement these methods:
#### 1. Model Invocation
This core method handles both streaming and non-streaming API calls to language models.
<CodeGroup>
```python Core Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
model_parameters: dict,
tools: Optional[list[PromptMessageTool]] = None,
stop: Optional[list[str]] = None,
stream: bool = True,
user: Optional[str] = None
) -> Union[LLMResult, Generator[LLMResultChunk, None, None]]:
"""
Invoke the language model
"""
# Prepare API parameters
api_params = self._prepare_api_parameters(
model,
credentials,
prompt_messages,
model_parameters,
tools,
stop
)
try:
# Choose between streaming and non-streaming implementation
if stream:
return self._invoke_stream(model, api_params, user)
else:
return self._invoke_sync(model, api_params, user)
except Exception as e:
# Map errors using the error mapping property
self._handle_api_error(e)
# Helper methods for streaming and non-streaming calls
def _invoke_stream(self, model, api_params, user):
# Implement streaming call and yield chunks
pass
def _invoke_sync(self, model, api_params, user):
# Implement synchronous call and return complete result
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Model identifier (e.g., "gpt-4", "claude-3")
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="list[PromptMessage]">
Message list in Dify's standardized format:
* For `completion` models: include a single `UserPromptMessage`.
* For `chat` models: include `SystemPromptMessage`, `UserPromptMessage`, `AssistantPromptMessage`, and `ToolPromptMessage` as needed.
</ParamField>
<ParamField type="dict">
Model-specific parameters (temperature, top\_p, etc.) as defined in the model's YAML configuration
</ParamField>
<ParamField type="list[PromptMessageTool]">
Tool definitions for function calling capabilities
</ParamField>
<ParamField type="list[string]">
Stop sequences that will halt model generation when encountered
</ParamField>
<ParamField type="boolean">
Whether to return a streaming response
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Values">
<ParamField type="Generator[LLMResultChunk, None, None]">
A generator yielding chunks of the response as they become available
</ParamField>
<ParamField type="LLMResult">
A complete response object with the full generated text
</ParamField>
</Accordion>
<Tip>
We recommend implementing separate helper methods for streaming and non-streaming calls to keep your code organized and maintainable.
</Tip>
#### 2. Token Counting
<CodeGroup>
```python Implementation theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
tools: Optional[list[PromptMessageTool]] = None
) -> int:
"""
Calculate the number of tokens in the prompt
"""
# Convert prompt_messages to the format expected by the tokenizer
text = self._convert_messages_to_text(prompt_messages)
try:
# Use the appropriate tokenizer for this model
tokenizer = self._get_tokenizer(model)
return len(tokenizer.encode(text))
except Exception:
# Fall back to a generic tokenizer
return self._get_num_tokens_by_gpt2(text)
```
</CodeGroup>
<Info>
If the model doesn't provide a tokenizer, you can use the base class's `_get_num_tokens_by_gpt2(text)` method for a reasonable approximation.
</Info>
#### 3. Custom Model Schema (Optional)
<CodeGroup>
```python Implementation theme={null}
def get_customizable_model_schema(
self,
model: str,
credentials: dict
) -> Optional[AIModelEntity]:
"""
Get parameter schema for custom models
"""
# For fine-tuned models, you might return the base model's schema
if model.startswith("ft:"):
base_model = self._extract_base_model(model)
return self._get_predefined_model_schema(base_model)
# For standard models, return None to use the predefined schema
return None
```
</CodeGroup>
<Info>
This method is only necessary for providers that support custom models. It allows custom models to inherit parameter rules from base models.
</Info>
### TextEmbedding Implementation
<Info>
Text embedding models convert text into high-dimensional vectors that capture semantic meaning, which is useful for retrieval, similarity search, and classification.
</Info>
To implement a Text Embedding provider, inherit from the `__base.text_embedding_model.TextEmbeddingModel` base class:
#### 1. Core Embedding Method
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
texts: list[str],
user: Optional[str] = None
) -> TextEmbeddingResult:
"""
Generate embedding vectors for multiple texts
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Handle batching if needed
batch_size = self._get_batch_size(model)
all_embeddings = []
total_tokens = 0
start_time = time.time()
# Process in batches to avoid API limits
for i in range(0, len(texts), batch_size):
batch = texts[i:i+batch_size]
# Make API call to the embeddings endpoint
response = client.embeddings.create(
model=model,
input=batch,
user=user
)
# Extract embeddings from response
batch_embeddings = [item.embedding for item in response.data]
all_embeddings.extend(batch_embeddings)
# Track token usage
total_tokens += response.usage.total_tokens
# Calculate usage metrics
elapsed_time = time.time() - start_time
usage = self._create_embedding_usage(
model=model,
tokens=total_tokens,
latency=elapsed_time
)
return TextEmbeddingResult(
model=model,
embeddings=all_embeddings,
usage=usage
)
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Embedding model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the embedding service
</ParamField>
<ParamField type="list[string]">
List of text inputs to embed
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="object">
A structured response containing:
* `model`: The model used for embedding.
* `embeddings`: Embedding vectors in the same order as the input texts.
* `usage`: Metadata about token usage and costs.
</ParamField>
</Accordion>
#### 2. Token Counting Method
<CodeGroup>
```python Implementation theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
texts: list[str]
) -> int:
"""
Calculate the number of tokens in the texts to be embedded
"""
# Join all texts to estimate token count
combined_text = " ".join(texts)
try:
# Use the appropriate tokenizer for this model
tokenizer = self._get_tokenizer(model)
return len(tokenizer.encode(combined_text))
except Exception:
# Fall back to a generic tokenizer
return self._get_num_tokens_by_gpt2(combined_text)
```
</CodeGroup>
<Tip>
For embedding models, accurate token counting is important for cost estimation, but not critical for functionality. The `_get_num_tokens_by_gpt2` method provides a reasonable approximation for most models.
</Tip>
### Rerank Implementation
<Info>
Reranking models help improve search quality by re-ordering a set of candidate documents based on their relevance to a query, typically after an initial retrieval phase.
</Info>
To implement a Reranking provider, inherit from the `__base.rerank_model.RerankModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
query: str,
docs: list[str],
score_threshold: Optional[float] = None,
top_n: Optional[int] = None,
user: Optional[str] = None
) -> RerankResult:
"""
Rerank documents based on relevance to the query
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Prepare request data
request_data = {
"query": query,
"documents": docs,
}
# Call reranking API endpoint
response = client.rerank(
model=model,
**request_data,
user=user
)
# Process results
ranked_results = []
for i, result in enumerate(response.results):
# Create RerankDocument for each result
doc = RerankDocument(
index=result.document_index, # Original index in docs list
text=docs[result.document_index], # Original text
score=result.relevance_score # Relevance score
)
ranked_results.append(doc)
# Sort by score in descending order
ranked_results.sort(key=lambda x: x.score, reverse=True)
# Apply score threshold filtering if specified
if score_threshold is not None:
ranked_results = [doc for doc in ranked_results if doc.score >= score_threshold]
# Apply top_n limit if specified
if top_n is not None and top_n > 0:
ranked_results = ranked_results[:top_n]
return RerankResult(
model=model,
docs=ranked_results
)
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Reranking model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
The search query text
</ParamField>
<ParamField type="list[string]">
List of document texts to be reranked
</ParamField>
<ParamField type="float">
Minimum score a document must reach to be included in the results
</ParamField>
<ParamField type="int">
Maximum number of results to return
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="object">
A structured response containing:
* `model`: The model used for reranking.
* `docs`: List of `RerankDocument` objects with index, text, and score.
</ParamField>
</Accordion>
<Warning>
Reranking can be computationally expensive, especially with large document sets. Implement batching for large document collections to avoid timeouts or excessive resource consumption.
</Warning>
### Speech2Text Implementation
<Info>
Speech-to-text models convert spoken language from audio files into written text, enabling applications like transcription services, voice commands, and accessibility features.
</Info>
To implement a Speech-to-Text provider, inherit from the `__base.speech2text_model.Speech2TextModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
file: IO[bytes],
user: Optional[str] = None
) -> str:
"""
Convert speech audio to text
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Determine the file format
file_format = self._detect_audio_format(file)
# Prepare the file for API submission
# Most APIs require either a file path or binary data
audio_data = file.read()
# Call the speech-to-text API
response = client.audio.transcriptions.create(
model=model,
file=("audio.mp3", audio_data), # Adjust filename based on actual format
user=user
)
# Extract and return the transcribed text
return response.text
except Exception as e:
# Map to appropriate error type
self._handle_api_error(e)
finally:
# Reset file pointer for potential reuse
file.seek(0)
```
```python Helper Methods theme={null}
def _detect_audio_format(self, file: IO[bytes]) -> str:
"""
Detect the audio format based on file header
"""
# Read the first few bytes to check the file signature
header = file.read(12)
file.seek(0) # Reset file pointer
# Check for common audio format signatures
if header.startswith(b'RIFF') and header[8:12] == b'WAVE':
return 'wav'
elif header.startswith(b'ID3') or header.startswith(b'\xFF\xFB'):
return 'mp3'
elif header.startswith(b'OggS'):
return 'ogg'
elif header.startswith(b'fLaC'):
return 'flac'
else:
# Default or additional format checks
return 'mp3' # Default assumption
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Speech-to-text model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="IO[bytes]">
Binary file object containing the audio to transcribe
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="string">
The transcribed text from the audio file
</ParamField>
</Accordion>
<Tip>
Audio format detection is important for proper handling of different file types. Consider implementing a helper method to detect the format from the file header as shown in the example.
</Tip>
<Warning>
Some speech-to-text APIs have file size limitations. Consider implementing chunking for large audio files if necessary.
</Warning>
### Text2Speech Implementation
<Info>
Text-to-speech models convert written text into natural-sounding speech, enabling applications such as voice assistants, screen readers, and audio content generation.
</Info>
To implement a Text-to-Speech provider, inherit from the `__base.text2speech_model.Text2SpeechModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
content_text: str,
streaming: bool,
user: Optional[str] = None
) -> Union[bytes, Generator[bytes, None, None]]:
"""
Convert text to speech audio
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Get voice settings based on model
voice = self._get_voice_for_model(model)
try:
# Choose implementation based on streaming preference
if streaming:
return self._stream_audio(
client=client,
model=model,
text=content_text,
voice=voice,
user=user
)
else:
return self._generate_complete_audio(
client=client,
model=model,
text=content_text,
voice=voice,
user=user
)
except Exception as e:
self._handle_api_error(e)
```
```python Helper Methods theme={null}
def _stream_audio(self, client, model, text, voice, user=None):
"""
Implementation for streaming audio output
"""
# Make API request with stream=True
response = client.audio.speech.create(
model=model,
voice=voice,
input=text,
stream=True,
user=user
)
# Yield chunks as they arrive
for chunk in response:
if chunk:
yield chunk
def _generate_complete_audio(self, client, model, text, voice, user=None):
"""
Implementation for complete audio file generation
"""
# Make API request for complete audio
response = client.audio.speech.create(
model=model,
voice=voice,
input=text,
user=user
)
# Get audio data as bytes
audio_data = response.content
return audio_data
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Text-to-speech model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
Text content to be converted to speech
</ParamField>
<ParamField type="boolean">
Whether to return streaming audio or complete file
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="Generator[bytes, None, None]">
A generator yielding audio chunks as they become available
</ParamField>
<ParamField type="bytes">
Complete audio data as bytes
</ParamField>
</Accordion>
<Tip>
Most text-to-speech APIs require you to specify a voice along with the model. Consider implementing a mapping between Dify's model identifiers and the provider's voice options.
</Tip>
<Warning>
Long text inputs may need to be chunked for better speech synthesis quality. Consider implementing text preprocessing to handle punctuation, numbers, and special characters properly.
</Warning>
### Moderation Implementation
<Info>
Moderation models analyze content for potentially harmful, inappropriate, or unsafe material, helping maintain platform safety and content policies.
</Info>
To implement a Moderation provider, inherit from the `__base.moderation_model.ModerationModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
text: str,
user: Optional[str] = None
) -> bool:
"""
Analyze text for harmful content
Returns:
bool: False if the text is safe, True if it contains harmful content
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Call moderation API
response = client.moderations.create(
model=model,
input=text,
user=user
)
# Check if any categories were flagged
result = response.results[0]
# Return True if flagged in any category, False if safe
return result.flagged
except Exception as e:
# Log the error but default to safe if there's an API issue.
# This is a conservative approach; production systems might want
# different fallback behavior.
logger.error(f"Moderation API error: {str(e)}")
return False
```
```python Detailed Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
text: str,
user: Optional[str] = None
) -> bool:
"""
Analyze text for harmful content with detailed category checking
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Call moderation API
response = client.moderations.create(
model=model,
input=text,
user=user
)
# Get detailed category results
result = response.results[0]
categories = result.categories
# Check specific categories based on your application's needs
# For example, you might want to flag certain categories but not others
critical_violations = [
categories.harassment,
categories.hate,
categories.self_harm,
categories.sexual,
categories.violence
]
# Flag content if any critical category is violated
return any(critical_violations)
except Exception as e:
self._handle_api_error(e)
# Default to safe in case of error
return False
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Moderation model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
Text content to be analyzed
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="boolean">
Boolean indicating content safety:
* `False`: The content is safe.
* `True`: The content contains harmful material.
</ParamField>
</Accordion>
<Warning>
Moderation is often used as a safety mechanism. Consider the implications of false negatives (letting harmful content through) versus false positives (blocking safe content) when implementing your solution.
</Warning>
<Tip>
Many moderation APIs provide detailed category scores rather than just a binary result. Consider extending this implementation to return more detailed information about specific categories of harmful content if your application needs it.
</Tip>
## Entities
### PromptMessageRole
The role of a message in a conversation.
```python theme={null}
class PromptMessageRole(Enum):
"""
Enum class for prompt message.
"""
SYSTEM = "system"
USER = "user"
ASSISTANT = "assistant"
TOOL = "tool"
```
### PromptMessageContentType
The type of message content: plain text or image.
```python theme={null}
class PromptMessageContentType(Enum):
"""
Enum class for prompt message content type.
"""
TEXT = 'text'
IMAGE = 'image'
```
### PromptMessageContent
Base class for message content. It exists only for type declarations—do not instantiate it directly.
```python theme={null}
class PromptMessageContent(BaseModel):
"""
Model class for prompt message content.
"""
type: PromptMessageContentType
data: str # Content data
```
Content currently supports two types, text and image, and a single message can combine text with multiple images. Instantiate `TextPromptMessageContent` and `ImagePromptMessageContent` instead.
### TextPromptMessageContent
```python theme={null}
class TextPromptMessageContent(PromptMessageContent):
"""
Model class for text prompt message content.
"""
type: PromptMessageContentType = PromptMessageContentType.TEXT
```
When a message combines text and images, wrap the text in this entity and add it to the `content` list.
### ImagePromptMessageContent
```python theme={null}
class ImagePromptMessageContent(PromptMessageContent):
"""
Model class for image prompt message content.
"""
class DETAIL(Enum):
LOW = 'low'
HIGH = 'high'
type: PromptMessageContentType = PromptMessageContentType.IMAGE
detail: DETAIL = DETAIL.LOW # Resolution
```
When a message combines text and images, wrap each image in this entity and add it to the `content` list. `data` accepts an image URL or a base64-encoded image string.
### PromptMessage
Base class for all role-specific messages. It exists only for type declarations—do not instantiate it directly.
```python theme={null}
class PromptMessage(ABC, BaseModel):
"""
Model class for prompt message.
"""
role: PromptMessageRole # Message role
content: Optional[str | list[PromptMessageContent]] = None # Either a string or a content list; the list form supports multimodal input, see PromptMessageContent
name: Optional[str] = None # Optional name
```
### UserPromptMessage
Represents a user message.
```python theme={null}
class UserPromptMessage(PromptMessage):
"""
Model class for user prompt message.
"""
role: PromptMessageRole = PromptMessageRole.USER
```
### AssistantPromptMessage
Represents a model response, typically used for few-shot examples or chat history input.
```python theme={null}
class AssistantPromptMessage(PromptMessage):
"""
Model class for assistant prompt message.
"""
class ToolCall(BaseModel):
"""
Model class for assistant prompt message tool call.
"""
class ToolCallFunction(BaseModel):
"""
Model class for assistant prompt message tool call function.
"""
name: str # Tool name
arguments: str # Tool parameters
id: str # Tool call ID; only meaningful for OpenAI tool calls. Uniquely identifies one invocation, since the same tool can be called multiple times
type: str # Defaults to "function"
function: ToolCallFunction # Tool call information
role: PromptMessageRole = PromptMessageRole.ASSISTANT
tool_calls: list[ToolCall] = [] # Model's tool call results (only returned when tools are passed in and the model decides to call them)
```
`tool_calls` holds the tool calls the model returns when the request includes `tools`.
### SystemPromptMessage
Represents a system message, typically used to set system instructions for the model.
```python theme={null}
class SystemPromptMessage(PromptMessage):
"""
Model class for system prompt message.
"""
role: PromptMessageRole = PromptMessageRole.SYSTEM
```
### ToolPromptMessage
Represents a tool message, which passes a tool's execution result back to the model for next-step planning.
```python theme={null}
class ToolPromptMessage(PromptMessage):
"""
Model class for tool prompt message.
"""
role: PromptMessageRole = PromptMessageRole.TOOL
tool_call_id: str # Tool call ID; if the provider doesn't support OpenAI tool calls, you can pass the tool name instead
```
Pass the tool's execution result through the inherited `content` field.
### PromptMessageTool
```python theme={null}
class PromptMessageTool(BaseModel):
"""
Model class for prompt message tool.
"""
name: str # Tool name
description: str # Tool description
parameters: dict # Tool parameters dict
```
### LLMResult
```python theme={null}
class LLMResult(BaseModel):
"""
Model class for llm result.
"""
model: str # Model actually used
prompt_messages: list[PromptMessage] # Prompt message list
message: AssistantPromptMessage # Reply message
usage: LLMUsage # Token usage and cost information
system_fingerprint: Optional[str] = None # Request fingerprint; see OpenAI's parameter definition
```
### LLMResultChunkDelta
The incremental delta within each chunk of a streaming response.
```python theme={null}
class LLMResultChunkDelta(BaseModel):
"""
Model class for llm result chunk delta.
"""
index: int # Sequence number
message: AssistantPromptMessage # Reply message
usage: Optional[LLMUsage] = None # Token usage and cost information; only returned in the last chunk
finish_reason: Optional[str] = None # Completion reason; only returned in the last chunk
```
### LLMResultChunk
A single chunk in a streaming response.
```python theme={null}
class LLMResultChunk(BaseModel):
"""
Model class for llm result chunk.
"""
model: str # Model actually used
prompt_messages: list[PromptMessage] # Prompt message list
system_fingerprint: Optional[str] = None # Request fingerprint; see OpenAI's parameter definition
delta: LLMResultChunkDelta # Content changes in this chunk
```
### LLMUsage
```python theme={null}
class LLMUsage(ModelUsage):
"""
Model class for llm usage.
"""
prompt_tokens: int # Tokens used by the prompt
prompt_unit_price: Decimal # Prompt unit price
prompt_price_unit: Decimal # Prompt price unit, i.e., the number of tokens the unit price applies to
prompt_price: Decimal # Prompt cost
completion_tokens: int # Tokens used by the completion
completion_unit_price: Decimal # Completion unit price
completion_price_unit: Decimal # Completion price unit, i.e., the number of tokens the unit price applies to
completion_price: Decimal # Completion cost
total_tokens: int # Total tokens used
total_price: Decimal # Total cost
currency: str # Currency unit
latency: float # Request latency in seconds
```
### TextEmbeddingResult
```python theme={null}
class TextEmbeddingResult(BaseModel):
"""
Model class for text embedding result.
"""
model: str # Model actually used
embeddings: list[list[float]] # Embedding vectors, in the same order as the input texts
usage: EmbeddingUsage # Usage information
```
### EmbeddingUsage
```python theme={null}
class EmbeddingUsage(ModelUsage):
"""
Model class for embedding usage.
"""
tokens: int # Tokens used
total_tokens: int # Total tokens used
unit_price: Decimal # Unit price
price_unit: Decimal # Price unit, i.e., the number of tokens the unit price applies to
total_price: Decimal # Total cost
currency: str # Currency unit
latency: float # Request latency in seconds
```
### RerankResult
```python theme={null}
class RerankResult(BaseModel):
"""
Model class for rerank result.
"""
model: str # Model actually used
docs: list[RerankDocument] # List of reranked documents
```
### RerankDocument
```python theme={null}
class RerankDocument(BaseModel):
"""
Model class for rerank document.
"""
index: int # Index in the original docs list
text: str # Document text
score: float # Relevance score
```
## Related Resources
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): standards for model configuration.
* [Model Plugin Introduction](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): core concepts of model plugins.
* [Quickly Integrate a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): add new models to existing providers.
* [Create a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): develop a new model provider from scratch.
# Multilingual README
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme
Add per-language README files so Dify Marketplace shows your plugin's documentation in each user's preferred language
A plugin's README is the first thing users read on the [Dify Marketplace](https://marketplace.dify.ai) detail page. Adding translations lets non-English users read your docs in their own language without losing the original.
## File Specifications
| Language | Required | Filename | Path |
| :------------------ | :------- | :------------------ | :---------- |
| English | Yes | `README.md` | Plugin root |
| Simplified Chinese | No | `README_zh_Hans.md` | `readme/` |
| Japanese | No | `README_ja_JP.md` | `readme/` |
| Portuguese (Brazil) | No | `README_pt_BR.md` | `readme/` |
All files must be UTF-8 encoded. The English `README.md` always stays in the plugin root; every other language goes inside a `readme/` subdirectory.
```text theme={null}
your_plugin/
├── README.md
├── readme/
│ ├── README_zh_Hans.md
│ ├── README_ja_JP.md
│ └── README_pt_BR.md
├── manifest.yaml
├── main.py
└── ...
```
## Recommended Structure
Keep READMEs concise, under \~500 words. The Marketplace detail page surfaces the README directly, so optimize it for someone evaluating whether to install:
```markdown theme={null}
# Plugin Name
One-sentence summary of what the plugin does.
## Features
- Key capability 1
- Key capability 2
- Key capability 3
## Setup
1. Where to get the credentials (link to the upstream service).
2. Where to paste them in Dify.
## Usage
A minimal example — for a tool, show the inputs and outputs. For a model
provider, show the model selector. Screenshots help.
## Privacy
Briefly describe what data the plugin sends to third parties. Link to your
PRIVACY.md.
```
Avoid putting a full API reference or development notes in the README; those belong in source comments or a separate docs site. The Marketplace audience is end users picking a plugin, not contributors reading your codebase.
## How the Marketplace Picks a Language
When a visitor opens your plugin's detail page, the Marketplace looks for a README matching their UI language. If a match exists in the `readme/` directory, it renders that file. Otherwise it falls back to the English `README.md`.
<Frame>
<img alt="Plugin Detail Page in English" />
</Frame>
<Note>
Language codes are matched exactly: `README_zh_Hans.md` serves Simplified Chinese only; Traditional Chinese users see the English fallback.
</Note>
# Persistent Storage
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv
Store data across plugin interactions with the built-in key-value storage
## Overview
Most plugin tools and endpoints operate in a stateless, single-round interaction model:
1. Receive a request
2. Process data
3. Return a response
4. End the interaction
However, many real-world applications require maintaining state across multiple interactions. This is where **persistent storage** becomes essential.
<Info>
Persistent storage lets plugins keep data within the same workspace across interactions, enabling stateful applications and memory features.
</Info>
Dify currently provides a key-value (KV) storage system for plugins; more flexible and powerful storage interfaces are planned based on developer needs.
## Access Storage
All storage operations are performed through the `storage` object available in your plugin's session:
```python theme={null}
# Access the storage interface
storage = self.session.storage
```
## Storage Operations
### Store Data
Store data with the `set` method:
```python theme={null}
def set(self, key: str, val: bytes) -> None:
"""
Store data in persistent storage
Parameters:
key: Unique identifier for your data
val: Binary data to store (bytes)
"""
pass
```
<Warning>
The value must be in `bytes` format. This provides flexibility to store various types of data, including files.
</Warning>
#### Example: Storing Different Data Types
```python theme={null}
# String data (must convert to bytes)
storage.set("user_name", "John Doe".encode('utf-8'))
# JSON data
import json
user_data = {"name": "John", "age": 30, "preferences": ["AI", "NLP"]}
storage.set("user_data", json.dumps(user_data).encode('utf-8'))
# File data
with open("image.jpg", "rb") as f:
image_data = f.read()
storage.set("profile_image", image_data)
```
### Retrieve Data
Retrieve stored data with the `get` method:
```python theme={null}
def get(self, key: str) -> bytes:
"""
Retrieve data from persistent storage
Parameters:
key: Unique identifier for your data
Returns:
The stored data as bytes, or None if key doesn't exist
"""
pass
```
#### Example: Retrieving and Converting Data
```python theme={null}
# Retrieving string data
name_bytes = storage.get("user_name")
if name_bytes:
name = name_bytes.decode('utf-8')
print(f"Retrieved name: {name}")
# Retrieving JSON data
import json
user_data_bytes = storage.get("user_data")
if user_data_bytes:
user_data = json.loads(user_data_bytes.decode('utf-8'))
print(f"User preferences: {user_data['preferences']}")
```
### Delete Data
Delete stored data with the `delete` method:
```python theme={null}
def delete(self, key: str) -> None:
"""
Delete data from persistent storage
Parameters:
key: Unique identifier for the data to delete
"""
pass
```
## Best Practices
<CardGroup>
<Card title="Use Descriptive Keys" icon="key">
Create a consistent naming scheme for your keys to avoid conflicts and make your code more maintainable.
</Card>
<Card title="Handle Missing Keys" icon="triangle-exclamation">
Always check if data exists before processing it, as the key might not be found.
</Card>
<Card title="Serialize Complex Data" icon="code">
Convert complex objects to JSON or other serialized formats before storing.
</Card>
<Card title="Implement Error Handling" icon="shield">
Wrap storage operations in try/except blocks to handle potential errors gracefully.
</Card>
</CardGroup>
## Common Use Cases
* **User preferences**: Store user settings and preferences between sessions.
* **Conversation history**: Maintain context from previous conversations.
* **API tokens**: Store authentication tokens securely.
* **Cached data**: Store frequently accessed data to reduce API calls.
* **File storage**: Store user-uploaded files or generated content.
# Manifest
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest
YAML schema for the plugin manifest that declares name, author, runtime, resources, permissions, and which tools/models/endpoints the plugin ships
The manifest is a YAML file that defines a plugin's basic information: name, author, included tools and models, and more. If the file is malformed, plugin parsing and packaging fails.
For the overall plugin architecture, see [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin) and the [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet).
## Code Example
Below is a simple manifest file; each field is explained in the Structure section that follows. For a real-world example, see the [Google tool plugin manifest](https://github.com/langgenius/dify-official-plugins/blob/main/tools/google/manifest.yaml).
```yaml theme={null}
version: 0.0.1
type: "plugin"
author: "Yeuoly"
name: "neko"
label:
en_US: "Neko"
created_at: "2024-07-12T08:03:44.658609186Z"
icon: "icon.svg"
resource:
memory: 1048576
permission:
tool:
enabled: true
model:
enabled: true
llm: true
endpoint:
enabled: true
app:
enabled: true
storage:
enabled: true
size: 1048576
plugins:
endpoints:
- "provider/neko.yaml"
meta:
version: 0.0.1
arch:
- "amd64"
- "arm64"
runner:
language: "python"
version: "3.12"
entrypoint: "main"
privacy: "./privacy.md"
```
## Structure
<ParamField type="version">
Plugin version.
</ParamField>
<ParamField type="string">
Plugin type. Currently only `plugin` is supported; `bundle` support is planned.
</ParamField>
<ParamField type="string">
Author, defined as the organization name in the Marketplace.
</ParamField>
<ParamField type="object">
Multilingual name.
</ParamField>
<ParamField type="RFC3339">
Creation time. The Marketplace requires this to be no later than the current time.
</ParamField>
<ParamField type="string">
Icon path.
</ParamField>
<ParamField type="object">
Resources the plugin requests.
<ParamField type="int64">
Maximum memory usage in bytes. Mainly relates to AWS Lambda resource allocation on Dify Cloud.
</ParamField>
<ParamField type="object">
Permissions the plugin requests.
<ParamField type="object">
Permission for reverse invocation of tools.
<ParamField type="boolean">
Whether to enable tool permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of models.
<ParamField type="boolean">
Whether to enable model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable large language model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable text embedding model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable rerank model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable text-to-speech model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable speech-to-text model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable content moderation model permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of nodes.
<ParamField type="boolean">
Whether to enable node permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission to register `endpoint`.
<ParamField type="boolean">
Whether to enable endpoint permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of `app`.
<ParamField type="boolean">
Whether to enable app permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission to apply for persistent storage.
<ParamField type="boolean">
Whether to enable storage permissions.
</ParamField>
<ParamField type="int64">
Maximum allowed persistent storage size, in bytes.
</ParamField>
</ParamField>
</ParamField>
</ParamField>
<ParamField type="object">
Lists the YAML files for the capabilities the plugin extends, as absolute paths within the plugin package. For example, to extend a model, define a file such as `openai.yaml` and list its path here. The file must exist at that path, or packaging fails.
<Warning>
The following combinations are not allowed:
* Extending both tools and models.
* Extending both models and Endpoints.
* Having no extensions at all.
Currently, each extension type supports only one provider.
</Warning>
<ParamField type="array[string]">
Plugin extension for [Tool](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Model](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Endpoints](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Agent Strategy](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) providers.
</ParamField>
</ParamField>
<ParamField type="object">
Metadata for the plugin.
<ParamField type="version">
Manifest format version. The initial version is `0.0.1`.
</ParamField>
<ParamField type="array[string]">
Supported architectures. Currently only `amd64` and `arm64` are supported.
</ParamField>
<ParamField type="object">
Runtime configuration.
<ParamField type="string">
Programming language. Currently only Python is supported.
</ParamField>
<ParamField type="string">
Language version. Currently only `3.12` is supported.
</ParamField>
<ParamField type="string">
Program entry point. For Python, this should be `main`.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="string">
Relative path or URL of the plugin's privacy policy, for example `"./privacy.md"` or `"https://your-web/privacy"`. **Required for listing on the Dify Marketplace**, where plugins must clearly state how they use user data. For details, see the [Plugin Privacy Data Protection Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
</ParamField>
# Plugin Logging
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/plugin-logging
Emit logs from your plugin with the SDK's plugin_logger_handler, visible during remote debugging and in daemon container logs
While developing or debugging a plugin, you often want to log what your code is doing.
The plugin SDK provides a handler for Python's standard `logging` library. Add it to your logger to write any string to both the standard output during remote debugging and the plugin daemon container logs (Community Edition only).
## Example
Import `plugin_logger_handler` and add it to your logger. The following example shows a tool plugin.
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
# Import logging and custom handler
import logging
from dify_plugin.config.logger_format import plugin_logger_handler
# Set up logging with the custom handler
logger = logging.getLogger(__name__)
logger.setLevel(logging.INFO)
logger.addHandler(plugin_logger_handler)
class LoggerDemoTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Log messages with different severity levels
logger.info("This is an INFO log message.")
logger.warning("This is a WARNING log message.")
logger.error("This is an ERROR log message.")
yield self.create_text_message("Hello, Dify!")
```
# Plugin Debugging
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin
Run your in-development plugin locally and attach it to a live Dify workspace for end-to-end testing, no packaging required
Remote debugging is the fastest way to iterate on a plugin. You run the plugin process on your laptop, and Dify treats it as if it were installed in the workspace. Save your edits and restart the process, and the changes take effect immediately.
## Prerequisites
* A Dify workspace where you can access **Plugins** in the top-right corner.
* A scaffolded plugin project (see [CLI](/en/develop-plugin/getting-started/cli) if you haven't created one yet).
* Python 3.12 and the plugin's dependencies installed (`pip install -r requirements.txt`).
## Step 1: Get the Debug URL and Key
Open the **Plugins** page in Dify and click the debug icon (the small bug icon next to **Install Plugin**). A dialog shows the **remote install host:port** and an **API key**.
<Frame>

</Frame>
<Tabs>
<Tab title="Dify Cloud">
The host is something like `debug-plugin.dify.dev:5003`. The key is unique to your workspace; anyone with the key can attach a plugin, so do not share it.
</Tab>
<Tab title="Self-hosted">
The host defaults to `127.0.0.1:5003` and is configured by `PLUGIN_REMOTE_INSTALLING_HOST` / `PLUGIN_REMOTE_INSTALLING_PORT` in the plugin daemon's environment. Make sure port `5003` is reachable from your dev machine. If Dify runs in Docker on the same host, use the daemon container's bridge IP (or expose the port).
</Tab>
</Tabs>
## Step 2: Configure the Plugin's `.env`
In your plugin project, copy `.env.example` to `.env` and fill in the values:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
<Note>
`REMOTE_INSTALL_URL` is the combined `host:port` from Step 1, not two separate variables.
</Note>
## Step 3: Run the Plugin
From the plugin project directory:
```bash theme={null}
pip install -r requirements.txt
python -m main
```
The process stays in the foreground and logs incoming invocations. Edit your code and restart the process to apply changes.
## Step 4: Verify the Install
Go back to the Dify **Plugins** page. The plugin appears in the list, labeled with a debug marker. Other members of the workspace can also see and use it.
<Frame>
</Frame>
<Check>
The plugin tile shows a debug indicator and your local terminal logs the first registration handshake. You're attached.
</Check>
Trigger the plugin as you would any other: call it from a workflow node, run it as a tool inside an Agent, or hit an endpoint URL. Invocations land on your local process and you can attach a debugger.
## Troubleshooting
<AccordionGroup>
<Accordion title="Connection refused / cannot reach host">
The daemon is not listening on the address you put in `REMOTE_INSTALL_URL`. On self-hosted setups, confirm the daemon container has `PLUGIN_REMOTE_INSTALLING_ENABLED=true` and that port `5003` is exposed. On cloud, double-check you copied the host:port exactly as shown in the debug dialog.
</Accordion>
<Accordion title="Plugin starts but never appears in the Plugins list">
The most common cause is a stale or wrong `REMOTE_INSTALL_KEY`. Regenerate the key from the debug dialog and rerun `python -m main`. Also confirm the daemon log shows the incoming registration.
</Accordion>
<Accordion title="`plugin_unique_identifier is not valid`">
The `author` field in `manifest.yaml` or in `provider/*.yaml` doesn't match a value the daemon accepts. Set it to your GitHub handle, then restart.
</Accordion>
<Accordion title="Changes don't take effect">
The plugin process needs to restart after every edit; there's no hot reload. Stop with `Ctrl+C` and rerun `python -m main`.
</Accordion>
</AccordionGroup>
## Related Resources
* [CLI](/en/develop-plugin/getting-started/cli)—Scaffold a plugin and set up `.env`
* [Plugin Logging](/en/develop-plugin/features-and-specs/plugin-types/plugin-logging)—Emit structured logs from inside your plugin
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file)—Ship the plugin once debugging is done
# Tool Return
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/tool
How tool plugins return messages (text, links, images, files, JSON), create standard and streaming variables, and define output schemas for workflow references
## Overview
A tool returns its results as messages and variables. This page covers the message interfaces, variable creation, and output schema definitions.
<CardGroup>
<Card title="Message Types" icon="comment-dots" href="#message-return">
Return different types of messages such as text, links, images, and JSON
</Card>
<Card title="Variables" icon="code-branch" href="#variables">
Create and manipulate variables for workflow integration
</Card>
<Card title="Output Schema" icon="diagram-project" href="#custom-output-variables">
Define custom output variables for workflow references
</Card>
</CardGroup>
## Data Structure
### Message Return
Dify supports several message types—text, links, images, file blobs, and JSON—each returned through a dedicated interface.
By default, a tool's output in a workflow includes three fixed variables: `files`, `text`, and `json`. The methods below populate these variables.
<Tip>
While you can use methods like `create_image_message` to return an image, tools also support custom output variables, which make it easier to reference specific data in a workflow.
</Tip>
### Message Types
<CodeGroup>
```python Image URL theme={null}
def create_image_message(self, image: str) -> ToolInvokeMessage:
"""
Return an image URL message
Dify will automatically download the image from the provided URL
and display it to the user.
Args:
image: URL to an image file
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Link theme={null}
def create_link_message(self, link: str) -> ToolInvokeMessage:
"""
Return a clickable link message
Args:
link: URL to be displayed as a clickable link
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Text theme={null}
def create_text_message(self, text: str) -> ToolInvokeMessage:
"""
Return a text message
Args:
text: Text content to be displayed
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python File theme={null}
def create_blob_message(self, blob: bytes, meta: dict = None) -> ToolInvokeMessage:
"""
Return a file blob message
For returning raw file data such as images, audio, video,
or documents (PPT, Word, Excel, etc.)
Args:
blob: Raw file data in bytes
meta: File metadata dictionary. Include 'mime_type' to specify
the file type, otherwise 'octet/stream' will be used
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python JSON theme={null}
def create_json_message(self, json: dict) -> ToolInvokeMessage:
"""
Return a formatted JSON message
Useful for data transmission between workflow nodes.
In agent mode, most LLMs can read and understand JSON data.
Args:
json: Python dictionary to be serialized as JSON
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
URL to an image that will be downloaded and displayed.
</ParamField>
<ParamField type="string">
URL to display as a clickable link.
</ParamField>
<ParamField type="string">
Text content to display.
</ParamField>
<ParamField type="bytes">
Raw file data in bytes.
</ParamField>
<ParamField type="dict">
File metadata, including:
* `mime_type`: The MIME type of the file, for example `image/png`.
* Other metadata relevant to the file.
</ParamField>
<ParamField type="dict">
Python dictionary to serialize as JSON.
</ParamField>
</Accordion>
<Tip>
When working with file blobs, always specify the `mime_type` in the `meta` dictionary to ensure proper handling of the file. For example: `{"mime_type": "image/png"}`.
</Tip>
### Variables
<CodeGroup>
```python Standard Variable theme={null}
from typing import Any
def create_variable_message(self, variable_name: str, variable_value: Any) -> ToolInvokeMessage:
"""
Create a named variable for workflow integration
For non-streaming output variables. If multiple instances with the
same name are created, the latest one overrides previous values.
Args:
variable_name: Name of the variable to create
variable_value: Value of the variable (any Python data type)
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Streaming Variable theme={null}
def create_stream_variable_message(
self, variable_name: str, variable_value: str
) -> ToolInvokeMessage:
"""
Create a streaming variable with typewriter effect
When referenced in an answer node in a Chatflow application,
the text will be output with a typewriter effect.
Args:
variable_name: Name of the variable to create
variable_value: String value to stream (only strings supported)
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Name of the variable to create or update.
</ParamField>
<ParamField type="Any/string">
Value to assign to the variable:
* Standard variables: any Python data type.
* Streaming variables: string data only.
</ParamField>
</Accordion>
<Warning>
`create_stream_variable_message` currently only supports string data. Complex data types cannot be streamed with the typewriter effect.
</Warning>
## Custom Output Variables
To reference a tool's output variables in a Workflow application, declare which variables the tool might output using [JSON Schema](https://json-schema.org/) in the tool's manifest.
### Define Output Schema
<CodeGroup>
```yaml Tool Manifest with Output Schema theme={null}
identity:
author: example_author
name: example_tool
label:
en_US: Example Tool
zh_Hans: 示例工具
ja_JP: ツール例
pt_BR: Ferramenta de exemplo
description:
human:
en_US: A simple tool that returns a name
zh_Hans: 返回名称的简单工具
ja_JP: 名前を返す簡単なツール
pt_BR: Uma ferramenta simples que retorna um nome
llm: A simple tool that returns a name variable
output_schema:
type: object
properties:
name:
type: string
description: "The name returned by the tool"
age:
type: integer
description: "The age returned by the tool"
profile:
type: object
properties:
interests:
type: array
items:
type: string
location:
type: string
```
</CodeGroup>
<Accordion title="Schema Structure">
<ParamField type="object">
Root object defining the tool's output schema.
</ParamField>
<ParamField type="string">
Must be `object` for tool output schemas.
</ParamField>
<ParamField type="object">
Dictionary of all possible output variables.
</ParamField>
<ParamField type="object">
Definition of each output variable, including its type and description.
</ParamField>
</Accordion>
<Warning>
Defining an output schema is not enough on its own: your implementation must still return each variable with `create_variable_message()`. Otherwise, the workflow receives `None` for that variable.
</Warning>
### Example Implementation
<CodeGroup>
```python Basic Variable Example theme={null}
def run(self, inputs):
# Process inputs and generate a name
generated_name = "Alice"
# Return the name as a variable that matches the output_schema
return self.create_variable_message("name", generated_name)
```
```python Complex Structure Example theme={null}
def run(self, inputs):
# Generate complex structured data
user_data = {
"name": "Bob",
"age": 30,
"profile": {
"interests": ["coding", "reading", "hiking"],
"location": "San Francisco"
}
}
# Return individual variables
self.create_variable_message("name", user_data["name"])
self.create_variable_message("age", user_data["age"])
self.create_variable_message("profile", user_data["profile"])
# Also return a text message for display
return self.create_text_message(f"User {user_data['name']} processed successfully")
```
</CodeGroup>
<Tip>
For complex workflows, you can define multiple output variables and return them all. This gives workflow designers more flexibility when using your tool.
</Tip>
## Examples
### Complete Tool Implementation
<CodeGroup>
```python Weather Forecast Tool theme={null}
import requests
from typing import Any
class WeatherForecastTool:
def run(self, inputs: dict) -> Any:
# Get location from inputs
location = inputs.get("location", "London")
try:
# Call weather API (example only)
weather_data = self._get_weather_data(location)
# Create variables for workflow use
self.create_variable_message("temperature", weather_data["temperature"])
self.create_variable_message("conditions", weather_data["conditions"])
self.create_variable_message("forecast", weather_data["forecast"])
# Create a JSON message for data transmission
self.create_json_message(weather_data)
# Create an image message for the weather map
self.create_image_message(weather_data["map_url"])
# Return a formatted text response
return self.create_text_message(
f"Weather in {location}: {weather_data['temperature']}°C, {weather_data['conditions']}. "
f"Forecast: {weather_data['forecast']}"
)
except Exception as e:
# Handle errors gracefully
return self.create_text_message(f"Error retrieving weather data: {str(e)}")
def _get_weather_data(self, location: str) -> dict:
# Mock implementation - in a real tool, this would call a weather API
return {
"location": location,
"temperature": 22,
"conditions": "Partly Cloudy",
"forecast": "Sunny with occasional showers tomorrow",
"map_url": "https://example.com/weather-map.png"
}
```
</CodeGroup>
<Tip>
When designing tools, consider both the direct output (what the user sees) and the variable output (what other workflow nodes can use). This separation provides flexibility in how your tool is used.
</Tip>
# Choose a Plugin Type
Source: https://docs.dify.ai/en/develop-plugin/getting-started/choose-plugin-type
A short decision guide for picking between Tool, Model, Agent Strategy, Extension, Datasource, and Trigger plugins
Dify supports several plugin types, each targeting a different extension point inside the platform. Pick the one that matches how your code will be invoked.
## Quick Decision
| You want to... | Build a... |
| :--------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------- |
| Add a callable action to Agents and Workflows (search, send email, transform data, etc.) | [Tool](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) |
| Make a new LLM, embedding, rerank, TTS, STT, or moderation model selectable inside Dify | [Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) |
| Implement a custom reasoning loop for Agents (ReAct, Function Calling variant, etc.) | [Agent Strategy](/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin) |
| Expose an HTTP endpoint that external services can call to drive a Dify workflow | [Extension (Endpoint)](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) |
| Ingest documents from an external system into a knowledge base | [Datasource](/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin) |
| Start a workflow when something happens upstream (a webhook fires, a file lands) | [Trigger](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin) |
## Common Questions
<AccordionGroup>
<Accordion title="Can one plugin combine multiple types?">
Yes. A Tool plugin can also expose endpoints. For example, a Discord bot plugin sends messages (tool) and receives webhooks (endpoint) in one package. Model plugins are stricter: they cannot bundle tools or endpoints.
</Accordion>
<Accordion title="Tool vs. Agent Strategy: what's the difference?">
A Tool is an individual capability the Agent decides to call (like "search the web"). An Agent Strategy is the *reasoning loop itself*: the policy that decides which tools to call, in what order, and when to stop. Build a tool unless you're replacing how Agents think.
</Accordion>
<Accordion title="Datasource vs. Trigger: both pull from external systems?">
Datasource brings documents into a knowledge base for retrieval. Trigger fires a workflow in real time on an upstream event. The same systems can power both, but the consumption pattern differs: indexing vs. event-driven execution.
</Accordion>
<Accordion title="Extension vs. Tool: when is a plain HTTP endpoint right?">
Extensions are for the other direction: an outside service calls *into* Dify. Tools are for Agents/Workflows calling *out* to a service. Build an Extension when your plugin is the entry point, not the action.
</Accordion>
</AccordionGroup>
## Next Steps
Once you've picked a type, set up the CLI and scaffold a project:
<CardGroup>
<Card title="Install the CLI" icon="rocket" href="/en/develop-plugin/getting-started/cli">
Get `dify` on your machine and run `dify plugin init`.
</Card>
<Card title="Read the manifest spec" icon="book" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Understand the YAML structure every plugin shares.
</Card>
</CardGroup>
# Dify Plugin CLI
Source: https://docs.dify.ai/en/develop-plugin/getting-started/cli
Install the Dify Plugin CLI, scaffold a new plugin project, and run it against a Dify instance for local development
The Dify Plugin CLI manages your plugin development workflow, from project initialization to packaging. This guide covers installing the CLI, scaffolding a plugin project, and running it against a Dify instance.
<Note>
This is the Dify Plugin CLI (the `dify` command) for building plugins. It is not the Dify CLI ([difyctl](/en/cli/overview)), which runs and manages Dify apps from the command line.
</Note>
## Prerequisites
Before you begin, make sure you have:
* Python 3.12
* Homebrew (macOS only, used to install the CLI)
## Install the CLI
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Download the latest binary from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases). Pick `dify-plugin-linux-amd64` for x86\_64 hosts or `dify-plugin-linux-arm64` for ARM hosts.
```bash theme={null}
chmod +x dify-plugin-linux-amd64
sudo mv dify-plugin-linux-amd64 /usr/local/bin/dify
```
</Tab>
<Tab title="Windows">
Download `dify-plugin-windows-amd64.exe` (or `dify-plugin-windows-arm64.exe`) from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases), rename it to `dify.exe`, and add its folder to your `PATH`.
</Tab>
</Tabs>
Verify the installation:
```bash theme={null}
dify version
```
## Create a Plugin Project
Create a new plugin project with:
```bash theme={null}
dify plugin init
```
Fill in the required fields when prompted:
```bash theme={null}
Edit profile of the plugin
Plugin name (press Enter to next step): hello-world
Author (press Enter to next step): langgenius
Description (press Enter to next step): hello world example
Repository URL (Optional) (press Enter to next step): Repository URL (Optional)
Enable multilingual README: [✔] English is required by default
Languages to generate:
English: [✔] (required)
→ 简体中文 (Simplified Chinese): [✔]
日本語 (Japanese): [✘]
Português (Portuguese - Brazil): [✘]
Controls:
↑/↓ Navigate • Space/Tab Toggle selection • Enter Next step
```
Choose `python` and press Enter to use the Python plugin template, then select the type of plugin you want to build:
```bash theme={null}
Select the type of plugin you want to create, and press `Enter` to continue
Before starting, here's some basic knowledge about Plugin types in Dify:
- Tool: Tool Providers like Google Search, Stable Diffusion, etc. Used to perform specific tasks.
- Model: Model Providers like OpenAI, Anthropic, etc. Use their models to enhance AI capabilities.
- Endpoint: Similar to Service API in Dify and Ingress in Kubernetes. Extend HTTP services as endpoints with custom logic.
- Trigger: Webhook-based providers that turn third-party platform events into workflow start signals.
- Agent Strategy: Implement your own agent strategies like Function Calling, ReAct, ToT, CoT, etc.
Based on the ability you want to extend, Plugins are divided into six types: Tool, Model, Extension, Agent Strategy, Datasource, and Trigger.
- Tool: A tool provider that can also implement endpoints. For example, building a Discord Bot requires both sending and receiving messages.
- Model: Strictly for model providers, no other extensions allowed.
- Extension: For simple HTTP services that extend functionality.
- Agent Strategy: Implement custom agent logic with a focused approach.
- Datasource: Provide datasource for Dify Knowledge Pipeline.
- Trigger: Build webhook integrations that emit events to kick off workflows.
We've provided templates to help you get started. Choose one of the options below:
-> tool
agent-strategy
llm
text-embedding
rerank
tts
speech2text
moderation
extension
datasource
trigger
```
When prompted for the minimal Dify version, leave it blank to use the latest version:
```bash theme={null}
Edit minimal Dify version requirement, leave it blank by default
Minimal Dify version (press Enter to next step):
```
The CLI creates a new directory named after your plugin and sets up the basic project structure. Move into it:
```bash theme={null}
cd hello-world
```
## Run the Plugin
From the `hello-world` directory, copy the example environment file:
```bash theme={null}
cp .env.example .env
```
Edit the `.env` file to set your plugin's environment variables, such as API keys or other configurations. To get the debugging credentials, log in to your Dify environment, click **Plugins** in the top-right corner, then click the debug icon. In the pop-up window, copy the **API Key** and **Host Address**.
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
<Note>
`REMOTE_INSTALL_URL` combines host and port in `host:port` form. The host and port are shown together in the **API Key** card on the Plugins page.
</Note>
Install the dependencies and run your plugin:
```bash theme={null}
pip install -r requirements.txt
python -m main
```
# Dify Plugin
Source: https://docs.dify.ai/en/develop-plugin/getting-started/getting-started-dify-plugin
Modular components that extend Dify AI applications with external services, custom logic, and specialized tools
Dify plugins are modular components that extend your Dify-built AI applications with external services, custom functions, and specialized tools.
<Frame>
<img alt="Marketplace" />
</Frame>
Through plugins, your AI applications can:
* Connect to external APIs
* Process different types of data
* Perform specialized calculations
* Execute real-world actions
## Start Here
<CardGroup>
<Card title="Choose a Plugin Type" icon="route" href="/en/develop-plugin/getting-started/choose-plugin-type">
A short decision guide for picking between Tool, Model, Agent Strategy, Extension, Datasource, and Trigger plugins.
</Card>
<Card title="Install the CLI" icon="rocket" href="/en/develop-plugin/getting-started/cli">
Set up `dify` on your machine and scaffold a new plugin project in minutes.
</Card>
</CardGroup>
## Types of Plugins
<AccordionGroup>
<Accordion title="Models" icon="microchip" href="/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider">
Package and manage AI models as plugins
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider">Learn more</a>
</Accordion>
<Accordion title="Tools" icon="toolbox" href="/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin">
Build specialized capabilities for Agents and workflows
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin">Learn more</a>
</Accordion>
<Accordion title="Agent Strategies" icon="brain" href="/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin">
Create custom reasoning strategies for autonomous Agents
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin">Learn more</a>
</Accordion>
<Accordion title="Extensions" icon="puzzle-piece" href="/en/develop-plugin/dev-guides-and-walkthroughs/endpoint">
Integrate with external services through HTTP webhooks
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/endpoint">Learn more</a>
</Accordion>
<Accordion title="Datasources" icon="database" href="/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin">
Feed external content into Dify's Knowledge Pipeline
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin">Learn more</a>
</Accordion>
<Accordion title="Triggers" icon="bolt" href="/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin">
Kick off workflows from third-party platform events received via webhooks
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin">Learn more</a>
</Accordion>
</AccordionGroup>
## Additional Resources
<CardGroup>
<Card title="Development & Debugging" icon="code" href="/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin">
Tools and techniques for efficient plugin development
</Card>
<Card title="Publishing & Marketplace" icon="shop" href="/en/develop-plugin/publishing/marketplace-listing/release-overview">
Package and share your plugins with the Dify community
</Card>
<Card title="API & SDK Reference" icon="book-open" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Technical specifications and documentation
</Card>
<Card title="Community & Contributions" icon="users" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
Communicate with other developers and contribute to the ecosystem
</Card>
</CardGroup>
# Frequently Asked Questions
Source: https://docs.dify.ai/en/develop-plugin/publishing/faq/faq
Common issues and fixes for building, packaging, debugging, and installing Dify plugins
## Package and Install
### Why does `dify plugin package` fail with `plugin_unique_identifier is not valid`?
The `author` field in `manifest.yaml` and any `provider/*.yaml` file must match your GitHub handle. Update it in every file, repackage with `dify plugin package`, and reinstall.
### Why am I seeing `plugin verification has been enabled, and the plugin you want to install has a bad signature`?
Self-hosted Dify enforces signature verification on plugin packages by default. You have two options:
1. **Recommended for production**: sign your package. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification).
2. **For development and trusted internal use**: disable verification. Add `FORCE_VERIFYING_SIGNATURE=false` to `docker/.env`, then restart:
```bash theme={null}
cd docker
docker compose down
docker compose up -d
```
This allows installing any unsigned plugin, including ones outside the Marketplace, so only do this in environments you control.
### Is there a maximum size for a `.difypkg` file?
Yes. The plugin daemon rejects packages over a configurable limit (default `50MB`). If you ship large model weights or static assets, host them externally and download on first use, or contact Dify support about raising the limit for marketplace plugins.
### My plugin needs Python 3.13. Can I change the runtime?
No. Plugins run inside a managed Python 3.12 environment. Pin your dependencies to versions compatible with 3.12. The daemon does not honor a different runtime version in `manifest.yaml`.
## Remote Debugging
### Why does my plugin start but never appear in the workspace?
Three things to check, in order: (1) the daemon log shows an incoming registration, (2) the `REMOTE_INSTALL_KEY` matches what's shown in the debug dialog, (3) `REMOTE_INSTALL_URL` uses the `host:port` format (not separate variables). See [Plugin Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) for the full troubleshooting list.
### Do my code changes hot-reload?
No. Stop the plugin process with `Ctrl+C` and rerun `python -m main` after every change.
## OAuth and Credentials
### What callback URL should I configure with the upstream OAuth provider?
Use `https://<your-dify-host>/console/api/oauth/plugin/<author>/<plugin-name>/tool/callback` for tool plugins, replacing `tool` with `datasource` or `trigger` for those plugin types. The exact pattern is shown in your plugin's OAuth setup card inside Dify.
### Why are my OAuth tokens not refreshing?
The plugin SDK refreshes tokens automatically when they expire, provided your provider implementation returns a valid `refresh_token` from the initial authorization. Confirm `OAuthCredentials.refresh_token` is populated, and that your `_oauth_refresh_credentials` method is implemented.
## Marketplace Publishing
### Why was my Marketplace PR rejected by the automated check?
The reviewer runs a 12-check pre-flight on every PR. The most common failures:
* **`author` in `manifest.yaml` contains `langgenius` or `dify`**: reserved for first-party plugins; use your own GitHub handle.
* **`dify_plugin` SDK pin is below `0.5.0`**: bump the pin in `requirements.txt`.
* **`README.md` contains Chinese characters**: move translations to `readme/README_zh_Hans.md` (see [Multilingual README](/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme)).
* **PR title or body contains Chinese**: only the bilingual notice line is allowlisted; everything else must be English.
* **Missing `PRIVACY.md` or `_assets/`**: both are required, and `PRIVACY.md` must be non-empty.
* **Version is already published**: bump `version` in `manifest.yaml` before re-submitting.
The full list of checks lives in [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace#reviewer-checklist).
### How long does the Marketplace review take?
PRs to `langgenius/dify-plugins` are typically reviewed within a few business days. PRs that haven't seen reviewer activity in 14–30 days are marked stale; respond on the PR to reset that timer.
### How do I publish an update for a plugin already on the Marketplace?
Bump `version` in `manifest.yaml`, open a new PR against `langgenius/dify-plugins` with the new package. The Marketplace shows the new version once merged. See [Auto-publish PR](/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr) for the GitHub Action that automates this.
### Can I monetize my plugin?
Not currently. The Marketplace only accepts free plugins. Future pricing policies will be announced separately.
## Storage and Limits
### Where do plugin logs go?
Self-hosted: container logs of the plugin daemon (`docker compose logs plugin_daemon`). Cloud: visible in the workspace's plugin debug panel during remote debugging only; persisted logs are not exposed in the UI. Use [Plugin Logging](/en/develop-plugin/features-and-specs/plugin-types/plugin-logging) for structured output.
### Is plugin storage scoped per workspace?
Yes. The KV storage API (`self.session.storage`) is isolated per workspace per plugin install. Two workspaces using the same plugin do not share keys. See [Persistent Storage (KV)](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv).
# Automatically Publish Plugins via PR
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr
Automate plugin packaging and Marketplace PR creation with a GitHub Actions workflow that runs on every push to main
## Background
Updating a plugin that others actively use is tedious by hand: modify the code, bump the version, push changes, create a branch, package the file, and open a PR—every release.
**Plugin Auto-PR** is a GitHub Actions workflow that automates the whole sequence. One push packages the plugin and opens the Marketplace PR, so you can focus on building.
## Concepts
### GitHub Actions
GitHub Actions automates development tasks in GitHub. When triggered (for example, by a code push), it runs your workflow in a cloud-based virtual machine, handling everything from build to deployment.
<Frame>

</Frame>
GitHub Actions usage limits:
* **Public repositories**: Unlimited.
* **Private repositories**: 2000 minutes per month.
### Plugin Auto-PR
The workflow runs these steps:
1. Triggers when you push code to the main branch of your plugin source repository.
2. Reads plugin information from the `manifest.yaml` file.
3. Packages the plugin as a `.difypkg` file.
4. Pushes the packaged file to your forked `dify-plugins` repository.
5. Creates a new branch and commits the changes.
6. Creates a PR to merge into the upstream repository.
## Prerequisites
### Repositories
* Your own plugin source code repository (e.g., `your-name/plugin-source`).
* Your own fork of the plugin repository (e.g., `your-name/dify-plugins`).
* The plugin directory structure already in place in your fork:
```text theme={null}
dify-plugins/
└── your-author-name
└── plugin-name
```
### Permissions
Create a GitHub Personal Access Token (PAT) that can push code to your forked repository and create PRs to the upstream repository.
## Parameters and Configuration
### Setup Requirements
Auto-publishing needs two things in place.
The `manifest.yaml` file drives the automation:
* **`name`**: Your plugin's name (affects package and branch names).
* **`version`**: Semantic version number (increment with each release).
* **`author`**: Your GitHub username (determines repository paths).
The `PLUGIN_ACTION` secret in your plugin source repository holds the credentials:
* **Value**: A Personal Access Token (PAT) with sufficient permissions.
* **Permissions**: Push branches to your forked repository and create PRs to the upstream repository.
### Automatically Generated Parameters
Once set up, the workflow derives these parameters for you:
* **GitHub username**: Read from the `author` field in `manifest.yaml`.
* **Author folder name**: Matches the `author` field.
* **Plugin name**: Read from the `name` field in `manifest.yaml`.
* **Branch name**: `bump-{plugin-name}-plugin-{version}`.
* **Package filename**: `{plugin-name}-{version}.difypkg`.
* **PR title and content**: Generated from the plugin name and version.
## Step-by-Step Guide
<Steps>
<Step title="Prepare Repositories">
Ensure you have forked the official `dify-plugins` repository and have your own plugin source repository.
</Step>
<Step title="Configure Secret">
In your plugin source repository, go to **Settings** > **Secrets and variables** > **Actions** > **New repository secret** and create a secret:
* **Name**: `PLUGIN_ACTION`
* **Value**: A GitHub Personal Access Token (PAT) with write permissions to the target repository (`your-name/dify-plugins`)
<Frame>

</Frame>
</Step>
<Step title="Create Workflow File">
Create a `.github/workflows/` directory in your repository, add a file named `plugin-publish.yml`, and paste in the workflow below.
At a high level, the workflow runs on every push to `main`, downloads the Dify Plugin CLI, packages the plugin from the manifest, checks out your `dify-plugins` fork, and opens a PR against `langgenius/dify-plugins` with the new `.difypkg`.
<Accordion title="Complete workflow YAML">
```yaml theme={null}
# .github/workflows/plugin-publish.yml
name: Auto Create PR on Main Push
on:
push:
branches: [ main ] # Trigger on push to main
workflow_dispatch: # Allow manual runs from the Actions tab
jobs:
create_pr: # Renamed job for clarity
runs-on: ubuntu-latest
steps:
- name: Checkout code
uses: actions/checkout@v3
- name: Print working directory # Kept for debugging
run: |
pwd
ls -la
- name: Download CLI tool
run: |
# Create bin directory in runner temp
mkdir -p $RUNNER_TEMP/bin
cd $RUNNER_TEMP/bin
# Download CLI tool
wget https://github.com/langgenius/dify-plugin-daemon/releases/latest/download/dify-plugin-linux-amd64
chmod +x dify-plugin-linux-amd64
# Show download location and file
echo "CLI tool location:"
pwd
ls -la dify-plugin-linux-amd64
- name: Get basic info from manifest # Changed step name and content
id: get_basic_info
run: |
PLUGIN_NAME=$(grep "^name:" manifest.yaml | cut -d' ' -f2)
echo "Plugin name: $PLUGIN_NAME"
echo "plugin_name=$PLUGIN_NAME" >> $GITHUB_OUTPUT
VERSION=$(grep "^version:" manifest.yaml | cut -d' ' -f2)
echo "Plugin version: $VERSION"
echo "version=$VERSION" >> $GITHUB_OUTPUT
# If the author's name is not your github username, you can change the author here
AUTHOR=$(grep "^author:" manifest.yaml | cut -d' ' -f2)
echo "Plugin author: $AUTHOR"
echo "author=$AUTHOR" >> $GITHUB_OUTPUT
- name: Package Plugin
id: package
run: |
# Use the downloaded CLI tool to package
cd $GITHUB_WORKSPACE
# Use variables for package name
PACKAGE_NAME="${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}.difypkg"
# Use CLI from runner temp
$RUNNER_TEMP/bin/dify-plugin-linux-amd64 plugin package . -o "$PACKAGE_NAME"
# Show packaging result
echo "Package result:"
ls -la "$PACKAGE_NAME"
echo "package_name=$PACKAGE_NAME" >> $GITHUB_OUTPUT
# Show full file path and directory structure (kept for debugging)
echo "\\nFull file path:"
pwd
echo "\\nDirectory structure:"
tree || ls -R
- name: Checkout target repo
uses: actions/checkout@v3
with:
# Use author variable for repository
repository: ${{steps.get_basic_info.outputs.author}}/dify-plugins
path: dify-plugins
token: ${{ secrets.PLUGIN_ACTION }}
fetch-depth: 1 # Fetch only the last commit to speed up checkout
persist-credentials: true # Persist credentials for subsequent git operations
- name: Prepare and create PR
run: |
# Debug info (kept)
echo "Debug: Current directory $(pwd)"
# Use variable for package name
PACKAGE_NAME="${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}.difypkg"
echo "Debug: Package name: $PACKAGE_NAME"
ls -la
# Move the packaged file to the target directory using variables
mkdir -p dify-plugins/${{ steps.get_basic_info.outputs.author }}/${{ steps.get_basic_info.outputs.plugin_name }}
mv "$PACKAGE_NAME" dify-plugins/${{ steps.get_basic_info.outputs.author }}/${{ steps.get_basic_info.outputs.plugin_name }}/
# Enter the target repository directory
cd dify-plugins
# Configure git
git config user.name "GitHub Actions"
git config user.email "actions@github.com"
# Ensure we are on the latest main branch
git fetch origin main
git checkout main
git pull origin main
# Create and switch to a new branch using variables and new naming convention
BRANCH_NAME="bump-${{ steps.get_basic_info.outputs.plugin_name }}-plugin-${{ steps.get_basic_info.outputs.version }}"
git checkout -b "$BRANCH_NAME"
# Add and commit changes (using git add .)
git add .
git status # for debugging
# Use variables in commit message
git commit -m "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin to version ${{ steps.get_basic_info.outputs.version }}"
# Push to remote (use force just in case the branch existed before from a failed run)
git push -u origin "$BRANCH_NAME" --force
# Confirm branch has been pushed and wait for sync (GitHub API might need a moment)
git branch -a
echo "Waiting for branch to sync..."
sleep 10 # Wait 10 seconds for branch sync
- name: Create PR via GitHub API
env:
GH_TOKEN: ${{ secrets.PLUGIN_ACTION }} # Use the provided token for authentication
run: |
gh pr create \
--repo langgenius/dify-plugins \
--head "${{ steps.get_basic_info.outputs.author }}:${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}" \
--base main \
--title "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin to version ${{ steps.get_basic_info.outputs.version }}" \
--body "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin package to version ${{ steps.get_basic_info.outputs.version }}
Changes:
- Updated plugin package file" || echo "PR already exists or creation skipped." # Handle cases where PR already exists
- name: Print environment info # Kept for debugging
run: |
echo "GITHUB_WORKSPACE: $GITHUB_WORKSPACE"
echo "Current directory contents:"
ls -R
```
</Accordion>
</Step>
<Step title="Update manifest.yaml">
Make sure these fields are set correctly:
```yaml theme={null}
version: 0.0.x # Version number
author: your-github-username # GitHub username/Author name
name: your-plugin-name # Plugin name
```
</Step>
</Steps>
## Usage Guide
### First-Time Setup
Before the first automated release, confirm that:
1. You have forked the official `dify-plugins` repository.
2. Your plugin source repository structure is correct.
3. The `PLUGIN_ACTION` secret is set in your plugin source repository.
4. The workflow file `.github/workflows/plugin-publish.yml` exists.
5. The `name` and `author` fields in `manifest.yaml` are configured correctly.
### Subsequent Updates
To publish new versions after setup:
1. Modify the code.
2. Update the `version` field in `manifest.yaml`.
<Frame>

</Frame>
3. Push all changes to the main branch.
4. Wait for GitHub Actions to complete packaging, branch creation, and PR submission.
## Outcome
When you push code to the main branch of your plugin source repository, GitHub Actions runs the publishing process automatically:
* Packages the plugin in `{plugin-name}-{version}.difypkg` format.
* Pushes the packaged file to the target repository.
* Creates a PR to merge into the fork repository.
<Frame>

</Frame>
## Example Repository
See the [example repository](https://github.com/Yevanchen/exa-in-dify) for a working configuration and best practices.
# Package as Local File and Share
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-by-file
Package a Dify plugin into a `.difypkg` file you can install directly or hand off to others, with no marketplace or GitHub release required
A `.difypkg` is the portable form of a Dify plugin. Once you have one, anyone can install it through the Plugins page by uploading the file. This is the right path for **private plugins**, **internal testing**, or **out-of-band distribution** to a small group.
For wider distribution, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Prerequisites
* The [Dify Plugin CLI](/en/develop-plugin/getting-started/cli) installed. Run `dify version` to confirm.
* A completed plugin project. If you haven't built one yet, start with the [Tool Plugin walkthrough](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
* The plugin tested with [remote debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) before packaging.
<Note>
The `author` field in `manifest.yaml` and every `provider/*.yaml` must match your GitHub handle. Mismatches cause `plugin_unique_identifier is not valid` at install time. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the full manifest spec.
</Note>
## Package the Plugin
<Steps>
<Step title="Move above the project">
Navigate to the directory **above** your plugin project (so the project is a subdirectory of the current working directory).
</Step>
<Step title="Run the packager">
```bash theme={null}
dify plugin package ./your_plugin_project
```
The CLI produces a `your_plugin_project.difypkg` file in the current directory.
</Step>
</Steps>
<Frame>

</Frame>
## Install from the File
<Steps>
<Step title="Open the Plugins page">
In Dify, click the **Plugins** icon in the top-right corner.
</Step>
<Step title="Choose Install Plugin > Via Local File">
Or drag the `.difypkg` onto the empty area of the Plugins page.
</Step>
<Step title="Confirm the install">
Review the permissions the plugin requests, then click **Install**.
</Step>
</Steps>
<Frame>
</Frame>
<Check>
The plugin is now in the workspace and ready to use in Agents, Workflows, or Tools. No further action required.
</Check>
<Warning>
Self-hosted Dify enforces signature verification by default. Unsigned `.difypkg` files installed via Local File will be rejected unless you sign them or change the verification setting. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification).
</Warning>
## Share the File
Hand the `.difypkg` file to your users directly: over email, an internal file share, or any channel you control. They install it with the same flow above.
If you want broader distribution instead, consider:
<CardGroup>
<Card title="Publish on GitHub" icon="github" href="/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo">
Attach the `.difypkg` to a GitHub release; users install via repo URL.
</Card>
<Card title="Submit to Marketplace" icon="store" href="/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace">
Open a PR against `langgenius/dify-plugins` for the official catalog.
</Card>
</CardGroup>
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Dify Plugin CLI](/en/develop-plugin/getting-started/cli)
* [Remote Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin)
* [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification)
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
# Publish Plugins
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-overview
Three ways to distribute a Dify plugin (Marketplace, GitHub repository, or local file) and how to pick the right one
Dify supports three ways to distribute a plugin. They differ in how much vetting happens up front and how broad an audience the plugin reaches.
Before publishing, finish development and testing, and read the [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct).
## Choose a Method
<CardGroup>
<Card title="Marketplace" icon="store" href="/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace">
Official catalog. Reviewed, trusted, one-click install for every Dify user.
</Card>
<Card title="GitHub Repository" icon="github" href="/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo">
Self-hosted on GitHub. No review; users install via repo URL.
</Card>
<Card title="Local File" icon="file-zipper" href="/en/develop-plugin/publishing/marketplace-listing/release-by-file">
A `.difypkg` file you hand off directly. Right for private or internal plugins.
</Card>
</CardGroup>
## Compare
| | <Icon icon="store" /> Marketplace | <Icon icon="github" /> GitHub | <Icon icon="file-zipper" /> Local File |
| :--------------- | :----------------------------------------------- | :------------------------------------------------- | :----------------------------------------------------- |
| **Audience** | Every Dify user | Anyone with the repo URL | People you give the file to |
| **Review** | Yes: 12 automated checks + human review | None | None |
| **Install path** | One click from Marketplace UI | Install from GitHub dialog | Upload via Plugins page |
| **Versioning** | New PR per version, automated workflow available | GitHub releases with `.difypkg` asset | Repackage and redistribute |
| **Best for** | Polished, broadly useful plugins | Open-source projects, internal tools shared by URL | Private plugins, internal testing, ad-hoc distribution |
<Tip>
Many developers ship to **GitHub first** for fast iteration, then submit to the **Marketplace** once the plugin is stable. The same `.difypkg` works for all three methods; only the distribution channel differs.
</Tip>
## Quick Rules of Thumb
* **Want broad reach and review?** Use the **Marketplace**.
* **Want full control over releases and versioning?** Use **GitHub**.
* **Private or one-off use?** Use a **Local File**.
## Related Resources
<CardGroup>
<Card title="Plugin Development Guidelines" icon="clipboard-check" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
Quality bar for Marketplace submissions.
</Card>
<Card title="Privacy Guidelines" icon="shield-halved" href="/en/develop-plugin/publishing/standards/privacy-protection-guidelines">
`PRIVACY.md` and data-disclosure requirements.
</Card>
<Card title="General Specifications" icon="file-code" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Manifest fields every plugin must set.
</Card>
<Card title="Getting Started" icon="rocket" href="/en/develop-plugin/getting-started/getting-started-dify-plugin">
New to plugins? Start here.
</Card>
</CardGroup>
# Publish to Dify Marketplace
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace
Submit a plugin to the Dify Marketplace, from the pre-submission checklist and the 12 reviewer checks through the PR flow and what happens after approval
The Marketplace is the official catalog of community-built and partner-built Dify plugins. Submitting your plugin here puts it one click away from every Dify user.
Plugins are published by opening a Pull Request against [`langgenius/dify-plugins`](https://github.com/langgenius/dify-plugins). A reviewer (and a set of automated checks) walks through the PR, and on approval the plugin goes live on [marketplace.dify.ai](https://marketplace.dify.ai/) automatically.
If you have not built a plugin yet, start with the [Tool Plugin walkthrough](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
## Before You Submit
The Dify reviewer runs an automated 12-check pre-flight on every PR. Most rejections are mechanical, and fixing them up front saves a review cycle.
<Tabs>
<Tab title="Project files">
Every plugin directory must contain:
| File / Folder | Purpose |
| :-------------- | :-------------------------------------------- |
| `manifest.yaml` | Plugin metadata (name, author, version, etc.) |
| `README.md` | English-only description, setup, usage |
| `PRIVACY.md` | Privacy policy (required, non-empty) |
| `_assets/` | Plugin icon and any other static assets |
See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for manifest fields and [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines) for the privacy policy.
</Tab>
<Tab title="Manifest rules">
* **Author** in `manifest.yaml` must not contain `langgenius` or `dify`; those are reserved for first-party plugins. Use your own GitHub handle.
* **Version** must be a new value. Submitting an already-published version is rejected.
* **Icon** must be an actual icon in `_assets/`, not a leftover template default.
</Tab>
<Tab title="Dependencies">
* `pip install -r requirements.txt` must succeed cleanly.
* The plugin SDK pin must be at least `dify_plugin>=0.5.0`.
* The plugin must install and package without errors against the current daemon (the reviewer runs `test-plugin-install.py` and `upload-package.py --test`).
</Tab>
<Tab title="Language">
* **PR title and body** must be in English. The bilingual notice line `【中文用户 & Non English User】请使用英语提交,否则会被关闭 :)` is the only allowlisted exception.
* **`README.md`** must contain no Chinese characters. Add translations as `readme/README_<lang>.md` instead. See [Multilingual README](/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme).
</Tab>
</Tabs>
## Reviewer Checklist
These are the exact checks the reviewer runs, in order. Treat this as your pre-flight before opening the PR.
| # | Check | Common cause of failure |
| :- | :----------------------- | :------------------------------------------------------------------------- |
| 1 | **Single `.difypkg`** | PR includes more than one packaged file, or none |
| 2 | **PR language** | CJK characters in title or body outside the allowlisted notice |
| 3 | **Project structure** | Missing `manifest.yaml`, `README.md`, `PRIVACY.md`, or `_assets/` |
| 4 | **Manifest author** | Author contains `langgenius` or `dify` |
| 5 | **Icon** | Default template icon left in place, or icon missing |
| 6 | **Version** | This version is already on the Marketplace |
| 7 | **README language** | Chinese characters in `README.md` (use `readme/README_zh_Hans.md` instead) |
| 8 | **PRIVACY.md** | Missing or empty |
| 9 | **Dependencies install** | `pip install -r requirements.txt` errors |
| 10 | **SDK version** | `dify_plugin` pinned below `0.5.0` |
| 11 | **Install test** | Plugin fails to install via the daemon |
| 12 | **Packaging test** | Plugin fails to repackage cleanly |
A failing check stops the review and posts a status table with `❌ Fail` rows and required fixes; you address them and push again.
## Submit the PR
<Steps>
<Step title="Read the Plugin Development Guidelines">
Skim the [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct). Reviewers use them to judge non-mechanical concerns: uniqueness, brand alignment, content quality, IP, and maintenance commitment.
</Step>
<Step title="Write your privacy policy">
Create `PRIVACY.md` in the plugin root (or host it and put the URL in the manifest). Follow [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines): declare what data the plugin and any third-party services it calls collect.
</Step>
<Step title="Package the plugin">
From the directory above your plugin project:
```bash theme={null}
dify plugin package ./your_plugin_project
```
This produces `your_plugin_project.difypkg`.
</Step>
<Step title="Fork and add your file">
Fork [`langgenius/dify-plugins`](https://github.com/langgenius/dify-plugins). Create a folder at `<your-author-name>/<your-plugin-name>/` and drop the `.difypkg` inside.
</Step>
<Step title="Open the PR">
Push to your fork, then open a PR against `main` using the repository's PR template. Title and body in English.
</Step>
<Step title="Respond to the review">
The automated checks post first, then a human reviewer follows up. Address feedback by pushing new commits; the checks rerun on each push.
</Step>
</Steps>
```mermaid theme={null}
flowchart LR
A[Build & test plugin] --> B[Package .difypkg]
B --> C[Fork langgenius/dify-plugins]
C --> D[Add file to author/plugin/]
D --> E[Open PR]
E --> F{Automated checks<br/>12 rules}
F -->|❌ Fail| G[Push fixes]
G --> F
F -->|✅ Pass| H[Human review]
H -->|Changes requested| G
H -->|Approve & merge| I[Live on Marketplace]
```
<Tip>
The first review usually lands within a week. If it takes longer, the reviewer leaves a comment explaining the delay.
</Tip>
<Check>
Once merged to `main`, the plugin appears on [marketplace.dify.ai](https://marketplace.dify.ai/) automatically, with no separate publishing step.
</Check>
## After Approval
You own the plugin from the merge onward:
* **Bug fixes and feature requests.** Triage issues from your users.
* **Compatibility updates.** When Dify ships a breaking API change, the team publishes migration notes; you update the plugin. Dify engineers can help if needed.
* **Versioning.** Bump `version` in `manifest.yaml`, repackage, open a new PR with the new `.difypkg`. The [Auto-publish PR workflow](/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr) automates this from a GitHub Action.
<Warning>
While the Marketplace is in public beta, avoid breaking changes to plugins already in use. Add new fields instead of renaming existing ones; deprecate before removing.
</Warning>
## PR Lifecycle
| Status | What it means | What to do |
| :------------------------ | :-------------------------------------------- | :----------------------------------------------------- |
| **Open, awaiting review** | Within the first \~7 days, no action needed | Wait |
| **Changes requested** | A check failed, or the reviewer left feedback | Push fixes; checks rerun automatically |
| **Stale (14 days idle)** | No response from you in two weeks | Reply on the PR to reset the timer; it can be reopened |
| **Closed (30 days idle)** | Closed for inactivity | Open a fresh PR; the closed one can't be reopened |
## Frequently Asked Questions
<AccordionGroup>
<Accordion title="How do I know if my plugin is too similar to an existing one?">
The Marketplace deduplicates by *function*, not by *integration*. A second Google-search plugin that only adds new translations is a duplicate. A Google-search plugin that adds batched queries, better error handling, or a meaningful new capability is fine; say so in the PR description.
</Accordion>
<Accordion title="My PR was marked stale or closed. What now?">
**Stale** PRs (14 days idle) can be reopened; reply on the PR or push a fix to restart the clock. **Closed** PRs (30 days idle) cannot be reopened; fix the feedback and open a fresh PR with the same package.
</Accordion>
<Accordion title="Can I update plugins during the public beta?">
Yes. Avoid breaking changes: add fields rather than rename, deprecate before removing.
</Accordion>
<Accordion title="Can I publish a paid plugin?">
Not currently. The Marketplace accepts free plugins only; monetization policies will be announced separately.
</Accordion>
<Accordion title="The PR body needs both English and Chinese for our team. Is that allowed?">
No. Only the single allowlisted bilingual notice line is permitted in the PR title/body. Put internal multilingual notes elsewhere (commit messages, internal docs).
</Accordion>
</AccordionGroup>
## Related Resources
<CardGroup>
<Card title="Publishing Overview" icon="signs-post" href="/en/develop-plugin/publishing/marketplace-listing/release-overview">
Compare Marketplace, GitHub, and local-file distribution.
</Card>
<Card title="Plugin Development Guidelines" icon="clipboard-check" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
The full content and quality bar reviewers apply.
</Card>
<Card title="Privacy Guidelines" icon="shield-halved" href="/en/develop-plugin/publishing/standards/privacy-protection-guidelines">
How to write a `PRIVACY.md` that passes review.
</Card>
<Card title="Auto-publish PR Workflow" icon="robot" href="/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr">
GitHub Action that packages and opens the PR for you on every push.
</Card>
<Card title="Multilingual README" icon="language" href="/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme">
Add `readme/README_<lang>.md` files for non-English users.
</Card>
<Card title="General Specifications" icon="file-code" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Manifest field reference.
</Card>
</CardGroup>
# Publish to Individual GitHub Repository
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo
Distribute a Dify plugin from your own GitHub repository so users can install it directly via repo URL, with no marketplace review required
Publishing through a personal GitHub repository lets you ship a plugin without going through Dify Marketplace review. Users install the plugin by entering your repo URL and selecting a release that contains a `.difypkg` asset.
This method fits when:
* You want full control over versioning and the release cadence.
* The plugin is open source and you want others to read, fork, or contribute to it.
* The plugin is for internal use within a team or org, but you still want one canonical install URL.
* Your plugin is awaiting marketplace review and you need an interim distribution channel.
For a comparison with other publishing methods, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Prerequisites
* A packaged plugin (`.difypkg` file). If you don't have one yet, see [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file).
* A GitHub account.
* A Dify workspace where you (or your users) have permission to install plugins.
## Step 1: Create a GitHub Repository
<Steps>
<Step title="Create the repository">
On GitHub, create a new public repository. The name typically matches your plugin name (for example, `dify-plugin-flomo`).
</Step>
<Step title="Push your plugin source">
Initialize git in your plugin project and push the source code:
```bash theme={null}
cd your_plugin_project
git init
git add .
git commit -m "initial commit"
git branch -M main
git remote add origin https://github.com/<your-handle>/<repo-name>.git
git push -u origin main
```
</Step>
<Step title="Confirm the manifest">
The `author` field in `manifest.yaml` and in any `provider/*.yaml` must match your GitHub handle. Mismatches cause `plugin_unique_identifier is not valid` when users try to install. See the [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for manifest details.
</Step>
</Steps>
## Step 2: Build the Plugin Package
From the directory **above** your plugin project, run:
```bash theme={null}
dify plugin package ./your_plugin_project
```
This produces `your_plugin_project.difypkg` in the current directory.
## Step 3: Publish a GitHub Release
GitHub releases are how Dify discovers installable versions of your plugin.
<Steps>
<Step title="Tag a release">
On your repository page, click **Releases** > **Draft a new release**. Create a new tag using semantic versioning (for example, `v0.0.1`). The tag should match the `version` field in your `manifest.yaml`.
</Step>
<Step title="Attach the .difypkg file">
In the release form, drag the `.difypkg` file into the **Assets** area. Dify reads this asset when users install from your repo.
</Step>
<Step title="Publish">
Add release notes describing what changed, then click **Publish release**.
</Step>
</Steps>
<Tip>
Repeat Steps 2 and 3 for each new version. Bump the `version` in `manifest.yaml` first, repackage, then create a new tag and release.
</Tip>
## Step 4: Install from Your Repository
Share your repository URL with users. They install it in Dify as follows:
<Steps>
<Step title="Open the Plugins page">
In Dify, go to **Plugins** in the top-right corner.
</Step>
<Step title="Install from GitHub">
Click **Install Plugin** > **From GitHub**.
</Step>
<Step title="Enter repository details">
Paste the repository URL (for example, `https://github.com/<your-handle>/<repo-name>`), then select the version from the dropdown. Dify pulls the matching `.difypkg` asset from that release.
</Step>
<Step title="Confirm installation">
Review the permissions the plugin requests, then click **Install**.
</Step>
</Steps>
<Check>
The plugin appears on the user's Plugins page within seconds of clicking **Install**. Dify pulls the `.difypkg` from your GitHub release on demand.
</Check>
## Troubleshooting
* **`plugin_unique_identifier is not valid`**: The `author` field in `manifest.yaml` (and `provider/*.yaml`) doesn't match the GitHub handle that owns the repo. Update it, repackage, and re-release.
* **No versions appear in the install dialog**: The release has no `.difypkg` asset attached, or the repo has no releases yet. Open the release on GitHub and confirm the asset is listed under **Assets**.
* **Signature verification error**: Self-hosted Dify instances may have signature verification enabled. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification) to sign your release, or see the [FAQ](/en/develop-plugin/publishing/faq/faq) for the bypass option.
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview): Compare publishing methods.
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file): Build a `.difypkg` package.
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace): Submit through the official marketplace.
* [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification): Sign packages for verified installs.
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Manifest field reference.
# Plugin Development Guidelines
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct
Requirements every Dify Marketplace plugin must meet to pass review, covering quality, language, privacy, IP, maintenance, and prohibited content
By submitting a plugin to the Dify Marketplace, you agree to follow the requirements on this page. Meeting them up front gets your plugin through review faster and helps keep the Marketplace useful and trustworthy.
## Value and uniqueness
* **Generative AI focus.** The plugin's core capability should integrate models, tools, or services that meaningfully extend AI applications on Dify.
* **No functional duplicates.** Don't reskin an existing Marketplace plugin. Each plugin should be unique and stand on its own.
* **Meaningful updates.** New versions must add real capability, not just metadata bumps.
* **Explain new submissions.** In your PR description, say briefly why the plugin is needed and what gap it fills.
## Plugin checklist
Before opening the publish PR, confirm each item:
* **Unique name.** Search the Marketplace first.
* **Brand alignment.** The plugin name reflects what it actually is.
* **Works end-to-end.** Tested via [remote debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin); production-ready.
* **README in English** with setup steps, required credentials, and usage. No exaggerated claims, ads, self-promotion, offensive content, real user data in screenshots, or dead links.
* **Clear error messages** for required fields and failure modes.
* **Authentication steps documented in full**, with no skipped steps.
* **Privacy policy ready.** See [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
* **Credentials handled securely**, never hardcoded, never exposed.
* **Performance acceptable.** Does not noticeably degrade Dify itself.
## Language
English is the primary language for every user-facing string: plugin name, description, field labels, help text, error messages. Additional translations are welcome on top of English.
## Prohibited and restricted plugins
| Category | Reason |
| ------------------------------------------------ | -------------------------------------------------------------- |
| **Prohibited**: misleading or malicious behavior | spam, phishing, credential theft, deceiving the review process |
| **Prohibited**: offensive content | violence, hate speech, discrimination |
| **Prohibited**: financial transactions | payments, asset transfers, token transfers |
| **Restricted**: frequent defects | repeated submissions with critical bugs |
| **Restricted**: unnecessary splitting | multiple plugins for the same API/auth; bundle them instead |
| **Restricted**: duplicate submissions | re-submitting essentially the same plugin |
Prohibited plugins are rejected. Restricted plugins may be delayed or asked to consolidate.
## Monetization
**The Dify Marketplace currently accepts free plugins only.** Pricing policies, if introduced, will be announced separately.
## Trademarks and intellectual property
* **You must have the rights** to any logo, trademark, or copyrighted material you include. We may ask for proof for recognizable third-party brands.
* **Do not use Dify's logos** in your plugin assets.
* **Image quality** must be sharp and well-cropped. No misleading or offensive icons.
Dify may ask for changes or remove a plugin if a rights holder complains or if unauthorized use is found.
## Updates and versioning
* **Announce breaking changes** in the plugin description or via GitHub Release Notes before users hit them.
* **Update regularly** for bug fixes, Dify platform changes, security patches, and upstream-service changes.
* **Deprecation notice.** If retiring a plugin, give users time to migrate and suggest alternatives where possible.
## Maintenance and support
You own technical support for your plugin. Provide **at least one** support channel (GitHub repository or email) and keep it active.
If a plugin is left unmaintained and the owner doesn't respond after a reasonable notification, Dify may tag it as `Maintenance Lacking` or `Potential Risk`, restrict new installs, and eventually unpublish it.
## Privacy and data
You **must** declare whether your plugin collects personal data and, if so, what types. The full guidelines are in [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
Your privacy policy must state:
* What data is collected
* How it is used
* What is shared with third parties (with links to their privacy policies)
Plugins that handle sensitive data (health, finance, children's information) get extra scrutiny. Collecting or transmitting user data without consent is grounds for removal.
## Review and discretion
* Dify may reject or remove plugins that don't meet these requirements or that abuse the review process.
* Reviews aim to land within a reasonable window; turnaround depends on submission volume and complexity.
* Reviewers communicate via the support channel you provide; keep it monitored.
## Related resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace)
* [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines)
* [Remote Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin)
# Privacy Guidelines
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/privacy-protection-guidelines
How to declare data collection and write the privacy policy required for every plugin submitted to the Dify Marketplace
Every plugin submitted to the Dify Marketplace must be transparent about how it handles user data. This page tells you what to declare and how to write the policy reviewers expect.
The whole submission boils down to one question: does your plugin collect or transmit any user personal data, either directly or through a third-party service it calls?
If yes, list the data types and link a privacy policy. If no, say so explicitly.
<Note>
"Personal data" means any information that identifies a specific individual on its own or when combined with other data: anything that could locate, contact, or target a unique person.
</Note>
## Identify the Data Your Plugin Handles
Walk through the three categories below. Anything you collect, store, log, or send to a third party must be declared.
### Direct Identifiers
* Full name, first name, last name
* Email address
* Phone number
* Home address or other physical address
* Government IDs (passport, driver's license, Social Security number, etc.)
### Indirect Identifiers
* Device identifiers (IMEI, MAC address, device ID)
* IP address
* Location data (GPS coordinates, city, region)
* Online identifiers (cookies, advertising IDs)
* Usernames, profile pictures
* Biometric data (fingerprints, facial recognition)
* Browsing history, purchase history
* Health or financial information
### Combinable Data
Data that becomes identifying when joined with other data:
* Age, gender
* Occupation
* Interests
### Third-Party Services Count Too
Your plugin is responsible for what the services it calls collect. If your plugin uses Slack, you must reference [Slack's privacy policy](https://slack.com/trust/privacy/privacy-policy) and disclose what Slack receives.
Before submitting, read the privacy policy of every third-party API the plugin touches and make sure your declaration covers it.
## Write the Privacy Policy
Your policy, either a `PRIVACY.md` in the plugin repository or a hosted URL, must cover:
* **What** is collected (from the categories above).
* **How** it is used.
* **Where** it goes, including any third parties and links to their policies.
If you're unsure where to start, look at the privacy policy of any plugin published by the Dify team for a working template.
## Declare It in the Manifest
The privacy URL goes in the plugin manifest. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the exact field.
## Common Questions
<AccordionGroup>
<Accordion title="What counts as 'collect and use' personal data?">
Any of: collecting, transmitting, storing, logging, sharing, or analyzing user data. Concrete examples:
* Forms that gather personally identifiable information
* Login or third-party-auth flows
* Capturing user input that may contain PII
* Analytics that track user behavior or usage patterns
* Storing messages, chat logs, or email addresses
* Accessing connected social-media profiles
* Collecting health or fitness data
* Storing search queries or browsing behavior
* Processing financial information (bank details, credit scores, transactions)
</Accordion>
<Accordion title="What if my plugin collects nothing?">
Say so explicitly in the privacy policy. Reviewers still expect a `PRIVACY.md` file or hosted URL; it just needs to state that no user data is collected, stored, or transmitted, including by any third-party services the plugin calls.
</Accordion>
<Accordion title="My plugin handles sensitive data: what changes?">
Plugins that touch health, finance, biometrics, or children's data get extra review. Be explicit about each data type, the legal basis for collecting it, retention period, and how users can request deletion.
</Accordion>
</AccordionGroup>
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct)
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace)
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
# Sign Plugins for Third-Party Signature Verification
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/third-party-signature-verification
Enable signed `.difypkg` installation in Dify Community Edition without disabling signature verification entirely (generate keys, sign packages, distribute the public key)
<Warning>
Third-party signature verification is a **Dify Community Edition** feature. Dify Cloud manages signatures centrally and does not expose these controls.
</Warning>
Self-hosted Dify enforces signature verification by default. Third-party signature verification lets administrators safely install plugins that are not on the Marketplace without disabling verification entirely.
Two scenarios:
<CardGroup>
<Card title="Admin signs an approved plugin" icon="user-shield">
The admin reviews a `.difypkg` from a trusted developer and signs it with their own key before installing.
</Card>
<Card title="Developer ships a signed plugin" icon="key">
The developer signs the `.difypkg` and publishes the matching public key. Admins who trust the developer add that public key to the verification list.
</Card>
</CardGroup>
The mechanics are the same in both cases: generate a key pair, sign with the private key, verify with the public key.
## Generate a Key Pair
```bash theme={null}
dify signature generate -f your_key_pair
```
Two files appear in the current directory:
| File | Use |
| :-------------------------- | :--------------------------------- |
| `your_key_pair.private.pem` | Sign plugins (keep secret) |
| `your_key_pair.public.pem` | Verify signatures (share publicly) |
<Warning>
Guard the private key. Anyone who has it can sign plugins that pass verification on installations trusting your public key.
</Warning>
## Sign and Verify a Plugin
<Steps>
<Step title="Sign the package">
```bash theme={null}
dify signature sign your_plugin_project.difypkg -p your_key_pair.private.pem
```
Produces `your_plugin_project.signed.difypkg` in the same directory.
</Step>
<Step title="Verify the signed package">
```bash theme={null}
dify signature verify your_plugin_project.signed.difypkg -p your_key_pair.public.pem
```
Confirms the signature matches before you distribute or install.
</Step>
</Steps>
<Info>
If you omit `-p`, `dify signature verify` checks against the Dify Marketplace public key. Any plugin not signed by Dify will fail verification in that mode.
</Info>
## Enable Verification on the Daemon
Admins install signed plugins by giving the plugin daemon a list of trusted public keys.
<Steps>
<Step title="Place the public key">
Put the `.public.pem` file somewhere the daemon container can reach it. For Docker Compose installs:
```bash theme={null}
mkdir -p docker/volumes/plugin_daemon/public_keys
cp your_key_pair.public.pem docker/volumes/plugin_daemon/public_keys/
```
</Step>
<Step title="Configure the daemon environment">
Set these variables on the `plugin_daemon` service:
| Variable | Value |
| :----------------------------------------------- | :-------------------------------------------------------- |
| `FORCE_VERIFYING_SIGNATURE` | `true` |
| `THIRD_PARTY_SIGNATURE_VERIFICATION_ENABLED` | `true` |
| `THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS` | Comma-separated paths to public keys inside the container |
A `docker-compose.override.yaml` snippet:
```yaml theme={null}
services:
plugin_daemon:
environment:
FORCE_VERIFYING_SIGNATURE: true
THIRD_PARTY_SIGNATURE_VERIFICATION_ENABLED: true
THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS: /app/storage/public_keys/your_key_pair.public.pem
```
<Note>
`docker/volumes/plugin_daemon` mounts to `/app/storage` inside the container, so the path in `THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS` must use the in-container path.
</Note>
</Step>
<Step title="Restart Dify">
```bash theme={null}
cd docker
docker compose down
docker compose up -d
```
Verified installs are now enforced: signed `.difypkg` files matching the configured public keys install cleanly; unsigned or mismatched ones are rejected.
</Step>
</Steps>
## Related Resources
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file)
* [Publish to Individual GitHub Repository](/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo)
* [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct)
* [Publishing FAQ](/en/develop-plugin/publishing/faq/faq)
# Local Source Code Start
Source: https://docs.dify.ai/en/self-host/deploy/advanced-deployments/local-source-code
## Prerequisites
### Setup Docker and Docker Compose
> Before installing Dify, make sure your machine meets the following minimum system requirements:
>
> * CPU >= 2 Core
> * RAM >= 4 GiB
| Operating System | Software | Explanation |
| -------------------------- | ---------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| macOS 10.14 or later | Docker Desktop | Set the Docker virtual machine (VM) to use a minimum of 2 virtual CPUs (vCPUs) and 8 GB of initial memory. Otherwise, the installation may fail. For more information, please refer to the [Docker Desktop installation guide for Mac](https://docs.docker.com/desktop/mac/install/). |
| Linux platforms | Docker 19.03 or later Docker Compose 1.25.1 or later | Please refer to the [Docker installation guide](https://docs.docker.com/engine/install/) and [the Docker Compose installation guide](https://docs.docker.com/compose/install/) for more information on how to install Docker and Docker Compose, respectively. |
| Windows with WSL 2 enabled | Docker Desktop | We recommend storing the source code and other data that is bound to Linux containers in the Linux file system rather than the Windows file system. For more information, please refer to the [Docker Desktop installation guide for using the WSL 2 backend on Windows.](https://docs.docker.com/desktop/windows/install/#wsl-2-backend) |
> If you need to use OpenAI TTS, `FFmpeg` must be installed on the system for it to function properly. For more details, refer to: [Link](https://docs.dify.ai/en/self-host/deploy/troubleshooting/integrations#text-to-speech-tts).
### Clone Dify Repository
Run the git command to clone the [Dify repository](https://github.com/langgenius/dify).
```bash theme={null}
git clone https://github.com/langgenius/dify.git
```
### Start Middlewares with Docker Compose
A series of middlewares for storage (e.g. PostgreSQL / Redis / Weaviate (if not locally available)) and extended capabilities (e.g. Dify's [sandbox](https://github.com/langgenius/dify-sandbox) and [plugin-daemon](https://github.com/langgenius/dify-plugin-daemon) services) are required by Dify backend services. Start the middlewares with Docker Compose by running these commands:
```bash theme={null}
cd docker
cp envs/middleware.env.example middleware.env
# Change DB_TYPE or COMPOSE_PROFILES in middleware.env if you are not using PostgreSQL and Weaviate.
docker compose --env-file middleware.env -f docker-compose.middleware.yaml -p dify up -d
```
***
## Setup Backend Services
The backend services include
1. API Service: serving API requests for Frontend service and API accessing
2. Worker Service: serving the aync tasks for datasets processing, workspaces, cleaning-ups etc.
### Start API Service
1. Navigate to the `api` directory:
```
cd api
```
2. Prepare the environment variable config file:
```
cp .env.example .env
```
<Note>
When the frontend and backend run on different subdomains, set `COOKIE_DOMAIN` to the site's top-level domain (e.g., `example.com`) in the `.env` file.
The frontend and backend must be under the same top-level domain to share authentication cookies.
</Note>
3. Generate a random secret key and replace the value of SECRET\_KEY in the `.env` file:
```
awk -v key="$(openssl rand -base64 42)" '/^SECRET_KEY=/ {sub(/=.*/, "=" key)} 1' .env > temp_env && mv temp_env .env
```
4. Install dependencies:
[uv](https://docs.astral.sh/uv/getting-started/installation/) is used to manage dependencies.
Install the required dependencies with `uv` by running:
```
uv sync --dev
```
> For macOS: install libmagic with `brew install libmagic`.
5. Perform the database migration:
Perform database migrations to the latest version:
```
uv run flask db upgrade
```
6. Start the API service:
```
uv run flask run --host 0.0.0.0 --port=5001 --debug
```
Expected output:
```
* Debug mode: on
INFO:werkzeug:WARNING: This is a development server. Do not use it in a production deployment. Use a production WSGI server instead.
* Running on all addresses (0.0.0.0)
* Running on http://127.0.0.1:5001
INFO:werkzeug:Press CTRL+C to quit
INFO:werkzeug: * Restarting with stat
WARNING:werkzeug: * Debugger is active!
INFO:werkzeug: * Debugger PIN: 695-801-919
```
### Start the Worker Service
To consume asynchronous tasks from the queue, such as dataset file import and dataset document updates, follow these steps to start the Worker service
* for macOS or Linux
```
uv run celery -A app.celery worker -P gevent -c 1 --loglevel INFO -Q dataset,dataset_summary,priority_dataset,priority_pipeline,pipeline,mail,ops_trace,app_deletion,plugin,workflow_storage,conversation,workflow,schedule_poller,schedule_executor,triggered_workflow_dispatcher,trigger_refresh_executor,retention,workflow_based_app_execution
```
If you are using a Windows system to start the Worker service, please use the following command instead:
* for Windows
```
uv run celery -A app.celery worker -P solo --without-gossip --without-mingle --loglevel INFO -Q dataset,dataset_summary,priority_dataset,priority_pipeline,pipeline,mail,ops_trace,app_deletion,plugin,workflow_storage,conversation,workflow,schedule_poller,schedule_executor,triggered_workflow_dispatcher,trigger_refresh_executor,retention,workflow_based_app_execution
```
Expected output:
```
-------------- celery@bwdeMacBook-Pro-2.local v5.4.0 (opalescent)
--- ***** -----
-- ******* ---- macOS-15.4.1-arm64-arm-64bit 2025-04-28 17:07:14
- *** --- * ---
- ** ---------- [config]
- ** ---------- .> app: app_factory:0x1439e8590
- ** ---------- .> transport: redis://:**@localhost:6379/1
- ** ---------- .> results: postgresql://postgres:**@localhost:5432/dify
- *** --- * --- .> concurrency: 1 (gevent)
-- ******* ---- .> task events: OFF (enable -E to monitor tasks in this worker)
--- ***** -----
-------------- [queues]
.> dataset exchange=dataset(direct) key=dataset
.> generation exchange=generation(direct) key=generation
.> mail exchange=mail(direct) key=mail
.> ops_trace exchange=ops_trace(direct) key=ops_trace
[tasks]
. schedule.clean_embedding_cache_task.clean_embedding_cache_task
. schedule.clean_messages.clean_messages
. schedule.clean_unused_datasets_task.clean_unused_datasets_task
. schedule.create_tidb_serverless_task.create_tidb_serverless_task
. schedule.mail_clean_document_notify_task.mail_clean_document_notify_task
. schedule.update_tidb_serverless_status_task.update_tidb_serverless_status_task
. tasks.add_document_to_index_task.add_document_to_index_task
. tasks.annotation.add_annotation_to_index_task.add_annotation_to_index_task
. tasks.annotation.batch_import_annotations_task.batch_import_annotations_task
. tasks.annotation.delete_annotation_index_task.delete_annotation_index_task
. tasks.annotation.disable_annotation_reply_task.disable_annotation_reply_task
. tasks.annotation.enable_annotation_reply_task.enable_annotation_reply_task
. tasks.annotation.update_annotation_to_index_task.update_annotation_to_index_task
. tasks.batch_clean_document_task.batch_clean_document_task
. tasks.batch_create_segment_to_index_task.batch_create_segment_to_index_task
. tasks.clean_dataset_task.clean_dataset_task
. tasks.clean_document_task.clean_document_task
. tasks.clean_notion_document_task.clean_notion_document_task
. tasks.deal_dataset_vector_index_task.deal_dataset_vector_index_task
. tasks.delete_account_task.delete_account_task
. tasks.delete_segment_from_index_task.delete_segment_from_index_task
. tasks.disable_segment_from_index_task.disable_segment_from_index_task
. tasks.disable_segments_from_index_task.disable_segments_from_index_task
. tasks.document_indexing_sync_task.document_indexing_sync_task
. tasks.document_indexing_task.document_indexing_task
. tasks.document_indexing_update_task.document_indexing_update_task
. tasks.duplicate_document_indexing_task.duplicate_document_indexing_task
. tasks.enable_segments_to_index_task.enable_segments_to_index_task
. tasks.mail_account_deletion_task.send_account_deletion_verification_code
. tasks.mail_account_deletion_task.send_deletion_success_task
. tasks.mail_email_code_login.send_email_code_login_mail_task
. tasks.mail_invite_member_task.send_invite_member_mail_task
. tasks.mail_reset_password_task.send_reset_password_mail_task
. tasks.ops_trace_task.process_trace_tasks
. tasks.recover_document_indexing_task.recover_document_indexing_task
. tasks.remove_app_and_related_data_task.remove_app_and_related_data_task
. tasks.remove_document_from_index_task.remove_document_from_index_task
. tasks.retry_document_indexing_task.retry_document_indexing_task
. tasks.sync_website_document_indexing_task.sync_website_document_indexing_task
2025-04-28 17:07:14,681 INFO [connection.py:22] Connected to redis://:**@localhost:6379/1
2025-04-28 17:07:14,684 INFO [mingle.py:40] mingle: searching for neighbors
2025-04-28 17:07:15,704 INFO [mingle.py:49] mingle: all alone
2025-04-28 17:07:15,733 INFO [worker.py:175] celery@bwdeMacBook-Pro-2.local ready.
2025-04-28 17:07:15,742 INFO [pidbox.py:111] pidbox: Connected to redis://:**@localhost:6379/1.
```
### Start the Beat Service
Additionally, if you want to debug the celery scheduled tasks or run the Schedule Trigger node, you can run the following command in another terminal to start the beat service:
```bash theme={null}
uv run celery -A app.celery beat
```
***
## Setup Web Service
Start the web service is built for frontend pages .
### Environment Preparation
To start the web frontend service, [Node.js v22 (LTS)](https://nodejs.org/en) and [PNPM v10](https://pnpm.io/) are required.
* Install NodeJS
Please visit [https://nodejs.org/en/download](https://nodejs.org/en/download) and choose the installation package for your respective operating system that is v18.x or higher. LTS version is recommanded for common usages.
* Install PNPM
Follow the [the installation guidance](https://pnpm.io/installation) to install PNPM. Or just run this command to install `pnpm` with `npm`.
```
npm i -g pnpm
```
### Start Web Service
1. Enter the web directory:
```
cd web
```
2. Install dependencies:
```
pnpm install --frozen-lockfile
```
3. Prepare the environment variable configuration file\
Create a file named `.env.local` in the current directory and copy the contents from `.env.example`. Modify the values of these environment variables according to your requirements:
```
# For production release, change this to PRODUCTION
NEXT_PUBLIC_DEPLOY_ENV=DEVELOPMENT
# The deployment edition, SELF_HOSTED or CLOUD
NEXT_PUBLIC_EDITION=SELF_HOSTED
# The base URL of console application, refers to the Console base URL of WEB service if console domain is different from api or web app domain.
# example: http://cloud.dify.ai/console/api
NEXT_PUBLIC_API_PREFIX=http://localhost:5001/console/api
# The URL for Web APP, refers to the Web App base URL of WEB service if web app domain is different from console or api domain.
# example: http://udify.app/api
NEXT_PUBLIC_PUBLIC_API_PREFIX=http://localhost:5001/api
# When the frontend and backend run on different subdomains, set NEXT_PUBLIC_COOKIE_DOMAIN=1.
NEXT_PUBLIC_COOKIE_DOMAIN=
# SENTRY
NEXT_PUBLIC_SENTRY_DSN=
NEXT_PUBLIC_SENTRY_ORG=
NEXT_PUBLIC_SENTRY_PROJECT=
```
4. Build the web service:
```
pnpm build
```
5. Start the web service:
```
pnpm start
```
Expected output:
```
▲ Next.js 15
- Local: http://localhost:3000
- Network: http://0.0.0.0:3000
✓ Starting...
✓ Ready in 73ms
```
### Access Dify
Access [http://localhost:3000](http://localhost:3000/) via browsers to enjoy all the exciting features of Dify.
Cheers ! 🍻
# Start Frontend Docker Container Separately
Source: https://docs.dify.ai/en/self-host/deploy/advanced-deployments/start-the-frontend-docker-container
When developing the backend separately, you may only need to start the backend service from source code without building and launching the frontend locally. In this case, you can directly start the frontend service by pulling the Docker image and running the container. Here are the specific steps:
#### Pull the Docker image for the frontend service from DockerHub:
```bash theme={null}
docker run -it -p 3000:3000 -e CONSOLE_URL=http://127.0.0.1:5001 -e APP_URL=http://127.0.0.1:5001 langgenius/dify-web:latest
```
#### Build Docker Image from Source Code
1. Build the frontend image
```
cd web && docker build . -t dify-web
```
2. Start the frontend image
```
docker run -it -p 3000:3000 -e CONSOLE_URL=http://127.0.0.1:5001 -e APP_URL=http://127.0.0.1:5001 dify-web
```
3. When the console domain and web app domain are different, you can set the CONSOLE\_URL and APP\_URL separately
4. To access it locally, you can visit [http://127.0.0.1:3000](http://127.0.0.1:3000/)
# Environment Variables
Source: https://docs.dify.ai/en/self-host/deploy/configuration/environments
Reference for all environment variables used by Dify self-hosted deployments
Dify works out of the box with default settings. To customize your deployment, edit environment variables in the relevant file:
* **Essential startup values** live in `docker/.env`, which you created from `docker/.env.example` during deployment. Edit them directly.
* **Optional or provider-specific settings** have templates under `docker/envs/`. To override a default value, copy the matching template (drop the `.example` suffix), then edit your copy.
For example:
```bash theme={null}
cd dify/docker
cp envs/vectorstores/milvus.env.example envs/vectorstores/milvus.env
```
Values in `docker/.env` take precedence over values in any `docker/envs/*.env` files.
<Tip>
After upgrading Dify, compare each `.env.example` with its matching `.env` for new or changed variables.
</Tip>
## Common Variables
These URL variables configure the addresses of Dify's various services.
For single-domain deployments behind Nginx (the default Docker Compose setup), these can be left empty—the system auto-detects from the incoming request. Configure them when using custom domains, split-domain deployments, or a reverse proxy.
### CONSOLE\_API\_URL
Default: (empty)
The public URL of Dify's backend API. Set this if you use OAuth login (GitHub, Google), Notion integration, or any plugin that requires OAuth—these features need an absolute callback URL to redirect users back after authorization. Also determines whether secure (HTTPS-only) cookies are used.
Example: `https://api.console.dify.ai`
### SERVER\_CONSOLE\_API\_URL
Default: `http://api:5001`
The console API address the web frontend container uses for server-side requests, reaching the API directly over the internal Docker network rather than your public domain. Only the web frontend container uses this variable, not the Python backend; browser requests still go to `CONSOLE_API_URL`.
If left empty, it falls back to `CONSOLE_API_URL`. Change it only if the API service is reachable at a different internal address.
### CONSOLE\_WEB\_URL
Default: (empty)
The public URL of Dify's console frontend. Used to build links in all system emails (invitations, password resets, notifications) and to redirect users back to the console after OAuth login. Also serves as the default CORS allowed origin if `CONSOLE_CORS_ALLOW_ORIGINS` is not set.
If empty, email links will be broken—even in single-domain setups, set this if you use email features.
Example: `https://console.dify.ai`
### SERVICE\_API\_URL
Default: (empty)
The API Base URL shown to developers in the Dify console—the URL they copy into their code to call the Dify API. If empty, auto-detects from the current request (e.g., `http://localhost/v1`). Set this to ensure a consistent URL when your server is accessible via multiple addresses.
Example: `https://api.dify.ai`
### APP\_API\_URL
Default: (empty)
The backend API URL for the web app frontend (published apps). This variable is only used by the web frontend container, not the Python backend. If empty, the Docker image defaults to `http://127.0.0.1:5001`.
Example: `https://api.app.dify.ai`
### APP\_WEB\_URL
Default: (empty)
The public URL where published web apps are accessible. Required for the **Human Input node** in workflows—form links in email notifications are built as `{APP_WEB_URL}/form/{token}`. If empty, Human Input email delivery will not include valid form links.
Example: `https://app.dify.ai`
### TRIGGER\_URL
Default: `http://localhost`
The publicly accessible URL for webhook and integration trigger endpoints. External systems use this address to invoke your workflows. Dify builds trigger callback URLs like `{TRIGGER_URL}/triggers/webhook/{id}` and displays them in the console.
For triggers to work from external systems, this must point to a public domain or IP address they can reach.
### FILES\_URL
Default: (empty; falls back to `CONSOLE_API_URL`)
The base URL for file preview and download links. Dify generates signed, time-limited URLs for all files (uploaded documents, tool outputs, workspace logos) and serves them to the frontend and multi-modal models.
Set this if you use file processing plugins, or if you want file URLs on a dedicated domain. If both `FILES_URL` and `CONSOLE_API_URL` are empty, file previews will not work.
Example: `https://upload.example.com` or `http://<your-ip>:5001`
### INTERNAL\_FILES\_URL
Default: (empty; falls back to `FILES_URL`)
The file access URL used for communication between services inside the Docker network (e.g., plugin daemon, PDF/Word extractors). These internal services may not be able to reach the external `FILES_URL` if it routes through Nginx or a public domain.
If empty, internal services use `FILES_URL`. Set this when internal services can't reach the external URL.
Example: `http://api:5001`
### FILES\_ACCESS\_TIMEOUT
Default: `300` (5 minutes)
How long signed file URLs remain valid, in seconds. After this time, the URL is rejected and the file must be re-requested. Increase for long-running processes; decrease for tighter security.
### ENABLE\_COLLABORATION\_MODE
Default: `true`
Enables real-time collaboration on the workflow canvas: simultaneous editing, in-canvas comments, and @mentions.
If you access Dify on a host other than `localhost`, set `NEXT_PUBLIC_SOCKET_URL` to a WebSocket URL your browser can reach (see [CORS Configuration](#cors-configuration)). The default `ws://localhost` only works for local-only setups.
To disable collaboration, set this to `false`. On Docker Compose, also remove `collaboration` from `COMPOSE_PROFILES`. Otherwise the dedicated `api_websocket` container keeps running but receives no traffic.
If you use your own reverse proxy, forward `Upgrade` and `Connection` headers on `/socket.io/` (the bundled nginx template already does this). Running multiple API replicas requires sticky sessions.
### System Encoding
| Variable | Default | Description |
| ------------------ | ---------------- | ------------------------------------------------------------------------------------------------ |
| `LANG` | `C.UTF-8` | System locale setting. Ensures UTF-8 encoding. |
| `LC_ALL` | `C.UTF-8` | Locale override for all categories. |
| `PYTHONIOENCODING` | `utf-8` | Python I/O encoding. |
| `UV_CACHE_DIR` | `/tmp/.uv-cache` | UV package manager cache directory. Avoids permission issues with non-existent home directories. |
## Server Configuration
### Logging
| Variable | Default | Description |
| ----------------------- | ---------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `LOG_LEVEL` | `INFO` | Minimum log severity. Controls what gets logged across all handlers (file + console). Levels from least to most severe: `DEBUG`, `INFO`, `WARNING`, `ERROR`, `CRITICAL`. |
| `LOG_OUTPUT_FORMAT` | `text` | `text` produces human-readable lines with timestamp, level, thread, and trace ID. `json` produces structured JSON for log aggregation tools (ELK, Datadog, etc.). |
| `LOG_FILE` | `/app/logs/server.log` | Log file path. When set, enables file-based logging with automatic rotation. The directory is created automatically. When empty, logs only go to console. |
| `LOG_FILE_MAX_SIZE` | `20` | Maximum log file size in MB before rotation. When exceeded, the active file is renamed to `.1` and a new file is started. |
| `LOG_FILE_BACKUP_COUNT` | `5` | Number of rotated log files to keep. With defaults, at most 6 files exist: the active file plus 5 backups. |
| `LOG_DATEFORMAT` | `%Y-%m-%d %H:%M:%S` | Timestamp format for text-format logs (strftime codes). Ignored by JSON format. |
| `LOG_TZ` | `UTC` | Timezone for log timestamps (pytz format, e.g., `Asia/Shanghai`). Only applies to text format—JSON always uses UTC. Also sets Celery's task scheduling timezone. |
### General
| Variable | Default | Description |
| ------------------------ | --------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DEBUG` | `false` | Enables verbose logging: workflow node inputs/outputs, tool execution details, full LLM prompts and responses, and app startup timing. Useful for local development; not recommended for production as it may expose sensitive data in logs. |
| `FLASK_DEBUG` | `false` | Standard Flask debug mode flag. Not actively used by Dify; `DEBUG` is the primary control. |
| `ENABLE_REQUEST_LOGGING` | `false` | Logs a compact access line (`METHOD PATH STATUS DURATION TRACE_ID`) for every HTTP request. When `LOG_LEVEL` is also set to `DEBUG`, additionally logs full request and response bodies as JSON. |
| `DEPLOY_ENV` | `PRODUCTION` | Tags monitoring data in Sentry and OpenTelemetry so you can filter errors and traces by environment. Also sent as the `X-Env` response header. Does not change application behavior. |
| `DEPLOYMENT_EDITION` | `COMMUNITY` | Which edition this deployment runs as: `COMMUNITY`, `ENTERPRISE`, or `CLOUD`. Keep the default.<br /><br />Replaces the former `EDITION`, `ENTERPRISE_ENABLED`, and `BILLING_ENABLED` variables, which are ignored from 1.17.0 onward. |
| `MIGRATION_ENABLED` | `true` | When `true`, runs database schema migrations (`flask upgrade-db`) automatically on container startup. Docker only. Set to `false` if you run migrations separately. For source code launches, run `flask db upgrade` manually. |
| `CHECK_UPDATE_URL` | `https://updates.dify.ai` | The console checks this URL for newer Dify versions. Set to empty to disable—useful for air-gapped environments or to prevent external HTTP calls. |
| `OPENAI_API_BASE` | `https://api.openai.com/v1` | Legacy variable. Not actively used by Dify's own code. May be picked up by the OpenAI Python SDK if present in the environment. |
### SECRET\_KEY
Default: (pre-filled in `.env.example`; must be replaced for production)
Used for session cookie signing, JWT authentication tokens, file URL signatures (HMAC-SHA256), and encrypting third-party OAuth credentials (AES-256). Generate a strong key before first launch:
```bash theme={null}
openssl rand -base64 42
```
<Warning>
Changing this key after deployment will immediately log out all users, invalidate all file URLs, and break any plugin integrations that use OAuth—their encrypted credentials become unrecoverable.
</Warning>
### KEY\_PROVIDER\_TYPE
Default: `local`
Where Dify keeps the per-workspace keys that encrypt stored credentials—model provider API keys, tool credentials, and other workspace secrets:
* `local`: generates an RSA key pair per workspace and keeps the private key in the `STORAGE_TYPE` backend.
* `azure-keyvault`: keeps each workspace's RSA key in Azure Key Vault instead, so the private key never leaves the vault; Dify authenticates with `DefaultAzureCredential` (managed identity, environment variables, or Azure CLI login).
<Warning>
Choose the provider before the first workspace is created. Credentials encrypted by one provider cannot be decrypted by the other, so switching on a deployment that already stores credentials makes them unreadable until re-entered.
</Warning>
| Variable | Default | Description |
| --------------------------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `AZURE_KEYVAULT_VAULT_URL` | (empty) | Key Vault instance URL. Required when `KEY_PROVIDER_TYPE` is `azure-keyvault`; the API service fails to start without it. Example: `https://your-vault-name.vault.azure.net` |
| `AZURE_KEYVAULT_KEY_SIZE` | `2048` | RSA key size in bits for the per-workspace keys Dify provisions in the vault. Applies only when a new key is created; existing keys keep their size. |
| `AZURE_KEYVAULT_ROTATION_INTERVAL_DAYS` | (empty) | When set (minimum 7), each newly provisioned per-workspace key gets a Key Vault auto-rotation policy that rotates it every N days. Old key versions stay usable, so credentials encrypted before a rotation keep decrypting without re-encryption. Leave empty to manage rotation yourself in Azure. |
### INIT\_PASSWORD
Default: (empty)
Optional security gate for first-time setup. When set, the `/install` page requires this password before the admin account can be created—preventing unauthorized setup if your server is exposed. Once setup is complete, this variable has no further effect. Maximum length: 30 characters.
### Token & Request Limits
| Variable | Default | Description |
| ----------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `ACCESS_TOKEN_EXPIRE_MINUTES` | `60` | How long a login session's access token stays valid (in minutes). When it expires, the browser silently refreshes it using the refresh token—users are not logged out. |
| `REFRESH_TOKEN_EXPIRE_DAYS` | `30` | How long a user can stay logged in without re-entering credentials (in days). If the user doesn't visit within this period, they must log in again. |
| `APP_MAX_EXECUTION_TIME` | `3600` | Maximum time in seconds an app execution can run before it is terminated. <br /><br />An outer limit alongside `WORKFLOW_MAX_EXECUTION_TIME`: both default to one hour, with this one applied at the app queue level and the other at the workflow engine level. Increase both together if your workflows need more time.<br /><br />If you run agents, keep these outer limits at or above the agent run deadline (`DIFY_AGENT_RUN_TIMEOUT_SECONDS`); otherwise agent runs are cut short. |
| `APP_DEFAULT_ACTIVE_REQUESTS` | `0` | Default concurrent request limit per app, used when an app doesn't have a custom limit set in the UI. `0` means unlimited. The effective limit is the smaller of this and `APP_MAX_ACTIVE_REQUESTS`. |
| `APP_MAX_ACTIVE_REQUESTS` | `0` | Global ceiling for concurrent requests per app. Overrides per-app settings if they exceed this value. `0` means unlimited. |
### Container Startup Configuration
Only effective when starting with Docker image or Docker Compose.
| Variable | Default | Description |
| ------------------------------------- | -------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DIFY_BIND_ADDRESS` | `0.0.0.0` | Network interface the API server binds to. `0.0.0.0` listens on all interfaces; set to `127.0.0.1` to restrict to localhost only. |
| `DIFY_PORT` | `5001` | Port the API server listens on. |
| `SERVER_WORKER_AMOUNT` | `1` | Number of Gunicorn worker processes. With gevent (default), each worker handles multiple concurrent connections via greenlets, so 1 is usually sufficient. For sync workers, use `(2 x CPU cores) + 1`. [Reference](https://gunicorn.org/design/#how-many-workers). |
| `SERVER_WORKER_CLASS` | `gevent` | Gunicorn worker type. Keep the default; other values break psycopg2 and gRPC patching. |
| `SERVER_WORKER_CONNECTIONS` | `10` | Maximum concurrent connections per worker. Only applies to async workers (gevent). If you experience connection rejections or slow responses under load, try increasing this value. |
| `GUNICORN_TIMEOUT` | `360` | If a worker doesn't respond within this many seconds, Gunicorn kills and restarts it. Set to 360 (6 minutes) to support long-lived SSE connections used for streaming LLM responses. |
| `API_WEBSOCKET_WORKER_AMOUNT` | `1` | Docker Compose only. Number of Gunicorn workers in the dedicated `api_websocket` container serving real-time collaboration. Collaboration events sync across workers through Redis, so it's safe to raise this when one worker saturates a CPU core under heavy editor traffic. |
| `API_WEBSOCKET_WORKER_CLASS` | `geventwebsocket.gunicorn.workers.GeventWebSocketWorker` | Docker Compose only. Worker class for the dedicated `api_websocket` container. Keep the default; other values break WebSocket support. |
| `API_WEBSOCKET_WORKER_CONNECTIONS` | `1000` | Docker Compose only. Maximum simultaneous WebSocket connections per `api_websocket` worker. Each open workflow editor in a browser tab uses one, so the default supports up to 1000 simultaneous editor sessions per worker; raise it or add workers if you expect more. |
| `API_WEBSOCKET_GUNICORN_TIMEOUT` | `360` | Docker Compose only. If an `api_websocket` worker doesn't respond within this many seconds, Gunicorn restarts it. The default 360 seconds (6 minutes) supports long-lived WebSocket connections. |
| `CELERY_WORKER_CLASS` | (empty; defaults to gevent) | Celery worker type with the same gevent patching requirements as `SERVER_WORKER_CLASS`. Strongly discouraged to change. |
| `CELERY_WORKER_AMOUNT` | `4` | Number of Celery worker processes. Only used when autoscaling is disabled. Lower it on constrained VMs; for elastic throughput, enable `CELERY_AUTO_SCALE` instead of raising this. |
| `CELERY_AUTO_SCALE` | `false` | Enable dynamic autoscaling. When enabled, Celery monitors queue depth and spawns/kills workers between `CELERY_MIN_WORKERS` and `CELERY_MAX_WORKERS`. |
| `CELERY_MAX_WORKERS` | (empty; defaults to CPU count) | Maximum workers when autoscaling is enabled. |
| `CELERY_MIN_WORKERS` | (empty; defaults to 1) | Minimum workers when autoscaling is enabled. |
| `COMPOSE_WORKER_HEALTHCHECK_DISABLED` | `true` | Disable the Docker Compose health check for the Celery worker container. Disabled by default because `celery inspect ping` can be expensive on busy workers. Set to `false` to enable. Only applies to Docker Compose deployments. |
| `COMPOSE_WORKER_HEALTHCHECK_INTERVAL` | `30s` | Interval between Celery worker health checks. Only used when `COMPOSE_WORKER_HEALTHCHECK_DISABLED=false`. Accepts Docker Compose duration values (e.g., `30s`, `1m`). |
| `COMPOSE_WORKER_HEALTHCHECK_TIMEOUT` | `30s` | Timeout for each Celery worker health check. Only used when `COMPOSE_WORKER_HEALTHCHECK_DISABLED=false`. |
### MODE
Default: `worker` (the worker service's shipped value; with the variable unset entirely, the container runs the API server)
What the `dify-api` image runs at container start. Each of the three env example files pins the value for its own service: `worker` in `worker.env.example`, `api` in `api.env.example`, and `beat` in `worker-beat.env.example`. Accepted values:
* `api` (and any empty or unrecognized value): the API server
* `worker`: the Celery task consumer
* `beat`: the scheduled-task dispatcher
* `job`: run one Flask CLI command, then exit
* `migration`: with `MIGRATION_ENABLED=true`, migrate the database and exit
The bundled Compose file pins the right value per service, so you only set this in custom setups such as Kubernetes. A wrong value runs the wrong process—with no worker, indexing and mail tasks queue forever.
### API Tool Configuration
| Variable | Default | Description |
| ---------------------------------- | ------- | ----------------------------------------------------------------------------------------------------------- |
| `API_TOOL_DEFAULT_CONNECT_TIMEOUT` | `10` | Maximum time (in seconds) to wait for establishing a TCP connection when API Tool nodes call external APIs. |
| `API_TOOL_DEFAULT_READ_TIMEOUT` | `60` | Maximum time (in seconds) to wait for receiving response data from external APIs called by API Tool nodes. |
### Database Configuration
The database uses PostgreSQL by default. OceanBase, MySQL, and seekdb are also supported.
| Variable | Default | Description |
| ------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| `DB_TYPE` | `postgresql` | Database type. Supported values: `postgresql`, `mysql`, `oceanbase`, `seekdb`. MySQL-compatible databases like TiDB can use `mysql`. |
| `DB_USERNAME` | `postgres` | Database username. URL-encoded in the connection string, so special characters are safe to use. |
| `DB_PASSWORD` | `difyai123456` | Database password. URL-encoded in the connection string, so characters like `@`, `:`, `%` are safe to use. |
| `DB_HOST` | `db_postgres` | Database server hostname. |
| `DB_PORT` | `5432` | Database server port. If using MySQL, set this to `3306`. |
| `DB_DATABASE` | `dify` | Database name. |
#### Connection Pool
These control how Dify manages its pool of database connections. The defaults work well for most deployments.
| Variable | Default | Description |
| --------------------------------- | ---------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `SQLALCHEMY_POOL_SIZE` | `30` | Number of persistent connections kept in the pool. |
| `SQLALCHEMY_MAX_OVERFLOW` | `10` | Additional temporary connections allowed when the pool is full. With default settings, up to 40 connections (30 + 10) can exist simultaneously. |
| `SQLALCHEMY_POOL_RECYCLE` | `3600` | Recycle connections after this many seconds to prevent stale connections. |
| `SQLALCHEMY_POOL_TIMEOUT` | `30` | How long to wait for a connection when the pool is exhausted. Requests fail with a timeout error if no connection frees up in time. |
| `SQLALCHEMY_POOL_RESET_ON_RETURN` | `rollback` | Action SQLAlchemy takes when a connection returns to the pool. `rollback` clears any uncommitted transaction state before reuse; `commit` commits it instead. |
| `SQLALCHEMY_POOL_PRE_PING` | `false` | Test each connection with a lightweight query before using it. Prevents "connection lost" errors but adds slight latency. Recommended for production with unreliable networks. |
| `SQLALCHEMY_POOL_USE_LIFO` | `false` | Reuse the most recently returned connection (LIFO) instead of rotating evenly (FIFO). LIFO keeps fewer connections "warm" and can reduce overhead. |
| `SQLALCHEMY_ECHO` | `false` | Print all SQL statements to logs. Useful for debugging query issues. |
#### PostgreSQL Performance Tuning
These are passed as startup arguments to the PostgreSQL container—they configure the database server, not the Dify application.
| Variable | Default | Description |
| ---------------------------------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `POSTGRES_MAX_CONNECTIONS` | `200` | Maximum number of database connections. Keep at least `SERVER_WORKER_AMOUNT × SERVER_WORKER_CONNECTIONS + CELERY_WORKER_AMOUNT + headroom` to avoid `too many connections` errors when API and Celery workers both open pools. [Reference](https://www.postgresql.org/docs/current/runtime-config-connection.html#GUC-MAX-CONNECTIONS) |
| `POSTGRES_SHARED_BUFFERS` | `128MB` | Shared memory for buffers. Recommended: 25% of available memory. [Reference](https://www.postgresql.org/docs/current/runtime-config-resource.html#GUC-SHARED-BUFFERS) |
| `POSTGRES_WORK_MEM` | `4MB` | Memory per database worker for working space. [Reference](https://www.postgresql.org/docs/current/runtime-config-resource.html#GUC-WORK-MEM) |
| `POSTGRES_MAINTENANCE_WORK_MEM` | `64MB` | Memory reserved for maintenance activities. [Reference](https://www.postgresql.org/docs/current/runtime-config-resource.html#GUC-MAINTENANCE-WORK-MEM) |
| `POSTGRES_EFFECTIVE_CACHE_SIZE` | `4096MB` | Planner's assumption about effective cache size. [Reference](https://www.postgresql.org/docs/current/runtime-config-query.html#GUC-EFFECTIVE-CACHE-SIZE) |
| `POSTGRES_STATEMENT_TIMEOUT` | `0` | Max statement duration before termination (ms). `0` means no timeout. [Reference](https://www.postgresql.org/docs/current/runtime-config-client.html#GUC-STATEMENT-TIMEOUT) |
| `POSTGRES_IDLE_IN_TRANSACTION_SESSION_TIMEOUT` | `0` | Max idle-in-transaction session duration (ms). `0` means no timeout. [Reference](https://www.postgresql.org/docs/current/runtime-config-client.html#GUC-IDLE-IN-TRANSACTION-SESSION-TIMEOUT) |
#### MySQL Performance Tuning
These are passed as startup arguments to the MySQL container—they configure the database server, not the Dify application.
| Variable | Default | Description |
| -------------------------------------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `MYSQL_MAX_CONNECTIONS` | `1000` | Maximum number of MySQL connections. |
| `MYSQL_INNODB_BUFFER_POOL_SIZE` | `512M` | InnoDB buffer pool size. Recommended: 70-80% of available memory for dedicated MySQL server. [Reference](https://dev.mysql.com/doc/refman/8.0/en/innodb-parameters.html#sysvar_innodb_buffer_pool_size) |
| `MYSQL_INNODB_LOG_FILE_SIZE` | `128M` | InnoDB log file size. [Reference](https://dev.mysql.com/doc/refman/8.0/en/innodb-parameters.html#sysvar_innodb_log_file_size) |
| `MYSQL_INNODB_FLUSH_LOG_AT_TRX_COMMIT` | `2` | InnoDB flush log at transaction commit. Options: `0` (no flush), `1` (flush and sync), `2` (flush to OS cache). [Reference](https://dev.mysql.com/doc/refman/8.0/en/innodb-parameters.html#sysvar_innodb_flush_log_at_trx_commit) |
### Redis Configuration
Configure these to connect Dify to your Redis instance. Dify supports three deployment modes: standalone (default), Sentinel, and Cluster.
| Variable | Default | Description |
| -------------------------- | -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `REDIS_HOST` | `redis` | Redis server hostname. Only used in standalone mode; ignored when Sentinel or Cluster mode is enabled. |
| `REDIS_PORT` | `6379` | Redis server port. Only used in standalone mode. |
| `REDIS_USERNAME` | (empty) | Redis 6.0+ ACL username. Applies to all modes (standalone, Sentinel, Cluster). |
| `REDIS_PASSWORD` | `difyai123456` | Redis authentication password. For Cluster mode, use `REDIS_CLUSTERS_PASSWORD` instead. |
| `REDIS_DB` | `0` | Redis database number (0–15). Only applies to standalone and Sentinel modes. Make sure this doesn't collide with Celery's database (configured in `CELERY_BROKER_URL`; default is DB 1). |
| `REDIS_KEY_PREFIX` | (empty) | Optional global prefix applied to all Redis keys, pub/sub channels, Redis Streams names, and Celery broker queues and result-backend keys. Dify automatically inserts a colon between the prefix and the key, so setting `staging` produces keys like `staging:session:abc`. Useful when multiple Dify instances share one Redis deployment (for example, staging and production) to prevent key collisions. Leave empty to preserve unprefixed behavior. Turning the prefix on for an existing deployment strands any keys written under the previous (empty or different) prefix. |
| `REDIS_USE_SSL` | `false` | Enable SSL/TLS for the Redis connection. Does not automatically apply to Sentinel protocol. |
| `REDIS_MAX_CONNECTIONS` | (empty) | Maximum connections in the Redis pool. Leave unset for the library default. Set this to match your Redis server's `maxclients` if needed. |
| `REDIS_KEEPALIVE` | `true` | Enable TCP keepalive on Redis connections, so idle connections silently dropped by a firewall or load balancer are detected and re-established instead of failing on next use. |
| `REDIS_KEEPALIVE_IDLE` | `30` | Seconds a connection stays idle before the first TCP keepalive probe (`TCP_KEEPIDLE`). Applies when `REDIS_KEEPALIVE=true`. |
| `REDIS_KEEPALIVE_INTERVAL` | `10` | Seconds between TCP keepalive probes (`TCP_KEEPINTVL`). Applies when `REDIS_KEEPALIVE=true`. |
| `REDIS_KEEPALIVE_COUNT` | `10` | Number of unacknowledged probes before the connection is treated as dead (`TCP_KEEPCNT`). Applies when `REDIS_KEEPALIVE=true`. |
#### Redis SSL Configuration
Only applies when `REDIS_USE_SSL=true`. These same settings are also used by the Celery broker when its URL uses the `rediss://` scheme.
| Variable | Default | Description |
| --------------------- | ----------- | ----------------------------------------------------------------------------------------------------------------------- |
| `REDIS_SSL_CERT_REQS` | `CERT_NONE` | Certificate verification level: `CERT_NONE` (no verification), `CERT_OPTIONAL`, or `CERT_REQUIRED` (full verification). |
| `REDIS_SSL_CA_CERTS` | (empty) | Path to CA certificate file for verifying the Redis server. |
| `REDIS_SSL_CERTFILE` | (empty) | Path to client certificate for mutual TLS authentication. |
| `REDIS_SSL_KEYFILE` | (empty) | Path to client private key for mutual TLS authentication. |
#### Redis Sentinel Mode
Sentinel provides automatic master discovery and failover for high availability. Mutually exclusive with Cluster mode.
| Variable | Default | Description |
| ------------------------------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `REDIS_USE_SENTINEL` | `false` | Enable Redis Sentinel mode. When enabled, `REDIS_HOST`/`REDIS_PORT` are ignored; Dify connects to Sentinel nodes instead and asks for the current master. |
| `REDIS_SENTINELS` | (empty) | Sentinel node addresses. Format: `<ip1>:<port1>,<ip2>:<port2>,<ip3>:<port3>`. These are the Sentinel instances, not the Redis servers. |
| `REDIS_SENTINEL_SERVICE_NAME` | (empty) | The logical service name Sentinel monitors (configured in `sentinel.conf`). Dify calls `master_for(service_name)` to discover the current master. |
| `REDIS_SENTINEL_USERNAME` | (empty) | Username for authenticating with Sentinel nodes. Separate from `REDIS_USERNAME`, which authenticates with the Redis master/replicas. |
| `REDIS_SENTINEL_PASSWORD` | (empty) | Password for authenticating with Sentinel nodes. Separate from `REDIS_PASSWORD`. |
| `REDIS_SENTINEL_SOCKET_TIMEOUT` | `0.1` | Socket timeout (in seconds) for communicating with Sentinel nodes. Default 0.1s assumes fast local network. For cloud/WAN deployments, increase to 1.0–5.0s to prevent intermittent timeouts. |
#### Redis Cluster Mode
Cluster mode provides automatic sharding across multiple Redis nodes. Mutually exclusive with Sentinel mode.
| Variable | Default | Description |
| ------------------------- | ------- | ------------------------------------------------------------------ |
| `REDIS_USE_CLUSTERS` | `false` | Enable Redis Cluster mode. |
| `REDIS_CLUSTERS` | (empty) | Cluster nodes. Format: `<ip1>:<port1>,<ip2>:<port2>,<ip3>:<port3>` |
| `REDIS_CLUSTERS_PASSWORD` | (empty) | Password for the Redis Cluster. |
#### Redis Connection Resilience
These tune client-side retry, timeout, and health-check behavior for Redis connections. Defaults are conservative; increase timeouts for cloud or WAN deployments where network latency is higher.
| Variable | Default | Description |
| ------------------------------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `REDIS_RETRY_RETRIES` | `3` | Maximum retries per Redis command on transient failures (`ConnectionError`, `TimeoutError`, `socket.timeout`). Set to `0` to disable retries. Uses exponential backoff with jitter. |
| `REDIS_RETRY_BACKOFF_BASE` | `1.0` | Base delay in seconds for exponential backoff between retries. |
| `REDIS_RETRY_BACKOFF_CAP` | `10.0` | Maximum backoff delay in seconds between retries. |
| `REDIS_SOCKET_TIMEOUT` | `5.0` | Socket timeout in seconds for Redis read/write operations. Increase if you see intermittent command timeouts under load. |
| `REDIS_SOCKET_CONNECT_TIMEOUT` | `5.0` | Socket timeout in seconds for establishing a Redis connection. |
| `REDIS_HEALTH_CHECK_INTERVAL` | `30` | Interval in seconds between client-side health checks on idle connections. Set to `0` to disable. Not applied in Cluster mode (silently stripped by `redis-py`). |
### Celery Configuration
Configure the background task queue used for dataset indexing, email sending, and scheduled jobs.
### CELERY\_BROKER\_URL
Default: `redis://:difyai123456@redis:6379/1`
Redis connection URL for the Celery message broker.
Direct connection format:
```text theme={null}
redis://<redis_username>:<redis_password>@<redis_host>:<redis_port>/<redis_database>
```
Sentinel mode format (separate multiple nodes with semicolons):
```text theme={null}
sentinel://<redis_username>:<redis_password>@<sentinel_host>:<sentinel_port>/<redis_database>
```
| Variable | Default | Description |
| -------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `CELERY_BACKEND` | `redis` | Where Celery stores task results. Options: `redis` (fast, in-memory) or `database` (stores in your main database). |
| `BROKER_USE_SSL` | `false` | Auto-enabled when `CELERY_BROKER_URL` uses `rediss://` scheme. Applies the Redis SSL certificate settings to the broker connection. |
| `CELERY_USE_SENTINEL` | `false` | Enable Redis Sentinel mode for the Celery broker. |
| `CELERY_SENTINEL_MASTER_NAME` | (empty) | Sentinel service name (Master Name). |
| `CELERY_SENTINEL_PASSWORD` | (empty) | Password for Sentinel authentication. Separate from `REDIS_SENTINEL_PASSWORD`; the two can differ if caching and task queuing use different Sentinel clusters. |
| `CELERY_SENTINEL_SOCKET_TIMEOUT` | `0.1` | Timeout for connecting to Sentinel in seconds. |
| `CELERY_TASK_ANNOTATIONS` | `null` | Apply runtime settings to specific tasks (e.g., rate limits). Format: JSON dictionary. Example: `{"tasks.add": {"rate_limit": "10/s"}}`. Most users don't need this. |
### CORS Configuration
Controls cross-domain access policies for the frontend.
| Variable | Default | Description |
| ------------------------------- | ---------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `WEB_API_CORS_ALLOW_ORIGINS` | `*` | Allowed origins for cross-origin requests to the Web API. Example: `https://dify.app` |
| `CONSOLE_CORS_ALLOW_ORIGINS` | `*` | Allowed origins for cross-origin requests to the console API. If not set, falls back to `CONSOLE_WEB_URL`. |
| `COOKIE_DOMAIN` | (empty) | Set to the shared top-level domain (e.g., `example.com`) when frontend and backend run on different subdomains. This allows authentication cookies to be shared across subdomains. When empty, cookies use the most secure `__Host-` prefix and are locked to a single domain. |
| `NEXT_PUBLIC_COOKIE_DOMAIN` | (empty) | Frontend flag for cross-subdomain cookies. Set to `1` (or any non-empty value) to enable—the actual domain is read from `COOKIE_DOMAIN` on the backend. |
| `NEXT_PUBLIC_SOCKET_URL` | `ws://localhost` | Browser-side WebSocket endpoint for real-time collaboration. Scheme + host + port only (path `/socket.io/` is fixed). Swap `http(s)://` for `ws(s)://`. Example: `wss://dify.example.com`. The default targets the bundled nginx on port 80. Applied at runtime; container restart picks up changes. |
| `NEXT_PUBLIC_BATCH_CONCURRENCY` | `5` | Frontend-only. Controls how many concurrent API calls the UI makes during batch operations. |
### Dify CLI and Programmatic API
The `/openapi/v1/*` surface is the user-scoped programmatic API that the [Dify CLI](/en/cli/quick-start) (`difyctl`) and other clients authenticate against with OAuth bearer tokens. It ships disabled: set both `OPENAPI_ENABLED` and `ENABLE_OAUTH_BEARER` to `true` to use the CLI against your deployment.
| Variable | Default | Description |
| ----------------------------------------- | --------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `OPENAPI_ENABLED` | `false` | Master switch for the `/openapi/v1/*` programmatic API used by the Dify CLI (`difyctl`).<br />When `false`, every `/openapi/v1/*` endpoint returns 404 and `difyctl login` cannot start. Enable together with `ENABLE_OAUTH_BEARER`. |
| `ENABLE_OAUTH_BEARER` | `false` | Binds the OAuth bearer authenticator for `/openapi/v1/*` and gates device-flow login approval.<br />With `OPENAPI_ENABLED=true` but this `false`, `difyctl login` fails with 503 at the approval step. Both must be `true` for the CLI to work. |
| `OPENAPI_KNOWN_CLIENT_IDS` | `difyctl` | Comma-separated OAuth client IDs allowed to start a device-flow login.<br />Add IDs to admit other clients without code changes; removing `difyctl` breaks CLI login with `unsupported_client`. |
| `OPENAPI_CORS_ALLOW_ORIGINS` | (empty) | Browser origins allowed to call `/openapi/v1/*` cross-origin, comma-separated.<br />Empty allows none, which is fine for the standard deployment and irrelevant to non-browser clients like the CLI. |
| `OPENAPI_RATE_LIMIT_PER_TOKEN` | `60` | Requests per minute per OAuth bearer token across `/openapi/v1/*`, shared across API replicas via Redis.<br />Exceeding it returns 429 with a `Retry-After` header. `0` disables the limit. |
| `DEVICE_FLOW_APPROVE_RATE_LIMIT_PER_HOUR` | `10` | Device-flow login approvals or denials one browser session can perform per hour.<br />Beyond that, approvals return 429 until the window passes. Cannot be `0`. |
### File Storage Configuration
Configure where Dify stores uploaded files, dataset documents, and encryption keys. Each storage type has its own credential variables—configure only the one you're using.
### STORAGE\_TYPE
Default: `opendal`
Selects the file storage backend. Supported values: `opendal`, `s3`, `azure-blob`, `aliyun-oss`, `google-storage`, `huawei-obs`, `volcengine-tos`, `tencent-cos`, `baidu-obs`, `oci-storage`, `supabase`, `clickzetta-volume`, `local` (deprecated; internally uses OpenDAL with filesystem scheme).
<AccordionGroup>
<Accordion title="OpenDAL (Default)">
Default storage backend using [Apache OpenDAL](https://opendal.apache.org/), a unified interface supporting many storage services. Dify automatically scans environment variables matching `OPENDAL_<SCHEME>_*` and passes them to OpenDAL. For example, with `OPENDAL_SCHEME=s3`, set `OPENDAL_S3_ACCESS_KEY_ID`, `OPENDAL_S3_SECRET_ACCESS_KEY`, etc.
| Variable | Default | Description |
| ---------------- | ------- | --------------------------------------------------------------------------------- |
| `OPENDAL_SCHEME` | `fs` | Storage service to use. Examples: `fs` (local filesystem), `s3`, `gcs`, `azblob`. |
For the default `fs` scheme:
| Variable | Default | Description |
| ----------------- | --------- | --------------------------------------------------------------------------------------- |
| `OPENDAL_FS_ROOT` | `storage` | Root directory for local filesystem storage. Created automatically if it doesn't exist. |
For all available schemes and their configuration options, see the [OpenDAL services documentation](https://github.com/apache/opendal/tree/main/core/services).
</Accordion>
<Accordion title="S3">
| Variable | Default | Description |
| ------------------------ | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `S3_ENDPOINT` | (empty) | S3 endpoint address. Required for non-AWS S3-compatible services (MinIO, etc.). |
| `S3_REGION` | `us-east-1` | S3 region. |
| `S3_BUCKET_NAME` | `difyai` | S3 bucket name. |
| `S3_ACCESS_KEY` | (empty) | S3 Access Key. Not needed when using IAM roles. |
| `S3_SECRET_KEY` | (empty) | S3 Secret Key. Not needed when using IAM roles. |
| `S3_ADDRESS_STYLE` | `auto` | S3 addressing style: `auto`, `path`, or `virtual`. Controls whether bucket names appear in the URL path (`path`) or as a subdomain (`virtual`). Only applies when `S3_USE_AWS_MANAGED_IAM` is `false`. |
| `S3_USE_AWS_MANAGED_IAM` | `false` | Use AWS IAM roles (EC2 instance profile, ECS task role) instead of explicit access key/secret key. When enabled, credentials are auto-discovered from the instance metadata. |
</Accordion>
<Accordion title="Azure Blob">
| Variable | Default | Description |
| --------------------------- | --------------------------------------------------- | --------------------------- |
| `AZURE_BLOB_ACCOUNT_NAME` | `difyai` | Azure storage account name. |
| `AZURE_BLOB_ACCOUNT_KEY` | `difyai` | Azure storage account key. |
| `AZURE_BLOB_CONTAINER_NAME` | `difyai-container` | Azure Blob container name. |
| `AZURE_BLOB_ACCOUNT_URL` | `https://<your_account_name>.blob.core.windows.net` | Azure Blob account URL. |
</Accordion>
<Accordion title="Google Cloud Storage">
| Variable | Default | Description |
| -------------------------------------------- | ------- | ---------------------------------------- |
| `GOOGLE_STORAGE_BUCKET_NAME` | (empty) | Google Cloud Storage bucket name. |
| `GOOGLE_STORAGE_SERVICE_ACCOUNT_JSON_BASE64` | (empty) | Base64-encoded service account JSON key. |
</Accordion>
<Accordion title="Alibaba Cloud OSS">
| Variable | Default | Description |
| ------------------------- | -------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `ALIYUN_OSS_BUCKET_NAME` | (empty) | OSS bucket name. |
| `ALIYUN_OSS_ACCESS_KEY` | (empty) | OSS access key. |
| `ALIYUN_OSS_SECRET_KEY` | (empty) | OSS secret key. |
| `ALIYUN_OSS_ENDPOINT` | `https://oss-ap-southeast-1-internal.aliyuncs.com` | OSS endpoint. [Regions and endpoints reference](https://www.alibabacloud.com/help/en/oss/user-guide/regions-and-endpoints). |
| `ALIYUN_OSS_REGION` | `ap-southeast-1` | OSS region. |
| `ALIYUN_OSS_AUTH_VERSION` | `v4` | OSS authentication version. |
| `ALIYUN_OSS_PATH` | (empty) | Object path prefix. Don't start with `/`. [Reference](https://www.alibabacloud.com/help/en/oss/support/0016-00000005). |
| `ALIYUN_CLOUDBOX_ID` | (empty) | CloudBox ID for CloudBox-based OSS deployments. |
</Accordion>
<Accordion title="Tencent Cloud COS">
| Variable | Default | Description |
| --------------------------- | ------- | --------------------------------------------------------------------------------------------------- |
| `TENCENT_COS_BUCKET_NAME` | (empty) | COS bucket name. |
| `TENCENT_COS_SECRET_KEY` | (empty) | COS secret key. |
| `TENCENT_COS_SECRET_ID` | (empty) | COS secret ID. |
| `TENCENT_COS_REGION` | (empty) | COS region, e.g., `ap-guangzhou`. [Reference](https://cloud.tencent.com/document/product/436/6224). |
| `TENCENT_COS_SCHEME` | (empty) | Protocol to access COS (`http` or `https`). |
| `TENCENT_COS_CUSTOM_DOMAIN` | (empty) | Custom domain for COS access. |
</Accordion>
<Accordion title="OCI Object Storage">
| Variable | Default | Description |
| ----------------- | -------------- | ----------------- |
| `OCI_ENDPOINT` | (empty) | OCI endpoint URL. |
| `OCI_BUCKET_NAME` | (empty) | OCI bucket name. |
| `OCI_ACCESS_KEY` | (empty) | OCI access key. |
| `OCI_SECRET_KEY` | (empty) | OCI secret key. |
| `OCI_REGION` | `us-ashburn-1` | OCI region. |
</Accordion>
<Accordion title="Huawei OBS">
| Variable | Default | Description |
| ------------------------ | ------- | -------------------------------------------------------------------------------------------------- |
| `HUAWEI_OBS_BUCKET_NAME` | (empty) | OBS bucket name. |
| `HUAWEI_OBS_ACCESS_KEY` | (empty) | OBS access key. |
| `HUAWEI_OBS_SECRET_KEY` | (empty) | OBS secret key. |
| `HUAWEI_OBS_SERVER` | (empty) | OBS server URL. [Reference](https://support.huaweicloud.com/sdk-python-devg-obs/obs_22_0500.html). |
| `HUAWEI_OBS_PATH_STYLE` | `false` | Use path-style URLs instead of virtual-hosted-style. |
</Accordion>
<Accordion title="Volcengine TOS">
| Variable | Default | Description |
| ---------------------------- | ------- | --------------------------------------------------------------------------- |
| `VOLCENGINE_TOS_BUCKET_NAME` | (empty) | TOS bucket name. |
| `VOLCENGINE_TOS_ACCESS_KEY` | (empty) | TOS access key. |
| `VOLCENGINE_TOS_SECRET_KEY` | (empty) | TOS secret key. |
| `VOLCENGINE_TOS_ENDPOINT` | (empty) | TOS endpoint URL. [Reference](https://www.volcengine.com/docs/6349/107356). |
| `VOLCENGINE_TOS_REGION` | (empty) | TOS region, e.g., `cn-guangzhou`. |
</Accordion>
<Accordion title="Baidu OBS">
| Variable | Default | Description |
| ----------------------- | ------- | ---------------------- |
| `BAIDU_OBS_BUCKET_NAME` | (empty) | Baidu OBS bucket name. |
| `BAIDU_OBS_ACCESS_KEY` | (empty) | Baidu OBS access key. |
| `BAIDU_OBS_SECRET_KEY` | (empty) | Baidu OBS secret key. |
| `BAIDU_OBS_ENDPOINT` | (empty) | Baidu OBS server URL. |
</Accordion>
<Accordion title="Supabase">
| Variable | Default | Description |
| ---------------------- | ------- | ----------------------------- |
| `SUPABASE_BUCKET_NAME` | (empty) | Supabase storage bucket name. |
| `SUPABASE_API_KEY` | (empty) | Supabase API key. |
| `SUPABASE_URL` | (empty) | Supabase server URL. |
</Accordion>
<Accordion title="ClickZetta Volume">
| Variable | Default | Description |
| -------------------------------- | ---------- | -------------------------------------------------------------------------------------------------------------------------- |
| `CLICKZETTA_VOLUME_TYPE` | `user` | Volume type. Options: `user` (personal/small team), `table` (enterprise multi-tenant), `external` (data lake integration). |
| `CLICKZETTA_VOLUME_NAME` | (empty) | External volume name (required only when `TYPE=external`). |
| `CLICKZETTA_VOLUME_TABLE_PREFIX` | `dataset_` | Table volume table prefix (used only when `TYPE=table`). |
| `CLICKZETTA_VOLUME_DIFY_PREFIX` | `dify_km` | Dify file directory prefix for isolation from other apps. |
ClickZetta Volume reuses the `CLICKZETTA_*` connection parameters configured in the Vector Database section.
</Accordion>
</AccordionGroup>
#### Archive Storage
Separate S3-compatible storage for archiving workflow run logs. The `archive-workflow-runs` maintenance command packs runs older than a chosen cutoff into monthly Parquet bundles; CSV exports generated from those archives are staged in the export bucket.
| Variable | Default | Description |
| -------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------- |
| `ARCHIVE_STORAGE_ENABLED` | `false` | Enable archive storage for workflow log archival. |
| `ARCHIVE_STORAGE_ENDPOINT` | (empty) | S3-compatible endpoint URL. |
| `ARCHIVE_STORAGE_ARCHIVE_BUCKET` | (empty) | Bucket for archived workflow run logs. |
| `ARCHIVE_STORAGE_EXPORT_BUCKET` | (empty) | Bucket for temporary CSV export ZIPs generated from archived logs. Safe to auto-expire with a bucket lifecycle rule. |
| `ARCHIVE_STORAGE_ACCESS_KEY` | (empty) | Access key. |
| `ARCHIVE_STORAGE_SECRET_KEY` | (empty) | Secret key. |
| `ARCHIVE_STORAGE_REGION` | `auto` | Storage region. |
### Vector Database Configuration
Configure the vector database used for knowledge base embedding storage and similarity search. Each provider has its own set of credential variables—configure only the one you're using.
### VECTOR\_STORE
Default: `weaviate`
Selects the vector database backend. If a dataset already has an index, the dataset's stored type takes precedence over this setting. When switching providers in Docker Compose, `COMPOSE_PROFILES` automatically starts the matching container based on this value.
Supported values: `weaviate`, `oceanbase`, `seekdb`, `qdrant`, `milvus`, `myscale`, `relyt`, `pgvector`, `pgvecto-rs`, `chroma`, `opensearch`, `oracle`, `tencent`, `elasticsearch`, `elasticsearch-ja`, `analyticdb`, `couchbase`, `vikingdb`, `opengauss`, `tablestore`, `vastbase`, `tidb`, `tidb_on_qdrant`, `baidu`, `lindorm`, `huawei_cloud`, `upstash`, `matrixone`, `clickzetta`, `alibabacloud_mysql`, `iris`, `hologres`.
| Variable | Default | Description |
| -------------------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| `VECTOR_INDEX_NAME_PREFIX` | `Vector_index` | Prefix added to collection names in the vector database. Change this if you share a vector database instance across multiple Dify deployments. |
<AccordionGroup>
<Accordion title="Weaviate">
| Variable | Default | Description |
| ------------------------ | ----------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `WEAVIATE_ENDPOINT` | `http://weaviate:8080` | Weaviate REST API endpoint. |
| `WEAVIATE_API_KEY` | (empty) | API key for Weaviate authentication. |
| `WEAVIATE_GRPC_ENDPOINT` | `grpc://weaviate:50051` | Separate gRPC endpoint for high-performance binary protocol. Significantly faster for batch operations. Falls back to inferring from HTTP endpoint if not set. |
| `WEAVIATE_TOKENIZATION` | `word` | Tokenization method for text fields. Options: `word` (splits on whitespace and punctuation), `whitespace` (splits on whitespace only), `character` (character-level, better for CJK languages). |
</Accordion>
<Accordion title="OceanBase / seekdb">
seekdb is the lite version of OceanBase and shares the same connection configuration.
| Variable | Default | Description |
| -------------------------------- | -------------- | -------------------------------------------------------------------------------------------------------------------------------------------- |
| `OCEANBASE_VECTOR_HOST` | `oceanbase` | Hostname or IP address. |
| `OCEANBASE_VECTOR_PORT` | `2881` | Port number. |
| `OCEANBASE_VECTOR_USER` | `root@test` | Database username. |
| `OCEANBASE_VECTOR_PASSWORD` | `difyai123456` | Database password. |
| `OCEANBASE_VECTOR_DATABASE` | `test` | Database name. |
| `OCEANBASE_CLUSTER_NAME` | `difyai` | Cluster name (Docker deployment only). |
| `OCEANBASE_MEMORY_LIMIT` | `6G` | Memory limit for OceanBase (Docker deployment only). |
| `SEEKDB_MEMORY_LIMIT` | `2G` | Memory limit for seekdb (Docker deployment only). |
| `OCEANBASE_ENABLE_HYBRID_SEARCH` | `false` | Enable fulltext index for BM25 queries alongside vector search. Requires OceanBase >= 4.3.5.1. Collections must be recreated after enabling. |
| `OCEANBASE_FULLTEXT_PARSER` | `ik` | Fulltext parser. Built-in: `ngram`, `beng`, `space`, `ngram2`, `ik`. External (require plugin): `japanese_ftparser`, `thai_ftparser`. |
</Accordion>
<Accordion title="Qdrant">
| Variable | Default | Description |
| --------------------------- | -------------------- | ----------------------------- |
| `QDRANT_URL` | `http://qdrant:6333` | Qdrant endpoint address. |
| `QDRANT_API_KEY` | `difyai123456` | API key for Qdrant. |
| `QDRANT_CLIENT_TIMEOUT` | `20` | Client timeout in seconds. |
| `QDRANT_GRPC_ENABLED` | `false` | Enable gRPC communication. |
| `QDRANT_GRPC_PORT` | `6334` | gRPC port. |
| `QDRANT_REPLICATION_FACTOR` | `1` | Number of replicas per shard. |
</Accordion>
<Accordion title="Milvus">
| Variable | Default | Description |
| ----------------------------- | ----------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `MILVUS_URI` | `http://host.docker.internal:19530` | Milvus URI. For [Zilliz Cloud](https://docs.zilliz.com/docs/free-trials), use the Public Endpoint. |
| `MILVUS_DATABASE` | (empty) | Database name. |
| `MILVUS_TOKEN` | (empty) | Authentication token. For Zilliz Cloud, use the API Key. |
| `MILVUS_USER` | (empty) | Username. |
| `MILVUS_PASSWORD` | (empty) | Password. |
| `MILVUS_ENABLE_HYBRID_SEARCH` | `false` | Enable BM25 sparse index for full-text search alongside vector similarity. Requires Milvus >= 2.5.0. If the collection was created without this enabled, it must be recreated. |
| `MILVUS_ANALYZER_PARAMS` | (empty) | Analyzer parameters for text fields. |
| `MILVUS_SECURE` | `false` | Enable one-way TLS for the Milvus connection. When enabled, the client connects over gRPC with TLS and verifies the server certificate. |
| `MILVUS_SERVER_PEM_PATH` | (empty) | Path inside the container to the Milvus server certificate (PEM), used to verify the server when `MILVUS_SECURE` is enabled. |
| `MILVUS_SERVER_NAME` | (empty) | Server name (TLS SNI, matching the certificate's CN or SAN) to verify against. Required when `MILVUS_SERVER_PEM_PATH` is set. |
</Accordion>
<Accordion title="MyScale">
| Variable | Default | Description |
| -------------------- | --------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| `MYSCALE_HOST` | `myscale` | MyScale host. |
| `MYSCALE_PORT` | `8123` | MyScale port. |
| `MYSCALE_USER` | `default` | Username. |
| `MYSCALE_PASSWORD` | (empty) | Password. |
| `MYSCALE_DATABASE` | `dify` | Database name. |
| `MYSCALE_FTS_PARAMS` | (empty) | Full-text search params. [Multi-language support reference](https://myscale.com/docs/en/text-search/#understanding-fts-index-parameters). |
</Accordion>
<Accordion title="Couchbase">
| Variable | Default | Description |
| ----------------------------- | ------------------------------ | -------------------------------------------- |
| `COUCHBASE_CONNECTION_STRING` | `couchbase://couchbase-server` | Connection string for the Couchbase cluster. |
| `COUCHBASE_USER` | `Administrator` | Username. |
| `COUCHBASE_PASSWORD` | `password` | Password. |
| `COUCHBASE_BUCKET_NAME` | `Embeddings` | Bucket name. |
| `COUCHBASE_SCOPE_NAME` | `_default` | Scope name. |
</Accordion>
<Accordion title="Hologres">
| Variable | Default | Description |
| --------------------------------- | -------- | ---------------------------------------- |
| `HOLOGRES_HOST` | (empty) | Hostname. |
| `HOLOGRES_PORT` | `80` | Port number. |
| `HOLOGRES_DATABASE` | (empty) | Database name. |
| `HOLOGRES_ACCESS_KEY_ID` | (empty) | Access key ID (used as PG username). |
| `HOLOGRES_ACCESS_KEY_SECRET` | (empty) | Access key secret (used as PG password). |
| `HOLOGRES_SCHEMA` | `public` | Schema name. |
| `HOLOGRES_TOKENIZER` | `jieba` | Tokenizer for text fields. |
| `HOLOGRES_DISTANCE_METHOD` | `Cosine` | Distance method. |
| `HOLOGRES_BASE_QUANTIZATION_TYPE` | `rabitq` | Quantization type. |
| `HOLOGRES_MAX_DEGREE` | `64` | HNSW max degree. |
| `HOLOGRES_EF_CONSTRUCTION` | `400` | HNSW ef\_construction parameter. |
</Accordion>
<Accordion title="PGVector">
| Variable | Default | Description |
| ------------------------- | -------------- | ----------------------------------------------- |
| `PGVECTOR_HOST` | `pgvector` | Hostname. |
| `PGVECTOR_PORT` | `5432` | Port number. |
| `PGVECTOR_USER` | `postgres` | Username. |
| `PGVECTOR_PASSWORD` | `difyai123456` | Password. |
| `PGVECTOR_DATABASE` | `dify` | Database name. |
| `PGVECTOR_MIN_CONNECTION` | `1` | Minimum pool connections. |
| `PGVECTOR_MAX_CONNECTION` | `5` | Maximum pool connections. |
| `PGVECTOR_PG_BIGM` | `false` | Enable pg\_bigm extension for full-text search. |
</Accordion>
<Accordion title="Vastbase">
| Variable | Default | Description |
| ------------------------- | -------------- | ------------------------- |
| `VASTBASE_HOST` | `vastbase` | Hostname. |
| `VASTBASE_PORT` | `5432` | Port number. |
| `VASTBASE_USER` | `dify` | Username. |
| `VASTBASE_PASSWORD` | `Difyai123456` | Password. |
| `VASTBASE_DATABASE` | `dify` | Database name. |
| `VASTBASE_MIN_CONNECTION` | `1` | Minimum pool connections. |
| `VASTBASE_MAX_CONNECTION` | `5` | Maximum pool connections. |
</Accordion>
<Accordion title="PGVecto.RS">
| Variable | Default | Description |
| --------------------- | -------------- | -------------- |
| `PGVECTO_RS_HOST` | `pgvecto-rs` | Hostname. |
| `PGVECTO_RS_PORT` | `5432` | Port number. |
| `PGVECTO_RS_USER` | `postgres` | Username. |
| `PGVECTO_RS_PASSWORD` | `difyai123456` | Password. |
| `PGVECTO_RS_DATABASE` | `dify` | Database name. |
</Accordion>
<Accordion title="AnalyticDB">
| Variable | Default | Description |
| ------------------------------- | ------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `ANALYTICDB_KEY_ID` | (empty) | Aliyun access key ID. [Create AccessKey](https://help.aliyun.com/zh/analyticdb/analyticdb-for-postgresql/support/create-an-accesskey-pair). |
| `ANALYTICDB_KEY_SECRET` | (empty) | Aliyun access key secret. |
| `ANALYTICDB_REGION_ID` | `cn-hangzhou` | Region identifier. |
| `ANALYTICDB_INSTANCE_ID` | (empty) | Instance ID, e.g., `gp-xxxxxx`. [Create instance](https://help.aliyun.com/zh/analyticdb/analyticdb-for-postgresql/getting-started/create-an-instance-1). |
| `ANALYTICDB_ACCOUNT` | (empty) | Account name. [Create account](https://help.aliyun.com/zh/analyticdb/analyticdb-for-postgresql/getting-started/createa-a-privileged-account). |
| `ANALYTICDB_PASSWORD` | (empty) | Account password. |
| `ANALYTICDB_NAMESPACE` | `dify` | Namespace (schema). Created automatically if not exists. |
| `ANALYTICDB_NAMESPACE_PASSWORD` | (empty) | Namespace password. Used when creating a new namespace. |
| `ANALYTICDB_HOST` | (empty) | Direct connection host (alternative to API-based access). |
| `ANALYTICDB_PORT` | `5432` | Direct connection port. |
| `ANALYTICDB_MIN_CONNECTION` | `1` | Minimum pool connections. |
| `ANALYTICDB_MAX_CONNECTION` | `5` | Maximum pool connections. |
</Accordion>
<Accordion title="TiDB Vector">
| Variable | Default | Description |
| ------------------------------------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `TIDB_VECTOR_HOST` | `tidb` | Hostname. |
| `TIDB_VECTOR_PORT` | `4000` | Port number. |
| `TIDB_VECTOR_USER` | (empty) | Username. |
| `TIDB_VECTOR_PASSWORD` | (empty) | Password. |
| `TIDB_VECTOR_DATABASE` | `dify` | Database name. |
| `TIDB_VECTOR_ENABLE_FULLTEXT_SEARCH` | `false` | Unlocks the Full-Text Search and Hybrid Search retrieval options for knowledge bases on TiDB Vector.<br /><br />New knowledge base tables get a multilingual full-text index; existing tables gain it the next time documents are indexed.<br /><br />Requires a TiDB deployment that supports full-text indexes. |
</Accordion>
<Accordion title="MatrixOne">
| Variable | Default | Description |
| -------------------- | ----------- | -------------- |
| `MATRIXONE_HOST` | `matrixone` | Hostname. |
| `MATRIXONE_PORT` | `6001` | Port number. |
| `MATRIXONE_USER` | `dump` | Username. |
| `MATRIXONE_PASSWORD` | `111` | Password. |
| `MATRIXONE_DATABASE` | `dify` | Database name. |
</Accordion>
<Accordion title="Chroma">
| Variable | Default | Description |
| ------------------------- | --------------------------------------------------- | -------------------- |
| `CHROMA_HOST` | `127.0.0.1` | Chroma server host. |
| `CHROMA_PORT` | `8000` | Chroma server port. |
| `CHROMA_TENANT` | `default_tenant` | Tenant name. |
| `CHROMA_DATABASE` | `default_database` | Database name. |
| `CHROMA_AUTH_PROVIDER` | `chromadb.auth.token_authn.TokenAuthClientProvider` | Auth provider class. |
| `CHROMA_AUTH_CREDENTIALS` | (empty) | Auth credentials. |
</Accordion>
<Accordion title="Oracle">
| Variable | Default | Description |
| ------------------------ | ------------------------- | ----------------------------------------- |
| `ORACLE_USER` | `dify` | Oracle username. |
| `ORACLE_PASSWORD` | `dify` | Oracle password. |
| `ORACLE_DSN` | `oracle:1521/FREEPDB1` | Data source name. |
| `ORACLE_CONFIG_DIR` | `/app/api/storage/wallet` | Oracle configuration directory. |
| `ORACLE_WALLET_LOCATION` | `/app/api/storage/wallet` | Wallet location for Autonomous DB. |
| `ORACLE_WALLET_PASSWORD` | `dify` | Wallet password. |
| `ORACLE_IS_AUTONOMOUS` | `false` | Whether using Oracle Autonomous Database. |
</Accordion>
<Accordion title="AlibabaCloud MySQL">
| Variable | Default | Description |
| ----------------------------------- | -------------- | ------------------------- |
| `ALIBABACLOUD_MYSQL_HOST` | `127.0.0.1` | Hostname. |
| `ALIBABACLOUD_MYSQL_PORT` | `3306` | Port number. |
| `ALIBABACLOUD_MYSQL_USER` | `root` | Username. |
| `ALIBABACLOUD_MYSQL_PASSWORD` | `difyai123456` | Password. |
| `ALIBABACLOUD_MYSQL_DATABASE` | `dify` | Database name. |
| `ALIBABACLOUD_MYSQL_MAX_CONNECTION` | `5` | Maximum pool connections. |
| `ALIBABACLOUD_MYSQL_HNSW_M` | `6` | HNSW M parameter. |
</Accordion>
<Accordion title="Relyt">
| Variable | Default | Description |
| ---------------- | -------------- | -------------- |
| `RELYT_HOST` | `db` | Hostname. |
| `RELYT_PORT` | `5432` | Port number. |
| `RELYT_USER` | `postgres` | Username. |
| `RELYT_PASSWORD` | `difyai123456` | Password. |
| `RELYT_DATABASE` | `postgres` | Database name. |
</Accordion>
<Accordion title="OpenSearch">
| Variable | Default | Description |
| ------------------------- | ---------------- | -------------------------------------------------------------------------------------------------------------------------------------------------- |
| `OPENSEARCH_HOST` | `opensearch` | Hostname. |
| `OPENSEARCH_PORT` | `9200` | Port number. |
| `OPENSEARCH_SECURE` | `true` | Use HTTPS. |
| `OPENSEARCH_VERIFY_CERTS` | `true` | Verify SSL certificates. |
| `OPENSEARCH_AUTH_METHOD` | `basic` | `basic` uses username/password. `aws_managed_iam` uses AWS SigV4 request signing via Boto3 credentials (for AWS Managed OpenSearch or Serverless). |
| `OPENSEARCH_USER` | `admin` | Username. Only used with `basic` auth. |
| `OPENSEARCH_PASSWORD` | `admin` | Password. Only used with `basic` auth. |
| `OPENSEARCH_AWS_REGION` | `ap-southeast-1` | AWS region. Only used with `aws_managed_iam` auth. |
| `OPENSEARCH_AWS_SERVICE` | `aoss` | AWS service type: `es` (Managed Cluster) or `aoss` (OpenSearch Serverless). Only used with `aws_managed_iam` auth. |
</Accordion>
<Accordion title="Tencent Cloud VectorDB">
| Variable | Default | Description |
| ---------------------------------------- | ------------------ | --------------------------------------------------------------------------------------------------- |
| `TENCENT_VECTOR_DB_URL` | `http://127.0.0.1` | Access address. [Console](https://console.cloud.tencent.com/vdb). |
| `TENCENT_VECTOR_DB_API_KEY` | `dify` | API key. [Key Management](https://cloud.tencent.com/document/product/1709/95108). |
| `TENCENT_VECTOR_DB_TIMEOUT` | `30` | Request timeout in seconds. |
| `TENCENT_VECTOR_DB_USERNAME` | `dify` | Account name. [Account Management](https://cloud.tencent.com/document/product/1709/115833). |
| `TENCENT_VECTOR_DB_DATABASE` | `dify` | Database name. [Create Database](https://cloud.tencent.com/document/product/1709/95822). |
| `TENCENT_VECTOR_DB_SHARD` | `1` | Number of shards. |
| `TENCENT_VECTOR_DB_REPLICAS` | `2` | Number of replicas. |
| `TENCENT_VECTOR_DB_ENABLE_HYBRID_SEARCH` | `false` | Enable hybrid search. [Sparse Vector docs](https://cloud.tencent.com/document/product/1709/110110). |
</Accordion>
<Accordion title="Elasticsearch">
| Variable | Default | Description |
| -------------------------------- | --------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| `ELASTICSEARCH_HOST` | `0.0.0.0` | Hostname. |
| `ELASTICSEARCH_PORT` | `9200` | Port number. |
| `ELASTICSEARCH_USERNAME` | `elastic` | Username. |
| `ELASTICSEARCH_PASSWORD` | `elastic` | Password. |
| `ELASTICSEARCH_USE_CLOUD` | `false` | Switch to Elastic Cloud mode. When `true`, uses `ELASTICSEARCH_CLOUD_URL` and `ELASTICSEARCH_API_KEY` instead of host/port/username/password. |
| `ELASTICSEARCH_CLOUD_URL` | (empty) | Elastic Cloud endpoint URL. Required when `ELASTICSEARCH_USE_CLOUD=true`. |
| `ELASTICSEARCH_API_KEY` | (empty) | Elastic Cloud API key. Required when `ELASTICSEARCH_USE_CLOUD=true`. |
| `ELASTICSEARCH_VERIFY_CERTS` | `false` | Verify SSL certificates. |
| `ELASTICSEARCH_CA_CERTS` | (empty) | Path to CA certificates. |
| `ELASTICSEARCH_REQUEST_TIMEOUT` | `100000` | Request timeout in milliseconds. |
| `ELASTICSEARCH_RETRY_ON_TIMEOUT` | `true` | Retry on timeout. |
| `ELASTICSEARCH_MAX_RETRIES` | `10` | Maximum retry attempts. |
</Accordion>
<Accordion title="Baidu Vector DB">
| Variable | Default | Description |
| ------------------------------------------------------ | ----------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `BAIDU_VECTOR_DB_ENDPOINT` | `http://127.0.0.1:5287` | Endpoint URL. |
| `BAIDU_VECTOR_DB_CONNECTION_TIMEOUT_MS` | `30000` | Connection timeout in milliseconds. |
| `BAIDU_VECTOR_DB_ACCOUNT` | `root` | Account name. |
| `BAIDU_VECTOR_DB_API_KEY` | `dify` | API key. |
| `BAIDU_VECTOR_DB_DATABASE` | `dify` | Database name. |
| `BAIDU_VECTOR_DB_SHARD` | `1` | Number of shards. |
| `BAIDU_VECTOR_DB_REPLICAS` | `3` | Number of replicas. |
| `BAIDU_VECTOR_DB_INVERTED_INDEX_ANALYZER` | `DEFAULT_ANALYZER` | Inverted index analyzer. |
| `BAIDU_VECTOR_DB_INVERTED_INDEX_PARSER_MODE` | `COARSE_MODE` | Inverted index parser mode. |
| `BAIDU_VECTOR_DB_AUTO_BUILD_ROW_COUNT_INCREMENT` | `500` | Absolute row-count increment that triggers an automatic index rebuild on the Baidu Vector DB side. Works alongside `_RATIO`; whichever threshold is crossed first wins. |
| `BAIDU_VECTOR_DB_AUTO_BUILD_ROW_COUNT_INCREMENT_RATIO` | `0.05` | Relative growth (new rows / existing rows) that triggers an automatic index rebuild. Whichever threshold is crossed first wins. |
| `BAIDU_VECTOR_DB_REBUILD_INDEX_TIMEOUT_IN_SECONDS` | `300` | Maximum time the client waits for an index rebuild to complete. On timeout, the client call fails but the server-side rebuild may still finish; retrying the query after a delay typically succeeds. |
</Accordion>
<Accordion title="VikingDB">
| Variable | Default | Description |
| ----------------------------- | ----------------------------- | ----------------------------------------------------- |
| `VIKINGDB_ACCESS_KEY` | (empty) | Access key. |
| `VIKINGDB_SECRET_KEY` | (empty) | Secret key. |
| `VIKINGDB_REGION` | `cn-shanghai` | Region. |
| `VIKINGDB_HOST` | `api-vikingdb.xxx.volces.com` | API host. Replace with your region-specific endpoint. |
| `VIKINGDB_SCHEME` | `http` | Protocol scheme (`http` or `https`). |
| `VIKINGDB_CONNECTION_TIMEOUT` | `30` | Connection timeout in seconds. |
| `VIKINGDB_SOCKET_TIMEOUT` | `30` | Socket timeout in seconds. |
</Accordion>
<Accordion title="Lindorm">
| Variable | Default | Description |
| ----------------------- | ------------------------ | -------------------------------------------------------------------------- |
| `LINDORM_URL` | `http://localhost:30070` | Lindorm search engine URL. [Console](https://lindorm.console.aliyun.com/). |
| `LINDORM_USERNAME` | `admin` | Username. |
| `LINDORM_PASSWORD` | `admin` | Password. |
| `LINDORM_USING_UGC` | `true` | Use UGC mode. |
| `LINDORM_QUERY_TIMEOUT` | `1` | Query timeout in seconds. |
</Accordion>
<Accordion title="OpenGauss">
| Variable | Default | Description |
| -------------------------- | ----------- | ------------------------- |
| `OPENGAUSS_HOST` | `opengauss` | Hostname. |
| `OPENGAUSS_PORT` | `6600` | Port number. |
| `OPENGAUSS_USER` | `postgres` | Username. |
| `OPENGAUSS_PASSWORD` | `Dify@123` | Password. |
| `OPENGAUSS_DATABASE` | `dify` | Database name. |
| `OPENGAUSS_MIN_CONNECTION` | `1` | Minimum pool connections. |
| `OPENGAUSS_MAX_CONNECTION` | `5` | Maximum pool connections. |
| `OPENGAUSS_ENABLE_PQ` | `false` | Enable PQ acceleration. |
</Accordion>
<Accordion title="Huawei Cloud Search">
| Variable | Default | Description |
| ----------------------- | ------------------------ | --------------------- |
| `HUAWEI_CLOUD_HOSTS` | `https://127.0.0.1:9200` | Cluster endpoint URL. |
| `HUAWEI_CLOUD_USER` | `admin` | Username. |
| `HUAWEI_CLOUD_PASSWORD` | `admin` | Password. |
</Accordion>
<Accordion title="Upstash Vector">
| Variable | Default | Description |
| ---------------------- | ------- | ---------------------------- |
| `UPSTASH_VECTOR_URL` | (empty) | Upstash Vector endpoint URL. |
| `UPSTASH_VECTOR_TOKEN` | (empty) | Upstash Vector API token. |
</Accordion>
<Accordion title="TableStore">
| Variable | Default | Description |
| ------------------------------------------ | ---------------------------------------------------- | ------------------------------------------------------------- |
| `TABLESTORE_ENDPOINT` | `https://instance-name.cn-hangzhou.ots.aliyuncs.com` | Endpoint address. Replace `instance-name` with your instance. |
| `TABLESTORE_INSTANCE_NAME` | (empty) | Instance name. |
| `TABLESTORE_ACCESS_KEY_ID` | (empty) | Access key ID. |
| `TABLESTORE_ACCESS_KEY_SECRET` | (empty) | Access key secret. |
| `TABLESTORE_NORMALIZE_FULLTEXT_BM25_SCORE` | `false` | Normalize fulltext BM25 scores. |
</Accordion>
<Accordion title="ClickZetta">
| Variable | Default | Description |
| ------------------------------------- | -------------------- | -------------------------- |
| `CLICKZETTA_USERNAME` | (empty) | Username. |
| `CLICKZETTA_PASSWORD` | (empty) | Password. |
| `CLICKZETTA_INSTANCE` | (empty) | Instance name. |
| `CLICKZETTA_SERVICE` | `api.clickzetta.com` | Service endpoint. |
| `CLICKZETTA_WORKSPACE` | `quick_start` | Workspace name. |
| `CLICKZETTA_VCLUSTER` | `default_ap` | Virtual cluster. |
| `CLICKZETTA_SCHEMA` | `dify` | Schema name. |
| `CLICKZETTA_BATCH_SIZE` | `100` | Batch size for operations. |
| `CLICKZETTA_ENABLE_INVERTED_INDEX` | `true` | Enable inverted index. |
| `CLICKZETTA_ANALYZER_TYPE` | `chinese` | Analyzer type. |
| `CLICKZETTA_ANALYZER_MODE` | `smart` | Analyzer mode. |
| `CLICKZETTA_VECTOR_DISTANCE_FUNCTION` | `cosine_distance` | Distance function. |
</Accordion>
<Accordion title="InterSystems IRIS">
| Variable | Default | Description |
| -------------------------- | ----------- | ---------------------------------------------------- |
| `IRIS_HOST` | `iris` | Hostname. |
| `IRIS_SUPER_SERVER_PORT` | `1972` | Super server port. |
| `IRIS_USER` | `_SYSTEM` | Username. |
| `IRIS_PASSWORD` | `Dify@1234` | Password. |
| `IRIS_DATABASE` | `USER` | Database name. |
| `IRIS_SCHEMA` | `dify` | Schema name. |
| `IRIS_CONNECTION_URL` | (empty) | Full connection URL (overrides individual settings). |
| `IRIS_MIN_CONNECTION` | `1` | Minimum pool connections. |
| `IRIS_MAX_CONNECTION` | `3` | Maximum pool connections. |
| `IRIS_TEXT_INDEX` | `true` | Enable text indexing. |
| `IRIS_TEXT_INDEX_LANGUAGE` | `en` | Text index language. |
</Accordion>
</AccordionGroup>
### Knowledge Configuration
| Variable | Default | Description |
| ----------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `UPLOAD_FILE_SIZE_LIMIT` | `15` | Maximum file size in MB for document uploads (PDFs, Word docs, etc.). Users see a "file too large" error when exceeded. Does not apply to images, videos, or audio—they have separate limits below. |
| `UPLOAD_FILE_BATCH_LIMIT` | `5` | Maximum number of files the frontend allows per upload batch. |
| `UPLOAD_FILE_EXTENSION_BLACKLIST` | (empty) | Security blocklist of file extensions that cannot be uploaded. Comma-separated, lowercase, no dots. Example: `exe,bat,cmd,com,scr,vbs,ps1,msi,dll`. Empty allows all types. |
| `SINGLE_CHUNK_ATTACHMENT_LIMIT` | `10` | Maximum number of images that can be embedded in a single knowledge base segment (chunk). |
| `IMAGE_FILE_BATCH_LIMIT` | `10` | Maximum number of image files per upload batch. |
| `ATTACHMENT_IMAGE_FILE_SIZE_LIMIT` | `2` | Maximum size in MB for images fetched from external URLs during knowledge base indexing. Images larger than this are skipped. Different from `UPLOAD_IMAGE_FILE_SIZE_LIMIT` which applies to direct uploads. |
| `ATTACHMENT_IMAGE_DOWNLOAD_TIMEOUT` | `60` | Timeout in seconds when downloading images from external URLs during knowledge base indexing. Slow or unresponsive image servers are abandoned after this timeout. |
| `ETL_TYPE` | `dify` | Document extraction library. `dify` supports txt, md, pdf, html, xlsx, docx, csv. `Unstructured` adds support for doc, msg, eml, ppt, pptx, xml, epub (requires `UNSTRUCTURED_API_URL`). |
| `UNSTRUCTURED_API_URL` | (empty) | Unstructured.io API endpoint. Required when `ETL_TYPE` is `Unstructured`. Also needed for `.ppt` file support. Example: `http://unstructured:8000/general/v0/general`. |
| `UNSTRUCTURED_API_KEY` | (empty) | API key for Unstructured.io authentication. |
| `SCARF_NO_ANALYTICS` | `true` | Disable Unstructured library's telemetry/analytics collection. |
| `TOP_K_MAX_VALUE` | `10` | Maximum value users can set for the `top_k` parameter in knowledge base retrieval (how many results to return per search). |
| `DATASET_MAX_SEGMENTS_PER_REQUEST` | `0` | Maximum number of segments per dataset API request. `0` means unlimited. |
#### Annotation Import
| Variable | Default | Description |
| ----------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------- |
| `ANNOTATION_IMPORT_FILE_SIZE_LIMIT` | `2` | Maximum CSV file size in MB for annotation import. Returns HTTP 413 when exceeded. |
| `ANNOTATION_IMPORT_MAX_RECORDS` | `10000` | Maximum number of records per annotation import. Files with more records must be split into batches. |
| `ANNOTATION_IMPORT_MIN_RECORDS` | `1` | Minimum number of valid records required per annotation import. |
| `ANNOTATION_IMPORT_RATE_LIMIT_PER_MINUTE` | `5` | Maximum annotation import requests per minute per workspace. Returns HTTP 429 when exceeded. |
| `ANNOTATION_IMPORT_RATE_LIMIT_PER_HOUR` | `20` | Maximum annotation import requests per hour per workspace. |
| `ANNOTATION_IMPORT_MAX_CONCURRENT` | `5` | Maximum concurrent annotation import tasks per workspace. Stale tasks are auto-cleaned after 2 minutes. |
### Model Configuration
| Variable | Default | Description |
| ------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------- |
| `PLUGIN_BASED_TOKEN_COUNTING_ENABLED` | `false` | Use plugin-based token counting for accurate usage tracking. When disabled, token counting returns 0 (faster but cost tracking is less accurate). |
### Multi-modal Configuration
| Variable | Default | Description |
| ------------------------------ | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `MULTIMODAL_SEND_FORMAT` | `base64` | How files are sent to multi-modal LLMs. `base64` embeds file data in the request (more compatible, works offline, larger payloads). `url` sends a signed URL for the model to fetch (faster, smaller requests, but the model must be able to reach `FILES_URL`). |
| `UPLOAD_IMAGE_FILE_SIZE_LIMIT` | `10` | Maximum image file size in MB for direct uploads (jpg, png, webp, gif, svg). |
| `UPLOAD_VIDEO_FILE_SIZE_LIMIT` | `100` | Maximum video file size in MB for direct uploads (mp4, mov, mpeg, webm). |
| `UPLOAD_AUDIO_FILE_SIZE_LIMIT` | `50` | Maximum audio file size in MB for direct uploads (mp3, m4a, wav, amr, mpga). |
<Note>
All upload size limits are also gated by `NGINX_CLIENT_MAX_BODY_SIZE` (default `100M`). If you increase any upload limit above 100 MB, also increase `NGINX_CLIENT_MAX_BODY_SIZE` to match—otherwise Nginx rejects the upload with a 413 error.
</Note>
### Sentry Configuration
Sentry provides error tracking and performance monitoring. Each service has its own DSN to separate error reporting.
| Variable | Default | Description |
| --------------------------------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `SENTRY_DSN` | (empty) | Sentry DSN shared across services. |
| `API_SENTRY_DSN` | (empty) | Sentry DSN for the API service. Overrides `SENTRY_DSN` if set. Empty disables Sentry for the backend. |
| `API_SENTRY_TRACES_SAMPLE_RATE` | `1.0` | Fraction of requests to include in performance tracing (0.01 = 1%, 1.0 = 100%). Traces track request flow across services. |
| `API_SENTRY_PROFILES_SAMPLE_RATE` | `1.0` | Fraction of requests to include in CPU/memory profiling (0.01 = 1%). Profiles show where time is spent in code. |
| `SENTRY_TRACES_SAMPLE_RATE` | `1.0` | Direct name for `API_SENTRY_TRACES_SAMPLE_RATE`, used by the config files under `docker/envs/core-services/`.<br />In the Compose stack the `API_SENTRY_*` value wins. No effect while the Sentry DSN is empty. |
| `SENTRY_PROFILES_SAMPLE_RATE` | `1.0` | Direct name for `API_SENTRY_PROFILES_SAMPLE_RATE`, used by the same config files.<br />Profiling only samples requests already selected by the traces rate, so effective volume is traces rate × profiles rate. |
| `WEB_SENTRY_DSN` | (empty) | Sentry DSN for the web frontend (Next.js). Frontend-only. |
| `PLUGIN_SENTRY_ENABLED` | `false` | Enable Sentry for the plugin daemon service. |
| `PLUGIN_SENTRY_DSN` | (empty) | Sentry DSN for the plugin daemon. |
### Notion Integration Configuration
Connect Dify to Notion as a knowledge base data source. Get integration credentials at [https://www.notion.so/my-integrations](https://www.notion.so/my-integrations).
| Variable | Default | Description |
| ------------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `NOTION_INTEGRATION_TYPE` | `public` | `public` uses standard OAuth 2.0 (requires HTTPS redirect URL, needs CLIENT\_ID + CLIENT\_SECRET). `internal` uses a direct integration token (works with HTTP). Use `internal` for local deployments. |
| `NOTION_CLIENT_SECRET` | (empty) | OAuth client secret. Required for `public` integration. |
| `NOTION_CLIENT_ID` | (empty) | OAuth client ID. Required for `public` integration. |
| `NOTION_INTERNAL_SECRET` | (empty) | Direct integration token from Notion. Required for `internal` integration. |
### Mail Configuration
Dify sends emails for account invitations, password resets, login codes, and Human Input node notifications. Configure one of the three supported providers. Email links require `CONSOLE_WEB_URL` to be set—see [Common Variables](#console_web_url).
| Variable | Default | Description |
| ------------------------ | -------- | --------------------------------------------------------- |
| `MAIL_TYPE` | `resend` | Mail provider: `resend`, `smtp`, or `sendgrid`. |
| `MAIL_DEFAULT_SEND_FROM` | (empty) | Default "From" address for all outgoing emails. Required. |
<AccordionGroup>
<Accordion title="Resend">
| Variable | Default | Description |
| ---------------- | ------------------------ | -------------------------------------------------------------- |
| `RESEND_API_URL` | `https://api.resend.com` | Resend API endpoint. Override for self-hosted Resend or proxy. |
| `RESEND_API_KEY` | (empty) | Resend API key. Required when `MAIL_TYPE=resend`. |
</Accordion>
<Accordion title="SMTP">
Three TLS modes: implicit TLS (`SMTP_USE_TLS=true`, `SMTP_OPPORTUNISTIC_TLS=false`, port 465), STARTTLS (`SMTP_USE_TLS=true`, `SMTP_OPPORTUNISTIC_TLS=true`, port 587), or plain (`SMTP_USE_TLS=false`, port 25).
| Variable | Default | Description |
| ------------------------ | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `SMTP_SERVER` | (empty) | SMTP server address. |
| `SMTP_PORT` | `465` | SMTP server port. Use `587` for STARTTLS mode. |
| `SMTP_USERNAME` | (empty) | SMTP username. Can be empty for IP-whitelisted servers. |
| `SMTP_PASSWORD` | (empty) | SMTP password. Can be empty for IP-whitelisted servers. |
| `SMTP_USE_TLS` | `true` | Enable TLS. When `true` with `SMTP_OPPORTUNISTIC_TLS=false`, uses implicit TLS (`SMTP_SSL`). |
| `SMTP_OPPORTUNISTIC_TLS` | `false` | Use STARTTLS (explicit TLS) instead of implicit TLS. Must be used with `SMTP_USE_TLS=true`. |
| `SMTP_LOCAL_HOSTNAME` | (empty) | Override the hostname sent in SMTP HELO/EHLO. Required in Docker when your SMTP server rejects container hostnames (common with Google Workspace, Microsoft 365). Set to your domain, e.g., `mail.yourdomain.com`. |
</Accordion>
<Accordion title="SendGrid">
| Variable | Default | Description |
| ------------------ | ------- | ----------------------------------------------------- |
| `SENDGRID_API_KEY` | (empty) | SendGrid API key. Required when `MAIL_TYPE=sendgrid`. |
For more details, see the [SendGrid documentation](https://www.twilio.com/docs/sendgrid/for-developers/sending-email/api-getting-started).
</Accordion>
</AccordionGroup>
### Other Configuration
#### Console Features
| Variable | Default | Description |
| ------------------ | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `ENABLE_LEARN_APP` | `true` | Shows the Learn Dify section: tutorial templates on the Explore page, the getting-started panel when Studio has no apps, and its show/hide toggle in the help menu.<br /><br />Set to `false` to hide all three. |
| `ENABLE_SKILL` | `true` | Shows the [Skills](/en/self-host/use-dify/build/skills) entry in the main navigation.<br /><br />Set to `false` to hide skills from the workspace UI. |
#### Authentication and Accounts
By default, sign-in is email + password, and new accounts come from workspace invitations or the initial setup wizard. The toggles below relax or tighten that.
| Variable | Default | Description |
| --------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `ENABLE_EMAIL_PASSWORD_LOGIN` | `true` | Sign in to the console with email and password. When disabled, the password form disappears from the sign-in page and the password login, password reset, and self-serve signup endpoints all return 403. Keep at least one sign-in method enabled—if every method is off, the sign-in page shows "Authentication method not configured" and no one can log in until you change the setting back. |
| `ENABLE_EMAIL_CODE_LOGIN` | `false` | Sign in with a one-time 6-digit code sent by email instead of a password. Requires mail delivery to be configured (see [Mail Configuration](#mail-configuration))—without it, codes are never delivered. With `ALLOW_REGISTER=true`, entering a code for an unknown email also creates the account, so this doubles as a self-serve signup path. |
| `EMAIL_CODE_LOGIN_TOKEN_EXPIRY_MINUTES` | `5` | How long a sign-in code stays valid (in minutes). An expired code is rejected; request a new one to continue. |
| `EMAIL_CODE_LOGIN_MAX_ATTEMPTS` | `5` | How many wrong entries one sign-in code survives before it is invalidated and a new code must be requested. |
| `ENABLE_SOCIAL_OAUTH_LOGIN` | `false` | Shows GitHub and Google sign-in buttons on the console sign-in page. The buttons only work if the matching GitHub or Google OAuth app credentials are also configured on the API service; with the flag on but no credentials, sign-in attempts fail. First-time OAuth sign-ins create an account only when `ALLOW_REGISTER=true`. |
| `ALLOW_REGISTER` | `false` | Lets people create their own accounts: shows the sign-up link on the sign-in page (with password login enabled) and allows first-time email-code or OAuth sign-ins to create accounts. Leave `false` for an invite-only deployment—workspace invitations and the initial setup wizard always work regardless. |
| `ALLOW_CREATE_WORKSPACE` | `false` | Automatically creates a workspace for an account that doesn't belong to one—during self-serve registration and at email-code or OAuth sign-in. When `false`, such accounts must wait for a workspace invitation. The admin workspace created by the setup wizard is unaffected. |
| `ENABLE_CHANGE_EMAIL` | `true` | Lets users change their account's email address from the account settings page. The flow confirms the change with emailed verification codes, so it requires mail delivery to be configured. Set to `false` to lock account emails, e.g. when they must match an external directory. |
#### LLMOps Trace Delivery
Traces of app runs are delivered to the configured LLMOps provider (Langfuse, LangSmith, Arize/Phoenix, and so on) by a background task. These variables govern its retries on transient failures.
| Variable | Default | Description |
| -------------------------------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `OPS_TRACE_RETRYABLE_DISPATCH_MAX_RETRIES` | `780` | How many times a trace delivery is retried after a transient failure before the trace is dropped. <br /><br />The default retry window (retries × `OPS_TRACE_RETRYABLE_DISPATCH_DELAY_SECONDS`) is sized to outlast the one-hour workflow limit plus the export grace period. <br /><br />Today only Arize/Phoenix tracing of nested workflows hits this path (a child trace arriving before its parent's context). Cannot be `0`. |
| `OPS_TRACE_RETRYABLE_DISPATCH_DELAY_SECONDS` | `5` | Seconds between those retries; the total tolerance window is delay × max retries (about 65 minutes at defaults).<br /><br />Lower delivers nested traces sooner but exhausts the retry budget faster. Cannot be `0`. |
| `OPS_TRACE_PARENT_CONTEXT_TTL_SECONDS` | `3900` | How long in seconds a parent workflow's trace context stays available for nested child traces to attach to.<br /><br />Keep it at or above the retry window (retries × delay). |
#### Indexing
| Variable | Default | Description |
| ----------------------------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `INDEXING_MAX_SEGMENTATION_TOKENS_LENGTH` | `4000` | Maximum token length per text segment when chunking documents for the knowledge base. Larger values retain more context per chunk; smaller values provide finer granularity. |
#### New User Defaults
| Variable | Default | Description |
| ----------------------------- | ------- | ------------------------------------------------------------------------------------------------- |
| `NEW_USER_DEFAULT_PLUGIN_IDS` | (empty) | Comma-separated Marketplace plugin IDs installed automatically when a new workspace is created. |
| `NEW_USER_DEFAULT_MODELS` | (empty) | Default models set up for a new workspace, comma-separated in `model_type:provider:model` format. |
#### Workflow Generation
| Variable | Default | Description |
| --------------------------------------------- | -------- | --------------------------------------------------------------------------------------------------- |
| `WORKFLOW_GENERATION_TIMEOUT_MS` | `180000` | How long the UI waits for one `/create` or `/refine` app generation run. Read by the web container. |
| `WORKFLOW_GENERATOR_NODE_BUILDER_MAX_WORKERS` | `6` | Maximum concurrent node-builder LLM calls per `/create` or `/refine` generation request. |
#### Token & Invitation
All token expiry variables control how long a one-time-use token stored in Redis remains valid. After expiry, the user must request a new token.
| Variable | Default | Description |
| ------------------------------------- | ------- | ------------------------------------------------------------ |
| `INVITE_EXPIRY_HOURS` | `72` | How long a workspace invitation link stays valid (in hours). |
| `RESET_PASSWORD_TOKEN_EXPIRY_MINUTES` | `5` | Password reset token validity in minutes. |
| `EMAIL_REGISTER_TOKEN_EXPIRY_MINUTES` | `5` | Email registration token validity in minutes. |
| `CHANGE_EMAIL_TOKEN_EXPIRY_MINUTES` | `5` | Change email token validity in minutes. |
| `OWNER_TRANSFER_TOKEN_EXPIRY_MINUTES` | `5` | Workspace owner transfer token validity in minutes. |
#### Code Execution Sandbox
These settings tell the API and Worker how to connect to the sandbox, a separate service that executes Code node (Python, JavaScript) and Template Transform (Jinja2) code in isolation.
| Variable | Default | Description |
| ----------------------------------------------- | --------------------- | ------------------------------------------------------------------------------------------ |
| `CODE_EXECUTION_ENDPOINT` | `http://sandbox:8194` | Sandbox service endpoint. |
| `CODE_EXECUTION_API_KEY` | `dify-sandbox` | API key for sandbox authentication. Must match `SANDBOX_API_KEY` in the sandbox service. |
| `CODE_EXECUTION_SSL_VERIFY` | `true` | Verify SSL for sandbox connections. Disable for development with self-signed certificates. |
| `CODE_EXECUTION_CONNECT_TIMEOUT` | `10` | Connection timeout in seconds. |
| `CODE_EXECUTION_READ_TIMEOUT` | `60` | Read timeout in seconds. |
| `CODE_EXECUTION_WRITE_TIMEOUT` | `10` | Write timeout in seconds. |
| `CODE_EXECUTION_POOL_MAX_CONNECTIONS` | `100` | Maximum concurrent HTTP connections to the sandbox service. |
| `CODE_EXECUTION_POOL_MAX_KEEPALIVE_CONNECTIONS` | `20` | Maximum idle connections kept alive in the sandbox connection pool. |
| `CODE_EXECUTION_POOL_KEEPALIVE_EXPIRY` | `5.0` | Seconds before idle sandbox connections are closed. |
#### Code and Template Output Limits
The API and Worker apply these limits to the output returned by Code and Template Transform nodes; the sandbox service does not read them. Changes take effect after you restart the API and Worker, not the sandbox.
| Variable | Default | Description |
| ------------------------------- | ---------------------- | ------------------------------------------------------------------------------------------------------- |
| `CODE_MAX_NUMBER` | `9223372036854775807` | Maximum numeric value allowed in Code node output (max 64-bit signed integer). |
| `CODE_MIN_NUMBER` | `-9223372036854775808` | Minimum numeric value allowed in Code node output (min 64-bit signed integer). |
| `CODE_MAX_STRING_LENGTH` | `400000` | Maximum string length in Code node output. Prevents memory exhaustion from unbounded string generation. |
| `CODE_MAX_DEPTH` | `5` | Maximum nesting depth for output data structures. |
| `CODE_MAX_PRECISION` | `20` | Maximum decimal places for floating-point numbers in output. |
| `CODE_MAX_STRING_ARRAY_LENGTH` | `30` | Maximum number of elements in a string array output. |
| `CODE_MAX_OBJECT_ARRAY_LENGTH` | `30` | Maximum number of elements in an object array output. |
| `CODE_MAX_NUMBER_ARRAY_LENGTH` | `1000` | Maximum number of elements in a number array output. |
| `TEMPLATE_TRANSFORM_MAX_LENGTH` | `400000` | Maximum character length for Template Transform node output. |
#### Workflow Runtime
| Variable | Default | Description |
| --------------------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `WORKFLOW_MAX_EXECUTION_STEPS` | `500` | Maximum number of node executions per workflow run. Exceeding this terminates the workflow. |
| `WORKFLOW_MAX_EXECUTION_TIME` | `3600` | Maximum wall-clock time in seconds per workflow run. Exceeding this terminates the workflow.<br /><br />An outer limit paired with `APP_MAX_EXECUTION_TIME` (both default to one hour): increase both together. If you run agents, keep them at or above the agent run deadline (`DIFY_AGENT_RUN_TIMEOUT_SECONDS`). |
| `WORKFLOW_CALL_MAX_DEPTH` | `5` | Maximum depth for nested workflow-calls-workflow. Prevents infinite recursion. |
| `MAX_VARIABLE_SIZE` | `204800` | Maximum size in bytes (200 KB) for a single workflow variable. |
| `WORKFLOW_FILE_UPLOAD_LIMIT` | `10` | Upper bound for the max-files setting on a single file-upload field (e.g., a User Input File List). The node panel's max-files slider is capped at this value; raise to allow larger per-field configurations. |
| `WORKFLOW_NODE_EXECUTION_STORAGE` | `rdbms` | Where workflow node execution records are stored. `rdbms` stores everything in the database. `hybrid` stores new data in object storage and reads from both. |
| `DSL_EXPORT_ENCRYPT_DATASET_ID` | `true` | Encrypt dataset IDs when exporting DSL files. Set to `false` to export plain IDs for easier cross-environment import. |
#### Workflow Storage Repository
These select which backend implementation handles workflow execution data. The default `SQLAlchemy` repositories store everything in the database. Alternative implementations (e.g., Celery, Logstore) can be used for different storage strategies.
| Variable | Default | Description |
| ----------------------------------------- | ----------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------- |
| `CORE_WORKFLOW_EXECUTION_REPOSITORY` | `core.repositories.sqlalchemy_workflow_execution_repository.SQLAlchemyWorkflowExecutionRepository` | Repository implementation for workflow execution records. |
| `CORE_WORKFLOW_NODE_EXECUTION_REPOSITORY` | `core.repositories.sqlalchemy_workflow_node_execution_repository.SQLAlchemyWorkflowNodeExecutionRepository` | Repository implementation for workflow node execution records. |
| `API_WORKFLOW_RUN_REPOSITORY` | `repositories.sqlalchemy_api_workflow_run_repository.DifyAPISQLAlchemyWorkflowRunRepository` | Service-layer repository for workflow run API operations. |
| `API_WORKFLOW_NODE_EXECUTION_REPOSITORY` | `repositories.sqlalchemy_api_workflow_node_execution_repository.DifyAPISQLAlchemyWorkflowNodeExecutionRepository` | Service-layer repository for workflow node execution API operations. |
| `LOOP_NODE_MAX_COUNT` | `100` | Maximum iterations for Loop nodes. Prevents infinite loops. |
| `MAX_PARALLEL_LIMIT` | `10` | Maximum number of parallel branches in a workflow. |
#### GraphEngine Worker Pool
| Variable | Default | Description |
| ----------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `GRAPH_ENGINE_MIN_WORKERS` | `3` | Minimum workers per GraphEngine instance. |
| `GRAPH_ENGINE_MAX_WORKERS` | `10` | Maximum workers per GraphEngine instance. |
| `GRAPH_ENGINE_SCALE_UP_THRESHOLD` | `0` | How many tasks may wait for a free worker before the pool adds another, up to `GRAPH_ENGINE_MAX_WORKERS`.<br /><br />At the default `0`, a worker is added as soon as any task waits; raise it to tolerate short backlogs before scaling up. |
| `GRAPH_ENGINE_SCALE_DOWN_IDLE_TIME` | `5.0` | Seconds of idle time before excess workers are removed. |
#### Workflow Log Cleanup
| Variable | Default | Description |
| -------------------------------------------- | ------- | ---------------------------------------------------------------------------------------------------- |
| `WORKFLOW_LOG_CLEANUP_ENABLED` | `false` | Enable automatic cleanup of workflow execution logs at 2:00 AM daily. |
| `WORKFLOW_LOG_RETENTION_DAYS` | `30` | Number of days to retain workflow logs before cleanup. |
| `WORKFLOW_LOG_CLEANUP_BATCH_SIZE` | `100` | Number of log entries processed per cleanup batch. Adjust based on system performance. |
| `WORKFLOW_LOG_CLEANUP_SPECIFIC_WORKFLOW_IDS` | (empty) | Comma-separated list of workflow IDs to limit cleanup to. When empty, all workflow logs are cleaned. |
#### HTTP Request Node
These configure the HTTP Request node used in workflows to call external APIs.
| Variable | Default | Description |
| ----------------------------------- | ---------- | ---------------------------------------------------------------------------------------------------------------- |
| `HTTP_REQUEST_NODE_MAX_TEXT_SIZE` | `1048576` | Maximum text response size in bytes (1 MB). Responses larger than this are truncated. |
| `HTTP_REQUEST_NODE_MAX_BINARY_SIZE` | `10485760` | Maximum binary response size in bytes (10 MB). |
| `HTTP_REQUEST_NODE_SSL_VERIFY` | `true` | Verify SSL certificates. Disable for testing with self-signed certificates. |
| `HTTP_REQUEST_MAX_CONNECT_TIMEOUT` | `10` | Maximum connect timeout users can set in the workflow editor (in seconds). Per-node timeouts cannot exceed this. |
| `HTTP_REQUEST_MAX_READ_TIMEOUT` | `600` | Maximum read timeout ceiling (in seconds). |
| `HTTP_REQUEST_MAX_WRITE_TIMEOUT` | `600` | Maximum write timeout ceiling (in seconds). |
#### Webhook
| Variable | Default | Description |
| ------------------------------- | ---------- | --------------------------------------------------------------------------------------------- |
| `WEBHOOK_REQUEST_BODY_MAX_SIZE` | `10485760` | Maximum webhook payload size in bytes (10 MB). Larger payloads are rejected with a 413 error. |
#### SSRF Protection
All outbound HTTP requests from Dify (HTTP nodes, image downloads, etc.) are routed through a proxy that blocks requests to internal/private IP ranges, preventing Server-Side Request Forgery (SSRF) attacks.
| Variable | Default | Description |
| ------------------------------------- | ------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| `SSRF_PROXY_HTTP_URL` | `http://ssrf_proxy:3128` | SSRF proxy URL for HTTP requests. |
| `SSRF_PROXY_HTTPS_URL` | `http://ssrf_proxy:3128` | SSRF proxy URL for HTTPS requests. |
| `SSRF_POOL_MAX_CONNECTIONS` | `100` | Maximum concurrent connections in the SSRF HTTP client pool. |
| `SSRF_POOL_MAX_KEEPALIVE_CONNECTIONS` | `20` | Maximum idle connections kept alive in the SSRF pool. |
| `SSRF_POOL_KEEPALIVE_EXPIRY` | `5.0` | Seconds before idle SSRF connections are closed. |
| `RESPECT_XFORWARD_HEADERS_ENABLED` | `false` | Trust X-Forwarded-For/Proto/Port headers from reverse proxies. Only enable behind a single trusted reverse proxy—otherwise allows IP spoofing. |
#### Agent Configuration
| Variable | Default | Description |
| -------------------- | ------- | -------------------------------------------------------------------------------- |
| `MAX_TOOLS_NUM` | `10` | Maximum number of tools an agent can use simultaneously. |
| `MAX_ITERATIONS_NUM` | `99` | Maximum reasoning iterations per agent execution. Prevents infinite agent loops. |
## Web Frontend Service
These variables are used by the Next.js web frontend container only, and do not affect the Python backend.
| Variable | Default | Description |
| -------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `TEXT_GENERATION_TIMEOUT_MS` | `60000` | Frontend timeout for streaming text generation UI. If a stream stalls for longer than this, the UI pauses rendering. |
| `ALLOW_INLINE_STYLES` | `false` | Allow inline `style` attributes and `<style>` blocks in user-generated Markdown content. Disabled by default for security (inline styles can be used for phishing). Enable only if you need rich styling from trusted content sources. |
| `ALLOW_UNSAFE_DATA_SCHEME` | `false` | Allow rendering URLs with the `data:` scheme. Disabled by default for security. |
| `MAX_TREE_DEPTH` | `50` | Maximum number of nodes along a single execution path. Longer paths cannot be published. Changes apply only to newly published workflows. |
| `MARKDOWN_FORM_FIELD_NAME_EXTRA_CHARS` | (empty) | Extra characters accepted in the `name` attributes of form fields that apps render from Markdown in chat responses.<br /><br />By default a field name must start with a letter and may contain letters, digits, underscores, and hyphens; fields whose names use other characters are not rendered.<br /><br />Set the additional characters as one string; both half-width and full-width characters work, e.g. `()!?`. |
### NEXT\_PUBLIC\_ENABLE\_FEATURE\_PREVIEW
Default: `true`
Enables the `/create` and `/refine` slash commands in the Go to Anything command palette, which generate and refine Workflow and Chatflow apps from a natural-language description. Set to `false` to hide them.
## Agent (New)
The new Agent runs as extra services in the Docker Compose deployment: an agent backend, a sandbox, and a dedicated egress proxy for the sandbox. All start automatically with `docker compose up`.
The feature is enabled by default, and most of its settings derive from your existing Compose values, so only the variables below usually need attention.
### DIFY\_AGENT\_SERVER\_SECRET\_KEY
Default: (development key pre-filled in `.env.example`; must be replaced for production)
Root secret the agent backend uses to derive the keys for its internal tokens, including the bearer tokens that authenticate the sandboxed agent's calls back into the backend.
A publicly known development key ships as the default, so the stack starts out of the box, but anyone who knows the key can forge those tokens. Replace it before production use.
The value must be unpadded base64url text that decodes to exactly 32 bytes; the agent backend refuses to start on a malformed value.
Generate one with:
```bash theme={null}
python3 -c "import secrets; print(secrets.token_urlsafe(32))"
```
### DIFY\_AGENT\_API\_TOKEN
Default: (development token pre-filled in `.env.example`; must be replaced for production)
Bearer token the Dify API presents when calling the agent backend's run API. Compose passes the same value to both services, so setting it once keeps them in agreement.
A publicly known development token ships as the default, so the stack starts out of the box—but anyone who can reach the agent backend and knows the token can start runs. Replace it with your own random value before production use.
### NEXT\_PUBLIC\_ENABLE\_AGENT\_V2
Default: `true`
Shows the new Agent in the web UI: the **Agents** item in the main navigation and the new Agent node in the workflow node picker.
Set to `false` to hide it and fall back to the classic Agent node. Replaces `ENABLE_AGENT_V2`, which still works as a fallback.
### UPLOAD\_SKILL\_FILE\_SIZE\_LIMIT
Default: `50`
Maximum size in MB for a skill package (`.zip` or `.skill`), whether uploaded to an agent as an embedded skill or imported into the skill library. Larger packages are rejected with a size error.
A skill's unpacked content is separately capped at 200 MB and 5000 files. For library imports, folders also count toward the 5000 limit. This variable doesn't change either limit. If you raise it above 100, also raise `NGINX_CLIENT_MAX_BODY_SIZE` to match; otherwise Nginx rejects the upload with a 413 error.
### AGENT\_BACKEND\_BASE\_URL
Default: `http://agent_backend:5050`
Address the API uses to reach the agent backend. Keep the default on Docker Compose.
The remaining variables configure the bundled services or derive from your existing Compose values, and don't normally need changes.
| Variable | Default | Description |
| ---------------------------------------------------------- | ------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DIFY_AGENT_REDIS_URL` | (empty; derives from `REDIS_PASSWORD`) | Redis connection for the agent backend's run state; the Compose default points at the bundled `redis` on database 2. |
| `DIFY_AGENT_REDIS_PREFIX` | `dify-agent` | Key prefix for the agent backend's Redis entries. |
| `DIFY_AGENT_SHUTDOWN_GRACE_SECONDS` | `30` | How long a stopping agent backend waits for in-flight runs to finish. |
| `DIFY_AGENT_RUN_RETENTION_SECONDS` | `259200` | How long finished run records are retained (3 days by default). |
| `DIFY_AGENT_RUN_TIMEOUT_SECONDS` | `3600` | Wall-clock deadline for one agent run's model and tool work. A run that exceeds it fails with `agent_run_limit_exceeded`. Replaces the former `AGENT_BACKEND_RUN_TIMEOUT_SECONDS`.<br /><br />The API-side `APP_MAX_EXECUTION_TIME` and `WORKFLOW_MAX_EXECUTION_TIME` (default `3600`) cap runs earlier if set below this.<br /><br />On the `e2b` backend the sandbox's `DIFY_AGENT_E2B_ACTIVE_TIMEOUT_SECONDS` (ceiling 3600) still applies, so values above an hour only take effect on the `local` backend. |
| `AGENT_BACKEND_STREAM_READ_TIMEOUT_SECONDS` | `30` | Read timeout for one SSE connection to the agent backend. |
| `AGENT_BACKEND_STREAM_MAX_RECONNECTS` | `3` | How many times the API reconnects a dropped agent-backend stream before failing the run. |
| `DIFY_AGENT_PLUGIN_DAEMON_URL` | (empty; derives from `PLUGIN_DAEMON_URL`) | Plugin daemon address the agent backend calls tools through. |
| `DIFY_AGENT_PLUGIN_DAEMON_API_KEY` | (empty; derives from `PLUGIN_DAEMON_KEY`) | Credential for the plugin daemon. |
| `DIFY_AGENT_OUTBOUND_HTTP_CONNECT_TIMEOUT` | `10` | Connect timeout in seconds for the agent service's outbound HTTP calls, such as tool and plugin traffic. |
| `DIFY_AGENT_OUTBOUND_HTTP_READ_TIMEOUT` | `600` | Read timeout in seconds; generous by default so slow tool responses and large downloads can finish. |
| `DIFY_AGENT_OUTBOUND_HTTP_WRITE_TIMEOUT` | `30` | Write timeout in seconds for outbound requests. |
| `DIFY_AGENT_OUTBOUND_HTTP_POOL_TIMEOUT` | `10` | How long in seconds a request waits for a free connection from the pool. |
| `DIFY_AGENT_OUTBOUND_HTTP_MAX_CONNECTIONS` | `100` | Connection pool size for the agent service's outbound HTTP. |
| `DIFY_AGENT_OUTBOUND_HTTP_MAX_KEEPALIVE_CONNECTIONS` | `20` | How many idle connections stay pooled for reuse. |
| `DIFY_AGENT_OUTBOUND_HTTP_KEEPALIVE_EXPIRY` | `30` | Seconds an idle pooled connection is kept before it closes. |
| `DIFY_AGENT_INNER_API_URL` | (empty; derives from `PLUGIN_DIFY_INNER_API_URL`) | Dify API address for the agent backend's internal calls. |
| `DIFY_AGENT_INNER_API_KEY` | (empty; derives from `PLUGIN_DIFY_INNER_API_KEY`) | Must match the API service's `INNER_API_KEY_FOR_PLUGIN`, not `INNER_API_KEY`. |
| `DIFY_AGENT_LOCAL_SANDBOX_ENDPOINT` | `http://local_sandbox:5004` | Address of the bundled sandbox service. Replaces the former `DIFY_AGENT_SHELLCTL_ENTRYPOINT`, which still works as a legacy alias. |
| `DIFY_AGENT_LOCAL_SANDBOX_AUTH_TOKEN` | (empty) | Optional bearer token securing the agent backend's calls to the sandbox; Compose passes the same value to both services. <br /><br />Replaces the former `DIFY_AGENT_SHELLCTL_AUTH_TOKEN`, which still works as a legacy alias. |
| `DIFY_AGENT_STUB_API_BASE_URL` | `http://agent_backend:5050/agent-stub` | Callback address the sandboxed agent uses to reach the agent backend. |
| `DIFY_AGENT_SANDBOX_FILES_BASE_URL` | `http://api:5001` | Dify API address the sandboxed agent uses for file transfers. Keep the default on Docker Compose. A remote sandbox backend needs your publicly reachable Dify address here. |
| `AGENT_BACKEND_BINDING_FILE_DOWNLOAD_TIMEOUT_SECONDS` | `240` | How long the API waits when fetching a file from an agent's sandbox before failing the transfer. Keep it above the agent-side `DIFY_AGENT_BINDING_FILE_DOWNLOAD_COMMAND_TIMEOUT_SECONDS`. |
| `AGENT_BACKEND_HOME_SNAPSHOT_TIMEOUT_SECONDS` | `45` | How long the API waits on agent backend calls that transfer a home snapshot: capturing or deleting one, and starting a run that restores one.<br /><br />If applying a build or starting runs fails for agents with large home environments, increase this. |
| `DIFY_AGENT_BINDING_FILE_DOWNLOAD_COMMAND_TIMEOUT_SECONDS` | `210` | How long the sandbox command serving that file may run. The default stays below the API's timeout so the agent's own error surfaces first. |
| `DIFY_AGENT_STUB_UPLOAD_FILE_SIZE_LIMIT` | `50` | Maximum size in MiB for one file the sandboxed agent uploads back to Dify, such as the files it generates for a reply. |
| `SHELLCTL_ENABLE_PATH_ISOLATION` | `true` | Kernel-enforced (Landlock) limits on which paths the sandbox can read and write. Requires Linux 5.13 or later; on older kernels the sandbox logs a warning and runs without it. Set in `docker/envs/core-services/local-sandbox.env`; `.env` values don't reach the sandbox container. |
| `DIFY_AGENT_SHELL_REDACT_PATTERNS` | (empty) | JSON array of regex patterns masked out of shell output before the agent reads it, for secrets like API keys. The agent's internal bearer token is always masked. |
### DIFY\_AGENT\_RUNTIME\_BACKEND
Default: `local`
Selects where agent sandboxes run. The default `local` uses the bundled sandbox container. Set to `e2b` to run each agent's sandbox as an [E2B](https://e2b.dev) cloud VM instead, for stronger isolation than the bundled container provides.
The `e2b` backend reads its own group of variables, and the `docker/docker-compose.e2b.yaml` overlay adjusts the Compose stack for it:
| Variable | Default | Description |
| --------------------------------------- | ---------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DIFY_AGENT_E2B_API_KEY` | (empty; falls back to `E2B_API_KEY`/`E2B_API_TOKEN`) | E2B account key; required for the `e2b` backend. |
| `DIFY_AGENT_E2B_TEMPLATE` | `difys-default-team/dify-agent-local-sandbox` | E2B sandbox template agents run in. |
| `DIFY_AGENT_E2B_ACTIVE_TIMEOUT_SECONDS` | `3600` | How long one E2B sandbox stays active, spanning a complete agent run. 3600 is also the hard ceiling: higher values are rejected. <br /><br />Keep it at or above `DIFY_AGENT_RUN_TIMEOUT_SECONDS`. If the sandbox's active time is shorter than the run's allowed time, runs lose their sandbox while still within their limit. |
| `DIFY_AGENT_E2B_SHELLCTL_PORT` | `5004` | Port the sandbox control service listens on inside the E2B VM. |
## Database Service
These configure the database containers directly in Docker Compose.
| Variable | Default | Description |
| ------------------- | --------------------------------- | ----------------------------------------------- |
| `PGDATA` | `/var/lib/postgresql/data/pgdata` | PostgreSQL data directory inside the container. |
| `MYSQL_HOST_VOLUME` | `./volumes/mysql/data` | Host path mounted as MySQL data volume. |
## Sandbox Service
The sandbox is an isolated service for executing code nodes (Python, JavaScript, Jinja2). Network access can be disabled for security.
| Variable | Default | Description |
| ------------------------ | ------------------------ | ---------------------------------------------------------------------------------------------------------- |
| `SANDBOX_API_KEY` | `dify-sandbox` | API key for sandbox authentication. Must match `CODE_EXECUTION_API_KEY` in the API service. |
| `SANDBOX_GIN_MODE` | `release` | Sandbox service mode: `release` or `debug`. |
| `SANDBOX_WORKER_TIMEOUT` | `15` | Maximum execution time in seconds for a single code run. |
| `SANDBOX_ENABLE_NETWORK` | `true` | Allow code to make outbound HTTP requests. Disable to prevent code nodes from accessing external services. |
| `SANDBOX_HTTP_PROXY` | `http://ssrf_proxy:3128` | HTTP proxy for SSRF protection when network is enabled. |
| `SANDBOX_HTTPS_PROXY` | `http://ssrf_proxy:3128` | HTTPS proxy for SSRF protection. |
| `SANDBOX_PORT` | `8194` | Sandbox service port. |
## Nginx Reverse Proxy
| Variable | Default | Description |
| -------------------------------- | -------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `NGINX_SERVER_NAME` | `_` | Nginx server name. `_` matches any hostname. |
| `NGINX_HTTPS_ENABLED` | `false` | Enable HTTPS. When `true`, place your SSL certificate and key in `./nginx/ssl/`. |
| `NGINX_PORT` | `80` | HTTP port. |
| `NGINX_SSL_PORT` | `443` | HTTPS port (only used when `NGINX_HTTPS_ENABLED=true`). |
| `NGINX_SSL_CERT_FILENAME` | `dify.crt` | SSL certificate filename in `./nginx/ssl/`. |
| `NGINX_SSL_CERT_KEY_FILENAME` | `dify.key` | SSL private key filename in `./nginx/ssl/`. |
| `NGINX_SSL_PROTOCOLS` | `TLSv1.2 TLSv1.3` | Allowed TLS protocol versions. |
| `NGINX_WORKER_PROCESSES` | `auto` | Number of Nginx worker processes. `auto` matches CPU core count. |
| `NGINX_CLIENT_MAX_BODY_SIZE` | `100M` | Maximum request body size. Affects file upload limits at the proxy level. |
| `NGINX_KEEPALIVE_TIMEOUT` | `65` | Keepalive timeout in seconds. |
| `NGINX_PROXY_READ_TIMEOUT` | `3600s` | Proxy read timeout. Set high (1 hour) to support long-running SSE streams. |
| `NGINX_PROXY_SEND_TIMEOUT` | `3600s` | Proxy send timeout. |
| `NGINX_ENABLE_CERTBOT_CHALLENGE` | `false` | Accept Let's Encrypt ACME challenge requests at `/.well-known/acme-challenge/`. Enable for automated certificate renewal. |
| `NGINX_SOCKET_IO_UPSTREAM` | `api_websocket:5001` | Upstream that Nginx forwards `/socket.io/` traffic to. Defaults to the dedicated `api_websocket` container started by the `collaboration` profile. Change only if you run the WebSocket service outside Docker Compose. |
<Note>
After enabling HTTPS, also update the URL variables in [Common Variables](#common-variables) (e.g., `CONSOLE_API_URL`, `CONSOLE_WEB_URL`) to use `https://`.
</Note>
### Certbot Configuration
| Variable | Default | Description |
| ----------------- | ------- | ---------------------------------------------------------------------- |
| `CERTBOT_EMAIL` | (empty) | Email address required by Let's Encrypt for certificate notifications. |
| `CERTBOT_DOMAIN` | (empty) | Domain name for the SSL certificate. |
| `CERTBOT_OPTIONS` | (empty) | Additional certbot CLI options (e.g., `--force-renewal`, `--dry-run`). |
## SSRF Proxy
These configure the Squid-based SSRF proxy container that blocks requests to internal/private networks.
| Variable | Default | Description |
| ---------------------------------- | ------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `SSRF_HTTP_PORT` | `3128` | Proxy listening port. |
| `SSRF_COREDUMP_DIR` | `/var/spool/squid` | Core dump directory. |
| `SSRF_SANDBOX_PROXY_PORT` | `8194` | Port the SSRF proxy listens on to reverse-proxy egress to the sandbox service. |
| `SSRF_SANDBOX_PROXY_HOST` | `sandbox` | Hostname of the sandbox service the SSRF proxy forwards to. |
| `SSRF_PROXY_ALLOW_PRIVATE_IPS` | (empty) | Comma- or space-separated private IPs or CIDR ranges to allow through the proxy, overriding the default block on private networks. Use when HTTP or tool requests must reach specific internal hosts. |
| `SSRF_PROXY_ALLOW_PRIVATE_DOMAINS` | (empty) | Comma- or space-separated internal domains to allow through the proxy, overriding the default block on private networks. |
| `SSRF_DEFAULT_TIME_OUT` | `5` | Default overall timeout in seconds for proxied requests. |
| `SSRF_DEFAULT_CONNECT_TIME_OUT` | `5` | Default connection timeout in seconds. |
| `SSRF_DEFAULT_READ_TIME_OUT` | `5` | Default read timeout in seconds. |
| `SSRF_DEFAULT_WRITE_TIME_OUT` | `5` | Default write timeout in seconds. |
## Docker Compose
These variables stay in `docker/.env` because Docker Compose uses them to select profiles and expose ports before containers start.
| Variable | Default | Description |
| ----------------------- | ---------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `COMPOSE_PROFILES` | `${VECTOR_STORE:-weaviate},${DB_TYPE:-postgresql},collaboration` | Selects which service containers to start. The default includes the matching vector store and database (so `DB_TYPE=mysql` starts MySQL instead of PostgreSQL), plus the `collaboration` profile that starts the dedicated `api_websocket` container. Remove `collaboration` to skip the separate WebSocket service. |
| `EXPOSE_NGINX_PORT` | `80` | Host port mapped to Nginx HTTP. |
| `EXPOSE_NGINX_SSL_PORT` | `443` | Host port mapped to Nginx HTTPS. |
## ModelProvider & Tool Position Configuration
Customize which tools and model providers are available in the app interface and their display order. Use comma-separated values with no spaces between items.
| Variable | Default | Description |
| ---------------------------- | ------- | --------------------------------------------------------------------- |
| `POSITION_TOOL_PINS` | (empty) | Pin specific tools to the top of the list. Example: `bing,google`. |
| `POSITION_TOOL_INCLUDES` | (empty) | Only show listed tools. If unset, all tools are available. |
| `POSITION_TOOL_EXCLUDES` | (empty) | Hide specific tools (pinned tools are not affected). |
| `POSITION_PROVIDER_PINS` | (empty) | Pin specific model providers to the top. Example: `openai,anthropic`. |
| `POSITION_PROVIDER_INCLUDES` | (empty) | Only show listed providers. If unset, all providers are available. |
| `POSITION_PROVIDER_EXCLUDES` | (empty) | Hide specific providers (pinned providers are not affected). |
## Plugin Daemon Configuration
The plugin daemon is a separate service that manages plugin lifecycle (installation, execution, upgrades). The API communicates with it via HTTP.
| Variable | Default | Description |
| -------------------------------------- | ---------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `PLUGIN_DAEMON_URL` | `http://plugin_daemon:5002` | Plugin daemon service URL. |
| `PLUGIN_DAEMON_KEY` | (auto-generated) | Authentication key for the plugin daemon. |
| `PLUGIN_DAEMON_PORT` | `5002` | Plugin daemon listening port. |
| `PLUGIN_DAEMON_TIMEOUT` | `600.0` | Timeout in seconds for all plugin daemon requests (installation, execution, listing). |
| `PLUGIN_MAX_PACKAGE_SIZE` | `52428800` | Maximum plugin package size in bytes (50 MB). Validated during marketplace downloads. |
| `PLUGIN_MAX_FILE_SIZE` | `52428800` | Maximum size in bytes (50 MB) for a single file a plugin returns to Dify, such as a tool plugin outputting a generated image or document. A larger file fails the invocation with a "file is too large" error. |
| `PLUGIN_MODEL_SCHEMA_CACHE_TTL` | `3600` | How long to cache plugin model schemas in seconds. Reduces repeated lookups. |
| `PLUGIN_MODEL_PROVIDERS_CACHE_ENABLED` | `true` | Whether each tenant's plugin model provider list is cached in Redis at all. Disable when plugins are installed by an external system that can't invalidate this deployment's cache when a tenant's plugins change. |
| `PLUGIN_MODEL_PROVIDERS_CACHE_TTL` | `86400` | How long to cache each tenant's plugin model provider list in Redis, in seconds (24 hours). Dify invalidates this cache when a tenant installs, uninstalls, or upgrades a plugin. |
| `PLUGIN_DIFY_INNER_API_KEY` | (auto-generated) | API key the plugin daemon uses to call back to the Dify API. Must match `DIFY_INNER_API_KEY` in the plugin daemon service config. |
| `INNER_API_KEY_FOR_PLUGIN` | (pre-filled in the env example; replace for production) | The API-service side of the same secret, under its direct name from `docker/envs/core-services/`; in the Compose stack `PLUGIN_DIFY_INNER_API_KEY` feeds both sides.<br />The API checks it on every plugin callback (model invocation, tool calls, file transfer). On mismatch those calls fail while plugin install keeps working.<br />Replace the shipped default: it is public in the Dify repo and is the only auth on the plugin callback API. |
| `PLUGIN_DIFY_INNER_API_URL` | `http://api:5001` | Internal API URL the plugin daemon calls back to. |
| `PLUGIN_DEBUGGING_HOST` | `0.0.0.0` | Host for plugin remote debugging connections. |
| `PLUGIN_DEBUGGING_PORT` | `5003` | Port for plugin remote debugging connections. |
| `PLUGIN_REMOTE_INSTALL_HOST` | `localhost` | Address the console shows plugin developers for remote plugin debugging. Display-only: the daemon's listener is unaffected.<br />Set it (via `EXPOSE_PLUGIN_DEBUGGING_HOST` in the Compose stack) to a host developers can reach; `localhost` only works when developing on the Docker host itself. |
| `PLUGIN_REMOTE_INSTALL_PORT` | `5003` | Port half of the advertised debugging address.<br />Must match the published daemon debugging port (`EXPOSE_PLUGIN_DEBUGGING_PORT`); the Compose stack keeps the two in sync from that one knob. |
| `MARKETPLACE_ENABLED` | `true` | Enable the plugin marketplace. When disabled, only locally installed plugins are available—browsing and auto-upgrades are unavailable. |
| `MARKETPLACE_API_URL` | `https://marketplace.dify.ai` | Marketplace API endpoint for plugin browsing, downloading, and upgrade checking. |
| `MARKETPLACE_URL` | (empty; the Compose stack falls back to `https://marketplace.dify.ai`) | Base URL for links that send users out to the Marketplace website (plugin detail pages, "more" links, the publishing guide).<br />Distinct from `MARKETPLACE_API_URL`, which the console and plugin daemon use to fetch Marketplace data. |
| `FORCE_VERIFYING_SIGNATURE` | `true` | Require valid signatures before installing plugins. Prevents installing tampered or unsigned packages. |
| `PLUGIN_MAX_EXECUTION_TIMEOUT` | `600` | Plugin execution timeout in seconds (plugin daemon side). Should match `PLUGIN_DAEMON_TIMEOUT` on the API side. |
| `PIP_MIRROR_URL` | (empty) | Custom PyPI mirror URL used by the plugin daemon when installing plugin dependencies. Useful for faster installs or air-gapped environments. |
## Creator Center Configuration
Creator Center (`creators.dify.ai`) is the submission portal where users upload Dify apps as templates. Submitted templates are reviewed and, once approved, listed on Dify Marketplace. The console's **Publish to Marketplace** action exports the app's DSL and uploads it to Creator Center on the user's behalf. See [Publish Apps to Marketplace](/en/self-host/use-dify/publish/publish-to-marketplace) for the user-facing flow.
| Variable | Default | Description |
| ------------------------------------ | -------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `CREATORS_PLATFORM_FEATURES_ENABLED` | `true` | Controls whether the **Publish to Marketplace** action appears in the app builder. Set to `false` to hide the action; the underlying console API also returns 403. Useful on deployments where users shouldn't have a one-click path to submit templates externally. |
| `CREATORS_PLATFORM_API_URL` | `https://creators.dify.ai` | Endpoint that receives DSL uploads from the **Publish to Marketplace** action. Change only if running a self-hosted Creator Center instance. |
| `CREATORS_PLATFORM_OAUTH_CLIENT_ID` | (empty) | OAuth client ID issued by Creator Center. When set, the post-upload redirect carries an OAuth authorization code so Creator Center can attribute the submission to the publishing user. Empty means anonymous upload. |
## OTLP / OpenTelemetry Configuration
OpenTelemetry provides distributed tracing and metrics collection. When enabled, Dify instruments Flask and exports telemetry data to an OTLP collector.
| Variable | Default | Description |
| ---------------------------------- | ----------------------- | ---------------------------------------------------------------------------------------------------------------- |
| `ENABLE_OTEL` | `false` | Master switch for OpenTelemetry instrumentation. |
| `OTLP_TRACE_ENDPOINT` | (empty) | Dedicated trace endpoint URL. If unset, falls back to `{OTLP_BASE_ENDPOINT}/v1/traces`. |
| `OTLP_METRIC_ENDPOINT` | (empty) | Dedicated metric endpoint URL. If unset, falls back to `{OTLP_BASE_ENDPOINT}/v1/metrics`. |
| `OTLP_BASE_ENDPOINT` | `http://localhost:4318` | Base OTLP collector URL. Used as fallback when specific trace/metric endpoints are not set. |
| `OTLP_API_KEY` | (empty) | API key for OTLP authentication. Sent as `Authorization: Bearer` header. |
| `OTEL_EXPORTER_TYPE` | `otlp` | Exporter type. `otlp` exports to a collector; other values use a console exporter (for debugging). |
| `OTEL_EXPORTER_OTLP_PROTOCOL` | (empty) | Protocol for OTLP export. `grpc` uses gRPC exporters; anything else uses HTTP. |
| `OTEL_SAMPLING_RATE` | `0.1` | Fraction of requests to trace (0.1 = 10%). Lower values reduce overhead in high-traffic production environments. |
| `OTEL_BATCH_EXPORT_SCHEDULE_DELAY` | `5000` | Delay in milliseconds between batch exports. |
| `OTEL_MAX_QUEUE_SIZE` | `2048` | Maximum number of spans queued before dropping. |
| `OTEL_MAX_EXPORT_BATCH_SIZE` | `512` | Maximum spans per export batch. |
| `OTEL_METRIC_EXPORT_INTERVAL` | `60000` | Metric export interval in milliseconds. |
| `OTEL_BATCH_EXPORT_TIMEOUT` | `10000` | Batch span export timeout in milliseconds. |
| `OTEL_METRIC_EXPORT_TIMEOUT` | `30000` | Metric export timeout in milliseconds. |
## Miscellaneous
| Variable | Default | Description |
| ---------------------------------- | ------------------ | -------------------------------------------------------------------------------------------------------------------------------------------- |
| `CSP_WHITELIST` | (empty) | Additional domains to allow in Content Security Policy headers. |
| `ALLOW_EMBED` | `false` | Allow Dify pages to be embedded in iframes. When `false`, sets `X-Frame-Options: DENY` to prevent clickjacking. |
| `SWAGGER_UI_ENABLED` | `false` | Expose Swagger UI at `SWAGGER_UI_PATH` for browsing API documentation. Swagger endpoints bypass authentication. |
| `SWAGGER_UI_PATH` | `/swagger-ui.html` | URL path for Swagger UI. |
| `MAX_SUBMIT_COUNT` | `100` | Maximum concurrent task submissions in the thread pool used for parallel workflow node execution. |
| `TENANT_ISOLATED_TASK_CONCURRENCY` | `1` | Number of document indexing or RAG pipeline tasks processed simultaneously per tenant. Increase for faster indexing with more database load. |
| `DIFY_ENV_NACOS_REQUEST_TIMEOUT` | `10.0` | Timeout in seconds for HTTP requests to the Nacos configuration server. |
| `DIFY_ENV_NACOS_CONNECT_TIMEOUT` | `3.0` | Timeout in seconds for establishing a connection to the Nacos configuration server. |
### Scheduled Tasks Configuration
Dify uses Celery Beat to run background maintenance tasks on configurable schedules.
| Variable | Default | Description |
| ------------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `ENABLE_CLEAN_EMBEDDING_CACHE_TASK` | `false` | Delete expired embedding cache records from the database at 2:00 AM daily. Manages database size. |
| `ENABLE_CLEAN_UNUSED_DATASETS_TASK` | `false` | Disable documents in knowledge bases that haven't had activity within the retention period. Runs at 3:00 AM daily. |
| `ENABLE_CLEAN_MESSAGES` | `false` | Delete conversation messages older than `SANDBOX_EXPIRED_RECORDS_RETENTION_DAYS` at 4:00 AM daily. |
| `ENABLE_MAIL_CLEAN_DOCUMENT_NOTIFY_TASK` | `false` | Email workspace owners a list of knowledge bases that had documents auto-disabled by the cleanup task. Runs every Monday at 10:00 AM. |
| `ENABLE_DATASETS_QUEUE_MONITOR` | `false` | Monitor the dataset processing queue backlog in Redis. Sends email alerts when the queue exceeds the threshold. |
| `QUEUE_MONITOR_INTERVAL` | `30` | How often to check the queue (in minutes). |
| `QUEUE_MONITOR_THRESHOLD` | `200` | Queue size that triggers an alert email. |
| `QUEUE_MONITOR_ALERT_EMAILS` | (empty) | Email addresses to receive queue alerts (comma-separated). |
| `ENABLE_CHECK_UPGRADABLE_PLUGIN_TASK` | `true` | Check the marketplace for newer plugin versions every 15 minutes. Dispatches upgrade tasks based on each tenant's auto-upgrade schedule. |
| `ENABLE_WORKFLOW_SCHEDULE_POLLER_TASK` | `true` | Enable the workflow schedule poller that checks for and triggers scheduled workflow runs. |
| `WORKFLOW_SCHEDULE_POLLER_INTERVAL` | `1` | How often to check for due scheduled workflows (in minutes). |
| `WORKFLOW_SCHEDULE_POLLER_BATCH_SIZE` | `100` | Maximum number of due schedules fetched per poll cycle. |
| `WORKFLOW_SCHEDULE_MAX_DISPATCH_PER_TICK` | `0` | Circuit breaker: maximum schedules dispatched per tick. `0` means unlimited. |
| `ENABLE_WORKFLOW_RUN_CLEANUP_TASK` | `false` | Enable automatic cleanup of workflow run records. |
| `ENABLE_CREATE_TIDB_SERVERLESS_TASK` | `false` | Pre-create TiDB Serverless clusters for vector database pooling. |
| `ENABLE_UPDATE_TIDB_SERVERLESS_STATUS_TASK` | `false` | Update TiDB Serverless cluster status periodically. |
| `ENABLE_HUMAN_INPUT_TIMEOUT_TASK` | `true` | Check for expired Human Input forms and resume or stop timed-out workflows. |
| `HUMAN_INPUT_TIMEOUT_TASK_INTERVAL` | `1` | How often to check for expired Human Input forms (in minutes). |
| `ENABLE_CONVERSATION_CLEANUP_TASK` | `true` | Safety net for conversation deletion. A deleted conversation disappears instantly while a background job removes its messages and the files generated by tools during the conversation. Files end users uploaded are kept.<br /><br />This sweep re-runs that job for conversations whose cleanup was lost, so their data does not linger. |
| `CONVERSATION_CLEANUP_TASK_INTERVAL` | `5` | How often the sweep runs (in minutes). |
| `CONVERSATION_CLEANUP_BATCH_SIZE` | `100` | Maximum conversations re-dispatched per sweep. |
#### Record Retention & Cleanup
These control the scheduled cleanup of old messages and workflow run records: anything older than the retention window is deleted in batches.
| Variable | Default | Description |
| -------------------------------------------------- | ------- | ------------------------------------------------------------------------------------- |
| `SANDBOX_EXPIRED_RECORDS_RETENTION_DAYS` | `30` | Records older than this many days are eligible for deletion. |
| `SANDBOX_EXPIRED_RECORDS_CLEAN_BATCH_SIZE` | `1000` | Number of records processed per cleanup batch. |
| `SANDBOX_EXPIRED_RECORDS_CLEAN_BATCH_MAX_INTERVAL` | `200` | Maximum random delay in milliseconds between cleanup batches to reduce database load. |
| `SANDBOX_EXPIRED_RECORDS_CLEAN_TASK_LOCK_TTL` | `90000` | Redis lock TTL in seconds (\~25 hours) to prevent concurrent cleanup task execution. |
## Aliyun SLS Logstore Configuration
Optional integration with Aliyun Simple Log Service for storing workflow execution logs externally instead of in the database. Enable by setting the repository configuration variables to use logstore implementations.
| Variable | Default | Description |
| --------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------ |
| `ALIYUN_SLS_ACCESS_KEY_ID` | (empty) | Aliyun access key ID for SLS authentication. |
| `ALIYUN_SLS_ACCESS_KEY_SECRET` | (empty) | Aliyun access key secret for SLS authentication. |
| `ALIYUN_SLS_ENDPOINT` | (empty) | SLS service endpoint URL (e.g., `cn-hangzhou.log.aliyuncs.com`). |
| `ALIYUN_SLS_REGION` | (empty) | Aliyun region (e.g., `cn-hangzhou`). |
| `ALIYUN_SLS_PROJECT_NAME` | (empty) | SLS project name for storing workflow logs. |
| `ALIYUN_SLS_LOGSTORE_TTL` | `365` | Data retention in days for SLS logstores. Use `3650` for permanent storage. |
| `LOGSTORE_DUAL_WRITE_ENABLED` | `false` | Write workflow data to both SLS and PostgreSQL simultaneously. Useful during migration to SLS. |
| `LOGSTORE_DUAL_READ_ENABLED` | `true` | Fall back to PostgreSQL when SLS returns no results. Useful during migration when historical data exists only in the database. |
| `LOGSTORE_ENABLE_PUT_GRAPH_FIELD` | `true` | Include the full workflow graph definition in SLS logs. Set to `false` to reduce storage by omitting large graph data. |
## Event Bus Configuration
Redis-based event transport between API and Celery workers.
| Variable | Default | Description |
| ------------------------------ | -------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| `EVENT_BUS_REDIS_URL` | (empty) | Redis connection URL for event streaming. When empty, uses the main Redis connection settings. |
| `EVENT_BUS_REDIS_CHANNEL_TYPE` | `pubsub` | Transport type: `pubsub` (Pub/Sub, at-most-once delivery), `sharded` (sharded Pub/Sub), or `streams` (Redis Streams, at-least-once delivery). |
| `EVENT_BUS_REDIS_USE_CLUSTERS` | `false` | Enable Redis Cluster mode for event bus. Recommended for large deployments. |
## Vector Database Service Configuration
These configure the vector database containers themselves (not the Dify client connection). Only the variables for your chosen `VECTOR_STORE` are relevant.
<AccordionGroup>
<Accordion title="Weaviate Service">
| Variable | Default | Description |
| -------------------------------------------------- | ------------------- | --------------------------------------------------------------------- |
| `WEAVIATE_PERSISTENCE_DATA_PATH` | `/var/lib/weaviate` | Data persistence directory inside the container. |
| `WEAVIATE_QUERY_DEFAULTS_LIMIT` | `25` | Default query result limit. |
| `WEAVIATE_AUTHENTICATION_ANONYMOUS_ACCESS_ENABLED` | `true` | Allow anonymous access. |
| `WEAVIATE_DEFAULT_VECTORIZER_MODULE` | `none` | Default vectorizer module. |
| `WEAVIATE_CLUSTER_HOSTNAME` | `node1` | Cluster node hostname. |
| `WEAVIATE_AUTHENTICATION_APIKEY_ENABLED` | `true` | Enable API key authentication. |
| `WEAVIATE_AUTHENTICATION_APIKEY_ALLOWED_KEYS` | (auto-generated) | Allowed API keys. Must match `WEAVIATE_API_KEY` in the client config. |
| `WEAVIATE_AUTHENTICATION_APIKEY_USERS` | `hello@dify.ai` | Users associated with API keys. |
| `WEAVIATE_AUTHORIZATION_ADMINLIST_ENABLED` | `true` | Enable admin list authorization. |
| `WEAVIATE_AUTHORIZATION_ADMINLIST_USERS` | `hello@dify.ai` | Admin users. |
| `WEAVIATE_DISABLE_TELEMETRY` | `false` | Disable Weaviate telemetry. |
| `WEAVIATE_ENABLE_TOKENIZER_GSE` | `false` | Enable GSE tokenizer (Chinese). |
| `WEAVIATE_ENABLE_TOKENIZER_KAGOME_JA` | `false` | Enable Kagome tokenizer (Japanese). |
| `WEAVIATE_ENABLE_TOKENIZER_KAGOME_KR` | `false` | Enable Kagome tokenizer (Korean). |
</Accordion>
<Accordion title="Milvus Service (ETCD + MinIO)">
| Variable | Default | Description |
| -------------------------------- | ------------ | ------------------------------------------------- |
| `ETCD_AUTO_COMPACTION_MODE` | `revision` | ETCD auto compaction mode. |
| `ETCD_AUTO_COMPACTION_RETENTION` | `1000` | Auto compaction retention in number of revisions. |
| `ETCD_QUOTA_BACKEND_BYTES` | `4294967296` | Backend quota in bytes (4 GB). |
| `ETCD_SNAPSHOT_COUNT` | `50000` | Number of changes before triggering a snapshot. |
| `ETCD_ENDPOINTS` | `etcd:2379` | ETCD service endpoints. |
| `MINIO_ACCESS_KEY` | `minioadmin` | MinIO access key. |
| `MINIO_SECRET_KEY` | `minioadmin` | MinIO secret key. |
| `MINIO_ADDRESS` | `minio:9000` | MinIO service address. |
| `MILVUS_AUTHORIZATION_ENABLED` | `true` | Enable Milvus security authorization. |
</Accordion>
<Accordion title="OpenSearch Service">
| Variable | Default | Description |
| ----------------------------------- | ----------------- | -------------------------------------------------- |
| `OPENSEARCH_DISCOVERY_TYPE` | `single-node` | Discovery type for cluster formation. |
| `OPENSEARCH_BOOTSTRAP_MEMORY_LOCK` | `true` | Lock memory on startup to prevent swapping. |
| `OPENSEARCH_JAVA_OPTS_MIN` | `512m` | Minimum JVM heap size. |
| `OPENSEARCH_JAVA_OPTS_MAX` | `1024m` | Maximum JVM heap size. |
| `OPENSEARCH_INITIAL_ADMIN_PASSWORD` | `Qazwsxedc!@#123` | Initial admin password for the OpenSearch service. |
| `OPENSEARCH_MEMLOCK_SOFT` | `-1` | Soft memory lock limit (`-1` = unlimited). |
| `OPENSEARCH_MEMLOCK_HARD` | `-1` | Hard memory lock limit (`-1` = unlimited). |
| `OPENSEARCH_NOFILE_SOFT` | `65536` | Soft file descriptor limit. |
| `OPENSEARCH_NOFILE_HARD` | `65536` | Hard file descriptor limit. |
</Accordion>
<Accordion title="PGVector / PGVecto.RS Service">
| Variable | Default | Description |
| ---------------------------- | --------------------------------- | ----------------------------------------------- |
| `PGVECTOR_PGUSER` | `postgres` | PostgreSQL user for the PGVector container. |
| `PGVECTOR_POSTGRES_PASSWORD` | (auto-generated) | PostgreSQL password for the PGVector container. |
| `PGVECTOR_POSTGRES_DB` | `dify` | Database name in the PGVector container. |
| `PGVECTOR_PGDATA` | `/var/lib/postgresql/data/pgdata` | Data directory inside the container. |
| `PGVECTOR_PG_BIGM_VERSION` | `1.2-20240606` | Version of the pg\_bigm extension. |
</Accordion>
<Accordion title="Oracle / Chroma / Elasticsearch Services">
| Variable | Default | Description |
| --------------------------------- | ------------------------------------------------------------- | ----------------------------------------------------------- |
| `ORACLE_PWD` | `Dify123456` | Oracle database password for the container. |
| `ORACLE_CHARACTERSET` | `AL32UTF8` | Oracle character set. |
| `CHROMA_SERVER_AUTHN_CREDENTIALS` | (auto-generated) | Authentication credentials for the Chroma server container. |
| `CHROMA_SERVER_AUTHN_PROVIDER` | `chromadb.auth.token_authn.TokenAuthenticationServerProvider` | Authentication provider for the Chroma server. |
| `CHROMA_IS_PERSISTENT` | `TRUE` | Enable persistent storage for Chroma. |
| `KIBANA_PORT` | `5601` | Kibana port (Elasticsearch UI). |
</Accordion>
<Accordion title="IRIS / Other Services">
| Variable | Default | Description |
| ---------------------- | ------------- | --------------------------------------- |
| `IRIS_WEB_SERVER_PORT` | `52773` | IRIS web server management port. |
| `IRIS_TIMEZONE` | `UTC` | Timezone for the IRIS container. |
| `DB_PLUGIN_DATABASE` | `dify_plugin` | Separate database name for plugin data. |
</Accordion>
</AccordionGroup>
## Plugin Daemon Storage Configuration
The plugin daemon can store plugin packages in different storage backends. Configure only the provider matching `PLUGIN_STORAGE_TYPE`.
| Variable | Default | Description |
| -------------------------------- | ------------------------------ | ------------------------------------------------------------------------------------------------------- |
| `PLUGIN_STORAGE_TYPE` | `local` | Plugin storage backend: `local`, `aws_s3`, `tencent_cos`, `azure_blob`, `aliyun_oss`, `volcengine_tos`. |
| `PLUGIN_STORAGE_LOCAL_ROOT` | `/app/storage` | Root directory for local plugin storage. |
| `PLUGIN_WORKING_PATH` | `/app/storage/cwd` | Working directory for plugin execution. |
| `PLUGIN_INSTALLED_PATH` | `plugin` | Subdirectory for installed plugins. |
| `PLUGIN_PACKAGE_CACHE_PATH` | `plugin_packages` | Subdirectory for cached plugin packages. |
| `PLUGIN_MEDIA_CACHE_PATH` | `assets` | Subdirectory for cached media assets. |
| `PLUGIN_STORAGE_OSS_BUCKET` | (empty) | Object storage bucket name (shared across S3/COS/OSS/TOS providers). |
| `PLUGIN_PPROF_ENABLED` | `false` | Enable Go pprof profiling for the plugin daemon. |
| `PLUGIN_PYTHON_ENV_INIT_TIMEOUT` | `120` | Timeout in seconds for initializing Python environments for plugins. |
| `PLUGIN_STDIO_BUFFER_SIZE` | `1024` | Buffer size in bytes for plugin stdio communication. |
| `PLUGIN_STDIO_MAX_BUFFER_SIZE` | `5242880` | Maximum buffer size in bytes (5 MB) for plugin stdio communication. |
| `ENDPOINT_URL_TEMPLATE` | `http://localhost/e/{hook_id}` | URL template for plugin endpoints. `{hook_id}` is replaced with the actual hook ID. |
| `EXPOSE_PLUGIN_DAEMON_PORT` | `5002` | Host port mapped to the plugin daemon. |
| `EXPOSE_PLUGIN_DEBUGGING_HOST` | `localhost` | Host for plugin remote debugging. |
| `EXPOSE_PLUGIN_DEBUGGING_PORT` | `5003` | Host port for plugin remote debugging. |
<AccordionGroup>
<Accordion title="Plugin S3 Storage">
| Variable | Default | Description |
| ------------------------------- | ------- | ---------------------------------------------- |
| `PLUGIN_S3_USE_AWS` | `false` | Use AWS S3 (vs S3-compatible services). |
| `PLUGIN_S3_USE_AWS_MANAGED_IAM` | `false` | Use IAM roles instead of explicit credentials. |
| `PLUGIN_S3_ENDPOINT` | (empty) | S3 endpoint URL. |
| `PLUGIN_S3_USE_PATH_STYLE` | `false` | Use path-style URLs instead of virtual-hosted. |
| `PLUGIN_AWS_ACCESS_KEY` | (empty) | AWS access key. |
| `PLUGIN_AWS_SECRET_KEY` | (empty) | AWS secret key. |
| `PLUGIN_AWS_REGION` | (empty) | AWS region. |
</Accordion>
<Accordion title="Plugin Azure Blob Storage">
| Variable | Default | Description |
| --------------------------------------------- | ------- | ----------------------------- |
| `PLUGIN_AZURE_BLOB_STORAGE_CONTAINER_NAME` | (empty) | Azure Blob container name. |
| `PLUGIN_AZURE_BLOB_STORAGE_CONNECTION_STRING` | (empty) | Azure Blob connection string. |
</Accordion>
<Accordion title="Plugin Tencent COS Storage">
| Variable | Default | Description |
| ------------------------------- | ------- | ----------------------- |
| `PLUGIN_TENCENT_COS_SECRET_KEY` | (empty) | Tencent COS secret key. |
| `PLUGIN_TENCENT_COS_SECRET_ID` | (empty) | Tencent COS secret ID. |
| `PLUGIN_TENCENT_COS_REGION` | (empty) | Tencent COS region. |
</Accordion>
<Accordion title="Plugin Aliyun OSS Storage">
| Variable | Default | Description |
| ------------------------------------- | ------- | ---------------------------------- |
| `PLUGIN_ALIYUN_OSS_REGION` | (empty) | Aliyun OSS region. |
| `PLUGIN_ALIYUN_OSS_ENDPOINT` | (empty) | Aliyun OSS endpoint. |
| `PLUGIN_ALIYUN_OSS_ACCESS_KEY_ID` | (empty) | Aliyun OSS access key ID. |
| `PLUGIN_ALIYUN_OSS_ACCESS_KEY_SECRET` | (empty) | Aliyun OSS access key secret. |
| `PLUGIN_ALIYUN_OSS_AUTH_VERSION` | `v4` | Aliyun OSS authentication version. |
| `PLUGIN_ALIYUN_OSS_PATH` | (empty) | Aliyun OSS path prefix. |
</Accordion>
<Accordion title="Plugin Volcengine TOS Storage">
| Variable | Default | Description |
| ---------------------------------- | ------- | -------------------------- |
| `PLUGIN_VOLCENGINE_TOS_ENDPOINT` | (empty) | Volcengine TOS endpoint. |
| `PLUGIN_VOLCENGINE_TOS_ACCESS_KEY` | (empty) | Volcengine TOS access key. |
| `PLUGIN_VOLCENGINE_TOS_SECRET_KEY` | (empty) | Volcengine TOS secret key. |
| `PLUGIN_VOLCENGINE_TOS_REGION` | (empty) | Volcengine TOS region. |
</Accordion>
</AccordionGroup>
# Deploy Dify
Source: https://docs.dify.ai/en/self-host/deploy/overview
Choose a deployment method and stand up Dify on your own infrastructure
<div>
<div>
<div>
<h1>Deploy Dify</h1>
<p>
Dify runs anywhere Docker runs: a laptop, an on-premises server, or a cloud VM. Start with Docker Compose, or pick another path below.
</p>
<div>
<a href="/en/self-host/deploy/quick-start/docker-compose">Deploy with Docker Compose</a>
<span>
<a href="/en/self-host/deploy/quick-start/faqs">FAQs</a>
<span>·</span>
<a href="https://github.com/langgenius/dify/releases">GitHub Releases</a>
</span>
</div>
</div>
</div>
<div>
<Card title="Local Source Code" icon="code" href="/en/self-host/deploy/advanced-deployments/local-source-code">
Run the services from source when you need to modify or debug the platform.
</Card>
<Card title="Platform Guides" icon="map" href="/en/self-host/deploy/platform-guides/bt-panel">
Run Dify Premium on AWS or set up through BT Panel.
</Card>
<Card title="Environment Variables" icon="gear" href="/en/self-host/deploy/configuration/environments">
Configure ports, storage, vector stores, and feature options.
</Card>
<Card title="Troubleshooting" icon="wrench" href="/en/self-host/deploy/troubleshooting/common-issues">
Resolve common startup, Docker, and integration issues.
</Card>
<Card title="Start Building" icon="hammer" href="/en/self-host/use-dify/getting-started/introduction">
Sign in to your instance and create your first app.
</Card>
<Card title="Get Help" icon="circle-question">
Ask the community or report a problem.
<div>
<a href="https://discord.gg/FngNHpbcY7">Discord</a>
<span>·</span>
<a href="https://github.com/langgenius/dify/issues">GitHub Issues</a>
<span>·</span>
<a href="https://github.com/langgenius/dify/discussions">Discussions</a>
</div>
</Card>
</div>
<div>
<Tip>
On Dify Enterprise, you can deploy on Kubernetes for high availability, with SSO and multi-workspace management. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
</div>
</div>
# Deploy with aaPanel
Source: https://docs.dify.ai/en/self-host/deploy/platform-guides/bt-panel
## Prerequisites
> Before installing Dify, make sure your machine meets the following minimum system requirements:
>
> * CPU >= 2 Core
> * RAM >= 4 GiB
<table>
<thead>
<tr>
<th>Operating System</th>
<th>Software</th>
<th>Explanation</th>
</tr>
</thead>
<tbody>
<tr>
<td>Linux platforms</td>
<td>
<p>aaPanel 7.0.11 or later</p>
</td>
<td>Please refer to the <a href="https://www.aapanel.com/new/download.html#install">aaPanel installation guide</a> for more information on how to install aaPanel.</td>
</tr>
</tbody>
</table>
## Deployment
1. Log in to aaPanel and click `Docker` in the menu bar
2. The first time you will be prompteINLINE\_CODE\_P`Docker Compose` the `Docker` and `Docker Compose` services, click Install Now. If it is already installed, please ignore it.
3. INLINE\_COD`One-Click Install`e ins`install` is complete, find `Dify` in `One-Click Install` and click `install`
4. configure basic information such as the domain name, ports to complete the installation
> \[!IMPORTANT]
>
> The domain name is optional, if the domain name is filled, it can be managed through \[Website]--> \[Proxy Project], and you do not need to check \[Allow external access] after filling in the domain name, otherwise you need to check it before you can access it through the port
5. After installation, enter the domain name or IP+ port s`Dify-characters`s step in the browser `latest`s.
* Name: application name, default `Dify-characters`
* Version selection: default `latest`
* Domain name: If you need to access directly through the domain name, please configure the domain na`IP+Port`nd resolve the domain name to the server
* Allow external access: If you nee`8088`ct access through `IP+Port`, please check. If you have set up a domain name, please do not check here.
* Port: De`Docker`0 `8088`, can be modified by yourself
6. After submission, the panel will automatically initialize the application, which will take about `1-3` minutes. It can be accessed after the initialization is completed.
### Access Dify
Access administrator initialization page to set up the admin account:
```bash theme={null}
# If you have set domain
http://yourdomain/install
# If you choose to access through `IP+Port`
http://your_server_ip:8088/install
```
Dify web interface address:
```bash theme={null}
# If you have set domain
http://yourdomain/
# If you choose to access through `IP+Port`
http://your_server_ip:8088/
```
# Dify Premium on AWS
Source: https://docs.dify.ai/en/self-host/deploy/platform-guides/dify-premium
Deploy, customize, and upgrade Dify Premium on AWS
Dify Premium is our AWS AMI offering that allows custom branding and is one-click deployable to your AWS VPC as an EC2 instance. Head to [AWS Marketplace](https://aws.amazon.com/marketplace/pp/prodview-t22mebxzwjhu6) to subscribe. It's useful in a couple of scenarios:
* You're looking to create one or a few applications as a small/medium business and you care about data residency.
* You are interested in [Dify Cloud](https://cloud.dify.ai), but your use case requires more resources than supported by the [plans](https://dify.ai/pricing).
* You'd like to run a POC before adopting Dify Enterprise within your organization.
## Access & Set up
After the AMI is deployed, access Dify via the instance's public IP found in the EC2 console (HTTP port 80 is used by default).
If this is your first time accessing Dify, enter the Admin initialization password (your EC2's instance ID) to start the setup process.
## Customize
### Configuration
<Steps>
<Step title="Edit Environment Variables">
Edit environment variables in the relevant file on your EC2 instance:
* **Essential startup values** live in `/dify/.env`. Edit them directly.
* **Optional or provider-specific settings** have templates under `/dify/envs/`. To override a default value, copy the matching template (drop the `.example` suffix), then edit your copy.
For example:
```bash theme={null}
cd /dify
cp envs/vectorstores/opensearch.env.example envs/vectorstores/opensearch.env
```
Values in `/dify/.env` take precedence over values in any `/dify/envs/*.env` files.
If your AWS deployment injects variables through `docker-compose.override.yaml`, keep those settings there. Service-level `environment:` values in Compose take precedence over env-file values.
</Step>
<Step title="Restart Dify">
```bash theme={null}
docker compose down
docker compose -f docker-compose.yaml -f docker-compose.override.yaml up -d
```
</Step>
</Steps>
### Web App Logo & Branding
In **Settings** > **Customization**, you can remove the `Powered by Dify` branding or replace it with your own logo.
## Upgrade
<Warning>
* Before upgrading, check the [Release Notes](https://github.com/langgenius/dify/releases) on GitHub for version-specific upgrade instructions. Some versions may require additional steps such as database migrations or configuration changes.
* Dify's Docker Compose files now require Docker Compose 2.24.0 or later. Run `docker compose version` to confirm before upgrading.
</Warning>
In the EC2 instance, run the following commands:
<Steps>
<Step title="Stop the Running Services">
```bash theme={null}
cd /dify
docker compose down
```
</Step>
<Step title="Back Up Your Data">
Back up your `.env` file, any optional env files you created under `envs/`, and the `volumes` directory, which contains your database, storage, and other persistent data:
```bash theme={null}
cp /dify/.env /dify/.env.bak
tar -cvf envs-$(date +%s).tgz envs
tar -cvf volumes-$(date +%s).tgz volumes
```
</Step>
<Step title="Update Dify">
<Warning>
The upgrade process will overwrite configuration templates but will not affect your `.env` file, local `/dify/envs/*.env` files, or runtime data (such as databases and uploaded files) in the `volumes/` directory.
If you have manually modified configuration files beyond `.env` and `/dify/envs/*.env`, back them up before upgrading.
</Warning>
Pull the latest code and sync the configuration files:
```bash theme={null}
git clone https://github.com/langgenius/dify.git /tmp/dify
rsync -av /tmp/dify/docker/ /dify/
rm -rf /tmp/dify
```
</Step>
<Step title="Check for New Environment Variables">
New versions may introduce variables in `.env.example` or in optional templates under `envs/`. Compare each template with its matching local env file and add any missing variables you need:
```bash theme={null}
diff /dify/.env /dify/.env.example
find /dify/envs -name "*.env" -print | while read -r env_file; do
diff "$env_file" "$env_file.example"
done
```
If you need to customize a newly added optional template, copy it beside itself without the `.example` suffix before editing it. See [Configuration](#configuration) for details.
</Step>
<Step title="Start Services">
```bash theme={null}
docker compose pull
docker compose -f docker-compose.yaml -f docker-compose.override.yaml up -d
```
</Step>
</Steps>
# Deploy Dify with Docker Compose
Source: https://docs.dify.ai/en/self-host/deploy/quick-start/docker-compose
<Tip>
For common deployment questions, see [FAQs](/en/self-host/deploy/quick-start/faqs).
</Tip>
## Before Deployment
Make sure your machine meets the following minimum system requirements.
### Hardware
* CPU >= 2 Core
* RAM >= 4 GiB
### Software
| Operating System | Required Software | Notes |
| :------------------------- | :---------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| macOS 10.14 or later | Docker Desktop with Docker Compose 2.24.0+ | Configure the Docker virtual machine with at least 2 virtual CPUs and 8 GiB of memory. <br /><br />For installation instructions, see [Install Docker Desktop on Mac](https://docs.docker.com/desktop/mac/install/). |
| Linux distributions | Docker 19.03+<br /><br />Docker Compose 2.24.0+ | For installation instructions, see [Install Docker Engine](https://docs.docker.com/engine/install/) and [Install Docker Compose](https://docs.docker.com/compose/install/). |
| Windows with WSL 2 enabled | Docker Desktop with Docker Compose 2.24.0+ | Store source code and data bound to Linux containers in the Linux file system rather than Windows. <br /><br />For installation instructions, see [Install Docker Desktop on Windows](https://docs.docker.com/desktop/windows/install/#wsl-2-backend). |
## Deploy and Start
<Steps>
<Step title="Clone Dify">
Clone the Dify source code to your local machine.
```bash theme={null}
git clone --branch "$(curl -s https://api.github.com/repos/langgenius/dify/releases/latest | jq -r .tag_name)" https://github.com/langgenius/dify.git
```
<Info>
This command requires `git`, `curl`, and `jq`. If you see a `command not found` error, install the missing tool and run the command again.
When the clone fails with `fatal: Remote branch null not found in upstream origin`, retry with an explicit version, using the latest version number from [Dify releases](https://github.com/langgenius/dify/releases):
```bash theme={null}
git clone --branch <version> https://github.com/langgenius/dify.git
```
See [Clone Fails with "Remote branch null not found"](/en/self-host/deploy/quick-start/faqs#clone-fails-with-remote-branch-null-not-found) for details.
</Info>
</Step>
<Step title="Start Dify">
1. Navigate to the `docker` directory in the Dify source code:
```bash theme={null}
cd dify/docker
```
2. Copy the essential environment configuration file:
```bash theme={null}
cp .env.example .env
```
To customize your deployment later, see [Customize](#customize).
3. Start the containers:
<Note>
Dify requires Docker Compose 2.24.0 or later. Run `docker compose version` to confirm.
</Note>
```bash theme={null}
docker compose up -d
```
The following containers will be started:
* 7 core services: `api`, `api_websocket`, `worker`, `worker_beat`, `web`, `plugin_daemon`, `agent_backend`
* 8 dependent components: `weaviate`, `db_postgres`, `redis`, `nginx`, `ssrf_proxy`, `agent_ssrf_proxy`, `sandbox`, `local_sandbox`
* 1 one-time task: `init_permissions`, which sets storage file permissions and exits when done
4. Verify that all containers are running successfully:
```bash theme={null}
docker compose ps
```
Each container should be in the `Up` or `healthy` status. An `Exited` status for `init_permissions` is expected.
</Step>
</Steps>
## Access
1. Open the administrator initialization page to set up the admin account:
```bash theme={null}
# Local environment
http://localhost/install
# Server environment
http://your_server_ip/install
```
2. After completing the admin account setup, log in to Dify at:
```bash theme={null}
# Local environment
http://localhost
# Server environment
http://your_server_ip
```
## Customize
To customize your deployment, edit environment variables in the relevant file, then restart Dify.
<Steps>
<Step title="Edit Environment Variables">
* **Essential startup values** live in `docker/.env`, which you created from `docker/.env.example` during deployment. Edit them directly.
* **Optional or provider-specific settings** have templates under `docker/envs/`. To override a default value, copy the matching template (drop the `.example` suffix), then edit your copy.
For example:
```bash theme={null}
cd dify/docker
cp envs/vectorstores/milvus.env.example envs/vectorstores/milvus.env
```
Values in `docker/.env` take precedence over values in any `docker/envs/*.env` files.
<Tip>
For descriptions of every variable, see [Environment Variables](/en/self-host/deploy/configuration/environments).
</Tip>
</Step>
<Step title="Restart Dify">
```bash theme={null}
docker compose down
docker compose up -d
```
</Step>
</Steps>
## Upgrade
Upgrade steps may vary between releases. Refer to the upgrade guide for your target version provided in the [Releases](https://github.com/langgenius/dify/releases) page.
<Note>
After upgrading, compare each `.env.example` with its matching `.env` for new or changed variables.
If you've customized `docker-compose.yaml`, re-apply your changes onto the release's new file rather than keeping the old one. A release can add services that Dify needs to run.
</Note>
# FAQs
Source: https://docs.dify.ai/en/self-host/deploy/quick-start/faqs
## Deployment Methods
### Install Older Version
Use the `--branch` flag to install a specific version:
```bash theme={null}
git clone https://github.com/langgenius/dify.git --branch 0.15.3
```
The rest of the setup is identical to installing the latest version.
### Install Using ZIP Archive
For network-restricted environments or when git is unavailable:
```bash theme={null}
# Download latest release
wget -O dify.zip "$(curl -s https://api.github.com/repos/langgenius/dify/releases/latest | jq -r '.zipball_url')"
unzip dify.zip && rm dify.zip
```
Alternatively, download the ZIP on another device and transfer it manually.
**To upgrade**:
```bash theme={null}
wget -O dify-latest.zip "$(curl -s https://api.github.com/repos/langgenius/dify/releases/latest | jq -r '.zipball_url')"
unzip dify-latest.zip && rm dify-latest.zip
rsync -a dify-latest/ dify/
rm -rf dify-latest/
cd dify/docker
docker compose pull
docker compose up -d
```
### Clone Fails with "Remote branch null not found"
The clone command in [Deploy Dify with Docker Compose](/en/self-host/deploy/quick-start/docker-compose) resolves the latest Dify version through the GitHub API. When that request fails (usually due to GitHub's rate limit on unauthenticated requests), `jq` outputs `null`, and git reports `fatal: Remote branch null not found in upstream origin`.
Clone with an explicit version instead. Find the latest version number on [Dify releases](https://github.com/langgenius/dify/releases), then run:
```bash theme={null}
git clone --branch <version> https://github.com/langgenius/dify.git
```
Cloning without `--branch` also works. The Compose file on `main` pins the latest released images, so you still run release builds, but the deployment files themselves (the Compose file and environment templates) track development and can drift from the tagged release.
## Backup Procedures
### Create Backup Before Upgrading
Always backup before upgrading to prevent data loss:
```bash theme={null}
cp -r dify "dify.bak.$(date +%Y%m%d%H%M%S)"
```
This creates a timestamped backup for easy restoration.
## Reverse Proxy Setup
### Login Session Drops with Split Frontend and Backend Subdomains
If you have split web and API across subdomains behind a reverse proxy (for example, `app.example.com` for the UI and `api.example.com` for the backend), authentication cookies cannot reach both hosts. Login appears to succeed, but the session is dropped on the next request.
Set both variables in `.env`, then restart Dify:
* **`COOKIE_DOMAIN`**: set to the shared top-level domain (e.g., `example.com`). Leading dots are optional.
* **`NEXT_PUBLIC_COOKIE_DOMAIN`**: set to `1` to enable cross-subdomain cookies on the frontend.
```bash theme={null}
docker compose down
docker compose up -d
```
Cookies cannot cross top-level domains, so the frontend and backend must share the same registrable domain. For full details, see [environment variables](/en/self-host/deploy/configuration/environments).
# Common Issues
Source: https://docs.dify.ai/en/self-host/deploy/troubleshooting/common-issues
## Authentication & Access
### Reset admin password
For Docker Compose deployments:
```bash theme={null}
docker exec -it docker-api-1 flask reset-password
```
Enter the account email and new password when prompted.
For source code deployments, run the same command from the `api` directory.
### 401 errors after login
This typically happens after changing domains. Update these environment variables:
* `CONSOLE_CORS_ALLOW_ORIGINS` - Console CORS policy
* `WEB_API_CORS_ALLOW_ORIGINS` - Web app CORS policy
* `CONSOLE_API_URL` - Backend URL for console API
* `CONSOLE_WEB_URL` - Frontend URL for console web
* `SERVICE_API_URL` - Service API URL
* `APP_API_URL` - Web app API backend URL
* `APP_WEB_URL` - Web app URL
Restart after updating configuration.
## Configuration
### Change default port
Modify `.env` configuration:
```
EXPOSE_NGINX_PORT=80
EXPOSE_NGINX_SSL_PORT=443
```
For API service port changes, update the nginx configuration in `docker-compose.yaml`.
### Increase file upload limits
Update in `.env`:
* `UPLOAD_FILE_SIZE_LIMIT` - Maximum file size
* `NGINX_CLIENT_MAX_BODY_SIZE` - Must match to avoid issues
### Workflow complexity limits
Adjust `MAX_TREE_DEPTH` in `web/app/components/workflow/constants.ts` (default: 50).
Note: Excessive depth impacts performance.
### Node execution timeout
Set `TEXT_GENERATION_TIMEOUT_MS` in `.env` to control runtime per node.
## Email Configuration
Not receiving password reset emails? Configure mail settings in `.env`:
1. Set up mail parameters (SMTP settings)
2. Restart services:
```bash theme={null}
docker compose down
docker compose up -d
```
Check spam folder if emails still don't arrive.
### Invite members without email service
In local deployments without email configured, the invitation page displays a link after sending. Copy and forward this link to users manually.
## Database Issues
### Connection errors with pg\_hba.conf
If you see:
```
FATAL: no pg_hba.conf entry for host "172.19.0.7", user "postgres", database "dify", no encryption
```
Allow connections from the error's network segment:
```bash theme={null}
docker exec -it docker-db-1 sh -c "echo 'host all all 172.19.0.0/16 trust' >> /var/lib/postgresql/data/pgdata/pg_hba.conf"
docker-compose restart
```
### File not found error for encryption keys
This error occurs after changing deployment methods or deleting `api/storage/privkeys`:
```
FileNotFoundError: File not found
File "/www/wwwroot/dify/dify/api/libs/rsa.py", line 45, in decrypt
```
Reset encryption key pairs:
Docker Compose:
```bash theme={null}
docker exec -it docker-api-1 flask reset-encrypt-key-pair
```
Source code (from `api` directory):
```bash theme={null}
flask reset-encrypt-key-pair
```
<Warning>
This is irreversible. Existing LLM credentials and tool credentials (built-in, custom, and MCP tools) are purged for every workspace and must be re-entered.
</Warning>
## Workspace Management
### Rename workspace
Modify the `tenants` table in the database directly.
### Change application access domain
Update `APP_WEB_URL` in `docker-compose.yaml`.
# Docker Issues
Source: https://docs.dify.ai/en/self-host/deploy/troubleshooting/docker-issues
## Network & Connectivity
### 502 Bad Gateway
Nginx is forwarding to wrong container IPs. Get current container IPs:
```bash theme={null}
docker ps -q | xargs -n 1 docker inspect --format '{{ .Name }}: {{range .NetworkSettings.Networks}}{{.IPAddress}}{{end}}'
```
Find these lines:
```
/docker-web-1: 172.19.0.5
/docker-api-1: 172.19.0.7
```
Update `dify/docker/nginx/conf.d`:
* Replace `http://api:5001` with `http://172.19.0.7:5001`
* Replace `http://web:3000` with `http://172.19.0.5:3000`
Restart nginx or reload configuration. Note: IPs change on container restart.
### Cannot access localhost services
Docker containers can't reach host services via `127.0.0.1`. Use your machine's local network IP instead.
Example: For OpenLLM running on host, configure Dify with `http://192.168.1.100:port` (your actual local IP).
### Page loads forever with CORS errors
Domain/URL changes cause cross-origin issues. Update in `docker-compose.yml`:
* `CONSOLE_API_URL` - Backend URL for console API
* `CONSOLE_WEB_URL` - Frontend URL for console web
* `SERVICE_API_URL` - Service API URL
* `APP_API_URL` - Web app API backend URL
* `APP_WEB_URL` - Web app URL
## Mounting & Volumes
### Nginx configuration mount failure
Error:
```
Error mounting "/run/desktop/mnt/host/d/Documents/docker/nginx/nginx.conf" to rootfs at "/etc/nginx/nginx.conf": not a directory
```
Clone the complete project and run from docker directory:
```bash theme={null}
git clone https://github.com/langgenius/dify.git
cd dify/docker
docker compose up -d
```
### Port conflicts
Port 80 already in use? Either:
1. Stop the conflicting service (usually Apache/Nginx):
```bash theme={null}
sudo service nginx stop
sudo service apache2 stop
```
2. Or change port mapping in `docker-compose.yaml`:
```yaml theme={null}
ports:
- "8080:80" # Map to different port
```
## Container Management
### View background shell outputs
List running shells:
```bash theme={null}
docker exec -it docker-api-1 ls /tmp/shells/
```
Check shell output:
```bash theme={null}
docker exec -it docker-api-1 cat /tmp/shells/[shell-id]/output.log
```
### Container restart issues
After system reboot, containers may fail to connect. Ensure proper startup order:
```bash theme={null}
docker compose down
docker compose up -d
```
Wait for all services to be healthy before accessing.
## SSRF Proxy
The `ssrf_proxy` container prevents Server-Side Request Forgery attacks.
### Customize proxy rules
Edit `docker/volumes/ssrf_proxy/squid.conf` to add ACL rules:
```
# Block access to sensitive internal IP
acl restricted_ip dst 192.168.101.19
acl localnet src 192.168.101.0/24
http_access deny restricted_ip
http_access allow localnet
http_access deny all
```
Restart the proxy container after changes.
### Why is SSRF\_PROXY needed?
Prevents services from making unauthorized requests to internal network resources. The proxy intercepts and filters all outbound requests from sandboxed services.
# Third-Party Integrations
Source: https://docs.dify.ai/en/self-host/deploy/troubleshooting/integrations
## Notion Integration
Notion OAuth only supports HTTPS, so local deployments must use internal integration.
### Configure environment variables
Set in `.env`:
```
NOTION_INTEGRATION_TYPE=internal
NOTION_INTERNAL_SECRET=your_internal_secret_here
```
For public integration (HTTPS only):
```
NOTION_INTEGRATION_TYPE=public
NOTION_CLIENT_SECRET=oauth_client_secret
NOTION_CLIENT_ID=oauth_client_id
```
Get credentials from [Notion Integrations](https://www.notion.so/my-integrations).
## Text-to-Speech (TTS)
### FFmpeg not installed error
OpenAI TTS requires FFmpeg for audio stream segmentation.
**macOS**:
```bash theme={null}
brew install ffmpeg
```
**Ubuntu**:
```bash theme={null}
sudo apt-get update
sudo apt-get install ffmpeg
```
**CentOS**:
```bash theme={null}
sudo yum install epel-release
sudo rpm -Uvh http://li.nux.ro/download/nux/dextop/el7/x86_64/nux-dextop-release-0-5.el7.nux.noarch.rpm
sudo yum update
sudo yum install ffmpeg ffmpeg-devel
```
**Windows**:
1. Download from [FFmpeg website](https://ffmpeg.org/download.html)
2. Extract and move to `C:\Program Files\`
3. Add FFmpeg bin directory to system PATH
4. Verify: `ffmpeg -version`
## Model Tokenizers
### Can't load tokenizer for 'gpt2'
Error:
```
Can't load tokenizer for 'gpt2'. If you were trying to load it from 'https://huggingface.co/models'...
```
Configure Hugging Face mirror or proxy in environment variables. See [environment documentation](https://docs.dify.ai/en/self-host/deploy/configuration/environments) for details.
## Security Policies
### Content Security Policy (CSP)
Enable CSP to reduce XSS attacks.
In `.env`:
```
CSP_WHITELIST=https://api.example.com,https://cdn.example.com
```
Add all domains used by your application (APIs, CDNs, analytics, etc.).
See [MDN CSP documentation](https://developer.mozilla.org/en-US/docs/Web/HTTP/CSP) for more information.
# Storage & Migration
Source: https://docs.dify.ai/en/self-host/deploy/troubleshooting/storage-and-migration
## Vector Database Migration
### Migrate from Weaviate to another database
1. **Update configuration**
Source code deployment (`.env`):
```
VECTOR_STORE=qdrant
```
Docker Compose (`docker-compose.yaml`):
```yaml theme={null}
VECTOR_STORE: qdrant
```
2. **Run migration**
```bash theme={null}
# Source code
flask vdb-migrate
# Docker
docker exec -it docker-api-1 flask vdb-migrate
```
Tested databases: Qdrant, Milvus, AnalyticDB
## Storage Migration
### Move from local to cloud storage
Migrate files from local storage to cloud providers (e.g., Alibaba Cloud OSS):
1. **Configure cloud storage**
`.env` or `docker-compose.yaml`:
```
STORAGE_TYPE=aliyun-oss
# Add OSS credentials
```
2. **Migrate data**
Source code:
```bash theme={null}
flask upload-private-key-file-to-cloud-storage
flask upload-local-files-to-cloud-storage
```
Docker:
```bash theme={null}
docker exec -it docker-api-1 flask upload-private-key-file-to-cloud-storage
docker exec -it docker-api-1 flask upload-local-files-to-cloud-storage
```
## Data Cleanup
### Delete old logs
1. **Get tenant ID**
```bash theme={null}
docker exec -it docker-api-1 bash -c "echo 'from models import Tenant; db.session.query(Tenant.id, Tenant.name).all(); quit()' | flask shell"
```
2. **Delete logs older than X days**
```bash theme={null}
docker exec -it docker-api-1 flask clear-free-plan-tenant-expired-logs \
--days 30 \
--batch 100 \
--tenant_ids 618b5d66-a1f5-4b6b-8d12-f171182a1cb2
```
3. **Remove exported logs** (optional)
```bash theme={null}
docker exec -it docker-api-1 bash -c 'rm -rf ${OPENDAL_FS_ROOT}/free_plan_tenant_expired_logs'
```
### Remove orphaned files
**Warning**: Back up database and storage before running. Run during maintenance window.
1. **Clean database records**
```bash theme={null}
docker exec -it docker-api-1 flask clear-orphaned-file-records
# Use -f flag to skip confirmation
```
2. **Delete orphaned files from storage**
```bash theme={null}
docker exec -it docker-api-1 flask remove-orphaned-files-on-storage
# Use -f flag to skip confirmation
```
Note: Only works with OpenDAL storage (`STORAGE_TYPE=opendal`).
## Backup & Recovery
### Create backup before upgrade
```bash theme={null}
cp -r dify "dify.bak.$(date +%Y%m%d%H%M%S)"
```
### What to backup
For Docker Compose deployments:
* Entire `dify/docker/volumes` directory
For source deployments:
* Database
* Storage configuration
* Vector database data
* Environment files
### Database maintenance
After deleting logs, reclaim storage:
PostgreSQL:
```sql theme={null}
VACUUM FULL;
```
## Upgrade Process
### Version upgrade
Image deployment:
```bash theme={null}
docker compose pull
docker compose up -d
```
Source code:
```bash theme={null}
git pull
cd api
flask db upgrade
```
### Database schema migration
Always required for source code updates:
```bash theme={null}
cd api
flask db upgrade
```
# Weaviate Migration Guide upgrading to Client v4 and Server 1.27+
Source: https://docs.dify.ai/en/self-host/deploy/troubleshooting/weaviate-v4-migration
> This guide explains how to migrate from Weaviate client v3 to v4.17.0 and upgrade your Weaviate server from version 1.19.0 to 1.27.0 or higher. This migration is required for Dify versions that include the weaviate-client v4 upgrade.
## Overview
Starting with **Dify v1.9.2**, the weaviate-client has been upgraded from v3 to v4.17.0. This upgrade brings significant performance improvements and better stability, but requires **Weaviate server version 1.27.0 or higher**.
<Warning>
**BREAKING CHANGE**: The new weaviate-client v4 is NOT backward compatible with Weaviate server versions below 1.27.0. If you are running a self-hosted Weaviate instance on version 1.19.0 or older, you must upgrade your Weaviate server before upgrading Dify.
</Warning>
### Who Is Affected?
This migration affects:
* Self-hosted Dify users running their own Weaviate instances on versions below 1.27.0
* Users currently on Weaviate server version 1.19.0-1.26.x
* Users upgrading to Dify versions with weaviate-client v4
**Not affected**:
* Cloud-hosted Weaviate users (Weaviate Cloud manages the server version)
* Users already on Weaviate 1.27.0+ can upgrade Dify without additional steps
* Users running Dify's default Docker Compose setup (Weaviate version is updated automatically)
## Breaking Changes
### Client v4 Requirements
The weaviate-client v4 introduces several breaking changes:
1. **Minimum Server Version**: Requires Weaviate server 1.27.0 or higher
2. **API Changes**: New import structure (`weaviate.classes` instead of `weaviate.client`)
3. **gRPC Support**: Uses gRPC by default on port 50051 for improved performance
4. **Authentication Changes**: Updated authentication methods and configuration
### Why Upgrade?
* **Performance**: Significantly faster query and import operations via gRPC (50051)
* **Stability**: Better connection handling and error recovery
* **Future Compatibility**: Access to latest Weaviate features and ongoing support
* **Security**: Weaviate 1.19.0 is over a year old and no longer receives security updates
## Version Compatibility Matrix
| Dify Version | Weaviate-client Version | Compatible Weaviate Server Versions |
| ------------ | ----------------------- | ----------------------------------- |
| ≤ 1.9.1 | v3.x | 1.19.0 - 1.26.x |
| ≥ 1.9.2 | v4.17.0 | 1.27.0+ (tested up to 1.33.1) |
<Info>
This migration applies to any Dify version using weaviate-client v4.17.0 or higher.
</Info>
<Info>
Weaviate server version 1.19.0 was released over a year ago and is now outdated. Upgrading to 1.27.0+ provides access to numerous improvements in performance, stability, and features.
</Info>
## Prerequisites
Before starting the migration, complete these steps:
1. **Check Your Current Weaviate Version**
```bash theme={null}
curl http://localhost:8080/v1/meta
```
Look for the `version` field in the response.
2. **Backup Your Data**
* Create a complete backup of your Weaviate data
* Backup your Docker volumes if using Docker Compose
* Document your current configuration settings
3. **Review System Requirements**
* Ensure sufficient disk space for database migration
* Verify network connectivity between Dify and Weaviate
* Confirm gRPC port (50051) is accessible if using external Weaviate
4. **Plan Downtime**
* The migration will require service downtime
* Notify users if running in production
* Schedule migration during low-traffic periods
## Migration Paths
Choose the migration path that matches your deployment setup and current Weaviate version.
### Choose Your Path
* **Path A – Migration with Backup (from 1.19)**: Recommended if you are still on Weaviate 1.19. You will create a backup, upgrade to 1.27+, repair any orphaned data, and then migrate the schema.
* **Path B – Direct Recovery (already on 1.27+)**: Use this if you already upgraded to 1.27+ and your knowledge bases stopped working. This path focuses on repairing the data layout and running the schema migration.
<Warning>
Do **not** attempt to downgrade back to 1.19. The schema format is incompatible and will lead to data loss.
</Warning>
### Path A: Migration with Backup (From 1.19)
<Info>
Safest path. Creates a backup before upgrading so you can restore if anything goes wrong.
</Info>
#### Prerequisites
* Currently running Weaviate 1.19
* Docker + Docker Compose installed
* Python 3.12 for the [schema migration script](https://github.com/langgenius/dify-docs/blob/main/assets/migrate_weaviate_collections.py)
#### Step A1: Enable the Backup Module on Weaviate 1.19
Edit `docker/docker-compose.yaml` so the `weaviate` service includes backup configuration:
```yaml theme={null}
weaviate:
image: semitechnologies/weaviate:1.19.0
volumes:
- ./volumes/weaviate:/var/lib/weaviate
- ./volumes/weaviate_backups:/var/lib/weaviate/backups
ports:
- "8080:8080"
- "50051:50051"
environment:
ENABLE_MODULES: backup-filesystem
BACKUP_FILESYSTEM_PATH: /var/lib/weaviate/backups
# ... rest of your environment variables
```
Restart Weaviate to apply the change:
```bash theme={null}
cd docker
docker compose down
docker compose --profile up -d
sleep 10
```
#### Step A2: Create a Backup
1. **List your collections**:
```bash theme={null}
curl -s -H "Authorization: Bearer <WEAVIATE_API_KEY>" \
"http://localhost:8080/v1/schema" | \
python3 -c "
import json, sys
data = json.load(sys.stdin)
print("Collections:")
for cls in data.get('classes', []):
print(f" - {cls['class']}")
"
```
2. **Trigger the backup**: include specific collection names if you prefer.
```bash theme={null}
curl -X POST \
-H "Authorization: Bearer <WEAVIATE_API_KEY>" \
-H "Content-Type: application/json" \
"http://localhost:8080/v1/backups/filesystem" \
-d '{
"id": "kb-backup",
"include": ["Vector_index_COLLECTION1_Node", "Vector_index_COLLECTION2_Node"]
}'
```
3. **Check backup status**:
```bash theme={null}
sleep 5
curl -s -H "Authorization: Bearer <WEAVIATE_API_KEY>" \
"http://localhost:8080/v1/backups/filesystem/kb-backup" | \
python3 -m json.tool | grep status
```
4. **Verify backup files exist**:
```bash theme={null}
ls -lh docker/volumes/weaviate_backups/kb-backup/
```
#### Step A3: Upgrade to Weaviate 1.27+
1. **Upgrade Dify to a version that ships Weaviate 1.27+**:
```bash theme={null}
cd /path/to/dify
git fetch origin
git checkout main # or a tagged release that includes the upgrade
```
2. **Confirm the new Weaviate image**:
```bash theme={null}
grep "image: semitechnologies/weaviate" docker/docker-compose.yaml
```
3. **Restart with the new version**:
```bash theme={null}
cd docker
docker compose down
docker compose up -d
sleep 20
```
#### Step A4: Fix Orphaned LSM Data (if present)
You can fix orphaned LSM data either from the host or inside the container:
**Option A: From host (if volumes are mounted)**:
```bash theme={null}
cd docker/volumes/weaviate
for dir in vector_index_*_node_*_lsm; do
[ -d "$dir" ] || continue
index_id=$(echo "$dir" | sed -n 's/vector_index_\([^_]*_[^_]*_[^_]*_[^_]*_[^_]*\)_node_.*/\1/p')
shard_id=$(echo "$dir" | sed -n 's/.*_node_\([^_]*\)_lsm/\1/p')
mkdir -p "vector_index_${index_id}_node/$shard_id/lsm"
cp -a "$dir/"* "vector_index_${index_id}_node/$shard_id/lsm/"
echo "✓ Copied $dir"
done
cd ../../
docker compose restart weaviate
sleep 15
```
**Option B: Inside Weaviate container (recommended)**:
```bash theme={null}
cd /path/to/dify/docker
docker compose exec -it weaviate /bin/sh
# Inside container
cd /var/lib/weaviate
for dir in vector_index_*_node_*_lsm; do
[ -d "$dir" ] || continue
index_id=$(echo "$dir" | sed -n 's/vector_index_\([^_]*_[^_]*_[^_]*_[^_]*_[^_]*\)_node_.*/\1/p')
shard_id=$(echo "$dir" | sed -n 's/.*_node_\([^_]*\)_lsm/\1/p')
mkdir -p "vector_index_${index_id}_node/$shard_id/lsm"
cp -a "$dir/"* "vector_index_${index_id}_node/$shard_id/lsm/"
echo "✓ Copied $dir"
done
exit
# Restart Weaviate
docker compose restart weaviate
sleep 15
```
#### Step A5: Migrate the Schema
1. **Install dependencies** (in a temporary virtualenv is fine):
```bash theme={null}
cd /path/to/dify
python3 -m venv weaviate_migration_env
source weaviate_migration_env/bin/activate
pip install weaviate-client requests
```
2. **Run the [migration script](https://github.com/langgenius/dify-docs/blob/main/assets/migrate_weaviate_collections.py)** either locally or inside the Worker container.\
**Option A: Run locally (if you have Python 3.12 and dependencies installed)**:
```bash theme={null}
python3 migrate_weaviate_collections.py
```
**Option B: Run inside Worker container (recommended for Docker setups)**:
```bash theme={null}
# Copy script to storage directory
cp migrate_weaviate_collections.py /path/to/dify/docker/volumes/app/storage/
# Enter worker container
cd /path/to/dify/docker
docker compose exec -it worker /bin/bash
# Run migration script (use --no-cache for Dify 1.11.0+)
uv run --no-cache /app/api/storage/migrate_weaviate_collections.py
# Exit container
exit
```
<Info>
The migration script uses environment variables for configuration, making it suitable for running inside Docker containers. For Dify 1.11.0+, if you encounter permission errors with `uv`, use `uv run --no-cache` instead.
</Info>
3. **Restart Dify services**:
```bash theme={null}
cd docker
docker compose restart api worker worker_beat
sleep 15
```
4. **Verify in the UI**: open Dify, test retrieval against your migrated knowledge bases.
<Warning>
For large collections (over 10,000 objects), verify that the object count matches between old and new collections. The migration script will display verification counts automatically.
</Warning>
<Info>
After confirming a healthy migration, you can delete `weaviate_migration_env` and the backup files to reclaim disk space.
</Info>
### Path B: Direct Recovery (Already on 1.27+)
<Warning>
Only use this path if you already upgraded to 1.27+ and your knowledge bases stopped working. You cannot create a 1.19 backup anymore, so you must repair the data in place.
</Warning>
#### Prerequisites
* Currently running Weaviate 1.27+ (including 1.33)
* Docker + Docker Compose installed
* Python 3.12 for the [migration script](https://github.com/langgenius/dify-docs/blob/main/assets/migrate_weaviate_collections.py)
#### Step B1: Repair Orphaned LSM Data
Stop Weaviate and fix orphaned LSM data:
```bash theme={null}
cd /path/to/dify/docker
docker compose stop weaviate
# Option A: From host (if volumes are mounted)
cd volumes/weaviate
for dir in vector_index_*_node_*_lsm; do
[ -d "$dir" ] || continue
index_id=$(echo "$dir" | sed -n 's/vector_index_\([^_]*_[^_]*_[^_]*_[^_]*_[^_]*\)_node_.*/\1/p')
shard_id=$(echo "$dir" | sed -n 's/.*_node_\([^_]*\)_lsm/\1/p')
mkdir -p "vector_index_${index_id}_node/$shard_id/lsm"
cp -a "$dir/"* "vector_index_${index_id}_node/$shard_id/lsm/"
echo "✓ Copied $dir"
done
# Option B: Inside container (recommended)
docker compose run --rm --entrypoint /bin/sh weaviate -c "
cd /var/lib/weaviate
for dir in vector_index_*_node_*_lsm; do
[ -d \"\$dir\" ] || continue
index_id=\$(echo \"\$dir\" | sed -n 's/vector_index_\([^_]*_[^_]*_[^_]*_[^_]*_[^_]*\)_node_.*/\1/p')
shard_id=\$(echo \"\$dir\" | sed -n 's/.*_node_\([^_]*\)_lsm/\1/p')
mkdir -p \"vector_index_\${index_id}_node/\$shard_id/lsm\"
cp -a \"\$dir/\"* \"vector_index_\${index_id}_node/\$shard_id/lsm/\"
echo \"✓ Copied \$dir\"
done
"
```
Restart Weaviate:
```bash theme={null}
docker compose start weaviate
sleep 15
```
List collections and confirm object counts are non-zero:
```bash theme={null}
curl -s -H "Authorization: Bearer <WEAVIATE_API_KEY>" \
"http://localhost:8080/v1/schema" | python3 -c "
import sys, json
for cls in json.load(sys.stdin).get('classes', []):
if cls['class'].startswith('Vector_index_'):
print(cls['class'])
"
curl -s -H "Authorization: Bearer <WEAVIATE_API_KEY>" \
"http://localhost:8080/v1/objects?class=YOUR_COLLECTION_NAME&limit=0" | \
python3 -c "import sys, json; print(json.load(sys.stdin).get('totalResults', 0))"
```
#### Step B2: Run the Schema Migration
Follow the same commands as [Step A5](#step-a5-migrate-the-schema). You can run the script locally or inside the Worker container:
**To run inside Worker container**:
```bash theme={null}
# Copy script to storage directory
cp migrate_weaviate_collections.py /path/to/dify/docker/volumes/app/storage/
# Enter worker container
cd /path/to/dify/docker
docker compose exec -it worker /bin/bash
# Run migration script
uv run --no-cache /app/api/storage/migrate_weaviate_collections.py
# Exit and restart services
exit
docker compose restart api worker worker_beat
```
<Info>
The migration script uses cursor-based pagination to safely handle large
collections. Verify object counts match after migration completes.
</Info>
#### Step B3: Verify in Dify
* Open Dify’s Knowledge Base UI.
* Use Retrieval Testing to confirm queries return results.
* If errors persist, inspect `docker compose logs weaviate` for additional repair steps (see [Troubleshooting](#troubleshooting)).
## Data Migration for Legacy Versions
<Warning>
**CRITICAL: Data Migration Required**
**Your existing knowledge bases will NOT work after upgrade without migration!**
**Why Migration is Needed**:
* Old data: Created with Weaviate v3 client (simple schema)
* New code: Requires Weaviate v4 format (extended schema)
* **Incompatible**: Old data missing required properties
**Migration Options**:
* Option A: Use Weaviate Backup/Restore
* Option B: Re-index from Original Documents
* Option C: Keep Old Weaviate (Don't Upgrade Yet) If you can't afford downtime or data loss.
</Warning>
### Automatic Migration
In most cases, Weaviate 1.27.0 will automatically migrate data from 1.19.0:
1. Stop Weaviate 1.19.0
2. Start Weaviate 1.27.0 with the same data directory
3. Weaviate will detect the old format and migrate automatically
4. Monitor logs for migration progress and any errors
### Manual Migration (If Automatic Fails)
If automatic migration fails, use Weaviate's export/import tools:
#### 1. Export Data from Old Version
Use the Cursor API or backup feature to export all data. For large datasets, use Weaviate's backup API:
```bash theme={null}
# Using backup API (recommended)
curl -X POST "http://localhost:8080/v1/backups/filesystem" \
-H "Content-Type: application/json" \
-d '{"id": "pre-migration-backup"}'
```
#### 2. Import Data to New Version
After upgrading to Weaviate 1.27.0, restore the backup:
```bash theme={null}
curl -X POST "http://localhost:8080/v1/backups/filesystem/pre-migration-backup/restore" \
-H "Content-Type: application/json"
```
<Info>
For comprehensive migration guidance, especially for complex schemas or large datasets, refer to the official [Weaviate Migration Guide](https://weaviate.io/developers/weaviate/installation/migration).
</Info>
## Configuration Changes
### New Environment Variables
The following new environment variable is available in Dify versions with weaviate-client v4:
#### WEAVIATE\_GRPC\_ENDPOINT
**Description**: Specifies the gRPC endpoint for Weaviate connections. Using gRPC significantly improves performance for batch operations and queries.
**Format**: `hostname:port` (NO protocol prefix)
**Default Ports**:
* Insecure: 50051
* Secure (TLS): 443
**Examples**:
```bash theme={null}
# Docker Compose (internal network)
WEAVIATE_GRPC_ENDPOINT=weaviate:50051
# External server (insecure)
WEAVIATE_GRPC_ENDPOINT=192.168.1.100:50051
# External server with custom port
WEAVIATE_GRPC_ENDPOINT=weaviate.example.com:9090
# Weaviate Cloud (secure/TLS on port 443)
WEAVIATE_GRPC_ENDPOINT=your-instance.weaviate.cloud:443
```
<Warning>
Do NOT include protocol prefixes like `grpc://` or `http://` in the WEAVIATE\_GRPC\_ENDPOINT value. Use only `hostname:port`.
</Warning>
### Updated Environment Variables
All existing Weaviate environment variables remain the same:
* **WEAVIATE\_ENDPOINT**: HTTP endpoint for Weaviate (e.g., `http://weaviate:8080`)
* **WEAVIATE\_API\_KEY**: API key for authentication (if enabled)
* **WEAVIATE\_BATCH\_SIZE**: Batch size for imports (default: 100)
* **WEAVIATE\_GRPC\_ENABLED**: Enable/disable gRPC (default: true in v4)
### Complete Configuration Example
```bash theme={null}
# docker/.env or environment configuration
VECTOR_STORE=weaviate
# HTTP Endpoint (required)
WEAVIATE_ENDPOINT=http://weaviate:8080
# Authentication (if enabled on your Weaviate instance)
WEAVIATE_API_KEY=your-secret-api-key
# gRPC Configuration (recommended for performance)
WEAVIATE_GRPC_ENABLED=true
WEAVIATE_GRPC_ENDPOINT=weaviate:50051
# Batch Import Settings
WEAVIATE_BATCH_SIZE=100
```
## Verification Steps
After completing the migration, verify everything is working correctly:
### 1. Check Weaviate Connection
Verify Weaviate is accessible and running the correct version:
```bash theme={null}
# Check HTTP endpoint and version
curl http://your-weaviate-host:8080/v1/meta | jq '.version'
# Should return 1.27.0 or higher
```
### 2. Verify Dify Connection
Check the Dify logs for successful Weaviate connection:
```bash theme={null}
docker compose logs api | grep -i weaviate
```
Look for messages indicating successful connection without "No module named 'weaviate.classes'" errors.
### 3. Test Knowledge Base Creation
1. Log into your Dify instance
2. Navigate to **Knowledge Base** section
3. Create a new knowledge base
4. Upload a test document (PDF, TXT, or MD)
5. Wait for indexing to complete
6. Check that status changes from "QUEUING" → "INDEXING" → "AVAILABLE"
<Info>
If documents get stuck in "QUEUING" status, check that the Celery worker is running: `docker compose logs worker`.
</Info>
### 4. Test Vector Search
1. Create or open a chat application with knowledge base integration
2. Ask a question that should retrieve information from your knowledge base
3. Verify that relevant results are returned with correct scores
4. Check the citation/source links work correctly
### 5. Verify gRPC Performance
If gRPC is enabled, you should see improved performance:
```bash theme={null}
# Check if gRPC port is accessible
docker exec -it dify-api-1 nc -zv weaviate 50051
# Monitor query times in logs
docker compose logs -f api | grep -i "query_time\|duration"
```
<Info>
With gRPC properly configured, vector search queries should be 2-5x faster compared to HTTP-only connections.
</Info>
## Troubleshooting
### Issue: "No module named 'weaviate.classes'"
**Cause**: The weaviate-client v4 is not installed, or v3 is still being used.
**Solution**:
```bash theme={null}
# For Docker installations, ensure you're running the correct Dify version
docker compose pull
docker compose down
docker compose up -d
# For source installations
pip uninstall weaviate-client
pip install weaviate-client==4.17.0
```
### Issue: Connection Refused on gRPC Port (50051)
**Cause**: Port 50051 is not exposed, not accessible, or Weaviate is not listening on it.
**Solution**:
1. **For Docker Compose users with bundled Weaviate**:
The port is available internally between containers. No action needed unless you're connecting from outside Docker.
2. **For external Weaviate**:
```bash theme={null}
# Check if Weaviate is listening on 50051
docker ps | grep weaviate
# Look for "0.0.0.0:50051->50051/tcp"
# If not exposed, restart with port mapping
docker run -p 8080:8080 -p 50051:50051 ...
```
3. **Check firewall rules**:
```bash theme={null}
# Linux
sudo ufw allow 50051/tcp
# Check if port is listening
netstat -tlnp | grep 50051
```
### Issue: Authentication Errors (401 Unauthorized)
**Cause**: API key mismatch or authentication configuration issue.
**Solution**:
1. Verify API key matches in both Weaviate and Dify:
```bash theme={null}
# Check Weaviate authentication
curl http://localhost:8080/v1/meta | jq '.authentication'
# Check Dify configuration
docker compose exec api env | grep WEAVIATE_API_KEY
```
2. If using anonymous access:
```yaml theme={null}
# Weaviate docker-compose.yaml
weaviate:
environment:
AUTHENTICATION_ANONYMOUS_ACCESS_ENABLED: "true"
AUTHENTICATION_APIKEY_ENABLED: "false"
```
Then remove `WEAVIATE_API_KEY` from Dify configuration.
### Issue: Documents Stuck in "QUEUING" Status
**Cause**: Celery worker not running or not connected to Redis.
**Solution**:
```bash theme={null}
# Check if worker is running
docker compose ps worker
# Check worker logs
docker compose logs worker | tail -50
# Check Redis connection
docker compose exec api redis-cli -h redis -p 6379 -a difyai123456 ping
# Should return "PONG"
# Restart worker
docker compose restart worker
```
### Issue: Slow Performance After Migration
**Cause**: gRPC not enabled or configured incorrectly.
**Solution**:
1. Verify gRPC configuration:
```bash theme={null}
docker compose exec api env | grep WEAVIATE_GRPC
```
Should show:
```
WEAVIATE_GRPC_ENABLED=true
WEAVIATE_GRPC_ENDPOINT=weaviate:50051
```
2. Test gRPC connectivity:
```bash theme={null}
docker exec -it dify-api-1 nc -zv weaviate 50051
# Should return "succeeded"
```
3. If still slow, check network latency between Dify and Weaviate
### Issue: Schema Migration Errors
**Cause**: Incompatible schema changes between Weaviate versions or corrupted data.
**Solution**:
1. Check Weaviate logs for specific error messages:
```bash theme={null}
docker compose logs weaviate | tail -100
```
2. List current schema:
```bash theme={null}
curl http://localhost:8080/v1/schema
```
3. If necessary, delete corrupted collections (⚠️ this deletes all data):
```bash theme={null}
# Backup first!
curl -X DELETE http://localhost:8080/v1/schema/YourCollectionName
```
4. Restart Dify to recreate schema:
```bash theme={null}
docker compose restart api worker
```
<Warning>
Deleting collections removes all data. Only do this if you have a backup and are prepared to re-index all content.
</Warning>
### Issue: Docker Volume Permission Errors
**Cause**: User ID mismatch in Docker containers.
**Solution**:
```bash theme={null}
# Check ownership of Weaviate data directory
ls -la docker/volumes/weaviate/
# Fix permissions (use the UID shown in error messages)
sudo chown -R 1000:1000 docker/volumes/weaviate/
# Restart services
docker compose restart weaviate
```
### Issue: Permission Denied When Running Migration Script (Dify 1.11.0+)
**Cause**: The `/home/dify` directory may not exist in newer Dify versions, causing `uv` cache creation to fail.
**Solution**:
```bash theme={null}
# Option 1: Use --no-cache flag (recommended)
uv run --no-cache migrate_weaviate_collections.py
# Option 2: Run as root user
docker compose exec -u root worker /bin/bash
uv run migrate_weaviate_collections.py
```
## Rollback Plan
If the migration fails and you need to rollback:
### Step 1: Stop Services
```bash theme={null}
cd /path/to/dify/docker
docker compose down
```
### Step 2: Restore Backup
```bash theme={null}
# Remove current volumes
rm -rf volumes/weaviate
# Restore from backup
tar -xvf ../weaviate-backup-TIMESTAMP.tgz
```
### Step 3: Revert Dify Version
```bash theme={null}
cd /path/to/dify
git checkout <previous-version-tag>
cd docker
docker compose pull
```
### Step 4: Restart Services
```bash theme={null}
docker compose up -d
```
### Step 5: Verify Rollback
Check that services are running with old versions:
```bash theme={null}
# Check versions
docker compose exec api pip show weaviate-client
curl http://localhost:8080/v1/meta | jq '.version'
# Check for errors
docker compose logs | grep -i error
```
<Info>
Always test the rollback procedure in a staging environment first if possible. Maintain multiple backup copies before attempting major migrations.
</Info>
## Additional Resources
### Official Documentation
* [Weaviate Migration Guide](https://weaviate.io/developers/weaviate/installation/migration)
* [Weaviate v4 Client Documentation](https://weaviate.io/developers/weaviate/client-libraries/python)
* [Weaviate Backup and Restore](https://weaviate.io/developers/weaviate/configuration/backups)
* [Dify Self-Hosting Guide](/en/self-host/deploy/quick-start/docker-compose)
* [Dify Environment Variables](/en/self-host/deploy/configuration/environments)
### Community Resources
* [Dify GitHub Repository](https://github.com/langgenius/dify)
* [Dify GitHub Issues - Weaviate](https://github.com/langgenius/dify/issues?q=is%3Aissue+weaviate)
* [Weaviate Community Forum](https://forum.weaviate.io/)
### Migration Tools
* [Weaviate Python Client v4](https://github.com/weaviate/weaviate-python-client)
* [Weaviate Backup Tools](https://github.com/weaviate/weaviate/tree/main/tools)
## Summary
This migration brings important improvements to Dify's vector storage capabilities:
* **Better Performance**: gRPC support dramatically improves query and import speeds (2-5x faster)
* **Improved Stability**: Enhanced connection handling and error recovery
* **Security**: Access to security updates and patches not available in Weaviate 1.19.0
* **Future-Proof**: Access to latest Weaviate features and ongoing support
While this is a breaking change requiring server upgrade for users on old versions, the benefits significantly outweigh the migration effort. Most Docker Compose users can complete the migration in under 15 minutes with the automatic update.
<Info>
If you encounter any issues not covered in this guide, please report them on the [Dify GitHub Issues page](https://github.com/langgenius/dify/issues) with the label "weaviate" and "migration".
</Info>
# Orchestration Logic
Source: https://docs.dify.ai/en/self-host/use-dify/build/orchestrate-node
How to arrange, nest, or reuse nodes when building a Workflow or Chatflow
## Serial and Parallel Execution
<Frame>
<img alt="Serial vs. Parallel Execution" />
</Frame>
When building a workflow, you can arrange nodes in series or in parallel:
* **In series**, nodes run one after another. Each node can read variables from any node earlier in the chain.
* **In parallel**, nodes run at the same time. They can't read each other's variables, but where parallel branches converge, the downstream node can read from all of them.
<Info>
A single execution path supports up to 50 nodes. You can change this limit with the `MAX_TREE_DEPTH` environment variable.
</Info>
## Node Reuse
All nodes except User Input can be copied and pasted within the same workflow, across workflows, or across Dify instances, though there might be compatibility issues between Dify versions.
<Note>
Pasting across workflows or Dify instances requires the Dify page to be served over HTTPS or accessed via a loopback address (such as `http://localhost` or `http://127.0.0.1`).
</Note>
When you paste a node, its configuration moves with it, but the availability of anything that depends on the surrounding environment is re-evaluated at the destination:
* **Workflow-specific resources**, such as variables
* **Workspace-specific resources**, such as integrations and knowledge bases
## Iteration and Loop
For nodes that should run multiple times (once per item in a list or until a condition is met), place them inside an [Iteration](/en/self-host/use-dify/nodes/iteration) or [Loop](/en/self-host/use-dify/nodes/loop) node.
# Workflow & Chatflow
Source: https://docs.dify.ai/en/self-host/use-dify/build/workflow-chatflow
Build agentic workflows that combine AI models, tools, and logic into reliable, repeatable processes
## Why Agentic Workflows
AI models are powerful, but on their own they can be unpredictable—they may hallucinate, miss steps, or produce inconsistent outputs. In production environments, especially for teams and enterprises where reliability matters, you need more control over how AI operates.
Agentic workflows solve this by embedding AI capabilities within a structured, repeatable process. Instead of relying on a single model to figure everything out, you design a flow that orchestrates models, tools, and logic step by step—with clear conditions, checkpoints, and fallback paths.
The AI is still doing the heavy lifting, but within boundaries you define.
## Workflow vs. Chatflow
Dify offers two app types for building agentic workflows: **Workflow** and **Chatflow**. Both are built on a shared visual canvas and node system.
To build a flow, connect nodes that each handle a specific step, such as calling a model, retrieving knowledge, running code, or branching on conditions. Most of the work is **drag, connect, and configure**—code is only needed when your logic calls for it.
Their core difference is how users interact with the app:
* A **Workflow** runs once from start to finish.
It takes an input, processes it through the flow, and returns a result. Use it for tasks like automated report generation, data processing pipelines, or batch processing.
* A **Chatflow** adds a conversation layer.
Users interact through a chat interface, and each message triggers the flow you designed before a response is generated. Use it for interactive assistants, guided Q\&A, or any conversational scenario that requires structured processing behind each reply.
<Tip>
Chatflows support optional features like content moderation, text to speech, and more. See [App Toolkit](/en/self-host/use-dify/build/additional-features) for details.
</Tip>
They also start and end with different nodes:
| | Workflow | Chatflow |
| :---------- | :---------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------ |
| Starts with | [User Input](/en/self-host/use-dify/nodes/user-input) or [Trigger](/en/self-host/use-dify/nodes/trigger/overview) | User Input |
| Ends with | [Output](/en/self-host/use-dify/nodes/output) node (optional) | [Answer](/en/self-host/use-dify/nodes/answer) node (required) |
A Trigger runs a workflow automatically: on a schedule, when a webhook fires, or from an integration event. Chatflows always start from a user message, so they don't have Triggers.
For how to compose either type, see [Orchestration Logic](/en/self-host/use-dify/build/orchestrate-node).
# Use Dify
Source: https://docs.dify.ai/en/self-host/use-dify/getting-started/introduction
Orchestrate, publish, and monitor AI applications in your workspace
<div>
<div>
<div>
<h1>Use Dify</h1>
<p>
Your workspace is where everything happens: build AI applications, ground them in your own data, then publish and monitor them.
</p>
<div>
<a href="/en/quick-start">Quick Start</a>
<span>
<a href="/en/learn/key-concepts">Key Concepts</a>
<span>·</span>
<a href="/en/learn/tutorials/workflow-101/lesson-01">Tutorials</a>
</span>
</div>
</div>
</div>
<div>
<Card title="Orchestrate" icon="hammer" href="/en/self-host/use-dify/build/workflow-chatflow">
Build workflows and chatflows on the visual canvas, plus agents, chatbots, and more.
</Card>
<Card title="Knowledge" icon="book" href="/en/self-host/use-dify/knowledge/readme">
Import documents and data so your apps can retrieve and cite them.
</Card>
<Card title="Publish" icon="paper-plane" href="/en/self-host/use-dify/publish/README">
Ship your app as a web app, embed it in a website, or call it over the API.
</Card>
<Card title="Monitor" icon="chart-line" href="/en/self-host/use-dify/monitor/analysis">
Track usage, review logs, and refine answers with annotations.
</Card>
<Card title="Integrations" icon="puzzle-piece" href="/en/self-host/use-dify/workspace/plugins">
Connect model providers, tools, data sources, and external services.
</Card>
<Card title="Get Help" icon="circle-question">
Ask the community or report a problem.
<div>
<a href="https://discord.gg/FngNHpbcY7">Discord</a>
<span>·</span>
<a href="https://github.com/langgenius/dify/issues">GitHub Issues</a>
<span>·</span>
<a href="https://github.com/langgenius/dify/discussions">Discussions</a>
</div>
</Card>
</div>
</div>
# Agent
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/agent
Run an agent as a step in your workflow, reasoning and using tools to complete a task
<Tabs>
<Tab title="Classic Agent">
The classic Agent node gives your LLM autonomous control over tools, enabling it to iteratively decide which tools to use and when to use them. Instead of pre-planning every step, the Agent reasons through problems dynamically, calling tools as needed to complete complex tasks.
<Frame>
</Frame>
## Agent Strategies
Agent strategies define how your Agent thinks and acts. Choose the approach that best matches your model's capabilities and task requirements.
<Frame>
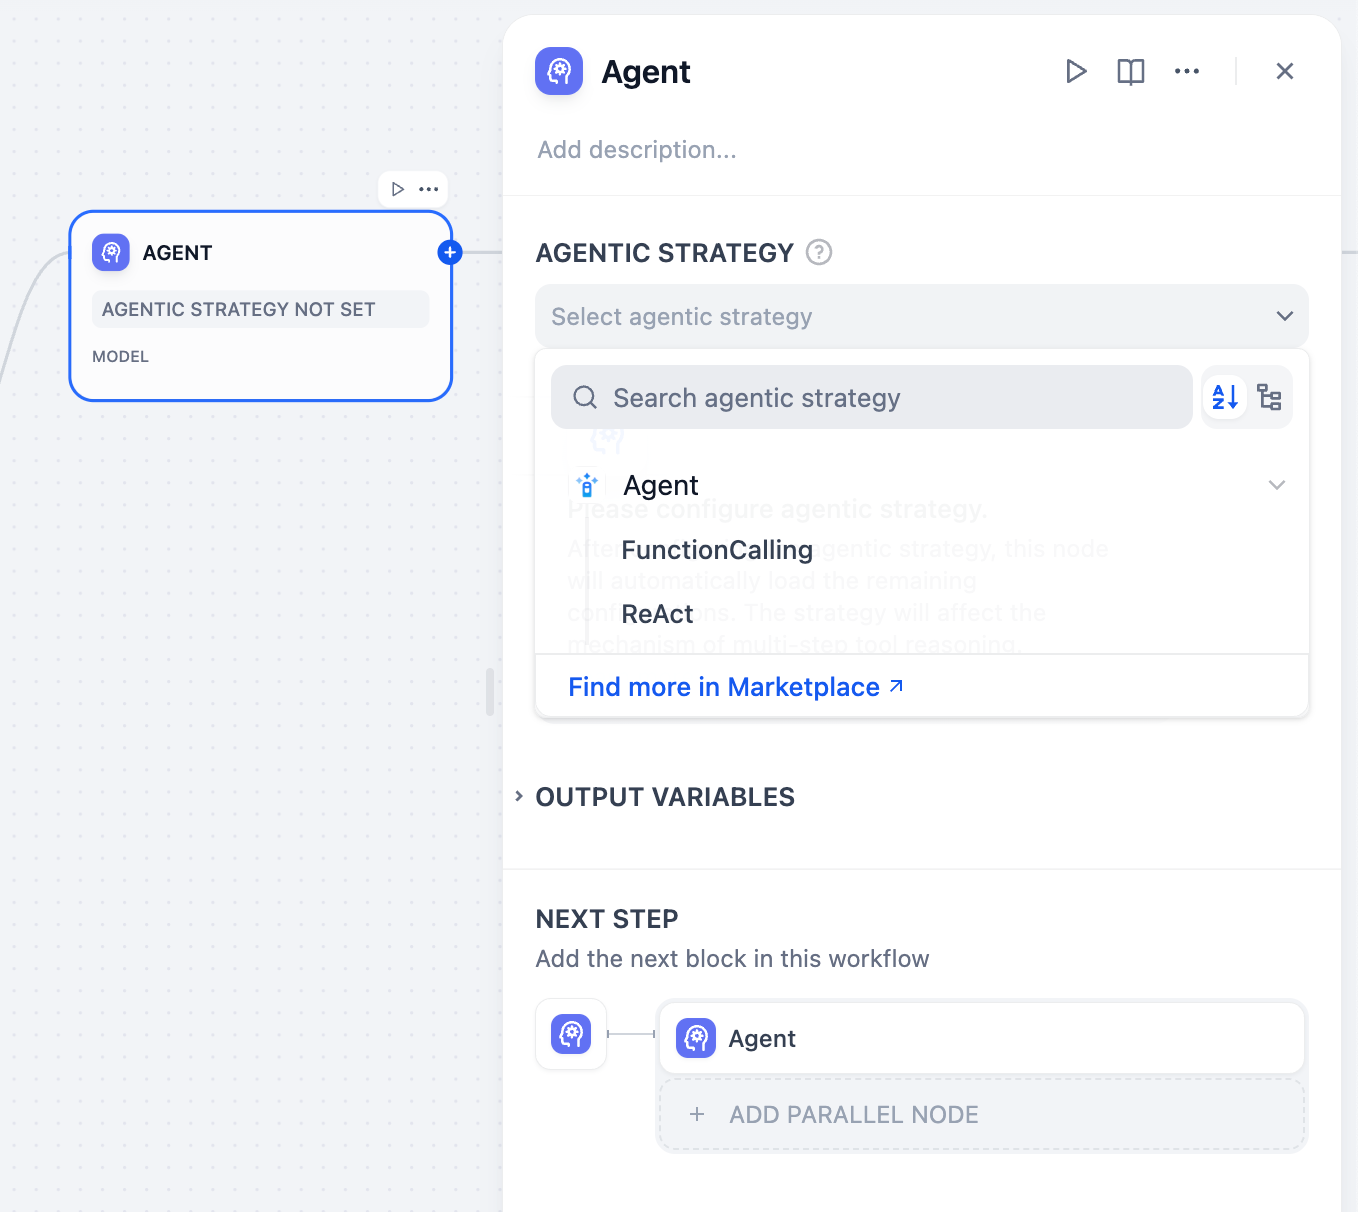
</Frame>
<Tabs>
<Tab title="Function Calling">
Uses the LLM's native function calling capabilities to directly pass tool definitions through the tools parameter. The LLM decides when and how to call tools using its built-in mechanism.
Best for models like GPT-4, Claude 3.5, and other models with robust function calling support.
</Tab>
<Tab title="ReAct (Reason + Act)">
Uses structured prompts that guide the LLM through explicit reasoning steps. Follows a **Thought → Action → Observation** cycle for transparent decision-making.
Works well with models that may not have native function calling or when you need explicit reasoning traces.
</Tab>
</Tabs>
<Info>
Install additional strategies from **Marketplace → Agent Strategies** or contribute custom strategies to the [community repository](https://github.com/langgenius/dify-plugins).
</Info>
<Frame>
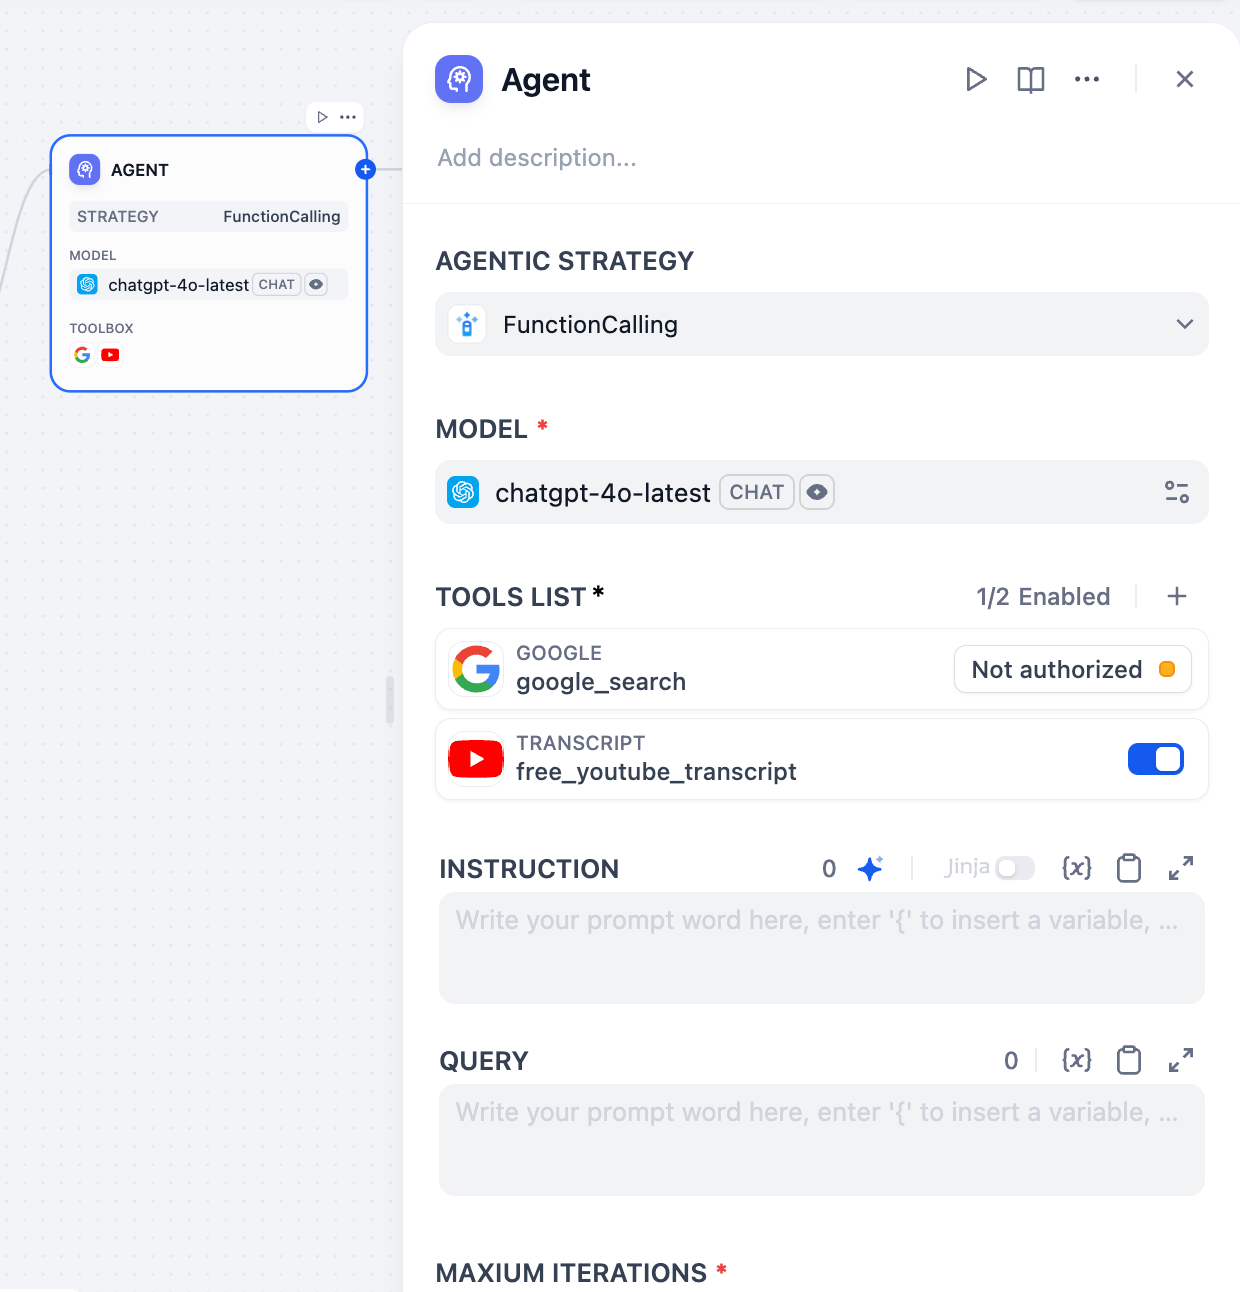
</Frame>
## Configuration
### Model Selection
Choose an LLM that supports your selected agent strategy. More capable models handle complex reasoning better but cost more per iteration. Ensure your model supports function calling if using that strategy.
### Tool Configuration
Configure the tools your Agent can access. Each tool requires:
**Authorization** - API keys and credentials for external services configured in your workspace
**Description** - Clear explanation of what the tool does and when to use it (this guides the Agent's decision-making)
**Parameters** - Required and optional inputs the tool accepts with proper validation
### Instructions and Context
Define the Agent's role, goals, and context using natural language instructions. Use Jinja2 syntax to reference variables from upstream workflow nodes.
**Query** specifies the user input or task the Agent should work on. This can be dynamic content from previous workflow nodes.
<Frame>
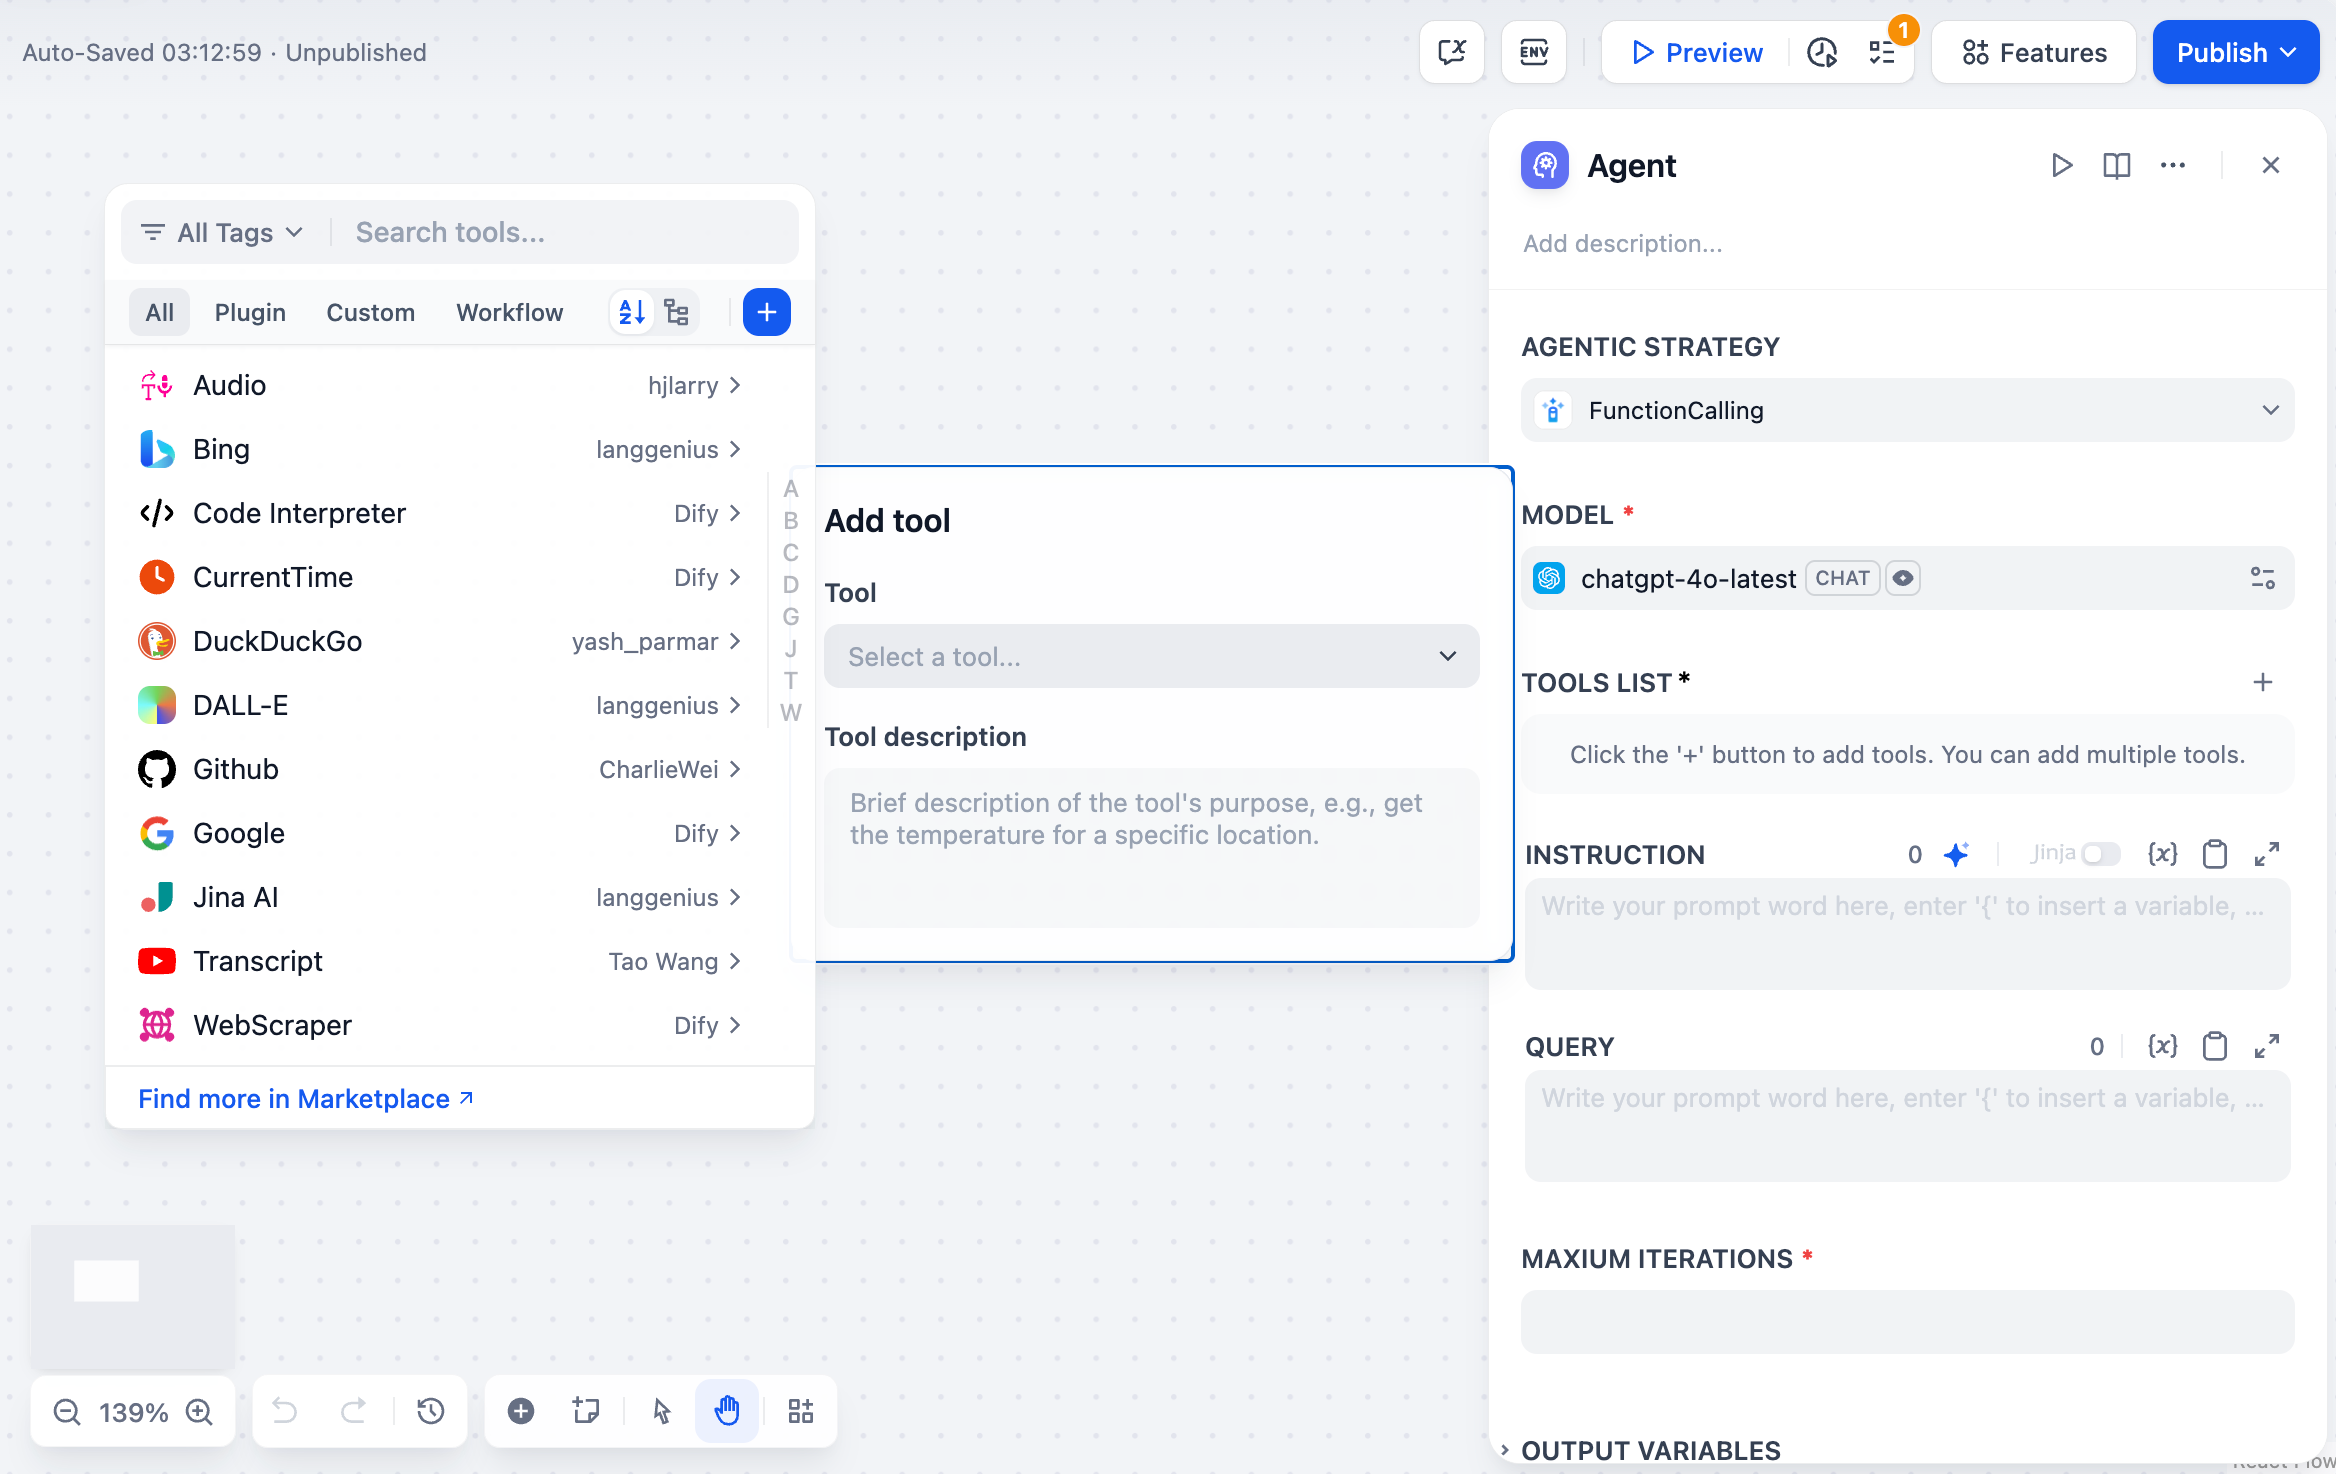
</Frame>
### Execution Controls
**Max Iterations** sets a safety limit to prevent infinite loops. Configure based on task complexity - simple tasks need 3-5 iterations, while complex research might require 10-15.
**Memory** controls how many previous messages the Agent remembers using TokenBufferMemory. Larger memory windows provide more context but increase token costs. This enables conversational continuity where users can reference previous actions.
### Tool Parameter Auto-Generation
Tools can have parameters configured as **auto-generated** or **manual input**. Auto-generated parameters (`auto: false`) are automatically populated by the Agent, while manual input parameters require explicit values that become part of the tool's permanent configuration.
<video />
## Output Variables
Agent nodes provide comprehensive output including:
**Final Answer** - The Agent's ultimate response to the query
**Tool Outputs** - Results from each tool invocation during execution
**Reasoning Trace** - Step-by-step decision process (especially detailed with ReAct strategy) available in the JSON output
**Iteration Count** - Number of reasoning cycles used
**Success Status** - Whether the Agent completed the task successfully
**Agent Logs** - Structured log events with metadata for debugging and monitoring tool invocations
## Use Cases
**Research and Analysis** - Agents can autonomously search multiple sources, synthesize information, and provide comprehensive answers.
**Troubleshooting** - Diagnostic tasks where the Agent needs to gather information, test hypotheses, and adapt its approach based on findings.
**Multi-step Data Processing** - Complex workflows where the next action depends on intermediate results.
**Dynamic API Integration** - Scenarios where the sequence of API calls depends on responses and conditions that can't be predetermined.
## Best Practices
**Clear Tool Descriptions** help the Agent understand when and how to use each tool effectively.
**Appropriate Iteration Limits** prevent runaway costs while allowing sufficient flexibility for complex tasks.
**Detailed Instructions** provide context about the Agent's role, goals, and any constraints or preferences.
**Memory Management** balance context retention with token efficiency based on your use case requirements.
</Tab>
<Tab title="New Agent">
<Warning>
**Data Security Notice**
Community Edition uses file-access controls to limit access to agent and session files when the same agent is exposed to multiple end users. These controls reduce the risk of cross-conversation data access through the filesystem, but the Agent runtime is not intended to provide a hardened security boundary between mutually untrusted users or workloads.
If your deployment requires strong isolation or strict security or compliance controls, use separately hardened infrastructure or contact Dify to assess an appropriate Cloud or Enterprise option. For Dify Enterprise, [contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Warning>
<Note>
The new Agent node is in beta and available in Workflow apps only. It's on by default on Docker Compose, with its runtime bundled in.
For production, replace [`DIFY_AGENT_SERVER_SECRET_KEY`](/en/self-host/deploy/configuration/environments#dify_agent_server_secret_key) and [`DIFY_AGENT_API_TOKEN`](/en/self-host/deploy/configuration/environments#dify_agent_api_token) with your own random values.
</Note>
The new Agent node runs an [agent](/en/self-host/use-dify/build/new-agent/overview) as one step of a workflow. Unlike the classic node's model-with-tools setup, the agent arrives as a complete worker with its own capabilities and sandbox.
You pick the agent and tell it what to do; it works through the task on its own and hands the results back to the rest of the flow.
## Choose an Agent
When you add the node, pick who does the work:
<Tabs>
<Tab title="Invite an Agent">
You can invite any published agent: it arrives with its saved capabilities, and you set only its task here.
An invited agent is like a full-time employee: its capabilities are managed centrally in **Agents**. When you publish an update there, every workflow that uses the agent gets it.
* To edit its capabilities, click **Edit in Agents**.
* If you want changes for this step only, click **Make a copy**: the node switches to a one-time copy that no longer follows the original.
</Tab>
<Tab title="Start from Scratch">
Create a one-time agent that lives on this node alone, and configure it right here, the same way you [build](/en/self-host/use-dify/build/new-agent/build) in **Agents**.
It's like a temp you bring in for one job. If it proves its worth, promote it to **Agents** to reuse it elsewhere.
<Frame>
<img alt="Save a One-Time Agent" />
</Frame>
</Tab>
</Tabs>
You can always swap the agent later.
<Info>
Two nodes that invite the same agent still work separately: each starts from the agent's saved setup in its own sandbox, and nothing from one node's run (files it wrote, tools it installed) carries into another.
To pass results between nodes, declare them as outputs and reference them downstream.
</Info>
## Give It a Task
In **Agent task**, describe what you need at this step, the way you'd brief a colleague on one job. This is separate from the agent's own prompt and capabilities. Type `/` to pull in outputs from earlier nodes.
Say you've invited a support agent that already knows your product docs and writes in your support tone, and the workflow hands it inbound customer emails. The task covers only this step:
```text wrap theme={null}
Read the customer email in {{customer_email}} and draft a reply that answers every question in it. Keep it under 150 words.
```
<Note>
Variables you pull in reach the agent as text and are truncated at 2,000 characters.
To hand over longer content in full, pass it as a file: the agent receives the whole file and reads it in its sandbox.
</Note>
## Declare Its Outputs
By default, an Agent node returns a single output, `text`: the agent's reply to its task, as one block of text. When a later step needs something more specific, like a single value or a particular file, declare it as its own output.
Type `/` in the **Agent task**, choose **New output**, then name it and pick a type in place. Each declared output can be referenced by downstream nodes on its own.
A declared output sits right in the task text, so you can tell the agent exactly what to put in it. For example, in this task `{{vendor_name}}` and `{{quote_file}}` are declared outputs:
```text wrap theme={null}
Compare the three vendor quotes in {{vendor_quotes}} and write a recommendation. Put the winning vendor's name in {{vendor_name}} and its quote PDF in {{quote_file}}.
```
Each file the agent returns is capped at 50 MB by default, adjustable with `DIFY_AGENT_STUB_UPLOAD_FILE_SIZE_LIMIT`. See [Environment Variables](/en/self-host/deploy/configuration/environments#agent-new) for details.
</Tab>
</Tabs>
# Answer
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/answer
Define response content in Chatflow applications
The Answer node defines what content gets delivered to users in Chatflow applications. Use it to format responses, combine text with variables, and stream multimodal content including text, images, and files.
<Info>
The Answer node is only available for Chatflow applications. Workflow applications use the End node instead.
</Info>
## Content Configuration
The Answer node provides a flexible text editor where you can craft responses using fixed text, variables from previous nodes, or combinations of both.
Reference variables from any previous workflow node using the `{{variable_name}}` syntax. The editor supports rich content formatting and variable insertion to create dynamic, contextual responses.
<Frame>
</Frame>
## Multimodal Responses
Answer nodes support rich content delivery including text, images, and files in a single response stream.
<Frame>
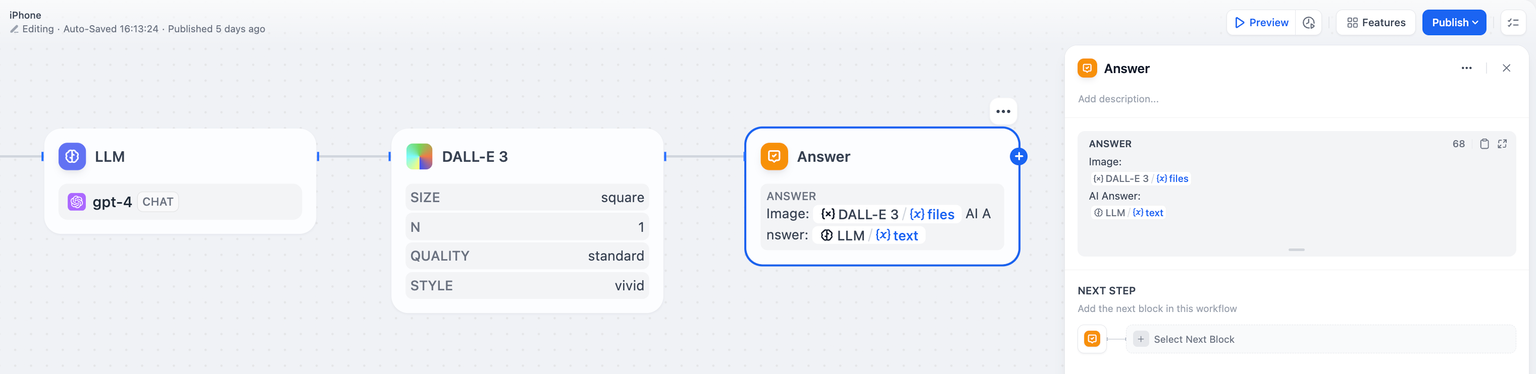
</Frame>
**Text Content** can include variable substitution, markdown formatting, and dynamic content based on workflow processing results.
**Image Content** displays images generated by tools, uploaded by users, or processed by workflow nodes. Images stream alongside text for rich user experiences.
**File Content** delivers documents, spreadsheets, or other files generated or processed during the workflow execution.
<Frame>
</Frame>
## Streaming Behavior
Answer nodes stream content progressively based on variable availability. The node outputs all content up to the first unresolved variable, then waits for that variable to resolve before continuing.
**Variable Order Matters** - The sequence of variables in your Answer node determines streaming behavior, not the execution order of upstream nodes.
For example, with nodes executing as `Node A -> Node B -> Answer`:
* If the Answer contains `{{A}}` then `{{B}}`, it streams A's content immediately when available, then waits for B
* If the Answer contains `{{B}}` then `{{A}}`, it waits for B to complete before streaming any content
This streaming behavior enables responsive user experiences while maintaining content coherence.
## Multiple Answer Nodes
You can place multiple Answer nodes throughout your Chatflow to deliver content at different stages of processing.
## Variable Integration
Answer nodes seamlessly integrate with outputs from all workflow node types. Common variable sources include:
**LLM Responses** - Display generated text, analysis results, or structured outputs from language models
**Knowledge Retrieval** - Show relevant information found in knowledge bases with automatic citation tracking
**Tool Results** - Present data from external APIs, calculations, or service integrations
**File Processing** - Display extracted text, analysis results, or processed document content
The variable system maintains type safety and automatically handles different content types for optimal display in the chat interface.
# Code
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/code
Execute custom Python or JavaScript for data processing
The Code node executes custom Python or JavaScript to handle complex data transformations, calculations, and logic within your workflow. Use it when preset nodes aren't sufficient for your specific processing needs.
<Frame>
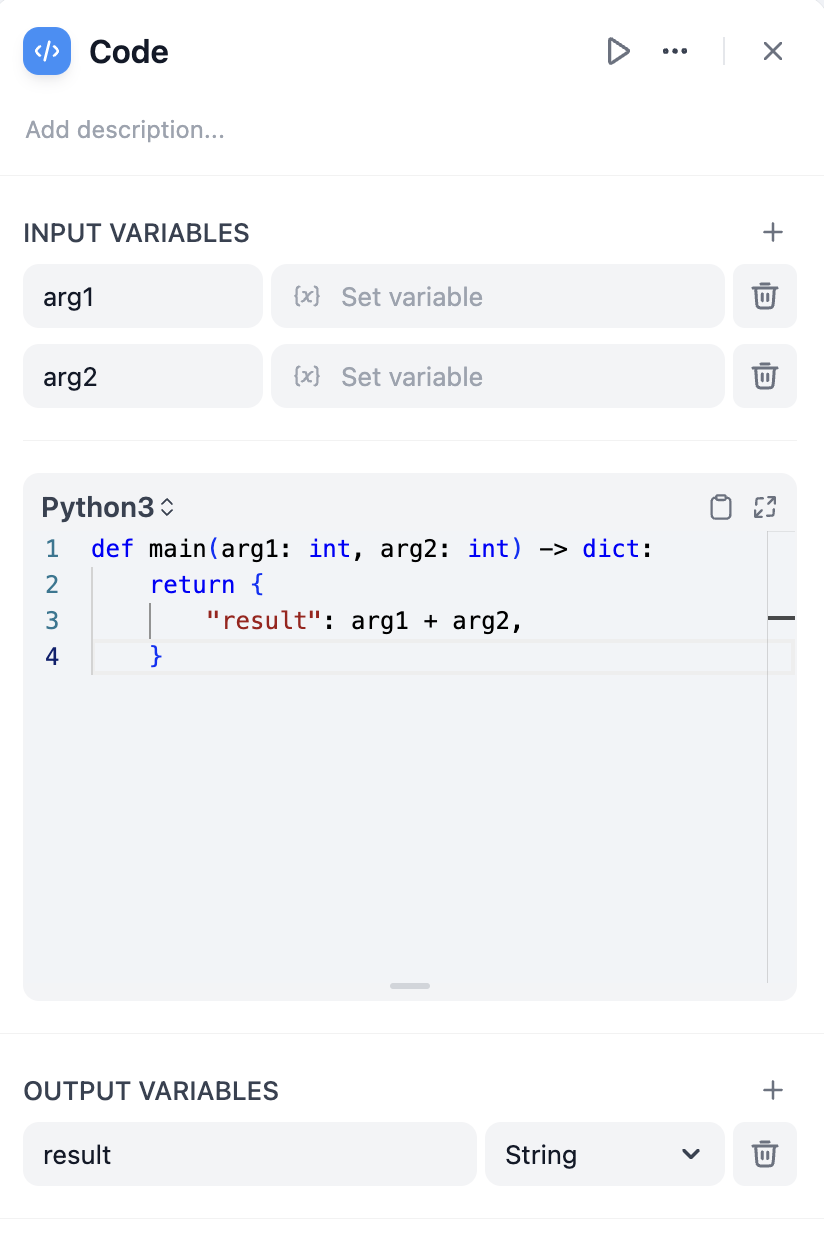
</Frame>
## Sandbox Service
The Code node depends on the `sandbox` service, defined in the standard Docker Compose deployment and started automatically with the rest of the stack:
```bash theme={null}
docker compose up -d
```
The sandbox runs as a separate container, isolating code execution from the host and from other services. Tune behavior through the `SANDBOX_*` environment variables in `docker/envs/core-services/sandbox.env.example` (worker timeout, network access via SSRF proxy, port) and through the `CODE_*` variables in `docker/envs/core-services/shared.env.example` (output limits consumed by the API).
## Configuration
Define **Input Variables** to access data from other nodes in your workflow, then reference these variables in your code. Your function must return a dictionary containing the **Output Variables** you've declared.
```python theme={null}
def main(input_variable: str) -> dict:
# Process the input
result = input_variable.upper()
return {
'output_variable': result
}
```
## Language Support
Choose between **Python** and **JavaScript** based on your needs and familiarity. Both languages run in secure sandboxes with access to common libraries for data processing.
<Tabs>
<Tab title="Python">
Python includes standard libraries like `json`, `math`, `datetime`, and `re`. Ideal for data analysis, mathematical operations, and text processing.
```python theme={null}
def main(data: list) -> dict:
import json
import math
average = sum(data) / len(data)
return {'result': math.ceil(average)}
```
</Tab>
<Tab title="JavaScript">
JavaScript provides standard built-in objects and methods. Good for JSON manipulation and string operations.
```javascript theme={null}
function main(data) {
const processed = data.map(item => item.toUpperCase());
return { result: processed };
}
```
</Tab>
</Tabs>
## Error Handling and Retries
Configure automatic retry behavior for failed code executions and define fallback strategies when code encounters errors.
<Frame>
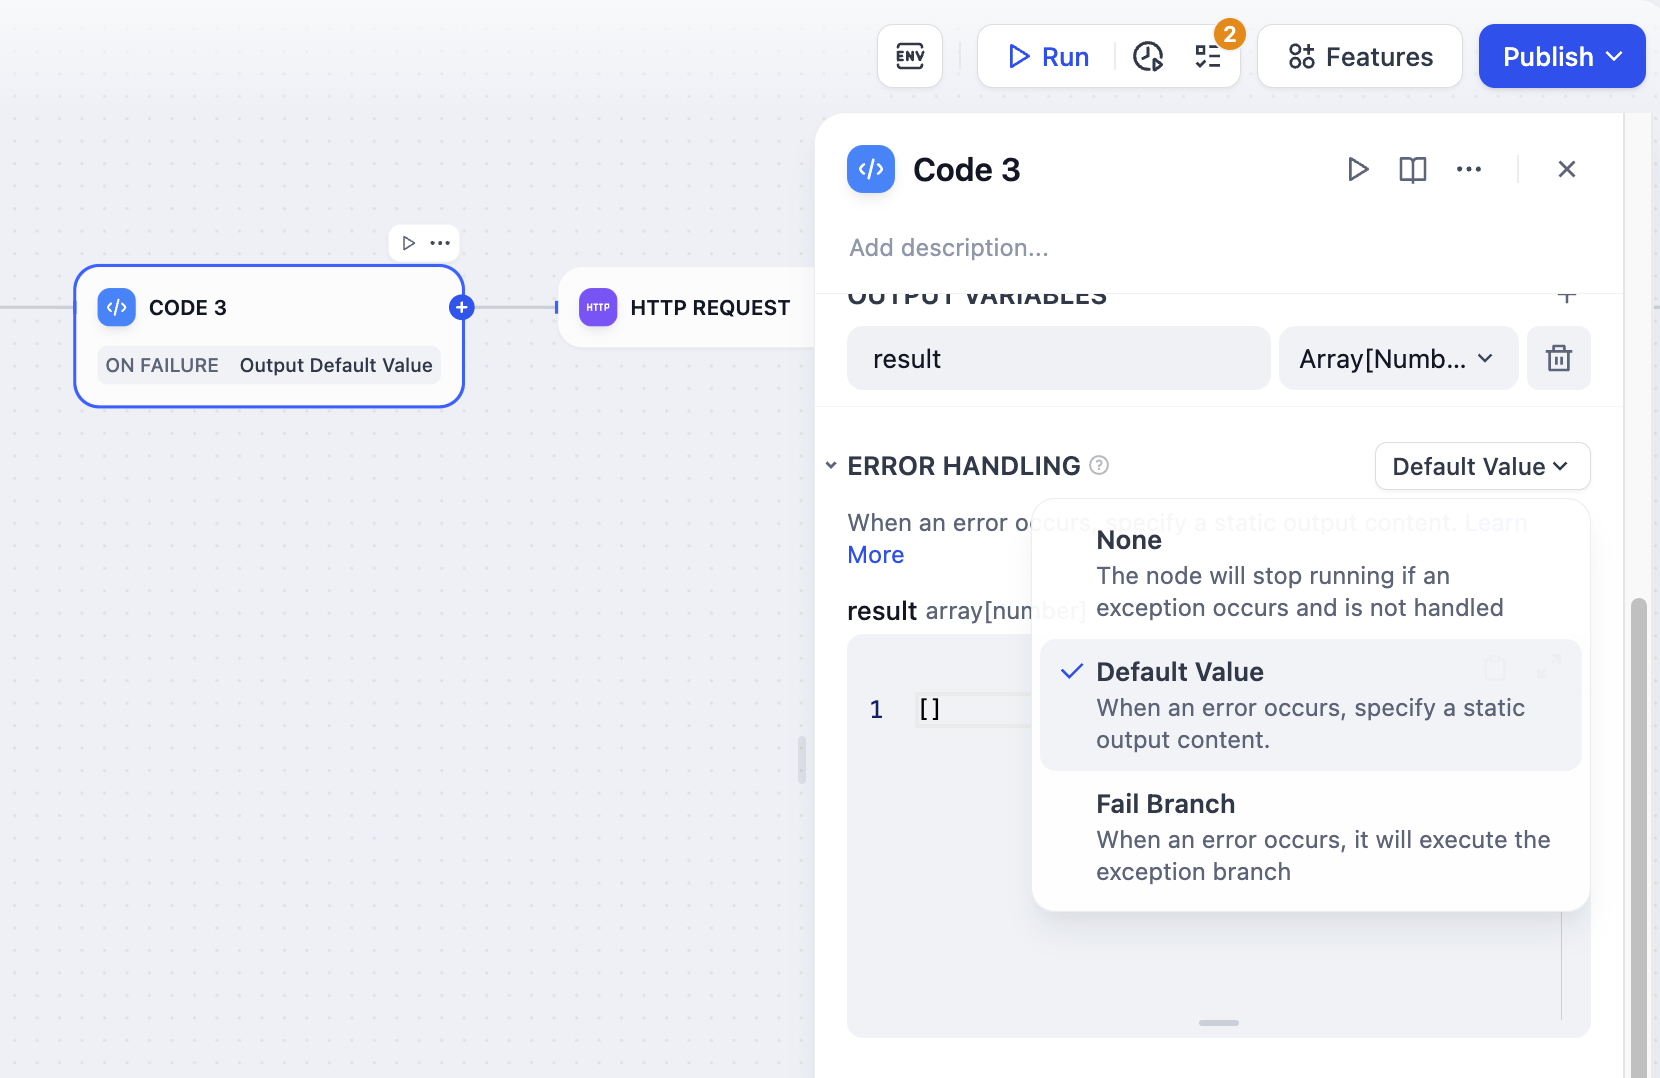
</Frame>
**Retry Settings** allow up to 10 automatic retries with configurable intervals (maximum 5000ms). Enable this for handling temporary processing issues.
**Error Handling** lets you define fallback paths when code execution fails, allowing your workflow to continue running even when the code encounters problems.
<Frame>
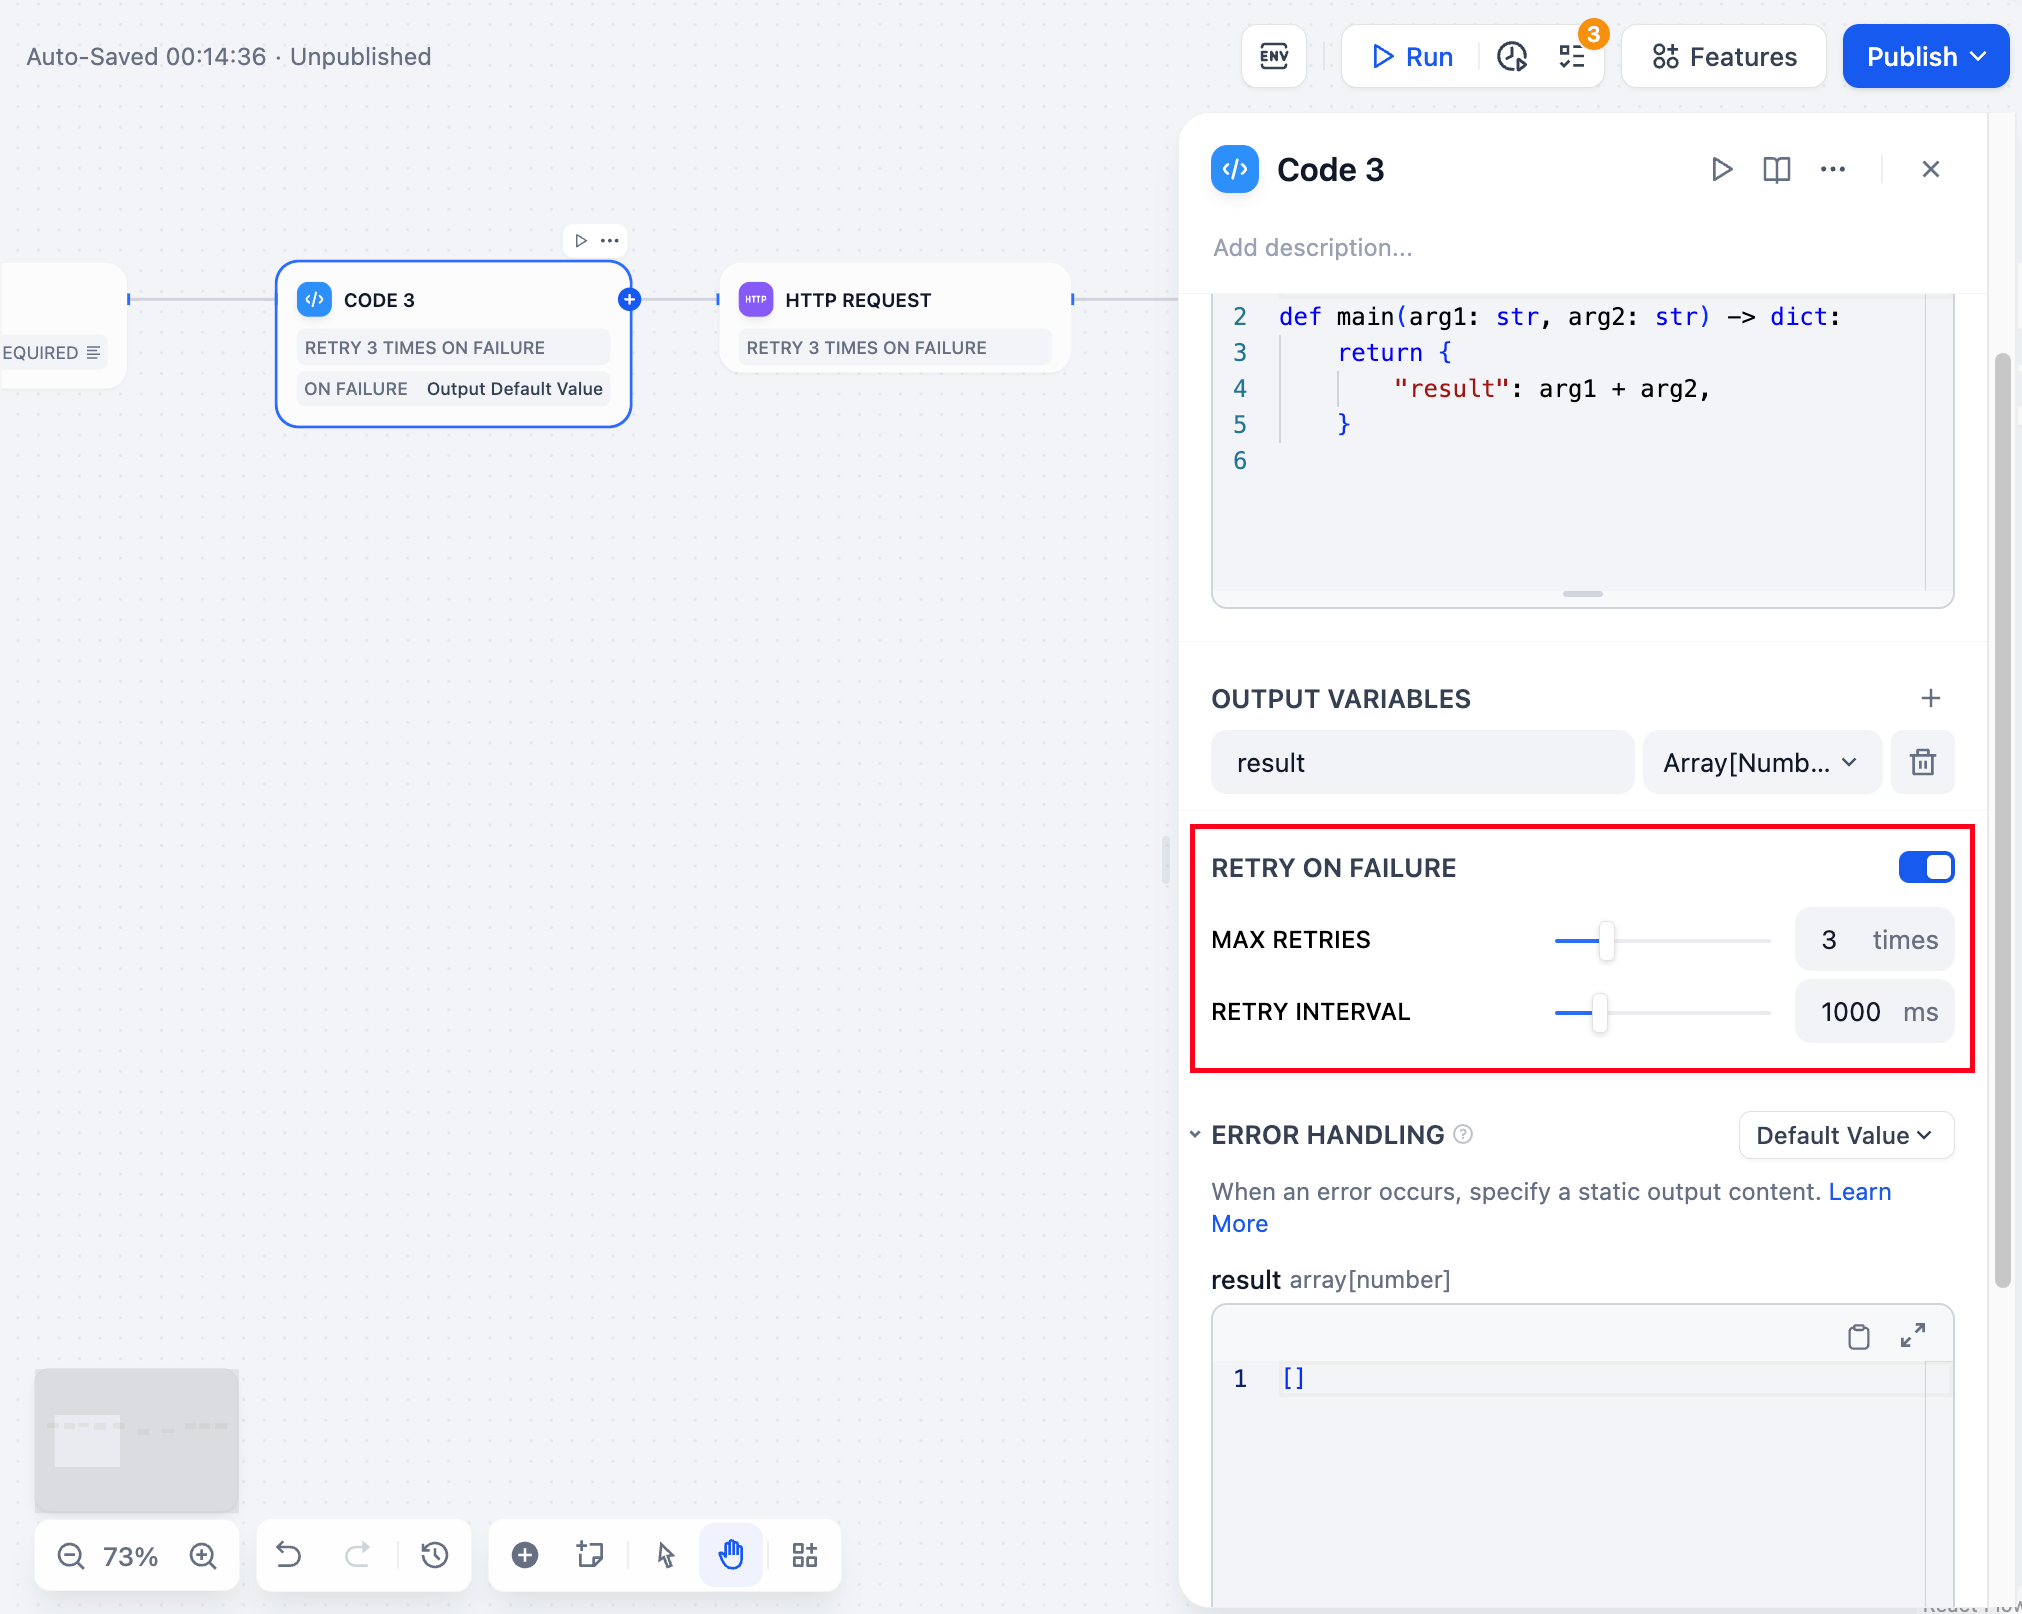
</Frame>
## Output Validation and Limits
Code outputs are validated against configurable limits set on the API container:
* **Strings**: Maximum length set by `CODE_MAX_STRING_LENGTH` (default 400,000 characters); null bytes are stripped.
* **Numbers**: Range set by `CODE_MAX_NUMBER` and `CODE_MIN_NUMBER` (default int64 range); float precision set by `CODE_MAX_PRECISION` (default 20 decimal places).
* **Objects and arrays**: Maximum nesting depth set by `CODE_MAX_DEPTH` (default 5); array sizes set by `CODE_MAX_STRING_ARRAY_LENGTH`, `CODE_MAX_OBJECT_ARRAY_LENGTH`, and `CODE_MAX_NUMBER_ARRAY_LENGTH`.
Defaults live in `docker/envs/core-services/shared.env.example`. Tighten limits to constrain output sizes; relax them when workflows legitimately produce larger payloads.
## Security Considerations
Code executes in a strict sandbox that prevents file system access, network requests, and system commands. This maintains security while providing programming flexibility.
Some operations are automatically blocked for security reasons. Avoid attempting to access system files or execute potentially dangerous operations. By default, outbound network calls from sandboxed code route through the SSRF proxy; set `SANDBOX_ENABLE_NETWORK=false` to disable network access from sandboxed code entirely.
## Dependencies Support
Code nodes support external dependencies for both Python and JavaScript:
```python theme={null}
# Python: Import numpy, pandas, requests, etc.
import numpy as np
import pandas as pd
def main(data: list) -> dict:
df = pd.DataFrame(data)
return {'mean': float(np.mean(df['values']))}
```
```javascript theme={null}
// JavaScript: Import lodash, moment, etc.
const _ = require('lodash');
function main(data) {
return { unique: _.uniq(data) };
}
```
Dependencies are pre-installed in the sandbox environment. Check the available packages list in your Dify installation.
# Human Input
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/human-input
Pause workflows to request human input
The Human Input node pauses workflows at key points to deliver a customizable request form. Recipients can use the form to review information, provide input, and choose from predefined decisions that determine how the workflow proceeds.
By embedding human judgement directly where it matters, you can *balance automated efficiency with human oversight*.
<Tip>
For a workflow design example, see [Example: Content Review Workflow](#example-content-review-workflow).
</Tip>
## Configuration
Configure the following to define how the node requests and processes human input:
* **Delivery method**: How the request form reaches recipients.
* **Form content**: What information recipients will see and what they can interact with.
* **User action**: What decisions recipients can make and how the workflow proceeds accordingly.
* **Timeout strategy**: How long to wait and what happens if no recipient responds.
### Delivery Method
Choose the channel through which the request is delivered. Currently available methods:
* **Web app**: Displays the request form to the web app end user. Not available in workflows started by a Trigger.
<Info>
External clients can drive the web app form lifecycle through the Service API. See [API Integration Flow](/en/api-reference/guides/human-input-flow).
</Info>
* **Email**: Sends a request link via email to specific workspace members, external email addresses, or every member of the workspace. Anyone with the link can respond, no Dify account required.
<Note>
The request closes after the first response regardless of delivery method.
</Note>
### Form Content
Customize the form recipients see and interact with:
* **Format and structure with Markdown**
Use headings, lists, bold text, links, and other Markdown elements to present information clearly.
* **Display dynamic data with variables**
Reference workflow variables to show dynamic content, such as AI-generated text for review or a file someone uploaded at an upstream Human Input node for approval.
In web app delivery, the form itself displays to end users. Any variables you reference render their values directly in the form, so **no Answer or Output node is needed before the Human Input node**.
<Tip>
Reasoning models emit their thinking process alongside the final answer. Referencing the `text` output variable shows both by default.
To show only the answer, toggle on **Enable Reasoning Tag Separation** for the corresponding LLM node.
</Tip>
* **Collect input with form fields**
Add fields into the request form to capture different types of input from recipients. Each field becomes a variable for downstream use.
For example, in a blog review workflow, you can pass recipient feedback to a downstream LLM node for content revision.
| Field Type | Description |
| :---------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Paragraph | Text input. Can start empty, or pre-filled with variables (e.g., LLM output to refine) or static text (examples or default values). <br /><br />No maximum length, but very long inputs may exceed downstream LLM context windows. |
| Select | Single-choice selection from a list of options. Define options manually, or reference an `array[string]` variable to use its items as options. |
| Single File / File List | Single or multiple file uploads. <Info>File upload limits are tunable via environment variables: <ul><li>`UPLOAD_FILE_SIZE_LIMIT`, `UPLOAD_IMAGE_FILE_SIZE_LIMIT`, `UPLOAD_VIDEO_FILE_SIZE_LIMIT`, and `UPLOAD_AUDIO_FILE_SIZE_LIMIT` cap per-file size by extension.</li><li>`WORKFLOW_FILE_UPLOAD_LIMIT` caps the max files a File List field can be configured to accept.</li></ul>See [Environment Variables](/en/self-host/deploy/configuration/environments) for defaults.</Info> |
<Note>Only Paragraph is optional; Select, Single File, and File List are mandatory. The form's action buttons stay disabled until all mandatory fields are filled.</Note>
After the recipient responds, the form content with all values filled in is available downstream as the `__rendered_content` variable. File field values render as plain-text placeholders: `[file]` for Single File and `[N files]` for File List.
### User Action
Define the decision buttons that recipients can click, each routing the workflow to a different execution path.
For example, a `Post` branch might lead to nodes that trigger content publishing, while a `Regenerate` branch might loop back to an LLM node to revise the content.
Each button has a display title and an action ID. When a button is clicked, its ID is exposed downstream as `__action_id` and its title (button text) as `__action_value`.
<Frame>
<img alt="Action Button Configuration" />
</Frame>
<Tip>
Use preset button styles to visually distinguish actions.
For example, use a prominent style for key actions like `Approve` and a subtler one for secondary options.
</Tip>
### Timeout Strategy
Configure how long the request stays open before it expires. The default is 3 days.
If no recipient responds before the timeout, the workflow follows the timeout branch from the node. Wire this branch to a fallback path, such as a notification or a retry loop.
If no timeout branch is connected, the workflow ends.
## Example: Content Review Workflow
<div>
<Frame>
<img alt="Workflow Example" />
</Frame>
<Frame>
<img alt="Request Form Example" />
</Frame>
</div>
This workflow drafts a blog post from the `topic` and `language` that a workflow initiator inputs, emails the draft to a reviewer, and finalizes the output based on the reviewer's choice.
It is designed around three things the reviewer should be able to do:
1. **See the AI-generated draft**: Reference the upstream LLM node's `text` variable in the form so the rendered form displays the draft directly.
2. **Edit the draft directly if needed**: Add a Paragraph field named `edits` in the form, pre-filled with the same `text` variable, so the reviewer sees the draft as starting content and can edit in place.
Because blog posts are long, the form's Markdown display (point 1) reads better than a Paragraph field on its own. For shorter content, the pre-filled Paragraph field alone can handle both reading and editing.
3. **Provide feedback for an AI revision**:
1. Add a Paragraph field named `feedback` in the form for the reviewer's feedback.
2. Connect two downstream LLM nodes in sequence:
1. A Regenerate node that takes the original draft `text` and the reviewer's `feedback` to produce a revised draft.
2. A Check Revision node that takes `feedback` and the revised draft to verify whether the revision addresses the feedback. The verified result is what flows downstream.
On the received request form, the reviewer fills the relevant Paragraph fields (or leaves them blank) based on their judgment, then clicks the matching action button. Each action wires to a different output:
* **Approve**: the original draft from the upstream LLM
* **Apply Edit**: the reviewer's edited content from the `edits` field
* **Regenerate**: the revised draft from the downstream LLM pipeline
<Accordion title="LLM Node Prompts for Reference">
<Tabs>
<Tab title="Generate Draft">
**System**
```text wrap theme={null}
Write a marketing blog post around the given topic in the specified language.
```
**User**
```text theme={null}
Topic: {{#user_input.topic#}}
Language: {{#user_input.language#}}
```
</Tab>
<Tab title="Regenerate">
**System**
```text wrap theme={null}
Regenerate the draft based on user feedback.
```
**User**
```text theme={null}
Draft: {{#generate_draft.text#}}
User Feedback: {{#human_input.feedback#}}
```
</Tab>
<Tab title="Check Revision">
**System**
```text wrap theme={null}
Check whether the draft below addresses the user's feedback. Return the draft unchanged if it does; revise it to address the feedback if it doesn't.
```
**User**
```text theme={null}
User Feedback: {{#human_input.feedback#}}
Regenerated Draft: {{#regenerate.text#}}
```
</Tab>
</Tabs>
</Accordion>
# If-Else
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/ifelse
Add conditional logic and branching to workflows
The If-Else node adds decision-making logic to your workflows by routing execution down different paths based on conditions you define. It evaluates variables and determines which branch your workflow should follow.
<Frame>
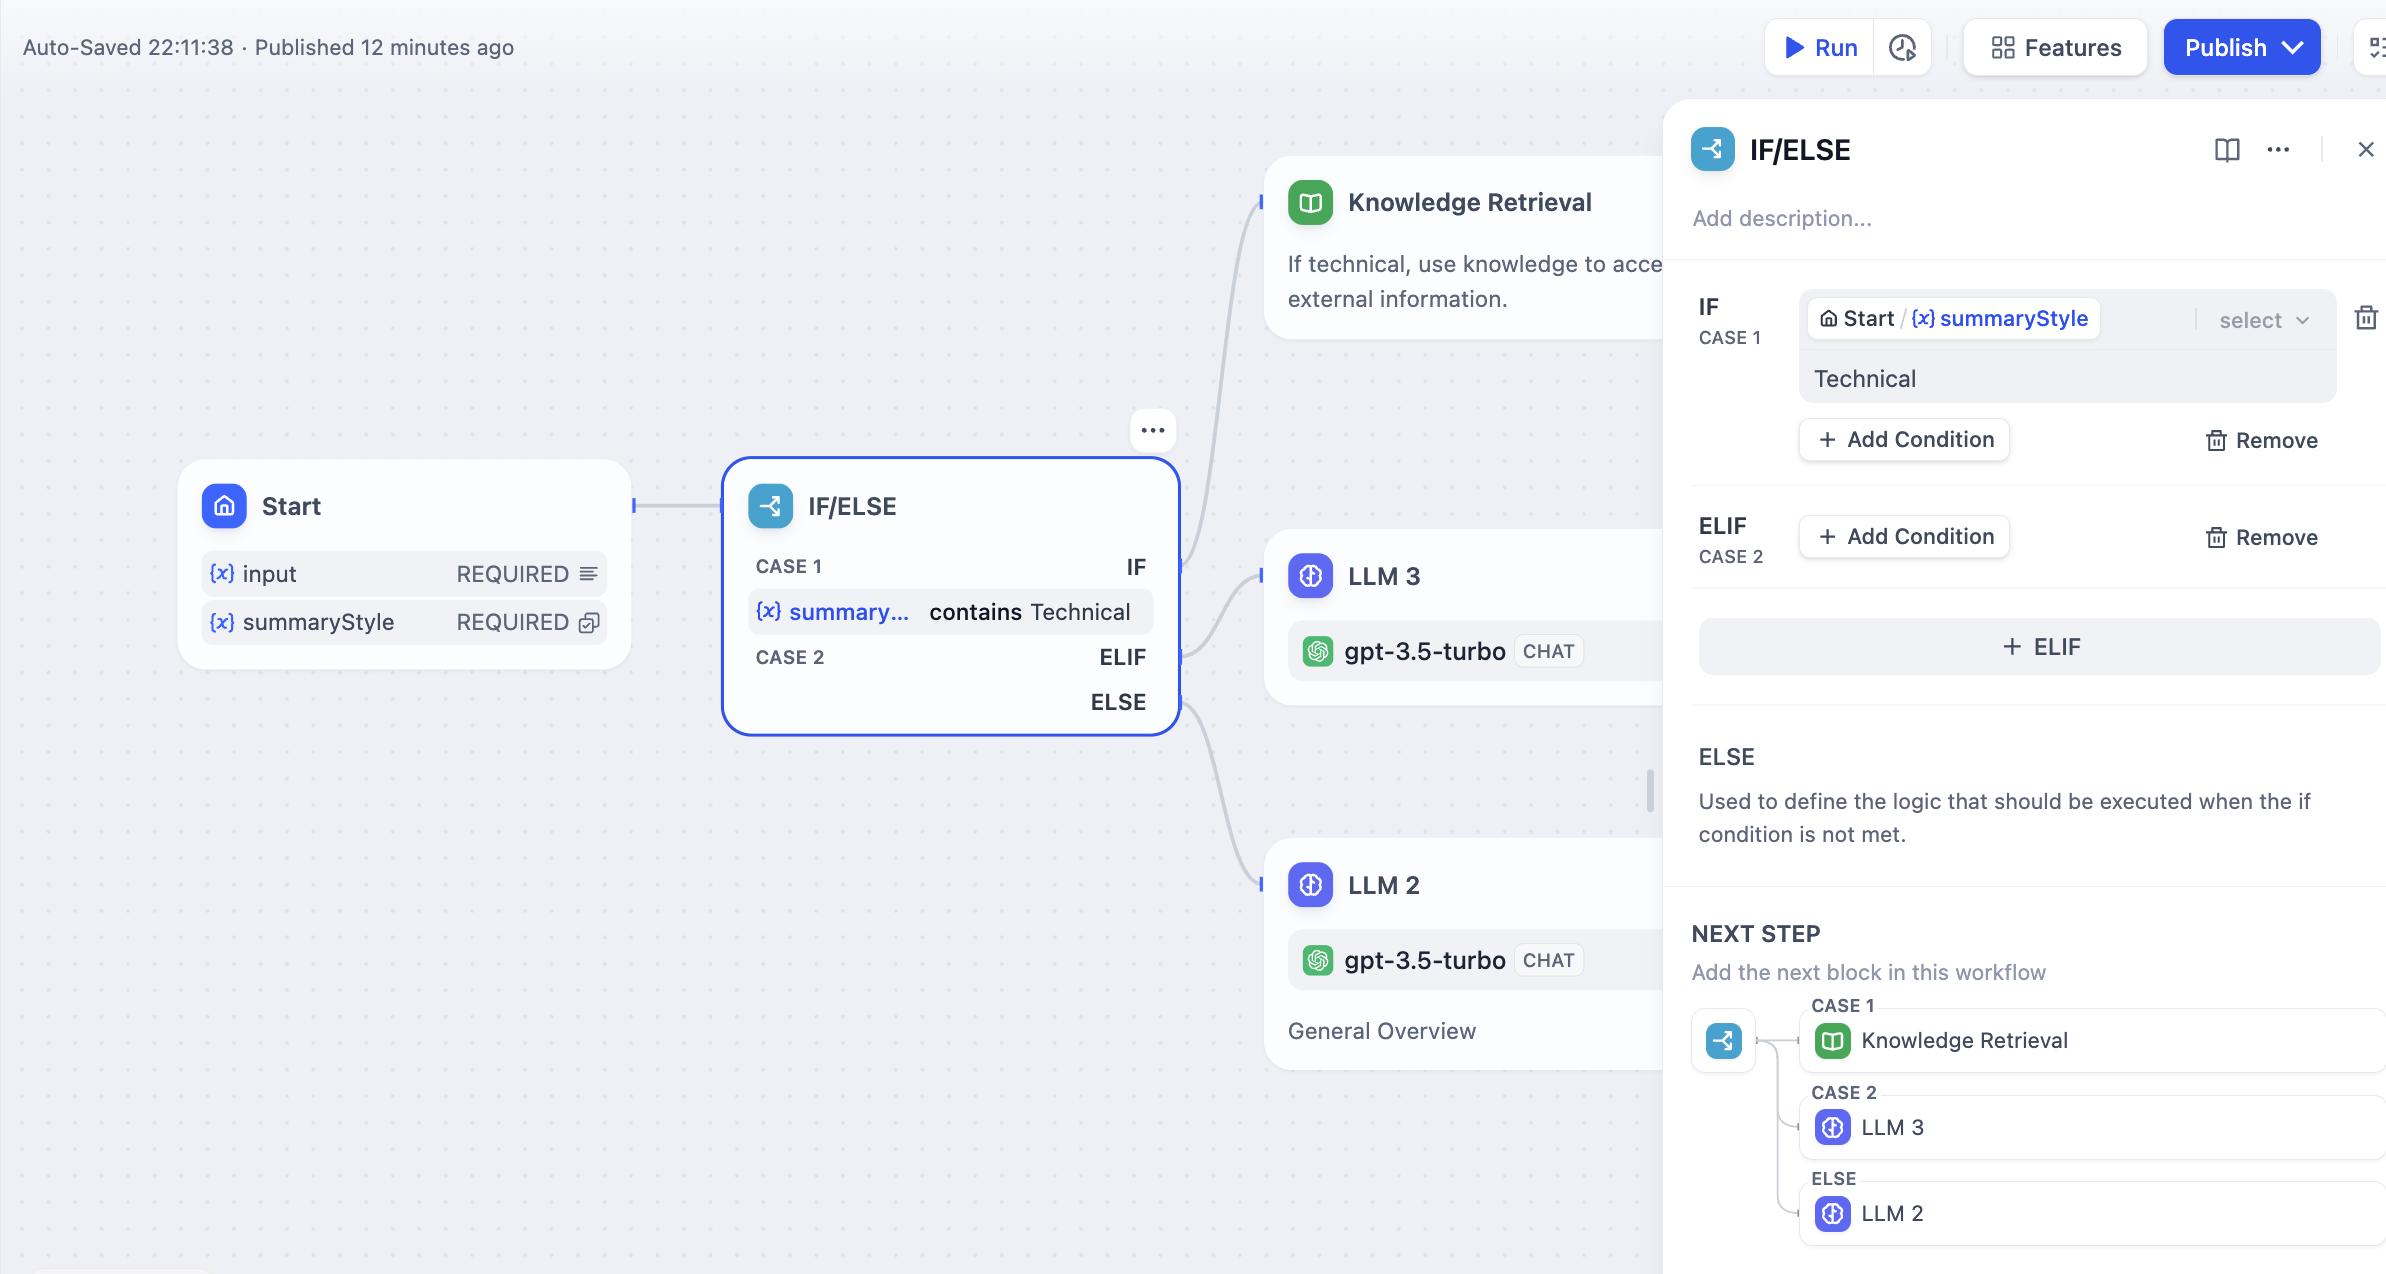
</Frame>
## Branching Logic
The node supports multiple branching paths to handle complex decision trees:
**IF Path** executes when the primary condition evaluates to true.
**ELIF Paths** provide additional conditions to check in sequence when the IF condition is false. You can add multiple ELIF branches for complex logic.
**ELSE Path** serves as the fallback when no conditions match, ensuring your workflow always has a path to follow.
## Condition Types
Configure conditions to test variables using various comparison operators:
<Tabs>
<Tab title="Text Operations">
**Contains** / **Not contains** - Check if the value includes specific words or phrases
**Starts with** / **Ends with** - Test text beginnings or endings for pattern matching
**Is** / **Is not** - Exact value matching
</Tab>
<Tab title="Value Checks">
**Is empty** / **Is not empty** - Check for blank, null, or missing values
**Greater than** / **Less than** - Numerical comparisons for numbers and dates
**Equals** / **Not equals** - Exact matching for any data type
</Tab>
</Tabs>
## Complex Conditions
Combine multiple conditions using logical operators for sophisticated decision-making:
<Frame>
</Frame>
**AND Logic** requires all conditions to be true. Use this when you need multiple criteria to be met simultaneously.
**OR Logic** requires any condition to be true. Use this when you want to trigger the same action for different scenarios.
## Variable References
Reference any variable from previous workflow nodes in your conditions. Variables can come from user input, LLM responses, API calls, or any other workflow node output.
Use the variable selector to choose from available variables, or type variable names directly using the `{{variable_name}}` syntax.
# Iteration
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/iteration
Process arrays by applying workflows to each element
The Iteration node processes arrays by running the same workflow steps on each element sequentially or in parallel. Use it for batch processing tasks that would otherwise hit limits or be inefficient as single operations.
<Frame>
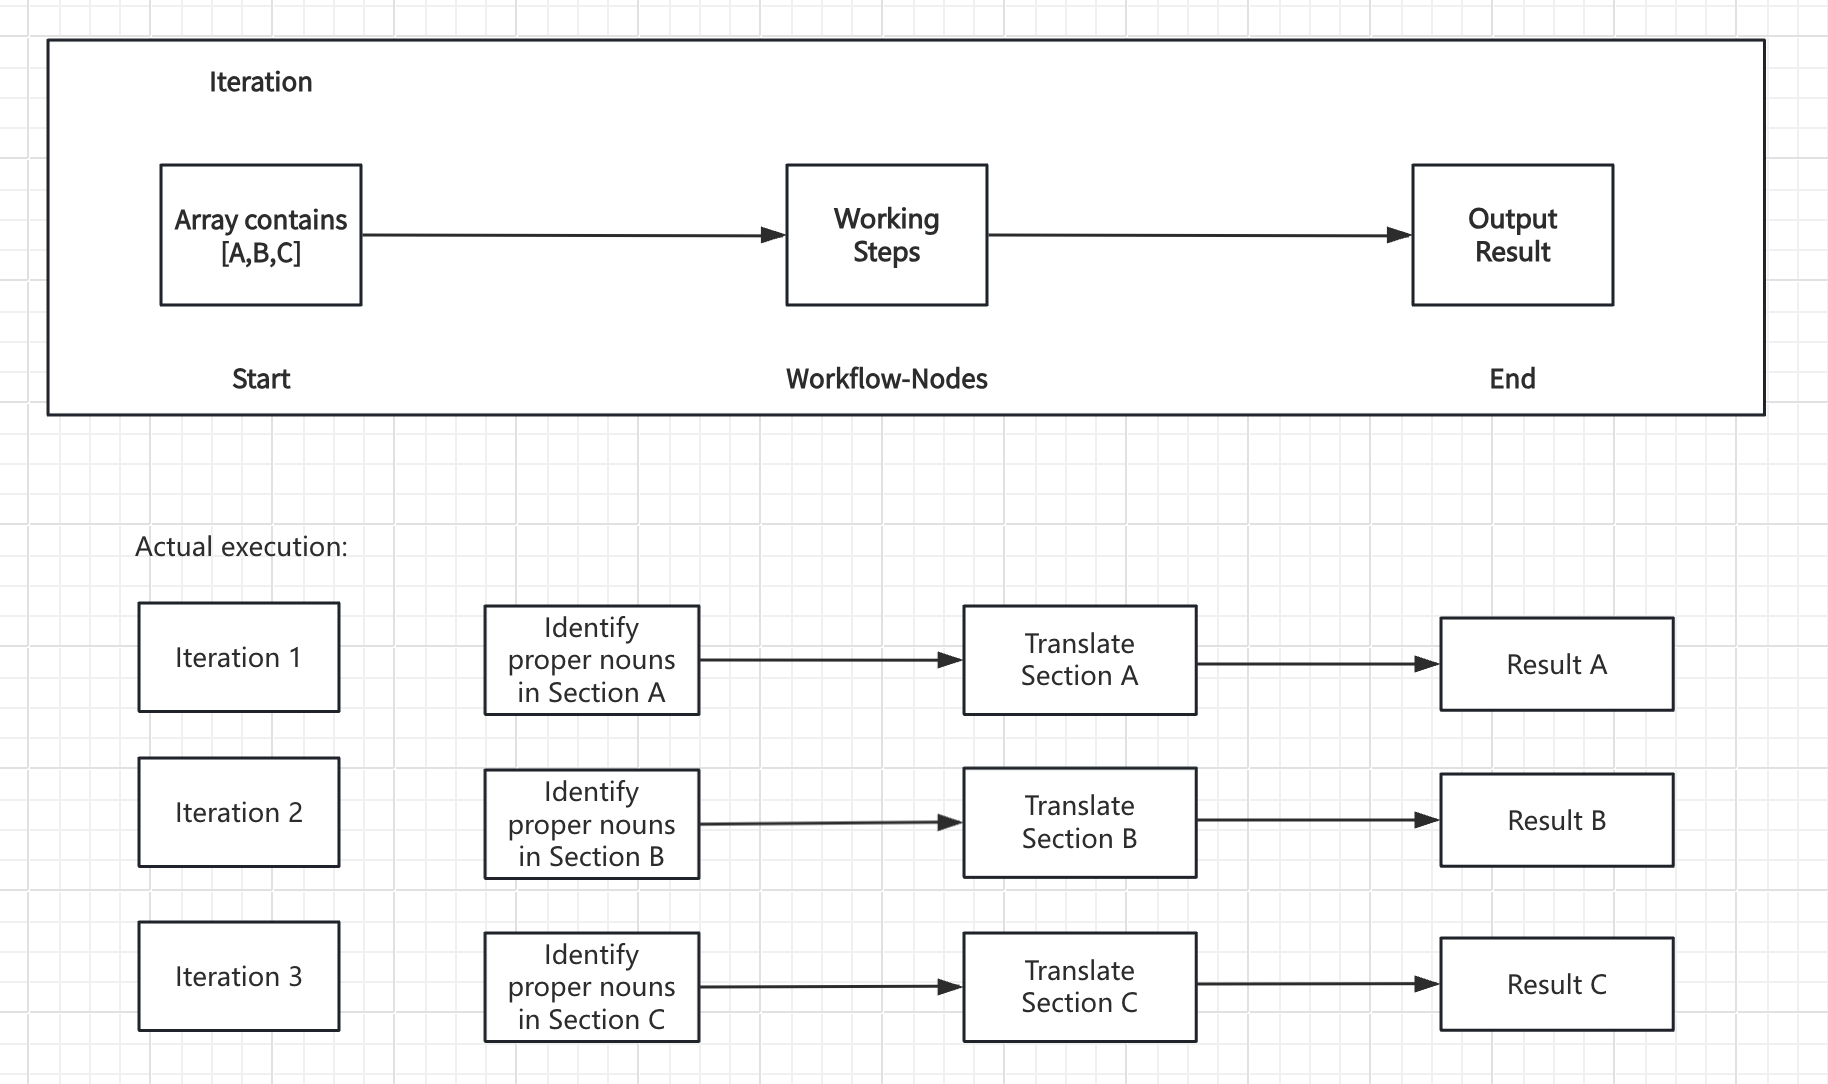
</Frame>
## How Iteration Works
The node takes an array input and creates a sub-workflow that runs once for each array element. During each iteration, the current item and its index are available as variables that internal nodes can reference.
**Core Components**:
* **Input Variables** - Array data from upstream nodes
* **Internal Workflow** - The processing steps to perform on each element
* **Output Variables** - Collected results from all iterations (also an array)
## Configuration
### Array Input
Connect an array variable from upstream nodes such as Parameter Extractor, Code nodes, Knowledge Retrieval, or HTTP Request responses.
### Built-in Variables
Each iteration provides access to:
* `items[object]` - The current array element being processed
* `index[number]` - The current iteration index (starting from 0)
### Processing Mode
<Tabs>
<Tab title="Sequential Mode">
**Sequential Processing** - Items processed one after another in order
**Streaming Support** - Results can be output progressively using Answer nodes
**Resource Management** - Lower memory usage, predictable execution order
**Best For** - When order matters or when using streaming output
</Tab>
<Tab title="Parallel Mode">
**Concurrent Processing** - Up to 10 items processed simultaneously
**Improved Performance** - Faster execution for independent operations
**Batch Processing** - Handles large arrays efficiently
**Best For** - Independent operations where order doesn't matter
</Tab>
</Tabs>
<Frame>
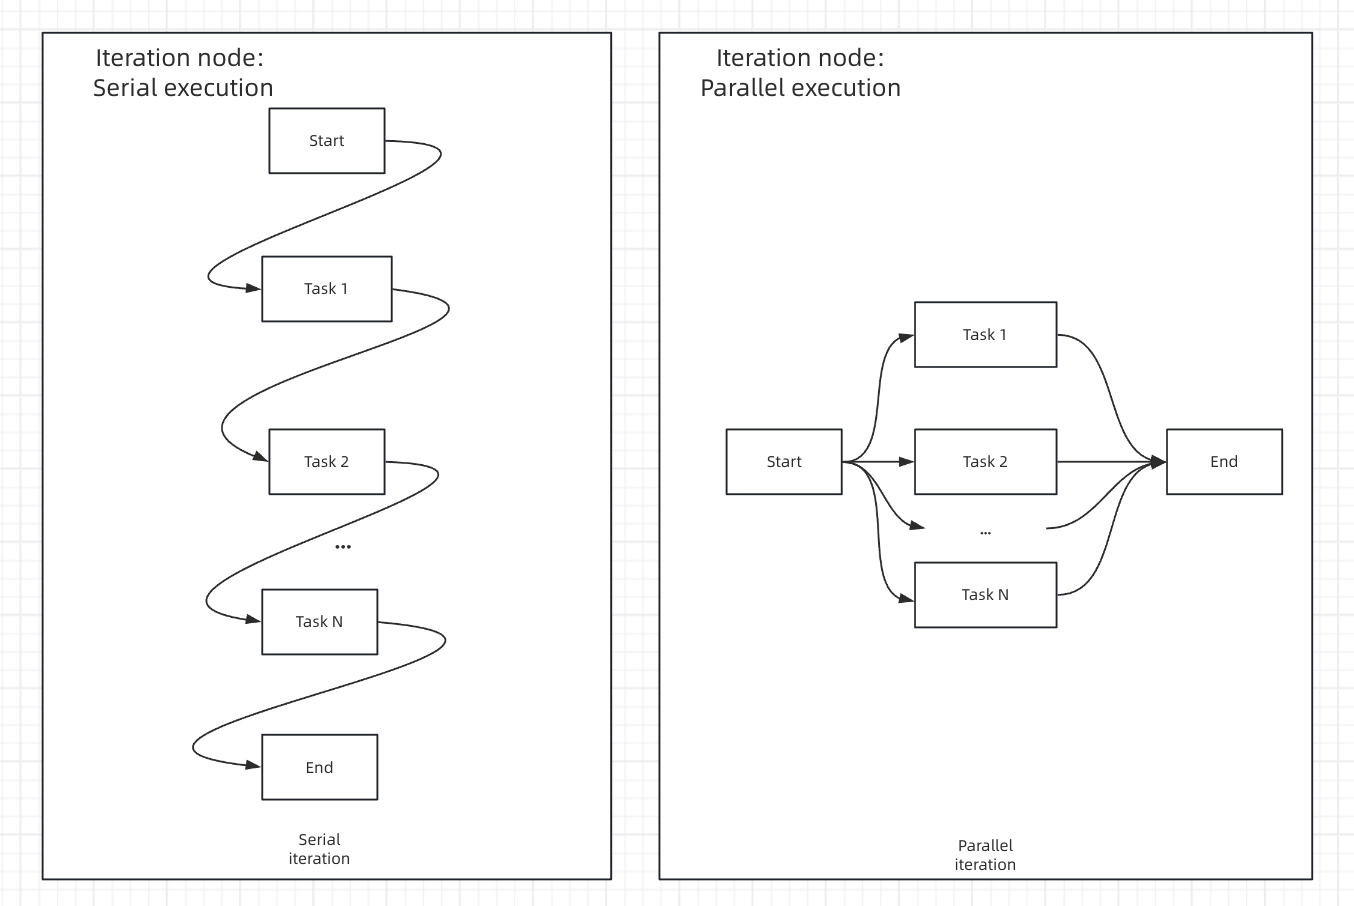
</Frame>
<Frame>
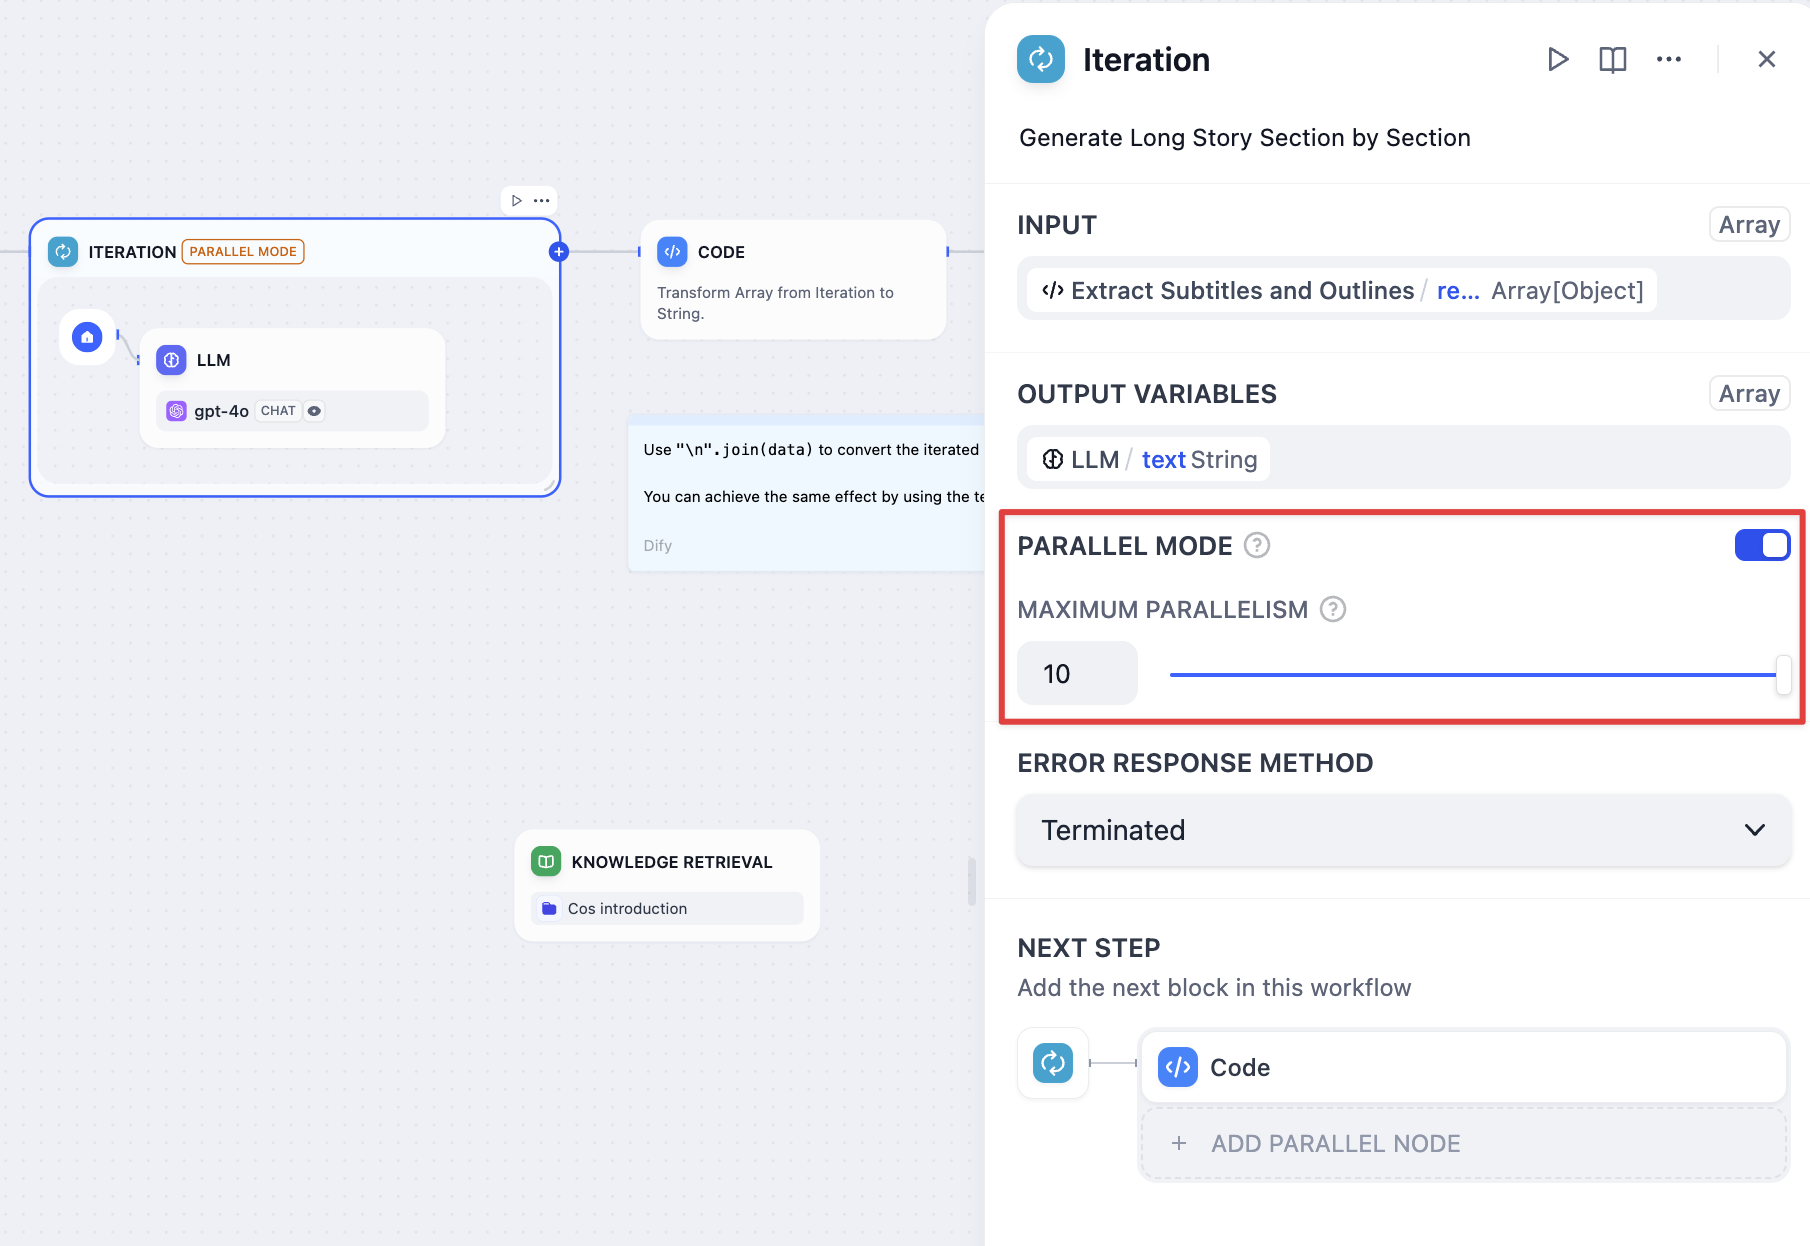
</Frame>
## Error Handling
Configure how to handle processing failures for individual array elements:
**Terminate** - Stop processing when any error occurs and return the error message
**Continue on Error** - Skip failed items and continue processing, outputting null for failed elements
**Remove Failed Results** - Skip failed items and return only successful results
Input-output correspondence examples:
* Input: `[1, 2, 3]`
* Output with Continue on Error: `[result-1, null, result-3]`
* Output with Remove Failed: `[result-1, result-3]`
## Long Article Generation Example
Generate lengthy content by processing chapter outlines individually:
<Frame>
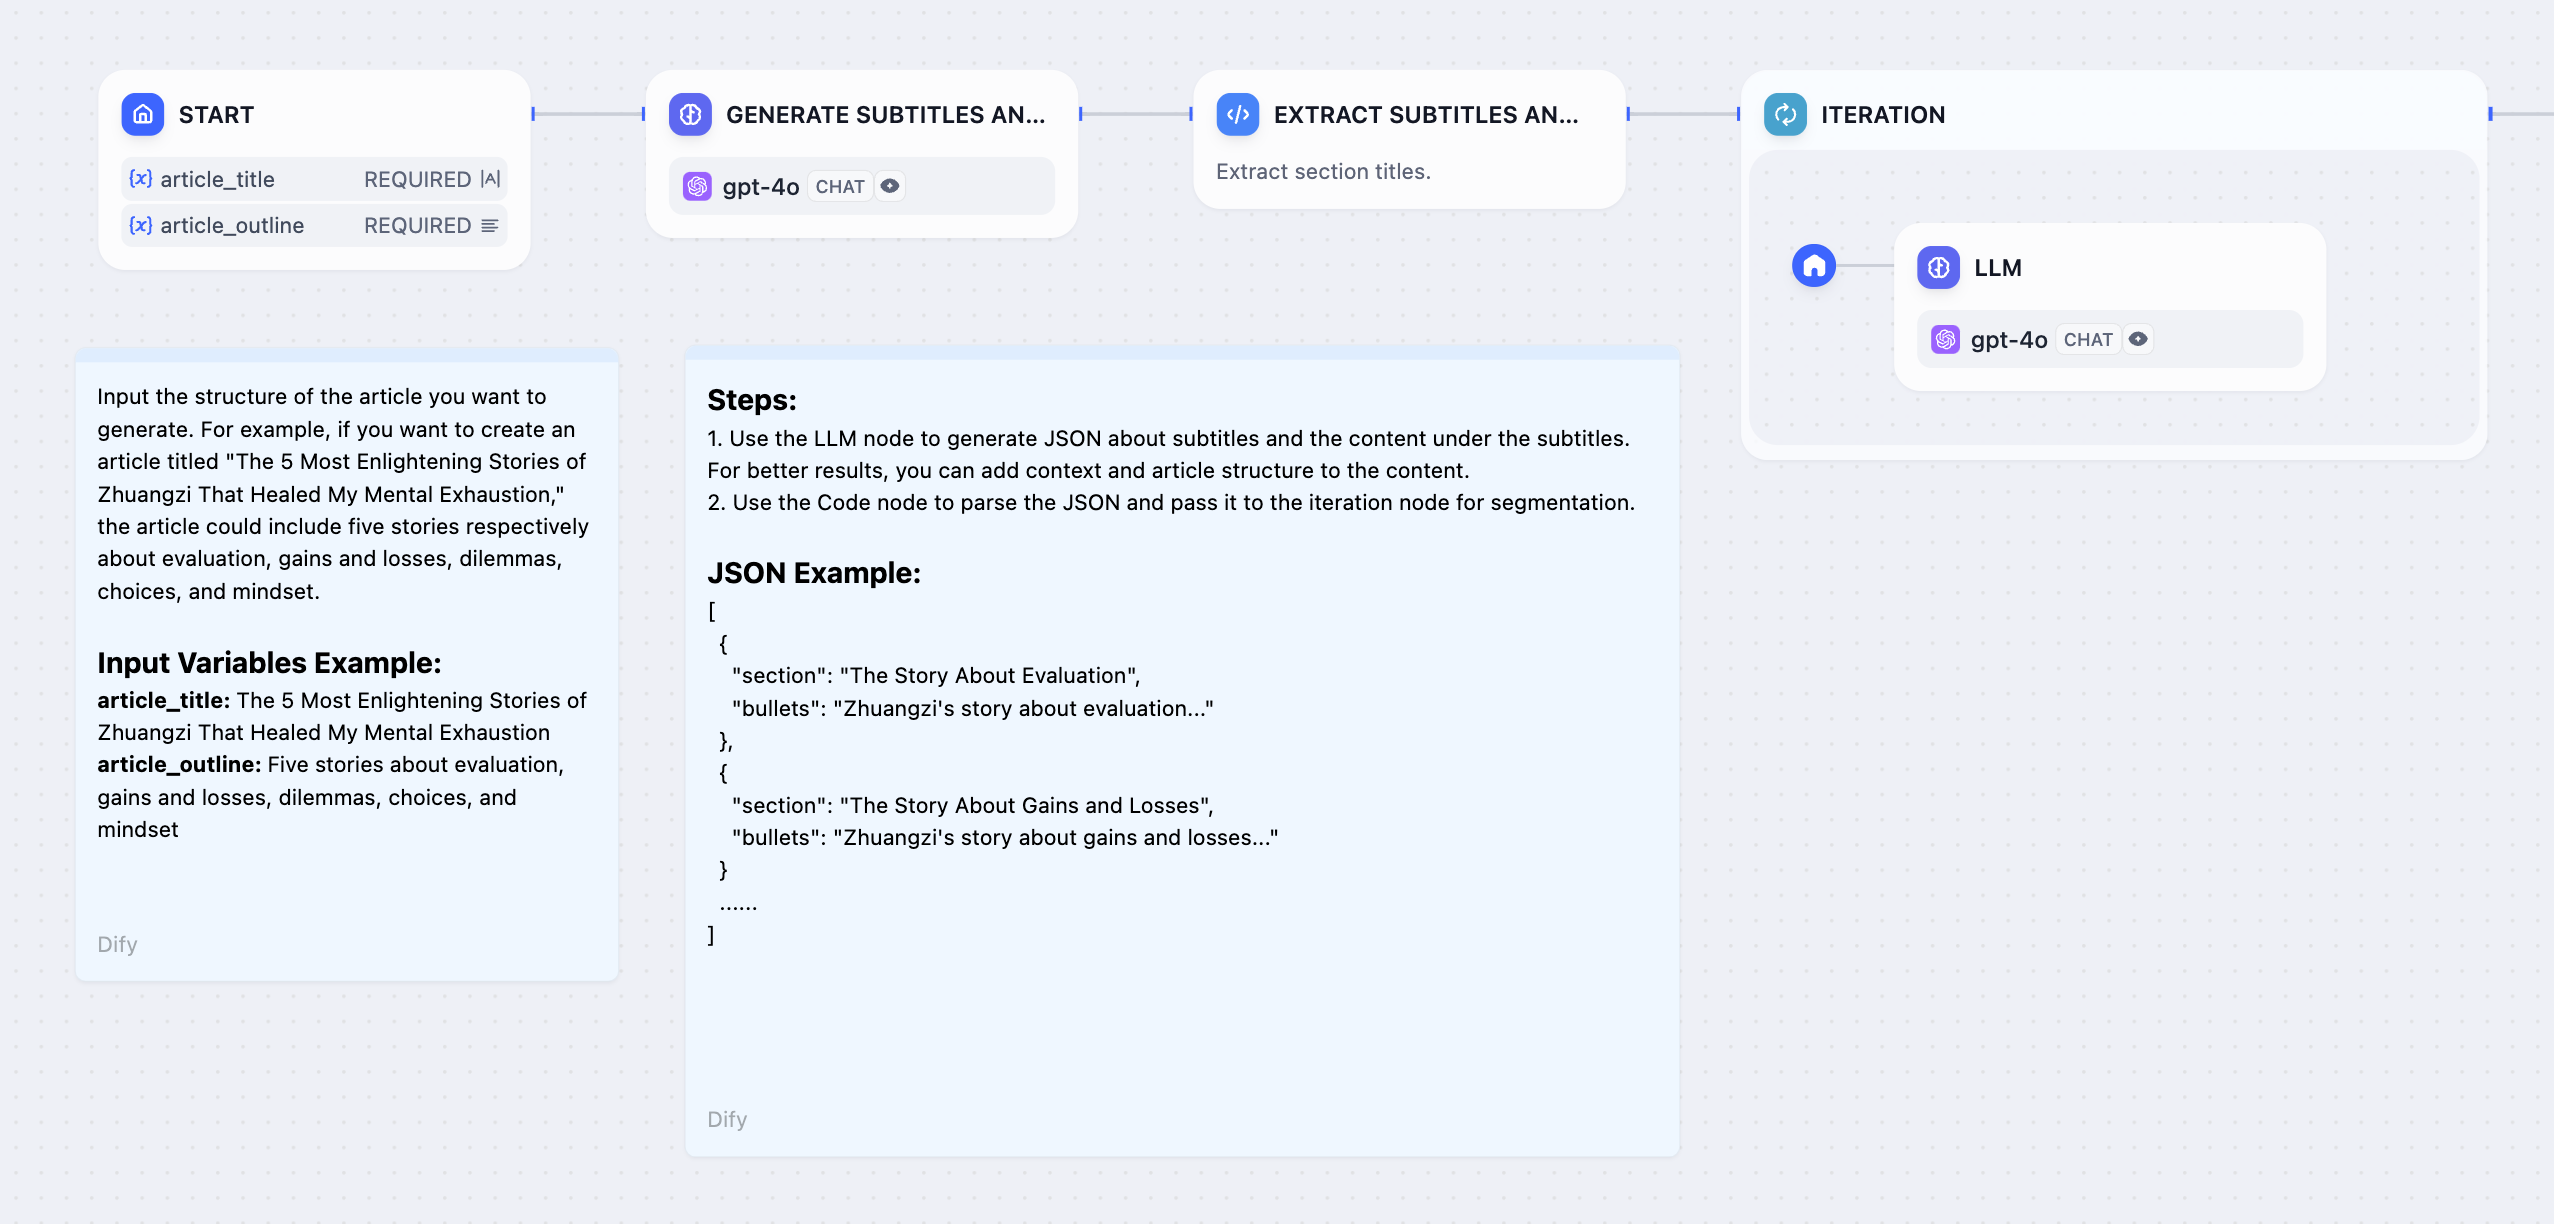
</Frame>
**Workflow Steps**:
1. **Start Node** - User provides story title and outline
2. **LLM Node** - Generate detailed chapter breakdown
3. **Parameter Extractor** - Convert chapter list to structured array
4. **Iteration Node** - Process each chapter with internal LLM
5. **Answer Node** - Stream chapter content as it's generated
<Frame>
</Frame>
<Frame>
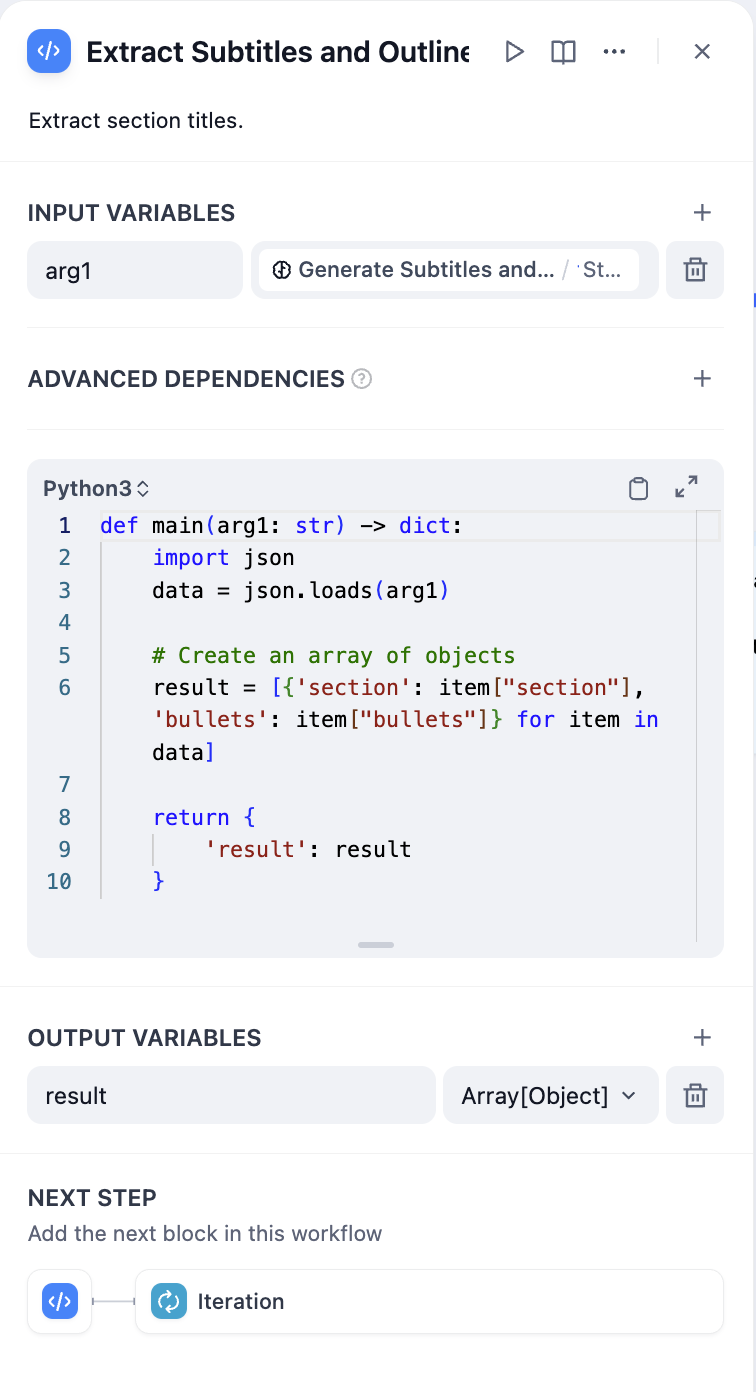
</Frame>
<Frame>
</Frame>
<Info>
Parameter extraction effectiveness depends on model capabilities and instruction quality. Use stronger models and provide examples in instructions to improve results.
</Info>
## Output Processing
Iteration nodes output arrays that often need conversion for final use:
### Convert Array to Text
<Tabs>
<Tab title="Using Code Node">
```python theme={null}
def main(articleSections: list):
return {
"result": "\n".join(articleSections)
}
```
<Frame>
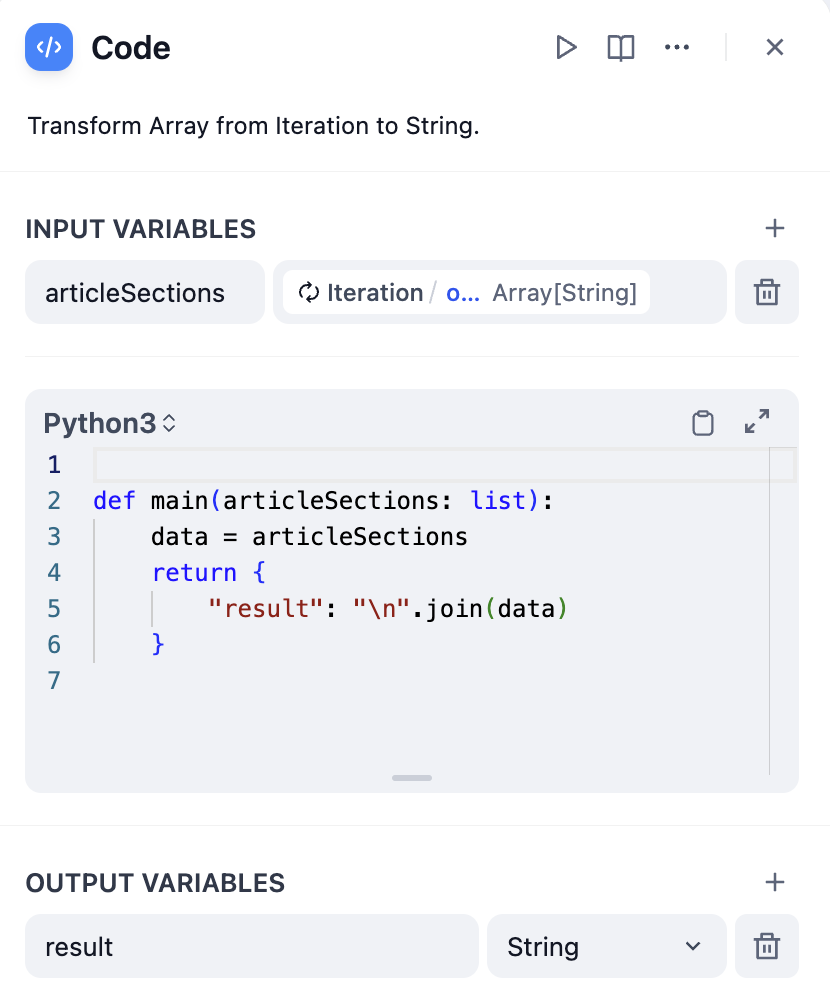
</Frame>
</Tab>
<Tab title="Using Template Node">
```jinja theme={null}
{{ articleSections | join("\n") }}
```
<Frame>
</Frame>
</Tab>
</Tabs>
# Knowledge Retrieval
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/knowledge-retrieval
Retrieve relevant content from knowledge bases and use it as context for downstream nodes
Use the Knowledge Retrieval node to integrate existing knowledge bases into your workflows. The node searches specific knowledge for information relevant to queries and outputs results as contextual content for use in downstream nodes (e.g., LLMs).
Below is an example of using the Knowledge Retrieval node in a Chatflow:
1. The **User Input** node collects the user query.
2. The **Knowledge Retrieval** node searches the selected knowledge base(s) for content related to the user query and outputs the retrieval results.
3. The **LLM** node generates a response based on both the user query and the retrieved knowledge.
4. The **Answer** node returns the LLM's response to the user.
<Frame>
<img alt="Knowledge Retrieval Node Use Case" />
</Frame>
Before using a Knowledge Retrieval node, ensure that you have at least one available knowledge base. To learn about creating knowledge bases, see [Knowledge](/en/self-host/use-dify/knowledge/readme#create-knowledge).
## Configure the Node
To make the Knowledge Retrieval node work properly, you need to specify:
* *What* it should search for (the query)
* *Where* it should search (the knowledge base)
* *How* to process the retrieval results (the node-level retrieval settings)
You can also use document metadata to enable filter-based searches and further improve retrieval precision.
### Specify the Query
Provide the query content that the node should search for in the selected knowledge base(s).
* **Query Text**: Select a text variable. For example, use `userinput.query` to reference user input in Chatflows, or a custom text-type user input variable in Workflows.
* **Query Images**: Select an image variable, e.g., the image(s) uploaded by the user through a User Input node, to search by image.
Each image must be 2 MB or smaller by default; adjust the cap via the `ATTACHMENT_IMAGE_FILE_SIZE_LIMIT` environment variable.
<Info>
The **Query Images** option is available only when at least one multimodal knowledge base is added.
Such knowledge bases are marked with the **Vision** tag, indicating that they are using a multimodal embedding model.
</Info>
### Select Knowledge to Search
Add one or more existing knowledge bases for the node to search for content relevant to the query.
When multiple knowledge bases are added, knowledge is first retrieved from all of them simultaneously, then combined and processed according to the [node-level retrieval settings](#configure-node-level-retrieval-settings).
<Info>
Knowledge bases marked with the **Vision** tag support cross-modal retrieval: they return both text and images based on semantic relevance.
</Info>
You can click the **Edit** icon next to any added knowledge base to modify its [settings](/en/self-host/use-dify/knowledge/manage-knowledge/introduction).
### Configure Node-Level Retrieval Settings
To fine-tune how the node processes retrieval results after they are fetched from the knowledge base(s), click **Retrieval Setting**.
<Info>
Retrieval settings exist at two layers: the knowledge base level and the knowledge retrieval node level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the node settings further rerank the results or narrow down the pool.
</Info>
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
<Note>
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
</Note>
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
### Enable Metadata Filtering
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/self-host/use-dify/knowledge/metadata).
## Output
The Knowledge Retrieval node outputs the retrieval results as a variable named `result`, which is an array of retrieved document chunks containing their content, metadata, title, and other attributes.
When the retrieval results contain image attachments, the `result` variable also includes a field named `files` containing image details.
## Use with LLM Nodes
To use the retrieval results as context in an LLM node:
1. In **Context**, select the Knowledge Retrieval node's `result` variable.
2. In the system instruction, reference the `Context` variable.
3. Optional: If the LLM is vision-capable, enable **Vision** so it can process image attachments in the retrieval results.
<Info>
You don't need to specify the retrieval results as the vision input. Once **Vision** is enabled, the LLM will automatically access any retrieved images.
</Info>
In chatflows, citations are shown alongside responses that reference knowledge by default. You can turn this off by disabling **[Citation and Attributions](/en/self-host/use-dify/build/additional-features#citations-and-attributions)** in **Features** at the top right corner of the canvas.
# LLM
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/llm
Invoke language models for text generation and analysis
The LLM node invokes language models to process text, images, and documents. It sends prompts to your configured models and captures their responses, supporting structured outputs, context management, and multimodal inputs.
<Frame>
</Frame>
<Info>
Configure at least one model provider in **Integrations** > **Model Provider** before using LLM nodes.
</Info>
## Model Selection and Parameters
Choose from any model provider you've configured. Different models excel at different tasks - GPT-4 and Claude 3.5 handle complex reasoning well but cost more, while GPT-3.5 Turbo balances capability with affordability. For local deployment, use Ollama, LocalAI, or Xinference.
<Frame>
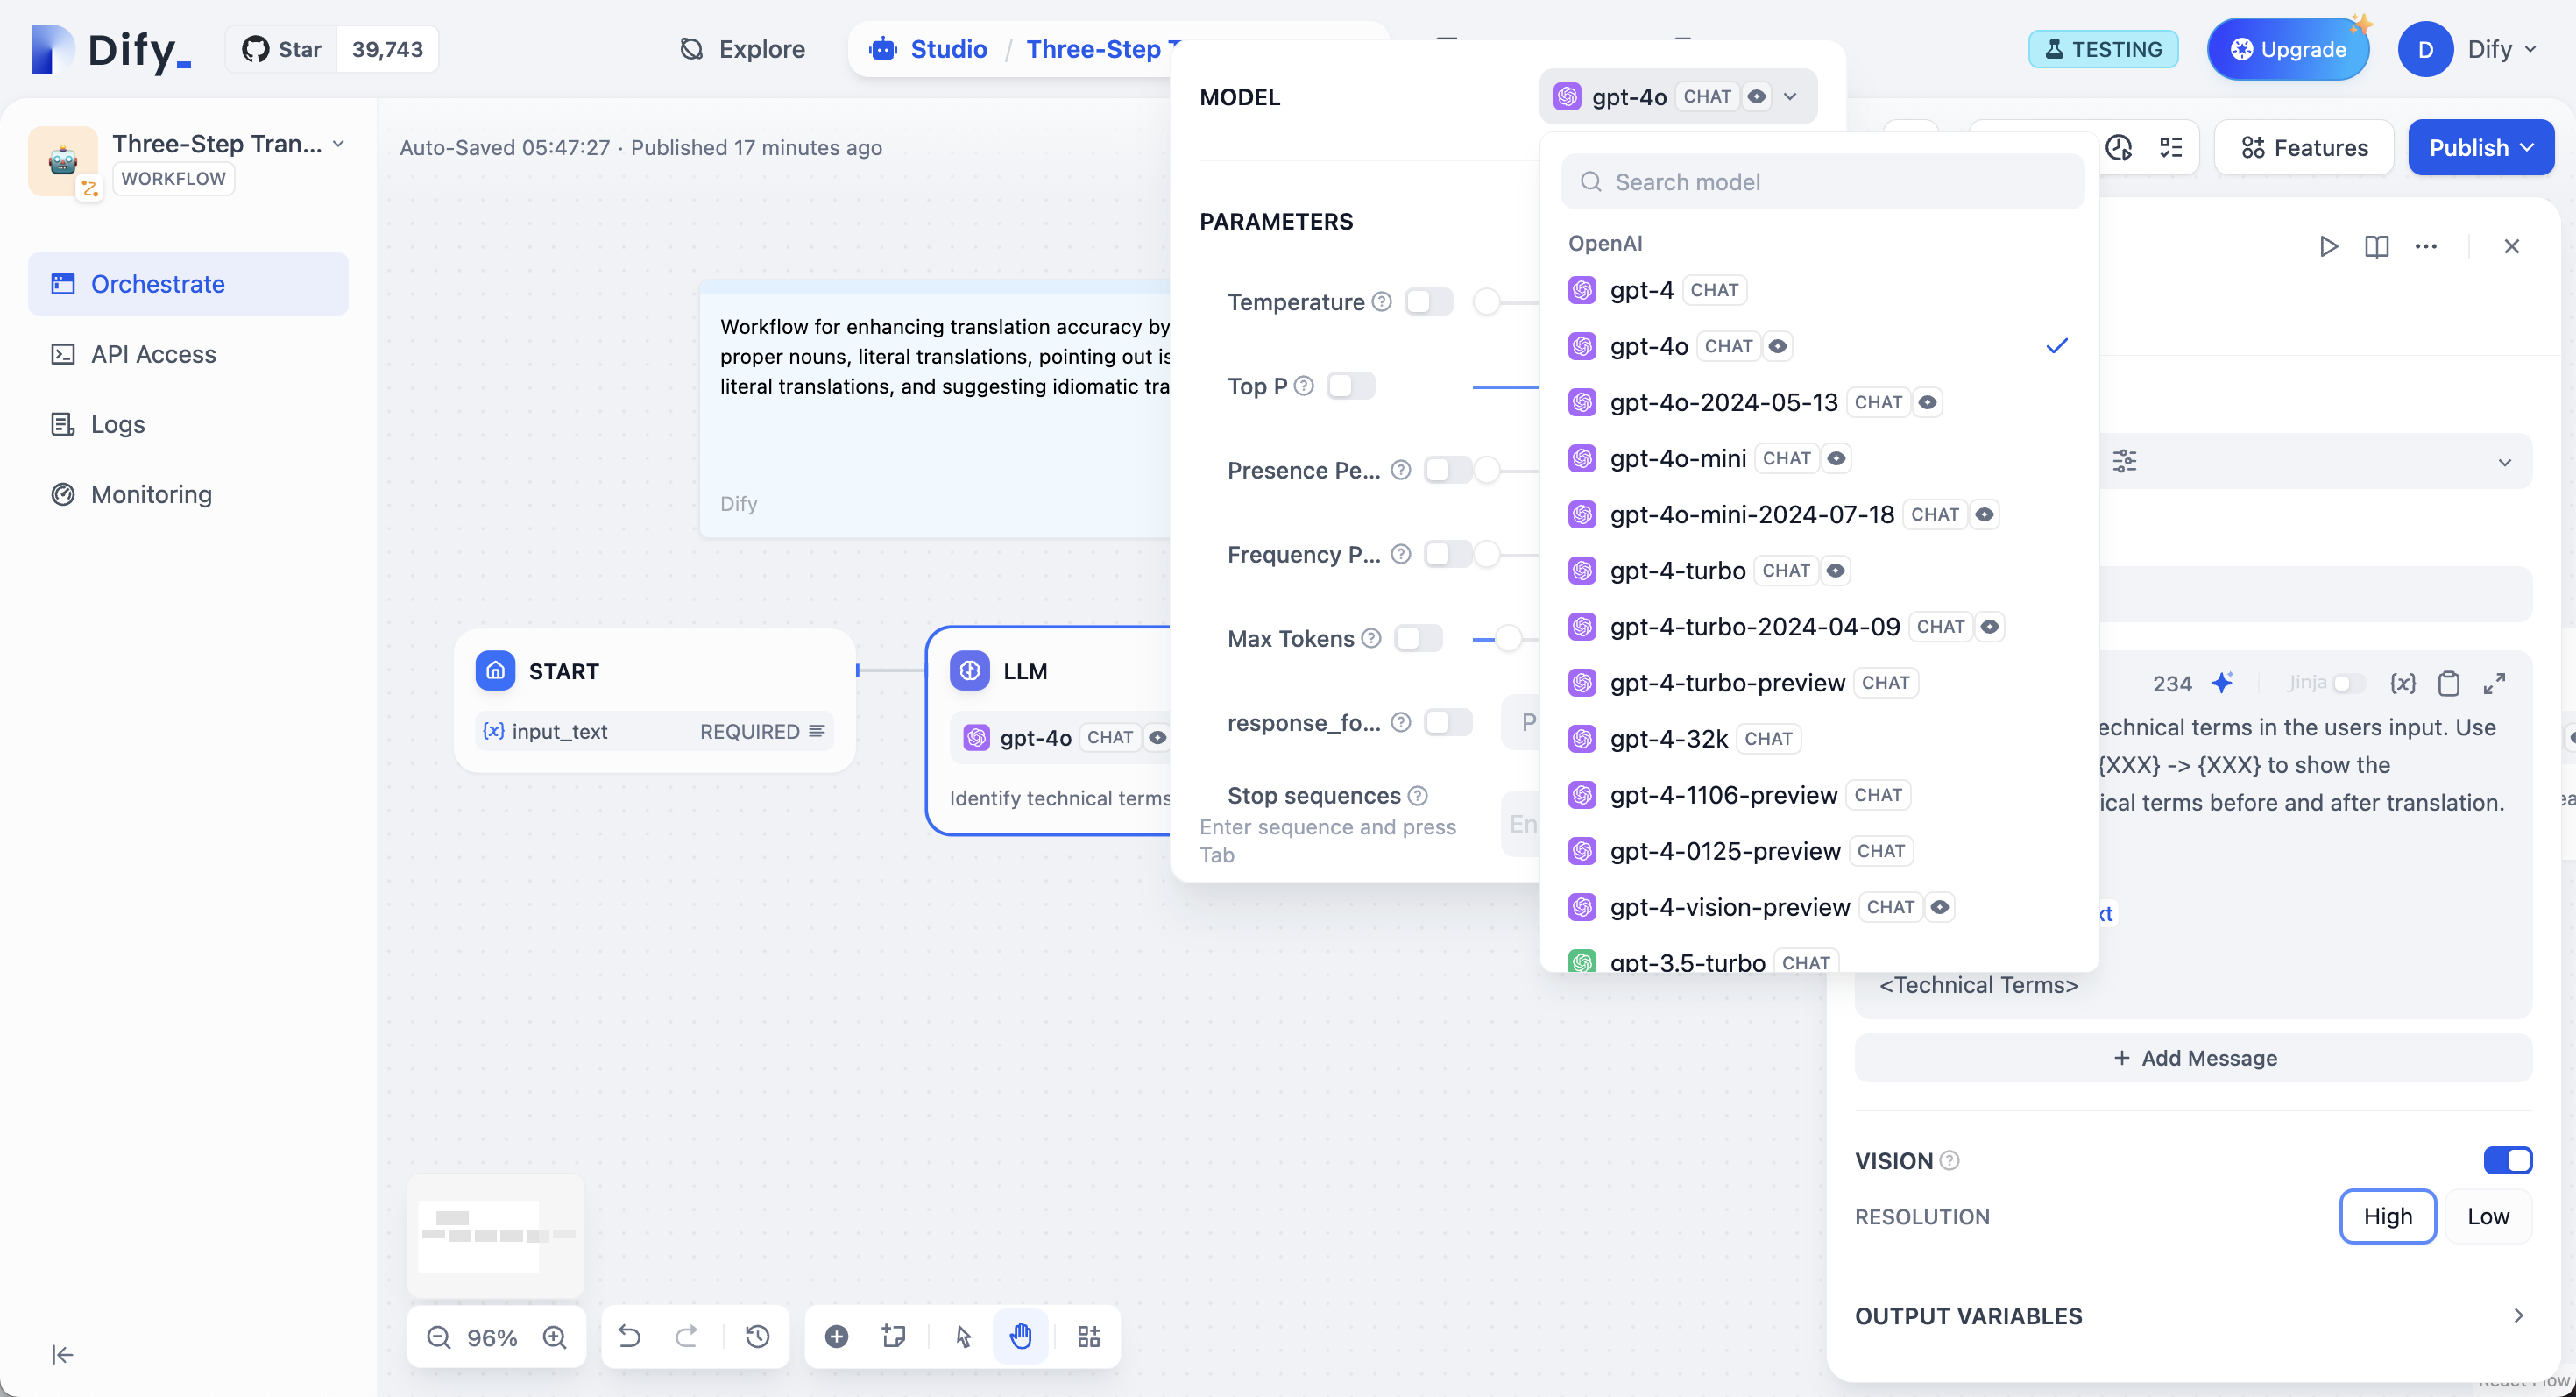
</Frame>
Model parameters control response generation. **Temperature** ranges from 0 (deterministic) to 1 (creative). **Top P** limits word choices by probability. **Frequency Penalty** reduces repetition. **Presence Penalty** encourages new topics. You can also use presets: **Precise**, **Balanced**, or **Creative**.
### Share a Model Configuration Across Nodes
When several LLM nodes should run on the same model, store the model selection in an environment variable instead of configuring each node separately. Editing the variable, such as pointing it at a different model, updates every node bound to it.
Open the **Environment Variables** panel, add a variable of the **LLM** type, and choose a model with its parameters.
Then, in each LLM node, switch the **Model** field to variable mode, and pick the variable. The variable carries the provider, model, and model parameters; prompts and other settings stay with each node.
## Prompt Configuration
Your interface adapts based on model type. Chat models use message roles (**System** for behavior, **User** for input, **Assistant** for examples), while completion models use simple text continuation.
Reference workflow variables in prompts using double curly braces: `{{variable_name}}`. Variables are replaced with actual values before reaching the model.
```text theme={null}
System: You are a technical documentation expert.
User: {{user_input}}
```
## Context Variables
Context variables inject external knowledge while preserving source attribution. This enables RAG applications where LLMs answer questions using your specific documents.
<Frame>
</Frame>
Connect a Knowledge Retrieval node's output to your LLM node's context input, then reference it:
```text theme={null}
Answer using only this context:
{{knowledge_retrieval.result}}
Question: {{user_question}}
```
When using context variables from knowledge retrieval, Dify automatically tracks citations so users see information sources.
## Structured Outputs
Force models to return specific data formats like JSON for programmatic use. Configure through three methods:
<Tabs>
<Tab title="Visual Editor">
User-friendly interface for simple structures. Add fields with names and types, mark required fields, set descriptions. The editor generates JSON Schema automatically.
</Tab>
<Tab title="JSON Schema">
Write schemas directly for complex structures with nested objects, arrays, and validation rules.
```json theme={null}
{
"type": "object",
"properties": {
"sentiment": {
"type": "string",
"enum": ["positive", "negative", "neutral"]
}
},
"required": ["sentiment"]
}
```
</Tab>
<Tab title="AI Generation">
Describe needs in plain language and let AI generate the schema.
</Tab>
</Tabs>
<Warning>
Models with native JSON support handle structured outputs reliably. For others, Dify includes the schema in prompts, but results may vary.
</Warning>
## Memory and File Processing
<Frame>
<img alt="LLM Memory" />
</Frame>
Enable Memory to maintain context across multiple LLM calls within a Chatflow conversation. When enabled, previous interactions will be included in subsequent prompts as formatted user - assistant outputs. You can customize what goes into the user prompts by editing the `USER` template. Memory is node-specific and doesn't persist between different conversations.
For **File Processing**, add file variables to prompts for multimodal models. GPT-4V handles images, Claude processes PDFs directly, while other models might need preprocessing.
### Vision Configuration
When processing images, you can control the detail level:
* **High detail** - Better accuracy for complex images but uses more tokens
* **Low detail** - Faster processing with fewer tokens for simple images
The default variable selector for vision is `userinput.files` which automatically picks up files from the User Input node.
<Frame>
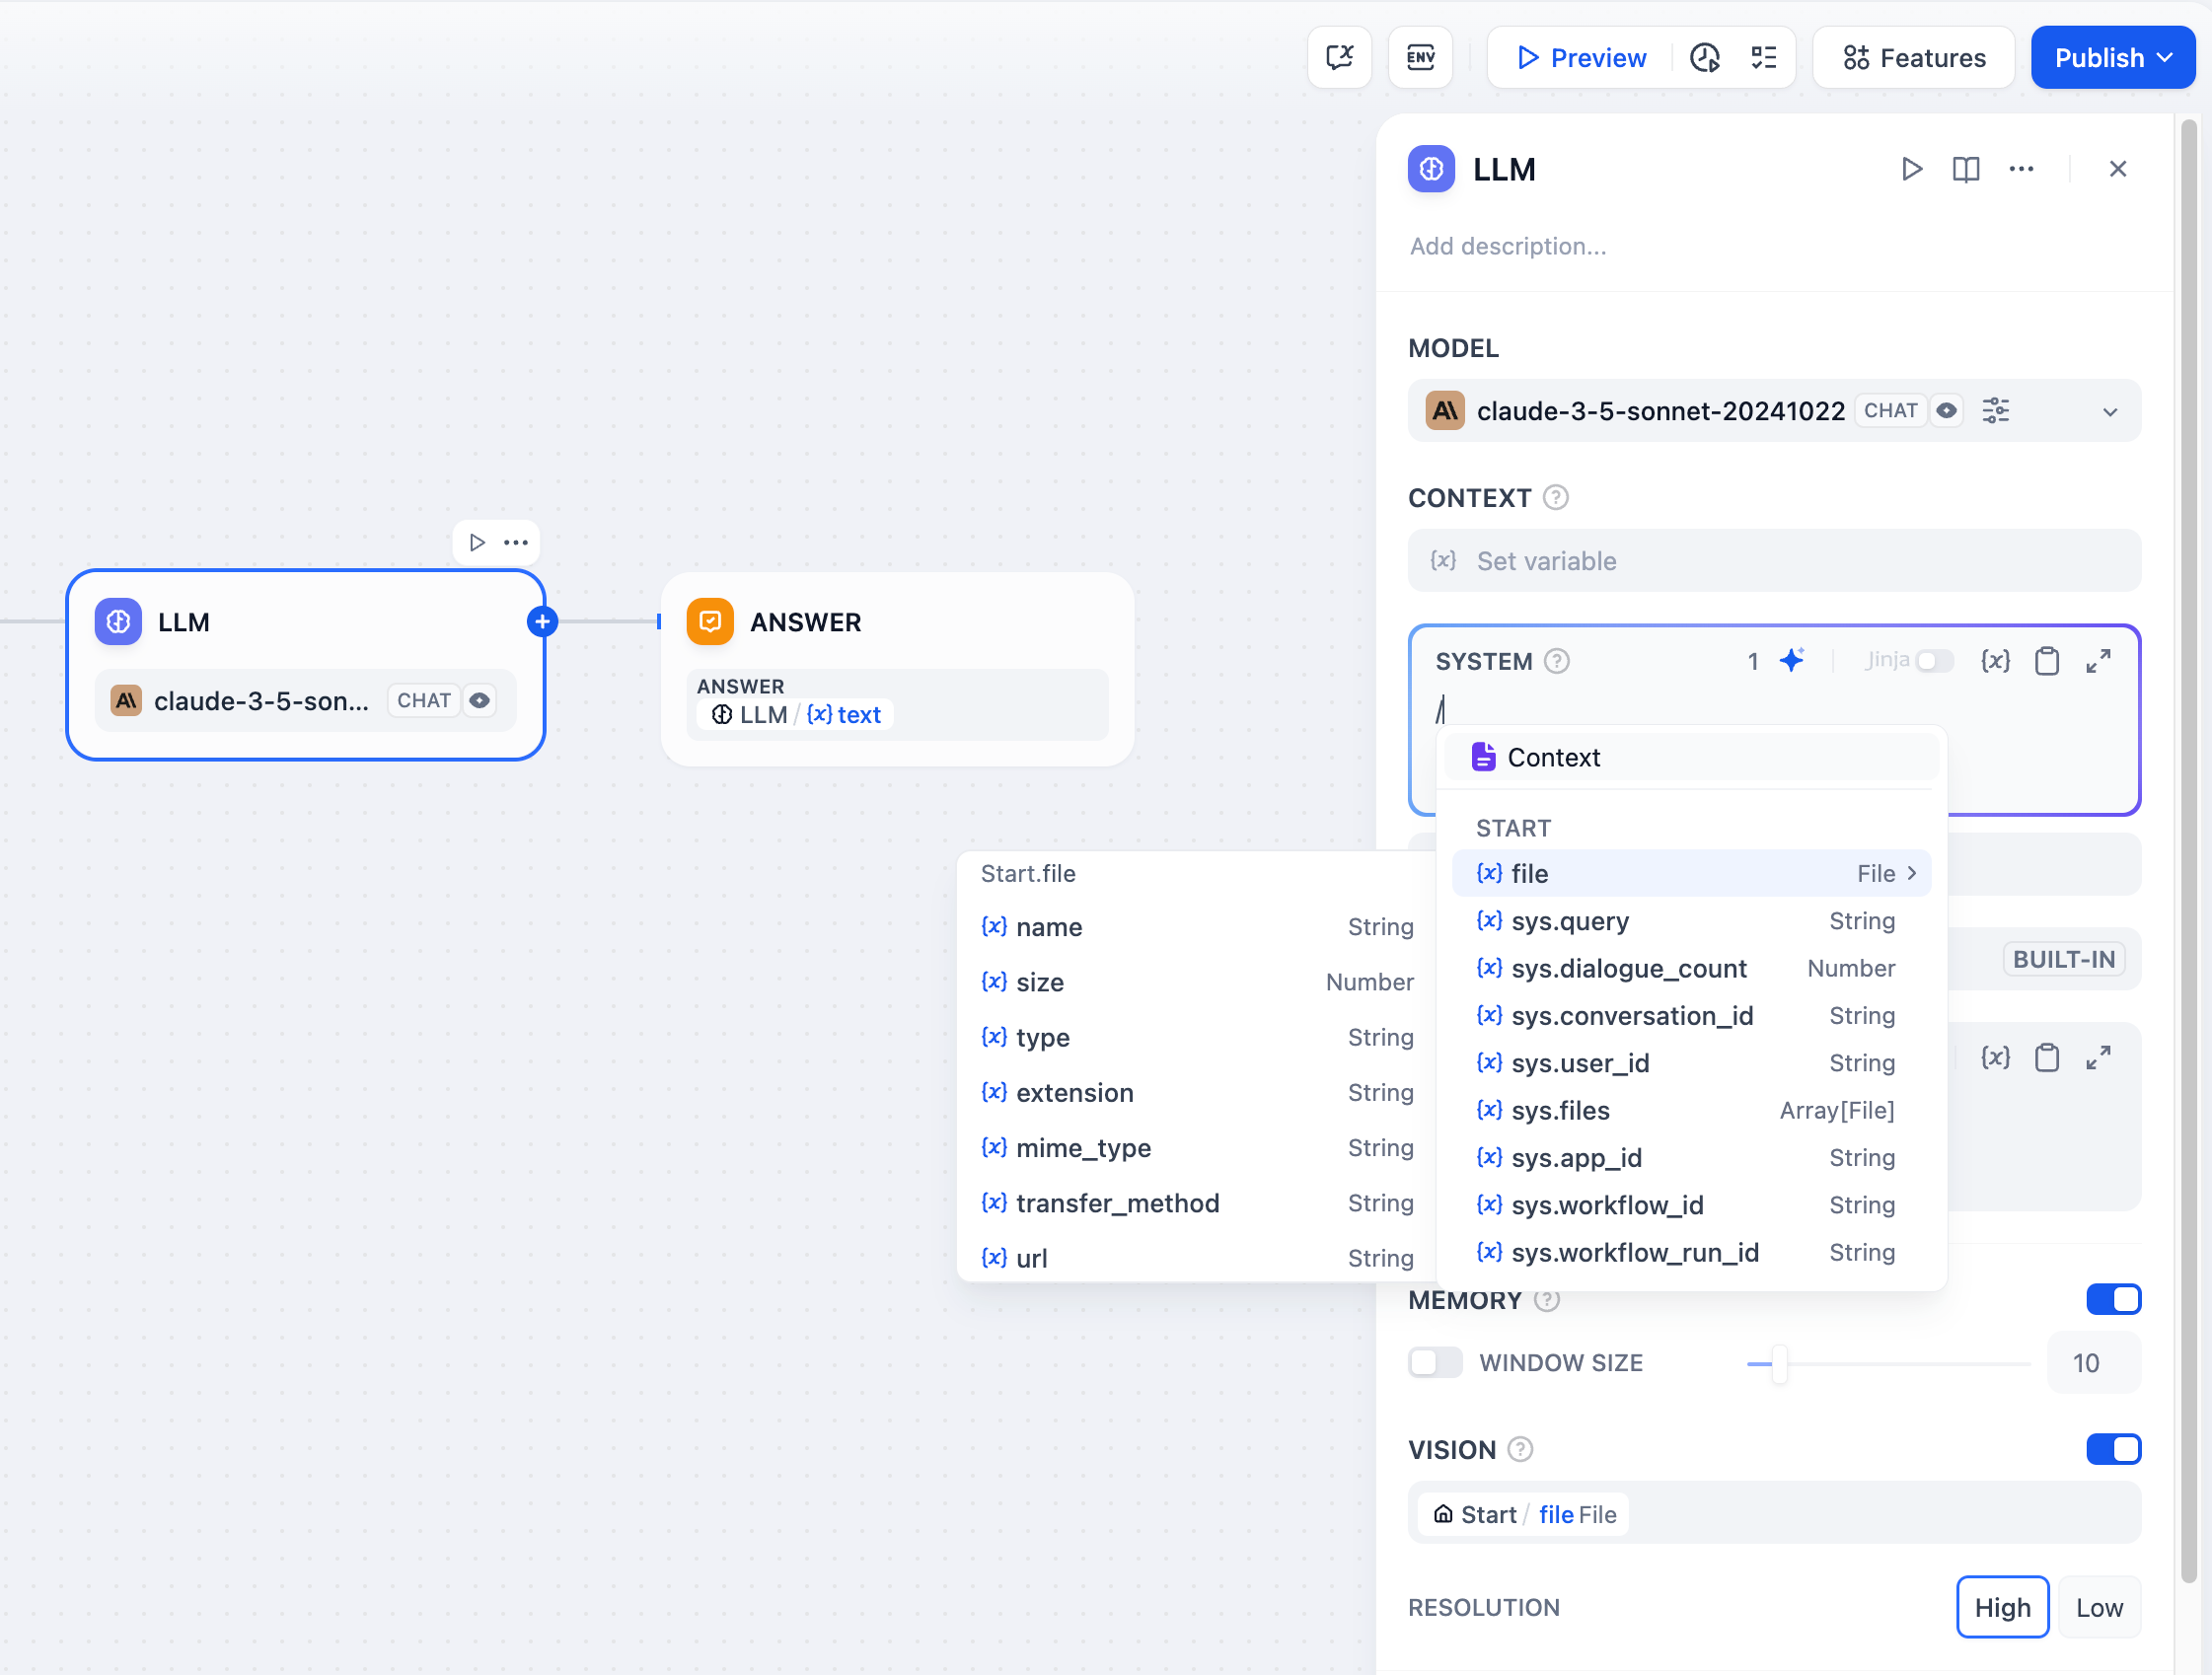
</Frame>
## Jinja2 Template Support
LLM prompts support Jinja2 templating for advanced variable handling. When you use Jinja2 mode (`edition_type: "jinja2"`), you can:
```jinja theme={null}
{% for item in search_results %}
{{ loop.index }}. {{ item.title }}: {{ item.content }}
{% endfor %}
```
Jinja2 variables are processed separately from regular variable substitution, allowing for loops, conditionals, and complex data transformations within prompts.
## Streaming Output
LLM nodes support streaming output by default. Each text chunk is yielded as a `RunStreamChunkEvent`, enabling real-time response display. File outputs (images, documents) are processed and saved automatically during streaming.
## Separate Reasoning from Responses
Some reasoning models wrap their thinking in `<think>...</think>` tags inside their response. By default, those tags are included in the `text` output, so the reasoning flows downstream together with the answer.
Turn on the **Enable reasoning tag separation** toggle to split them: the `text` output keeps only the answer, and the thinking moves to a separate `reasoning_content` output variable. While the toggle is off, `reasoning_content` stays empty.
In API calls, this toggle appears as the `reasoning_format` parameter. When the toggle is on, `reasoning_format` is `separated`, and streaming API clients receive the reasoning as dedicated `reasoning_chunk` events, outside the answer stream. For event details, see [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) and [Run Workflow](/en/api-reference/workflow-runs/run-workflow).
<Info>
This setting affects only models that wrap their reasoning in `<think>` tags.
</Info>
## Error Handling
Configure retry behavior for failed LLM calls. Set maximum retry attempts, intervals between retries, and backoff multipliers. Define fallback strategies like default values, error routing, or alternative models when retries aren't sufficient.
# Loop
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/loop
Execute repetitive workflows with progressive refinement
The Loop node executes repetitive workflows where each cycle builds on the results of the previous one. Unlike iteration, which processes array elements independently, loops create progressive workflows that evolve with each repetition.
## Loop vs Iteration
Understanding when to use each repetition pattern:
<Tabs>
<Tab title="Loop">
**Sequential Processing** - Each cycle depends on previous results
**Progressive Refinement** - Outputs improve or evolve over iterations
**State Management** - Variables persist and accumulate across cycles
**Use Cases** - Content refinement, problem solving, quality assurance
</Tab>
<Tab title="Iteration">
**Independent Processing** - Each item processed separately
**Parallel Execution** - Items can be processed simultaneously
**Batch Operations** - Same operation applied to multiple data points
**Use Cases** - Data transformation, bulk processing, parallel analysis
</Tab>
</Tabs>
## Configuration
### Loop Variables
Define variables that persist across loop iterations and remain accessible after the loop completes. These variables maintain state and enable progressive workflows.
### Termination Conditions
Configure when the loop should stop executing:
**Loop Termination Condition** - Expression that determines when to exit (e.g., `quality_score > 0.9`)
**Maximum Loop Count** - Safety limit to prevent infinite loops
**Exit Loop Node** - Immediate termination when this node is reached
<Info>
The loop terminates when either the termination condition is met, the maximum count is reached, or an Exit Loop node executes. If no conditions are specified, the loop continues until the maximum count.
</Info>
## Basic Loop Example
Generate random numbers until finding one less than 50:
<Frame>
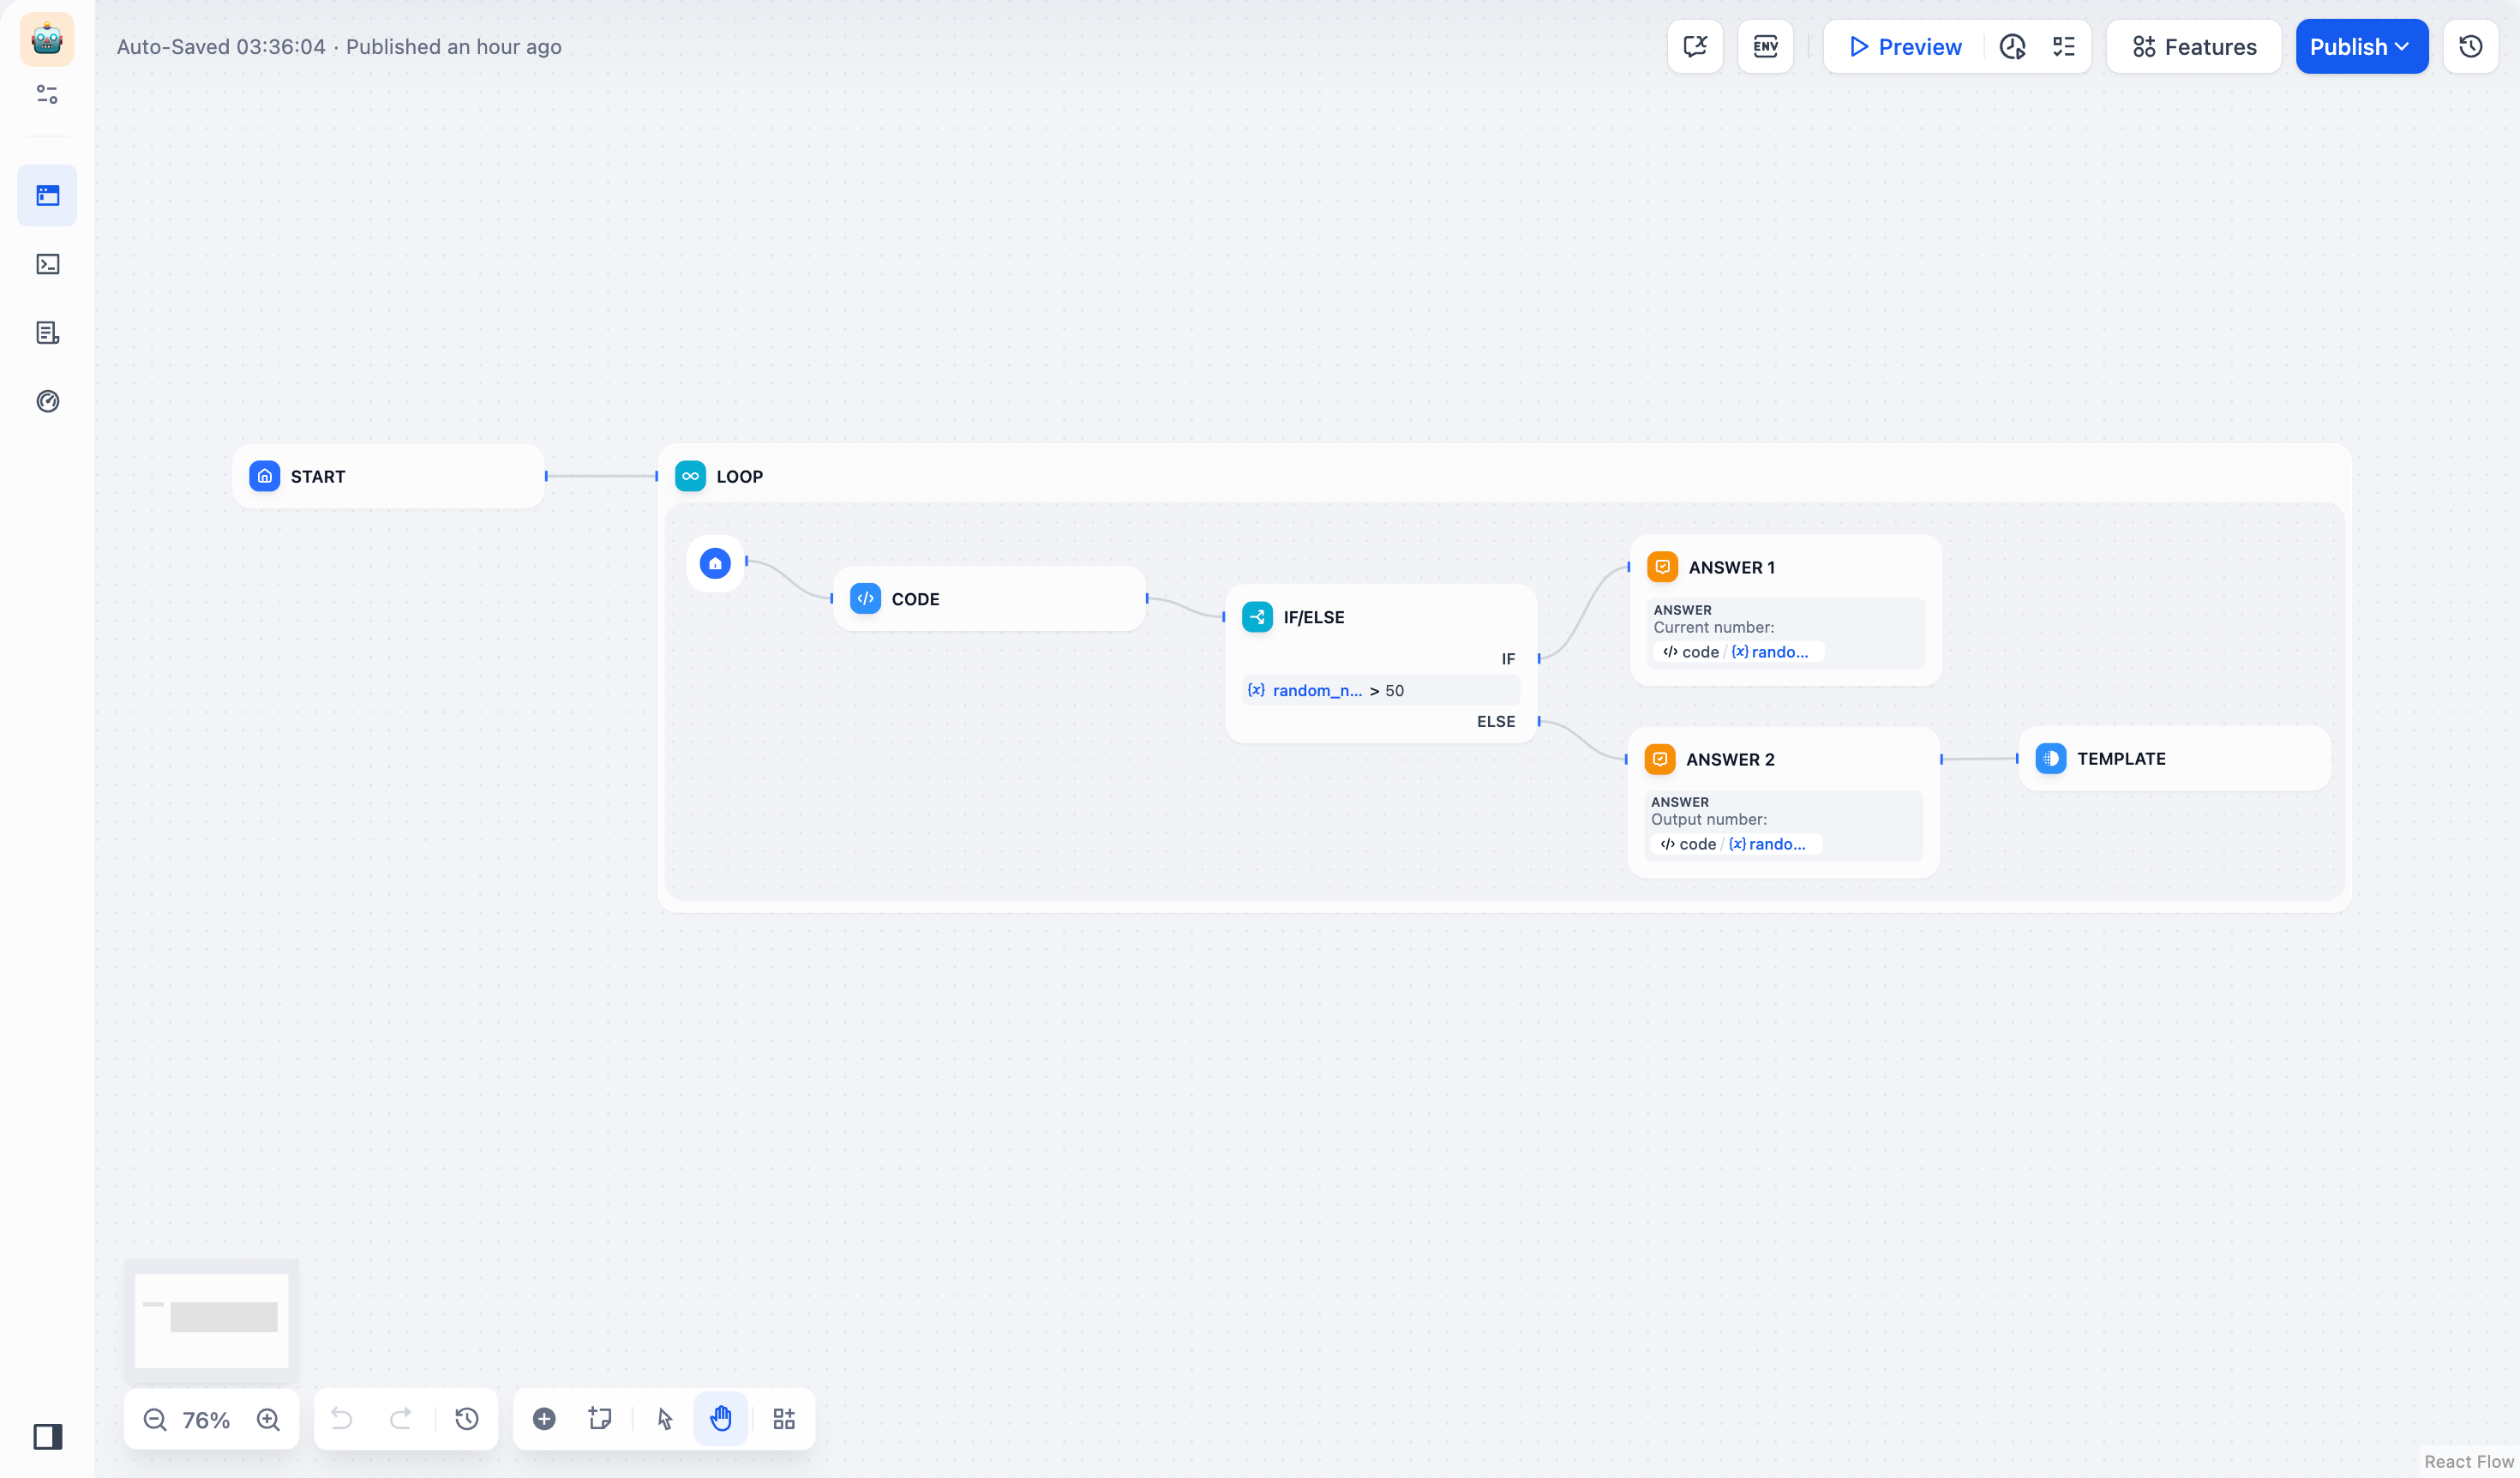
</Frame>
**Workflow Steps**:
1. **Code node** generates random integers between 1-100
2. **If-Else node** checks if number is less than 50
3. **Template node** returns "done" for numbers \< 50 to trigger loop termination
4. Loop continues until termination condition is met
<Frame>
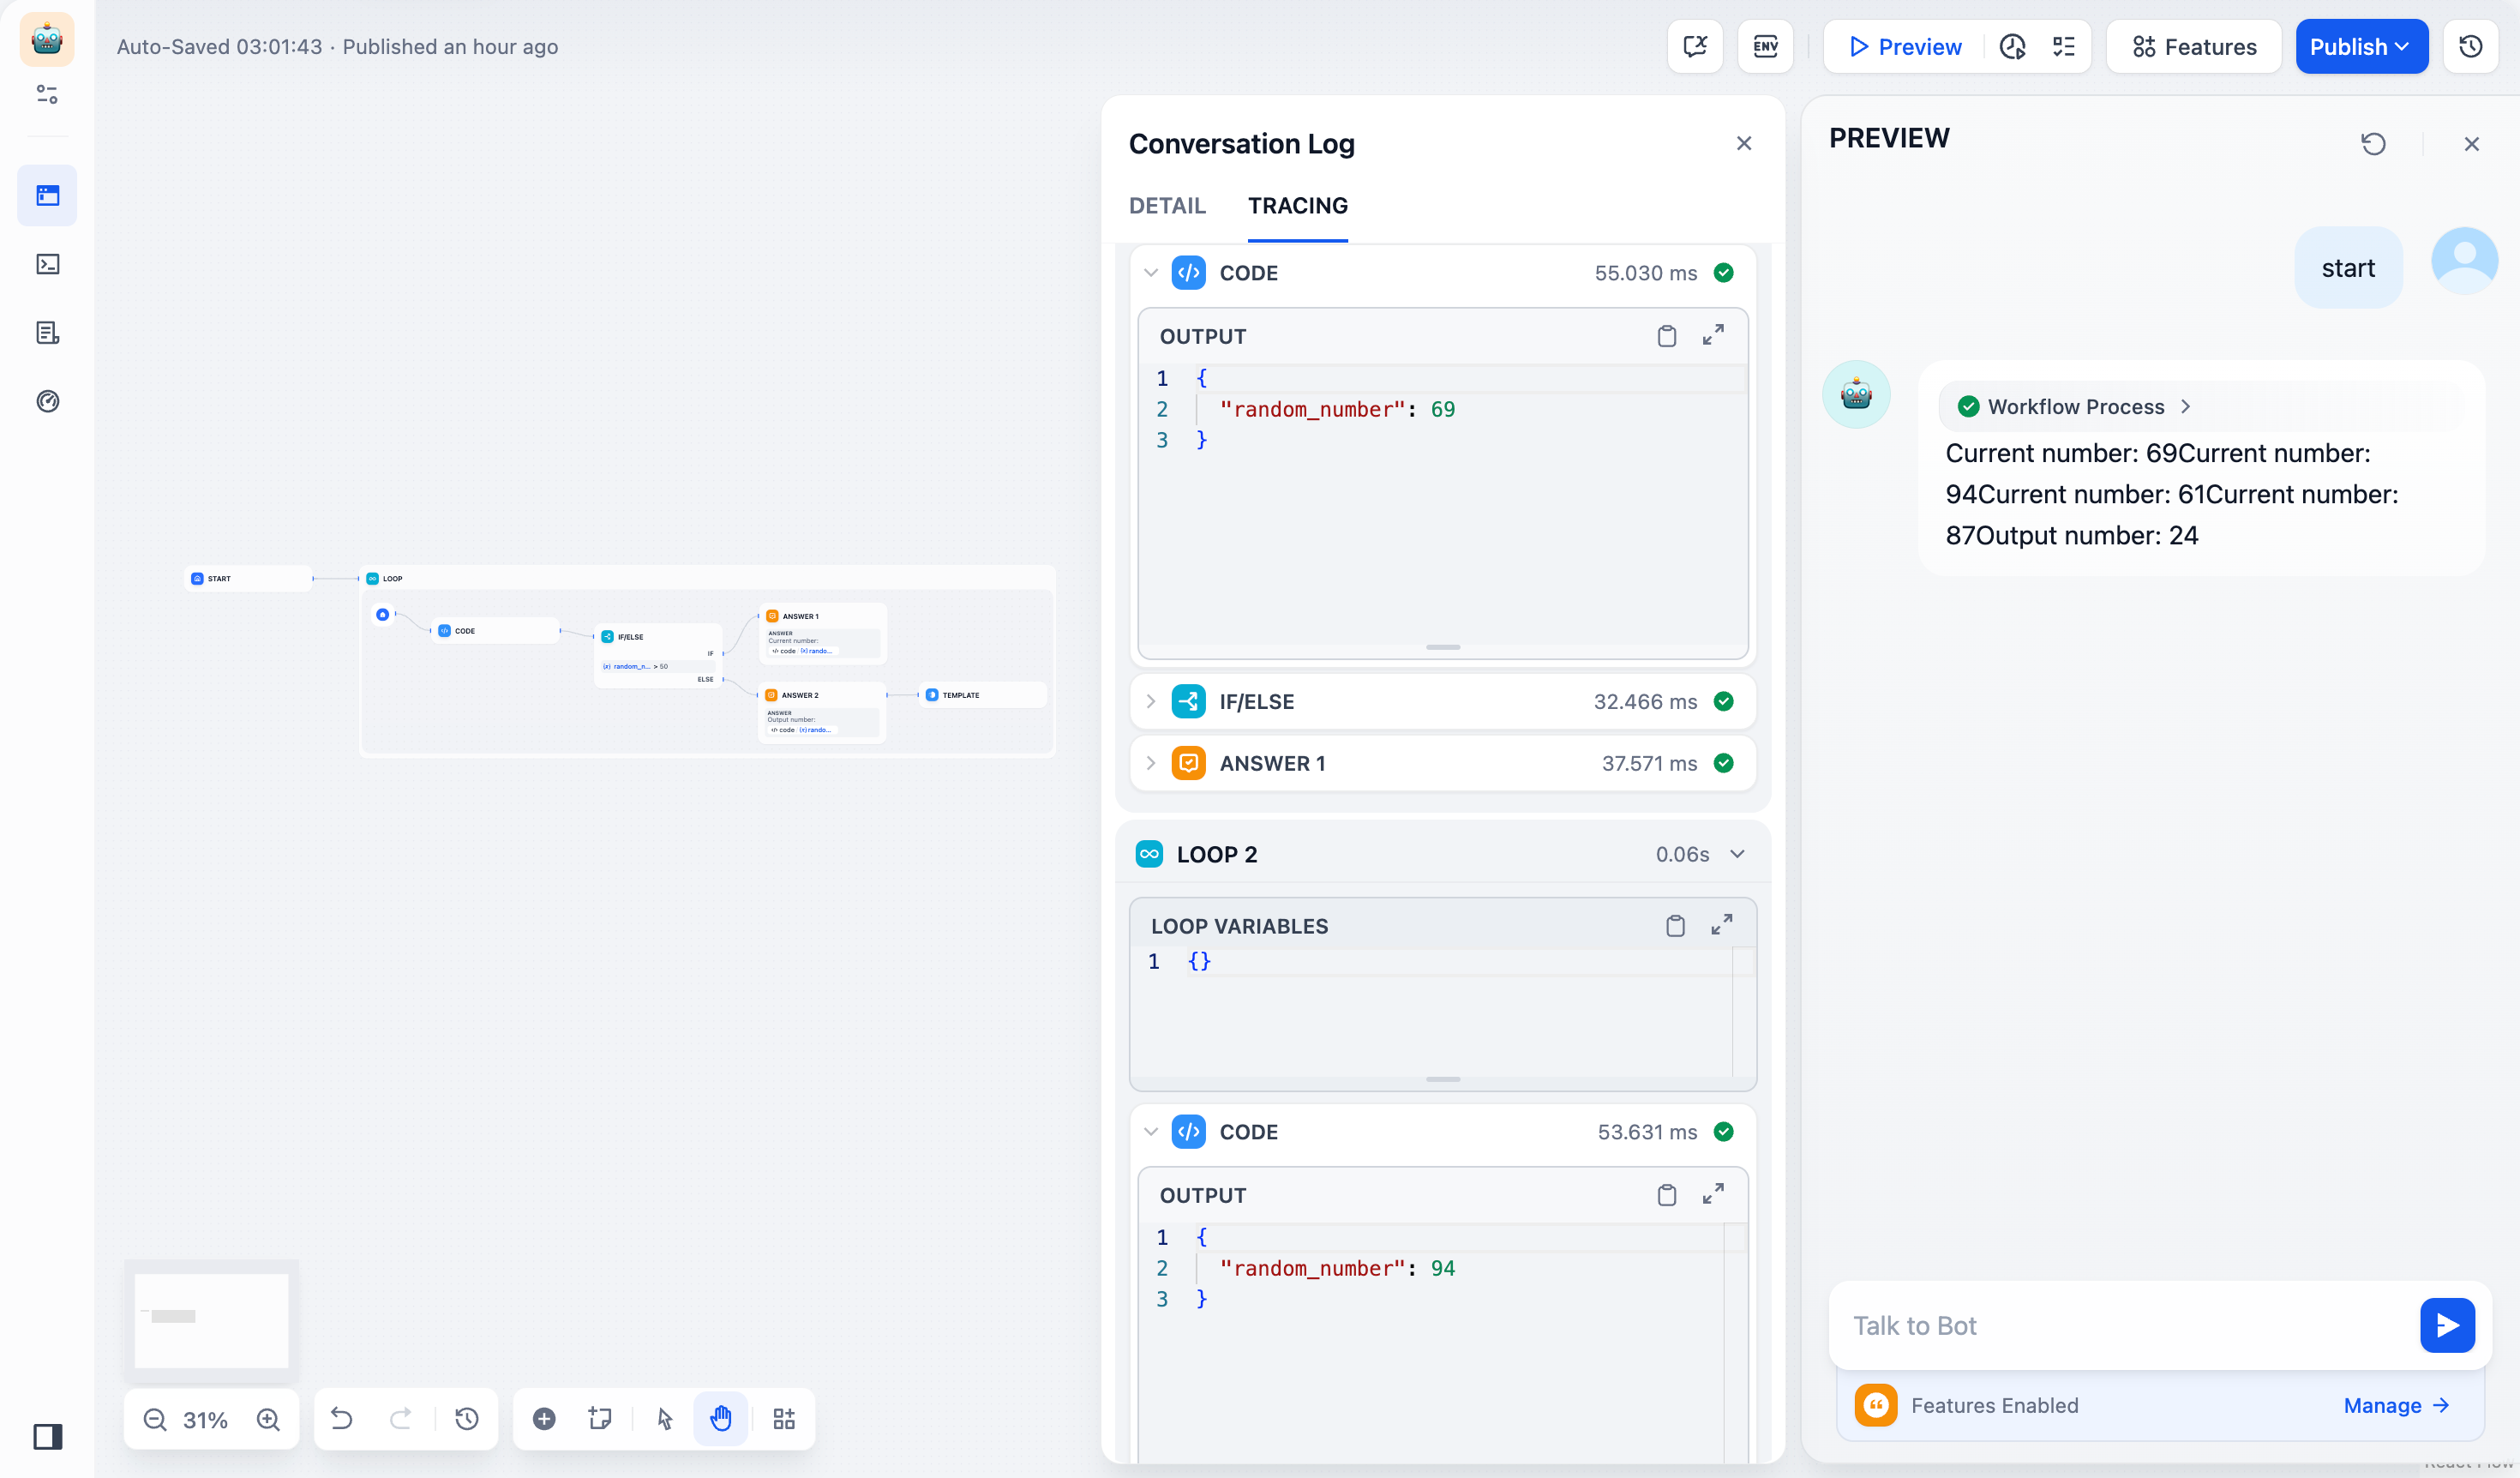
</Frame>
## Advanced Loop Example
Create a poem through iterative refinement, with each version building upon the previous one:
<video />
**Loop Variables**:
* `num` - Counter starting at 0, incrementing each iteration
* `verse` - Text variable holding the current poem version
**Workflow Logic**:
1. **If-Else node** checks if `num > 3` to determine when to exit
2. **LLM node** generates improved poem based on previous version
3. **Variable Assigner** updates both counter and poem content
4. **Exit Loop node** terminates after 4 refinement cycles
The LLM prompt references both the current verse and iteration context:
```text theme={null}
You are a European literary figure creating poetic verses.
Current verse: {{verse}}
Refine and improve this poem based on your previous work.
```
# Output
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/output
Return workflow results to the end user or API caller
Use the Output node to deliver specific variable values from your workflow to the end user or API caller. Add it where you need to surface results.
<Info>
The Output node was previously named *End* and was required in every workflow.
It is now optional—workflows run successfully without one, but any workflow or branch without an Output node returns no data to the caller.
Output nodes are only available in Workflows. Chatflows use the [Answer](/en/self-host/use-dify/nodes/answer) node instead.
</Info>
## Configure Output Variables
Each Output node requires at least one output variable. To add a variable, assign a name and select the source from any upstream node's output.
<Info>
The variable name you assign becomes the key in API responses.
</Info>
You can add multiple output variables to a single Output node and reorder them by dragging.
## Supported Variable Types
Output variables support the following types:
`string`, `number`, `integer`, `boolean`, `object`, `file`, `array[string]`, `array[number]`, `array[object]`, `array[boolean]`, `array[file]`
## Multiple Output Nodes
A workflow can contain more than one Output node. The Output node does not stop workflow execution—other parallel branches (if any) continue running after it completes.
All output variables from every executed Output node are combined into one final result. Each Output node adds its variables to the result as the workflow reaches it:
* On the **same branch**, variables are added in the order the Output nodes are placed.
* On **parallel branches**, whichever Output node executes first adds its variables first.
<Warning>
Always use unique variable names across all Output nodes in a workflow.
When two Output nodes use the same output variable name, the later one overwrites the earlier value.
</Warning>
## API Response Structure
When you call a workflow through the API, output variables appear in the `outputs` object of the response.
<Tabs>
<Tab title="Blocking Mode">
All outputs return in a single response once the workflow completes:
```json theme={null}
{
"workflow_run_id": "...",
"status": "succeeded",
"outputs": {
"result_text": "The processed output...",
"score": 95
}
}
```
</Tab>
<Tab title="Streaming Mode">
Outputs arrive in the final `workflow_finished` event:
```json theme={null}
{
"event": "workflow_finished",
"data": {
"outputs": {
"result_text": "The processed output...",
"score": 95
}
}
}
```
</Tab>
</Tabs>
Each output variable name maps directly to a key in the `outputs` object.
## For Workflow Tools
When you [publish a workflow as a tool](/en/self-host/use-dify/workspace/tools#workflow), the Output node defines the tool's return schema. Each output variable name becomes a key in the tool's result, accessible to the parent workflow that invokes the tool.
# Question Classifier
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/question-classifier
Intelligently categorize user input to route workflow paths
The Question Classifier node intelligently categorizes user input to route conversations down different workflow paths. Instead of building complex conditional logic, you define classes and let the LLM determine which one fits best based on semantic understanding.
## Configuration
### Input and Model Setup
**Input Variable** - Select what to classify, typically `sys.query` for user questions, but can be any text variable from previous workflow nodes.
**Model Selection** - Choose an LLM for classification. Faster models work well for simple classes, while more powerful models handle nuanced distinctions better.
<Frame>
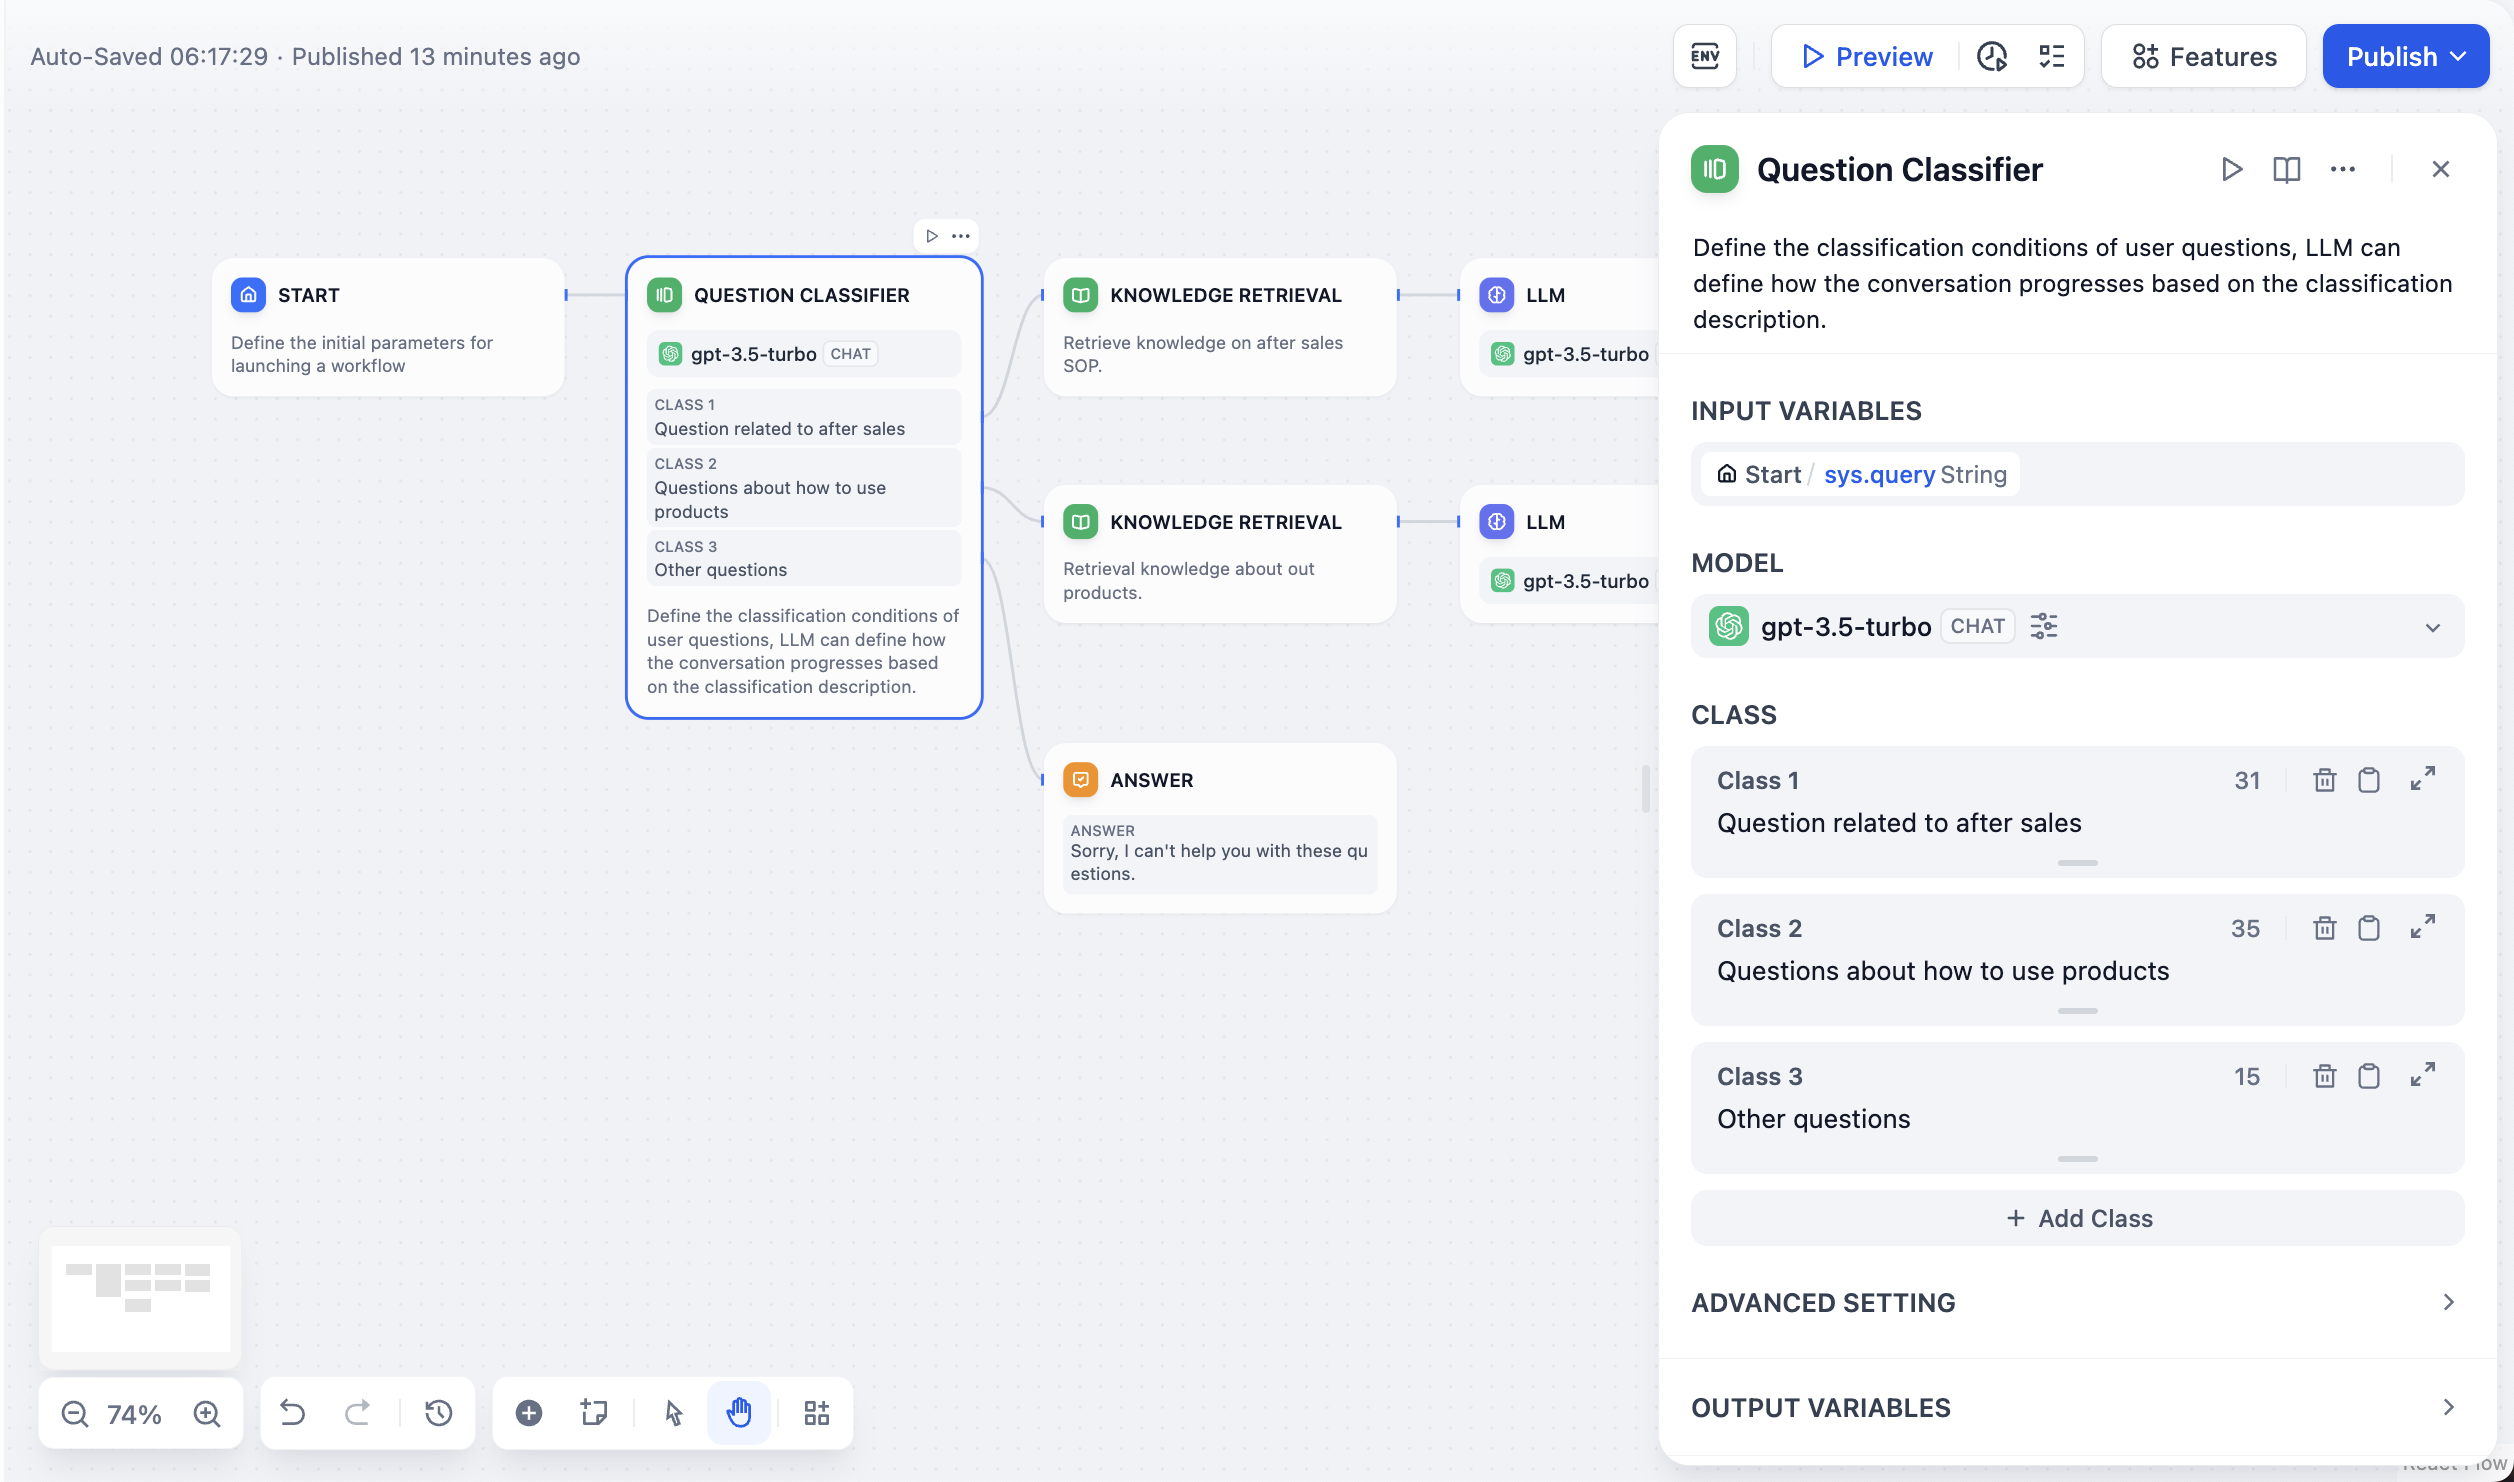
</Frame>
### Class Definition
Each class has two independent pieces of text:
* **Class description** (the editor body) is what the LLM reads when choosing a branch.
Write a precise, distinguishing description of what belongs in the class; boundary phrases like "anything related to..." or "excluding..." help when classes overlap. Exposed downstream as `class_name`.
* **Class title** (the small heading above the editor) is the label shown on the canvas.
Double-click the default **CLASS N** title to rename it. Exposed downstream as `class_label`.
The title and the description edit independently, so you can keep a short, scannable label on the canvas while giving the LLM a longer, more specific description.
Each class becomes a potential output path that you can connect to different downstream nodes like specialized knowledge bases, response templates, or processing workflows.
## Classification Example
Here's how the Question Classifier works in a customer service scenario:
<Frame>
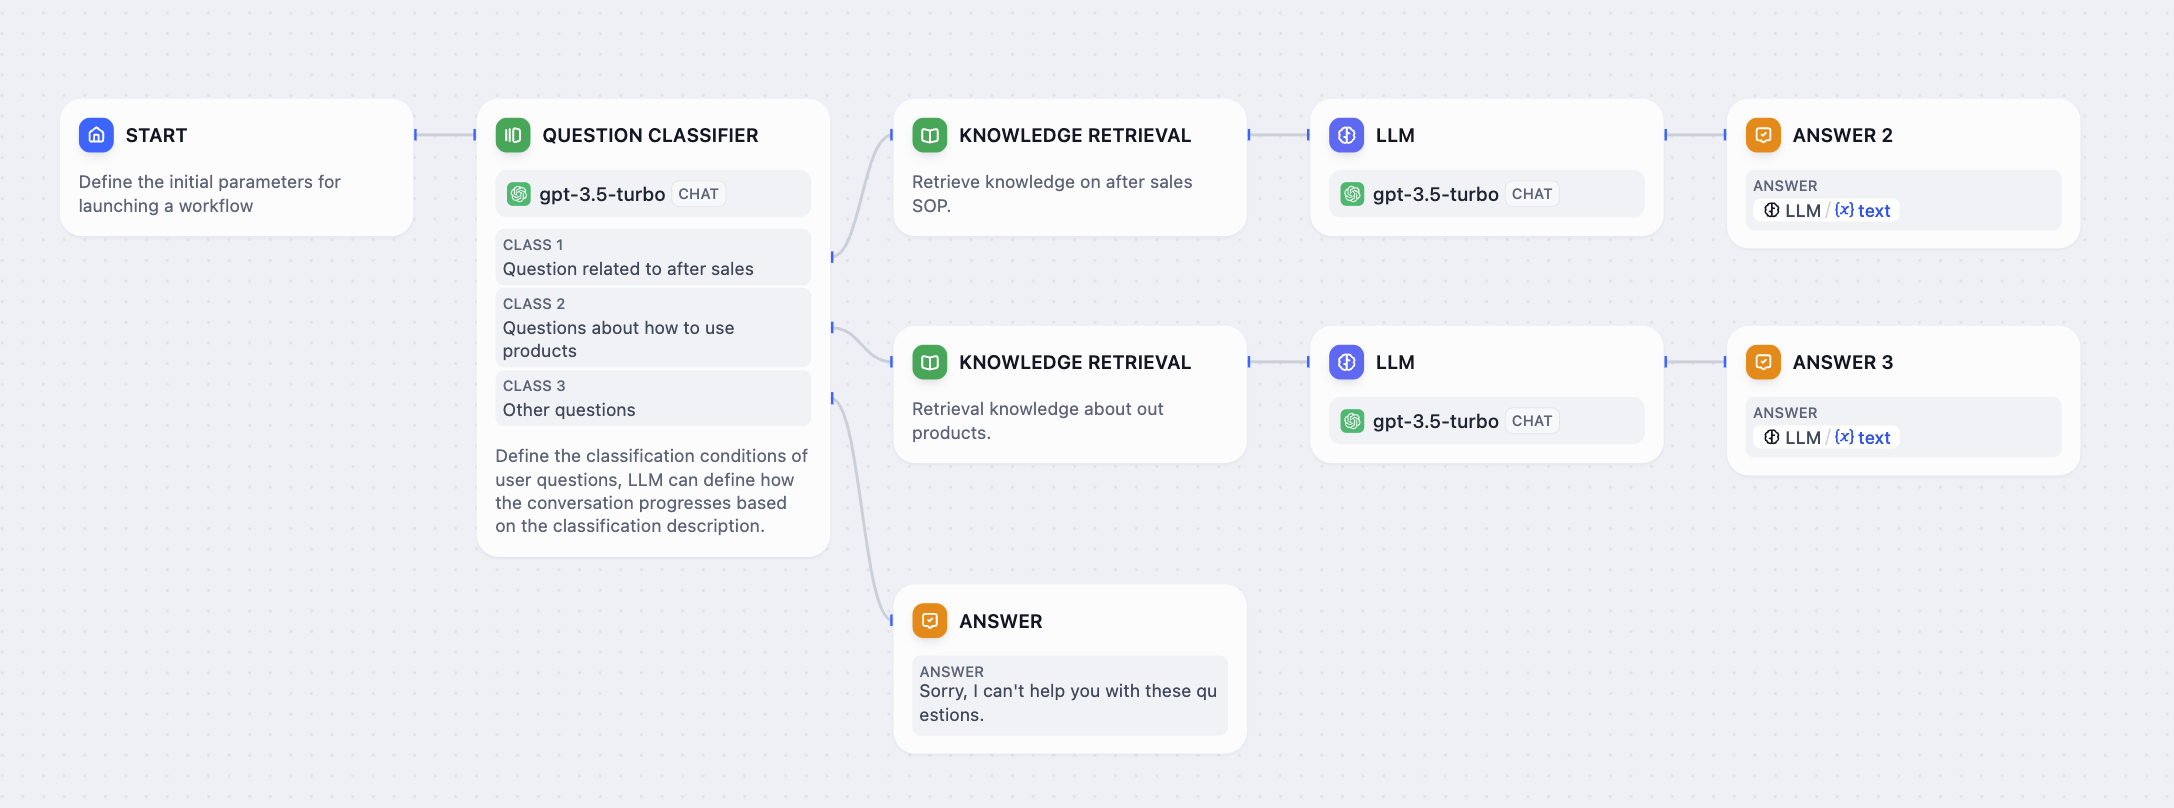
</Frame>
**Classes Defined**:
* **After-sales service** - Warranty claims, returns, repairs, and post-purchase support
* **Product usage** - Setup instructions, troubleshooting, feature explanations
* **Other questions** - General inquiries not covered by specific classes
**Classification Results**:
* "How to set up contacts on iPhone 14?" → **Product usage**
* "What is the warranty period for my purchase?" → **After-sales service**
* "What's the weather like today?" → **Other questions**
Each classification result routes to different knowledge bases and response strategies, ensuring users receive relevant, specialized assistance.
## Advanced Configuration
### Instructions and Guidelines
Add detailed classification guidelines in the **Instructions** field to handle edge cases, ambiguous scenarios, or specific business rules. This helps the LLM understand nuanced distinctions between classes.
# Start Node
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/start
Choose how your workflow begins, on demand or automatically
When you create a new workflow, you choose a start node that decides whether the workflow waits for someone to run it or runs on its own.
## User Input
Use [User Input](/en/self-host/use-dify/nodes/user-input) when someone (or an API call) should kick off the workflow and supply information it needs. You define input fields for text, numbers, files, and other data, and downstream nodes reference those values.
Only User Input workflows can be published as web apps, MCP servers, backend service APIs, or reused as tools in other Dify apps.
<Info>
Chatflows always start with User Input. Only Workflows can use triggers.
</Info>
## Trigger
Use a [trigger](/en/self-host/use-dify/nodes/trigger/overview) when the workflow should run automatically, without anyone invoking it. Three types are available:
* **[Schedule Trigger](/en/self-host/use-dify/nodes/trigger/schedule-trigger)**: runs at specified times or intervals.
* **[Integration Trigger](/en/self-host/use-dify/nodes/trigger/plugin-trigger)**: runs when an event occurs in an external system, via a subscription through a trigger integration.
* **[Webhook Trigger](/en/self-host/use-dify/nodes/trigger/webhook-trigger)**: runs when the workflow receives an HTTP request from an external system.
## Switch Between Start Nodes
User Input and triggers are mutually exclusive on a canvas. To switch, right-click the current start node and select **Change Node**, or delete it and add a new one.
# Template
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/template
Transform and format data using Jinja2 templating
The Template node transforms and formats data from multiple sources into structured text using Jinja2 templating. Use it to combine variables, format outputs, and prepare data for downstream nodes or end users.
<Frame>
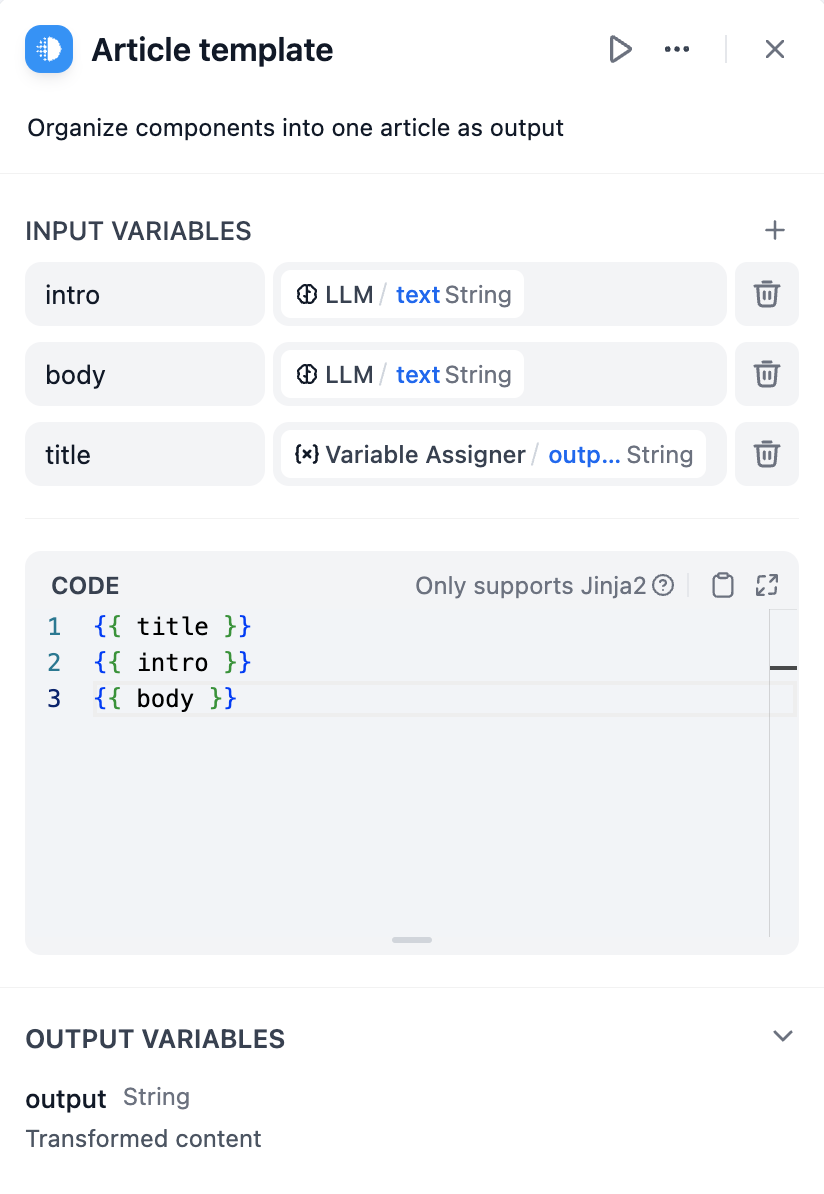
</Frame>
## Jinja2 Templating
Template nodes use Jinja2 templating syntax to create dynamic content that adapts based on workflow data. This provides programming-like capabilities including loops, conditionals, and filters for sophisticated text generation.
### Variable Substitution
Reference workflow variables using double curly braces: `{{ variable_name }}`. You can access nested object properties and array elements using dot notation and bracket syntax.
```jinja theme={null}
{{ user.name }}
{{ items[0].title }}
{{ data.metrics.score }}
```
### Conditional Logic
Show different content based on data values using if-else statements:
```jinja theme={null}
{% if user.subscription == 'premium' %}
Welcome back, Premium Member! You have access to all features.
{% else %}
Consider upgrading to Premium for additional capabilities.
{% endif %}
```
### Loops and Iteration
Process arrays and objects with for loops to generate repetitive content:
```jinja theme={null}
{% for item in search_results %}
### Result {{ loop.index }}
**Score**: {{ item.score | round(2) }}
{{ item.content }}
---
{% endfor %}
```
<Frame>
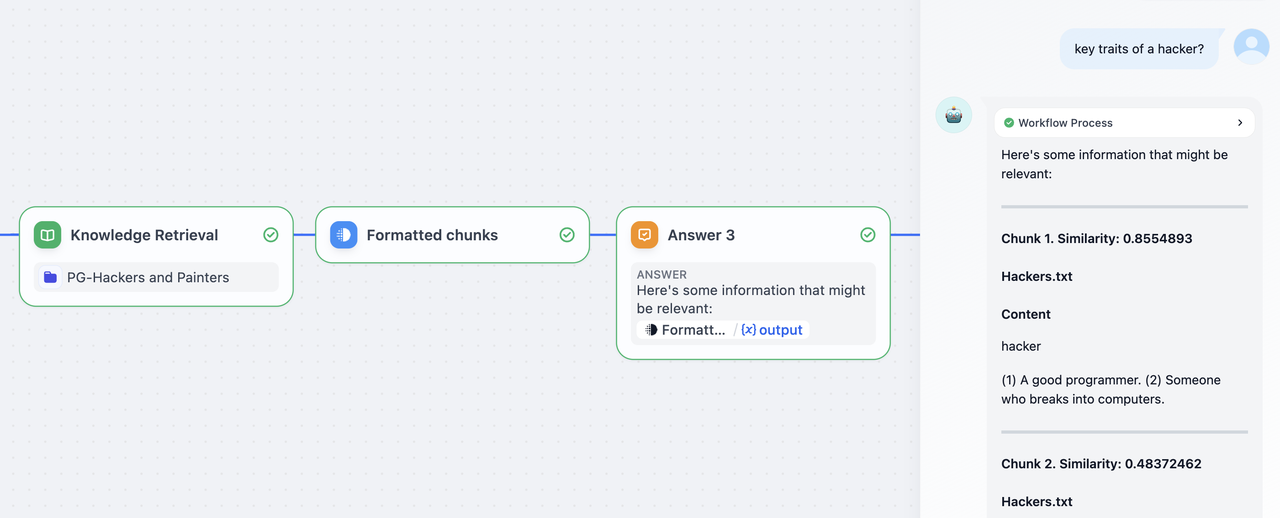
</Frame>
## Data Formatting
### Filters
Jinja2 filters transform data during template rendering:
```jinja theme={null}
{{ name | upper }}
{{ price | round(2) }}
{{ content | replace('\n', '<br>') }}
{{ tags | join(', ') }}
{{ score | default('No score available') }}
```
### Error Handling
Handle missing or invalid data gracefully using default values and conditional checks:
```jinja theme={null}
{{ user.email | default('No email provided') }}
{{ metrics.accuracy | round(2) if metrics.accuracy else 'Not calculated' }}
```
## Interactive Forms
Templates can generate interactive HTML forms for structured data collection in Chatflows.
On submit, the form values are sent to the chat as the end user's next message. The format depends on the `<form>`'s `data-format` attribute:
* **`data-format="json"`**: values are serialized as a JSON object. A downstream Code node or Parameter Extractor can `JSON.parse` it (or pattern-match it) to pull out each field.
* **Unset (or any other value)**: values are sent as plain text, one `name: value` per line. Easier for an LLM to read.
For example:
<Columns>
<Column>
```html theme={null}
<form data-format="json">
<label for="username">Username:</label>
<input type="text" name="username" placeholder="Please enter" />
<label for="password">Password:</label>
<input type="password" name="password" placeholder="Please enter" />
<label for="content">Content:</label>
<textarea name="content">
Date:
Time:
Datetime:
Select:
Login
```
### Supported Tags
| Tag
| Attributes | Notes |
| :------------- | :---------------------------------------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `` | `data-format` | Container for form fields.` | `for` | Renders the inner text as a field label.` before its field in the source so it appears above. |
| `` | `name`, `placeholder`, `value` | Multi-line text input. |
| `<button>` | `data-variant`, `data-size` | Submits the form. <ul><li>Variants: `primary`, `warning`, `secondary`, `secondary-accent`, `ghost`, `ghost-accent`, `tertiary`.</li><li>Sizes: `small`, `medium`, `large`.</li></ul>Values outside these lists are ignored and the button falls back to the default styling.<br /><br />Ignores `data-message` and `data-link`, which only apply to [quick-reply buttons](#quick-reply-buttons). |
<Note>
Do not leave blank lines between tags inside `<form>`. A blank line ends the HTML block during markdown parsing, and any tags after the break will fail to render as form fields.
</Note>
### Supported Input Types
| `type` value | Renders as | Submitted as |
| :------------------------------------ | :------------------------------------------------------------------- | :----------------------------------------------------------- |
| `text`, `password`, `email`, `number` | Single-line input with matching HTML semantics | String |
| `date` | Date picker | ISO date string (e.g., `2026-01-10`) |
| `datetime` | Date picker with time selection | ISO date-time string (e.g., `2026-01-10T14:30:00.000+08:00`) |
| `time` | Time picker | String (includes a full date prefix, not just the time) |
| `checkbox` | Checkbox followed by the `data-tip` text as a label | Boolean (`true` or `false`) |
| `select` | Dropdown built from the `data-options` JSON array of strings | Selected option string |
| `hidden` | Renders as an `<input type="hidden">` element; not visible in the UI | String |
* Any other `type` value renders an "Unsupported tag" fallback in place of the field.
* HTML5 validation attributes such as `required`, `min`, `max`, and `pattern` are not enforced.
* Browsers may autofill `<input type="password">` and `<input type="email">` with saved credentials for the current site; use `<input type="text">` for fields that should not be prefilled.
### Quick-Reply Buttons
A standalone `<button>` placed outside any `<form>` renders as a clickable button in the chat. Use these to offer canned responses or external links inline with the assistant's message. For example:
```html wrap theme={null}
Would you like to see more options?
<button data-variant="primary" data-message="Yes, show me more">Yes</button> <button data-variant="secondary" data-message="No, that is enough">No</button> <button data-variant="secondary-accent" data-link="https://docs.dify.ai">Read the docs</button>
```
<Frame>
<img alt="Quick Reply Button" />
</Frame>
| Attribute | Click behavior |
| :------------- | :-------------------------------------------------- |
| `data-message` | Sends the text as the end user's next chat message. |
| `data-link` | Opens the URL in a new tab. Must be a valid URL. |
If both are set, `data-link` takes precedence. A button with neither renders but performs no action when clicked.
Apply `data-variant` and `data-size` for styling, using the same values listed for [form buttons above](#supported-tags).
<Note>
Unlike form buttons, standalone buttons pass `data-variant` and `data-size` through to the underlying component without validation. An unrecognized value can leave the button rendered as plain text rather than a styled button.
Use only the values listed above.
</Note>
## Output Limits
Template output is limited to **400,000 characters** (configurable via `TEMPLATE_TRANSFORM_MAX_LENGTH`). This prevents memory issues and ensures reasonable processing times for large template outputs.
# Trigger
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/trigger/overview
<Info>
Triggers are available for Workflow applications only.
</Info>
A trigger is a type of Start node that lets your workflow run automatically on a schedule or in response to events from external systems (such as GitHub, Gmail, or your own internal systems), rather than waiting for active initiation from a user or an API call.
Use triggers to automate repetitive tasks or synchronize data with third-party applications.
A workflow can have multiple triggers running in parallel. You can also build several independent workflows on the same canvas, each starting with its own triggers.
The trigger source for each workflow execution is displayed in the **Logs** section.
## Trigger Types
* [Schedule Trigger](/en/self-host/use-dify/nodes/trigger/schedule-trigger)
* Runs your workflow at specified times or intervals.
* Example: Automatically generate a daily sales report every morning at 9 AM and email it to your team.
<Info>
Each workflow can have at most one schedule trigger.
</Info>
* [Integration Trigger](/en/self-host/use-dify/nodes/trigger/plugin-trigger)
* Runs your workflow when a specific event occurs in an external system, via an event subscription through a trigger integration.
* Example: Automatically analyze and archive new messages in a specific Slack channel via a subscription to the `New Message in Channel` event through a Slack trigger integration.
* [Webhook Trigger](/en/self-host/use-dify/nodes/trigger/webhook-trigger)
* Runs your workflow when a specific event occurs in an external system via a custom webhook.
* Example: Automatically process new orders in response to an HTTP request containing the order details from your e-commerce platform.
<Tip>
Both integration triggers and webhook triggers make your workflow *event-driven*. Here's how to choose:
1. Use an **integration trigger** when a trigger integration is available for your target external system. You can simply subscribe to the supported events.
2. Use a **webhook trigger** when no trigger integration exists or when you need to capture events not covered by available trigger integrations. In such cases, you'll need to set up custom webhooks in the external system.
</Tip>
## Enable or Disable Triggers
To pause a published trigger, open the app's **Access Point** tab and switch it off on the **Trigger** card. While a trigger is off, its events are ignored.
<Note>
Only published triggers appear on the **Trigger** card. If you don't see an added trigger listed, ensure it has been published first.
</Note>
## Test Multiple Triggers
When a workflow has multiple triggers, you can click **Test Run** > **Run all triggers** to test them at once. The first trigger that activates will initiate the workflow, and the others will then be ignored.
After you click **Run all triggers**:
* Schedule triggers will run at the next scheduled execution time.
* Integration triggers will listen for subscribed events.
* Webhook triggers will listen for external HTTP requests.
# Integration Trigger
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/trigger/plugin-trigger
<Info>
Triggers are available for Workflow applications only.
</Info>
An Integration Trigger starts your workflow automatically when a specific event occurs in an external system. You subscribe to those events through an integration, then add the matching trigger to your workflow.
For example, after installing a GitHub trigger integration, you can subscribe to events such as `Pull Request`, `Push`, and `Issue`. Subscribe to `Pull Request` and add its trigger, and the workflow runs whenever someone opens a pull request in the chosen repository.
## Add and Configure an Integration Trigger
1. On the workflow canvas, right-click and select **Add Node** > **Start**, then choose the integration trigger event you want to start the workflow. To find more integrations, search the [Marketplace](https://marketplace.dify.ai/?language=en-US\&category=trigger).
<Tip>
* If no integration exists for your target system, [request one](https://github.com/langgenius/dify-plugins/issues/new?template=plugin_request.yaml), [build one yourself](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin), or use a [Webhook Trigger](/en/self-host/use-dify/nodes/trigger/webhook-trigger) instead.
* A workflow can have multiple Integration Triggers. If their branches share downstream nodes, add a [Variable Aggregator](/en/self-host/use-dify/nodes/variable-aggregator) to converge them.
</Tip>
2. Select an existing subscription or [create a new one](/en/self-host/use-dify/nodes/trigger/plugin-trigger#create-a-subscription). The trigger needs a subscription to receive events.
3. Configure any other required settings.
<Info>
The output variables of an integration trigger are defined by the integration and can't be modified.
</Info>
## Create a Subscription
A subscription is a webhook that listens for events from an external system. Each integration supports up to 10 subscriptions per workspace.
<Accordion title="What is a webhook?">
A webhook lets one system send real-time data to another. When an event occurs, the source system packages the details into an HTTP request and sends it to a URL the destination system provides.
</Accordion>
<Note>
**Prerequisite: set the callback URL base**
Dify builds each subscription's callback URL from the `TRIGGER_URL` environment variable plus an integration-specific path. The default `http://localhost` is unreachable by external systems, so set `TRIGGER_URL` to a public domain or IP they can reach, then restart Dify before creating subscriptions.
</Note>
Dify supports two ways to create a subscription, depending on what the integration supports.
* **Automatic**: You pick the events to subscribe to, and Dify creates the webhook in the external system for you. This requires prior authorization, through OAuth or an API key, so Dify can set it up on your behalf.
* **Manual**: You create the webhook yourself using the callback URL Dify provides. No authorization needed.
<Tabs>
<Tab title="OAuth (Automatic)">
1. Select **Create with OAuth** > **Custom**.
2. In the external system, create an OAuth application using the callback URL Dify provides.
3. Back in Dify, enter the application's client ID and client secret, then click **Save and Authorize**.
<Info>Once saved, the same credentials can be reused for future subscriptions.</Info>
4. Name the subscription, select the events to subscribe to, and configure any other required settings.
<Tip>
Subscribe to all available events. A trigger only fires for events its subscription covers, so a broad subscription can be reused by any trigger you add later instead of creating new ones.
</Tip>
5. Click **Create**.
</Tab>
<Tab title="API Key (Automatic)">
1. Select **Create with API Key**.
2. Enter the required authentication details, then click **Verify**.
3. Name the subscription, select the events to subscribe to, and configure any other required settings.
<Tip>
Subscribe to all available events. A trigger only fires for events its subscription covers, so a broad subscription can be reused by any trigger you add later instead of creating new ones.
</Tip>
4. Click **Create**.
</Tab>
<Tab title="Paste URL to create a new subscription (Manual)">
1. Select **Paste URL to create a new subscription**.
2. Name the subscription and use the callback URL Dify provides to create a webhook in the external system.
3. (Optional) Test it: trigger a subscribed event, then check the **Request Logs** at the bottom of the **Manual Setup** page for the received request and Dify's response.
<Frame>
<img alt="Request Logs" />
</Frame>
4. Click **Create**.
</Tab>
</Tabs>
## Manage Subscriptions
Manage an integration's subscriptions from **Integrations** > **Trigger**. Open the integration to see its subscriptions, including how many workflows use each one, and to edit or delete them.
## Test an Integration Trigger
To test an unpublished trigger, first click **Run this step** or test-run the whole workflow. This puts the trigger into a listening state so it can capture subscribed events; otherwise events are ignored even when they occur.
# Schedule Trigger
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/trigger/schedule-trigger
<Info>
* Triggers are available for Workflow applications only.
* Each workflow can have at most one schedule trigger.
</Info>
Schedule triggers enable your workflow to run at specified times or intervals. They are ideal for recurring tasks like generating daily reports or sending scheduled notifications.
## Add a Schedule Trigger
On the workflow canvas, right-click and select **Add Node** > **Start** > **Schedule Trigger**.
## Configure a Schedule Trigger
You can configure the schedule using either the default visual picker or a cron expression.
After configuration, you can see the next 5 scheduled execution times.
<Info>
Schedule triggers do not produce output variables, but they update the system variable `sys.timestamp` (the start time of each workflow execution) each time they initiate the workflow.
</Info>
### With the Visual Picker
Use this for simple hourly, daily, weekly, or monthly schedules. For weekly and monthly frequencies, you can select multiple days or dates.
### With a Cron Expression
Use this for more complex and precise timing patterns, such as every 15 minutes from 9 AM to 5 PM on weekdays.
<Tip>
You can use LLMs to generate cron expressions.
</Tip>
#### Standard Format
A cron expression is a string that defines the schedule for executing your workflow. It consists of five fields separated by spaces, each representing a different time unit.
<Note>
Ensure that there is a single space between each field.
</Note>
```
* * * * *
| | | | |
| | | | |── Day of week (0-7 or SUN-SAT, where both 0 and 7 = Sunday)
| | | |──── Month (1-12 or JAN-DEC)
| | |────── Day of month (1-31)
| |──────── Hour (0-23)
|────────── Minute (0-59)
```
<Info>
When both the **day-of-month** and **day-of-week** fields are specified, the trigger activates on dates that match *either* field.
For example, `1 2 3 4 4` will trigger your workflow on the 3rd of April *and* every Thursday in April, not just on Thursdays that fall on the 3rd.
</Info>
#### Special Characters
| Character | Description | Example |
| :-------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `*` | Means "every". | `*` in the **hour** field means "every hour". |
| `,` | Separates multiple values. | `1,3,5` in the **day-of-week** field means "Monday, Wednesday, and Friday". |
| `-` | Defines a range of values. | `9-17` in the **hour** field means "from 9 AM to 5 PM". |
| `/` | Specifies step values. | `*/15` in the **minute** field means "every 15 minutes". |
| `L` | Means "the last". <br /><br />In the **day-of-month** field, means "the last day of the month".<br /><br />In the **day-of-week** field:<ul><li>When used alone, means "the last day of the week".</li><li>When combined with a number, means "the last occurrence of that weekday in the month". </li></ul> | `L` in the **day-of-month** field means "Jan 31, April 30, or Feb 28 in a non-leap year".<br /><br />`L` in the **day-of-week** field means Sunday.<br /><br />`5L` in the **day-of-week** field means "the last Friday of the month". |
| `?` | Means "any" or "no specific value".<br /><br />If you specify a value for the **day-of-week** field, you can use `?` for the **day-of-month** field to ignore it, and vice versa.<br /><br />Not required, because `*` works as well. | To run a task every Monday, it's more precise to set the **day-of-month** field to `?` instead of `*`. |
#### Predefined Expressions
* `@yearly`: Run once a year at 12 AM on January 1.
* `@monthly`: Run once a month at 12 AM on the first day of the month.
* `@weekly`: Run once a week at 12 AM on Sunday.
* `@daily`: Run once a day at 12 AM.
* `@hourly`: Run at the beginning of every hour.
#### Examples
| Schedule | Cron Expression |
| :-------------------------------------- | :--------------------------------- |
| Weekdays at 9 AM | `0 9 * * MON-FRI` or `0 9 * * 1-5` |
| Every Wednesday at 2:30 PM | `30 14 * * WED` |
| Every Sunday at 12 AM | `0 0 * * 0` |
| Every 2 hours on Tuesday | `0 */2 * * 2` |
| The first day of every month at 12 AM | `0 0 1 * *` |
| At 12 PM on January 1 and June 1 | `0 12 1 JAN,JUN *` |
| The last day of every month at 5 PM | `0 17 L * *` |
| The last Friday of every month at 10 PM | `0 22 * * 5L` |
## Test a Schedule Trigger
* **Run this step**: The schedule trigger runs immediately, ignoring the configured schedule.
* **Test Run**: The schedule trigger waits for its next scheduled execution time.
# Webhook Trigger
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/trigger/webhook-trigger
<Info>
Triggers are available for Workflow applications only.
</Info>
A webhook allows one system to automatically send real-time data to another. When a certain event occurs, the source system packages the event details into an HTTP request and sends it to a designated URL provided by the destination system.
Following the same mechanism, webhook triggers enable your workflow to run in response to third-party events. Here's how you work with it:
1. When you add a webhook trigger to your workflow, Dify generates a unique webhook URL that listens for external HTTP requests.
<Info>
Set the `TRIGGER_URL` environment variable (default `http://localhost`) to the base prefix you want this URL to use. Point it to a public domain or IP address reachable by the external systems that will call the webhook.
</Info>
2. You use this URL to create a webhook subscribing to the events you want to monitor in an external system. Then you configure the webhook trigger to define how it processes incoming requests and extracts request data.
<Note>
For testing purposes, always use the test webhook URL to keep test data separate from production data.
<Frame>
<img alt="Test Webhook URL" />
</Frame>
</Note>
3. When a subscribed event occurs, the external system sends an HTTP request with the event data to that provided webhook URL. Once the request is received and processed successfully, your workflow is triggered, and the specified event data is extracted into variables that can be referenced by downstream nodes.
<Tip>
If there's a ready-made trigger integration for your target external system, consider using an [Integration Trigger](/en/self-host/use-dify/nodes/trigger/plugin-trigger) instead.
</Tip>
## Add a Webhook Trigger
On the workflow canvas, right-click and select **Add Node** > **Start** > **Webhook Trigger**.
<Tip>
A workflow can have multiple webhook triggers. If these trigger branches share identical downstream nodes, add a [Variable Aggregator](/en/self-host/use-dify/nodes/variable-aggregator) to converge them and avoid duplicating those nodes on each branch.
</Tip>
## Configure a Webhook Trigger
You can define how a webhook trigger handles incoming HTTP requests, including:
* The expected HTTP method for the webhook URL
* The request's content-type
* The data you wish to extract from the request
* The response sent back to the external system when your workflow is successfully triggered
<Note>
To test an unpublished webhook trigger, make sure to click **Run this step** or test-run the entire workflow first. This puts the trigger into a listening state so that it can receive external requests. Otherwise, no request will be captured.
</Note>
### HTTP Method
To ensure the incoming request can be received successfully, you need to specify which HTTP method the webhook URL accepts.
The method you select here must match the one used by the external system to send requests; otherwise, the requests will be rejected.
<Tip>
You can typically find this information in the external system's webhook documentation or setup interface.
</Tip>
### Content-Type
To ensure the request body can be properly parsed and the data you need extracted, you need to specify the expected content type of the incoming request.
The content-type you select here must match the content type of the request sent from the external system; otherwise, the request will be rejected.
### Query Parameters, Header Parameters, and Request Body Parameters
You can extract specific data from the query parameters, headers, and body of the incoming request. **Each extracted parameter becomes an output variable that can be used in your workflow.**
Some external systems provide a delivery log for each request, where you can view all the data included in the request and decide which parameters to extract.
Alternatively, you can send a test request to the webhook trigger and check the received request data in its last run logs:
1. Create a webhook in the external system using the provided test webhook URL.
2. Set the correct HTTP method and content-type in the trigger.
3. Click the **Run this step** icon. The trigger will start listening for external requests.
4. Trigger the subscribed event in the external system so it sends an HTTP request to the provided webhook URL.
5. Go to the trigger's **Last Run** tab and check the received request data in **Input**.
<Note>
The variable name you define in the trigger must match the key name of the corresponding parameter in the request.
</Note>
<Tabs>
<Tab title="Query Parameters">
* Parameters in key-value pairs added to the webhook URL (after `?`) by external systems when sending requests, each pair separated by `&`.
* Typically simple, non-sensitive identifiers or filter data about the event.
* Example: From the URL `{webhook url}?userID=u-456&source=email`, you can extract the `userID` (`u-456`) or the `source` (`email`).
</Tab>
<Tab title="Header Parameters">
* Request metadata included in the request headers.
* Technical information needed for processing the request, such as an authentication token or the request body's data format.
* Example: From headers like `Authorization: Bearer sk-abc... `and `Content-Type: application/json`, you can extract the authorization information (`Bearer sk-abc...`) or the content-type (`application/json`).
</Tab>
<Tab title="Request Body Parameters">
* The main payload where the core event data is sent, such as a customer profile, order details, or the content of a Slack message.
* Example: From the following request body, you can extract the `customerName` (`Alex`), the list of items, or the `isPriority` status (`true`).
```json theme={null}
"customerName": "Alex",
"items":
[
{ "sku": "A42", "quantity": 2 },
{ "sku": "B12", "quantity": 1 }
],
"isPriority": true
```
<Info>
The content-type determines which data types can be extracted from the request body.
| Content-Type | `String` | `Number` | `Boolean` | `Object` | `File` | `Array[String]` | `Array[Number]` | `Array[Boolean]` | `Array[Object]` | `Array[File]` |
| :-------------------------------- | :------: | :------: | :-------: | :------: | :----: | :-------------: | :-------------: | :--------------: | :-------------: | :-----------: |
| application/json | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ |
| application/x-www-form-urlencoded | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ | ❌ | ❌ |
| multipart/form-data | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ |
| text/plain | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
</Info>
</Tab>
</Tabs>
**Parameter Settings**
For each parameter to be extracted, you can specify the following:
* **Variable Name**: The key name of the parameter in the incoming request (e.g., `userID` in `userID=u-456`).
<Note>
For header parameters, any hyphen (`-`) in the variable name will be automatically converted to an underscore (`_`) in the output variable.
</Note>
* **Data Type**: The expected data format. Available for query and request body parameters only, as header parameters are always treated as strings.
* **Required**: Whether the parameter is required for your workflow to execute properly. If any required parameter is missing from an incoming request, your workflow will not be triggered.
### Response
When your workflow is successfully triggered by an external HTTP request, a default `200 OK` response is sent back to the external system.
If the external system requires a specific success response format, you can customize the status code and response body. The default one will be overridden.
* **Status Code**: Supports any status code in the range \[200, 399].
* **Response Body**: Supports JSON or plain text.
<Note>
In the returned response body, non-JSON content will be automatically converted to JSON.
For example, `OK` will be wrapped as `"message": "OK"`.
</Note>
<Info>
The following error responses are system-defined and cannot be customized. Error details can be found in the response body.
* 400 Bad Request
* 404 Not Found
* 413 Payload Too Large
* 500 Internal Server Error
</Info>
## Test a Webhook Trigger
To test an unpublished webhook trigger, you must first click **Run this step** or test-run the entire workflow. This puts the trigger into a listening state so that it can receive external requests. Otherwise, incoming requests will not be captured.
# User Input
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/user-input
Collects user inputs to start Workflow and Chatflow applications
The User Input node allows you to define what to collect from end users as inputs for your applications.
Applications that start with this node run *on demand* and can be initiated by direct user interaction or API calls.
You can also publish these applications as standalone web apps or MCP servers, expose them through backend service APIs, or use them as tools in other Dify applications.
<Info>
Each application canvas can contain only one User Input node.
</Info>
## Input Variable
### Preset
Preset input variables are system-defined and available by default.
* `userinput.files`: Files uploaded by end users when they run the application.
<Note>
For Workflow applications, this preset variable has been considered *legacy* and kept only for backward compatibility.
We recommend using a [custom file input field](#file-input) instead to collect user files.
</Note>
* `userinput.query` (for chatflows only): The text message automatically captured from the user's latest chat turn.
### Custom
You can configure custom input fields in a User Input node to collect different kinds of user input. Each field becomes a variable that can be referenced by downstream nodes.
<Info>
**Label Name** is displayed to your end users.
</Info>
<Tip>
If a field's value is something you already know (like a product identifier or tenant ID) and doesn't have to come from end users, mark it as **Hidden & Pre-Filled** and supply it yourself. See [Hide and Pre-Fill Input Fields](#hide-and-pre-fill-input-fields) for details.
</Tip>
#### Text Input
<Tabs>
<Tab title="Short Text">
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
</Tab>
<Tab title="Paragraph">
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed responses or descriptions.
</Tab>
</Tabs>
#### Structured Input
<Tabs>
<Tab title="Select">
Displays a dropdown menu with predefined options. Users can choose only from listed options, ensuring data consistency and preventing invalid inputs.
</Tab>
<Tab title="Number">
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
</Tab>
<Tab title="Checkbox">
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
</Tab>
<Tab title="JSON Code">
Accepts data in JSON object format, ideal for passing complex, nested data structures into your application.
You can optionally define a JSON schema to validate the input and guide end users on the expected structure and validation requirements. This also allows you to reference individual properties of the object in other nodes.
</Tab>
</Tabs>
#### File Input
<Tabs>
<Tab title="Single File">
Allows users to upload one file of any supported type, either from their device or via a file URL. The uploaded file is available as a variable containing file metadata (name, size, type, etc.).
</Tab>
<Tab title="File List">
Supports multiple file uploads at once. It's useful for handling batches of documents, images, or other files together.
<Tip>
Use a List Operator node to filter, sort, or extract specific files from the uploaded file list for further processing.
</Tip>
</Tab>
</Tabs>
**File Processing**
Since the User Input node only collects files—it does not read or parse their content—uploaded files must be processed appropriately by subsequent nodes. For example:
* Document files can be routed to a Doc Extractor node for text extraction so that LLMs can understand their content.
* Images can be sent to LLM nodes with vision capabilities or specialized image processing tool nodes.
* Structured data files such as CSV or JSON can be processed with Code nodes to parse and transform the data.
<Tip>
When users upload multiple files with mixed types (e.g., images and documents), you can use a List Operator node to separate them by file type before routing them to different processing branches.
</Tip>
## Hide and Pre-Fill Input Fields
Sometimes the workflow needs an input you already know, and asking end users to type it would be friction. Mark such a field as **Hidden & Pre-Filled**: you supply the value, end users never see the field, and the workflow still receives it.
Imagine your company runs landing pages for many different products, each featuring an AI chatbot. The workflow behind every chatbot is essentially the same; only the product identifier differs.
Rather than maintain a separate workflow per product, you keep just one (with a hidden `productName` field) and pre-fill a different value on each landing page. End users perceive each page as having its own product-specific chatbot, but behind the scenes, every page passes a different `productName` into the same workflow.
<Warning>
Hidden fields are **not secret**. Values travel in the URL query string and are visible in the browser address bar, browser history, and network traffic. For credentials and API keys, use [Environment Variables](/en/learn/key-concepts#variables) instead.
</Warning>
<Info>
Single File and File List fields do not support this feature.
</Info>
<Steps>
<Step title="Enable the Feature">
1. In the **Edit Input Field** window, uncheck **Required** if it's checked. These two options are mutually exclusive.
2. Check **Hidden & Pre-Filled**. Optionally set a default value as a fallback when no value is pre-filled at runtime.
Hidden fields still appear in the **Preview** panel so you can test the flow without publishing.
</Step>
<Step title="Pre-Fill the Field">
1. **Publish your app**.
2. Choose the method that fits how your end users reach the app.
<Tabs>
<Tab title="Shareable Link">
Use this when end users open the web app directly from its link.
1. On the app's **Access Point** tab, click **Configure** on the **Web App** card.
2. Fill in the hidden fields and click **Launch**. The web app opens with your values applied as URL query parameters.
3. Copy the URL from the address bar to share the web app.
**To generate many links with different values**, use the same pattern to write more yourself, or have a system fill in the values automatically:
```text wrap theme={null}
{WEBAPP_URL}?{VARIABLE_NAME}={VALUE}&{VARIABLE_NAME}={VALUE}
# Example: {WEBAPP_URL}/chat/abc123?productName=Acme®ion=us-east
```
<Note>
URL-encode any values that contain spaces or special characters (for example, `Acme Corp` becomes `Acme%20Corp`).
</Note>
<Accordion title="Example: A CRM Auto-Fills the Customer ID">
A support team using a CRM can add `?customerId={{customer.id}}` to the end of the web app URL in their ticket-response templates.
The CRM substitutes the real customer ID when the rep sends the link, so the chatbot knows which customer it's talking to without having to ask.
</Accordion>
</Tab>
<Tab title="Embed on Your Site">
Use this when the app is embedded as an iframe or script on your site.
<Tabs>
<Tab title="Same Value for Every Visitor">
Use this when every visitor should receive the same values (a site-wide region, the embedded page's product ID, etc.).
1. On the app's **Access Point** tab, click **Embed Into Site** > **Pre-Fill Hidden Fields** on the **Web App** card.
2. Fill in the hidden fields. Entered values are baked into the iframe URL and the `inputs` object of the script snippet.
</Tab>
<Tab title="Different Value Per Visitor">
Use this when each visitor should receive their own values (the logged-in user's ID, the page they're on, etc.).
In the embed snippet on your site, set each hidden field as a key in the `inputs` object of `window.difyChatbotConfig`. Each value is computed at render time from your site's context, so every visitor gets their own.
```html theme={null}
<script>
window.difyChatbotConfig = {
token: 'YOUR_TOKEN',
inputs: {
productName: getCurrentProduct(), // from the current page
tenantId: getCurrentTenant(), // from your auth system
},
};
</script>
```
</Tab>
</Tabs>
</Tab>
</Tabs>
</Step>
</Steps>
# Agent API
Source: https://docs.dify.ai/en/api-reference/guides/agent
API for Agent apps, covering streaming chat messages, conversation management, file uploads, and app configuration
<Info>
Agent here means the new Agent app type (`agent` mode). The Legacy Agent app (`agent-chat`) is covered on [Chatbot and Legacy Agent](/en/api-reference/guides/chat).
</Info>
[Agent apps](/en/self-host/use-dify/build/new-agent/overview) run in `agent` mode: you send a message, stream the reply as it generates, and keep multi-turn context in conversations.
The model reasons and calls tools autonomously, and the stream shows that work: the reply text streams incrementally as `agent_message` events, with `agent_thought` events carrying each reasoning step and tool call alongside.
The turn closes with a single `message` event carrying the complete answer, then `message_end`. Render the `agent_message` deltas live and treat the closing `message` as the final answer rather than appending it.
Each `agent_thought` event carries the step's `thought`, the `tool` it called with its `tool_input`, and the tool's `observation`. The full stream shape is on [Send Chat Message](/en/api-reference/chat-messages/send-chat-message).
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Agent app. Streaming mode only; blocking mode returns a 400 `bad_request` error.
Reply text streams as `agent_message` deltas, batched at roughly half-second intervals rather than token by token.
The closing `message_end` event reports token usage. It never includes knowledge-retrieval citations (`retriever_resources`).
Two limits end a run early, and either one closes the stream with the `agent_run_limit_exceeded` error code:
* **Time**: a run is stopped after 1 hour by default.
For longer runs on self-hosted deployments, raise `APP_MAX_EXECUTION_TIME`, `WORKFLOW_MAX_EXECUTION_TIME`, and `DIFY_AGENT_RUN_TIMEOUT_SECONDS` above the duration you need. See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
* **Model requests**: each run is capped at 500.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI. Each message's `agent_thoughts` array carries the reasoning steps for that turn.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set a conversation's name, or have one generated from its content.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation and its messages.
## Upload Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file, scoped to the uploading end user.
Files passed to [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) are surfaced to the agent as downloadable references it can fetch and inspect in its sandbox.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: app metadata; the `tool_icons` map is empty for Agent apps.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
# Chat App API
Source: https://docs.dify.ai/en/api-reference/guides/chat
API for Chatbot and Legacy Agent apps, covering chat messages, conversation management, file uploads, voice, and annotations
[Chatbot apps](/en/cloud/use-dify/build/chatbot) (`chat` mode) and [Legacy Agent apps](/en/cloud/use-dify/build/agent) (`agent-chat` mode) share the same endpoints to send messages, manage conversations, handle files, and retrieve app settings. Only the streamed reply differs: Chatbot apps stream the reply as `message` events, while Legacy Agent apps stream `agent_thought` and `agent_message` events.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Chatbot or Legacy Agent app. Blocking mode returns the full reply once it finishes; Legacy Agent apps support streaming mode only.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
Conversations created through the API stay isolated from conversations started in the app's web app.
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set or auto-generate a display name.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation.
* **[List Conversation Variables](/en/api-reference/conversations/list-conversation-variables)**: read the values the session persists across turns.
* **[Update Conversation Variable](/en/api-reference/conversations/update-conversation-variable)**: change one of those values directly.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a reply as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
## Manage Annotations
Annotations pair a question with a fixed answer that the app returns directly instead of generating a new response:
* **[Create Annotation](/en/api-reference/annotations/create-annotation)**, **[List Annotations](/en/api-reference/annotations/list-annotations)**, **[Update Annotation](/en/api-reference/annotations/update-annotation)**, **[Delete Annotation](/en/api-reference/annotations/delete-annotation)**: manage the annotation set.
* **[Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply)**: turn annotation matching on or off. The change runs asynchronously.
* **[Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status)**: poll with the returned job ID to confirm the change finished.
# Chatflow App API
Source: https://docs.dify.ai/en/api-reference/guides/chatflow
API for Chatflow apps, covering chat messages, workflow-level streaming, conversation management, and Human Input pauses
[Chatflow apps](/en/cloud/use-dify/build/workflow-chatflow) run in `advanced-chat` mode, streaming workflow-level events (node starts, finishes, iterations, and pauses) alongside the reply. Previous turns persist as context, so later messages can reference earlier ones.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Send Messages and Stream Replies
* **[Send Chat Message](/en/api-reference/chat-messages/send-chat-message)**: send a query to your Chatflow app. Streaming mode carries workflow and node events alongside the answer text; blocking mode returns once the run finishes.
* **[Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation)**: interrupt a streaming reply before it finishes.
* **[Get Next Suggested Questions](/en/api-reference/chat-messages/get-next-suggested-questions)**: propose follow-up questions after a reply completes, based on the conversation so far.
## Manage Conversations
* **[List Conversations](/en/api-reference/conversations/list-conversations)**: the current user's conversations, ordered by most recent activity.
* **[List Conversation Messages](/en/api-reference/conversations/list-conversation-messages)**: one conversation's message history, for a scrolling chat UI.
* **[Rename Conversation](/en/api-reference/conversations/rename-conversation)**: set or auto-generate a display name.
* **[Delete Conversation](/en/api-reference/conversations/delete-conversation)**: remove a conversation.
* **[List Conversation Variables](/en/api-reference/conversations/list-conversation-variables)**: read the values the session persists across turns.
* **[Update Conversation Variable](/en/api-reference/conversations/update-conversation-variable)**: change one of those values directly.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a reply back into speech.
## Pause for Human Input
When a run reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input) whose delivery method is web app, complete the pause over the API:
<Steps>
<Step title="Listen for the pause">
The event stream emits `human_input_required` carrying a `form_token` and the run's `workflow_run_id`, then ends with the `workflow_paused` event.
</Step>
<Step title="Fetch the form">
Load the form's contents with [Get Human Input Form](/en/api-reference/human-input/get-human-input-form), using the `form_token`.
</Step>
<Step title="Submit the response">
Send the recipient's input with [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form). Submitting resumes the run.
</Step>
<Step title="Resume the stream">
Open a new stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), using the `workflow_run_id` from the paused stream, and follow the remaining events through the final answer.
</Step>
</Steps>
For file-attached submissions and the full event sequence, see the [Human Input Flow](/en/api-reference/guides/human-input-flow) guide.
## Inspect Workflow Runs
* **[Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail)**: a run's status and outputs, by the `workflow_run_id` that appears in the workflow and node events streamed alongside a chat reply.
* **[List Workflow Logs](/en/api-reference/workflow-runs/list-workflow-logs)**: run-level summaries covering status, token usage, step count, and timing, rather than a node-by-node execution log.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback and Annotations
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a reply as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
Annotations pair a question with a fixed answer that the app returns directly instead of generating a new response:
* **[Create Annotation](/en/api-reference/annotations/create-annotation)**, **[List Annotations](/en/api-reference/annotations/list-annotations)**, **[Update Annotation](/en/api-reference/annotations/update-annotation)**, **[Delete Annotation](/en/api-reference/annotations/delete-annotation)**: manage the annotation set.
* **[Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply)**: turn annotation matching on or off. The change runs asynchronously.
* **[Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status)**: poll with the returned job ID to confirm the change finished.
# Completion App API
Source: https://docs.dify.ai/en/api-reference/guides/completion
API for Text Generator apps, covering completion messages, file uploads, voice, and feedback
[Text Generator apps](/en/cloud/use-dify/build/text-generator) run in `completion` mode: each call submits its own input values and returns one response, with no conversation state carried between calls.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Generate Text
* **[Send Completion Message](/en/api-reference/completion-messages/send-completion-message)**: send `inputs` to fill the app's prompt template and generate a response. Blocking mode returns the full response once it finishes; streaming mode delivers `message` events ending in `message_end`, plus `tts_message` events when the app has text-to-speech auto-play enabled.
* **[Stop Completion Message Generation](/en/api-reference/completion-messages/stop-completion-message-generation)**: interrupt a streaming response before it finishes.
## Handle Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file for [Send Completion Message](/en/api-reference/completion-messages/send-completion-message) to reference. Files are scoped to the uploading end user.
* **[Download File](/en/api-reference/files/download-file)**: preview or download an uploaded file, as long as it belongs to a message in your app.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak their input instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize the generated response back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
## Collect Feedback
* **[Submit Message Feedback](/en/api-reference/feedback/submit-message-feedback)**: end users rate a response as `like` or `dislike`, with an optional text comment.
* **[List App Feedbacks](/en/api-reference/feedback/list-app-feedbacks)**: every feedback submitted across the app, from both end users and admins.
# End User Identity
Source: https://docs.dify.ai/en/api-reference/guides/end-user-identity
What the user field identifies, what it scopes, and why it must stay consistent across calls
Most app endpoints take a `user` field: your own identifier for the end user a call acts on behalf of. Dify never authenticates it, so pick a stable value per person, such as an account ID, and send it consistently.
Dify starts tracking a new `user` the first time it appears, and one app key serves any number of end users.
## What `user` Scopes
`user` controls what each call can see and do:
* **Conversations**: listing, history, renaming, and deletion all operate on that user's conversations only.
* **Files**: an upload belongs to the uploading user, and referencing it under a different `user` fails.
* **Stopping generation**: the chat-family stop endpoints act only when `user` matches the one that started the reply. A mismatch is silently ignored—the call succeeds either way, so it isn't detectable from the response.
Workflow's Stop Workflow Task does not check `user`.
* **Resuming runs**: [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) returns a 404 when `user` doesn't match the run's creator.
Keep one `user` per person across every call in a flow—upload, send, stop, and resume all check it.
## API Users and Web App Users Stay Separate
Traffic through the API and Dify's hosted web app keep separate identities: conversations your API users create never appear in the web app, and web app conversations never appear through the API.
## Resolve an End-User ID
Some responses carry an end-user ID instead of full details, such as `created_by` in the Upload File response. [Get End User Info](/en/api-reference/end-users/get-end-user-info) resolves it.
# Get Started with the Dify API
Source: https://docs.dify.ai/en/api-reference/guides/get-started
Get an API key, make your first call, and find the endpoints for your app type
Every app you publish in Dify doubles as a REST API, and so do your knowledge bases. You call the same app your end users interact with, from your own backend, with an API key.
## Get an API Key
<Warning>
Call the API from your backend only. A key embedded in frontend code or a client app can be extracted and abused.
</Warning>
* For an app, create an API key from inside the app itself. The key is scoped to that one app, and one key serves all your end users.
<Info>
Your calls tell people apart with a per-person `user` value. See [End User Identity](/en/api-reference/guides/end-user-identity) for details.
</Info>
* For knowledge bases, go to **Knowledge** and click **Service API** in the top-right corner.
A knowledge API key is broader: it can reach every knowledge base visible to the account that created the key, so treat it with extra care. See [Knowledge API](/en/api-reference/guides/knowledge) for details.
## Make Your First Call
Every request carries the key as a Bearer token. For Dify Cloud, the base URL is `https://api.dify.ai/v1`; for self-hosted deployments, use your own instance's API base URL.
The fastest first call needs no code: open [Get App Info](/en/api-reference/applications/get-app-info), click **Try it**, paste your key into the **Authorization** field, and press **Send**. It works for every app type.
The same call from a terminal:
```bash theme={null}
curl https://api.dify.ai/v1/info \
-H "Authorization: Bearer $DIFY_API_KEY"
```
A response like this confirms the key works and shows which app it belongs to:
```json theme={null}
{
"name": "My Chat App",
"description": "A helpful assistant",
"tags": ["assistant"],
"mode": "chat",
"author_name": "Dify Team"
}
```
Using a knowledge API key? Its endpoints are a separate family: start with [List Knowledge Bases](/en/api-reference/knowledge-bases/list-knowledge-bases) instead.
## Find Your App Type's Endpoints
See each app type's own overview page for its full API surface:
* [Chatflow](/en/api-reference/guides/chatflow) (`advanced-chat`)
* [Workflow](/en/api-reference/guides/workflow) (`workflow`)
* [Agent](/en/api-reference/guides/agent) (`agent`)
* [Chatbot and Legacy Agent](/en/api-reference/guides/chat) (`chat`, `agent-chat`)
* [Text Generator](/en/api-reference/guides/completion) (`completion`)
* [Knowledge](/en/api-reference/guides/knowledge)
# Human Input API Integration Flow
Source: https://docs.dify.ai/en/api-reference/guides/human-input-flow
End-to-end sequence for handling a paused Human Input form via the API
When a workflow reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input), it pauses and emits a `human_input_required` event in the streaming response. The event carries a `form_token` that your integration uses to drive the form lifecycle until the workflow resumes.
For per-endpoint reference, see the [Human Input API](/en/api-reference/human-input/get-human-input-form).
## Steps
The sequence below applies to both Workflow and Chatflow apps. Only the entry endpoint in Step 1 differs between the two.
<Steps>
<Step title="Start the app in streaming mode">
1. Call [Run Workflow](/en/api-reference/workflow-runs/run-workflow) (Workflow apps) or [Send Chat Message](/en/api-reference/chat-messages/send-chat-message) (Chatflow apps), passing your end user's `user` identifier.
2. Watch the SSE stream for the `human_input_required` event and capture its `form_token`.
If `form_token` is `null`, the form uses Email delivery and can't be driven via the API (see [Delivery Method Requirement](#delivery-method-requirement)).
The `human_input_required` event also carries the run's `workflow_run_id`; keep it in case you need to resume listening in Step 5.
</Step>
<Step title="Get the form definition">
Call [Get Human Input Form](/en/api-reference/human-input/get-human-input-form) with `form_token`. The response includes the rendered Markdown, input field definitions, available actions, pre-filled default values, and an `expiration_time` after which the form can no longer be submitted. Render the form for the recipient.
If the form expires before it is submitted, the paused run follows the node's configured timeout behavior; a resumed stream then carries `human_input_form_timeout` rather than `human_input_form_filled`.
</Step>
<Step title="(File inputs only) Upload local files">
If the recipient attaches a local file to a `file` or `file-list` input, upload it first with [Upload File](/en/api-reference/files/upload-file). It returns an `id` you reference as `upload_file_id` in the submit payload. Use one consistent `user` across the run, upload, and submit calls (see [End User Identity](/en/api-reference/guides/end-user-identity) for details).
A remote file needs no upload step: attach it inline in the submit as a `{transfer_method: remote_url, url}` mapping.
</Step>
<Step title="Submit the response">
Call [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form) with the recipient's input values, the selected `action`, and your `user`. The `action` must be one of the actions from the form definition in Step 2.
File inputs accept either a `{transfer_method: local_file, upload_file_id}` mapping (from Step 3) or an inline `{transfer_method: remote_url, url}` mapping. See [Upload First vs. Inline Remote URL](#upload-first-vs-inline-remote-url) for the trade-off.
A successful submit is final: it closes the form and resumes the run along the matching action branch, so the same `form_token` can't be submitted again.
A rejected submit (an invalid action, a missing required input, or a failed remote-file fetch) leaves the form unchanged—fix the inputs and resubmit with the same `form_token`.
</Step>
<Step title="Resume listening to the workflow">
If the original SSE stream closed, reopen it via [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) with the `workflow_run_id` from Step 1 and the same `user` that started the run—a different `user` gets a 404.
The resumed stream includes `human_input_form_filled` confirming the submission (or `human_input_form_timeout` if the form expired), then the remaining node events through to completion, like a run that never paused.
Add `include_state_snapshot=true` to first replay the status of nodes that already executed. If the workflow has more than one Human Input node in sequence, the stream closes at each pause by default; pass `continue_on_pause=true` to keep one stream open across all of them.
</Step>
</Steps>
## Upload First vs. Inline Remote URL
Both patterns work for file inputs:
* **Pre-upload, then reference `upload_file_id`** (recommended)
[Upload File](/en/api-reference/files/upload-file) enforces the file size limits at upload time, so the recipient gets immediate feedback and can retry before committing the whole submission.
* **Submit inline with `transfer_method: remote_url`**
The backend fetches the file at submit time. Faster to integrate, but any size, type, or fetch failure rejects the entire submission, forcing the recipient to redo other fields.
<Tip>
For interactive forms with recipient feedback, prefer the pre-upload pattern. The trade-off only pays off when the integration is fully programmatic and no human is waiting to retype anything.
</Tip>
## Delivery Method Requirement
The Human Input API works only with forms delivered via the Human Input node's web app method. Email-only delivery doesn't expose a `form_token`.
## Example: File-Attached Submission
This example uses a form with a `feedback` paragraph input, an `attachments` file-list input, and `approve` / `reject` actions.
1. Call [Get Human Input Form](/en/api-reference/human-input/get-human-input-form) to get the form definition:
```http theme={null}
GET /form/human_input/<form_token>
Authorization: Bearer {api-key}
```
Returns the form definition:
```json theme={null}
{
"form_content": "Please review the draft and confirm or request changes.",
"inputs": [
{
"type": "paragraph",
"output_variable_name": "feedback",
"default": {
"type": "constant",
"selector": [],
"value": ""
}
},
{
"type": "file-list",
"output_variable_name": "attachments",
"allowed_file_types": [
"image",
"document"
],
"allowed_file_extensions": [],
"allowed_file_upload_methods": [
"local_file",
"remote_url"
],
"number_limits": 5
}
],
"resolved_default_values": {},
"user_actions": [
{
"id": "approve",
"title": "Approve",
"button_style": "primary"
},
{
"id": "reject",
"title": "Request changes",
"button_style": "default"
}
],
"expiration_time": 1745510400
}
```
2. For each local file, call [Upload File](/en/api-reference/files/upload-file):
```http theme={null}
POST /files/upload
Authorization: Bearer {api-key}
Content-Type: multipart/form-data
file=<binary>
user=abc-123
```
Returns `{"id": "1a77f0df-...", ...}`.
3. Call [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form) with the recipient's input and selected action:
```http theme={null}
POST /form/human_input/<form_token>
Authorization: Bearer {api-key}
Content-Type: application/json
{
"inputs": {
"feedback": "Looks good to ship",
"attachments": [
{"transfer_method": "local_file", "upload_file_id": "1a77f0df-..."}
]
},
"action": "approve",
"user": "abc-123"
}
```
Returns `{}`. The workflow resumes along the `approve` branch.
4. Reconnect to the run's stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) to follow it through to completion, as in Step 5 of the sequence above.
# Knowledge API
Source: https://docs.dify.ai/en/api-reference/guides/knowledge
API for managing knowledge bases, documents, chunks, metadata, tags, and knowledge pipelines
Build and maintain [knowledge bases](/en/cloud/use-dify/knowledge/readme) from your own code, without going through the Dify console: create a knowledge base, load documents and chunks into it, organize them with metadata and tags, and query it directly for search or RAG.
<Note>
A single Knowledge Base API key has access to every knowledge base visible to the account that created the key. Handle your keys carefully to avoid unintended data exposure.
</Note>
## Get Your API Endpoint and Key
In **Knowledge**, click **Service API** in the top-right corner to open the API configuration panel. From here:
* Copy the Service API endpoint, the base URL for every Knowledge API request.
* Click **API Key** to create and manage keys.
<Warning>
Store your API key securely on the server side. Never expose it in client-side code or public repositories.
</Warning>
## Manage API Access for a Knowledge Base
Every knowledge base is reachable through the API by default. To restrict a specific knowledge base, open it, click **API Access** in the bottom-left corner, and turn the toggle off.
## Create and Manage Knowledge Bases
* **[Create an Empty Knowledge Base](/en/api-reference/knowledge-bases/create-an-empty-knowledge-base)**: create a knowledge base with no documents yet.
* **[List Knowledge Bases](/en/api-reference/knowledge-bases/list-knowledge-bases)**: a paginated list, filterable by keyword or tag.
* **[Get Knowledge Base](/en/api-reference/knowledge-bases/get-knowledge-base)**: one knowledge base's embedding model, retrieval configuration, and document statistics.
* **[Update Knowledge Base](/en/api-reference/knowledge-bases/update-knowledge-base)**: change the name, permissions, embedding model, or retrieval settings; only the fields you provide are updated.
* **[Delete Knowledge Base](/en/api-reference/knowledge-bases/delete-knowledge-base)**: permanently remove a knowledge base and every document inside it.
* **[Retrieve Chunks from a Knowledge Base / Test Retrieval](/en/api-reference/knowledge-bases/retrieve-chunks-from-a-knowledge-base-test-retrieval)**: search a knowledge base and return the most relevant chunks—the same endpoint serves production retrieval and retrieval testing.
## Add and Update Documents
Document creation is asynchronous. Create the document, then poll until indexing finishes:
<Steps>
<Step title="Create a knowledge base">
Call [Create an Empty Knowledge Base](/en/api-reference/knowledge-bases/create-an-empty-knowledge-base), or use an existing knowledge base.
</Step>
<Step title="Add a document">
Call [Create Document by Text](/en/api-reference/documents/create-document-by-text) or [Create Document by File](/en/api-reference/documents/create-document-by-file); both return a `batch` ID.
If you didn't set `indexing_technique` (how content is indexed for search) when creating the knowledge base, set it on this first document; later documents inherit it automatically.
</Step>
<Step title="Poll the indexing status">
Poll [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status) with the `batch` ID until `indexing_status` reaches `completed` or `error`; it progresses through `waiting`, `parsing`, `cleaning`, `splitting`, and `indexing` along the way.
</Step>
</Steps>
* **[List Documents](/en/api-reference/documents/list-documents)**: a paginated list, filterable by keyword or indexing status.
* **[Get Document](/en/api-reference/documents/get-document)**: one document's indexing status, metadata, and processing statistics; the `metadata` query parameter includes, omits, or returns only the metadata fields.
* **[Download Document](/en/api-reference/documents/download-document)**: a signed URL for the document's original uploaded file.
* **[Download Documents as ZIP](/en/api-reference/documents/download-documents-as-zip)**: bundle up to 100 uploaded-file documents into a single archive.
* **[Update Document](/en/api-reference/documents/update-document)**: replace a document's content by uploading a new file, re-triggering indexing; the canonical way to update a file-based document.
* **[Update Document by Text](/en/api-reference/documents/update-document-by-text)**: update a document's text content, name, or processing configuration inline; re-triggers indexing when the content changes.
* **[Update Document by File](/en/api-reference/documents/update-document-by-file)**: deprecated alias for uploading a replacement file; use Update Document instead.
* **[Update Document Status in Batch](/en/api-reference/documents/update-document-status-in-batch)**: enable, disable, archive, or unarchive multiple documents at once.
* **[Delete Document](/en/api-reference/documents/delete-document)**: permanently remove a document and every chunk inside it.
## Manage Chunks and Child Chunks
* **[Create Chunks](/en/api-reference/chunks/create-chunks)**: add chunks to a document by hand—indexing already chunks uploaded content automatically. Each chunk requires `content`; documents in Q\&A mode also require `answer`.
* **[List Chunks](/en/api-reference/chunks/list-chunks)**: a paginated list, filterable by keyword or status.
* **[Get Chunk](/en/api-reference/chunks/get-chunk)**: one chunk's content, keywords, and indexing status.
* **[Update Chunk](/en/api-reference/chunks/update-chunk)**: change a chunk's content, keywords, or answer; re-triggers indexing for that chunk.
* **[Delete Chunk](/en/api-reference/chunks/delete-chunk)**: permanently remove a chunk.
For documents in Parent-child mode (`hierarchical_model`), child chunks nest under a parent chunk. Child chunks you create or update through the API are always typed `customized`, unlike the `automatic` ones the indexing pipeline generates.
* **[Create Child Chunk](/en/api-reference/chunks/create-child-chunk)**: add a child chunk under a parent chunk.
* **[List Child Chunks](/en/api-reference/chunks/list-child-chunks)**: a paginated list of one parent chunk's child chunks.
* **[Update Child Chunk](/en/api-reference/chunks/update-child-chunk)**: change a child chunk's content.
* **[Delete Child Chunk](/en/api-reference/chunks/delete-child-chunk)**: permanently remove a child chunk.
## Manage Metadata Fields
Metadata fields annotate documents with structured information that retrieval can filter on:
* **[Create Metadata Field](/en/api-reference/metadata/create-metadata-field)**: add a custom field to the knowledge base, typed `string`, `number`, or `time`.
* **[List Metadata Fields](/en/api-reference/metadata/list-metadata-fields)**: every field, custom and built-in, with a count of documents using each.
* **[Update Metadata Field](/en/api-reference/metadata/update-metadata-field)**: rename a custom field.
* **[Delete Metadata Field](/en/api-reference/metadata/delete-metadata-field)**: remove a custom field; documents lose their values for it.
* **[Get Built-in Metadata Fields](/en/api-reference/metadata/get-built-in-metadata-fields)**: the system-provided fields, such as `document_name`, `uploader`, and `upload_date`.
* **[Update Built-in Metadata Field](/en/api-reference/metadata/update-built-in-metadata-field)**: enable or disable built-in fields for the knowledge base.
* **[Update Document Metadata in Batch](/en/api-reference/metadata/update-document-metadata-in-batch)**: set metadata key-value pairs across multiple documents in a single call.
Metadata also works as a stable external key: store your source system's ID on each document, then filter on it in later sync runs to find and update the same documents.
## Organize Knowledge Bases with Tags
Tags live at the workspace level, independent of any single knowledge base:
* **[Create Knowledge Tag](/en/api-reference/tags/create-knowledge-tag)**: create a tag for organizing knowledge bases.
* **[List Knowledge Tags](/en/api-reference/tags/list-knowledge-tags)**: every tag in the workspace.
* **[Update Knowledge Tag](/en/api-reference/tags/update-knowledge-tag)**: rename a tag.
* **[Delete Knowledge Tag](/en/api-reference/tags/delete-knowledge-tag)**: remove a tag from every knowledge base it was bound to, without deleting those knowledge bases.
* **[Create Tag Binding](/en/api-reference/tags/create-tag-binding)**: bind one or more tags to a knowledge base; a knowledge base can carry multiple tags.
* **[Delete Tag Binding](/en/api-reference/tags/delete-tag-binding)**: remove tags from a knowledge base.
* **[Get Knowledge Base Tags](/en/api-reference/tags/get-knowledge-base-tags)**: the tags currently bound to one knowledge base.
## Look Up Available Models
* **[Get Available Models](/en/api-reference/models/get-available-models)**: the models available for a given `model_type`; query `text-embedding` for embedding models or `rerank` for reranking models when configuring a knowledge base.
## Run the Knowledge Pipeline
A knowledge pipeline is a workflow that ingests data from a datasource and turns it into documents:
* **[Upload Pipeline File](/en/api-reference/knowledge-pipeline/upload-pipeline-file)**: upload a file for the pipeline to process.
* **[List Datasource Plugins](/en/api-reference/knowledge-pipeline/list-datasource-plugins)**: the datasource nodes configured in the pipeline—published by default, or the draft version with `is_published=false`.
* **[Run Datasource Node](/en/api-reference/knowledge-pipeline/run-datasource-node)**: execute a single datasource node and stream its results, useful for testing one step in isolation.
* **[Run Pipeline](/en/api-reference/knowledge-pipeline/run-pipeline)**: execute the full pipeline in `streaming` or `blocking` response mode; `is_published` picks the published version or the current draft.
# Consume Streaming Responses
Source: https://docs.dify.ai/en/api-reference/guides/streaming
Choose a response mode, parse the SSE stream, dispatch events, and recover when a connection drops
Generation endpoints return either one complete response or a Server-Sent Events (SSE) stream, chosen per request with `response_mode`. Streaming is the usual choice: the reply renders as it generates, and long runs aren't cut off mid-flight.
## Choose a Response Mode
`blocking` returns a single JSON body once generation finishes. It's the simpler integration for short, non-interactive calls, but long generations risk interruption: proxies cut long requests, and on Dify Cloud the edge proxy may end the connection if the upstream response doesn't arrive within its timeout.
`streaming` delivers the reply as SSE events. Use it for anything user-facing, for long runs, and for every flow that pauses for [Human Input](/en/api-reference/guides/human-input-flow).
<Info>
Legacy Agent and Agent apps stream only.
</Info>
## Parse the Stream
Every event except `ping` arrives as a `data: ` line holding one JSON object, terminated by a blank line.
Read the `event` field to decide what to do, and skip anything that isn't a `data: ` line: the keep-alive `ping` arrives as a bare `event: ping` line with no `data:` payload.
Chatflow and Workflow app streams open with a `ping` as the very first frame, and more arrive roughly every 10 seconds during the run. Treat the first `data:` event (`workflow_started`), not the first frame, as the signal that the run was accepted.
```python theme={null}
import json
import requests
body = {
"query": "What are this month's top issues?",
"inputs": {},
"user": "customer-4821",
"response_mode": "streaming",
}
with requests.post(url, headers=headers, json=body, stream=True) as r:
for line in r.iter_lines(decode_unicode=True):
if not line or not line.startswith("data: "):
continue # skips blank separators and ping lines
event = json.loads(line[len("data: "):])
handle(event)
```
On the wire, a stream looks like this:
```text theme={null}
event: ping
data: {"event": "workflow_started", "task_id": "c3800678-…", "workflow_run_id": "fb47b2e6-…", "data": {…}}
data: {"event": "node_finished", "task_id": "c3800678-…", "workflow_run_id": "fb47b2e6-…", "data": {…}}
```
<Tip>
When testing with curl, pass `-N` (`--no-buffer`) so events print as they arrive instead of after the run completes.
</Tip>
## Dispatch by Event Type
Which events arrive depends on the app type. See the event tables on [Send Chat Message](/en/api-reference/chat-messages/send-chat-message), [Run Workflow](/en/api-reference/workflow-runs/run-workflow), and [Send Completion Message](/en/api-reference/completion-messages/send-completion-message) for the contract.
The typical minimum:
1. Concatenate reply chunks in order:
* `message` events for Chatbot and Chatflow apps
* `agent_message` events for Legacy Agent and Agent apps
For Agent apps, a single closing `message` event repeats the complete answer; treat it as the final answer, not extra text to append.
2. Close on the right terminal event:
* `message_end` for Chatbot, Legacy Agent, and Agent apps
* `message_end` then `workflow_finished` (both arrive, in that order) for Chatflow apps
* `workflow_finished` for Workflow apps
3. Surface `error`.
## Handle Errors Mid-Stream
A failure after the stream opens doesn't change the HTTP status: the connection stays `200`. How the failure surfaces depends on where it happens:
* A workflow node failure arrives as `node_finished` and `workflow_finished` events with `status: "failed"`.
* Other failures end the stream with an `error` event carrying `status`, `code`, and `message`.
Handle both, and treat either as terminal for that request.
## Reconnect and Resume
Two identifiers matter, and they're easy to mix up:
* `task_id` controls the in-flight generation and is what the stop endpoints ([Stop Chat Message Generation](/en/api-reference/chat-messages/stop-chat-message-generation) / [Stop Workflow Task](/en/api-reference/workflow-runs/stop-workflow-task)) take.
* `workflow_run_id` names the persistent run record.
Both arrive on the stream itself: every event except `error` carries `task_id`, and workflow and node events carry `workflow_run_id`. Save `workflow_run_id` as soon as it arrives: if the connection drops mid-run, it's the only handle you have for reconnecting or checking the outcome.
For workflow-backed runs (Workflow and Chatflow apps), a dropped connection isn't fatal. Reopen the stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), passing the `workflow_run_id` and the same `user` that started the run. A mismatch returns 404.
Add `include_state_snapshot=true` to first replay the status of nodes that already ran, and `continue_on_pause=true` to keep one stream open across multiple Human Input pauses.
After reconnecting to a still-running workflow, confirm completion with [Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail) rather than relying on the reconnected stream's final event alone.
Other replies have no resume endpoint: if the connection drops mid-reply, issue a new request. For chat-style apps, [List Conversation Messages](/en/api-reference/conversations/list-conversation-messages) shows what was saved to the conversation.
## Keep the Connection Alive
Set your client's read timeout comfortably above the 10-second `ping` interval so idle stretches between events don't kill the connection. The pings themselves need no handling beyond being skipped.
# Workflow App API
Source: https://docs.dify.ai/en/api-reference/guides/workflow
API for Workflow apps, covering workflow execution, run control and streaming, Human Input pauses, and run history
[Workflow apps](/en/cloud/use-dify/build/workflow-chatflow) run in `workflow` mode, executing the published workflow once per call and returning its outputs. There's no conversation state between calls, so each run is independent of any previous one.
<Info>
Authentication, the base URL, and the `user` field that scopes end-user data are covered in [Get Started](/en/api-reference/guides/get-started) and [End User Identity](/en/api-reference/guides/end-user-identity).
</Info>
## Run a Workflow
* **[Run Workflow](/en/api-reference/workflow-runs/run-workflow)**: execute the app's currently published workflow with the input variables you provide.
Streaming mode delivers events live as nodes execute; blocking mode returns once the run finishes.
* **[Run Workflow by ID](/en/api-reference/workflow-runs/run-workflow-by-id)**: execute a specific published version instead, identified by the `workflow_id` from an earlier run response or run detail lookup.
## Follow and Control a Run
Whichever mode you run in, the response carries two IDs: `task_id` controls the run while it's active, and `workflow_run_id` identifies the persisted record afterward.
* **[Stop Workflow Task](/en/api-reference/workflow-runs/stop-workflow-task)**: cancel an active run by its `task_id`. Works in streaming mode only; a blocking call has already finished by the time it returns.
* **[Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events)**: resume a run's event stream from its `workflow_run_id` after a dropped connection or a pause.
Pass `include_state_snapshot=true` to replay the status of already-executed nodes first, or `continue_on_pause=true` to stay open across multiple Human Input pauses.
## Pause for Human Input
When a run reaches a [Human Input node](/en/cloud/use-dify/nodes/human-input) whose delivery method is web app, complete the pause over the API:
<Steps>
<Step title="Listen for the pause">
The run's event stream emits `human_input_required` carrying a `form_token` and the run's `workflow_run_id`, then ends with the `workflow_paused` event.
</Step>
<Step title="Fetch the form">
Load the form's contents with [Get Human Input Form](/en/api-reference/human-input/get-human-input-form), using the `form_token`.
</Step>
<Step title="Submit the response">
Send the recipient's input with [Submit Human Input Form](/en/api-reference/human-input/submit-human-input-form). Submitting resumes the run.
</Step>
<Step title="Resume the stream">
Open a new stream with [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events), using the `workflow_run_id` from the paused stream, and follow the remaining events through to the run's finish.
</Step>
</Steps>
For file-attached submissions and the full event sequence, see the [Human Input Flow](/en/api-reference/guides/human-input-flow) guide.
## Inspect Past Runs
* **[Get Workflow Run Detail](/en/api-reference/workflow-runs/get-workflow-run-detail)**: a run's status and outputs, by its `workflow_run_id`.
* **[List Workflow Logs](/en/api-reference/workflow-runs/list-workflow-logs)**: run-level summaries covering status, token usage, step count, and timing, rather than a node-by-node execution log; filter by keyword, status, date range, or who triggered the run.
For node-level events, stream the run instead of listing its logs: call [Run Workflow](/en/api-reference/workflow-runs/run-workflow) in streaming mode for a run you're starting, or [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) for one already in progress.
## Work with Files
* **[Upload File](/en/api-reference/files/upload-file)**: upload an image, document, audio, or video file, then pass the returned `id` as `upload_file_id` in a file-type input variable when you run the workflow. Files are scoped to the uploading end user.
* **[Get End User Info](/en/api-reference/end-users/get-end-user-info)**: look up an end user's details from an end-user ID, such as the `created_by` in the Upload File response.
## Transcribe and Synthesize Speech
* **[Convert Audio to Text](/en/api-reference/audio/convert-audio-to-text)**: transcribe an uploaded audio file (MP3, M4A, WAV, AMR, or MPGA, up to 30 MB) so end users can speak an input value instead of typing it.
* **[Convert Text to Audio](/en/api-reference/audio/convert-text-to-audio)**: synthesize a workflow's text output back into speech.
## Retrieve App Info and Settings
* **[Get App Info](/en/api-reference/applications/get-app-info)**: the app's name, description, tags, and mode.
* **[Get App Parameters](/en/api-reference/applications/get-app-parameters)**: the fields your calls send in `inputs` (names, types, defaults) plus the app's feature switches—the basis for building requests or a client UI.
* **[Get App Meta](/en/api-reference/applications/get-app-meta)**: tool icons and other configuration metadata.
* **[Get App WebApp Settings](/en/api-reference/applications/get-app-webapp-settings)**: the web app's site configuration, theme, and customization options.
# Key Concepts
Source: https://docs.dify.ai/en/learn/key-concepts
Quick overview of essential Dify concepts
### Dify App
Dify is made for agentic app building. In **Studio**, you can quickly build agentic workflows via a drag & drop interface and publish them as apps. You can access published apps via API, the web, or as an [MCP server](/en/cloud/use-dify/publish/publish-mcp). Dify offers two main app types: Workflow and Chatflow. You will need to choose an app type when creating a new app.
<Info>
We recommend choosing Workflow or Chatflow your app type. But in addition to these, Dify also offers 3 more basic app types: Chatbot, Agent, and Text Generator.
<Frame>
<img alt="App Type Selector" />
</Frame>
These app types run on the same workflow engine underneath, but comes with simpler legacy interfaces:
<Frame>
<img alt="Chatbot Interface" />
</Frame>
</Info>
### Workflow
Build Workflow apps to handle single-turn tasks. The webapp interface and API provides easy access to batch execute many tasks at once.
<Info>
Underneath it all, workflow forms the basis for all other app types in Dify.
</Info>
Every workflow begins with a [start node](/en/cloud/use-dify/nodes/start): either User Input (on-demand, triggered by a user or API call) or a Trigger (automatic, on a schedule or in response to external events).
### Chatflow
Chatflow is a special type of workflow app that gets triggered at every turn of a conversation. Other than workflow features, Chatflow comes with the ability to store and update custom conversation-specific variables, enable memory in LLM nodes, and stream formatted text, images, and files at different points throughout the Chatflow run.
Chatflows always start with User Input.
### Dify DSL
All Dify apps can be exported into a YAML file in Dify's own DSL (Domain-Specific Language) and you may create Dify apps from these DSL files directly. This makes it easy to port apps to other Dify instances and share with others.
### Variables
A variable is a labeled container to store information, so you can find and use that information later by referencing its name. You'll come across different types of variables when building a Dify app:
**Inputs**: You can specify any number of input variables at the [User Input](/en/cloud/use-dify/nodes/user-input) node for your app's end users to fill in.
<Frame>
<img alt="User Input Node Variables" />
</Frame>
Additionally, the User Input node comes with a set of input variables that you can reference later in the flow. Depending on the app type (Workflow or Chatflow), different variables are provided.
<Tabs>
<Tab title="Workflow">
| Variable Name | <div>Data Type</div> | Description | Notes |
| :-------------------- | :------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------- |
| `sys.user_id` | String | User ID: A unique identifier automatically assigned by the system to each user when they use a Workflow application. It is used to distinguish different users. | |
| `sys.app_id` | String | App ID: A unique identifier automatically assigned by the system to each App. This parameter is used to record the basic information of the current application. | This parameter is used to differentiate and locate distinct Workflow applications for users with development capabilities. |
| `sys.workflow_id` | String | Workflow ID: This parameter records information about all nodes information in the current Workflow application. | This parameter can be used by users with development capabilities to track and record information about the nodes contained within a workflow. |
| `sys.workflow_run_id` | String | Workflow Run ID: Used to record the runtime status and execution logs of a Workflow application. | This parameter can be used by users with development capabilities to track the application's historical execution records. |
| `sys.timestamp` | Number | The start time of each workflow execution. | |
</Tab>
<Tab title="Chatflow">
| Variable Name | <div>Data Type</div> | Description | Notes |
| :-------------------- | :------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sys.conversation_id` | String | A unique ID for the chatting box interaction session, grouping all related messages into the same conversation, ensuring that the LLM continues the chatting on the same topic and context. | |
| `sys.dialogue_count` | Number | The number of conversations turns during the user's interaction with a Chatflow application. The count automatically increases by one after each chat round and can be combined with if-else nodes to create rich branching logic.<br /><br />For example, LLM will review the conversation history at the X conversation turn and automatically provide an analysis. | |
| `sys.user_id` | String | A unique ID is assigned for each application user to distinguish different conversation users. | The Service API does not share conversations created by the web app. This means users with the same ID will have separate conversation histories between API and web app interfaces. |
| `sys.app_id` | String | App ID: A unique identifier automatically assigned by the system to each App. This parameter is used to record the basic information of the current application. | This parameter is used to differentiate and locate distinct applications for users with development capabilities. |
| `sys.workflow_id` | String | Workflow ID: This parameter records information about all nodes information in the current application. | This parameter can be used by users with development capabilities to track and record information about the nodes contained within a workflow. |
| `sys.workflow_run_id` | String | Workflow Run ID: Used to record the runtime status and execution logs of an application. | This parameter can be used by users with development capabilities to track the application's historical execution records. |
</Tab>
</Tabs>
User inputs are set at the start of each workflow run and cannot be updated.
**Outputs**: Each node produces one or more outputs that can be referenced in subsequent nodes. For instance, the LLM node has outputs:
<Frame>
<img alt="LLM Node Output Variables" />
</Frame>
Like inputs, node outputs cannot be updated either.
**Environment Variables**: Store secrets like API keys outside the app itself, so sharing your app's DSL doesn't expose them. An environment variable can also hold a model configuration shared by multiple LLM nodes; editing the variable updates the model in every node that uses it.
**Conversation Variables (Chatflow only)**: These variables are conversation-specific -- meaning they persist over multi-turn Chatflow runs in a single conversation so you can store and access dynamic information like to-do list and token cost. You can update the value of a conversation variable via the Variable Assigner node:
<Frame>
<img alt="Conversation Variables Panel" />
</Frame>
### Variable Referencing
You can easily pass variables to any node when configuring its input field by selecting from a dropdown:
<Frame>
<img alt="Variable Picker Dropdown" />
</Frame>
You can also insert variable values into complex text inputs by typing `/` slash, and selecting the desired variable from the dropdown.
<Frame>
<img alt="Variable Slash Insert" />
</Frame>
# Article Reader Using File Upload
Source: https://docs.dify.ai/en/learn/tutorials/article-reader
In Dify, you can use the knowledge base to allow agent to obtain accurate information from a large amount of text content. However, in many cases, the local files provided are not large enough to warrant the use of the knowledge base. In such cases, you can use the file upload feature to directly provide local files as context for the LLM to read.
In this experiment, we will build the article reader as a case study. This assistant will ask questions based on the uploaded document, helping users to read papers and other materials with those questions in mind.
## You Will Learn
* File upload usage
* Basic usage of Chatflow
* Prompt writing skill
* Iteration node usage
* Doc extractor and list operator usage
## **Prerequisites**
Create a Chatflow in Dify. Make sure you have added a model provider and have sufficient quota.
## **Add Nodes**
In this experiment, at least four types of nodes are required: start node, document extractor node, LLM node, and answer node.
### **Start Node**
In the start node, you need to add a file variable. File upload is supported in v0.10.0 Dify, allowing you to add files as variable.
In the start node, you need to add a file variable and check the document in the supported file types.
Some readers might notice the `sys.files` in the system variables, which are files or file lists uploaded by users in the dialog box.
The difference between creating your own file variables is that this feature requires enabling file upload in the functions and setting the upload file types, and each time a new file is uploaded in the dialog, this variable will be overwritten.
Please choose the appropriate file upload method according to your business scenario.
### **Doc Extractor**
**LLM cannot read files directly.** This is a common misconception among many users when they first use file upload, as they might think simply using the file as a variable in an LLM node would work. However, in reality, the LLM reads nothing from file variables.
Thus, Dify introduced the **doc extractor** node, which can extract text from the file variable and output it as a text variable.
The **doc extractor** node takes the file variable from the **start** node as input and converts document files into text output.
<Frame>

</Frame>
### **LLM**
In this experiment, two LLM nodes need to be designed: structure extraction and question generation.
#### **Structure Extraction**
The structure extraction node can extract the structure of the original text, summarizing key content.
The prompts are as follow:
```
Read the following article content and perform the task
{{Result variable of the document extractor}}
# Task
- **Main Objective**: Thoroughly analyze the structure of the article.
- **Objective**: Detail the content of each part of the article.
- **Requirements**: Analyze as detailed as possible.
- **Restrictions**: No specific format restrictions, but the analysis must be organized and logical.
- **Expected Output**: A detailed analysis of the article structure, including the main content and role of each part.
# Reasoning Order
- **Reasoning Part**: By carefully reading the article, identify and analyze its structure.
- **Conclusion Part**: Provide specific content and role for each part.
# Output Format
- **Analysis Format**: Each part should be listed in a headline format, followed by a detailed explanation of that part's content.
- **Structure Form**: Markdown, to enhance readability.
- **Specific Description**: The content and role of each part, including but not limited to the introduction, body, conclusion, citations, etc.
```
#### **Question Generation**
The question generation node can summarize the issues of the article from the content summarized by the structure extraction node, assisting the reader in thinking through the questions during the reading process.
The prompts are as follow:
```
Read the following article content and perform the task
{{Output of the structure extraction}}
# Task
- **Main Objective**: Thoroughly read the above text, and propose as many questions as possible for each part of the article.
- **Requirements**: Questions should be meaningful and valuable, worthy of consideration.
- **Restrictions**: No specific restrictions.
- **Expected Output**: A series of questions for each part of the article, each question should have depth and thinking value.
# Reasoning Order
- **Reasoning Part**: Thoroughly read the article, analyze the content of each part, and consider the deep questions each part may raise.
- **Conclusion Part**: Pose meaningful and valuable questions, ensuring they provoke in-depth thought.
# Output Format
- **Format**: Each question should be listed separately, numbered.
- **Content**: Propose questions for each part of the article (such as introduction, background, methods, results, discussion, conclusion, etc.).
- **Quantity**: As many as possible, but each question should be meaningful and valuable.
```
## **Question 1: Handling Multiple Uploaded Files**
To handle multiple uploaded files, an iterative node is needed.
The iterative node is similar to the while loop in many programming languages, except that Dify has no conditional restrictions, and the **input variable can only be of type `array` (list)**. The reason is that Dify will execute all the content in the list until it is done.
<Frame>

</Frame>
Therefore, you need to adjust the file variable in the start node to an `array` type, i.e., a file list.
<Frame>

</Frame>
## **Question 2: Handling Specific Files from a File List**
In Question 1, some readers might notice that Dify will process all files before ending the loop, while in some cases, only a part of the files need to be operated on, not all. For this issue, you can process the file list in Dify using the **list operation** node. List operations can operate on all array-type variables, not just file lists.
For example, limit the analysis to only document-type files and sort the files to be processed in order of file names.
Before the iterative node, add a list operation, adjust the **filter condiftion** and **order by**, then change the input of the iterative node to the output of the list operation node.
<Frame>

</Frame>
# AI Image Generation App
Source: https://docs.dify.ai/en/learn/tutorials/build-ai-image-generation-app
With the rise of image generation, many excellent image generation products have emerged, such as Dall-e, Flux, Stable Diffusion, etc.
In this article, you will learn how to develop an AI image generation app using Dify.
<Frame>

</Frame>
## You Will Learn
* Methods for building an Agent using Dify
* Basic concepts of Agent
* Fundamentals of prompt engineering
* Tool usage
* Concepts of large model hallucinations
## 1. Set Stability API Key
[Click here](https://platform.stability.ai/account/keys) to go to the Stability API key management page.
If you haven't registered yet, you will be asked to register before entering the API management page.
After entering the management page, click `copy` to copy the key.
<Frame>

</Frame>
Next, fill in the key under **Tools** > **Stability** in your Dify instance by following these steps:
* Log in to Dify
* Enter Tools
* Select Stability
* Click `Authorize`
<Frame>

</Frame>
* Fill in the key and save
## 2. Configure Model Providers
To optimize interaction, we need an LLM to concretize user instructions, i.e., to write prompts for generating images. Next, we will configure model providers in Dify following these steps.
Add a model provider by following the steps in the image below:
Go to **Integrations** > **Model Provider**
<Frame>

</Frame>
If you haven't found a suitable model provider, the groq platform provides free call credits for LLMs like Llama.
Log in to [groq API Management Page](https://console.groq.com/keys)
Click **Create API Key**, set a desired name, and copy the API Key.
Back to **Dify - Model Providers**, select **groqcloud**, and click **Setup**.
<Frame>

</Frame>
Paste the API Key and save.
<Frame>

</Frame>
## 3. Build an Agent
Back to **Dify - Studio**, select **Create from Blank**.
<Frame>

</Frame>
In this experiment, we only need to understand the basic usage of Agent.
<Info>
**What is an Agent**
An Agent is an AI system that simulates human behavior and capabilities. It interacts with the environment through natural language processing, understands input information, and generates corresponding outputs. The Agent also has "perception" capabilities, can process and analyze various forms of data, and can call and use various external tools and APIs to complete tasks, extending its functional scope. This design allows the Agent to handle complex situations more flexibly and simulate human thinking and behavior patterns to some extent.
</Info>
Select **Agent**, fill in the name.
<Frame>

</Frame>
Next, you will enter the Agent orchestration interface as shown below.
<Frame>

</Frame>
Select the LLM. Here we use Llama-3.1-70B provided by groq as an example:
<Frame>

</Frame>
Select Stability in **Tools**:
<Frame>

</Frame>
<Frame>

</Frame>
### Write Prompts
Prompts are the soul of the Agent and directly affect the output effect. Generally, the more specific the prompts, the better the output, but overly lengthy prompts can also lead to negative effects.
The engineering of adjusting prompts is called Prompt Engineering.
In this experiment, you don't need to worry about not mastering Prompt Engineering; we will learn it step by step later.
Let's start with the simplest prompts:
```
Draw the specified content according to the user's prompt using stability_text2image.
```
Each time the user inputs a command, the Agent will know this system-level instruction, thus understanding that when executing a user's drawing task, it needs to call stability tool.
For example: Draw a girl holding an open book.
<Frame>

</Frame>
### Don't want to write prompts? Of course you can!
Click **Generate** in the upper right corner of Instructions.
<Frame>

</Frame>
Enter your requirements in the **Instructions** and click **Generate**. The generated prompts on the right will show AI-generated prompts.
<Frame>

</Frame>
However, to develop a good understanding of prompts, we should not rely on this feature in the early stages.
## Publish
Click the publish button in the upper right corner, and after publishing, click **Open web app** to get a web page for an online running Agent.
<Frame>

</Frame>
Copy the URL of this web page to share with other friends.
## Question 1: How to Specify the Style of Generated Images?
We can add style instructions in the user's input command, for example: Anime style, draw a girl holding an open book.
<Frame>

</Frame>
But if we want set the default style to anime style, we can add it to the system prompt because we previously learned that the system prompt is known each time the user command is executed and has a higher priority.
```
Draw the specified content according to the user's prompt using stability_text2image, the picture is in anime style.
```
## Question 2: How to Reject Certain Requests from Some Users?
In many business scenarios, we need to avoid outputting some unreasonable content, but LLMs are often "dumb" and will follow user instructions without question, even if the output content is wrong. This phenomenon of the model trying hard to answer users by fabricating false content is called **model hallucinations**. Therefore, we need the model to refuse user requests when necessary.
Additionally, users may also ask some content unrelated to the business, and we also need the Agent to refuse such requests.
We can use markdown format to categorize different prompts, writing the prompts that teach the Agent to refuse unreasonable content under the "Constraints" title. Of course, this format is just for standardization, and you can have your own format.
```
## Task
Draw the specified content according to the user's prompt using stability_text2image, the picture is in anime style.
## Constraints
If the user requests content unrelated to drawing, reply: "Sorry, I don't understand what you're saying."
```
For example, let's ask: What's for dinner tonight?
<Frame>

</Frame>
In some more formal business scenarios, we can call a sensitive word library to refuse user requests.
Add the keyword "dinner" in **Add Feature - Content Moderation**. When the user inputs the keyword, the Agent app outputs "Sorry, I don't understand what you're saying."
<Frame>

</Frame>
# Customer Service Bot With Knowledge Base
Source: https://docs.dify.ai/en/learn/tutorials/customer-service-bot
Build a Chatflow that answers customer questions from a knowledge base
In the last experiment, we learned the basic usage of file uploads. However, when the text we need to read exceeds the LLM's context window, we need to use a knowledge base.
<Info>
**What is context?**
The context window refers to the range of text that the LLM can "see" and "remember" when processing text. It determines how much previous text information the model can refer to when generating responses or continuing text. The larger the window, the more contextual information the model can utilize, and the generated content is usually more accurate and coherent.
</Info>
Previously, we learned about the concept of LLM hallucinations. In many cases, an LLM knowledge base allows the Agent to locate accurate information, thus accurately answering questions. It has applications in specific fields such as customer service and search tools.
Traditional customer service bots are often based on keyword retrieval. When users input questions outside of the keywords, the bot cannot solve the problem. The knowledge base is designed to solve this problem, enabling semantic-level retrieval and reducing the burden on human agents.
Before starting the experiment, remember that the core of the knowledge base is retrieval, not the LLM. The LLM enhances the output process, but the real need is still to generate answers.
### What You Will Learn in This Experiment
* Basic usage of Chatflow
* Usage of knowledge bases and external knowledge bases
* The concept of embeddings
### Prerequisites
#### Create an Application
In Dify, select **Create from Blank** > **Chatflow**.
<Frame>

</Frame>
#### Add a Model Provider
This experiment involves using embedding models. Currently, supported embedding model providers include OpenAI and Cohere. In Dify's model providers, those with the `TEXT EMBEDDING` label are supported. Ensure you have added at least one and have sufficient balance.
<Frame>

</Frame>
<Info>
**What is embedding?**
"Embedding" is a technique that converts discrete variables (such as words, sentences, or entire documents) into continuous vector representations.
Simply put, when we process natural language into data, we convert text into vectors. This process is called embedding. Vectors of semantically similar texts will be close together, while vectors of semantically opposite texts will be far apart. LLMs use this data for training, predicting subsequent vectors, and thus generating text.
</Info>
### Create a Knowledge Base
Go to **Knowledge** > **Create Knowledge**.
Dify supports three data sources: documents, Notion, and web pages.
For local text files, note the file type and size limitations; syncing Notion content requires binding a Notion account; syncing a website requires using the **Jina** or **Firecrawl API**.
We will start with uploading a local document as an example.
#### Chunk Settings
After uploading the document, you will enter the following page:
<Frame>

</Frame>
You can see a segmentation preview on the right. The default selection is automatic segmentation and cleaning. Dify will automatically divide the article into many paragraphs based on the content. You can also set other segmentation rules in the custom settings.
#### Index Method
Normally we prefer to select **High Quality**, but this will consume extra tokens. Selecting **Economical** will not consume any tokens.
#### Embedding Model
Please refer to the model provider's documentation and pricing information before use.
Different embedding models are suitable for different scenarios. For example, Cohere's `embed-english` is suitable for English documents, and `embed-multilingual` is suitable for multilingual documents.
#### Retrieval Settings
Dify provides three retrieval functions: vector retrieval, full-text retrieval, and hybrid retrieval. Hybrid retrieval is the most commonly used.
In hybrid retrieval, you can set weights or use a reranking model. When setting weights, you can set whether the retrieval should focus more on semantics or keywords. For example, in the image below, semantics account for 70% of the weight, and keywords account for 30%.
<Frame>

</Frame>
Clicking **Save and Process** will process the document. After processing, the document can be used in the application.
<Frame>

</Frame>
#### Sync from a Website
In many cases, we need to build a smart customer service bot based on help documentation. Taking Dify as an example, we can convert the [Dify help documentation](https://docs.dify.ai) into a knowledge base.
Currently, Dify supports processing up to 50 pages. Please pay attention to the quantity limit. If exceeded, you can create a new knowledge base.
<Frame>

</Frame>
#### Adjust Knowledge Base Content
After the knowledge base has processed all documents, it is best to check the coherence of the segmentation in the knowledge base. Incoherence will affect the retrieval effect and needs to be manually adjusted.
Click on the document content to browse the segmented content. If there is irrelevant content, you can disable or delete it.
If content is segmented into another paragraph, it also needs to be adjusted back.
#### Recall Test
In the document page of the knowledge base, click **Retrieval Testing** in the left sidebar to input keywords to test the accuracy of the retrieval results.
### Add Nodes
Enter the created app, and let's start building the smart customer service bot.
#### Question Classification Node
You need to use a Question Classifier node to separate different user needs. In some cases, users may even chat about irrelevant topics, so you need to set a classification for this as well.
To make the classification more accurate, you need to choose a better LLM, and the classification needs to be specific enough with sufficient distinction.
Here is a reference classification:
* User asks irrelevant questions
* User asks Dify-related questions
* User requests explanation of technical terms
* User asks about joining the community
<Frame>

</Frame>
#### Direct Reply Node
In the question classification, "User asks irrelevant questions" and "User asks about joining the community" do not need LLM processing to reply. Therefore, you can directly connect an Answer node after these two questions.
For "User asks irrelevant questions", you can guide the user to the help documentation, allowing them to try to solve the problem themselves, for example:
```text theme={null}
I'm sorry, I can't answer your question. If you need more help, please check the [help documentation](https://docs.dify.ai).
```
Dify supports Markdown formatted text output. You can use Markdown to enrich the text format in the output. You can even insert images in the text using Markdown.
#### Knowledge Retrieval Node
Add a Knowledge Retrieval node after "User asks Dify-related questions" and check the knowledge base to be used.
#### LLM Node
In the next node after the Knowledge Retrieval node, you need to select an LLM node to organize the content retrieved from the knowledge base.
The LLM needs to adjust the reply based on the user's question to make the reply more appropriate.
Context: You need to use the output of the Knowledge Retrieval node as the context of the LLM node.
System prompt: Based on `{{context}}`, answer `{{user question}}`.
<Frame>

</Frame>
You can use `/` or `{` to reference variables in the prompt writing area. Variables starting with `sys.` are system variables.
In addition, you can enable LLM memory to make the user's conversation experience more coherent.
### Question 1: How to Connect External Knowledge Bases
In the knowledge base function, you can connect external knowledge bases through external knowledge base APIs, such as the AWS Bedrock knowledge base.
<Frame>

</Frame>
### Question 2: How to Manage Knowledge Bases Through APIs
You can add, delete, and query the status of knowledge bases through the knowledge base API.
<Frame>

</Frame>
In the knowledge base detail page, go to **API Access** and create an API key. Please keep the API key safe.
### Question 3: How to Embed the Customer Service Bot into a Webpage
After publishing the application, open its **Access Point** tab and select **Embed Into Site** on the **Web App** card. Choose a suitable embedding method, and paste the code into the appropriate location on the webpage.
# Simple Chatbot
Source: https://docs.dify.ai/en/learn/tutorials/simple-chatbot
Hello World
The real value of Dify lies in how easily you can build, deploy, and scale an idea no matter how complex. It's built for fast prototyping, smooth iteration, and reliable deployment at any level.
Let's start by learning reliable LLM integration into your applications. In this guide, you'll build a simple chatbot that classifies the user's question, respond directly using the LLM, and enhance the response with a country-specific fun fact.
<iframe title="Dify Quick Start Video" />
## Step 1: Create a New Workflow (2 min)
1. Go to **Studio** > **Workflow** > **Create from Blank** > **Orchestrate** > **New Chatflow** > **Create**
## Step 2: Add Workflow Nodes (6 min)
<Tip>
When you want to reference any variable, type `{` or `/` first and you can see the different variables available in your workflow.
</Tip>
### 1. LLM Node and Output: Understand and Answer the Question
<Info>
`LLM` node sends a prompt to a language model to generate a response based on user input. It abstracts away the complexity of API calls, rate limits, and infrastructure, so you can just focus on designing logic.
</Info>
<Steps>
<Step title="Create LLM Node">
Create an LLM node using the `Add Node` button and connect it to your Start node
</Step>
<Step title="Configure Model">
Choose a default model
</Step>
<Step title="Set System Prompt">
Paste this into the System Prompt field:
```text theme={null}
The user will ask a question about a country. The question is {{sys.query}}
Tasks:
1. Identify the country mentioned.
2. Rephrase the question clearly.
3. Answer the question using general knowledge.
Respond in the following JSON format:
{
"country": "<country name>",
"question": "<rephrased question>",
"answer": "<direct answer to the question>"
}
```
</Step>
<Step title="Enable Structured Output">
**Enable Structured Output** allows you to easily control what the LLM will return and ensure consistent, machine-readable outputs for downstream use in precise data extraction or conditional logic.
* Toggle Output Variables Structured ON > `Configure` and click `Import from JSON`
* Paste:
```json theme={null}
{
"country": "string",
"question": "string",
"answer": "string"
}
```
</Step>
</Steps>
### 2. Code Block: Get Fun Fact
<Info>
`Code` node executes custom logic using code. It lets you inject code exactly where needed—within a visual workflow—saving you from wiring up an entire backend.
</Info>
<Steps>
<Step title="Create Code Node">
Create a `Code` Node using the `Add Node` button and connect to LLM block
</Step>
<Step title="Configure Input Variable">
Change one `Input Variable` name to "country" and set the variable to `structured_output` > `country`
</Step>
<Step title="Add Python Code">
Paste this code into `PYTHON3`:
```python theme={null}
def main(country: str) -> dict:
country_name = country.lower()
fun_facts = {
"japan": "Japan has more than 5 million vending machines.",
"france": "France is the most visited country in the world.",
"italy": "Italy has more UNESCO World Heritage sites than any other country."
}
fun_fact = fun_facts.get(country_name, f"No fun fact available for {country.title()}.")
return {"fun_fact": fun_fact}
```
</Step>
<Step title="Rename Output Variable">
Change output variable `result` to `fun_fact` to have a better labeled variable
</Step>
</Steps>
### 3. Answer Node: Final Answer to User
<Info>
`Answer` Node creates a clean final output to return.
</Info>
<Steps>
<Step title="Create Answer Node">
Create an `Answer` Node using the `Add Node` button
</Step>
<Step title="Configure Answer Field">
Paste into the Answer Field:
```text theme={null}
Q: {{ structured_output.question }}
A: {{ structured_output.answer }}
Fun Fact: {{ fun_fact }}
```
</Step>
</Steps>
End Workflow:
<Frame>
<img alt="Complete workflow diagram showing LLM, Code, and Answer nodes connected" />
</Frame>
***
## Step 3: Test the Bot (3 min)
Click `Preview`, then ask:
* "What is the capital of France?"
* "Tell me about Japanese cuisine"
* "Describe the culture in Italy"
* Any other questions
Make sure your Bot works as expected!
## You've Completed the Bot!
This guide showed how to integrate language models reliably and scalably without reinventing infrastructure. With Dify's visual workflows and modular nodes, you're not just building faster, you're adopting a clean, production-ready architecture for LLM-powered apps.
# Twitter Account Analyzer
Source: https://docs.dify.ai/en/learn/tutorials/twitter-chatflow
Build a Chatflow that scrapes a Twitter profile via Crawlbase and analyzes the user's tweets with an LLM
## Introduction
In Dify, you can use some crawler tools, such as Jina, which can convert web pages into markdown format that LLMs can read.
Recently, [wordware.ai](https://www.wordware.ai/) has brought to our attention that we can use crawlers to scrape social media for LLM analysis, creating more interesting applications.
However, knowing that X (formerly Twitter) stopped providing free API access on February 2, 2023, and has since upgraded its anti-crawling measures. Tools like Jina are unable to access X's content directly.
> Starting February 9, we will no longer support free access to the Twitter API, both v2 and v1.1. A paid basic tier will be available instead 🧵
>
> — Developers (@XDevelopers) [February 2, 2023](https://twitter.com/XDevelopers/status/1621026986784337922?ref_src=twsrc%5Etfw)
Fortunately, Dify also has an HTTP tool, which allows us to call external crawling tools by sending HTTP requests. Let's get started!
## Prerequisites
### Register Crawlbase
Crawlbase is an all-in-one data crawling and scraping platform designed for businesses and developers. Crawlbase Scraper can pull data from social platforms like X, Facebook, and Instagram.
Register at [crawlbase.com](https://crawlbase.com).
### Sign in to Dify
Open Dify in your browser and sign in. You'll need access to a running Dify instance to follow along.
### Configure LLM Providers
Go to **Integrations** > **Model Provider**, install at least one model provider (for example, OpenAI), and configure its credentials.
<Frame>

</Frame>
## Create a Chatflow
Now, let's get started on the Chatflow.
Click on `Create from Blank` to start:
<Frame>

</Frame>
The initialized Chatflow should be like:
<Frame>

</Frame>
## Add nodes to Chatflow
<Frame>

</Frame>
### Start node
In start node, we can add some system variables at the beginning of a chat. In this article, we need a Twitter user's ID as a string variable. Let's name it `id`.
Click on Start node and add a new variable:
<Frame>

</Frame>
### Code node
According to [Crawlbase docs](https://crawlbase.com/docs/crawling-api/scrapers/#twitter-profile), the variable `url` (this will be used in the following node) should be `https://twitter.com/` + `user id`, such as `https://twitter.com/elonmusk` for Elon Musk.
To convert the user ID into a complete URL, we can use the following Python code to integrate the prefix `https://twitter.com/` with the user ID:
```python theme={null}
def main(id: str) -> dict:
return {
"url": "https://twitter.com/"+id,
}
```
Add a code node and select python, and set input and output variable names:
<Frame>

</Frame>
### HTTP request node
Based on the [Crawlbase docs](https://crawlbase.com/docs/crawling-api/scrapers/#twitter-profile), to scrape a Twitter user's profile in http format, we need to complete HTTP request node in the following format:
<Frame>

</Frame>
Importantly, it is best not to directly enter the token value as plain text for security reasons, as this is not a good practice. Actually, in the latest version of Dify, we can set token values in **`Environment Variables`**. Click `env` - `Add Variable` to set the token value, so plain text will not appear in the node.
Check [https://crawlbase.com/dashboard/account/docs](https://crawlbase.com/dashboard/account/docs) for your crawlbase API Key.
<Frame>

</Frame>
By typing `/`, you can easily insert the API Key as a variable.
<Frame>

</Frame>
Tap the start button of this node to check whether it works correctly:
<Frame>

</Frame>
### LLM node
Now, we can use LLM to analyze the result scraped by crawlbase and execute our command.
The value `context` should be `body` from HTTP Request node.
The following is a sample system prompt.
<Frame>

</Frame>
## Test run
Click `Preview` to start a test run and input twitter user id in `id`.
<Frame>

</Frame>
For example, I want to analyze Elon Musk's tweets and write a tweet about global warming in his tone.
<Frame>

</Frame>
Does this sound like Elon? lol
Click `Publish` in the upper right corner and add it in your website.
Have fun!
## Lastly...
### Other X(Twitter) Crawlers
In this article, I've introduced crawlbase. It should be the cheapest Twitter crawler service available, but sometimes it cannot correctly scrape the content of user tweets.
The Twitter crawler service used by [wordware.ai](https://www.wordware.ai/) mentioned earlier is **Tweet Scraper V2**, but the subscription for the hosted platform **apify** is \$49 per month.
## Links
* [X@dify\_ai](https://x.com/dify_ai)
* Dify's repo on GitHub: [https://github.com/langgenius/dify](https://github.com/langgenius/dify)
# Lesson 1: What is a Workflow?
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-01
## 👋 Welcome to Dify 101
We are going to take you from Zero to Hero. By the end of this course, you will build your very own Advanced AI Email Assistant.
Let's leave coding behind for a second and talk about cooking.
Imagine you want to cook a dish that you haven't made before. To make that happen, you need a **Recipe**. A recipe is just like a workflow! It tells you exactly what to do, in what order, to get the dish you want.
## Meet Workflow
In Dify, you are the head chef who writes a Recipe for the AI to follow. Here're the things you need to prepare beforehand:
1. Input (Ingredients): The information you give the AI. This could be a user's question, a PDF document, or a messy email draft.
2. Process (Instructions): The steps you force the AI to take. For example: First, summarize this text. Next, translate it into Spanish. Finally, format it as a LinkedIn post.
3. Output (The Dish): The final result the AI hands back to you.
To sum up, a workflow is a flowchart that asks AI to complete tasks in a specific order.
This is a Smart ID Scanner workflow. Its job is to extract the information on front and back of an ID card, then send these texts back to you.
<Frame>
<img alt="Workflow Example" />
</Frame>
### Node
Let's have a closer look of the workflow above. That whole process is simply made up of a few connected steps: **Uploading the image, Extracting the information, and Combining the results**.
Each of these steps is called a **Node**.
Think of them like runners in a relay race: each node has a specific task. Once it finishes its turn, it passes the baton to the next node in line.
Dify offers you a box of ready-to-use nodes, such as the LLM, Knowledge Retrieval, If/Else, Tools, etc.
You can connect these nodes just by dragging and dropping—it's like building with the Lego blocks! You can easily snap them together to create a powerful automated workflow.
## It's Your Turn
1. Go [Dify](https://dify.ai/) and click **Get Started** in the upper right corner.
2. Click on Explore. This is a library which collects different workflow of different scenarios.
<Frame>
<img alt="Explore" />
</Frame>
3. Pick a template that looks like a right fit for you. Don't worry if you don't understand every setting yet—just look at how the nodes are connected.
# Lesson 2: Head and Tail (Start & Output Node)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-02
In the last lesson, we compared a Workflow to a Recipe. Today, we are stepping into the professional kitchen to prep our ingredients (Start) and get our serving plates ready (Output).
## Create the App
<Steps>
<Step title="Create from Blank">
Click on **Studio** at the top of the screen. Under Create App on the left, click **Create from Blank**.
<Frame>
<img alt="Create the App" />
</Frame>
</Step>
<Step title="Configure App Type">
Select **Workflow** as the app type, fill up **App Name & Icon**, then click **Create**.
<Frame>
<img alt="App Name & Icon" />
</Frame>
</Step>
<Step title="Choose Start Node Type">
Click User Input, and you'll see a new popup window. There are two options here that decide how your app starts running:
* **User Input**
This is **Manual Mode**. The workflow only starts working when you (the user) type something into the chat box.
Best for: Most AI apps. For example, chatbots, writing assistants, translation, etc.
* **Trigger**
This is **Automatic Mode**. It runs automatically based on a signal (like 8:00 AM every morning, or a specific event).
Best for: Repetitive task that runs on a specific time, or run this workflow after a task is completed else where. For example, daily news summary.
<Frame>
<img alt="Trigger" />
</Frame>
</Step>
</Steps>
## Meet the Orchestration Canvas
After selecting the Start node, you will see a large blank area. This is your orchestration canvas where you will design, build, and test your workflow.
<Frame>
<img alt="Orchestration Studio" />
</Frame>
Remember the Nodes we learned in Lesson 1? The user input node you see on the canvas now is where everything begins.
Every complete workflow relies on a basic skeleton: the Start Node (The Head) and the Output Node (The Tail).
## The Start Node
<Frame>
<img alt="Start Node" />
</Frame>
The Start Node is the only entrance to your entire workflow. It's like the Prep Ingredients step in cooking. Its job is to define what information the workflow needs to receive from the user to get started.
We just selected **User Input** as our Start Node.
### Core Concept: Variables
Inside the Start Node, you will see the word **Variable**. Don't panic! You can think of a variable as a **Storage Box with a Label**.
Each box is designed to hold a specific type of information:
For example, if you are building a Travel Planner, you need the user to provide two pieces of information: `Destination` and `Travel Days`.
User A might want to go to Japan for 5 days. User B might want to go to Paris for 3 days.
Every user provides different content, so every time the app runs, the stuff inside these boxes changes.
This is the meaning of a Variable—digging a hole for the user to fill, helping your workflow to handle different requests flexibly every time.
## The End Node (Output)
<Frame>
<img alt="Output" />
</Frame>
This is the finish line of the workflow. Think of it as Serving the Dish and it defines what the user actually sees at the very end.
For example, remember that Travel Planner we talked about? If the user inputs Destination: Paris and Duration: 5 Days in the User Input Node. The Output Node is where the system finally hands over the result: Here is your complete 5-Day Itinerary for Paris.
To sum up, the Start Node and End Node define the basic input and output, shaping the skeleton of your app.
## Hands-On Practice: Start Building an AI Email Assistant
Let's build the basic framework for an AI Assistant that helps you write emails.
<Steps>
<Step title="Create the App">
You can either:
* Continue on the canvas you just opened, or
* Go back to Studio → Create Blank App → select Workflow, and name it Email Assistant (Remember to select **User Input** in the popup!)
</Step>
<Step title="Configure the Start Node (Prep Ingredients)">
If you need AI to help you with a email reply, what information do you need to give it?
That's right: usually the Customer's Name and the Original Email Content.
1. Click on the **Start** node. In the panel on the right, look for **Input Field** and click the **+** button.
<Frame>
<img alt="User Input Field" />
</Frame>
2. In the popup, we will create two variables (two storage boxes):
**Variable 1 (For the Customer Name)**
<Frame>
<img alt="Add First Variable" />
</Frame>
* Field Type: Text (Short Text)
* Variable Name: `customer_name`
* Label Name: Customer Name
* Keep other options as default
**Variable 2 (For the Email Content)**
<Frame>
<img alt="Add Second Variable" />
</Frame>
* Field Type: Click the dropdown and select **Paragraph** (Since emails are usually long, a Paragraph box is bigger and holds more text)
* Variable Name: `email_content`
* Label Name: Original Email
* Max Length: Manually change this to **2000** to ensure it fits long emails
<Tip>
**Variable Name vs. Label Name**
You might notice we had to fill in two names. What's the difference?
* **Variable Name**: This is the ID card for the system. It must be unique, use English letters, and cannot have spaces.
* **Label Name**: This is the Label for the users. You can name it with any language (English, Chinese, etc.). It will be shown on the screen.
</Tip>
</Step>
<Step title="Create the End Node (Set the Goal)">
Right-click anywhere on the blank white space of the canvas. Select **Add Node** and select **Output** from the list.
<Frame>
<img alt="Create the End Node" />
</Frame>
</Step>
</Steps>
Here's everything on your canvas: a **Start Node** ready to receive a name and an email, and an **Output Node** waiting to send the final result.
<Frame>
<img alt="Start Node and Output" />
</Frame>
We have successfully built basic frame of the workflow. The empty space in the middle is where we will place the LLM (AI Brain) Node in the next lesson to process this information.
## Mini Challenge
**Task**: If you needed to create a Travel Plan Generator, what variables should the Start Node include?
<Tip>
Try exploring the Field Types in **Add Variable**.
</Tip>
# Lesson 3: The Brain of the Workflow (LLM Node)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-03
<Frame>
<img alt="LLM Node" />
</Frame>
In Lesson 2, we set up the Ingredients (Start Node) and the Serving Plate (Output Node).
If the Start Node is the prep cook, the LLM Node is the Master Chef. It is the brain and core of your workflow.
It handles all the thinking, analyzing, and creative writing. Whether you want to summarize an article, write code, or draft an email, this is the node that does the heavy lifting.
## Configure the Model
Before getting started, we need to connect to a model provider.
<Steps>
<Step title="Open Integrations">
Go to **Integrations** > **Model Provider**.
<Frame>
<img alt="Model Provider" />
</Frame>
</Step>
<Step title="Install OpenAI Provider">
Find OpenAI, and click **Install**.
<Frame>
<img alt="Choose OpenAI" />
</Frame>
<Frame>
<img alt="Install OpenAI" />
</Frame>
</Step>
<Step title="Return to the Canvas">
Once installed, you are ready to go! Click **ESC** (or the **X**) in the upper right corner to return to your canvas.
</Step>
</Steps>
## Understand the Tags
A pastry chef is great at cakes but terrible at sushi. Similarly, different AI models have different strengths.
When selecting a model in Dify, you will see tags next to their names. Here's how to read them so you can pick the right one for you.
<AccordionGroup>
<Accordion title="CHAT (The Conversationalist)">
This is the bread and butter of AI. It's best for:
* Dialogue
* Writing articles
* Summarizing text
* Answering questions
</Accordion>
<Accordion title="128K (The Great Memory)">
This number represents the **Context Window**. You can think of it as short-term memory.
Here, K stands for thousand. **128K** means the model can hold 128,000 tokens (roughly equals to a word or a syllable). The bigger the number is, the better its memory is.
<Info>
If you need to analyze a massive PDF report or a whole book, you need a model with a big number here.
</Info>
</Accordion>
<Accordion title="Multi-modal (The Evolved Senses)">
Modal just means **Type of Information**. Most early AI models could only read text. Multi-modal models are evolved—they have senses like eyes and ears.
**VISION (The Eyes)**
Models with this tag can do more than read; they can see! You can upload a photo of a sunset and ask, What colors are in this? or upload a picture of your fridge ingredients and ask, What can I cook with this?
**AUDIO (The Ears)**
Models with this tag can hear. You can upload an audio recording of a meeting or a lecture, and the model can transcribe it into text or write a summary for you.
**VIDEO (The Movie Analyst)**
These models can watch and understand video content. They can analyze what is happening in a video clip, just like a human watching a movie.
**DOCUMENT (The Reader)**
These models are expert readers. Instead of copying and pasting text, you can just upload a file (like a PDF or Word document). The model will read the file directly and answer questions based on what is written inside.
</Accordion>
</AccordionGroup>
For our Email Assistant, the LLM with the **CHAT** tag is exactly what we need.
## Hands-On 1: Add the LLM Node
Let's put the brain into our workflow.
<Steps>
<Step title="Open your App">
Go back to the **AI Email Assistant** workflow we created in Lesson 2.
</Step>
<Step title="Add the Node">
Right-click in the empty space between Start and Output node. Click on the new **LLM** block. In the right-side panel, look for **Model**. Select **gpt-4o-mini**.
<Frame>
<img alt="Add the Node" />
</Frame>
</Step>
<Step title="Connect the Nodes">
Drag a line from the Start node to the LLM node. Drag a line from the LLM node to the Output node. Your flow should look like this: **Start → LLM → Output**.
<Frame>
<img alt="Connect the Nodes" />
</Frame>
</Step>
</Steps>
Now we need to tell LLM exactly what to do by sending instructions which is called a **Prompt**.
<Frame>
<img alt="Add Prompt" />
</Frame>
### Key Concept: The Prompt (The Instructions)
**What is a Prompt?** Think of the Prompt as the specific note you attach to the order ticket. It tells the AI exactly **what to do** and **how to do it**.
The most critical part is the ability to use **Variables** from the Start Node directly within your Prompt. This allows the AI to adapt its output based on the different raw materials you provide each time.
In Dify, when you insert a variable like `customer_name` into the prompt, you are telling the AI: Go and look in the box labeled Customer Name and use the text inside.
## Hands-On 2: Write the Prompt
Now, let's apply this. We are going to write a prompt that mixes instructions with our variables.
<Steps>
<Step title="Draft the Instructions">
Click the LLM Node to open the panel and find the **system** box. **System instructions** set the rules for how the model should respond—its role, tone, and behavioral guidelines.
Let's start by writing out the instructions. You can copy and paste the text below.
```plaintext wrap theme={null}
You are a professional customer service manager. Based on the customer's email, please draft a professional reply.
Requirements:
1. Start by addressing the customer name with a friendly tone.
2. Thank them for their email.
3. Let them know we have received it.
4. Sign off as Anne.
```
</Step>
<Step title="Add User Messages">
User messages are what you send to the model—a question, request, or task for the model to work on.
In this workflow, the customer's name and the email content change every single time. Instead of typing them out manually, we add Variables in user messages.
1. Click **Add Message** button below system box.
2. In the User Message box, type **customer name**:.
3. Press `/` on your keyboard.
4. The Variable Selection menu pops out, and click `customer_name`.
5. Press Enter to start a new line, and type **email content:.** Then, Press the / key again and click on `email_content`.
<Frame>
<img alt="Add User Message" />
</Frame>
<Tip>
You don't need to type out those curly brackets manually! Just hit `/`, then pick your variable from the menu.
</Tip>
4. Finally, your final Prompt will look like this:
<Frame>
<img alt="Final Prompt" />
</Frame>
</Step>
</Steps>
<Check>
**Hooray!** You've finished your first AI workflow in Dify!
</Check>
## Run and Test
The ingredients are prepared, the chef is stand-by, and the instructions are ready. But does the dish taste good? Before we serve it to the customer, let's do a recipe testing.
Testing is the secret sauce to a stable workflow. It helps us catch those sneaky little issues before they are put into work.
### Quick Concept: The Checklist
Think of the **Checklist** as your workflow's personal Health Check Doctor.
It monitors your work in real-time, automatically spotting incomplete settings or mistakes (like a node that isn't connected to anything).
Glancing at the Checklist before you hit **Publish** button is the best way to catch unnecessary errors early.
### Hands-On 3: Test & Debug
<Steps>
<Step title="The Pre-flight Check">
Look at the top right corner of your canvas. Do you see the **Checklist** icon with a little number **1** on it? This is Dify telling you: Wait a second! There's one small thing missing here\_.\_
<Frame>
<img alt="Checklist" />
</Frame>
</Step>
<Step title="Analyze the Warning">
Click on it, and you will see a warning: **output variable is required**. It means that the output node receives nothing.
Imagine your Head Chef (the LLM) has finished cooking the food, but the Waiter (the Output Node) has empty hands.
</Step>
<Step title="Fix the Issue">
1. Click on the **Output Node**
2. Look for **Output Variable** and click the **Plus (+)** icon next to it
3. Type `email_reply` in the **Variable Name** field
4. Select the value: Click the variable selector and choose `{x} text` from the LLM Node
<Frame>
<img alt="Fix the Issue" />
</Frame>
</Step>
<Step title="Make a Test Run">
Now, there's no pop-up number on checklist. Let's do a test run.
Click **Test Run** at the top right corner of the canvas. Enter the customer's name and the email, then click **Start Run**.
<Frame>
<img alt="Test Run" />
</Frame>
<CodeGroup>
```text Sample Email for Testing theme={null}
Customer Name: Amanda
Original Email:
Hi there,
I'm writing to ask for more information about Dify. Could you please tell me more on it?
Best regards,
Amanda
```
</CodeGroup>
</Step>
<Step title="Success!">
This time, you will see green checkmarks ✅ on each of the nodes and the generated reply from AI.
</Step>
</Steps>
<Check>
**Great job!**
You didn't just build a workflow, but also know how to use the checklist and check before it goes live.
</Check>
## Mini Challenge
Use the same structure to build a travel planner.
<Tip>
Explore the **Prompt Generator** to help you craft better prompts!
<Frame>
<img alt="Prompt Generator" />
</Frame>
</Tip>
# Lesson 4: The Cheat Sheet (Knowledge Retrieval)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-04
In the previous lessons, our AI email assistant can draft basic emails. But what if a customer asks about specific pricing plans or refund policy, the AI might start Hallucinating—which is a fancy way of saying it's confidently making things up.
How do we stop the AI from hallucination? We give it a Cheat Sheet.
## What is Retrieval Augmented Generation (RAG)
The technical name for this is RAG (Retrieval-Augmented Generation). Think of it as turning the AI from a chef who memorizes general recipes into a chef who has a Specific Cookbook right on the counter.
It happens in three simple steps:
**1. Retrieval (Find the Recipe)**
When a user asks a question, the AI flips through your Cookbook (the files you uploaded) to find the most relevant pages.
Example: Someone asks for Grandma's Special Apple Pie. You go find that specific recipe page.
**2. Augmentation (Prepare the Ingredients)**
The AI takes that specific recipe and puts it right in front of its eyes so it doesn't have to rely on memory.
Example: You lay the recipe on the counter and get the exact apples and cinnamon ready.
**3. Generation (The Baking)**
The AI writes the answer based only on the facts it just found.
Example: You bake the pie exactly as the recipe says, ensuring it tastes like Grandma's, not a generic store-bought version.
## The Knowledge Retrieval Node
Think of this as placing a stack of reference materials right next to your AI Assistant. When a user asks a question, the AI first flips through this Cheat Sheet to find the most relevant pages. Then, it combines those findings with the user's original question to think of the best answer.
In this practice, we will use the Knowledge Retrieval node to provide our AI Assistant with official Cheat Sheets, ensuring its answers are always backed by facts!
### Hands-On 1: Create the Knowledge Base
<Steps>
<Step title="Enter the Library">
Click **Knowledge** in the top navigation bar and click **Create Knowledge**.
<Frame>
<img alt="Create Knowledge" />
</Frame>
In Dify, you can sync from Notion or a website, but for today, let's upload a file from your device. Click [here](https://drive.google.com/file/d/1imExB0-rtwASbmKjg3zdu-FAqSSI7-7K/view) to download Dify Intro for the upload later.
</Step>
<Step title="Upload the File">
Click **Import from file**. Then, select the file we just downloaded for upload.
<Frame>
<img alt="Import from File" />
</Frame>
</Step>
<Step title="The 'Chopping' Step (Text Segmentation)">
High-relevance chunks are crucial for AI applications to provide precise and comprehensive responses. Imagine a long book. It's hard to find one sentence in 500 pages. Dify chops the book into different Knowledge Cards so it can find the right answer faster.
**Chunk Structure**
Here, Dify automatically splits your long text into smaller, easier-to-retrieve chunks. We'll just stick with the General Mode here.
<Frame>
<img alt="Chunk Structure" />
</Frame>
**Index Method**
* **High Quality**: Use LLM model to process documents for more precise retrieval helps LLM generate high-quality answers
* **Economical**: Using 10 keywords per chunk for retrieval, no tokens are consumed at the expense of reduced retrieval accuracy
<Frame>
<img alt="Index Method" />
</Frame>
</Step>
<Step title="Retrieval Settings">
After the document has been processed, we need to do one final check on the retrieval settings. Here, you can configure how Dify looks up the information.
In Economical mode, only the inverted index approach is available.
<Frame>
<img alt="Retrieval Setting" />
</Frame>
* **Inverted Index**
This is the default structure Dify uses. Think of it like the Index at the back of a book—it lists key terms and tells Dify exactly which pages they appear on.
This allows Dify to instantly jump to the right knowledge card based on keywords, rather than reading the whole book from start.
* **Top K**
You'll see a slider set to 3. This tells Dify: When the user asks a question, find the top 3 most relevant Knowledge Cards from the cookbook to show the AI.
If you set it higher, the AI gets more context to read, but if it's too high, it might get overwhelmed with too much information.
For now, let's just keep the default settings—they are already perfectly suited for our needs.
<Frame>
<img alt="Document Processing" />
</Frame>
</Step>
<Step title="Save and Process">
Click **Save and Process**. Your knowledge base is ready!
</Step>
</Steps>
<Check>
**Awesome!**
You have successfully created your first Knowledge Base. Next, we'll use this Knowledge Base to upgrade our AI Email Assistant.
</Check>
### Hands-On 2: Add the Knowledge Retrieval Node
<Steps>
<Step title="Add the Node">
1. Go back to your Email Assistant Workflow.
2. Hover over the line between the Start and LLM nodes.
3. Click the **Plus (+)** icon and select the **Knowledge Retrieval** node.
<Frame>
<img alt="Add Knowledge Retrieval Node" />
</Frame>
</Step>
<Step title="Connect Knowledge Base">
1. Click the node, and head to the right panel.
2. Click the **plus (+)** button next to **Knowledge** to add knowledge.
<Frame>
<img alt="Add Knowledge" />
</Frame>
3. Choose **What's Dify**, and click **Add**.
<Frame>
<img alt="Select Knowledge" />
</Frame>
</Step>
<Step title="Configure Query Text">
Now the knowledge base is ready, how can we make sure that AI is looking through the knowledge base to search the answer with the email?
Stay at the panel, navigate to **Query text** above, and select `email_content`.
By doing this, we are telling AI: Take the customer's message and use it as a search keyword to flip through our cookbook and find the matching info. Without a query, the AI is just staring at a closed book.
<Frame>
<img alt="Query Text" />
</Frame>
</Step>
</Steps>
In this way, the Email Assistant will use the customer's original email as a search keyword to find the most relevant answers in the Knowledge Base.
### Hands-On 3: Upgrade the Email Assistant
Now, the knowledge base is ready. We need to tell the LLM node to actually read the knowledge as context before generating the reply.
<Steps>
<Step title="Add Context">
1. Click the **LLM Node**. You'll see a new section called **Context**.
2. Click it and select **result** from the Knowledge Retrieval node.
<Frame>
<img alt="Add Context" />
</Frame>
</Step>
<Step title="Update the Prompt">
We need to tell the AI to generate reply based on the context.
In **System**, add additional requirement **Generate response based on** `/` and select **Context**.
<Frame>
<img alt="Update Prompt" />
</Frame>
</Step>
</Steps>
**Whoo!** You've just completed the most challenging part. Now, your email assistant has a knowledge base to check when generating responses. Let's see how it works.
Feel free to use the sample texts below to do the testing.
<CodeGroup>
```text Sample Email for Testing theme={null}
Customer Name: Amanda
Original Email:
Hi,
What does the name 'Dify' actually stand for, and what can it do for my business?
Best regards,
Amanda
```
</CodeGroup>
Check on the result and you'll find that instead of a generic guess, the AI will look at the knowledge base and explain what Dify stands for.
<Frame>
<img alt="Test Result" />
</Frame>
## Mini Challenge
1. What happens if a customer asks a question that isn't in the knowledge base?
2. What kind of information could you upload as a knowledge base?
3. Explore Chunk Structure, Index Method, and Retrieval Setting.
# Lesson 5: The Crossroads of Your Workflow (Sorting and Executing)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-05
Right now, our Email Assistant treats every message following the same path of the workflow. That's not smart enough. An email asking about Dify's price should be handled differently than an email on bug reporting.
To make our assistant truly intelligent, we need to teach it how to Read the Room. We're going to set up a Crossroads that sends different types of emails down different tracks.
## The If/Else Node
<Frame>
<img alt="If/Else Node" />
</Frame>
If/Else node is just like a traffic light. It checks a condition (like Does this email mention pricing? ) and sends the flow left or right based on the result.
### Hands-On 1: Set up the Crossroads
Let's upgrade our assistant so it can tell the difference between Dify-related emails and Everything else.
<Steps>
<Step title="Insert the Node">
Hover over the line between the Start and Knowledge Retrieval nodes. Click the **Plus (+)** icon and select the **If/Else** node.
</Step>
<Step title="Set the Rules">
1. Click the node to open the panel
2. Click **+ Add Condition** in the IF section. Choose the variable: `{x} email_content`
<Frame>
<img alt="Add Condition" />
</Frame>
3. The Logic: Keep it as **Contains**. Type **Dify** in the input box
<Frame>
<img alt="Contains" />
</Frame>
Now, the complete logic for the IF branch is: `If the email content contains the word Dify`.
</Step>
</Steps>
<Info>
**Understanding the Traffic Light**
When setting conditions, Dify offers several ways to judge information, much like the different signals at a crossroads:
* **Is / Is Not**
Like a perfect key for a lock. The content must match your value exactly.
* **Contains / Not Contains**
Like a magnifying glass. It checks if a specific keyword exists anywhere in the text. This is what we are using today.
* **Starts with / Ends with**
Check if the text begins or ends with specific characters.
* **Is Empty / Is Not Empty**
Check if the variable has any content. For example: Checking if a user actually uploaded an attachment. Understanding these helps you set accurate and flexible rules, building a much smarter workflow!
</Info>
### Hands-On 2: Plan Different Paths
Now that we have the crossroad here, we need to decide what happens on each road.
#### A. The Dify-Related Email Track (IF Branch)
Click the **plus (+)** icon on the right side of the IF branch, drag out a line, and connect it to **Knowledge Retrieval** node.
What this means: When the email contains the word Dify, the flow will execute the professional reply process we built in the last lesson (which looks up information in the Knowledge Base).
<Frame>
<img alt="Connect IF Branch" />
</Frame>
#### B. The Unrelated Email Track (ELSE Branch)
For emails that are not related or mention Dify, we want to create a simple, polite, and general reply process.
<Steps>
<Step title="Create a new Node">
Click the **(+)** next to ELSE and select a new **LLM Node (LLM 2)**
</Step>
<Step title="Add Prompt to this LLM node">
Copy and paste the prompt below
```plaintext wrap theme={null}
You are a professional customer service manager. Based on the customer's email, kindly inform the user that no relevant information was found and provide relevant guidance.
Requirements:
1. Address the customer name in a friendly tone.
2. Thank them for their letter.
3. Keep the tone professional and friendly.
4. Sign off as "Anne."
```
</Step>
<Step title="Add User Message">
1. Click **Add Message** button below system.
2. In the User Message box, type **customer name**:.
3. Press `/` on your keyboard.
4. You can see the Variable Selection menu pops out, and click `customer_name`.
5. Press Enter to start a new line, and type **email content**:
6. Press the / key again and click on `email_content`.
<Frame>
<img alt="Prompt for LLM 2" />
</Frame>
</Step>
</Steps>
Now we have two tracks generating two different replies. Imagine if we had 10 tracks, our workflow would look like a messy plate of spaghetti.
To keep things clean, we use a Variable Aggregator. Think of it as a Traffic Hub where all the different roads merge back into one main highway.
## Variable Aggregator
<Frame>
<img alt="Variable Aggregator" />
</Frame>
Variable Aggregator is like a traffic hub where all the different roads merge back into one main highway.
### Hands-On 3: Add Variable Aggregator
<Steps>
<Step title="Add the Aggregator">
1. Select the connection line between the End Node and the LLM node and delete it.
2. Right-click on the canvas, select **Add Node**, and choose the **Variable Aggregator** node.
<Frame>
<img alt="Add Variable Aggregator" />
</Frame>
</Step>
<Step title="Merge the Paths">
Connect LLM and LLM 2 node to the Variable Aggregator.
</Step>
<Step title="Assign the Output">
1. Click the Variable Aggregator node.
2. Click the **plus (+)** icon next to **Assign Variables**.
3. Select the **text** from LLM 1 AND the **text** from LLM 2.
<Frame>
<img alt="Assign Variable" />
</Frame>
Now, no matter which LLM node generates the response, the Variable Aggregator node gathers the content and hands it to the Output Node.
</Step>
<Step title="The Final Step">
1. Connect the Variable Aggregator to the Output node.
2. Update the Output Variable to the Variable Aggregator's result instead of previous LLM results.
<Frame>
<img alt="Update Output Variable" />
</Frame>
Here's how the workflow looks:
<Frame>
<img alt="Final Workflow" />
</Frame>
</Step>
<Step title="Test and Run">
Click **Test Run**, enter a customer name, and try testing with inputs that both include and exclude the keyword Dify to see the different results.
</Step>
</Steps>
## Mini Challenge
For business inquiry emails, how should we edit this workflow to generate proper response?
<Tip>
Don't forget to update knowledge base with business-related files.
</Tip>
# Lesson 6: Handle Multiple Tasks (Parameter Extraction & Iteration)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-06
Imagine you get an email saying:
> Hi! What exactly is Dify? Also, which models does it support? And do you have a free plan?
If we send this to our current AI assistant, it might only answer the first question or give a vague response to both.
We need a way to identify every question first, and then loop through our Knowledge Base to answer them one by one.
## Parameter Extractor
<Frame>
<img alt="Parameter Extractor" />
</Frame>
You can take Parameter Extractor as a highly organized scout. It reads a paragraph of texts (like an email) and picks out the specific piece of information you asked for, putting them into a neat and organized list.
### Hands-On 1: Add Parameter Extractor
Before we upgrade the email assistant, let's remove these nodes: Knowledge Retrieval, If/Else, LLM, LLM 2, and Variable Aggregator.
<Steps>
<Step title="Add the Node">
Right after the Start node, add the **Parameter Extractor** node.
<Frame>
<img alt="Add Parameter Extractor" />
</Frame>
</Step>
<Step title="Set the Input">
Click Parameter Extractor, and in the **Input Variable** section on the right panel, choose `email_content`.
<Frame>
<img alt="Set the Input" />
</Frame>
Since AI doesn't automatically know which specific information we need from the email, we must tell it to collect all the questions.
</Step>
<Step title="Add Extract Parameter">
Click the **plus (+)** icon next to **Extract Parameters** to start defining what the AI should look for. Let's call it `question_list`.
<Frame>
<img alt="Add Extract Parameter" />
</Frame>
<Info>
**Parameter Types**
If Parameter Extractor is a scout, then Type is the bucket they use to carry the info. You need the right bucket for the right information.
**Single Items (The Small Buckets)**
* **String (Text)**: For a single piece of text, e.g. customer's name
* **Number**: For a single digit, e.g. order quantity
* **Boolean**: A simple Yes or No (True/False), good for a judgement result or a decision
**List Items (The Arrays)**
* **Array\[String]**: Array means List, and String means Text. So, `Array[String]` means we are using a basket that can hold multiple pieces of text—like all the separate questions in an email
* **Array\[Number]**: A container that holds different numbers, e.g. a list of prices or commodities
* **Array\[Boolean]**: Used to store multiple Yes/No judgment results. For example, checking a list containing multiple to-do items and returning whether each item is completed, such as `[Yes, No, Yes]`
* **Array\[Object]**: An advanced folder that holds sets of data (like a contact list where each entry has a Name and a Phone Number)
</Info>
</Step>
<Step title="Finish Adding Extract Parameter">
1. Based on our needs, choose `Array[String]` for the email content.
2. Add description for providing additional context. You can write: All the questions raised by the user in the email. After that, click **Add**.
<Frame>
<img alt="Finish Adding Extract Parameter" />
</Frame>
</Step>
<Step title="Add Instructions">
In the **Instructions** box below the extracted parameters, type a clear command to tell the AI how to act.
For example: Extract all questions from the email, and make each question as a single item on the list.
</Step>
</Steps>
By doing this, the node will be able to find all the questions in the email. Now that our scout has successfully gathered the Golden Nuggets, we need to move to the next step: teaching the AI to process each question.
## Iteration
<Frame>
<img alt="Iteration" />
</Frame>
With iteration, your assistant has a team of identical twins. When you hand over a list (like questions in the mail list), a twin appears for every single item on that list.
Each twin takes their assigned item and performs the exact same task you've set up, ensuring nothing gets missed.
### Hands-On 2: Set up Iteration Node
<Steps>
<Step title="Add the Node">
1. Add an Iteration node after the Parameter Extractor.
2. Click on the Iteration node and navigate to the Input panel on the right.
3. Select `{x} question_list` from the Parameter Extractor. Leave the output variable blank for now.
<Frame>
<img alt="Add Iteration Node" />
</Frame>
**Advanced Options in Iteration**
In the Iteration panel, you'll see more settings. Let's have a quick walk-through.
<Frame>
<img alt="Advanced Options in Iteration" />
</Frame>
**Parallel Mode**: OFF (Default)
* When disabled, the workflow processes each item in the list one after another (finish Question 1, then move to Question 2).
* When enabled, the workflow attempts to process all items in the list simultaneously (similar to 5 chefs cooking 5 different dishes at the same time).
**Error Response Method**: Terminate on error by default.
* **Terminate**: This means if any single item in the list (e.g., the 2nd question) fails during the sub-process, the entire workflow will stop immediately
* **Ignore Error and Continue**: This means even if the 2nd question fails, the workflow will skip it and move on to process the remaining questions
* **Remove Abnormal Output**: Similar to ignore, but it also removes that specific failed item from the final output list results
Back to the workflow, you'll see a sub-process area under the Iteration node. Every node inside this box will run once for every question.
</Step>
<Step title="Add Knowledge Retrieval Node">
1. Inside the Iteration box, add a Knowledge Retrieval node.
2. Set the query text to `{x} item`. In Iteration, item always refers to the question that is currently being processed.
<Frame>
<img alt="Add Knowledge Retrieval Node and Set Query Text" />
</Frame>
</Step>
<Step title="Add LLM Node">
1. Add an LLM node after Knowledge Retrieval.
2. Configure it to answer the question based on the retrieved context.
<Tip>
Remember Lesson 4? Use those Prompt skills and don't forget context!
</Tip>
Feel free to use the prompt below:
**System**:
```plaintext wrap theme={null}
You are a professional Dify Customer Service Manager. Please provide a response to questions strictly based on the `Context`.
```
**User**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="Add LLM Prompt" />
</Frame>
Since the iteration node generates an answer for each individual question, we need to gather all these answers to create one complete reply email.
</Step>
<Step title="Set Iteration Output">
1. Click the Iteration node.
2. In the **Output Variable**, select the variable representing the LLM's answer inside the loop. Now, the Iteration node will collect every answer and gather them into a new list.
<Frame>
<img alt="Set Iteration Output" />
</Frame>
</Step>
<Step title="Add Final LLM Node">
Finally, connect one last LLM node. This final editor will take all the collected answers and polish them into one professional email.
Don't forget to add prompt in system and user message. Feel free to refer the prompt below.
```plaintext wrap theme={null}
You are a professional customer service assistant. Please organize the answers prepared for customer into a clear and complete email reply.
Sign the email as Anne.
```
**User**:
```plaintext wrap theme={null}
answers: Iteration/{x}output
customer: User Input/{x}customer_name
```
<Frame>
<img alt="Add Final LLM Node" />
</Frame>
</Step>
<Step title="Final Check">
1. Click on the checklist to see if there's any missing spot. According to the notes, we need to connect Output node while fix the invalid variable issue.
2. Connect Output node with LLM 2 node before it, remove its previous variable, then select text in LLM 2 as the output variable.
<Frame>
<img alt="Select Output Variable" />
</Frame>
</Step>
</Steps>
Now, you can write a test email with 3 different questions and check on the generated reply.
## Mini Challenge
What else could Parameter Extractor find?
<Tip>
Try exploring the parameter type in it.
</Tip>
# Lesson 7: Enhance Workflows (Tools)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-07
Our email assistant can now flip through our knowledge base. But what if a customer asks a beyond-knowledge-base question, like: What is in the latest Dify release?
If the knowledge base hasn't been updated yet, the workflow will be at a loss. To fix this, we need to equip it with a Live Search skill!
## Tools
<Frame>
<img alt="Tools" />
</Frame>
Tools are the superpower for your AI workflow.
The [Dify Marketplace](https://marketplace.dify.ai/) is like a supermarket of ready-made tools—searching Google, checking the weather, drawing images, or calculating complex math. You just install and plug them into your workflow with several clicks.
Now, let's continue to upgrade on current workflow.
### Hands-On 1: Upgrade the Sub-process Area in Iteration
We are going to add a new logic to our assistant: Check the Knowledge Base first; if the answer isn't there, go search Google.
To focus on the new logic, let's keep only these nodes: **User input, Parameter Extractor, and Iteration**.
#### Step 1: Knowledge Query and the Judge
<Steps>
<Step title="Enter the Iteration">
1. Click to enter the sub-process area of the Iteration node.
2. Keep Knowledge Retrieval node, and make sure the query variable is `{x} item`.
3. Delete the previous LLM node.
</Step>
<Step title="Add the Judge (LLM Node)">
Add an LLM node right after Knowledge Retrieval node. Its job is to decide if the Knowledge Base info can actually respond to the questions.
* **For Context session**: Select the `Knowledge Retrieval / {x} result Array [Object]` from Knowledge Retrieval
* **System Prompt**:
```plaintext wrap theme={null}
Based on the `Context`, determine if the answer contains enough information to answer the questions. If the information is insufficient, you MUST reply with: "Information not found in knowledge base".
```
* **User Message**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="LLM Settings" />
</Frame>
</Step>
</Steps>
Here's what it looks like on the canvas.
<Frame>
<img alt="Workflow Preview" />
</Frame>
#### Step 2: Setting the Crossroads
<Steps>
<Step title="Add If/Else Node">
After LLM node, let's add If/Else node. Set the rule: If LLM Output **Contains** **Information not found in knowledge base**.
This means, when we can't respond with the information in knowledge base.
<Frame>
<img alt="Add if/Else Node" />
</Frame>
</Step>
<Step title="Add Tool for Searching">
Let's connect a search tool after the IF branch. This indicates that when the knowledge base cannot find relevant answer information, we use web search to find the answers.
1. After the IF node, click plus(+) icon and select Tool.
2. In the search box, type Google. Hover over Google, click Install on the right, and then click Install again in the pop-up window.
<Frame>
<img alt="Install Tool" />
</Frame>
</Step>
<Step title="Install Google Search">
Click Google Search in Google.
<Frame>
<img alt="Install Google Search" />
</Frame>
</Step>
<Step title="Get Your API Key">
Using Google Search for the first time requires authorization—it's like needing a Wi-Fi password.
<Frame>
<img alt="Google Search Setup" />
</Frame>
1. Click API Key Authorization Configuration, then click Get your SerpApi API key from SerpApi. Sign in to get your private API key.
<Note>
Your API Key is your passport to the outside world. Keep it safe and avoid sharing it with others.
</Note>
<Frame>
<img alt="API Key Authorization Configuration" />
</Frame>
2. Copy and paste the API key in SerpApi API key. Click **Save**.
3. Once the API key is successfully authorized, the settings panel shows up immediately. Head to Query string field, and select `Iteration/{x} item`.
<Frame>
<img alt="Add Query String" />
</Frame>
</Step>
<Step title="Configure the Two Paths">
Now, we need different ways to answer depending on which path we're looking at.
**The Search Answer Path**
Add a new LLM node to answer the question based on the search results. Connect it to the Google Search node.
**System**:
```plaintext wrap theme={null}
You are a Web Research Specialist. Based on Google Search, concisely answer the user's questions. Please do not mention the knowledge base in your response.
```
**User Message**:
```plaintext wrap theme={null}
results: GOOGLESEARCH/{x} text
questions: Iteration/{x} item
```
<Frame>
<img alt="Prompt for LLM 2" />
</Frame>
**The Knowledge Searching Path**
After the Else node, add a new LLM node to handle answers based on the knowledge base.
**System**:
```plaintext wrap theme={null}
You are a professional Dify Customer Service Manager. Strictly follow the `Context` to reply to questions.
```
**User Message**:
```plaintext wrap theme={null}
questions: Iteration/{x} item
```
<Frame>
<img alt="Prompt for LLM 3" />
</Frame>
</Step>
<Step title="Combine the Information">
1. In the sub-process (inside the Iteration box), add a Variable Aggregator node that connects both LLM 2 and LLM 3 at the very end.
2. In the Variable Aggregator panel, select the variables `LLM 2/{x}text String` and `LLM 3/{x}text String` as the Assign Variables.
In this way, we're merging the two possible answers into a single path.
<Frame>
<img alt="Variable Aggregator Setup" />
</Frame>
</Step>
</Steps>
This is how the current workflow looks.
<Frame>
<img alt="Workflow Preview 2" />
</Frame>
#### Step 3: The Final Email Assembly
Now that our logic branches have finished processing, let's combine all the answers into a single, polished email.
<Steps>
<Step title="Configure Iteration Output">
Click on the Iteration node, and set `{x}Variable Aggregator/{x}output String` as the output variables.
<Frame>
<img alt="Iteration Output" />
</Frame>
</Step>
<Step title="Connect the Summary LLM">
After the Iteration node, connect a new LLM node to summarize all outputs. Feel free to use the prompt below.
**System**:
```plaintext wrap theme={null}
You are a professional Customer Service Manager. Summarize all the answers of the questions, and organize a clear and complete email reply for the customer.
Do not include content where the knowledge base could not find relevant information.
Signature: Anne.
```
**User Message**:
```plaintext wrap theme={null}
questions: Iteration/ {x} output
customer: User Input / {x} customer_name
```
<Frame>
<img alt="Prompt for LLM 4" />
</Frame>
</Step>
<Step title="Finalize with the Output Node">
After the LLM node, add an End node. Set the output variable as `LLM 4/{x}text String`.
<Frame>
<img alt="Output Setup" />
</Frame>
</Step>
</Steps>
We have now completed the entire setup and configuration of the workflow. Our email assistant can now answer questions based on the Knowledge Base and use Google Search for supplementary answers when needed.
<Frame>
<img alt="Final Workflow Preview" />
</Frame>
Try sending an email with question that definitely isn't in the knowledge base. Let's see if the AI successfully uses Google to find the related answers.
## Mini Challenge
1. What are other conditions you can choose in If/Else node?
2. Browse marketplace to see if you can add another tool for this workflow?
# Lesson 8: The Agent Node
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-08
Let's look back at the upgrades we've made for our email assistant.
* Learned to Read: It can search a Knowledge Base
* Learned to Choose: It uses Conditions to make decisions
* Learned to Multitask: It handles multiple questions via Iteration
* Learned to Use Tools: It can access the Internet via Google Search
These nodes work, but we have had to describe every step in advance. What if we could give the job to an AI teammate that already knows how to reason, use its resources, and improve over time?
Meet your AI teammate: the **Agent**.
## From Workflow to Agentic Workflow
A traditional workflow follows a path designed by its builder. An Agentic workflow combines that dependable structure with an Agent that can decide how to complete a task inside the boundaries you set.
Think of the workflow as the shared operating procedure and the Agent as the teammate performing part of it:
* The **workflow** supplies inputs, order, checks, fallbacks, and outputs.
* The **Agent** works toward a goal, uses its available knowledge and tools, and returns a result.
* The **Agent node** is where that Agent appears in this particular workflow.
The same Agent can be invited into several workflows, or even appear more than once in one workflow. Its core identity and capabilities belong to the Agent. The instructions you add in an Agent node describe only its job at that point in the workflow.
You do not need to install or select a reasoning strategy. The Agent manages its own reasoning loop. Your job is to give it the right assignment, inputs, and expected outputs.
## Agent & Agent Node
There are two ways to add an Agent to a workflow:
* **Invite an Agent**: Reuse an existing Agent that you or your team has already built.
* **Start from Scratch**: Create a one-time Agent directly on the canvas. This is useful for a role that exists only in this workflow. You can save it to **Agents** later if it becomes reusable.
In the earlier lessons, we did not create an agent, so we will start from scratch and this tutorial works from a clean workspace. At the end, you can save it to the **Agents** page and reuse it elsewhere.
After this lesson, the whole workflow is: `Start → Knowledge Retrieval → Product Support Agent → Output`
## Hands-on 1: Create an Agent
Our goal is to replace the entire manually orchestrated middle section with one Agent. The Agent will receive the complete customer email, identify and answer every question, and return one coherent email body.
<Steps>
<Step title="Remove Extra Nodes">
Starting from Lesson 7's workflow, delete the Parameter Extractor and the Iteration node (everything inside it goes with it), leaving only Start and Output.
</Step>
<Step title="Add Knowledge Retrieval">
After Start, click **+** and add a Knowledge Retrieval node. Select the Dify product Knowledge Base used in the previous lessons.
<Frame>
<img alt="Add a Knowledge Retrieval Node" />
</Frame>
</Step>
<Step title="Add an Agent Node">
After Knowledge Retrieval, click **+**, choose **Agent**, and select **Start from Scratch**.
<Frame>
<img alt="Add an Agent Node and Start from Scratch" />
</Frame>
This opens the agent's setup over the workflow canvas:
* The **Configure** panel on the left contains the model, prompt, skills, files, tools, etc. You can set them up manually.
* **Build** on the right lets you build your agent by chatting, and the configuration is filled automatically.
* **Preview** lets you try the Agent before returning to the workflow.
<Frame>
<img alt="The Agent Setup with Build Mode" />
</Frame>
</Step>
<Step title="Connect to the Required Resources">
Before entering Build mode, do a quick setup:
* **Model**: select a compatible model if the current model is missing or marked incompatible.
* **Tools**: add Google Search.
</Step>
<Step title="Build the Agent by Chatting">
In Build mode, enter the following request.
```text wrap theme={null}
Create a Dify Product Support Agent.
Configure the Agent to use context provided by the workflow first and search only when that context is insufficient or current information is required.
Do not create duplicate search capabilities.
```
<Frame>
<img alt="Describe the Agent in Build Mode" />
</Frame>
After the build finishes, the agent has set up its own assets:
* `product-support`: an embedded skill carrying the Agent's support behavior and source-use rules.
* `build_note.md`: a note recording what was set up during the build chat.
</Step>
<Step title="Add the Main Prompt">
After you click **Apply**, Build mode closes and the **Configure** panel becomes editable again. Add the following instruction to **Prompt**:
```text wrap theme={null}
Answer accurately using the context provided with each assignment. Treat that context as the primary source. Use Google Search only when the context is insufficient, irrelevant, or outdated.
```
The generated skill defines the Agent's reusable product-support expertise. The prompt adds a clear rule for when the Agent should use Google Search.
<Frame>
<img alt="The Generated Skill and Prompt in Configure" />
</Frame>
</Step>
<Step title="Preview the Agent">
Switch to **Preview** and ask a Dify product question to confirm the agent answers concisely and searches only when necessary.
When the setup looks correct, close it and return to the workflow canvas.
</Step>
</Steps>
<Check>
🎉 The Agent is ready now.
</Check>
## Hands-on 2: Assign the Workflow Task
Now the Agent has a reusable role, support expertise, and a search tool. Next, let's give it an assignment of what to do in this workflow.
<Steps>
<Step title="Provide the Email and Retrieved Knowledge">
Select the Agent node. In **Agent task**, describe this step's assignment:
```text wrap theme={null}
Answer every question or request in {{email_content}}.
Use the retrieved product knowledge in {{result}} first.
Combine all answers into one email body.
```
Type `/` to insert `email_content` from User Input and `result` from Knowledge Retrieval, so they arrive as variables rather than plain text.
<Frame>
<img alt="Describe the Assignment in Agent Task" />
</Frame>
</Step>
<Step title="Connect the Output Node">
Click the Output node and set its variable to the Agent's `text` output. This way, the workflow returns the generated email reply.
<Frame>
<img alt="Set the Output to the Agent's Text" />
</Frame>
</Step>
</Steps>
Here comes the final workflow.
<Frame>
<img alt="The Final Four-Node Workflow" />
</Frame>
Click **Test Run** and input a customer email with a few questions. The Agent answers from the retrieved knowledge and searches only when it needs to.
## Optionally Save the Agent
The Product Support Agent is already stored as part of this workflow. You do not need to save it separately to continue to the next lesson.
To reuse it in other workflows: click the Agent node to open its setup, then in **Configure**, click **⋯** and select **Save to Agents**.
<Frame>
<img alt="Save the Agent to Agents" />
</Frame>
Give the agent a name, an icon, and a description.
<Frame>
<img alt="Name the Saved Agent" />
</Frame>
## Mini Challenge
1. Add a requirement that the Agent clearly labels information obtained from an Internet search.
2. Ask one question that cannot be answered from either the retrieved knowledge or Google Search. Confirm that the Agent acknowledges the limitation instead of omitting the question.
# Lesson 9: Layout Designer (Template)
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-09
In Lesson 8, we simplified the workflow to one Product Support Agent.
The content may be accurate and well written, but generated formatting can still vary. A greeting may change, a divider may disappear, or a signature may be phrased differently from one run to the next.
For elements that must remain consistent, we can use a Template node.
## Template
It takes the original data (like your list of answers), follows a strict design template/standards you provide, and generates a perfectly formatted block of text, ensuring consistency every single time.
## Hands-On: Polish the Email Layout
<Steps>
<Step title="Check the Product Support Agent">
Select **Product Support** on the workflow canvas. Its assignment should require it to handle the complete email but return only the substantive body. Add the text below in **Agent task**:
```text wrap theme={null}
Return the body only, without a greeting, divider, or signature.
```
This separation matters: the Agent controls delivery and tone, while the Template controls the fixed layout.
<Frame>
<img alt="Add the Body-Only Rule to Agent Task" />
</Frame>
</Step>
<Step title="Add a Template Node">
Insert a Template node after the Agent node and before Output.
<Frame>
<img alt="Insert a Template Node Before Output" />
</Frame>
</Step>
<Step title="Set the Input Variables">
Open the Template node and add these variables:
* `customer`: `User Input /{x} customer_name`
* `body`: `Agent /{x} text`
Using the Agent's `text` output makes the handoff easy to understand and inspect.
<Frame>
<img alt="Add the Customer and Body Variables" />
</Frame>
</Step>
<Step title="Format the Email with Jinja">
**What is Jinja2?**
In simple terms, Jinja2 is a tool that allows you to format variables (like your list of answers) into a text template exactly how you want. It uses simple symbols to mark where variables go and perform basic logic. With it, we can turn a raw list of data into a neat, standardized text block.
Here, we can put together opening, signatures, and email body to make sure the email is professional and consistent every time.
Copy and paste this exact layout into the Template code box:
```text wrap theme={null}
Hi {{ customer }},
Thank you for reaching out. We are happy to help with your questions.
{{ body }}
---
Best regards,
Dify Support Team
```
The values of `customer` and `body` can change with every workflow run. Everything around them remains fixed. This gives the Agent freedom to write the answer while ensuring that the final email always follows the required layout.
</Step>
<Step title="Update the Output Node">
Open Output. Replace the previous value with the Template node's output.
<Frame>
<img alt="Point the Output at the Template" />
</Frame>
</Step>
</Steps>
Here's the final workflow.
<Frame>
<img alt="The Final Workflow with the Template Node" />
</Frame>
Click **Test Run**. Ask multiple questions in one email. Notice how your final output has a perfectly written custom intro, the LLM's beautifully summarized answers in the middle, and a standard, professional signature at the bottom.
## Mini Challenge
1. Add a conditional fallback when `customer` is empty, such as `Hi there,`.
2. Add a fixed support disclaimer that the Agent cannot change or omit.
# Lesson 10: Publish and Monitor Your AI App
Source: https://docs.dify.ai/en/learn/tutorials/workflow-101/lesson-10
After building and tuning, your Email Assistant is now fully ready. It can read knowledge bases, use search tools, and generate beautifully formatted replies. But right now, it's still sitting inside your Dify Studio and only you can see it.
How do we share it with others? How do we know if it's working correctly when we aren't watching?
It's time for the final two critical steps: Publish and Monitor.
## Publish Your Application
1. Move your mouse to the top right corner of the canvas and click the **Publish** button. You'll see other buttons light up.
<Note>
Whenever you make changes to your workflow, you must click **Publish** > **Publish Update** to save them.
If you don't update, the live version will remain the old one.
</Note>
2. Once published, the grayed-out buttons become clickable.
1. **Share Your App**
Click **Open web app**. Dify automatically generates a web app for you. This is a ready-to-use chat interface for your Email Assistant.
You can send this URL to colleagues or friends. They don't need to log in to Dify to use the email assistant.
<Frame>
<img alt="Web App" />
</Frame>
2. **Run Batch**
If you have 100 emails to reply, copying and pasting them one by one will drag you down.
In Dify, all you need to do is to prepare a CSV file with the 100 emails. Upload it on the **Run Batch** tab. Dify processes all 100 emails automatically and gives you back a spreadsheet with all the generated replies.
Since we set specific variables (like `email_content`), your CSV must match that format. Dify provides a template you can download to make this easy.
<Frame>
<img alt="Download Template" />
</Frame>
3. **Others**
* **Access Point**: Manage every way your app can be reached—the web app, the API, an MCP server, and triggers. If you know coding, get an API Key here to integrate this workflow directly into your own website or mobile app
* **Workflow as Tool**: Package your workflow as a tool so other Agents can use your Email Assistant
## Monitor Your App
As the creator, you need to understand the status of this assistant. By monitoring and using logs, you can check the health, performance, and costs.
### The Command Center: Monitoring
Click **Monitoring** on the left sidebar to see how your app is performing.
| Name | Explanation |
| :--------------------- | :----------------------------------------------------------------------------------- |
| Total Messages | How many times users interacted with the AI today. It shows how popular your app is. |
| Active Users | The number of unique people engaging with the AI. |
| Token Usage | How much tokens the AI used. Watch for sudden spikes to control costs. |
| Avg. User Interactions | Do the users ask follow-up questions? |
### The Magnifying Glass: Logs
Logs record the details of every single run: time, input, duration, and output. To access detailed records, click Logs in the left sidebar.
**Why Logs?**
* **Debugging**: User says *It doesn't work*? Check the logs to replay the *crime scene* and see exactly which node failed.
* **Performance**: See how long each node took. Find the blocker that is slowing things down.
* **Understand Users**: Read what users are actually asking. Use this real data to update your Knowledge Base or improve your Prompts.
* **Cost Control**: Check exactly how many tokens a specific run cost.
| Name | Explanation |
| :------------------ | :---------------------------------------------------------- |
| Start Time | The time when the workflow was triggered |
| Status | Success or Failure. |
| Run Time | How long the whole process took. |
| Tokens | The tokens consumed by this run. |
| End User or Account | The specific user ID or account that initiated the session. |
| Triggered By | Web app interface or called via API. |
You can click on each log entry to view more details. For example, you can identify frequently asked user questions and use them to timely update and modify your Knowledge Base.
Building AI app is a new starting point, and this is the core of **LLMOps** (Large language model operations).
1. **Observe**: Look at the Logs. What are users asking? Are they happy with the answers?
2. **Analyze**: Hallucination happens on certain questions or some tools run out often
3. **Optimize**: Go back to the Canvas. Edit the Prompt, add a document to the Knowledge Base, or tweak the workflow logic
4. **Publish**: Release the upgraded version
By repeating this cycle, your Email Assistant gets smarter and faster.
## Thank You
**Thank you for your time and you're now a Dify builder with a new way of thinking**:
```plaintext wrap theme={null}
Break down the task → Choose Nodes and Tools → Connect them with the right logic → Monitor and upgrade
```
Now, feel free to open a template in Dify explore. Break it down, analyze it, or start building a workflow that solves a task in your daily work from the scratch.
May your workload get lighter and your imagination goes higher. Happy building with Dify.
# 30-Minute Quick Start
Source: https://docs.dify.ai/en/quick-start
Dive into Dify through an example app
<Info>
This quick start uses **Dify Cloud**, the fastest way to get going: free to start, AI credits included, and nothing to install. Prefer to run Dify yourself? [Self-host Dify](/en/self-host/deploy/quick-start/docker-compose), then follow the same steps on your own instance.
</Info>
This step-by-step tutorial will walk you through creating a multi-platform content generator from scratch.
Beyond basic LLM integration, you'll discover how to use powerful Dify nodes to orchestrate sophisticated AI applications faster with less effort.
By the end of this tutorial, you'll have a workflow that takes whatever content you throw at it (text, documents, or images), adds your preferred voice and tone, and spits out polished, platform-specific social media posts in your chosen language.
The complete workflow is shown below. Feel free to refer back to this as you build to stay on track and see how all the nodes work together.
<Frame>
<img alt="Workflow Overview" />
</Frame>
## Before You Start
<Steps>
<Step title="Sign Up">
Go to [cloud.dify.ai](https://cloud.dify.ai) and sign up for free.
New accounts start on the Sandbox plan, which includes 200 AI credits for calling models from providers like OpenAI, Anthropic, and Gemini.
<Info>
The Sandbox AI credits are a one-time allocation and don't renew monthly.
</Info>
</Step>
<Step title="Set Up the Model Provider">
Go to **Integrations** > **Model Provider** and install the OpenAI model provider. This tutorial uses `gpt-5.2` for the examples.
No API key is required for the models covered by your AI credits; they're ready to use once the provider is installed. You can also configure your own API key and use it instead.
</Step>
<Step title="Configure the Default Model">
1. In the top-right corner of the **Model Provider** page, click **Default Models**.
2. Set the **System Reasoning Model** to `gpt-5.2`. This becomes the default model in the workflow.
</Step>
</Steps>
## Step 1: Create a New Workflow
1. Go to **Studio**, then select **Create from Blank** > **Workflow**.
2. Name the workflow `Multi-platform content generator` and click **Create**. You'll automatically land on the workflow canvas to start building.
3. Select the User Input node to start our workflow.
## Step 2: Orchestrate & Configure
<Note>
Keep any unmentioned settings at their default values.
</Note>
<Tip>
Give nodes and variables clear, descriptive names to make them easier to identify and reference.
</Tip>
### 1. Collect User Inputs: User Input Node
<Info>
First, we need to define what information to gather from users for running our content generator, such as the draft text, target platforms, desired tone, and any reference materials.
The User Input node is where we can easily set this up. Each input field we add here becomes a variable that all downstream nodes can reference and use.
</Info>
Click the User Input node to open its configuration panel, then add the following input fields.
<Accordion title="Reference materials - text">
* Field type: `Paragraph`
* Variable Name: `draft`
* Label Name: `Draft`
* Max length: `2048`
* Required: `Yes`
</Accordion>
<Accordion title="Reference materials - files">
* Field type: `File list`
* Variable Name: `user_file`
* Label Name: `Upload File (≤ 10)`
* Support File Types: `Document`, `Image`
* Upload File Types: `Both`
* Max number of uploads: `10`
* Required: `No`
</Accordion>
<Accordion title="Voice and tone">
* Field type: `Paragraph`
* Variable Name: `voice_and_tone`
* Label Name: `Voice & Tone`
* Max length: `2048`
* Required: `No`
</Accordion>
<Accordion title="Target platform">
* Field type: `Short Text`
* Variable Name: `platform`
* Label Name: `Target Platform (≤ 10)`
* Max length: `256`
* Required: `Yes`
</Accordion>
<Accordion title="Language requirements">
* Field type: `Select`
* Variable Name: `language`
* Label Name: `Language`
* Options:
* `English`
* `日本語`
* `简体中文`
* Required: `Yes`
</Accordion>
<Frame>
<img alt="User Input" />
</Frame>
### 2. Identify Target Platforms: Parameter Extractor Node
<Info>
Since our platform field accepts free-form text input, users might type in various ways: `x and linkedIn`, `post on Twitter and LinkedIn`, or even `Twitter + LinkedIn please`.
However, we need a clean and structured list, like `["Twitter", "LinkedIn"]`, that downstream nodes can work with reliably.
This is the perfect job for the Parameter Extractor node. In our case, it uses the gpt-5.2 model to analyze users' natural language, recognize all these variations, and output a standardized array.
</Info>
After the User Input node, add a Parameter Extractor node and configure it:
1. In the **Input Variable** field, select `User Input/platform`.
2. Add an extract parameter:
* Name: `platform`
* Type: `Array[String]`
* Description: `The platform(s) for which the user wants to create tailored content.`
* Required: `Yes`
3. In the **Instruction** field, paste the following to guide the LLM in parameter extraction:
```markdown INSTRUCTION theme={null}
# TASK DESCRIPTION
Parse platform names from input and output as a JSON array.
## PROCESSING RULES
- Support multiple delimiters: commas, semicolons, spaces, line breaks, "and", "&", "|", etc.
- Standardize common platform name variants (twitter/X→Twitter, insta→Instagram, etc.)
- Remove duplicates and invalid entries
- Preserve unknown but reasonable platform names
- Preserve the original language of platform names
## OUTPUT REQUIREMENTS
- Success: ["Platform1", "Platform2"]
- No platforms found: [No platforms identified. Please enter a valid platform name.]
## EXAMPLES
- Input: "twitter, linkedin" → ["Twitter", "LinkedIn"]
- Input: "x and insta" → ["Twitter", "Instagram"]
- Input: "invalid content" → [No platforms identified. Please enter a valid platform name.]
```
<Check>
Note that we've instructed the LLM to output a specific error message for invalid inputs, which will serve as the end trigger for our workflow in the next step.
</Check>
<Frame>
<img alt="Parameter Extractor" />
</Frame>
### 3. Validate Platform Extraction Results: IF/ELSE Node
<Info>
What if a user enters an invalid platform name, like `ohhhhhh` or `BookFace`? We don't want to waste time and tokens generating useless content.
In such cases, we can use an IF/ELSE node to create a branch that stops the workflow early. We'll set a condition that checks for the error message from the Parameter Extractor node; if that message is detected, the workflow will route directly to an Output node and end.
</Info>
<Frame>
<img alt="IF Branch" />
</Frame>
1. After the Parameter Extractor node, add an IF/ELSE node.
2. On the IF/ELSE node's panel, define the **IF** condition:
**IF** `Parameter Extractor/platform` **contains** `No platforms identified. Please enter a valid platform name.`
3. After the IF/ELSE node, add an Output node to the IF branch.
4. On the Output node's panel, set `Parameter Extractor/platform` as the output variable.
### 4. Separate Uploaded Files by Type: List Operator Node
<Info>
Our users can upload both images and documents as reference materials, but these two types require different handling with `gpt-5.2`: images can be interpreted directly via its vision capability, while documents must first be converted to text before the model can process them.
To manage this, we'll use two List Operator nodes to filter and split the uploaded files into separate branches: one for images and one for documents.
</Info>
<Frame>
<img alt="List Operator" />
</Frame>
1. After the IF/ELSE node, add **two** parallel List Operator nodes to the ELSE branch.
2. Rename one node to `Image` and the other to `Document`.
3. Configure the Image node:
1. Set `User Input/user_file` as the input variable.
2. Enable **Filter Condition**: `{x}type` **in** `Image`.
4. Configure the Document node:
1. Set `User Input/user_file` as the input variable.
2. Enable **Filter Condition**: `{x}type` **in** `Doc`.
### 5. Extract Text from Documents: Doc Extractor Node
<Info>
`gpt-5.2` cannot directly read uploaded documents like PDF or DOCX, so we must first convert them into plain text.
This is exactly what a Doc Extractor node does. It takes document files as input and outputs clean, usable text for the next steps.
</Info>
<Frame>
<img alt="Doc Extractor" />
</Frame>
1. After the Document node, add a Doc Extractor node.
2. On the Doc Extractor node's panel, set `Document/result` as the input variable.
### 6. Integrate All Reference Materials: LLM Node
<Info>
When users provide multiple reference types (draft text, documents, and images) simultaneously, we need to consolidate them into a single, coherent summary.
An LLM node will handle this task by analyzing all the scattered pieces to create a comprehensive context that guides subsequent content generation.
</Info>
<Frame>
<img alt="Integrate Information" />
</Frame>
1. After the Doc Extractor node, add an LLM node.
2. Connect the Image node to this LLM node as well.
3. Click the LLM node to configure it:
1. Rename it to `Integrate Info`.
2. Enable **VISION** and set `Image/result` as the vision variable.
3. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are a content strategist. Analyze the provided draft and reference materials (if any), then create a comprehensive content foundation for multi-platform social media optimization.
# ANALYSIS PRINCIPLES
- Work exclusively with provided information—no external assumptions
- Focus on extraction, synthesis, and strategic interpretation
- Identify compelling and actionable elements
- Prepare insights adaptable across different platforms
# REQUIRED ANALYSIS
Deliver structured analysis with:
## 1. CORE MESSAGE
- Central theme, purpose, objective
- Key value or benefit being communicated
## 2. ESSENTIAL CONTENT ELEMENTS
- Primary topics, facts, statistics, data points
- Notable quotes, testimonials, key statements
- Features, benefits, characteristics mentioned
- Dates, locations, contextual details
## 3. STRATEGIC INSIGHTS
- What makes content compelling/unique
- Emotional/rational appeals present
- Credibility factors, proof points
- Competitive advantages highlighted
## 4. ENGAGEMENT OPPORTUNITIES
- Discussion points, questions emerging
- Calls-to-action, next steps suggested
- Interactive/participation opportunities
- Trending themes touched upon
## 5. PLATFORM OPTIMIZATION FOUNDATION
- High-impact: Quick, shareable formats
- Professional: Business-focused discussions
- Community: Interaction and sharing
- Visual: Enhanced with strong visuals
## 6. SUPPORTING DETAILS
- Metrics, numbers, quantifiable results
- Direct quotes, testimonials
- Technical details, specifications
- Background context available
```
4. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace `Doc Extractor/text` and `User Input/draft` with the corresponding variables from the list.
```markdown USER theme={null}
Draft: User Input/draft
Reference material: Doc Extractor/text
```
<Frame>
<img alt="User Message" />
</Frame>
### 7. Create Customized Content for Each Platform: Iteration Node
<Info>
Now that the integrated references and target platforms are ready, let's generate a tailored post for each platform using an Iteration node.
The node will loop through the list of platforms and run a sub-workflow for each: first analyze the specific platform's style guidelines and best practices, then generate optimized content based on all available information.
</Info>
<Frame>
<img alt="Iteration Node" />
</Frame>
1. After the Integrate Info node, add an Iteration node.
2. Inside the Iteration node, add an LLM node and configure it:
1. Rename it to `Identify Style`.
2. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are a social media expert. Analyze the platform and provide content creation guidelines.
# ANALYSIS REQUIRED
For the given platform, provide:
## 1. PLATFORM PROFILE
- Platform type and category
- Target audience characteristics
## 2. CONTENT GUIDELINES
- Optimal content length (characters/words)
- Recommended tone (professional/casual/conversational)
- Formatting best practices (line breaks, emojis, etc.)
## 3. ENGAGEMENT STRATEGY
- Hashtag recommendations (quantity and style)
- Call-to-action best practices
- Algorithm optimization tips
## 4. TECHNICAL SPECS
- Character/word limits
- Visual content requirements
- Special formatting needs
## 5. PLATFORM-SPECIFIC NOTES
- Unique features or recent changes
- Industry-specific considerations
- Community engagement approaches
# OUTPUT REQUIREMENTS
- For recognized platforms: Provide specific guidelines
- For unknown platforms: Base recommendations on similar platforms
- Focus on actionable, practical advice
- Be concise but comprehensive
```
3. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace `Current Iteration/item` with the corresponding variable from the list.
```markdown USER theme={null}
Platform: Current Iteration/item
```
3. After the Identify Style node, add another LLM node and configure it:
1. Rename it to `Create Content`.
2. In the system instruction field, paste the following:
```markdown wrap theme={null}
# ROLE & TASK
You are an expert social media content creator. Generate publication-ready content that matches platform guidelines, incorporates source information, and follows specified voice/tone and language requirements.
# LANGUAGE REQUIREMENT
- Generate ALL content exclusively in the target language specified in the user message. You MUST write the entire post in that language, regardless of the language of any source materials.
- No mixing of languages whatsoever
- Adapt platform terminology to the target language
# CONTENT REQUIREMENTS
- Follow platform guidelines exactly (format, length, tone, hashtags)
- Integrate source information effectively (key messages, data, value props)
- Apply voice & tone consistently (if provided)
- Optimize for platform-specific engagement
- Ensure cultural appropriateness for the specified language
# OUTPUT FORMAT
- Generate ONLY the final social media post content. No explanations or meta-commentary. Content must be immediately copy-paste ready.
- Maximum heading level: ## (H2) - never use # (H1)
- No horizontal dividers: avoid ---
# QUALITY CHECKLIST
✅ Platform guidelines followed
✅ Source information integrated
✅ Voice/tone consistent (when provided)
✅ Language consistency maintained
✅ Engagement optimized
✅ Publication ready
```
3. Click **Add Message** to add a user message, then paste the following. Type `{` or `/` to replace all inputs with the corresponding variable from the list.
```markdown USER theme={null}
Platform Name: Current Iteration/item
Target Language: User Input/language
Platform Guidelines: Identify Style/text
Source Information: Integrate Info/text
Voice & Tone: User Input/voice_and_tone
```
4. Enable structured output.
<Info>
This allows us to extract specific pieces of information from the LLM's response in a more reliable way, which is crucial for the next step where we format the final output.
</Info>
<Frame>
<img alt="Structured Output" />
</Frame>
1. Next to **Output Variables**, toggle **Structured** on. The `structured_output` variable will appear below. Click **Configure**.
2. In the pop-up schema editor, click **Import From JSON** in the top-right corner, and paste the following:
```json theme={null}
{
"platform_name": "string",
"post_content": "string"
}
```
<Frame>
<img alt="Import from JSON" />
</Frame>
4. Click the Iteration node to configure it:
1. Set `Parameter Extractor/platform` as the input variable.
2. Set `Create Content/structured_output` as the output variable.
3. Enable **Parallel Mode** and set the maximum parallelism to `10`.
<Check>
This is why we included `(≤10)` in the label name for the target platform field back in the User Input node.
</Check>
<Frame>
<img alt="Iteration Configuration" />
</Frame>
### 8. Format the Final Output: Template Node
<Info>
The Iteration node generates a post for each platform, but its output is a raw array of data (e.g., `[{"platform_name": "Twitter", "post_content": "..."}]`) that isn't very readable. We need to present the results in a clearer format.
That's where the Template node comes in. It lets us format this raw data into well-organized text using [Jinja2](https://jinja.palletsprojects.com/en/stable/) templating, ensuring the final output is user-friendly and easy to read.
</Info>
<Frame>
<img alt="Template Node" />
</Frame>
1. After the Iteration node, add a Template node.
2. On the Template node's panel, set `Iteration/output` as the input variable and name it `output`.
3. Paste the following Jinja2 code:
```
{% for item in output %}
# 📱 {{ item.platform_name }}
{{ item.post_content }}
{% endfor %}
```
* `{% for item in output %}` / `{% endfor %}`: Loops through each platform-content pair in the input array.
* `{{ item.platform_name }}`: Displays the platform name as an H1 heading with a phone emoji.
* `{{ item.post_content }}`: Displays the generated content for that platform.
* The blank line between `{{ item.post_content }}` and `{% endfor %}` adds spacing between platforms in the final output.
<Tip>
While LLMs can handle output formatting as well, their outputs can be inconsistent and unpredictable. For rule-based formatting that requires no reasoning, the Template node gets things done in a more stable and reliable way at zero token cost.
LLMs are incredibly powerful, but knowing when to use the right tool is key to building more reliable and cost-effective AI applications.
</Tip>
### 9. Return the Results to Users: Output Node
1. After the Template node, add an Output node.
2. On the Output node's panel, set the `Template/output` as the output variable.
## Step 3: Test
Your workflow is now complete! Let's test it out.
1. Make sure your Checklist is clear.
<Frame>
<img alt="Check Checklist" />
</Frame>
2. Check your workflow against the reference diagram provided at the beginning to ensure all nodes and connections match.
3. Click **Test Run** in the top-right corner, fill in the input fields, then click **Start Run**.
If you're not sure what to enter, try these sample inputs:
* **Draft**: `We just launched a new AI writing assistant that helps teams create content 10x faster.`
* **Upload File**: Leave empty
* **Voice & Tone**: `Friendly and enthusiastic, but professional`
* **Target Platform**: `Twitter and LinkedIn`
* **Language**: `English`
A successful run produces a formatted output with a separate post for each platform, like this:
<Frame>
<img alt="Test Output" />
</Frame>
<Note>
Your results may vary depending on the model you're using. Higher-capability models generally produce better output quality.
</Note>
<Tip>
To test how a node reacts to different inputs from previous nodes, you don't need to re-run the entire workflow. Just click **View cached variables** at the bottom of the canvas, find the variable you want to change, and edit its value.
</Tip>
If you encounter any errors, check the **Last Run** logs of the corresponding node to identify the exact cause of the problem.
## Step 4: Publish & Share
Once the workflow runs as expected and you're happy with the results, click **Publish** > **Publish Update** to make it live and shareable.
<Warning>
If you make any changes later, always remember to publish again so the updates take effect.
</Warning>
# App Toolkit
Source: https://docs.dify.ai/en/self-host/use-dify/build/additional-features
Optional features that make your Dify apps more useful
Dify apps come with optional features you can enable to improve the end-user experience. Open the **Features** panel of the builder to see what's available for your app type.
<Columns>
<Column>
<Frame>
<img alt="Features Panel in Chatbots, Agents, and Text Generators" />
</Frame>
</Column>
<Column>
<Frame>
<img alt="Features Panel in Chatflows" />
</Frame>
</Column>
</Columns>
## Conversation Opener
Set an opening message that greets users at the start of each conversation, with optional suggested questions to guide them toward what the app does well.
You can insert variables into the opening message and suggested questions to personalize the experience.
* In the opening message, type `{` or `/` to insert variables from the picker.
* In suggested questions, type variable names manually in `{{variable_name}}` format.
<Columns>
<Column>
<Frame>
<img alt="Configuration" />
</Frame>
</Column>
<Column>
<Frame>
<img alt="Web App" />
</Frame>
</Column>
</Columns>
## Follow-up
When enabled, follow-up questions are generated after each response to help users continue the conversation.
Click **Settings** to pick the model that generates the questions, or write a custom prompt (up to 1,000 characters) to adjust the number, wording, or length of the questions.
## Text to Speech
Convert AI responses to audio. You can configure the language and voice to match your app's audience, and enable **Auto Play** to stream audio automatically as the AI responds.
<Info>
**Text to Speech** uses your workspace's text-to-speech model (set in **Integrations** > **Model Provider** > **Default Models**).
The feature only appears in the **Features** panel when a default TTS model is configured.
</Info>
## Speech to Text
Enable voice input for the chat interface. When enabled, your end users can dictate messages instead of typing by clicking the microphone button.
<Info>
**Speech to Text** uses your workspace's speech-to-text model (set in **Integrations** > **Model Provider** > **Default Models**).
The feature only appears in the **Features** panel when a default STT model is configured.
</Info>
## File Upload
Allow end users to send files at any point during a conversation. You can configure which file types to accept, the upload method, and the maximum number of files per message.
Adjust per-file size limits via these environment variables:
* `UPLOAD_IMAGE_FILE_SIZE_LIMIT` (default: 10 MB)
* `UPLOAD_FILE_SIZE_LIMIT` (default: 15 MB)
* `UPLOAD_AUDIO_FILE_SIZE_LIMIT` (default: 50 MB)
* `UPLOAD_VIDEO_FILE_SIZE_LIMIT` (default: 100 MB)
See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
## Citations and Attributions
Show the source documents behind AI responses. When enabled, responses that draw from a connected knowledge base display numbered citations linking back to the original documents and chunks.
<Frame>
<img alt="Citations and Attributions" />
</Frame>
## Content Moderation
Filter inappropriate content in user inputs, AI outputs, or both. Choose a moderation provider based on your needs:
* **OpenAI Moderation**: Use OpenAI's dedicated moderation model to detect harmful content across multiple categories.
* **Keywords**: Define a list of blocked terms. Any match triggers the preset response.
* **Custom Endpoint**: Connect a custom moderation endpoint for your own filtering logic.
When content is flagged, the app replaces it with a preset response that you define.
## Annotation Reply
Define curated Q\&A pairs that take priority over LLM responses. When a user's query **semantically** matches an annotation above the score threshold (how closely a query must match), the curated answer is returned directly without calling the LLM.
You can configure the score threshold and the embedding model used for semantic matching.
To create and manage your annotations:
* Convert existing conversations into annotations directly from **Debug & Preview** or **Logs** by clicking the **Add annotation** icon on any LLM response.
Once a message is annotated, the icon changes to **Edit**, so you can modify the annotation in place.
<Frame>
<img alt="Add Annotation Icon" />
</Frame>
* In **Annotations**, manually add new Q\&A pairs, manage existing annotations, and view hit history. Click `...` to bulk import or bulk export.
<Frame>
<img alt="Bulk Annotation Operation" />
</Frame>
## More Like This
Generate alternative outputs for the same input. Once enabled, each generated result includes a button to produce a variation, so you can explore different responses without re-entering your query.
<Frame>
<img alt="More Like This" />
</Frame>
You can generate up to 2 variations per result. Each variation uses additional tokens.
# Agent
Source: https://docs.dify.ai/en/self-host/use-dify/build/agent
Chat-style apps where the model can reason, make decisions, and use tools autonomously
<Tip>
[A new kind of Agent](/en/self-host/use-dify/build/new-agent/overview) is in beta: it works in a sandbox of its own, and you build it once to use as a chat app or inside workflows.
</Tip>
Agents are chat-style apps where the model can reason through a task, decide what to do next, and use tools when needed to complete the user's request.
Use it when you want the model to autonomously decide how to approach a task using available tools, without designing a multi-step workflow. For example, building a data analysis assistant that can fetch live data, generate charts, and summarize findings on its own.
<Info>
Agents keep up to 500 messages or 2,000 tokens of history per conversation. If either limit is exceeded, the oldest messages will be removed to make room for new ones.
</Info>
<Tip>
Agents support optional features like conversation openers, follow-up suggestions, and more. See [App Toolkit](/en/self-host/use-dify/build/additional-features) for details.
</Tip>
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow. For an agent, the prompt also guides how the model reasons through tasks and decides when to use tools, so be specific about the workflow you expect.
Here are some tips for writing effective prompts:
* **Define the persona**: Describe who the model should act as and the expertise it should draw on.
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
* **Guide tool usage**: Mention specific tools by name and describe when they should be used.
* **Outline the workflow**: Break down complex tasks into logical steps the model should follow.
#### Create Dynamic Prompts with Variables
To adapt the agent to different users or contexts without rewriting the prompt each time, add variables to collect the necessary information upfront.
Variables are placeholders in the prompt—each one appears as an input field that users fill in before the conversation starts, and their values are injected into the prompt at runtime. Users can also update variable values mid-conversation, and the prompt will adjust accordingly.
For example, a data analysis agent might use a domain variable so users can specify which area to focus on:
```text wrap theme={null}
You are a data analyst specializing in {{domain}}. Help users explore and understand their data.
When asked a question, use available data tools to fetch the relevant information. If the result suits a visual format, generate a chart. Explain your findings in plain language.
Keep responses concise. If a question is ambiguous, ask for clarification before fetching data.
```
<Tip>
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
</Tip>
Choose the variable type that matches the input you expect:
<Tabs>
<Tab title="Short Text">
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
</Tab>
<Tab title="Paragraph">
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
</Tab>
<Tab title="Select">
Displays a dropdown menu with predefined options.
</Tab>
<Tab title="Number">
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
</Tab>
<Tab title="Checkbox">
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
</Tab>
<Tab title="API-based Variable">
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/self-host/use-dify/workspace/api-extension/api-extension) for details.
</Tab>
</Tabs>
<Info>
**Label Name** is what end users see for each input field.
</Info>
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Extend the Agent with Dify Tools
Add [Dify tools](/en/self-host/use-dify/workspace/tools) to enable the model to interact with external services and APIs for tasks beyond text generation, such as fetching live data, searching the web, or querying databases.
The model decides when and which tools to use based on each query. To guide this more precisely, mention specific tool names in your prompt and describe when they should be used.
<Frame>
<img alt="Tool Name" />
</Frame>
You can disable or remove added tools, and modify their configuration. If a tool requires authentication, select an existing credential or create a new one.
<Info>
To change the default credential, go to **Integrations** > **Tools** > **Tool Plugin**.
</Info>
#### Maximum Iterations
**Maximum Iterations** in **Agent Settings** limits how many times the model can repeat its reasoning-and-action cycle (think, call a tool, process the result) for a single request.
Increase this value for complex, multi-step tasks that require multiple tool calls. Higher values increase latency and token costs.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base.
The model evaluates each user query against your knowledge base descriptions and decides whether retrieval is needed—you don't need to mention knowledge bases in your prompt.
**The more detailed your knowledge base description, the better the model can determine relevance**, leading to more accurate and targeted retrieval.
<Info>
An Agent app has no app-level retrieval settings. Each knowledge base is queried independently using its own settings you've configured. When you add several, the agent picks which to query and does not rerank results across them.
</Info>
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/self-host/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
<Tip>
You can quickly identify a model's supported modalities by its tags.
<Frame>
<img alt="Model Tags" />
</Frame>
</Tip>
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per message.
Per-file size caps default to 10 MB for images (`UPLOAD_IMAGE_FILE_SIZE_LIMIT`), 15 MB for documents (`UPLOAD_FILE_SIZE_LIMIT`), and 50 MB for audio (`UPLOAD_AUDIO_FILE_SIZE_LIMIT`). Adjust the environment variables to change these limits. See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
## Debug & Preview
In the preview panel on the right, test your agent in real time. Select a model, type a message, and send it to see how the agent responds.
You can adjust a model's parameters to control how it generates responses. Available parameters and presets vary by model.
<Tip>
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
<Frame>
<img alt="Debug with Multiple Models" />
</Frame>
</Tip>
We recommend selecting models that are strong at **reasoning** and **natively support tool calling**.
<Accordion title="Why This Matters">
An agent needs to judge *when* to use a tool, *which tool* fits the task, and *how* to interpret the result—this depends on the model's reasoning ability. Models with built-in tool-call support also execute these decisions more reliably.
</Accordion>
You can verify your model's tool-call support in **Agent Settings**, where the system automatically displays the agent mode:
* **Function Calling** for models with native support, meaning they can call tools directly.
* **ReAct** for others, so Dify guides them to use tools through a prompting strategy.
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/self-host/use-dify/publish/README) for the full list of publishing options.
# Chatbot
Source: https://docs.dify.ai/en/self-host/use-dify/build/chatbot
The simplest way to build a conversational app with a model and a prompt
Chatbots are conversational apps where users interact with the model through a chat interface.
Use it for tasks that benefit from back-and-forth interaction but don't require tool calls or a multi-step workflow—for example, building an internal Q\&A assistant grounded in your team's knowledge base.
<Info>
Chatbots keep up to 500 messages or 2,000 tokens of history per conversation. If either limit is exceeded, the oldest messages will be removed to make room for new ones.
</Info>
<Tip>
Chatbots also support optional features like conversation openers, follow-up suggestions, and more. See [App Toolkit](/en/self-host/use-dify/build/additional-features) for details.
</Tip>
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow. It shapes how the model behaves throughout the conversation, so think of it as defining a consistent persona rather than describing a one-off task.
Here are some tips for writing effective prompts:
* **Define the persona**: Describe who the model should act as and the tone it should use.
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
#### Create Dynamic Prompts with Variables
To adapt your chatbot to different users or contexts without rewriting the prompt each time, add variables to collect the necessary information upfront.
Variables are placeholders in the prompt—each one appears as an input field that users fill in before the conversation starts, and their values are injected into the prompt at runtime. Users can also update variable values mid-conversation, and the prompt will adjust accordingly.
For example, an onboarding assistant might use `role` and `language` to tailor its responses:
```text wrap theme={null}
You are an onboarding assistant for new {{role}} hires. Answer questions about company processes and policies. Keep answers friendly and concise, and respond in {{language}}.
```
<Tip>
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
</Tip>
Choose the variable type that matches the input you expect:
<Tabs>
<Tab title="Short Text">
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
</Tab>
<Tab title="Paragraph">
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
</Tab>
<Tab title="Select">
Displays a dropdown menu with predefined options.
</Tab>
<Tab title="Number">
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
</Tab>
<Tab title="Checkbox">
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
</Tab>
<Tab title="API-based Variable">
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/self-host/use-dify/workspace/api-extension/api-extension) for details.
</Tab>
</Tabs>
<Info>
**Label Name** is what end users see for each input field.
</Info>
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base.
Each time a user sends a message, it is used as the search query to retrieve relevant content from the knowledge base, which is then injected into the prompt as context for the model.
#### Configure App-Level Retrieval Settings
To fine-tune how retrieval results are processed, click **Retrieval Setting**.
<Info>
There are two layers of retrieval settings—the knowledge base level and the app level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the app settings further rerank the results or narrow down the pool.
</Info>
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
<Note>
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
</Note>
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/self-host/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
<Tip>
You can quickly identify a model's supported modalities by its tags.
<Frame>
<img alt="Model Tags" />
</Frame>
</Tip>
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per message.
<Info>
Adjust file size limits via these environment variables:
* `UPLOAD_IMAGE_FILE_SIZE_LIMIT` (default: 10 MB)
* `UPLOAD_FILE_SIZE_LIMIT` (default: 15 MB)
* `UPLOAD_AUDIO_FILE_SIZE_LIMIT` (default: 50 MB)
See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
</Info>
## Debug & Preview
In the preview panel on the right, test your chatbot in real time. Select a model that best fits your task, type a message, and send it to see how the model responds.
After selecting a model, you can adjust its parameters to control how it generates responses. Available parameters and presets vary by model.
<Tip>
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
<Frame>
<img alt="Debug with Multiple Models" />
</Frame>
</Tip>
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/self-host/use-dify/publish/README) for the full list of publishing options.
# Go to Anything
Source: https://docs.dify.ai/en/self-host/use-dify/build/goto-anything
Search and jump to apps, agents, skills, knowledge bases, integrations, and workflow nodes from anywhere with a keyboard shortcut
The **Go to Anything** overlay is a search box for the whole console: type once to find apps, agents, skills, knowledge bases, Marketplace integrations, and nodes on the canvas you're editing, or run quick commands.
### Open the Overlay
Press `⌘ + K` on macOS or `Ctrl + K` on Windows/Linux, or click the search button at the top of the sidebar.
<Info>
If the shortcut doesn't respond, another app or browser extension may be using it. The sidebar button always works.
</Info>
### Search with @
Type a keyword to search everything at once; results are grouped by category. Prefix a scope to narrow the search:
* `@app` – search your applications
* `@knowledge` or `@kb` – search knowledge bases
* `@plugin` – search integrations on the Marketplace
* `@agent` – search your agents
* `@skill` – search your skills
* `@node` – search nodes on the open canvas (available for workflows and knowledge pipelines)
Navigate results with the arrow keys and press `Enter` to open the selected item.
### Run Commands with /
Type `/` to see every command, or keep typing to filter:
| Command | What it does |
| :--------------------- | :--------------------------------------------------------------------------------------------------------------------------- |
| `/create` / `/new` | describe an app and Dify builds it as a Workflow or Chatflow; pick the type yourself or choose **Auto** to let the AI decide |
| `/refine` / `/improve` | describe a change and Dify applies it to the Workflow or Chatflow you're editing (only when one is open) |
| `/go` | jump to a main section of the console |
| `/docs` | open the help documentation |
| `/discord` | open the Discord community |
| `/models` | open the system model settings |
| `/account` | go to your account page |
| `/theme` | switch the interface theme |
| `/language` / `/lang` | change the interface language |
# Build an Agent
Source: https://docs.dify.ai/en/self-host/use-dify/build/new-agent/build
Create an agent and shape what it can do, by hand or by describing what you want
<Note>
The new Agent is in beta. It's on by default on Docker Compose, with its runtime bundled in.
For production, replace [`DIFY_AGENT_SERVER_SECRET_KEY`](/en/self-host/deploy/configuration/environments#dify_agent_server_secret_key) and [`DIFY_AGENT_API_TOKEN`](/en/self-host/deploy/configuration/environments#dify_agent_api_token) with your own random values.
</Note>
## Create an Agent
From **Agents**, click **Create** > **Create from Blank** and give the agent a name; optionally add a role such as *Research Assistant* and a description. Then you shape everything else in **Configure**.
To create an agent from a shared DSL file, choose **Import DSL file**. [Library skills](/en/self-host/use-dify/build/skills) reattach automatically when your workspace has skills with the same names; embedded skills and files aren't included, so add them after importing.
<Info>
Creating and managing agents requires the Editor role or above.
</Info>
## Configure Its Capabilities
Set up each capability by hand, or describe what you want and build it by chatting in [Build mode](#build-by-chatting).
Everything you set up in **Configure** is saved as the agent's capabilities and used in every task later. Separately, the agent works inside its own *sandbox*, where it runs commands and handles files as it goes.
The agent's capabilities can only be changed here: even if an end user asks a published agent to change its own prompt, skills, or tools, it won't.
### Model
Pick the chat model the agent runs on. Favor models that are strong at reasoning and natively support tool calling, since the agent has to judge when to act, which tool fits, and how to read the result.
<Note>
Agent performance rises and falls with the model, so pick a recent one.
Older models often can't make full use of the sandbox: a common symptom is an agent that never runs commands or installs tools, even when the task needs it.
</Note>
### Prompt
In the prompt, set the agent's role and how it should approach its work. Be specific about how it should reason, when to lean on its tools, and what to avoid.
A few things worth covering:
* **Persona and goal**: who the agent acts as and what it's trying to achieve.
* **Approach**: the steps or order you expect for a typical task.
* **Tool and file use**: when to reach for each, named explicitly.
* **Output**: the format, length, or tone you want back.
You can point the agent at a specific skill, file, or tool, or leave the choice to the agent:
* **Reference it in the prompt** with `/` to send the agent straight to it, right where you want it used. Best when a step depends on a specific one.
* **Just add it to its section** and let the agent decide on its own when to use it. Best when you'd rather trust the agent's judgment than script every move.
### Skills
A skill is a procedure the agent follows for one specific task. Unlike the prompt, which sets the agent's overall role, a skill covers just that task.
For example, a support agent's prompt might set its role as a customer helper that handles any issue, while its `refund-requests` skill covers only refunds: look up the order, refund only within 30 days, and end with a help-center link.
Click **Add** and choose which kind of skill to add:
* Choose **Add from library** to add a [*library skill*](/en/self-host/use-dify/build/skills) shared workspace-wide. You can add up to 20 library skills to an agent, and it follows the latest published version of each.
* Choose **Upload skill.zip** to add a `.zip` or `.skill` package as an *embedded skill*, one the agent keeps to itself.
The package needs a `SKILL.md` inside and can be up to 50 MB by default, adjustable with [`UPLOAD_SKILL_FILE_SIZE_LIMIT`](/en/self-host/deploy/configuration/environments#upload_skill_file_size_limit).
To share an embedded skill with other agents, [make it a library skill](/en/self-host/use-dify/build/skills#import-a-skill).
You can also have the agent create embedded skills for you in [Build mode](#build-by-chatting).
<Tip>
To make a Dify tool or file part of the agent's own capabilities, add it to the agent directly rather than inside a skill package.
</Tip>
### Files
Files are reference documents the agent can read while it works, like specs, templates, or guidelines. Unlike a skill, a file is just material to read, not a procedure to run.
Size limits depend on file type; each is a default you can adjust with [environment variables](/en/self-host/deploy/configuration/environments):
| File type | Default limit | Environment variable |
| :-------- | :------------ | :----------------------------- |
| Documents | 15 MB | `UPLOAD_FILE_SIZE_LIMIT` |
| Images | 10 MB | `UPLOAD_IMAGE_FILE_SIZE_LIMIT` |
| Video | 100 MB | `UPLOAD_VIDEO_FILE_SIZE_LIMIT` |
| Audio | 50 MB | `UPLOAD_AUDIO_FILE_SIZE_LIMIT` |
You can also have the agent create files and save them here in [Build mode](#build-by-chatting).
<Info>
Files the agent creates and saves are capped at 50 MB each by default, adjustable with `DIFY_AGENT_STUB_UPLOAD_FILE_SIZE_LIMIT`. See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
</Info>
### Tools
Give the agent [Dify tools](/en/self-host/use-dify/workspace/tools) so it can act beyond the chat: plugins, custom APIs, workflows, and MCP servers from your workspace. Some tools need authentication before use.
<Tip>
Beyond the Dify tools you add here, the agent can also install and run command-line tools on its own inside the sandbox when it needs one. Those tools don't appear in the Tools list.
Tools the agent installs in [Build mode](#build-by-chatting) can stay available after publishing, while anything installed during a published run is temporary.
</Tip>
### Environment Variables
Under **Advanced Settings**, you can add **environment variables**: key-value pairs the agent can read in its sandbox while it works.
Say your agent's skills all work with the same order system: one checks stock, one files orders, one pulls reports. Store the system's address here as `ORDER_API_URL`, and every script reads it by name. To switch from the test system to the production one, update this one value, and all of them follow.
Import a `.env` file to add several at once. You can also have the agent set them up in [Build mode](#build-by-chatting).
<Note>
Values stored here can surface in command output the agent reads. To mask sensitive strings from it, set `DIFY_AGENT_SHELL_REDACT_PATTERNS`. See [Environment Variables](/en/self-host/deploy/configuration/environments#agent-new) for details.
</Note>
## Build by Chatting
Instead of setting everything up by hand, you can build the agent by describing what it should do, and as you chat it sets up *skills*, *files*, and *environment variables* itself.
For example, your first message might be:
```text wrap theme={null}
Build an agent that turns raw meeting notes into structured minutes: attendees, decisions, and action items.
```
You're talking to the live agent: test it as you build, watch how it behaves, and refine it in the same build chat.
As the agent works, it edits the configuration in the panel directly, and you can see all changes listed in **Build draft**. Click **Apply** to keep them, or **Discard** to drop. Either one exits Build mode and clears the conversation.
<Note>
**Discard** drops everything from this build chat: any changes to the configuration and persistent files in the [**File system**](#file-system).
</Note>
While you're in Build mode, the configuration panel is read-only—just tell the agent what you want to change.
### File System
In Build mode, the agent handles real files in its sandbox: artifacts it generates, programs it installs on its own, and everything else it's working with. During a build chat, click **File system** in the top-right corner to browse them.
Since a build chat is where you shape the agent itself, whatever it adds (a template it drafted, a tool it installed) is **Persistent** by default, kept for every future conversation and workflow run. In effect, these files are part of the agent's setup, like its prompt and skills.
For one-off work, like a test file or a converter it only needs once, tell the agent in the chat, e.g. "keep this file temporary": it goes under **Temporary** and is cleared when this build chat ends.
In published runs, whatever the agent adds is always temporary, so nothing that happens in a run changes the agent itself.
### The Build Note
In build chats, the agent records what it set up in a *build note*, a `build_note.md` that appears in **Files** the first time you **Apply**.
The note is saved with the agent's setup, and it reads the note back at the start of every new conversation, combining it with your **Prompt** to form its instructions.
After you apply, open the build note and read what the agent captured:
* If it covers what you want, you're set.
* To change what it says, have the agent revise it in Build mode.
<Info>
The agent maintains only the auto-generated build note: a downloaded copy you re-upload is just an ordinary file, and the next build chat creates a fresh note alongside it.
</Info>
* If anything's missing, add it to the **Prompt**.
* To start over with a clean record, delete the note in **Files**.
Across build chats, the note also serves as the agent's *memory*. If you shaped the meeting-minutes agent in one chat, a later chat to add action-item owners starts from the format and decisions you already settled, not from scratch.
## Publish
Your edits autosave as a draft. When the agent is ready, publish it to make that version live. Open the version history anytime to revisit or restore an earlier version.
<Info>
Restoring a version also restores the persistent files in the agent's sandbox to that version.
</Info>
<Tip>
To polish the chat experience, you can add extras like a welcome message, suggested questions, and voice in **Chat Features**. See [App Toolkit](/en/self-host/use-dify/build/additional-features) for details.
</Tip>
From the **Access Point** tab, host it as a web app at a shareable link, embed it in your site, or call it from your code through the [service API](/en/api-reference/guides/agent).
<Warning>
**Data Security Notice**
Community Edition uses file-access controls to limit access to agent and session files when the same agent is exposed to multiple end users. These controls reduce the risk of cross-conversation data access through the filesystem, but the Agent runtime is not intended to provide a hardened security boundary between mutually untrusted users or workloads.
If your deployment requires strong isolation or strict security or compliance controls, use separately hardened infrastructure or contact Dify to assess an appropriate Cloud or Enterprise option. For Dify Enterprise, [contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Warning>
You can also invite the agent into a workflow's [Agent node](/en/self-host/use-dify/nodes/agent#new-agent) to handle a step.
To share the agent across workspaces, export it as a DSL file. Library skills reattach by name when the target workspace has them; embedded skills and files aren't included, so share them alongside.
### Run Limits
* **Time**
A single agent run is stopped after 1 hour by default, whichever access point it starts from (web app, service API, or a workflow), and the unfinished reply is discarded.
If a run gets cut off, try again or break the task into smaller steps. For longer runs, raise `APP_MAX_EXECUTION_TIME`, `WORKFLOW_MAX_EXECUTION_TIME`, and `DIFY_AGENT_RUN_TIMEOUT_SECONDS` above the duration you need.
See [Environment Variables](/en/self-host/deploy/configuration/environments) for details on these variables.
* **Model requests**
Every call the agent makes to its model counts toward a cap of 500 per run, so heavy reasoning and frequent tool use spend it faster.
Try breaking the task into smaller steps to keep each run within the cap.
* **Reply files**
Each file the agent sends back in a reply can be up to 50 MB by default, and larger files aren't delivered.
If your agent produces bigger artifacts, raise `DIFY_AGENT_STUB_UPLOAD_FILE_SIZE_LIMIT`. See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
## Troubleshooting
<AccordionGroup>
<Accordion title="Agents doesn't appear in the navigation or the node list">
The deployment's `.env` predates 1.16.0, so the Agents switch is missing or still off.
Sync it with `.env.example` (the switch is [`NEXT_PUBLIC_ENABLE_AGENT_V2`](/en/self-host/deploy/configuration/environments#next_public_enable_agent_v2)), then recreate the web container (`docker compose up -d web`) and hard-refresh the browser.
In Chatflow apps the node's absence is expected: it's available in Workflow apps only.
If other members see **Agents** but you don't, the cause is your workspace role: the entry needs the Editor role or above.
</Accordion>
<Accordion title="Agent runs fail as soon as they start">
If every run errors immediately, the deployment may be running 1.16.0 or later images with an older `docker-compose.yaml`, which lacks the agent's services (including `agent_backend` and `local_sandbox`).
Update the compose file along with the images, then bring the stack up again.
</Accordion>
<Accordion title="The agent errors or never calls tools with an OpenAI-compatible model">
Models served through OpenAI-compatible endpoints (vLLM and similar) often lack full native tool-calling support, which the agent depends on in build chats as well as published runs.
Pick a model that supports tool calling natively. If a compatible model still errors, check **Token parameter name** in the model's settings on the provider: some newer models require `max_completion_tokens`, and auto-detection can guess wrong.
Some OpenAI models reject tool calls when reasoning is enabled over the Chat Completions protocol. For those, set the provider credential's **API Protocol** to Responses API.
</Accordion>
<Accordion title="The agent errors on or ignores uploaded images">
Image upload can be turned on in **Chat Features** regardless of whether the agent's model supports vision. With a non-vision model, the agent may error on an image or reply as if none was sent.
Switch to a model that supports vision: look for the Vision tag when picking the model.
</Accordion>
<Accordion title="The agent can't fetch files or pages from your internal network">
The sandbox's internet access goes through a proxy that blocks private-network addresses by design. Public URLs work; for material on your intranet, add it to the agent's [Files](#files) instead.
</Accordion>
</AccordionGroup>
# Agent
Source: https://docs.dify.ai/en/self-host/use-dify/build/new-agent/overview
Build an agent once, then put it to work as a standalone app or inside a workflow
<Warning>
**Data Security Notice**
Community Edition uses file-access controls to limit access to agent and session files when the same agent is exposed to multiple end users. These controls reduce the risk of cross-conversation data access through the filesystem, but the Agent runtime is not intended to provide a hardened security boundary between mutually untrusted users or workloads.
If your deployment requires strong isolation or strict security or compliance controls, use separately hardened infrastructure or contact Dify to assess an appropriate Cloud or Enterprise option. For Dify Enterprise, [contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Warning>
<Note>
The new Agent is in beta. It's on by default on Docker Compose, with its runtime bundled in.
For production, replace [`DIFY_AGENT_SERVER_SECRET_KEY`](/en/self-host/deploy/configuration/environments#dify_agent_server_secret_key) and [`DIFY_AGENT_API_TOKEN`](/en/self-host/deploy/configuration/environments#dify_agent_api_token) with your own random values.
</Note>
An *Agent* is an AI worker you set up once and then put to work. It's a different kind of agent than the [Legacy Agent app](/en/self-host/use-dify/build/agent):
* It works in a **sandbox of its own**: it runs commands, installs programs, and reads and writes files, so it takes on open-ended work rather than just calling the tools you configured.
* You [build](/en/self-host/use-dify/build/new-agent/build) it **once** and use it **two ways**: on its own as a chat app, or as [a step](/en/self-host/use-dify/nodes/agent#new-agent) inside a workflow.
Create, configure, and manage your agents on the **Agents** page. Open one anytime to refine it or revisit an earlier version.
## Capability and Task
An Agent separates what it *is* from what you ask it to *do*:
* **Its *capability* (think of it as the agent's soul) is who the agent is.**
The role and prompt you write, the model it runs on, and the skills, Dify tools, and files you give it. You shape it once and keep refining it as you learn what the agent needs.
* **Its *task* is what you ask it to do on a given run.**
When the agent works on its own, the task is the message you send it. When it works inside a workflow, the task is the instruction you give the node.
It's the same split as hiring someone: you choose a person for what they can do, then give them a specific task. Strong results need both: the right person for the job and a clear brief.
## Two Ways to Use an Agent
### On Its Own
The agent runs as its own chat app. You give it tasks by chatting, and you can publish it as a web app or call it through the service API.
Each conversation has its own memory: how much the agent keeps in mind depends on the model's context window, and a new conversation starts fresh.
Choose this when a single capable worker can reach the goal on its own: a support assistant that looks things up and answers, or a research agent that gathers sources and summarizes them.
### Inside a Workflow
You invite the agent into an [Agent node](/en/self-host/use-dify/nodes/agent#new-agent) to handle one step of a larger process. There you set only the task you want done. It's like asking a colleague to take care of one thing: you describe the task, and they bring their own skills to it.
Choose this when the work needs structure around it: several steps in a set order, branching on conditions, other kinds of nodes, or a few specialized agents handing off to each other.
However the agent runs, its sessions collect in one place: the **Logs** page, where each row carries its source—the agent's web app or a workflow that uses it.
# Handle Errors
Source: https://docs.dify.ai/en/self-host/use-dify/build/predefined-error-handling-logic
<Frame>
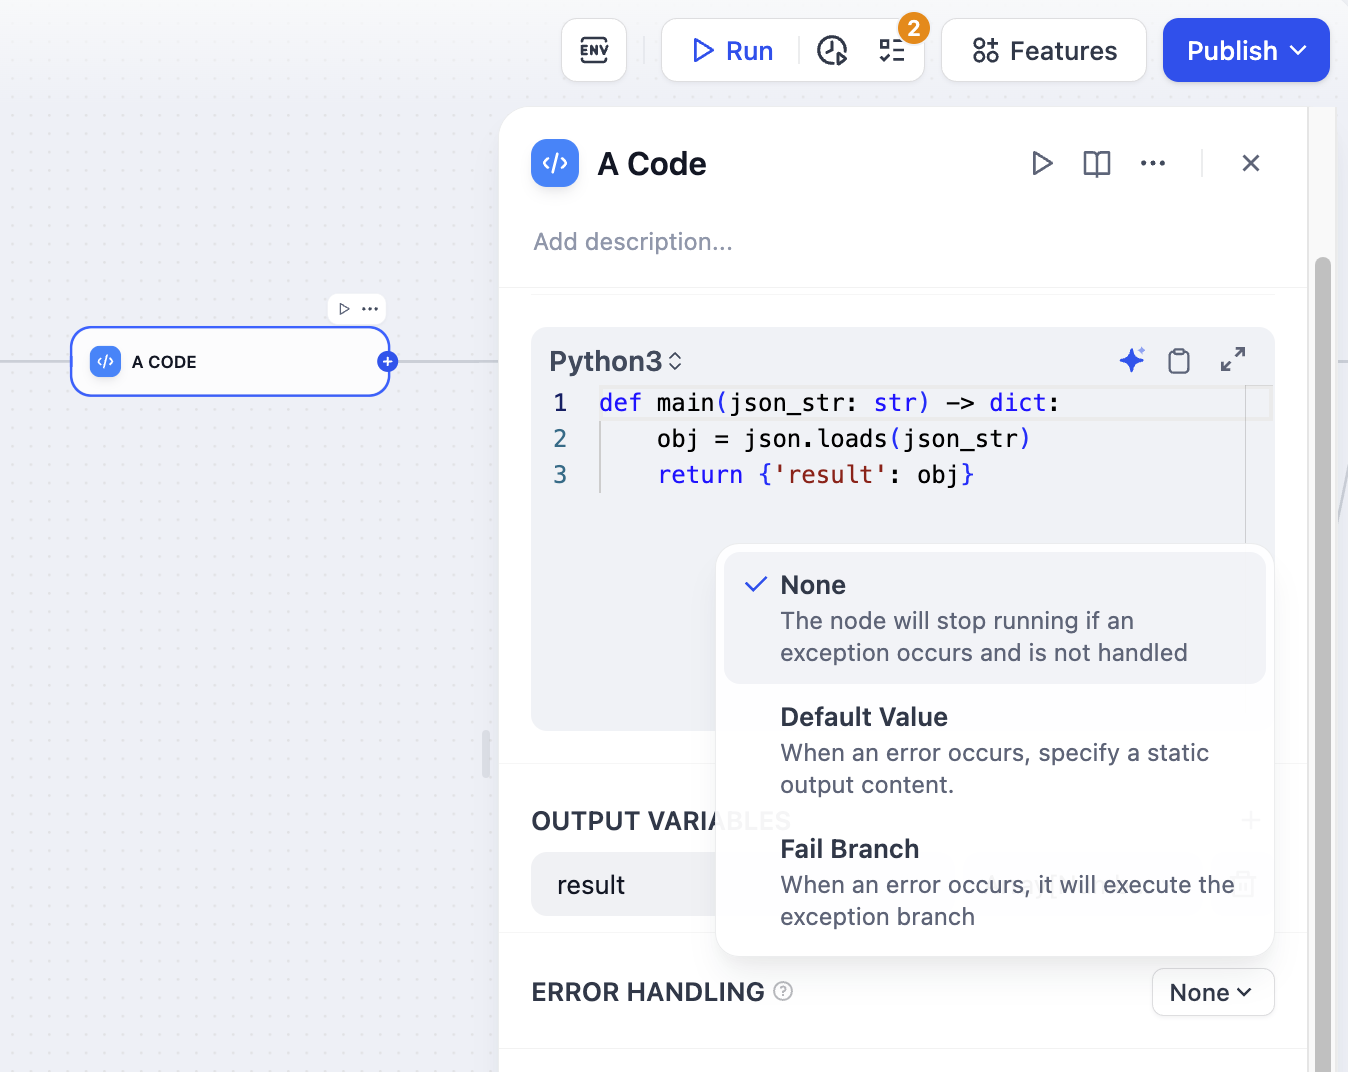
</Frame>
[LLM](/en/self-host/use-dify/nodes/llm), [HTTP](/en/self-host/use-dify/nodes/http-request), [Code](/en/self-host/use-dify/nodes/code), and [Tool](/en/self-host/use-dify/nodes/tools)
nodes support error handling out-of-box. When a node fails, it can take one of the three behaviors below:
<AccordionGroup>
<Accordion title="None">
The default behavior. When a node fails, the whole workflow stops. You get the original error message.
Use this when:
* You're testing and want to see what broke
* The workflow can't continue without this step
</Accordion>
<Accordion title="Default Value">
When a node fails, use a backup value instead. The workflow keeps running.
<Frame>
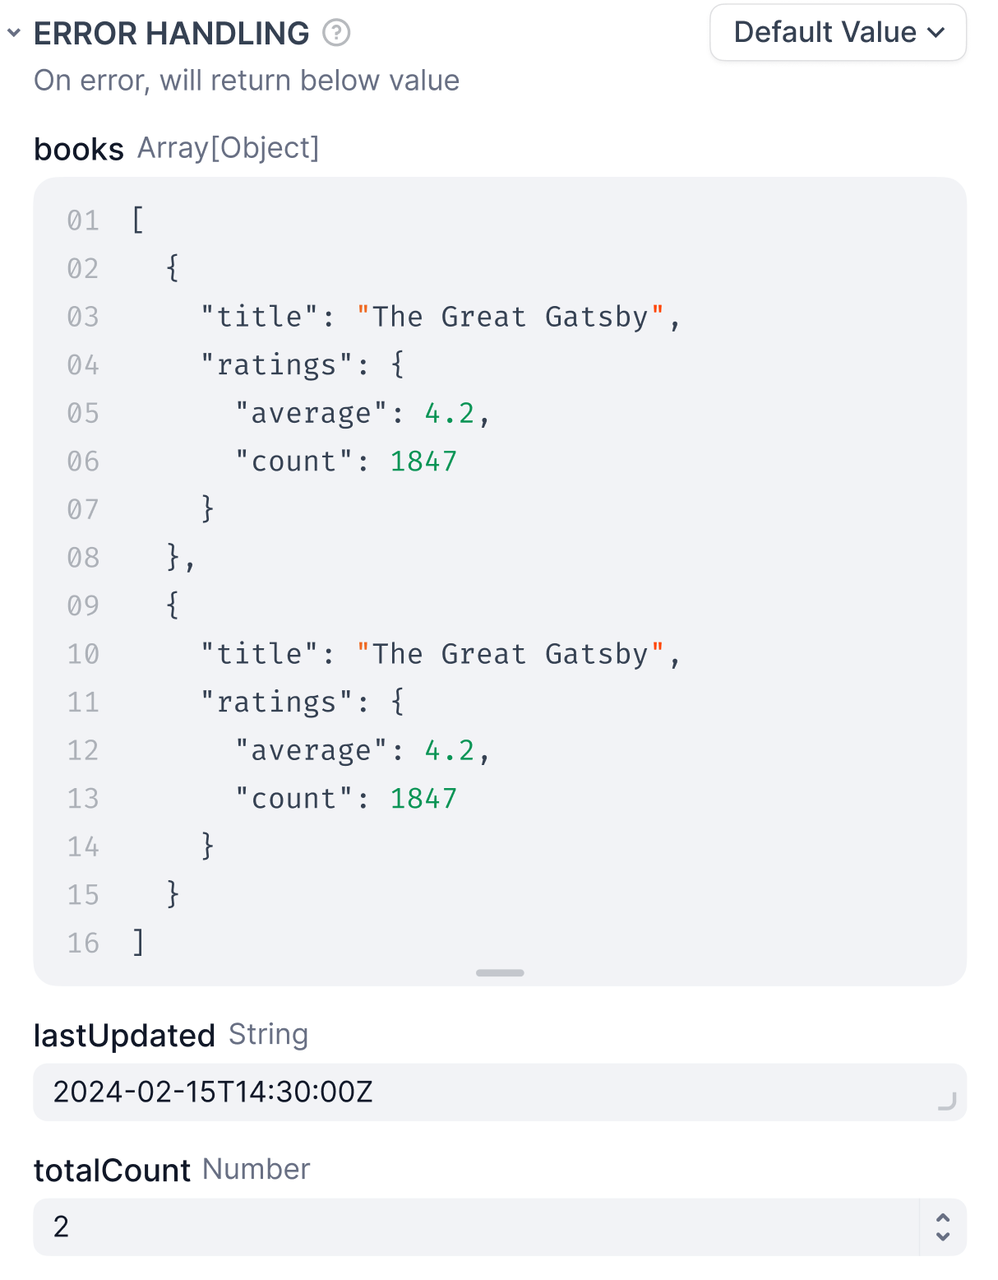
</Frame>
**Requirements**
* The default value must match the node's output type -- if it outputs a string, your default must be a string.
**Example**
Your LLM node normally returns analysis, but sometimes it fails due to rate limits. Set a default value like:
```
"Sorry, I'm temporarily unavailable. Please try again in a few minutes."
```
Now users get a helpful message instead of a broken workflow.
</Accordion>
<Accordion title="Fail Branch">
When a node fails, trigger a separate flow to handle the error.
<Frame>
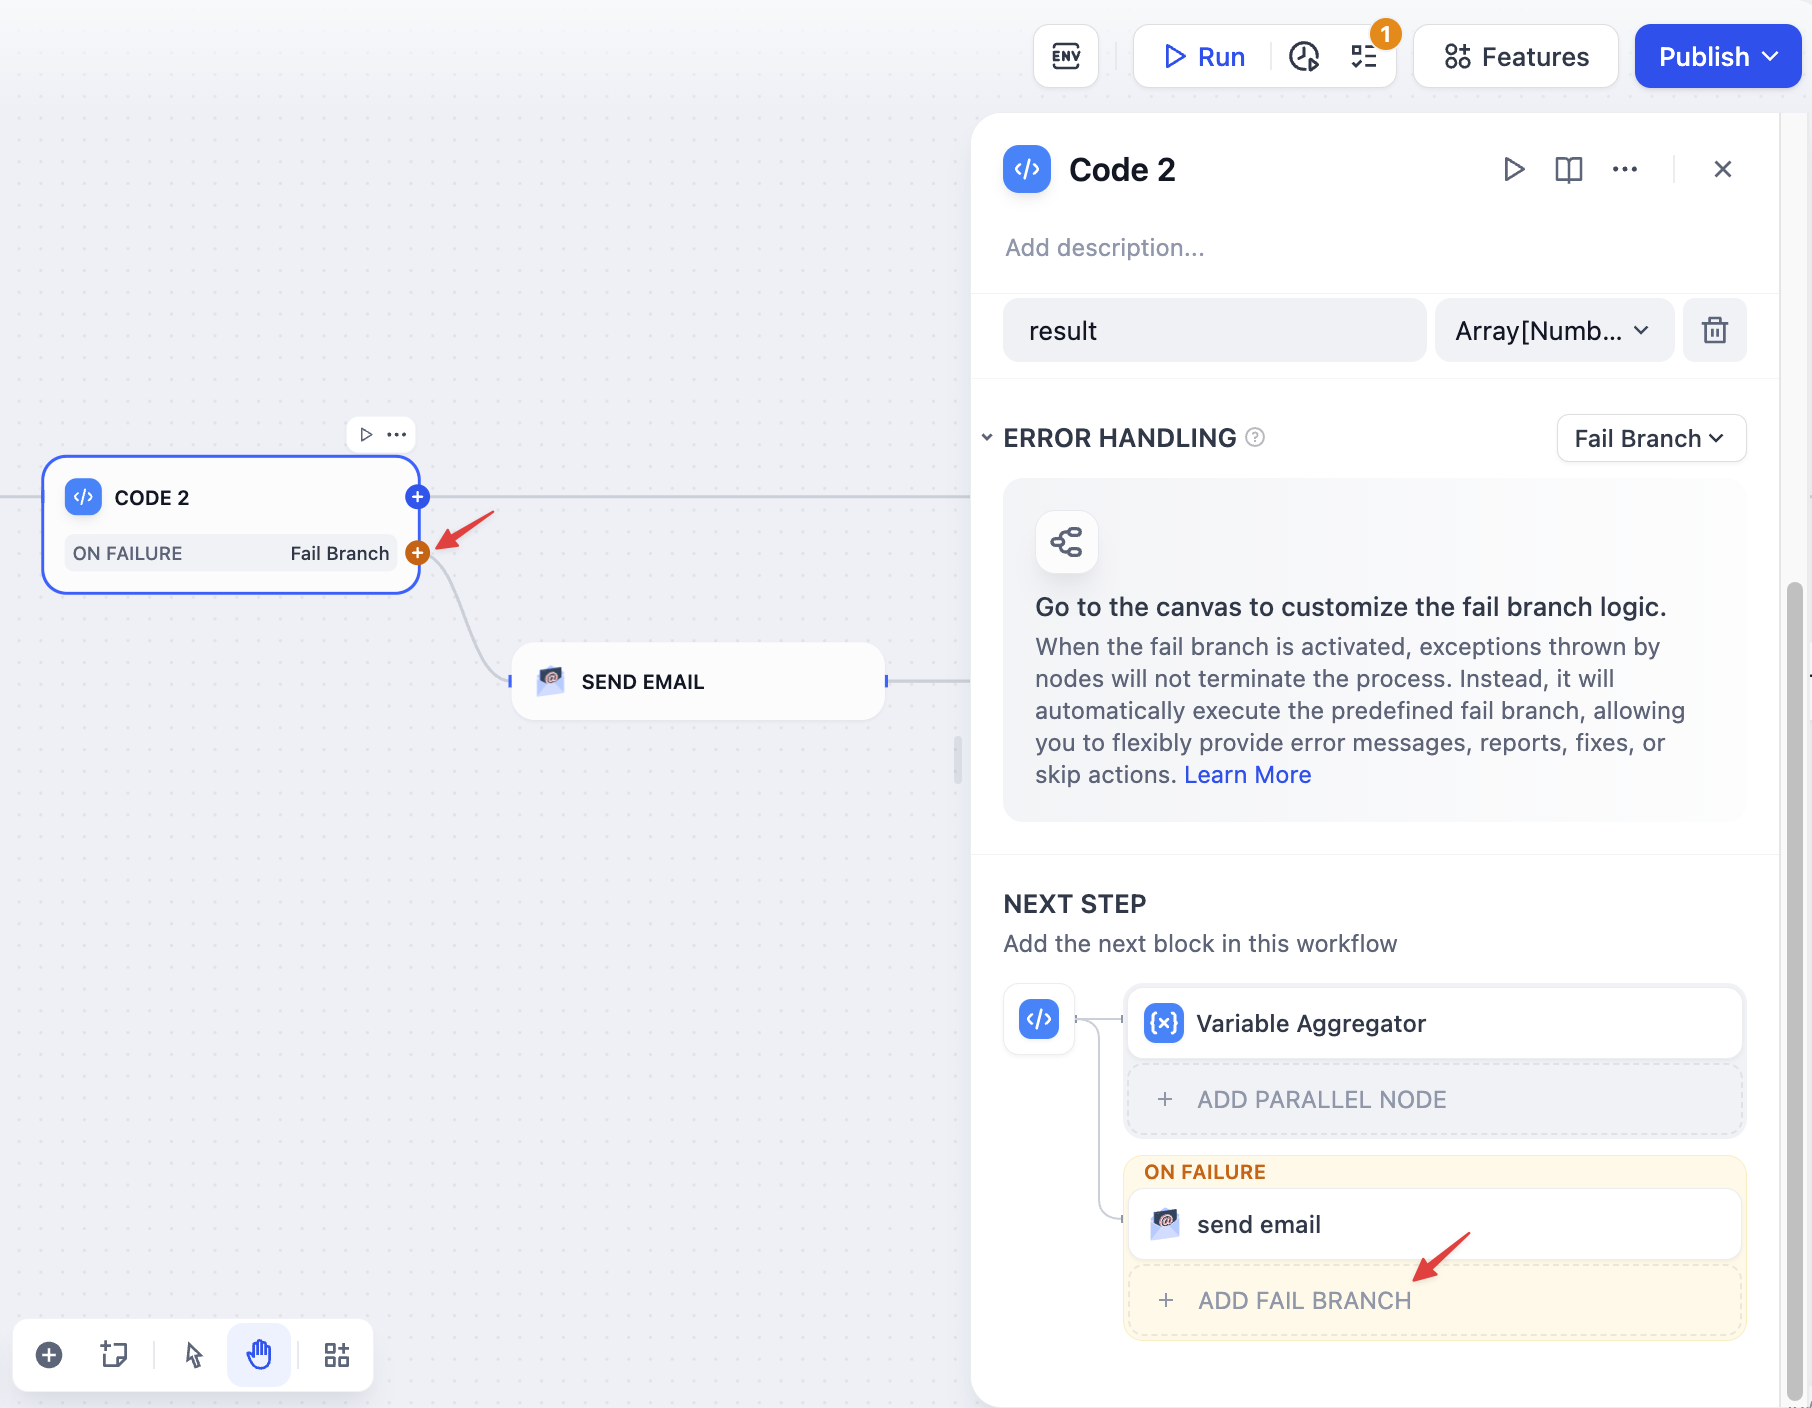
</Frame>
The fail branch is highlighted in orange. You can:
* Send error notifications
* Try a different approach
* Log the error for debugging
* Use a backup service
**Example**
Your main API fails, so the fail branch calls a backup API instead. Users never know there was a problem.
</Accordion>
</AccordionGroup>
## Error in Loop/Iteration Nodes
When child nodes fail inside loops and iterations, these control flow nodes have their own error behaviors.
**Loop nodes** always stop immediately when any child node fails. The entire loop terminates and returns the error, preventing any further iterations from running.
**Iteration nodes** let you choose how to handle child node failures through the error handling mode setting:
* `terminated` - Stops processing immediately when any item fails (default)
* `continue-on-error` - Skips the failed item and continues with the next one
* `remove-abnormal-output` - Continues processing but filters out failed items from the final output
When you set an iteration to `continue-on-error`, failed items return `null` in the output array. When you use `remove-abnormal-output`, the output array only contains successful results, making it shorter than the input array.
## Error variables
When using default value or fail branch, you get two special variables:
* `error_type` - What kind of error happened (see [Error Types](/en/self-host/use-dify/debug/error-type))
* `error_message` - The actual error details
Use these to:
* Show users helpful messages
* Send alerts to your team
* Choose different recovery strategies
* Log errors for debugging
**Example**
```
{% if error_type == "rate_limit" %}
Too many requests. Please wait a moment and try again.
{% else %}
Something went wrong. Our team has been notified.
{% endif %}
```
# Hotkeys
Source: https://docs.dify.ai/en/self-host/use-dify/build/shortcut-key
Keyboard shortcuts for building workflows faster in Dify
Speed up your workflow building with keyboard shortcuts.
<Tip>
**[Go to Anything](/en/self-host/use-dify/build/goto-anything)**: Press `Cmd+K` (macOS) or `Ctrl+K` (Windows) anywhere in Dify to find and jump to almost anything.
* Type `@` to search apps, integrations, knowledge bases, or workflow nodes.
* Type `/` to run a command like `/docs`, `/theme`, or `/language`.
<Frame>
<img alt="Go to Anything Search Interface" />
</Frame>
</Tip>
## Selection and Editing
With one or more nodes selected on the canvas:
| Windows | macOS | Action |
| :------------- | :------------- | :------------------------------------------------- |
| `Ctrl` + `C` | `Cmd` + `C` | Copy |
| `Ctrl` + `V` | `Cmd` + `V` | Paste |
| `Ctrl` + `D` | `Cmd` + `D` | Duplicate |
| `Delete` | `Delete` | Delete selected nodes or edges |
| `Shift` (hold) | `Shift` (hold) | Highlight the selected node's variable connections |
## Canvas Modes
| Windows | macOS | Action |
| :------ | :---- | :-------------------- |
| `V` | `V` | Pointer mode (select) |
| `H` | `H` | Hand mode (pan) |
| `C` | `C` | Comment mode |
## Zoom and Layout
| Windows | macOS | Action |
| :------------ | :------------ | :------------- |
| `Ctrl` + `1` | `Cmd` + `1` | Zoom to fit |
| `Ctrl` + `=` | `Cmd` + `=` | Zoom in |
| `Ctrl` + `-` | `Cmd` + `-` | Zoom out |
| `Shift` + `1` | `Shift` + `1` | Zoom to 100% |
| `Shift` + `5` | `Shift` + `5` | Zoom to 50% |
| `Ctrl` + `O` | `Cmd` + `O` | Organize nodes |
## History
| Windows | macOS | Action |
| :--------------------- | :-------------------- | :----- |
| `Ctrl` + `Z` | `Cmd` + `Z` | Undo |
| `Ctrl` + `Y` | `Cmd` + `Y` | Redo |
| `Ctrl` + `Shift` + `Z` | `Cmd` + `Shift` + `Z` | Redo |
## Testing
| Windows | macOS | Action |
| :---------- | :------------- | :------- |
| `Alt` + `R` | `Option` + `R` | Test run |
# Skills
Source: https://docs.dify.ai/en/self-host/use-dify/build/skills
Package a task and its supporting files into a reusable skill, then share it workspace-wide
A *skill* is a self-contained package you build once and reuse. It includes a `SKILL.md` that holds the instructions for one task and tells the agent when to use it, plus any reference materials and scripts the task needs. For the full format, see [Agent Skills](https://agentskills.io/home).
Create, import, and manage your library skills on the **Skills** page.
You can keep up to 500 skills in the library and share them workspace-wide. When you publish an update to a skill, every agent that uses it picks up the latest version.
Use skills in:
* [Agent apps](/en/self-host/use-dify/build/new-agent/build#skills)
* [New Agent nodes](/en/self-host/use-dify/nodes/agent#new-agent) in Workflow apps
<Info>
Creating and managing skills requires the Editor role or above.
</Info>
## Create a Skill
From **Skills**, click **Create**. To start from a copy instead, choose **Duplicate** from an existing skill's **⋯** menu; published skills are copied without draft changes. Either way you land in the editor, where you write the skill yourself or draft it with the [Skill Builder](#draft-with-the-skill-builder).
In the body of `SKILL.md`, lay out the procedure for the agent to follow. In the frontmatter, set:
* **Display name**: the name shown at the top of the sidebar and anywhere the skill appears. Make it easy to recognize.
* **Name**: the unique name agents use to reference the skill, like `refund-requests`.
* **Description**: what the agent reads to decide whether to use the skill. Make it specific.
* **Metadata**: custom fields for your own reference details, like `owner: payments-team` or `source: https://wiki.example.com/refund-policy`.
Add any scripts, references, and other supporting files through the file tree. What you can do with each depends on its type:
* **Text and code** (Markdown, scripts, JSON, YAML, and the like): edit in place.
* **CSV, images, and PDFs**: preview in place.
* **Other files**: download to view.
### Draft with the Skill Builder
Chat with the Skill Builder and it drafts the skill for you. Describe the scenario or attach existing process docs, and it writes the `SKILL.md` and creates supporting files to review and refine.
It accepts the following file types:
| Type | Examples |
| :------------ | :----------------------------------------------- |
| PDF | `.pdf` |
| Word | `.docx` |
| Excel | `.xlsx` |
| PowerPoint | `.pptx` |
| RTF | `.rtf` |
| Image | `.png`, `.jpg`, `.jpeg`, `.gif`, `.webp`, `.svg` |
| Text and data | `.txt`, `.md`, `.csv`, `.json`, `.yaml` |
Attach up to 10 files per message: images up to 10 MB and other files up to 15 MB. They are context for the Skill Builder, not part of the skill. To include a file, add it through the file tree.
## Import a Skill
To bring in a skill built elsewhere as a library skill, click **Import** and choose a `.zip` or `.skill` package. The package needs a `SKILL.md` inside and can be up to 50 MB by default, adjustable with [`UPLOAD_SKILL_FILE_SIZE_LIMIT`](/en/self-host/deploy/configuration/environments#upload_skill_file_size_limit). Once imported, it arrives as a draft for you to review and publish.
## Tag a Skill
Add tags to a skill on its card or in the editor, then filter skills by tags.
## Publish and Versions
Your edits autosave as a draft. Publish the draft so you can add it to agents. Each publish is saved as a version you can revisit or restore later. To record what a version changed, open its **⋯** menu and add a title and note.
<Note>
Restoring a version replaces your current draft. Publish the draft to make it the newest version.
</Note>
## Export a Skill
To take a skill beyond this workspace, choose **Export** from the **⋯** menu on its card. You get the skill's latest published version as a `.zip`.
## Delete a Skill
Deleting a skill removes it from the workspace and from every agent that uses it, along with all of its versions. A deleted skill can't be recovered; export a copy first if you may need it again.
# Snippets
Source: https://docs.dify.ai/en/self-host/use-dify/build/snippet
Reuse and share groups of nodes across workflows
Useful node patterns have a way of showing up in more than one workflow. Without a way to save and reuse them, you end up rebuilding the same logic every time: a particular chain of LLM and tool nodes, a data processing sequence, or a multi-step summarization pipeline.
Save a group of nodes as a reusable unit by turning them into a *snippet*: build the logic once, reuse it across workflows, and share it with your team to save others the effort of building the same thing from scratch.
You can also export snippets as DSL files to share them across workspaces.
## Create a Snippet
There are three ways to create a snippet:
* **From a workflow**
Select the nodes you want to reuse, then right-click and choose **Create Snippet**.
Their configurations are saved into the snippet. Any external variables they reference (outputs from nodes you didn't select, environment variables, and so on) become the snippet's [Input Variables](#edit-a-snippet).
<Info>
An exception: an LLM node that takes its model from an environment variable keeps that model configuration as a fixed setting, so the snippet uses the same model wherever you add it.
</Info>
* **From scratch**
In **Studio**, click **Snippets** at the top-right corner, then click **Create Snippet** > **Create from blank** to start with an empty canvas.
* **From a DSL file**
In **Studio**, click **Snippets** at the top-right corner, then click **Create Snippet** > **Import DSL file** to import an existing snippet.
A snippet you create is shared with your workspace. What each member can do with it depends on their workspace role; see [Permissions](#permissions).
## Edit a Snippet
Building a snippet works much like building a standard workflow, with two differences.
First, a few nodes aren't available. Because a snippet plugs into a workflow instead of running on its own, it has no Start node (User Input or Triggers) and no end node (Output for Workflows, Answer for Chatflows). Knowledge Retrieval and Human Input aren't supported yet either.
Second, because a snippet has no Start node to collect input, you define **Input Variables** that specify what data it expects to receive, such as a variable from an upstream node. When a snippet is added to a workflow, these input variables become the connection points.
## Publish a Snippet
As you edit, your changes save automatically as a draft, so you can pick up where you left off next time. When the draft is ready, click **Publish** to make it usable. A workflow always uses the published version, never a draft.
Every publish is kept in the snippet's version history, where you can review or restore an earlier version.
## Add a Snippet to a Workflow
Right-click on the canvas, select **Add Node** > **Snippets**, then choose one to insert. Only published snippets appear here.
The snippet is added to your canvas as a copy. In the inserted nodes, set each input variable to the appropriate variable from your workflow, so they receive the data they expect.
Editing the original snippet later won't change workflows that already use it, and vice versa.
## Permissions
What you can do with a snippet depends on your workspace role:
| Action | Roles |
| :------------------------------------ | :-------------------------------------- |
| View the snippet list | Owner, Admin, Editor |
| Create, edit, and publish snippets | Owner, Admin, Editor |
| Delete snippets | Owner, Admin |
| Add a published snippet to a workflow | Anyone who can edit the target workflow |
Members with the Normal role don't see the snippet list.
<Tip>
On Dify Enterprise, administrators can reassign these permissions to custom roles. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
# Text Generator
Source: https://docs.dify.ai/en/self-host/use-dify/build/text-generator
Simple single-turn apps for generating text from a prompt and user inputs
Text Generators are simple single-turn apps: you write a prompt, provide inputs, and the model generates a response.
It's a good fit for tasks that don't require multi-turn conversation, tool calls, or a multi-step workflow. Just a clear input, one model call, and a ready-to-use output.
<Tip>
Text Generators support optional features like generating multiple outputs at once, text to speech, and content moderation. See [App Toolkit](/en/self-host/use-dify/build/additional-features) for details.
</Tip>
## Configure
### Write the Prompt
The prompt tells the model what to do, how to respond, and what constraints to follow.
Since a Text Generator runs in a single turn with no conversation history, the prompt is the model's only source of context—include everything it needs to produce the right output in one pass.
Here are some tips for writing effective prompts:
* **Define the task clearly**: State what the model should produce (e.g., a translation, a summary, a SQL statement).
* **Specify the output format**: Describe the structure, length, or style you expect.
* **Set constraints**: Tell the model what to avoid or what rules to follow.
Because a Text Generator always requires user input to run, a paragraph-type `query` variable is automatically inserted into the prompt when you create a new app. You can rename `query` or change its type.
Variables are placeholders—each one becomes an input field that users fill in before running the app, and their values are substituted into the prompt at runtime. For example:
```text wrap theme={null}
You are a professional editor. Summarize the following text into 3 concise bullet points. Use neutral tone and avoid adding information not present in the original text.
{{query}}
```
<Tip>
While drafting the prompt, type `/` > **New Variable** to quickly insert a named placeholder. You can configure its details in the **Variables** section later.
</Tip>
Choose the variable type that matches the input you expect:
<Tabs>
<Tab title="Short Text">
Accepts up to 256 characters. Use it for names, email addresses, titles, or any brief text input that fits on a single line.
</Tab>
<Tab title="Paragraph">
Allows long-form text without length restrictions. It gives users a multi-line text area for detailed descriptions.
</Tab>
<Tab title="Select">
Displays a dropdown menu with predefined options.
</Tab>
<Tab title="Number">
Restricts input to numerical values only—ideal for quantities, ratings, IDs, or any data requiring mathematical processing.
</Tab>
<Tab title="Checkbox">
Provides a simple yes/no option. When a user checks the box, the output is `true`; otherwise, it's `false`. Use it for confirmations or any case that requires a binary choice.
</Tab>
<Tab title="API-based Variable">
Fetches variable values from an external API at runtime instead of collecting them from users.
Use it when your prompt needs dynamic data from an external source, such as live weather conditions or database records. See [Custom Endpoints](/en/self-host/use-dify/workspace/api-extension/api-extension) for details.
</Tab>
</Tabs>
<Info>
**Label Name** is what end users see for each input field.
</Info>
#### Create Dynamic Prompts with Variables
To adapt your app to different users or contexts without rewriting the prompt each time, add more variables.
Each variable collects a specific piece of information upfront and injects it into the prompt at runtime.
For example, an SQL generator might use `database_type` to adapt the output dialect while `query` captures the user's natural language request:
```text wrap theme={null}
You are an SQL generator. Translate the following natural language query into a {{database_type}} SQL statement: {{query}}
```
#### Generate or Improve the Prompt with AI
If you're unsure where to start or want to refine the existing prompt, click **Generate** to let an LLM help you draft it.
Describe what you want from scratch, or reference `current_prompt` and specify what to improve. For more targeted results, add an example in **Ideal Output**.
Each generation is saved as a version, so you can experiment and roll back freely.
### Ground Responses in Your Own Data
To ground the model's responses in your own data rather than general knowledge, add a knowledge base and select an existing variable as the **Query Variable**.
When a user runs the app and fills in that field, its value is used as the search query to retrieve relevant content from the knowledge base. The retrieved content is then injected into the prompt as context, so the model can generate a more informed response.
<Accordion title="Example: Use Content Type to Retrieve Style Guides in a Content Writing App">
For example, suppose your knowledge base contains style guides for different content types—blog posts, social media captions, product descriptions, and so on.
In a content writing app, set `content_type` as the **Query Variable**. When a user selects a content type, the app retrieves the matching style guide and generates copy that follows the corresponding writing standards.
Your prompt might look like this:
```text wrap theme={null}
You are a brand content writer. Write a {{content_type}} based on the following brief: {{brief}}
Follow the style and tone guidelines provided in the context.
```
</Accordion>
#### Configure App-Level Retrieval Settings
To fine-tune how retrieval results are processed, click **Retrieval Setting**.
<Info>
There are two layers of retrieval settings—the knowledge base level and the app level.
Think of them as two consecutive filters: the knowledge base settings determine the initial pool of results, and the app settings further rerank the results or narrow down the pool.
</Info>
* **Rerank Settings**
* **Weighted Score**
The relative weight between semantic similarity and keyword matching during reranking. Higher semantic weight favors meaning relevance, while higher keyword weight favors exact matches.
Weighted Score is available only when all added knowledge bases are indexed with **High Quality** mode.
* **Rerank Model**
The rerank model to re-score and reorder all the results based on their relevance to the query.
<Note>
If any multimodal knowledge bases are added, select a multimodal rerank model (marked with a **Vision** tag) as well. Otherwise, retrieved images will be excluded from reranking and the final output.
</Note>
* **Top K**
The maximum number of top results to return after reranking.
When a rerank model is selected, this value will be automatically adjusted based on the model's maximum input capacity (how much text the model can process at once).
* **Score Threshold**
The minimum similarity score for returned results. Results scoring below this threshold are excluded. Use higher thresholds for stricter relevance or lower thresholds to include broader matches.
#### Search Within Specific Documents
By default, retrieval searches across the entire knowledge base. To restrict retrieval to specific documents, enable manual or automatic metadata filtering.
This improves retrieval precision, especially when your knowledge base is large or contains content for different contexts.
For creating and managing document metadata, see [Metadata](/en/self-host/use-dify/knowledge/metadata).
### Process Multimodal Inputs
To allow end users to upload files, select a model with the corresponding multimodal capabilities. The relevant file type toggles—**Vision**, **Audio**, or **Document**—appear once the model supports them, and you can enable each as needed.
<Tip>
You can quickly identify a model's supported modalities by its tags.
<Frame>
<img alt="Model Tags" />
</Frame>
</Tip>
Click **Settings** under **Vision** to configure how files are accepted and processed. Upload settings apply across all enabled file types.
* **Resolution**: Controls the detail level for **image** processing only.
* **High**: Better accuracy for complex images but uses more tokens
* **Low**: Faster processing with fewer tokens for simple images
* **Upload Method**: Choose whether users can upload from their device, paste a URL, or both.
* **Upload Limit**: The maximum number of files a user can upload per run.
<Info>
Adjust file size limits via the following environment variables:
* `UPLOAD_IMAGE_FILE_SIZE_LIMIT` (default: 10 MB)
* `UPLOAD_FILE_SIZE_LIMIT` (default: 15 MB)
* `UPLOAD_AUDIO_FILE_SIZE_LIMIT` (default: 50 MB)
See [Environment Variables](/en/self-host/deploy/configuration/environments) for details.
</Info>
## Debug & Preview
In the preview panel on the right, test your app in real time. Select a model that best fits your task, fill in the input fields, and click **Run** to see the output.
After selecting a model, you can adjust its parameters to control how it generates responses. Available parameters and presets vary by model.
<Tip>
To compare outputs across different models, click **Debug as Multiple Models** to run up to 4 models simultaneously.
<Frame>
<img alt="Debug with Multiple Models" />
</Frame>
</Tip>
## Publish
When you're happy with the results, click **Publish** to make your app available. See [Publish](/en/self-host/use-dify/publish/README) for the full list of publishing options.
When running the web app, end users can save individual outputs for future reference.
<Frame>
<img alt="Save Output" />
</Frame>
# Version Control
Source: https://docs.dify.ai/en/self-host/use-dify/build/version-control
Track changes and manage versions in Chatflow and Workflow apps.
<Info>
Only available for Chatflow and Workflow apps right now.
</Info>
## How it works
**Current Draft**: Your working version. This is where you make changes. Not live for users.
<Frame>
</Frame>
**Latest Version**: The live version users see.
<Frame>
</Frame>
**Previous Versions**: Older published versions.
<Frame>
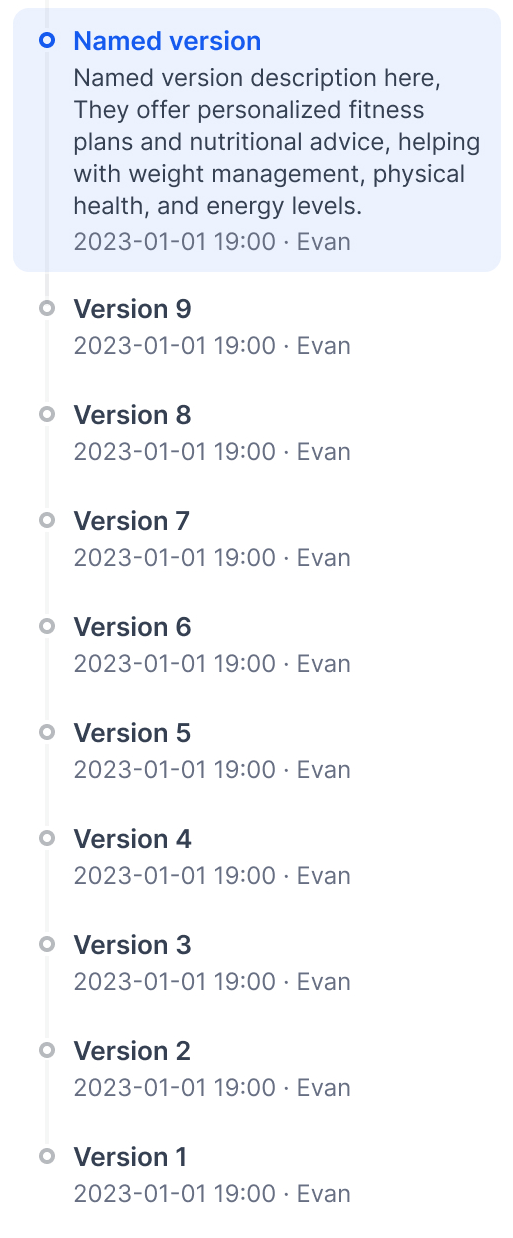
</Frame>
## Publish versions
Click **Publish** → **Publish Update** to make your draft live.
<Frame>
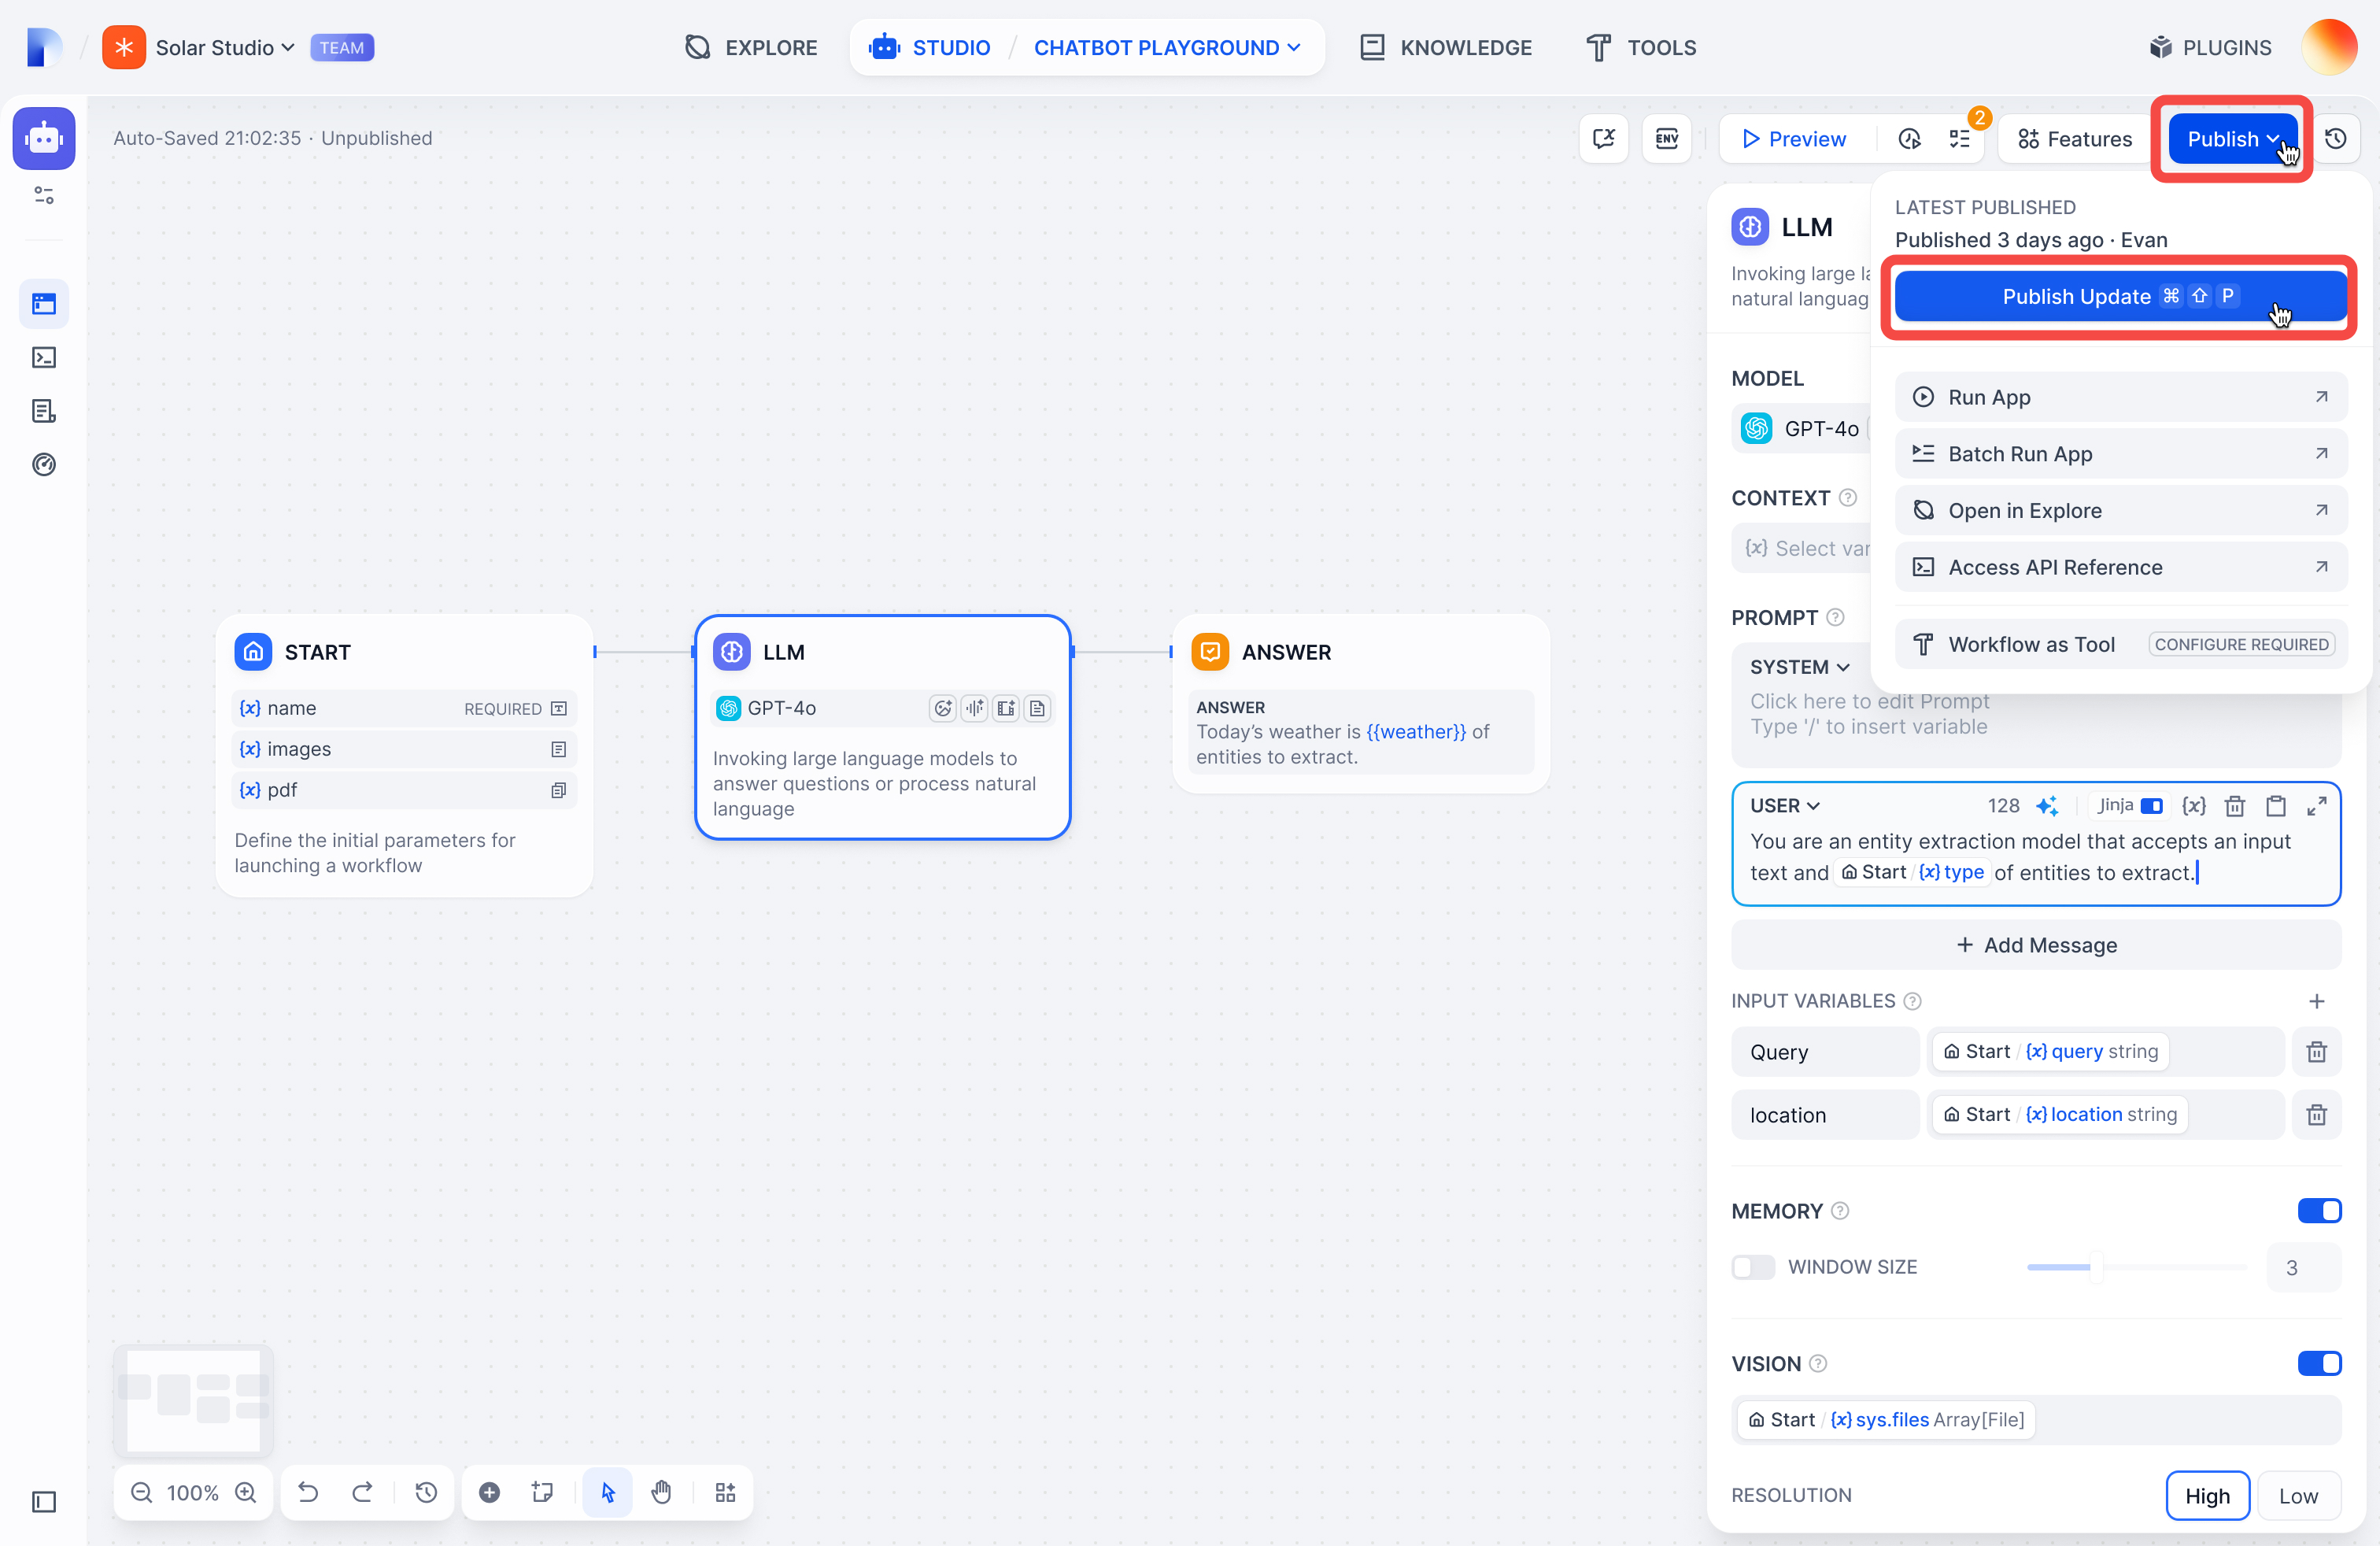
</Frame>
Your draft becomes the new Latest Version, and you get a fresh draft to work in.
<Frame>
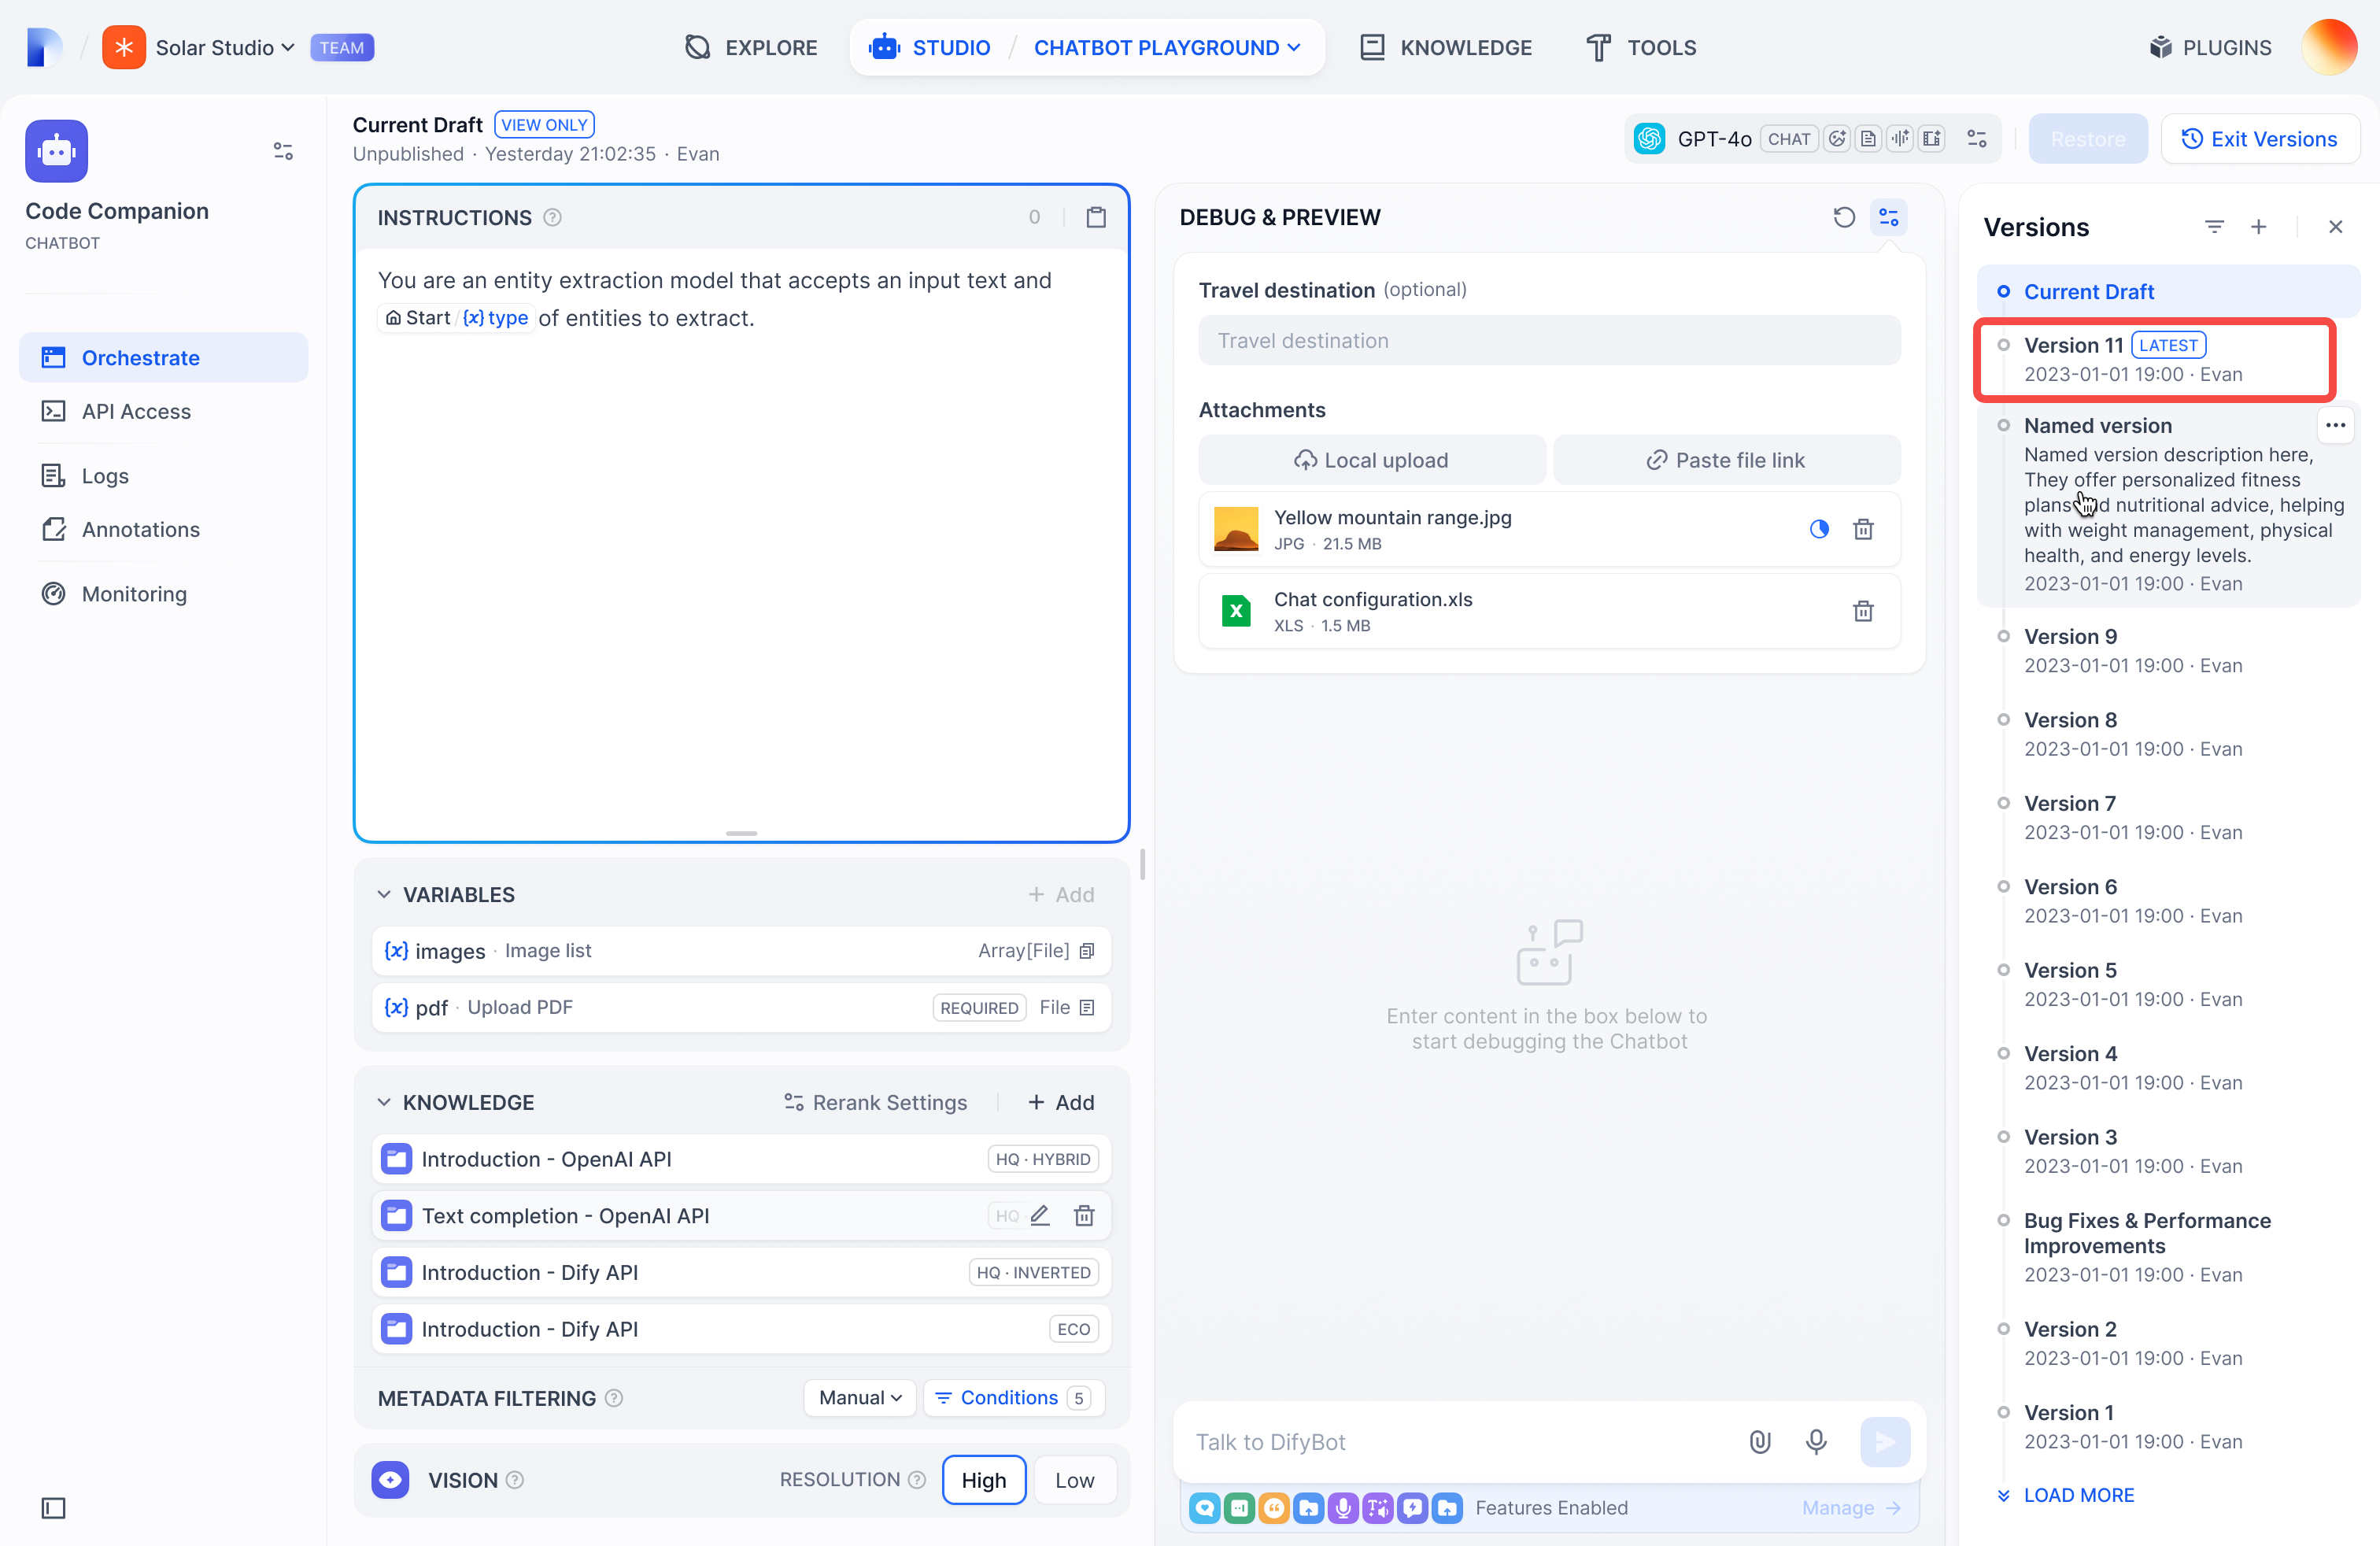
</Frame>
## View versions
Click the history icon to see all versions:
<Frame>
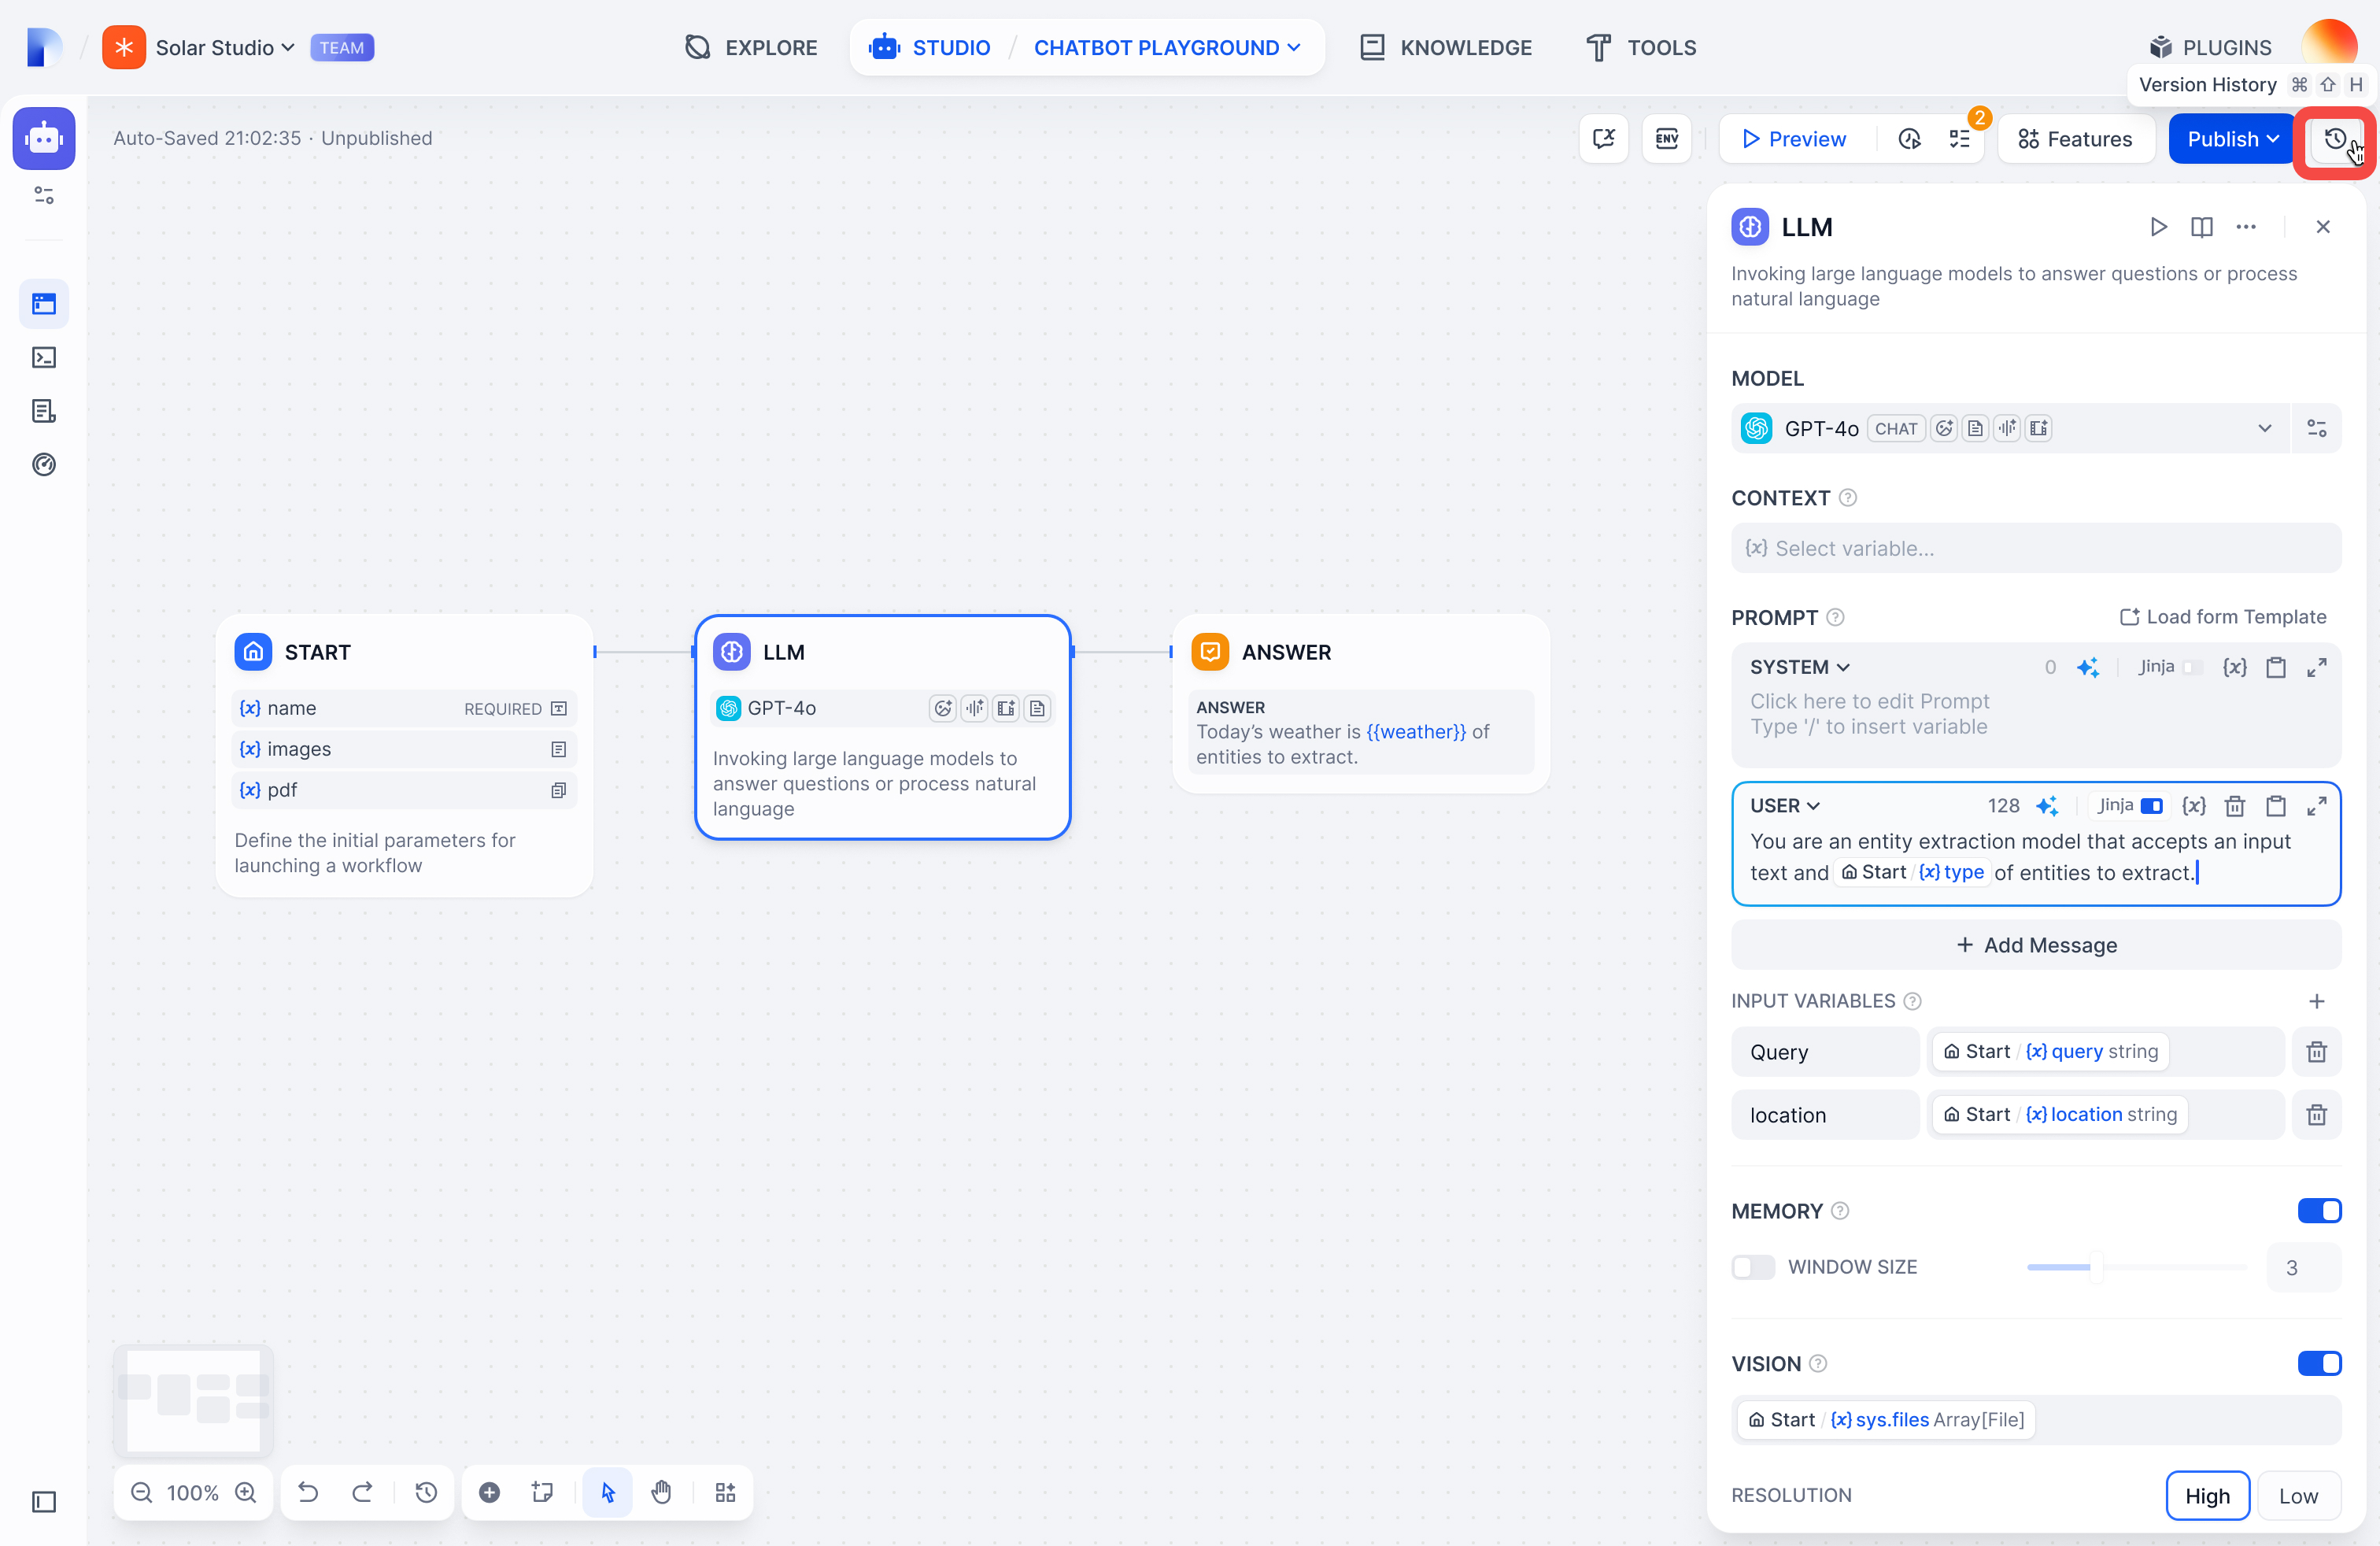
</Frame>
Filter by:
* **All versions** or **only yours**
* **Only named versions** (skip auto-generated names)
<Frame>
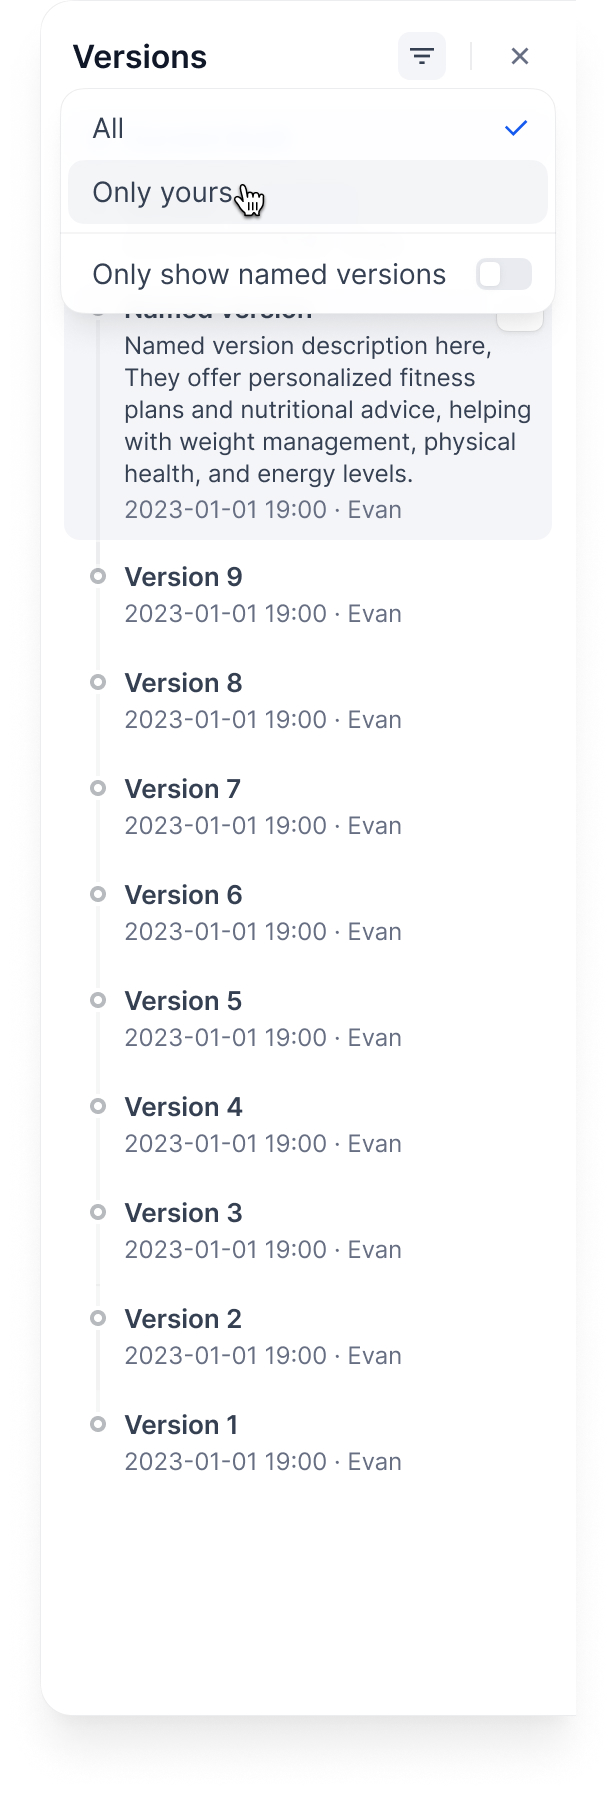
</Frame>
## Manage versions
**Name a version**: Give it a proper name instead of the auto-generated one
<Frame>
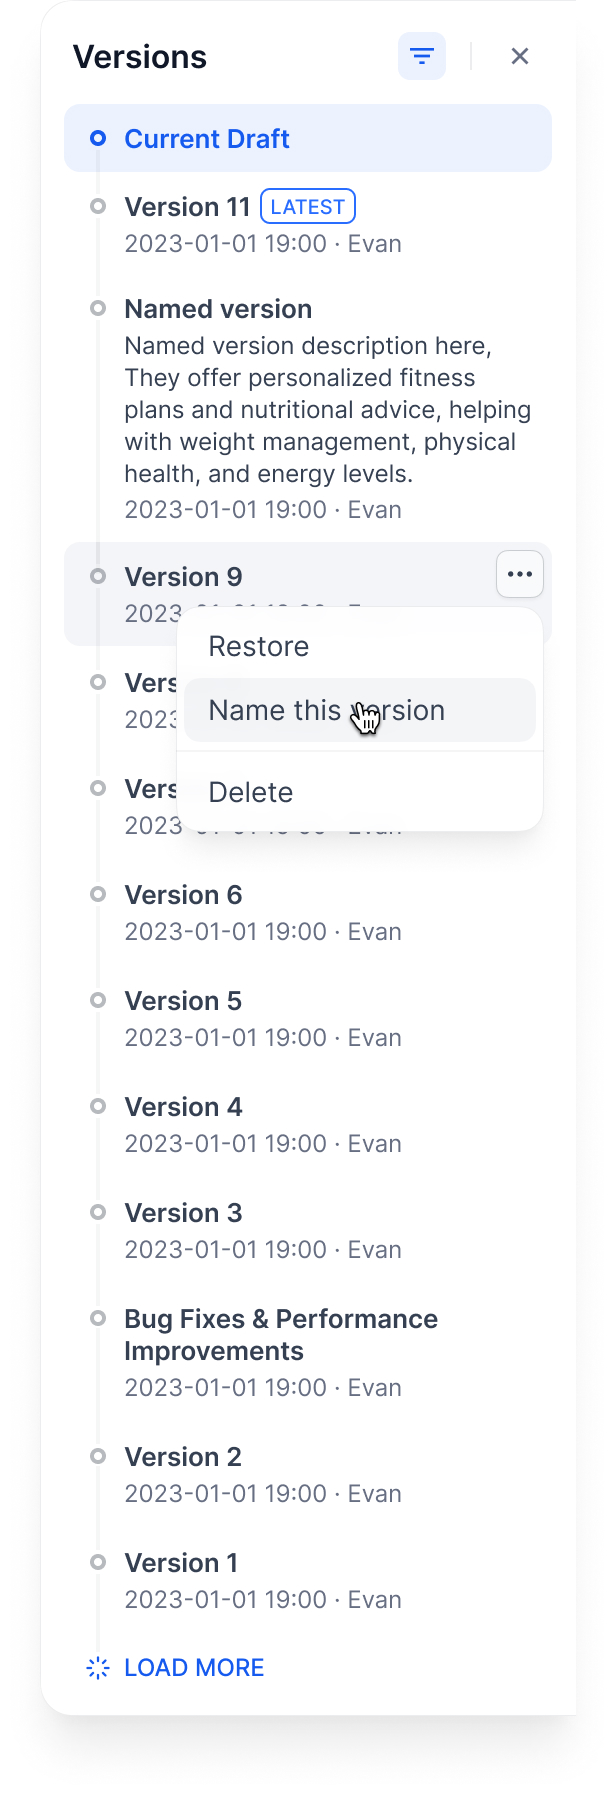
</Frame>
**Edit version info**: Change the name and add release notes
<Frame>
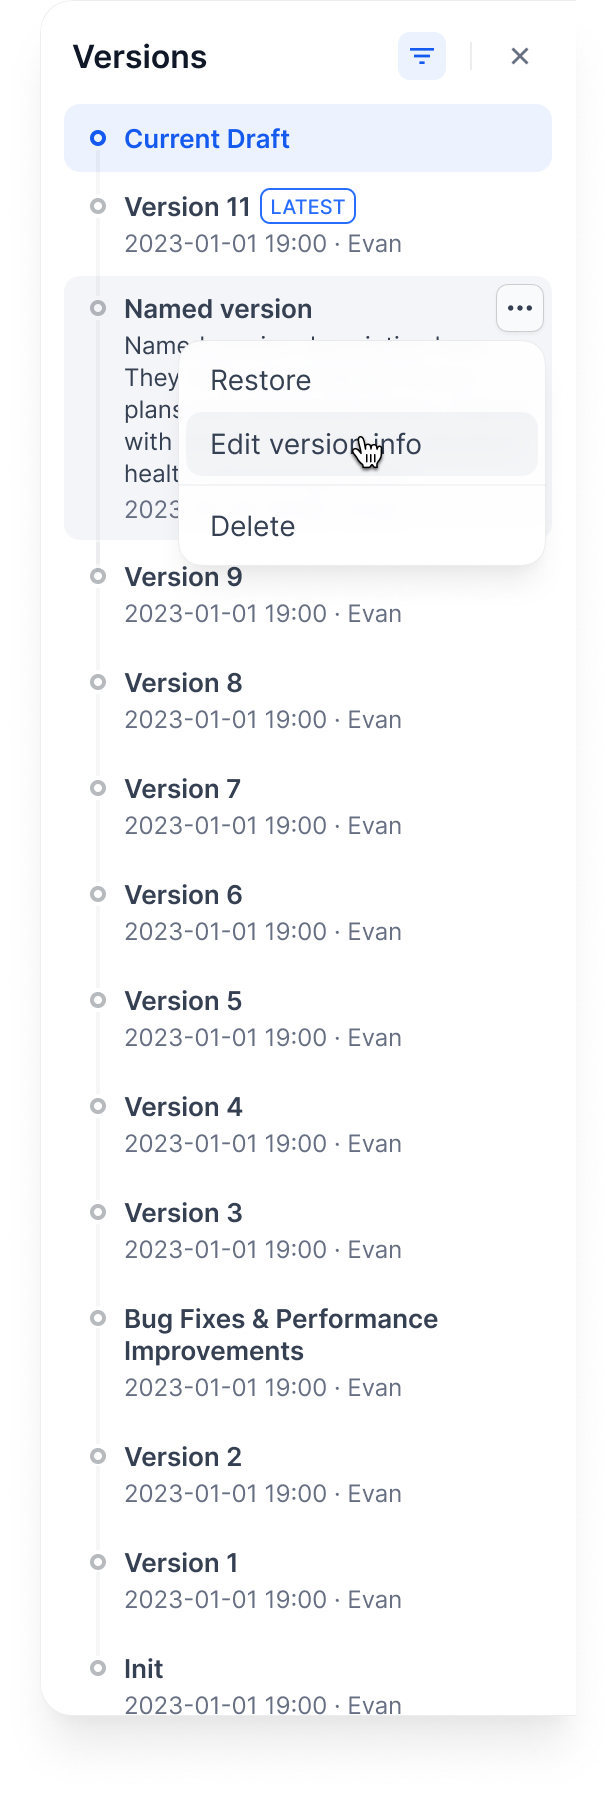
</Frame>
**Delete old versions**: Clean up versions you don't need
<Frame>
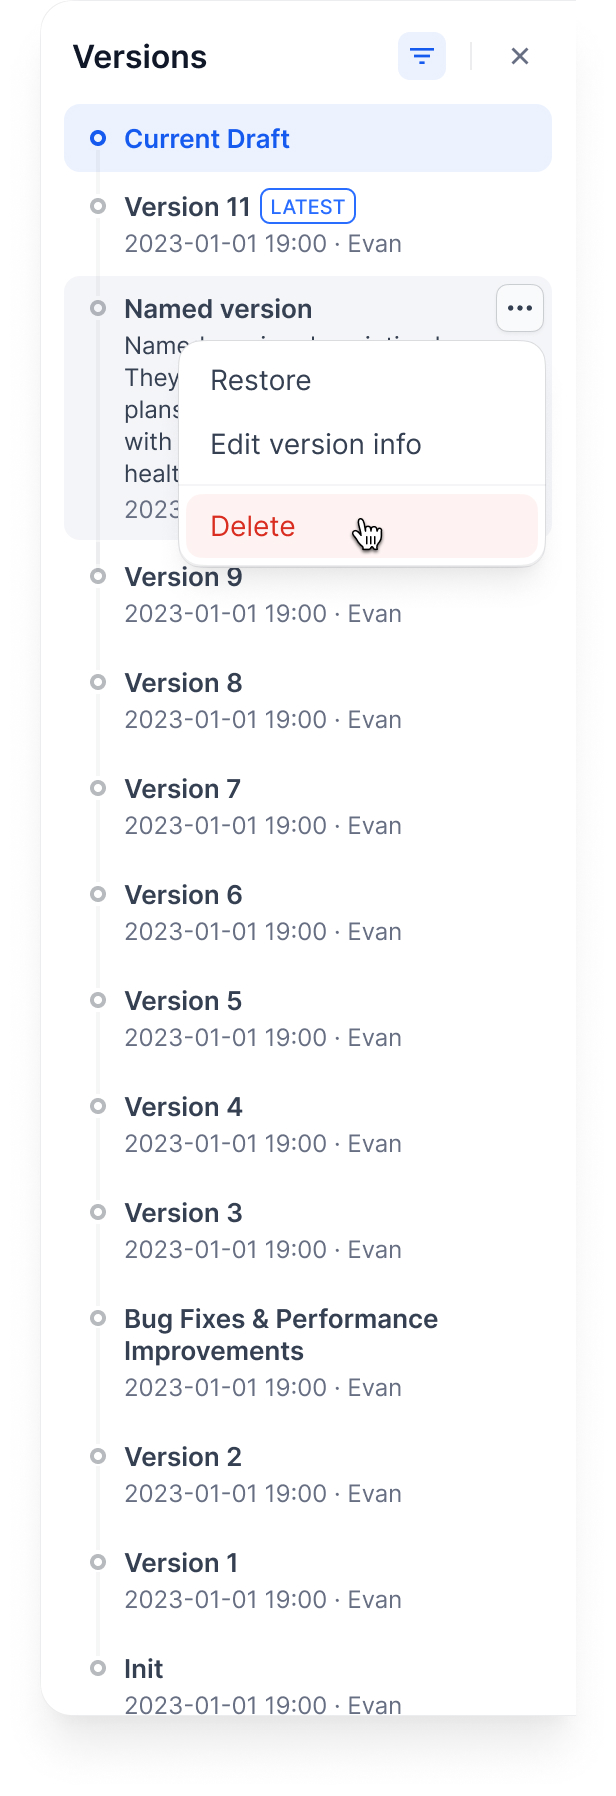
</Frame>
<Warning>
You can't delete the Current Draft or Latest Version.
</Warning>
**Restore a version**: Load an old version back into your draft
<Frame>
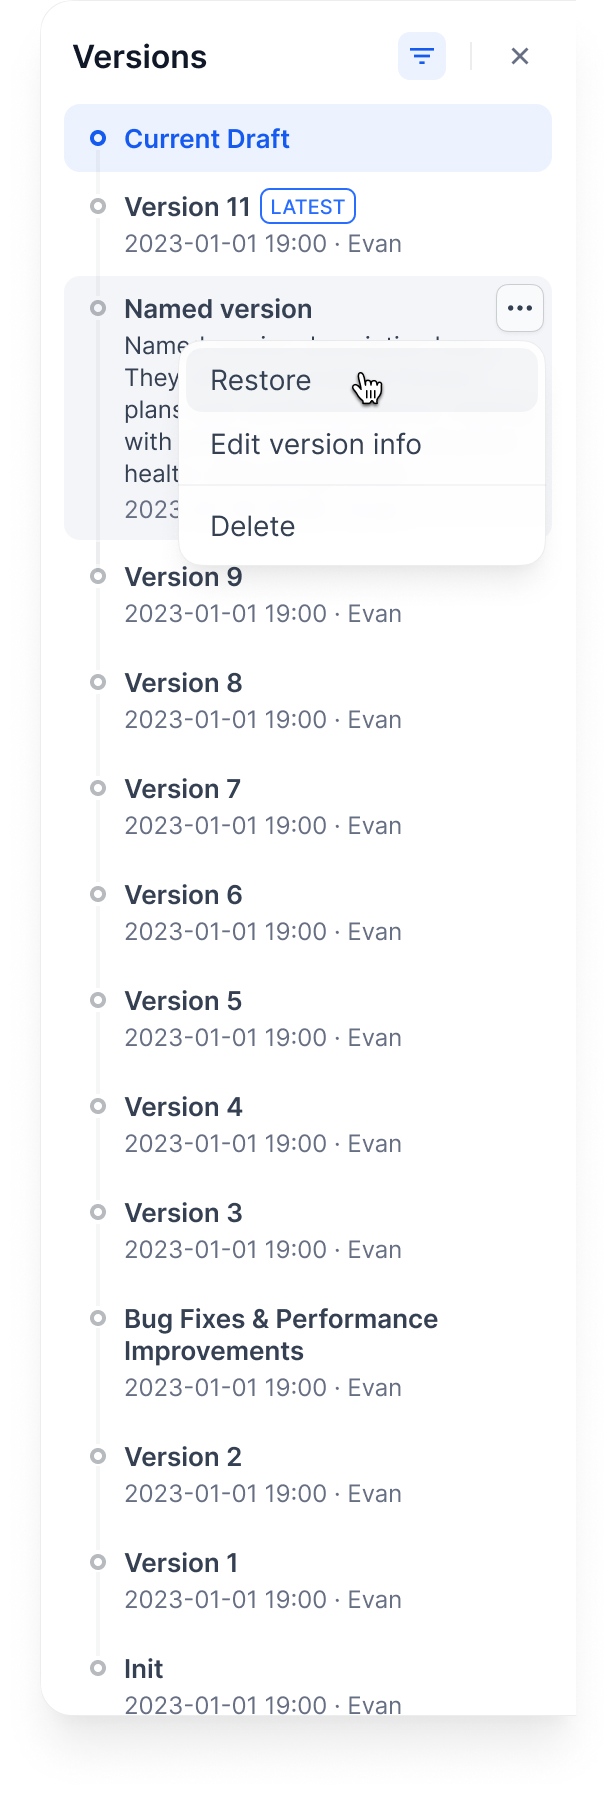
</Frame>
<Warning>
This replaces your current draft completely. Make sure you don't have unsaved work.
</Warning>
## Example workflow
Here's how versions work through a typical development cycle:
### 1. Start with a draft
<Frame>
</Frame>
### 2. Publish first version
<Frame>
</Frame>
### 3. Publish second version
<Frame>
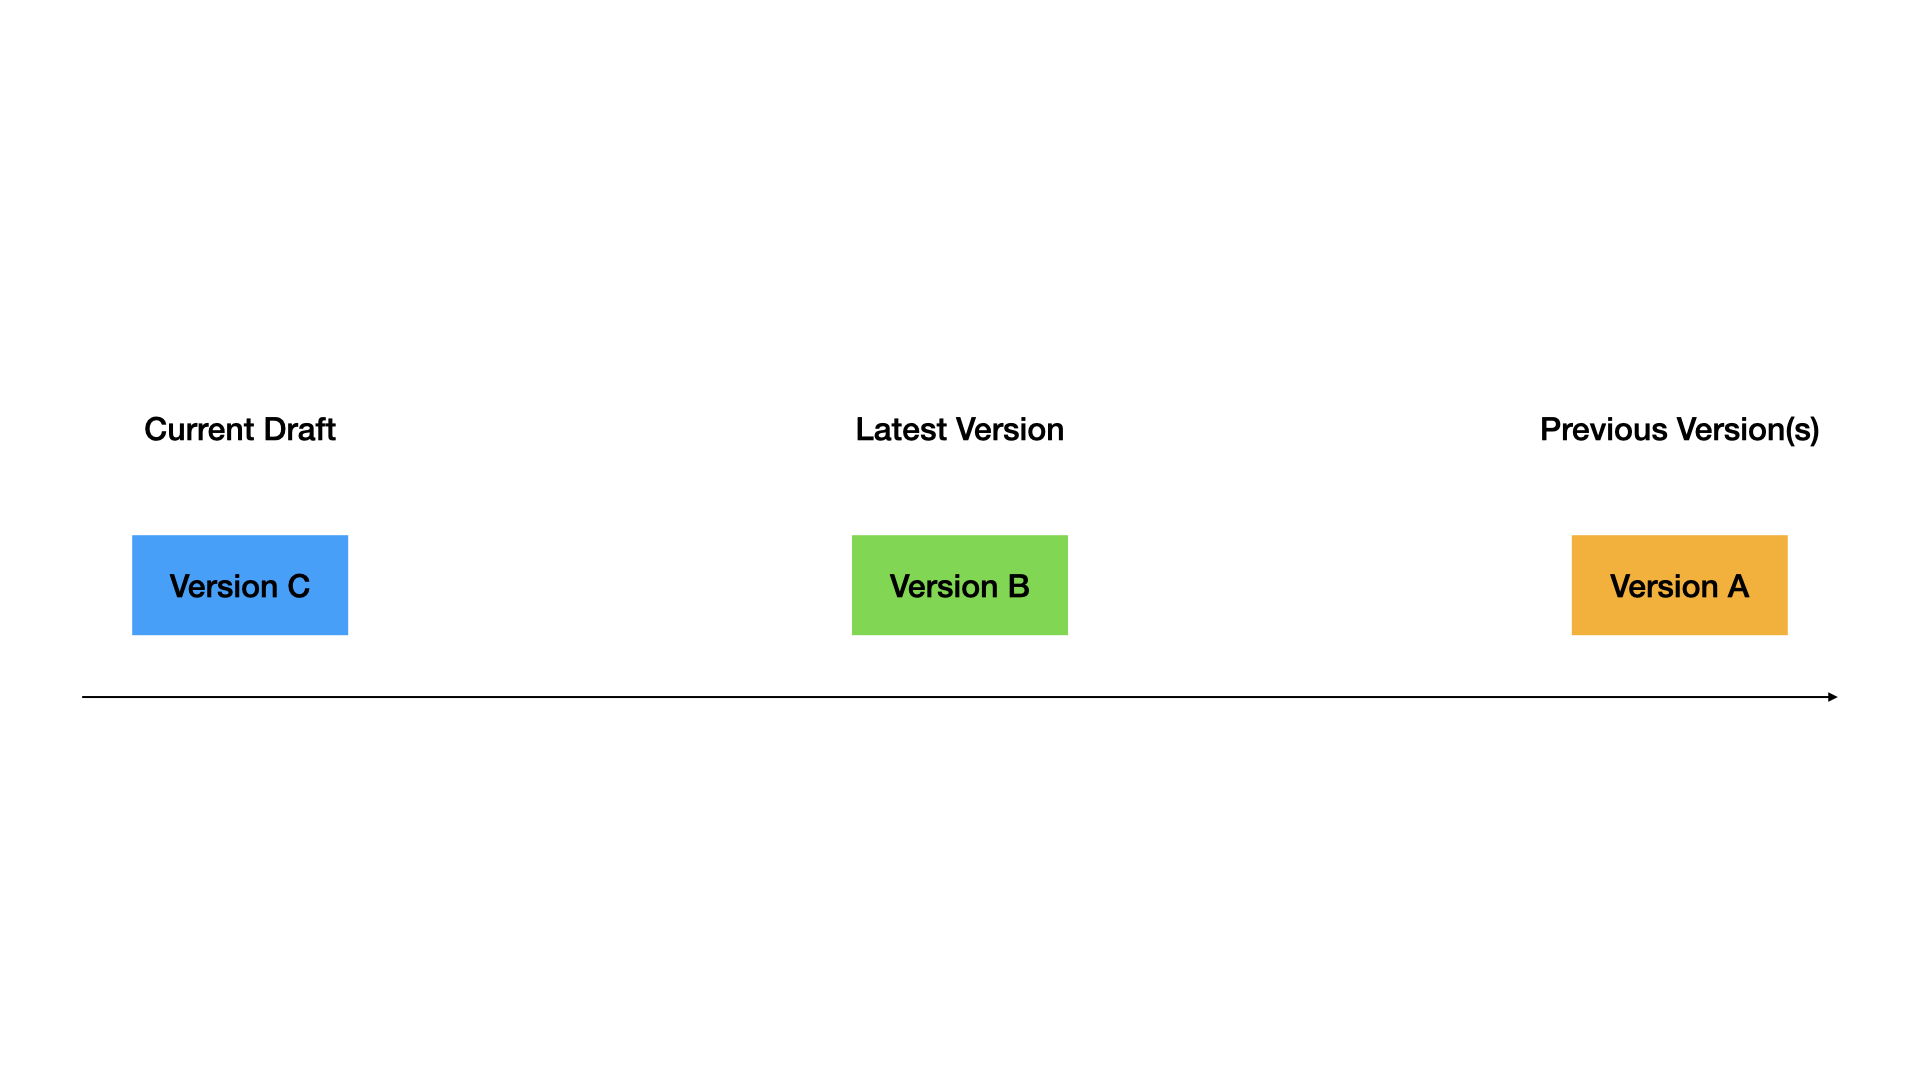
</Frame>
### 4. Restore old version to draft
<Frame>
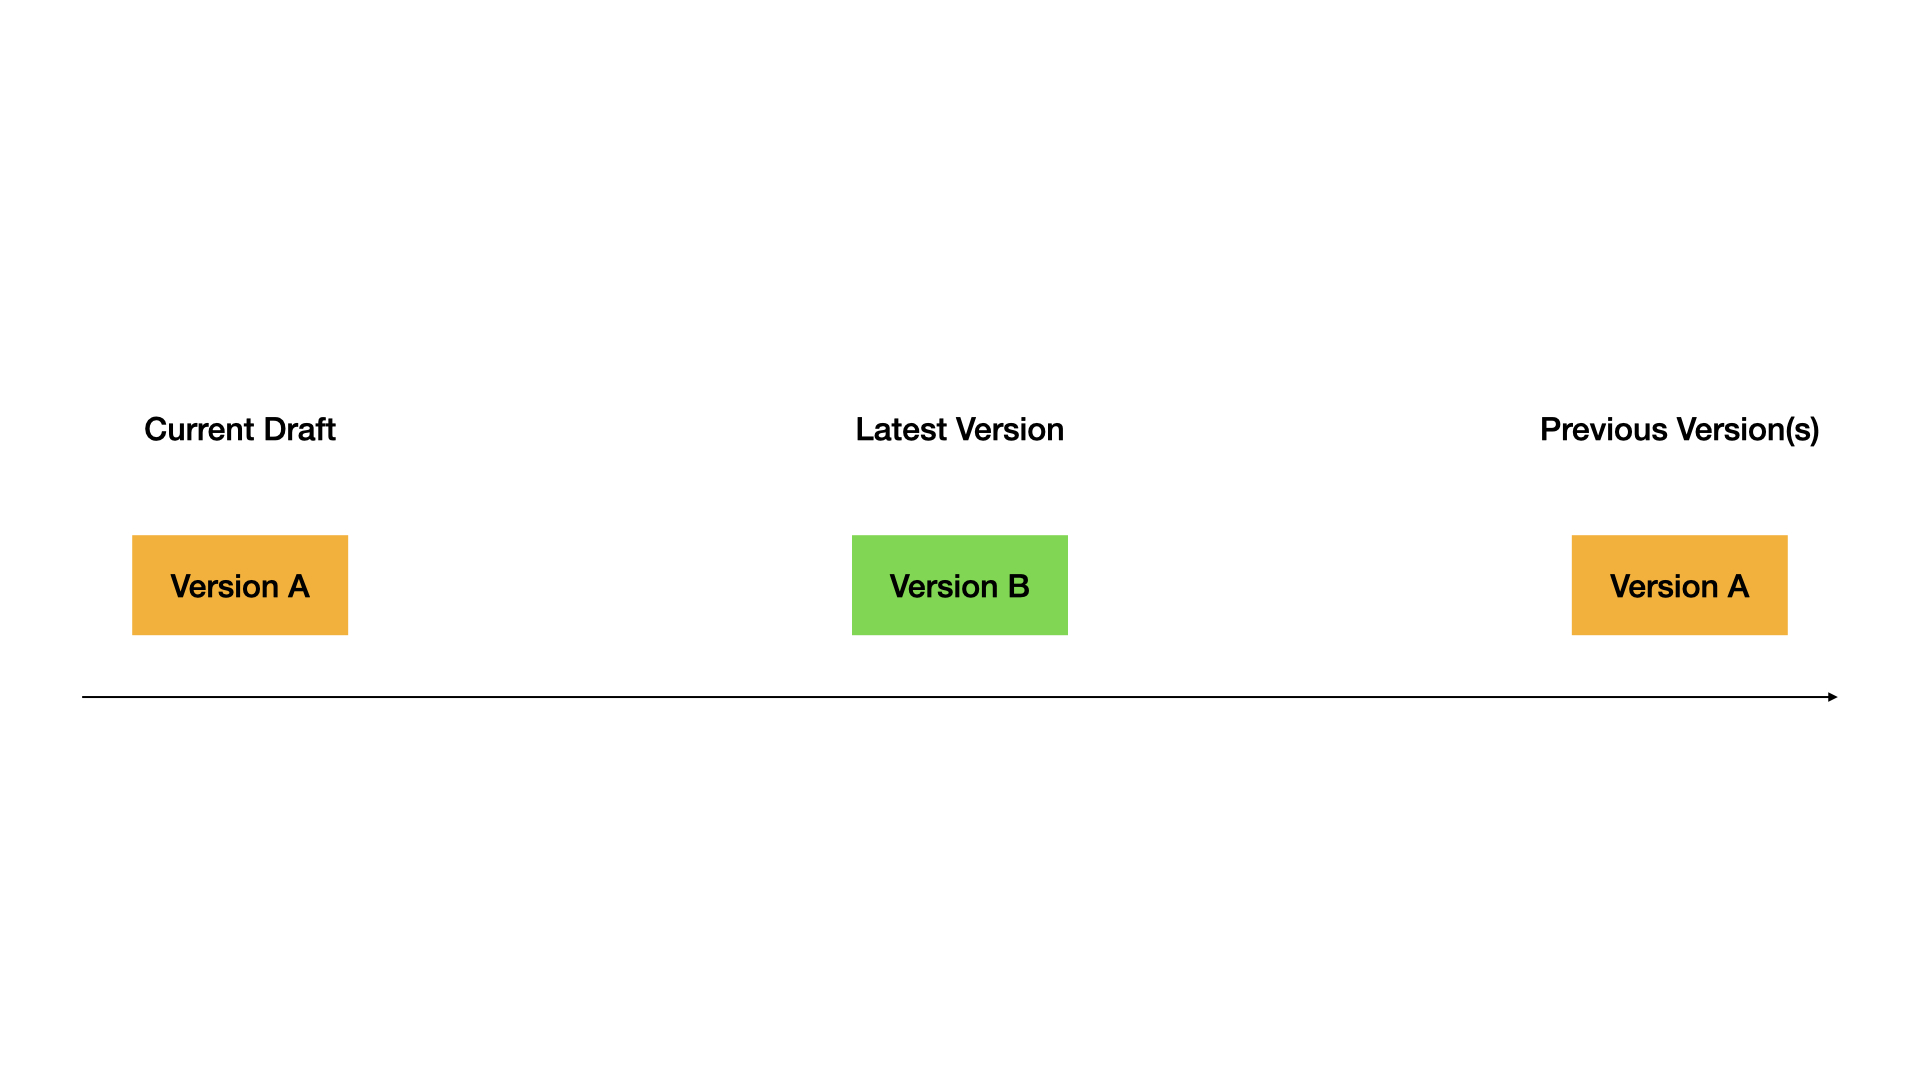
</Frame>
### 5. Publish the restored version
<Frame>
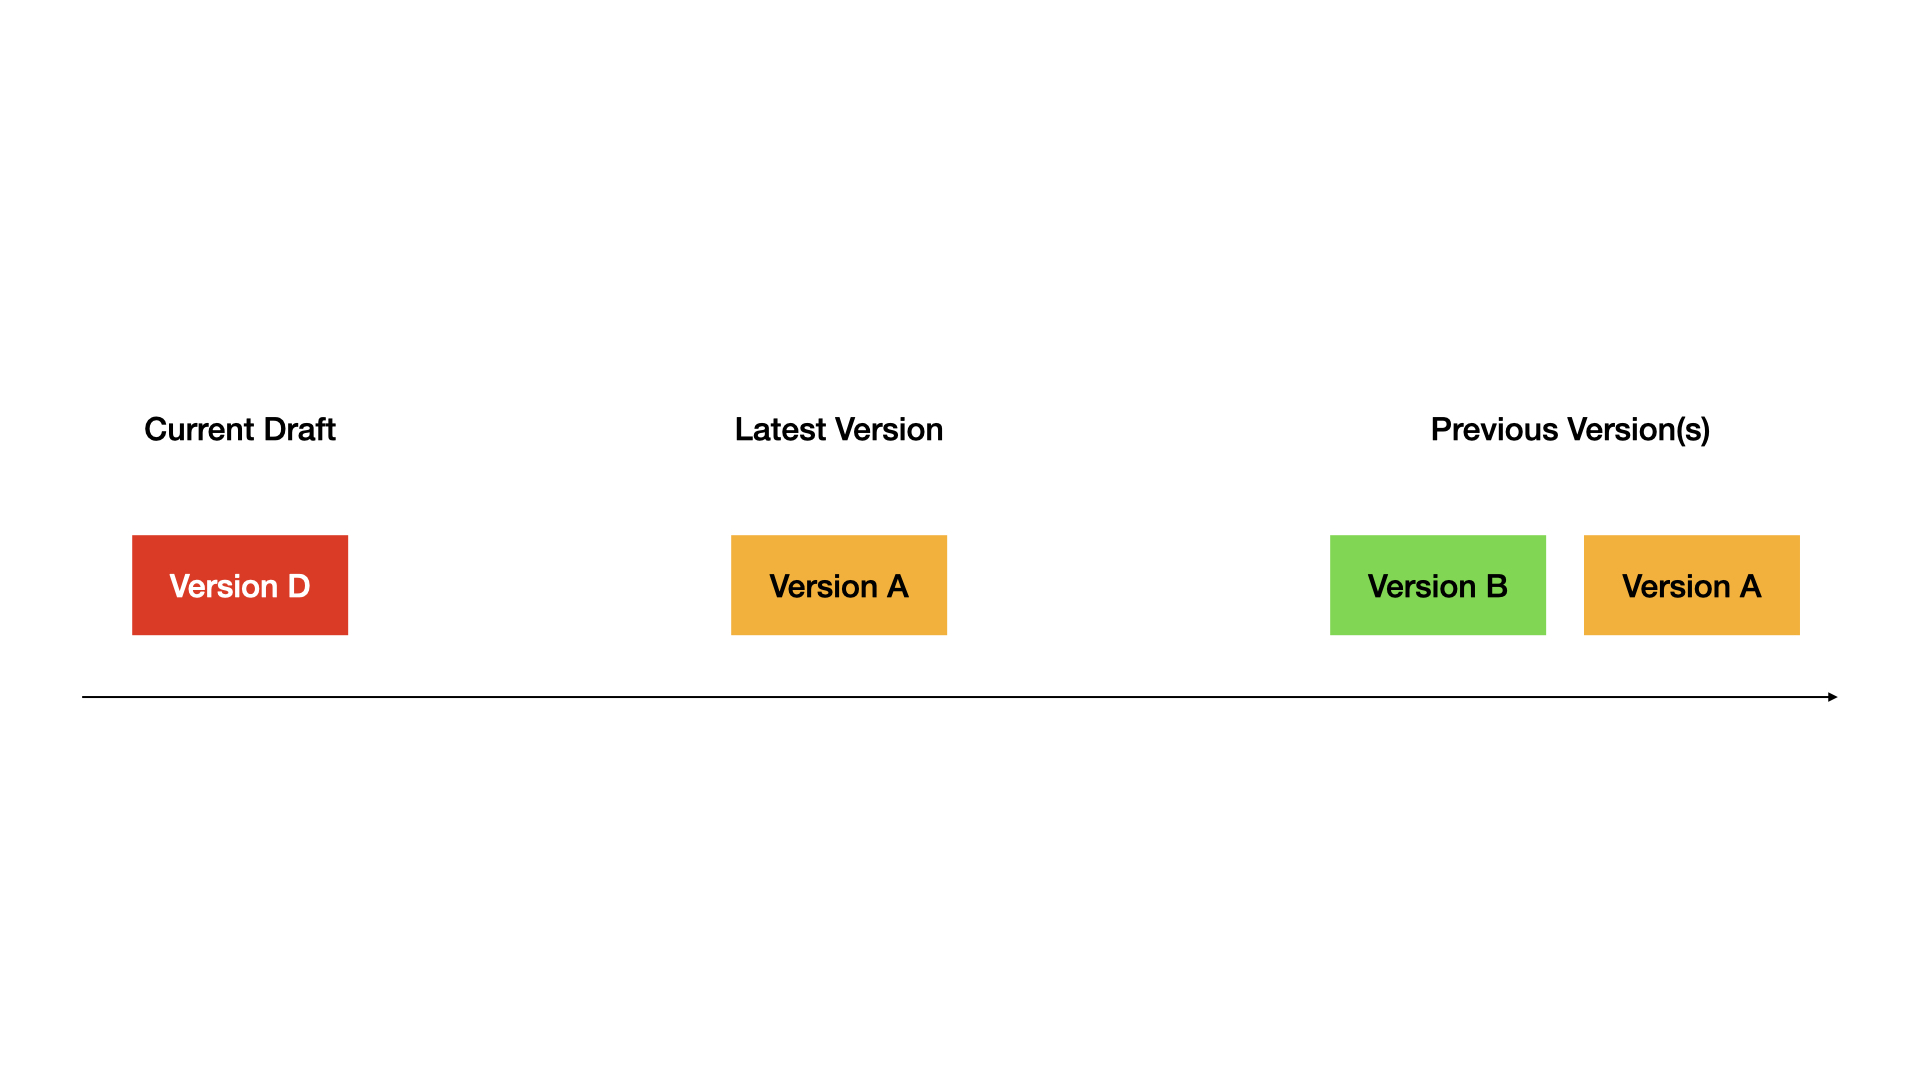
</Frame>
Complete demo:
<Frame>
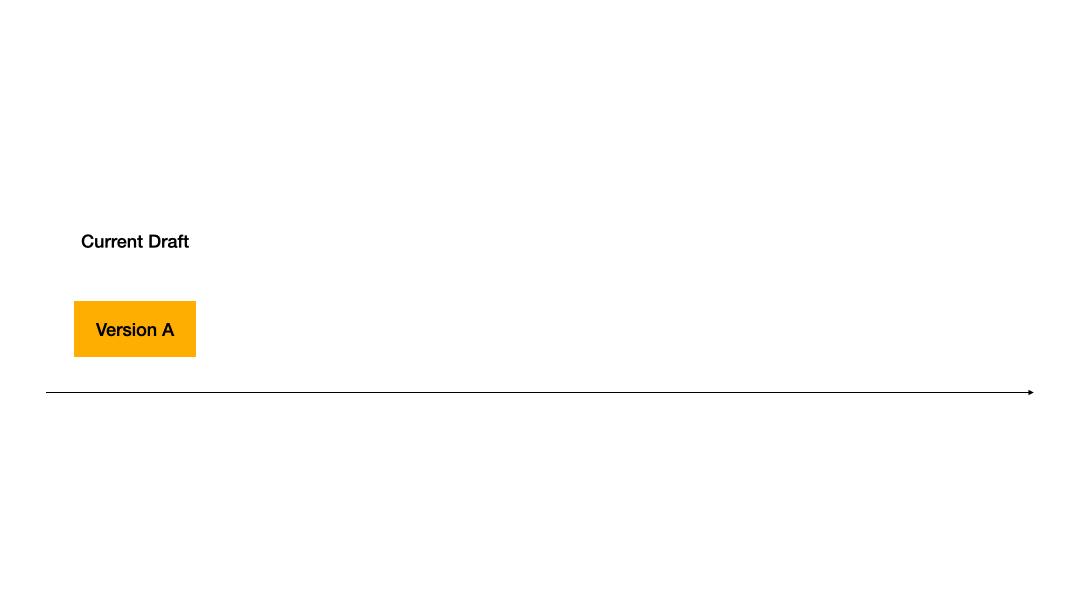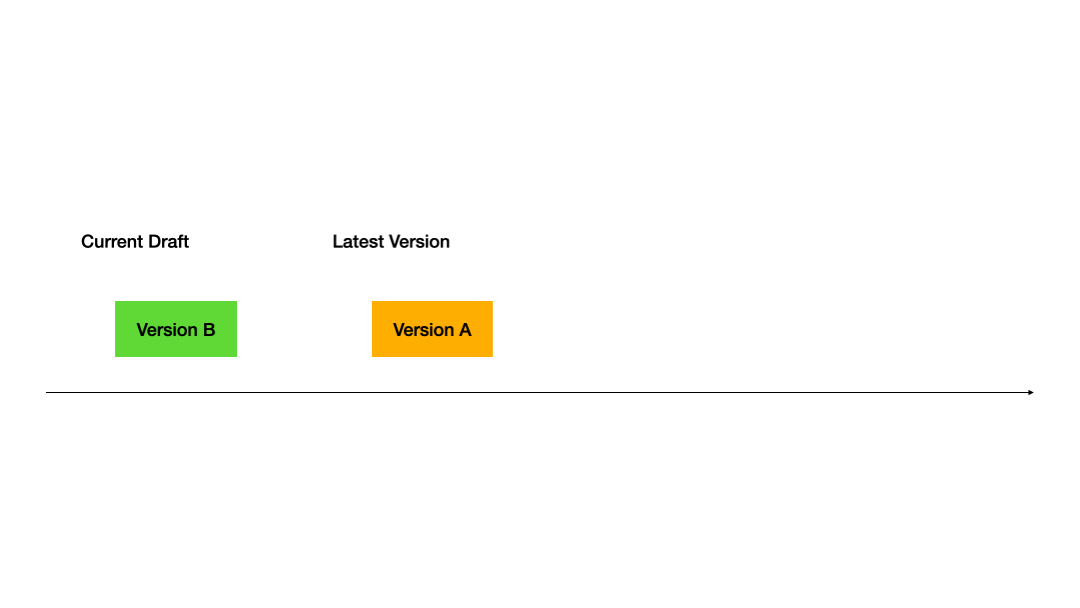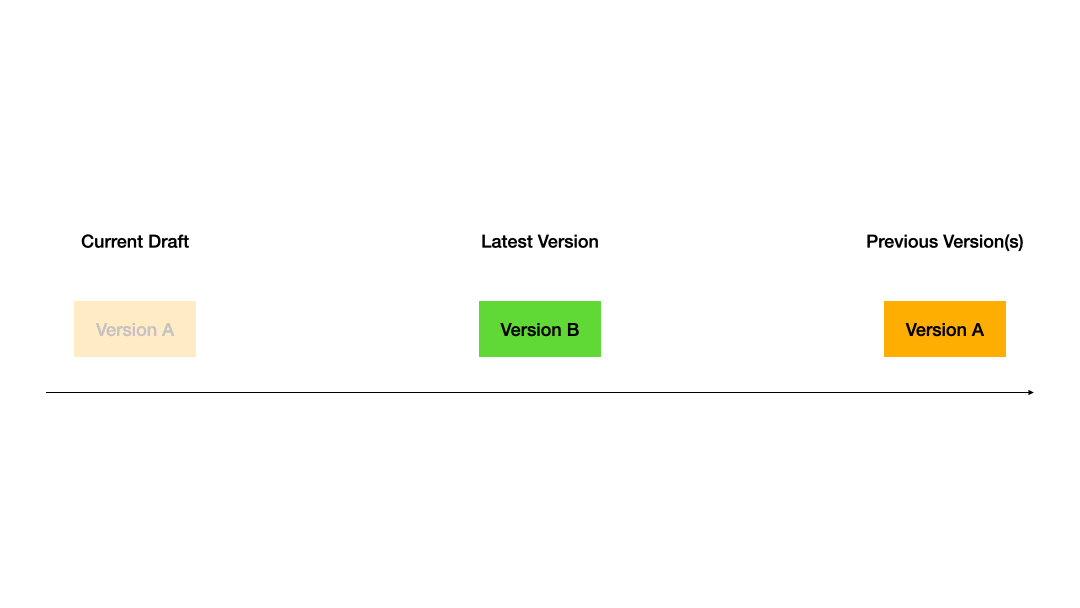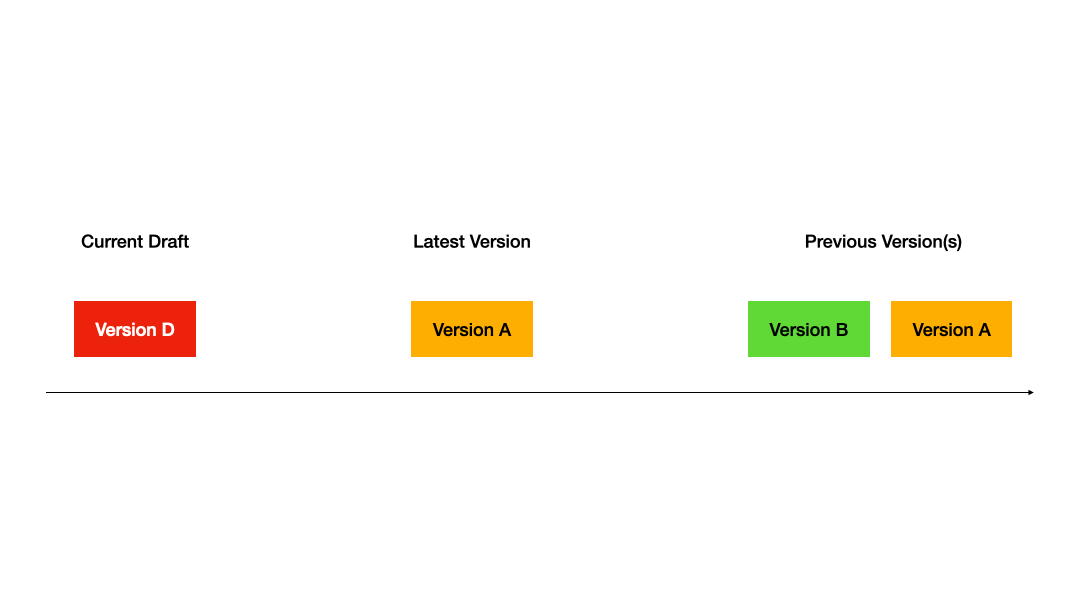
</Frame>
## Tips
* Always test in draft before publishing
* Use descriptive version names for important releases
* Restore versions when you need to rollback quickly
* Keep old versions around for reference
# Collaborate with Teammates
Source: https://docs.dify.ai/en/self-host/use-dify/build/workflow-collaboration
Edit workflows with workspace members in real time and discuss design decisions through in-canvas comments
Building a workflow sometimes takes more than one person: a prompt engineer tuning instructions, a domain expert validating logic, a reviewer flagging edge cases.
Rather than taking turns, you can edit the same workflow alongside other workspace members and leave comments directly on the canvas, so the discussion stays with the work.
<Tip>
Comments and collaborator cursors can be hidden from the zoom menu in the bottom-right corner of the canvas.
<Frame>
<img alt="Hide Comments and Collaborator Cursors" />
</Frame>
</Tip>
## Real-Time Editing
Workspace members with editor permissions or above can edit the same workflow simultaneously. When two members change the same element at the same time, the last edit wins.
## Comments
Right-click an empty area of the canvas and select **Add Comment** to leave a note. To drop multiple comments in a row, press `C` to enter comment mode. Comments persist across workflow versions.
If you @mention a workspace member in a comment, they'll receive an email notification.
Anyone with access to the app can read comments; adding, editing, or resolving requires editor permissions or above.
## Deployment Requirements
Collaboration runs over WebSocket, alongside the main API. The bundled Docker Compose stack ships this enabled, but production deployments behind a custom domain or reverse proxy need to confirm a few settings:
* `ENABLE_COLLABORATION_MODE` is `true` (the master switch for simultaneous editing, comments, and @mentions).
* `SERVER_WORKER_CLASS` is `geventwebsocket.gunicorn.workers.GeventWebSocketWorker` on the WebSocket worker (the bundled `api_websocket` service sets this).
* `NEXT_PUBLIC_SOCKET_URL` points to a WebSocket URL the browser can reach, for example `wss://dify.example.com`. The default `ws://localhost` only works for local access to the bundled nginx.
* The `collaboration` profile stays in `COMPOSE_PROFILES` so the dedicated WebSocket service runs.
If you front Dify with your own reverse proxy, forward `Upgrade` and `Connection` headers on `/socket.io/`. Running multiple API replicas requires sticky sessions.
See [Environment Variables](/en/self-host/deploy/configuration/environments#enable_collaboration_mode) for the full reference.
# Error Types
Source: https://docs.dify.ai/en/self-host/use-dify/debug/error-type
Each node type throws specific error classes that help you understand what went wrong and how to fix it.
## Node-specific errors
<Tabs>
<Tab title="Code" icon="code">
`CodeNodeError`
<Info>Your Python or JavaScript code threw an exception during execution</Info>
<Frame>
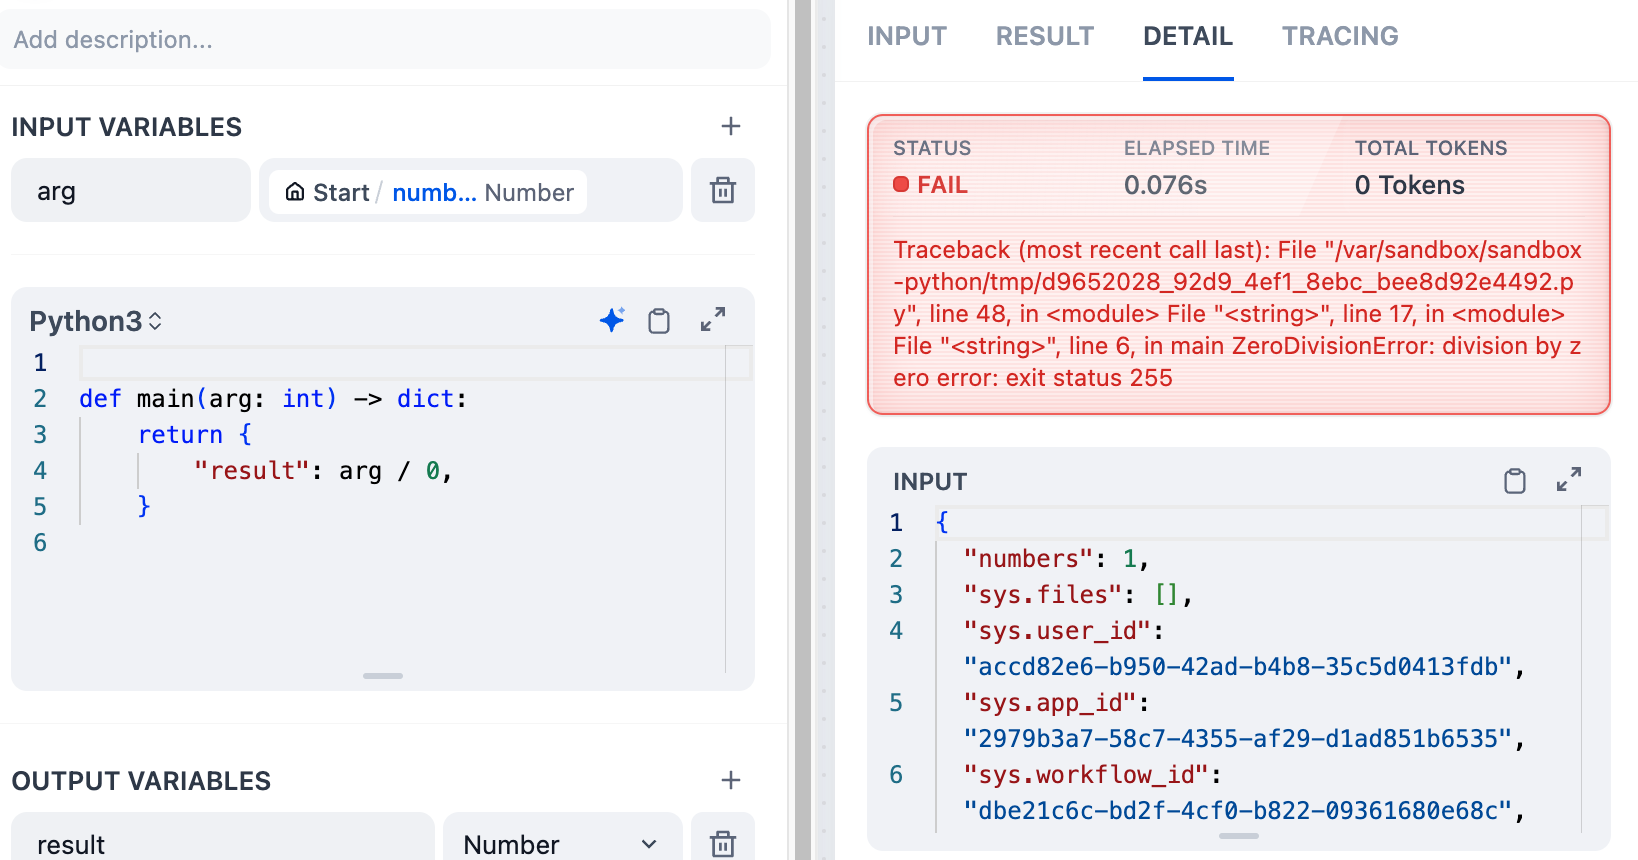
</Frame>
`OutputValidationError`
<Info>The data type your code returned doesn't match the output variable type you configured</Info>
`DepthLimitError`
<Info>Your code created nested data structures deeper than 5 levels</Info>
`CodeExecutionError`
<Info>The sandbox service couldn't execute your code - usually means the service is down</Info>
<Frame>
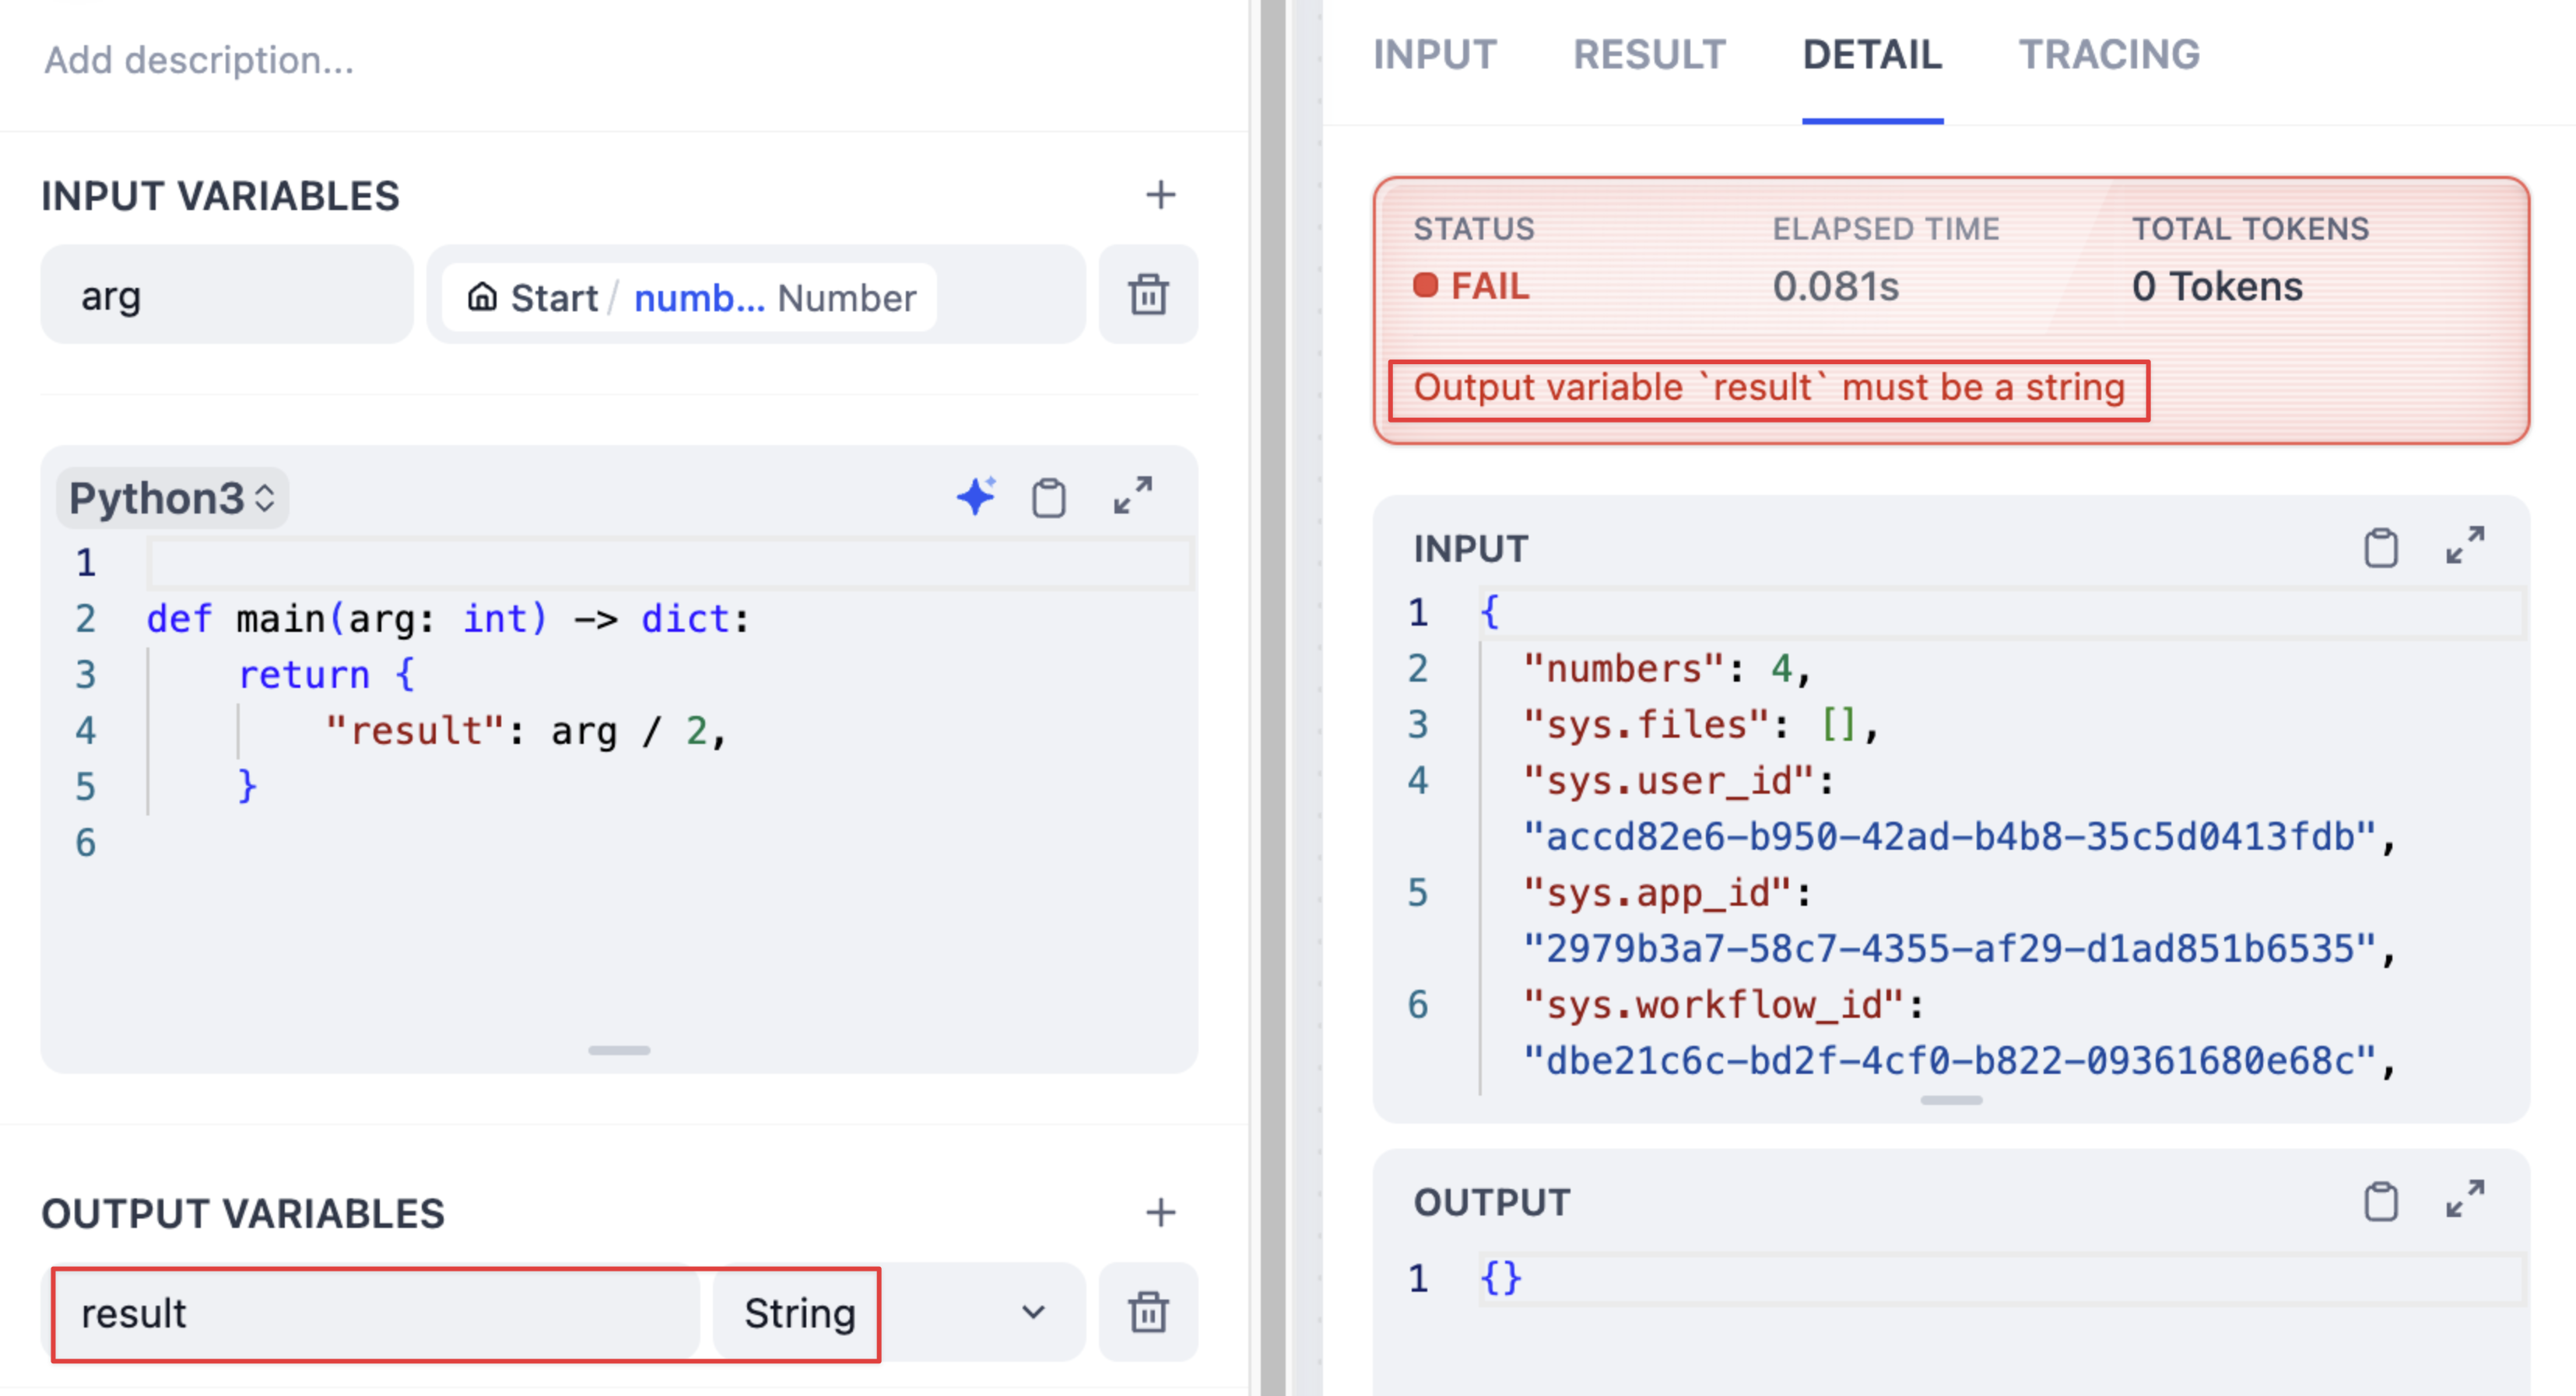
</Frame>
</Tab>
<Tab title="LLM" icon="brain">
`VariableNotFoundError`
<Info>Your prompt template references a variable that doesn't exist in the workflow context</Info>
<Frame>
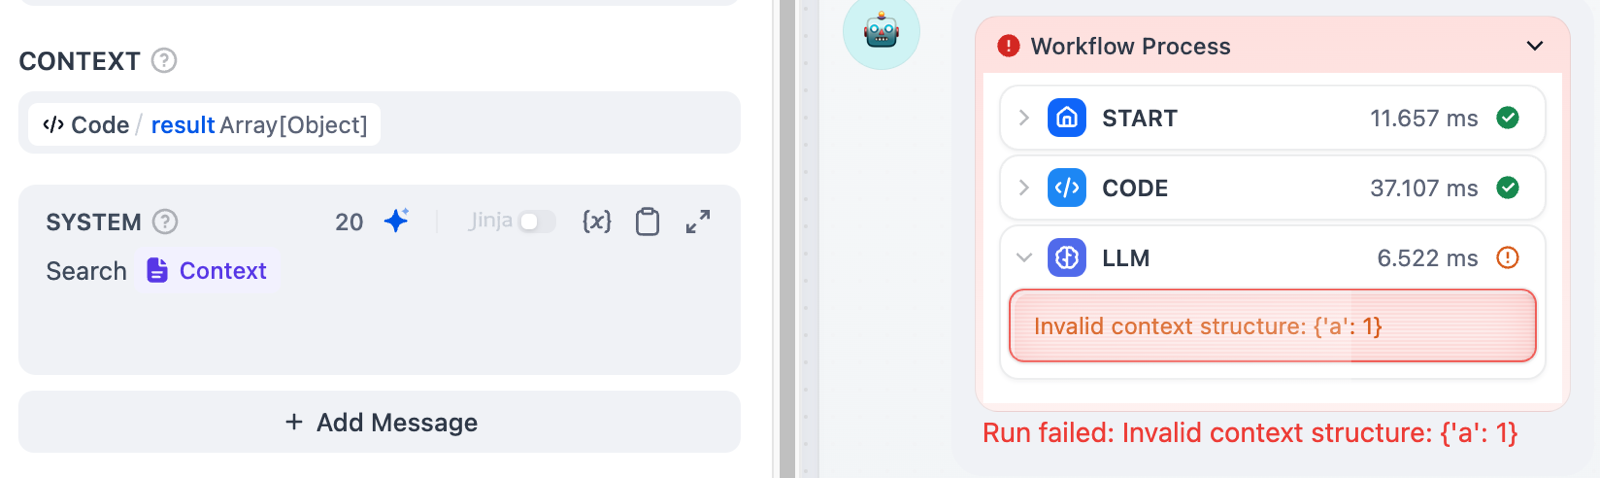
</Frame>
`InvalidContextStructureError`
<Info>You passed an array or object to the context field, which only accepts strings</Info>
`NoPromptFoundError`
<Info>The prompt field is completely empty</Info>
`ModelNotExistError`
<Info>No model is selected in the LLM node configuration</Info>
`LLMModeRequiredError`
<Info>The selected model doesn't have valid API credentials configured</Info>
`InvalidVariableTypeError`
<Info>Your prompt template isn't valid Jinja2 syntax or plain text format</Info>
<Frame>
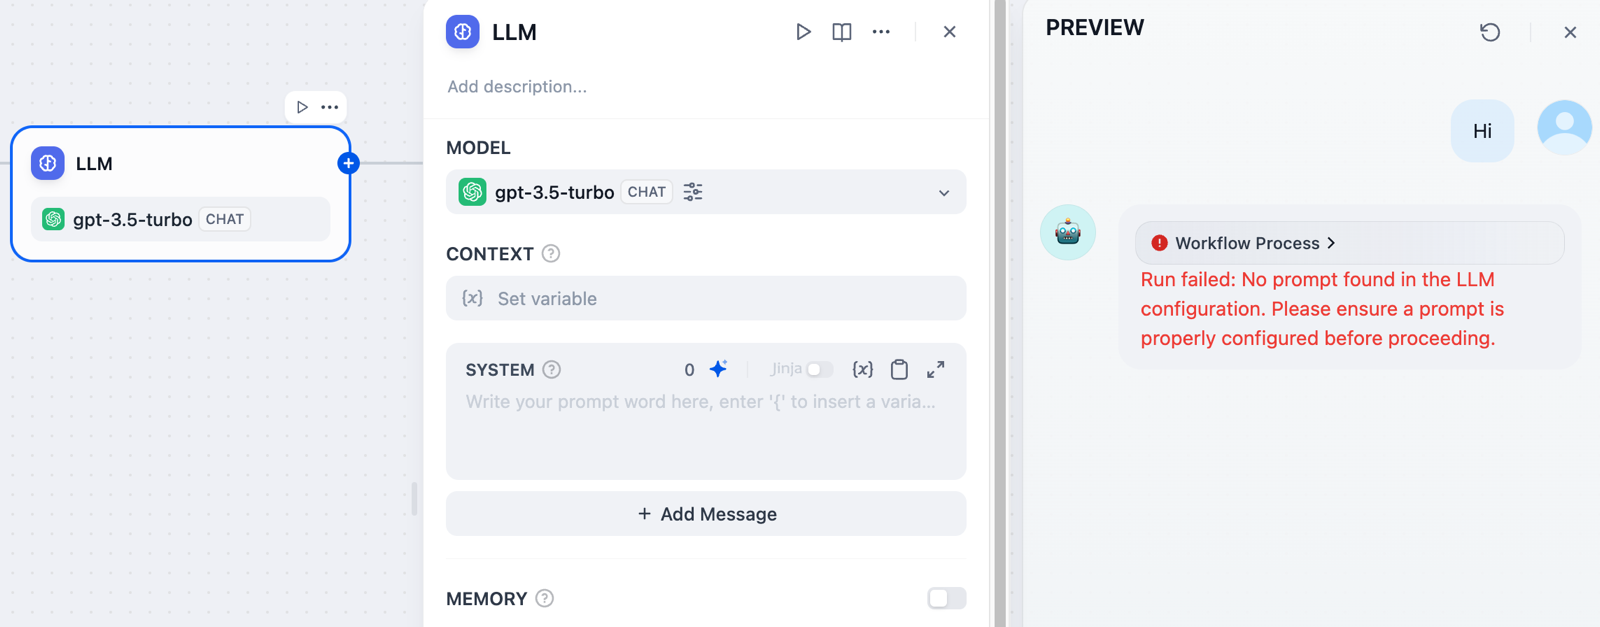
</Frame>
</Tab>
<Tab title="HTTP Request" icon="globe">
`AuthorizationConfigError`
<Info>Missing or invalid authentication configuration for the API endpoint</Info>
`InvalidHttpMethodError`
<Info>HTTP method must be GET, HEAD, POST, PUT, PATCH, or DELETE</Info>
`ResponseSizeError`
<Info>API response exceeded the 10MB size limit</Info>
`FileFetchError`
<Info>Couldn't retrieve a file variable referenced in the request</Info>
`InvalidURLError`
<Info>The URL format is malformed or unreachable</Info>
</Tab>
<Tab title="Tool" icon="wrench">
`ToolParameterError`
<Info>Parameters passed to the tool don't match its expected schema</Info>
`ToolFileError`
<Info>The tool couldn't access required files</Info>
`ToolInvokeError`
<Info>The external tool API returned an error during execution</Info>
<p>
<Frame>
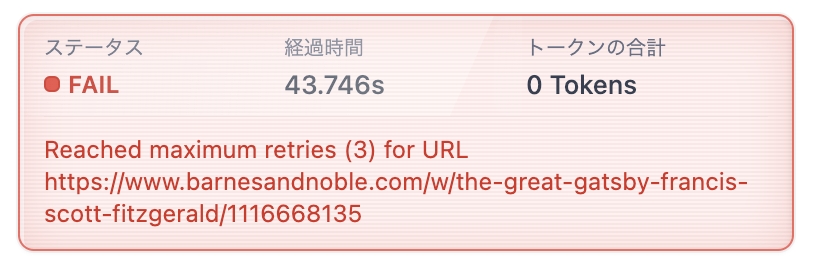
</Frame>
</p>
`ToolProviderNotFoundError`
<Info>The tool provider isn't installed or configured properly</Info>
</Tab>
</Tabs>
## System-level errors
`InvokeConnectionError`
<Info>Network connection failed to the external service</Info>
`InvokeServerUnavailableError`
<Info>External service returned a 503 status or is temporarily down</Info>
`InvokeRateLimitError`
<Info>You've hit rate limits on the API or model provider</Info>
`QuotaExceededError`
<Info>Your usage quota has been exceeded for this service</Info>
# Run History
Source: https://docs.dify.ai/en/self-host/use-dify/debug/history-and-logs
Dify records detailed Run History every time your workflow runs. You can see what happened at both the application level and for individual nodes.
<Info>
For Run History from live users after publishing, see [Logs](/en/self-host/use-dify/monitor/logs).
</Info>
## Application Run History
Each workflow run creates a complete log entry. Click any entry to see three sections:
<Frame>
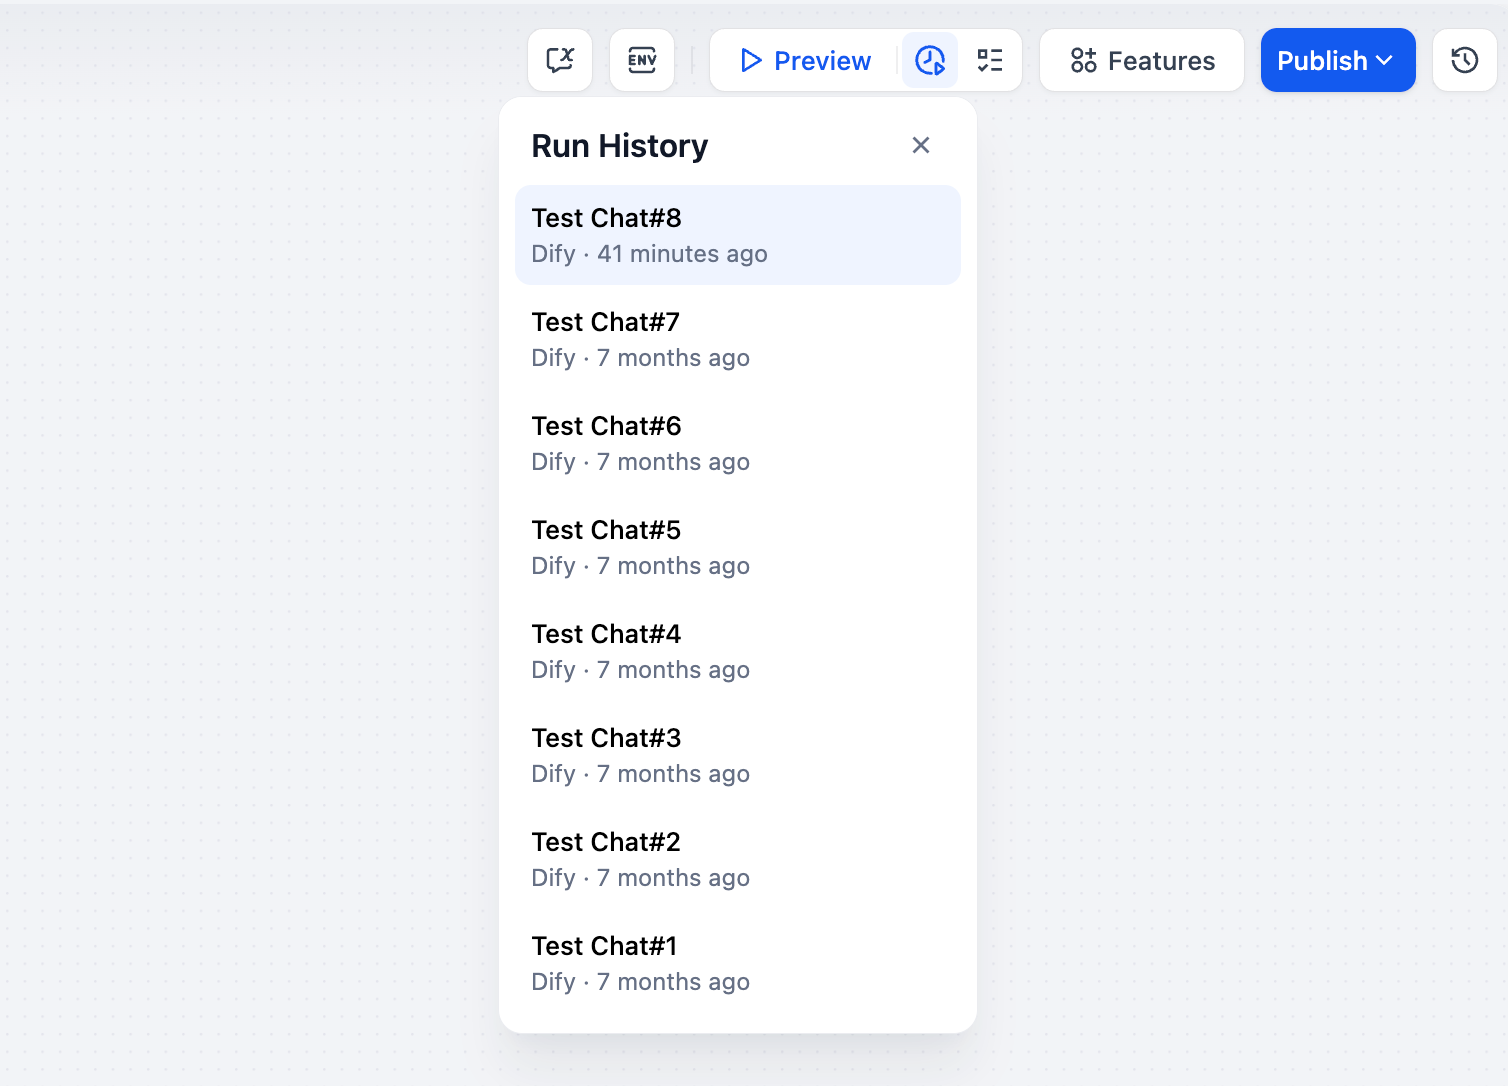
</Frame>
### Result
Shows the final output that users see. If the workflow failed, you'll see error messages here.
<Frame>
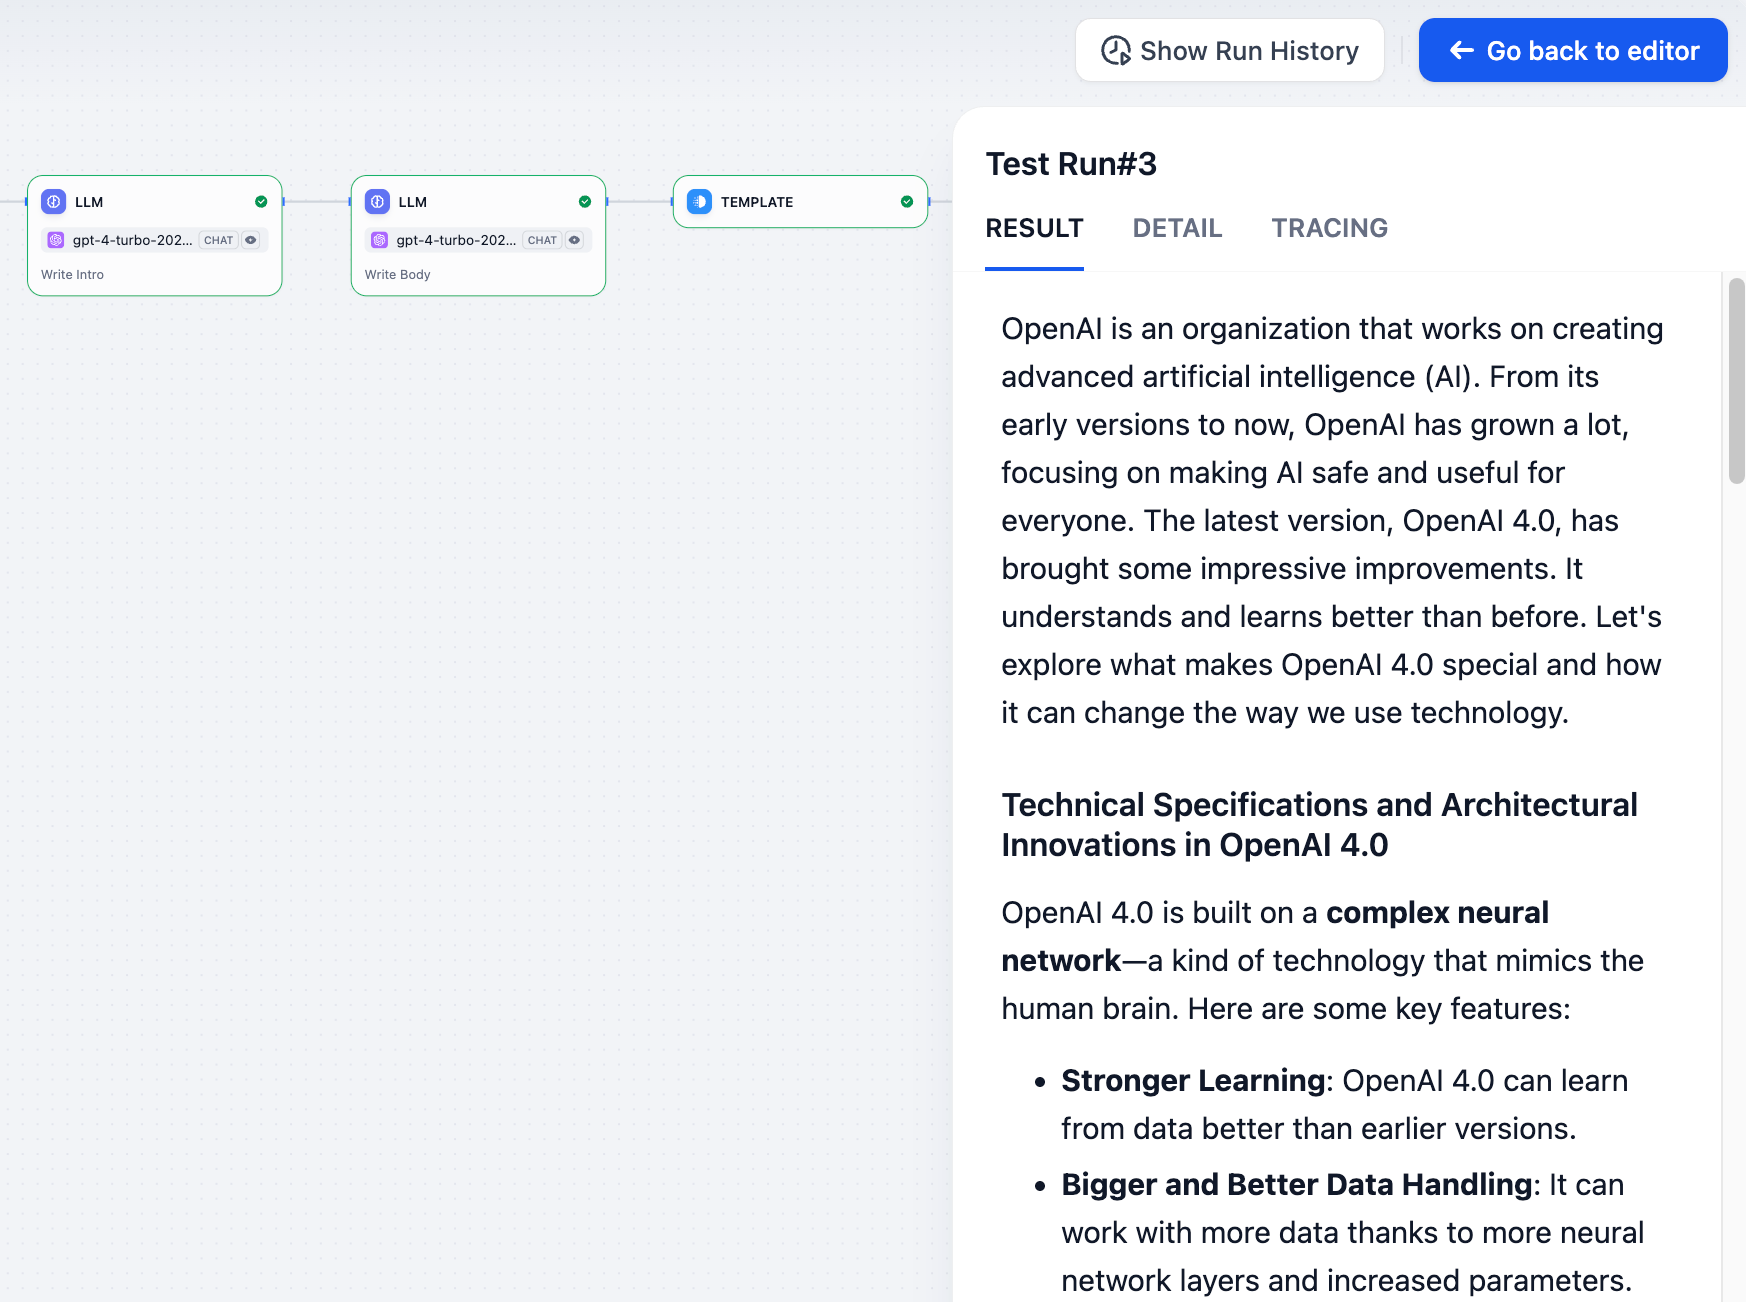
</Frame>
<Warning>
Only available for Workflow applications.
</Warning>
### Detail
Shows the original input, final output, and system metadata from the execution.
<Frame>
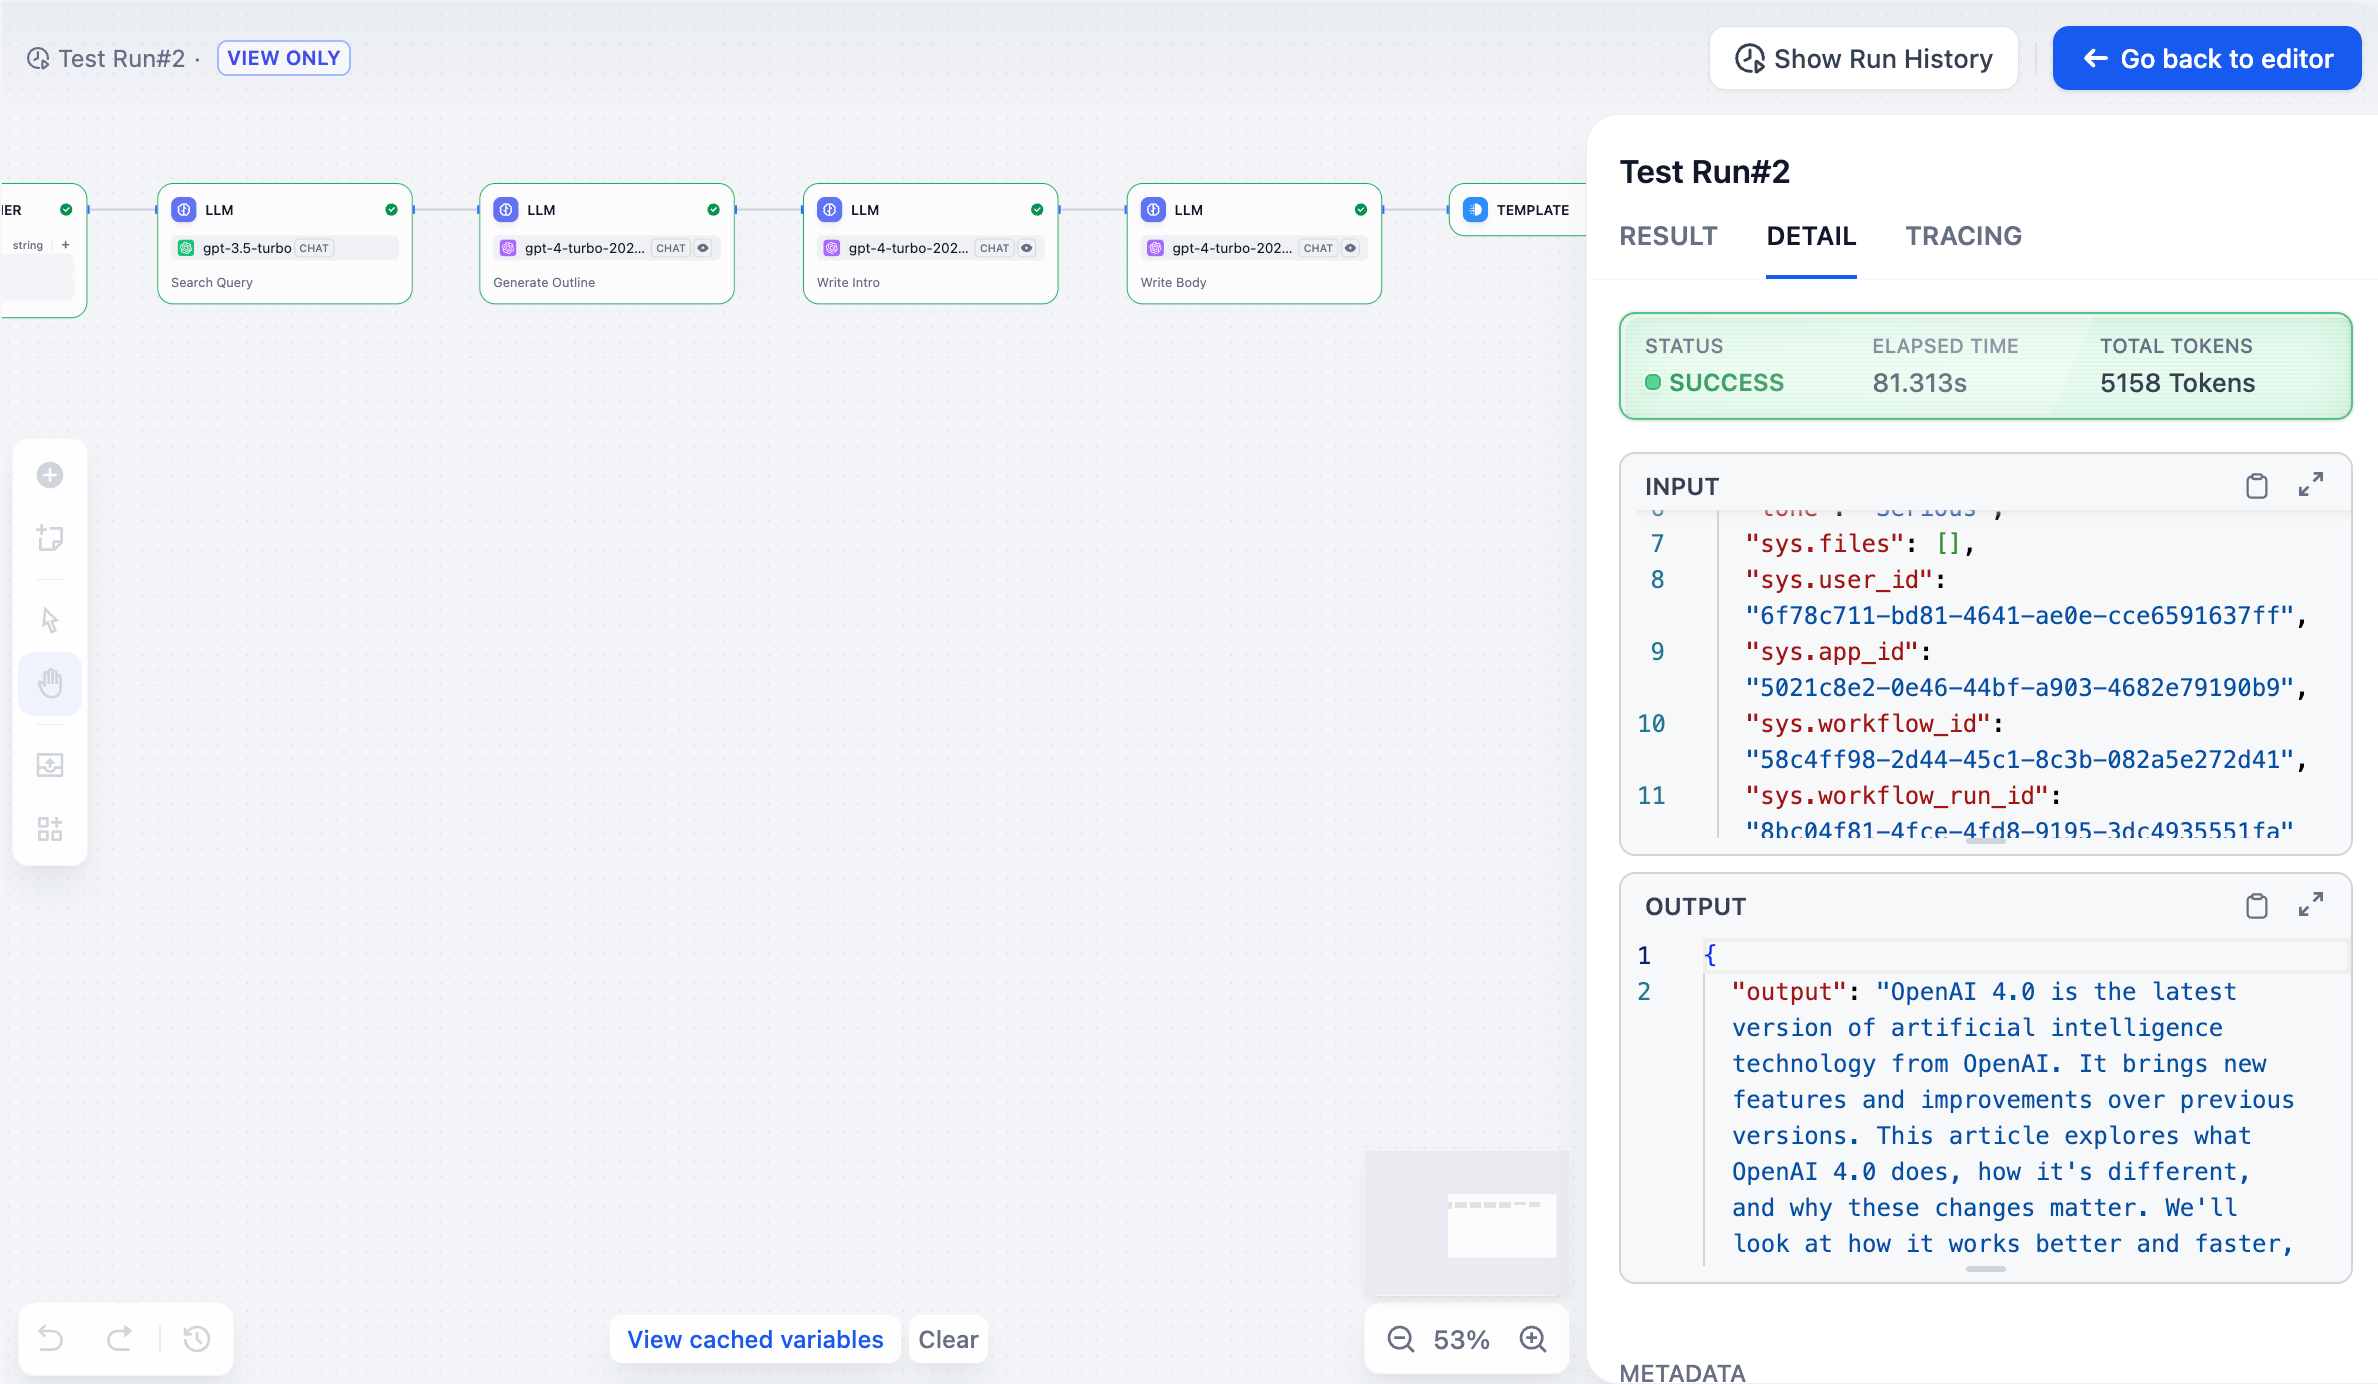
</Frame>
### Tracing
Shows exactly how your workflow executed, including which nodes ran in what order, how long each took, and where data flowed between them. This is useful for finding bottlenecks and understanding complex workflows with branches or loops.
<Frame>
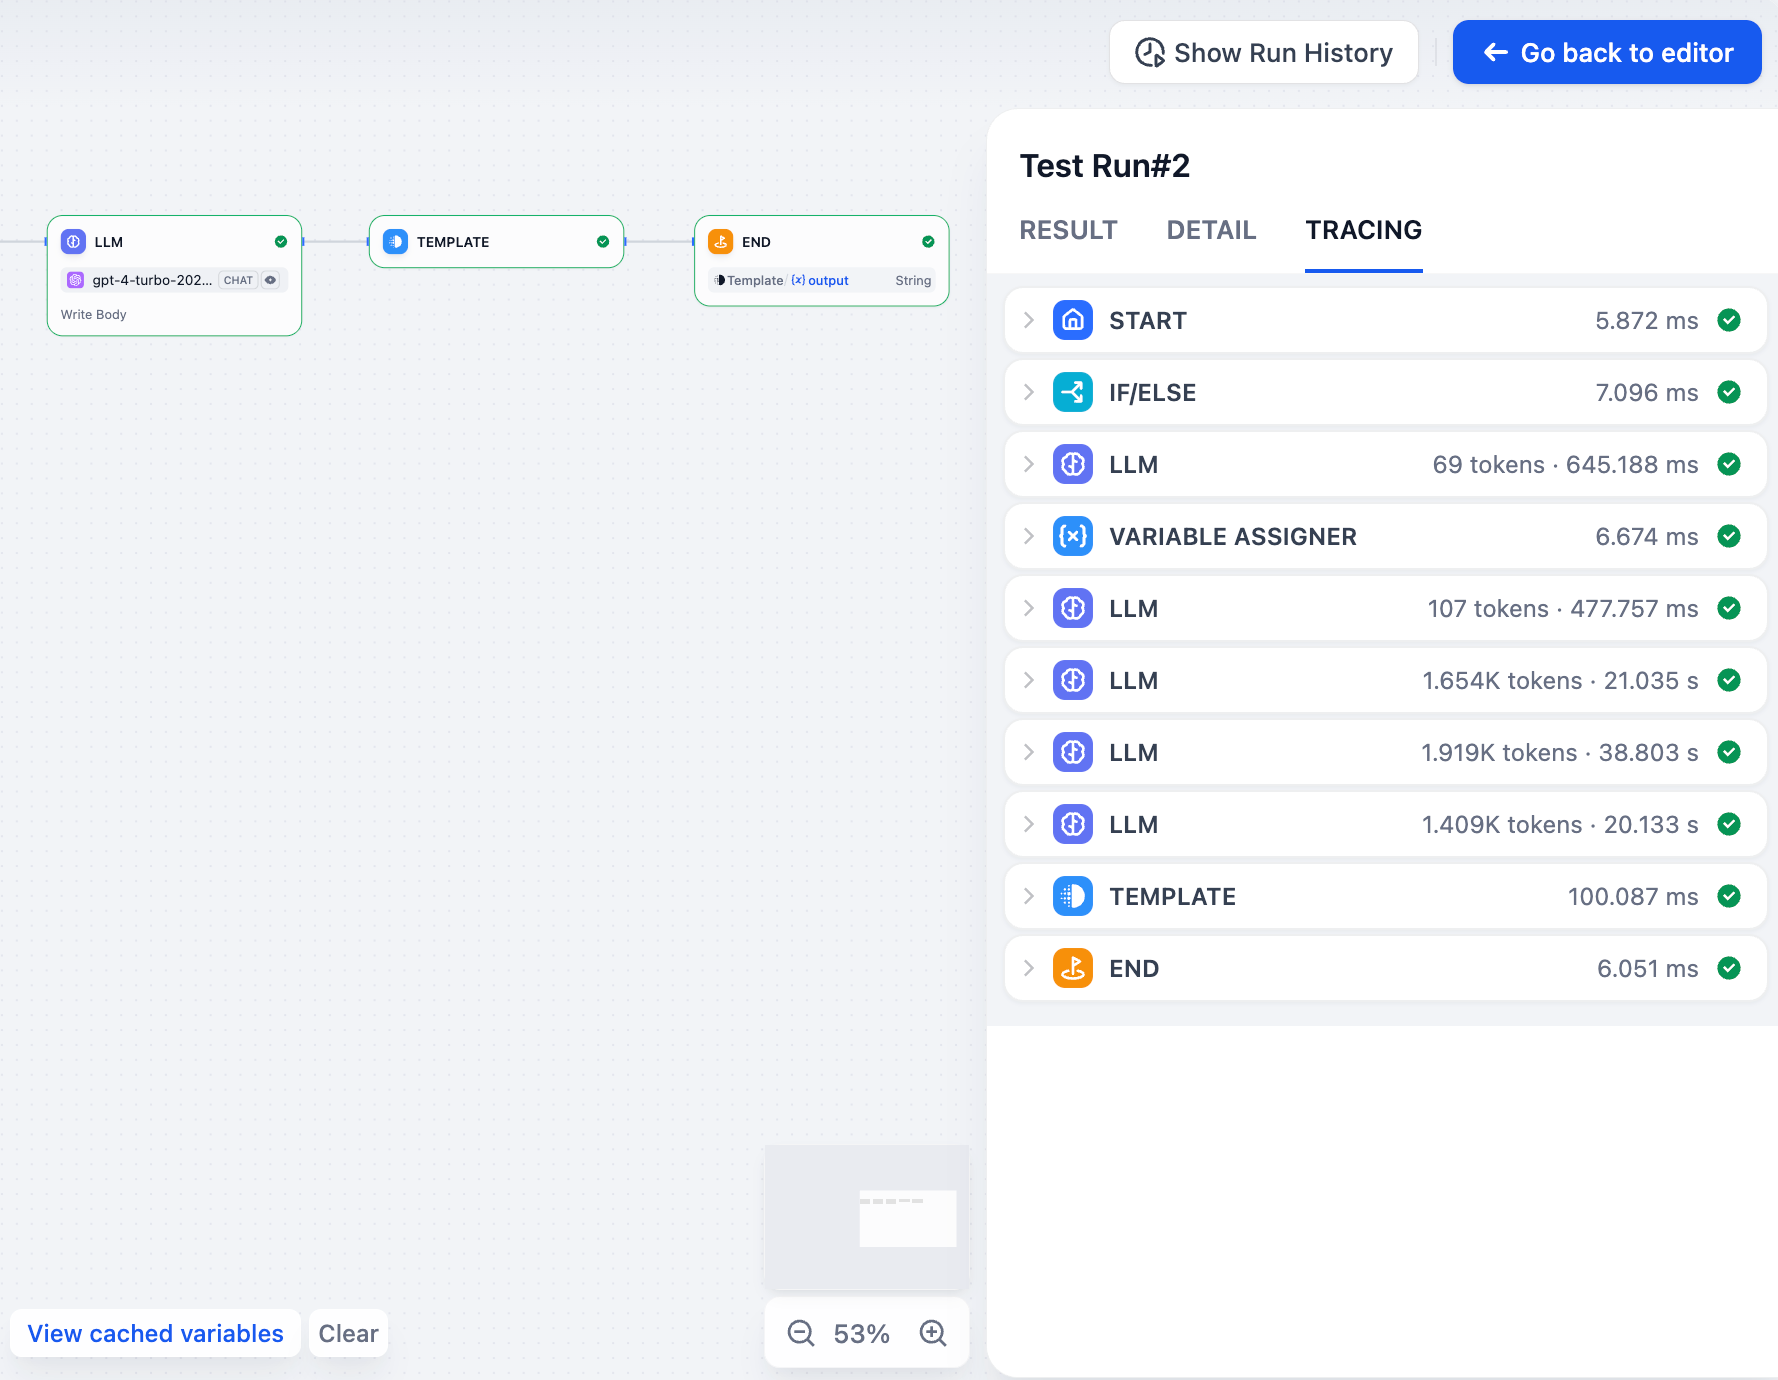
</Frame>
## Node Run History
You can also check the last execution of any individual node. Click "Last run" in the node's config panel to see its most recent input, output, and timing details.
<Frame>
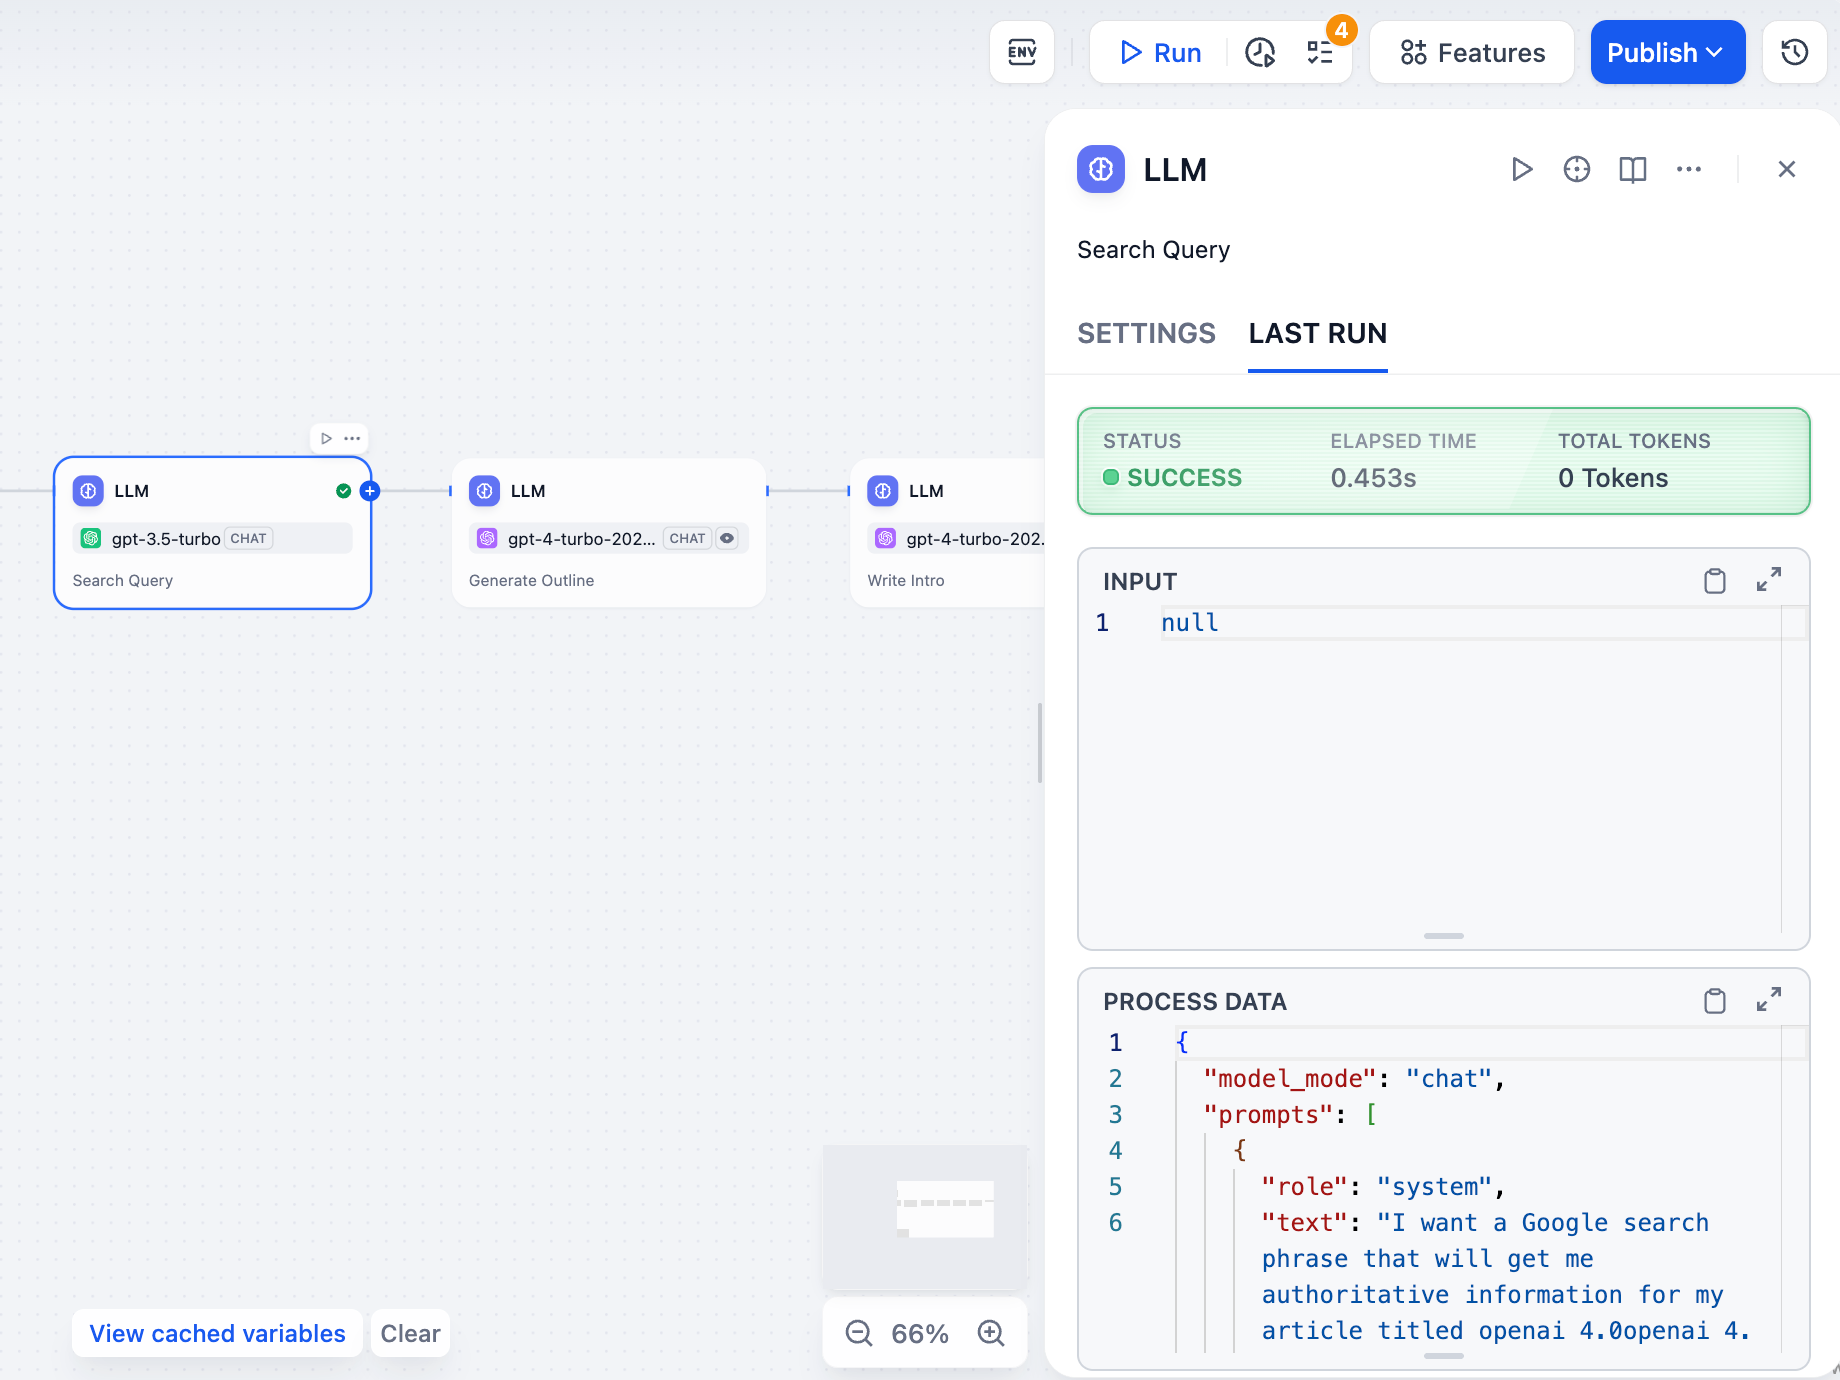
</Frame>
# Single Node
Source: https://docs.dify.ai/en/self-host/use-dify/debug/step-run
Test individual nodes or run through your workflow step-by-step to catch issues before publishing.
## Single node testing
You can test any node individually without running the entire workflow. Select the node, provide test input in its settings panel, and click Run to see the output.
<Frame>
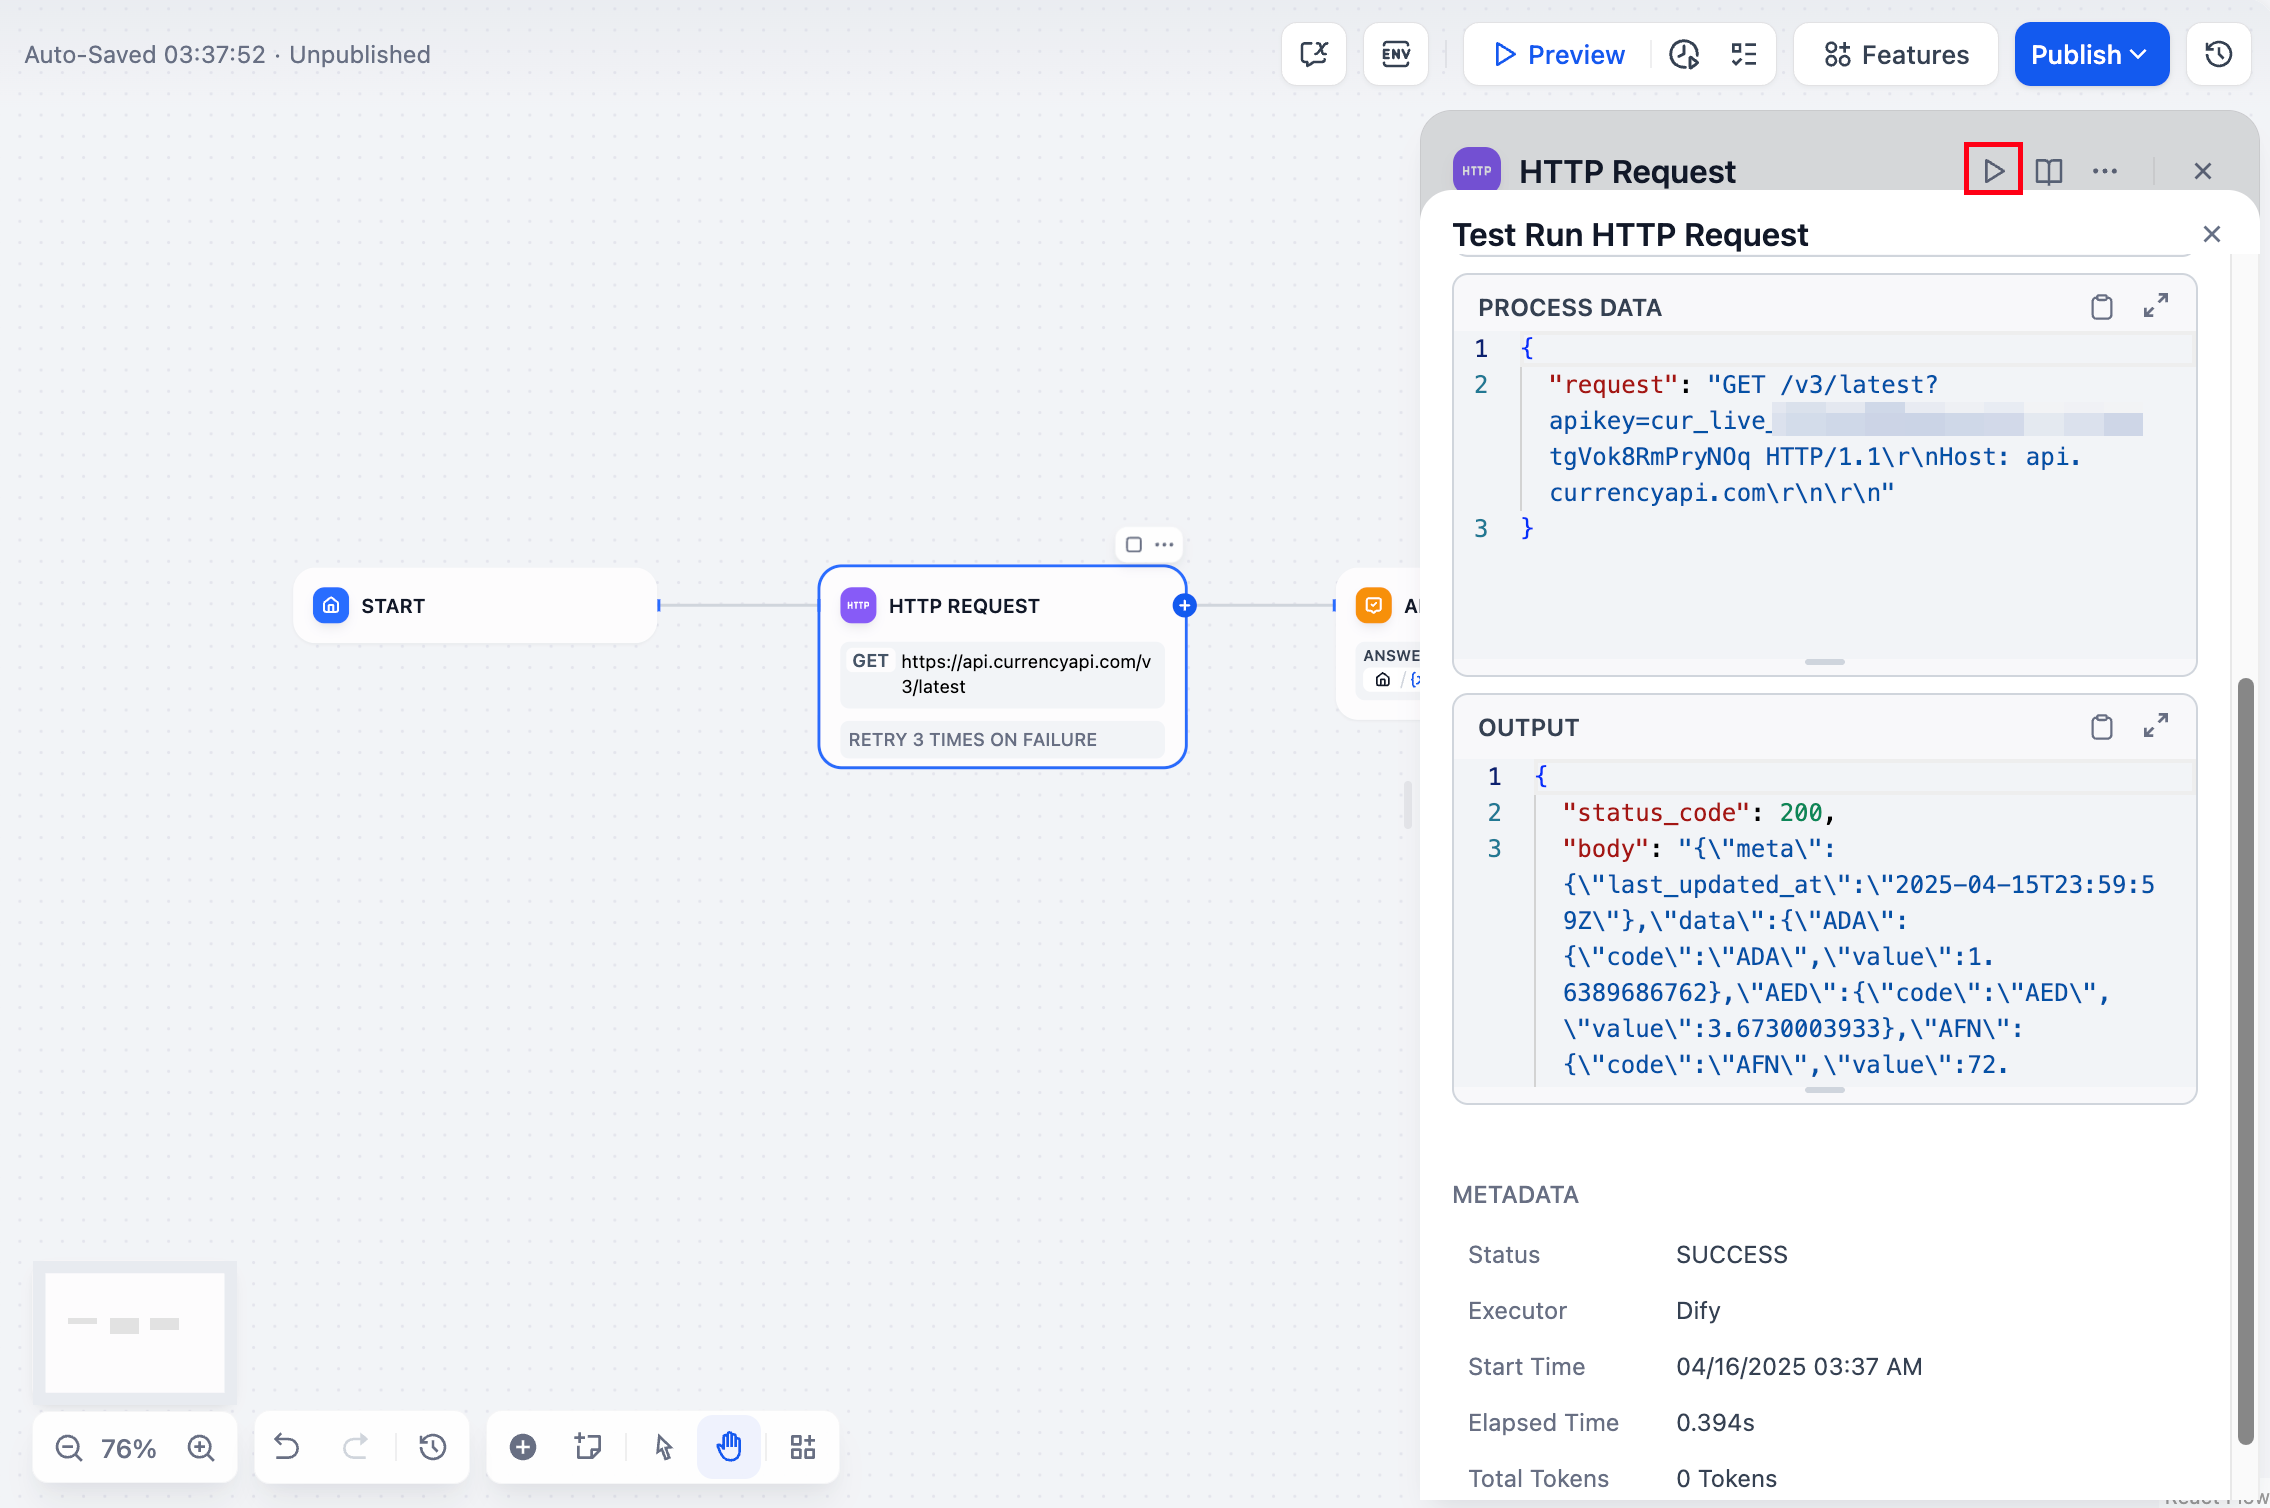
</Frame>
After testing, click "Last run" to see execution details including inputs, outputs, timing, and any error messages.
<Warning>
Answer and End nodes don't support single node testing.
</Warning>
## Step-by-step execution
When you run nodes one at a time, their outputs are cached in the Variable Inspector. You can edit these cached variables to test different scenarios without re-running upstream nodes.
<Frame>
</Frame>
This is useful when you want to test how a node responds to different data without having to modify and re-run all the nodes before it. Just change the variable values in the inspector and run the node again.
## View execution history
Every node execution creates a record. Click "Last run" on any node to see its most recent execution details including what data went in, what came out, and how long it took.
<Frame>
</Frame>
# Variable Inspector
Source: https://docs.dify.ai/en/self-host/use-dify/debug/variable-inspect
The Variable Inspector shows you all the data flowing through your workflow. It captures inputs and outputs from each node after they run, so you can see what's happening and test different scenarios.
<Frame>
</Frame>
## View variables
After any node runs, its output variables appear in the inspector panel at the bottom of the screen. Click any variable to see its full content.
<Frame>
</Frame>
## Edit variables
You can edit most variable values by clicking on them. When you run downstream nodes, they'll use your edited values instead of the original ones. This lets you test different scenarios without re-running the entire workflow.
<Info>
Editing variables here doesn't change the "Last run" record for the node that originally created them.
</Info>
For example, if an LLM node generates SQL like `SELECT * FROM users`, you can edit it to `SELECT username FROM users` in the inspector and then re-run just the database node to see different results.
<Frame>
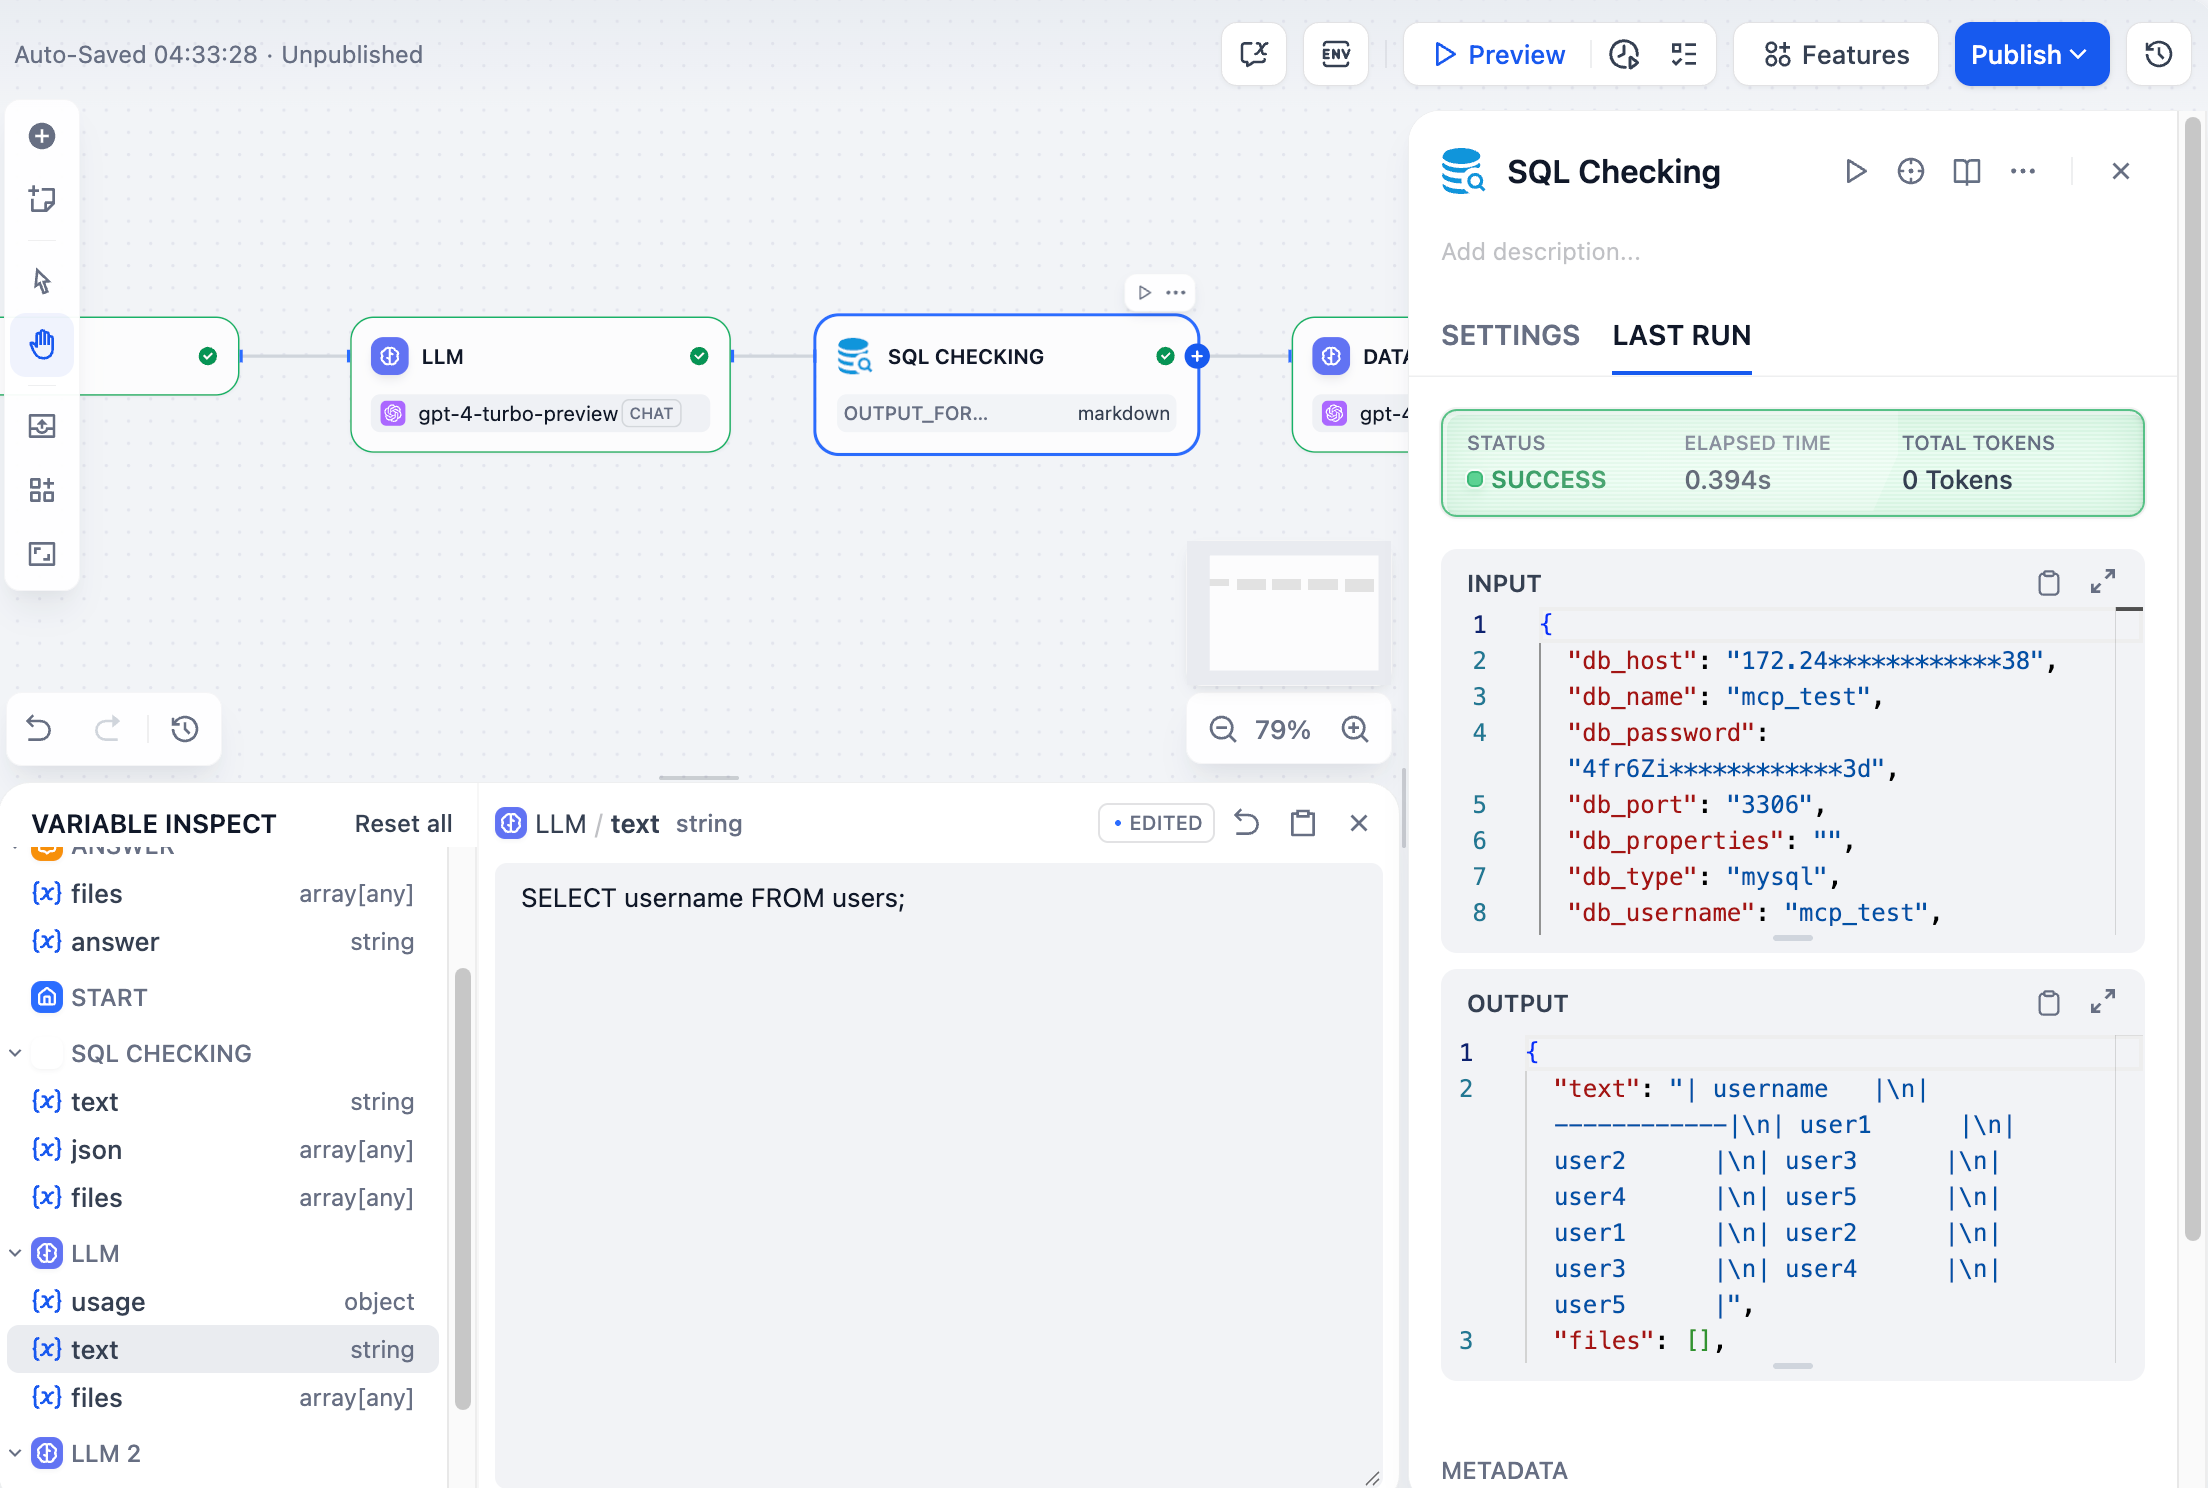
</Frame>
## Reset variables
Click the revert icon next to any variable to restore its original value, or click "Reset all" to clear all cached variables at once.
<Frame>
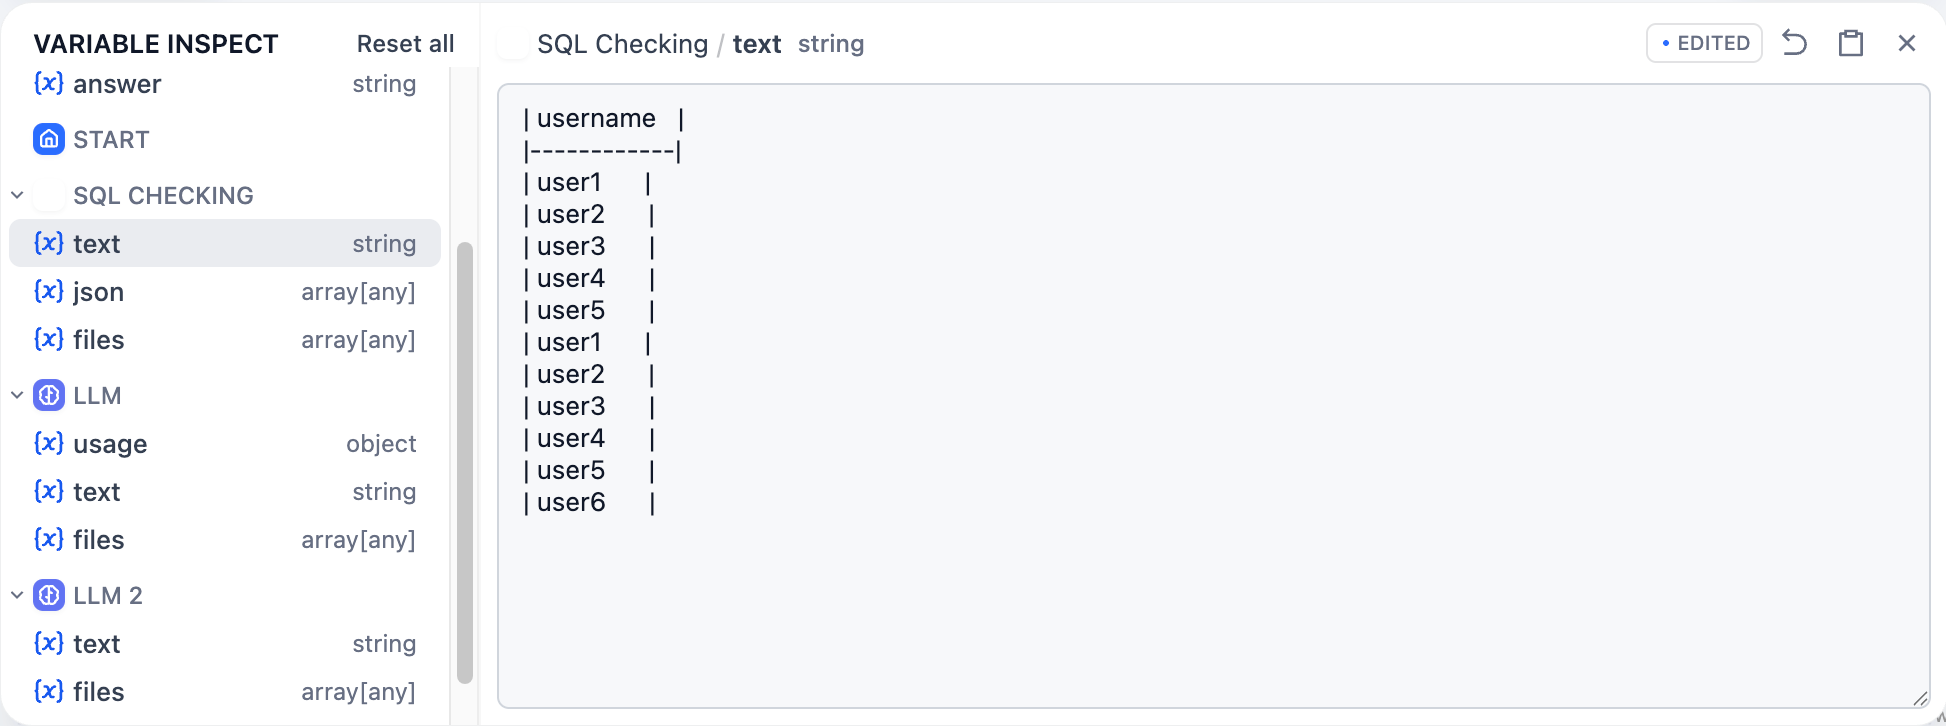
</Frame>
# Connect to External Knowledge Base
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/connect-external-knowledge-base
Integrate external knowledge sources with Dify applications through API connections to leverage custom RAG systems or third-party knowledge services
If your team maintains its own RAG system or hosts content in a third-party knowledge service like [AWS Bedrock](https://aws.amazon.com/bedrock/), you can connect these external sources to Dify instead of migrating content into Dify's built-in knowledge base.
This lets your AI applications retrieve information directly from your existing infrastructure while you retain full control over the retrieval logic and content management.
<Frame>
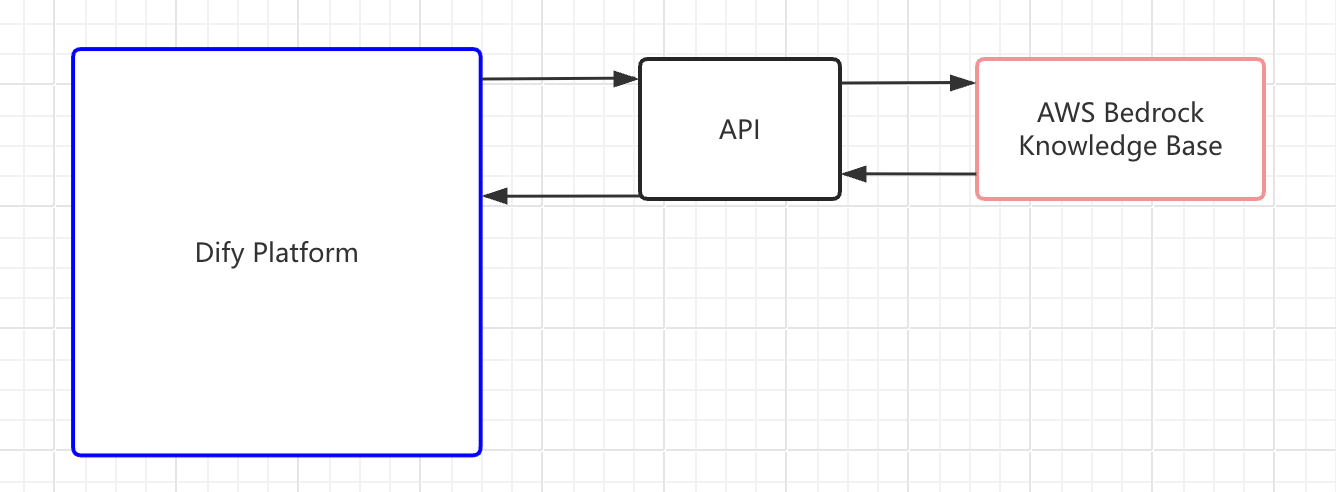
</Frame>
**Connecting an external knowledge base involves three steps**:
1. [Build an API service that Dify can query](#step-1-build-the-retrieval-api).
2. [Register the API endpoint in Dify](#step-2-register-an-external-knowledge-api).
3. [Connect a specific knowledge source through the registered API](#step-3-create-an-external-knowledge-base).
When your application runs, Dify sends retrieval requests to your endpoint and uses the returned chunks as context for LLM responses.
<Tip>
If you're connecting to LlamaCloud, install the [LlamaCloud plugin](https://marketplace.dify.ai/plugin/langgenius/llamacloud) instead of building a custom API. See the [video walkthrough](https://www.youtube.com/watch?v=FaOzKZRS-2E) for a complete setup demo.
If you're building a plugin for another knowledge service, the LlamaCloud plugin's [source code](https://github.com/langgenius/dify-official-plugins/tree/main/extensions/llamacloud) is available for reference.
</Tip>
<Info>
Dify only has retrieval access to external knowledge bases. It cannot modify or manage your external content. You maintain the knowledge base and its retrieval logic independently.
</Info>
## Step 1: Build the Retrieval API
Build an API service that implements the [External Knowledge API specification](/en/self-host/use-dify/knowledge/external-knowledge-api). Your service needs a single `POST` endpoint that accepts a search query and returns matching text chunks with similarity scores.
## Step 2: Register an External Knowledge API
An External Knowledge API stores your endpoint URL and authentication credentials. Multiple knowledge bases can share one API connection.
1. Go to **Knowledge**, click **External Knowledge API** in the upper-right corner, then click **Add an External Knowledge API**.
2. Fill in the following fields:
* **Name**: A label to distinguish this API connection from others.
* **API Endpoint**: The base URL of your external knowledge service. Dify appends `/retrieval` automatically when sending requests.
* **API Key**: The authentication credential for your service. Dify sends this as a Bearer token in the `Authorization` header.
Dify validates the connection by sending a test request to your endpoint when you save.
## Step 3: Create an External Knowledge Base
With the API registered, connect an external knowledge source to Dify. This creates a knowledge base in Dify that is linked to your external system.
1. Go to **Knowledge** and click **Connect to an External Knowledge Base**.
<Frame>
<img alt="Connect to External Knowledge Base" />
</Frame>
2. Fill in the following fields:
* **External Knowledge Name** and **Knowledge Description** (optional).
* **External Knowledge API**: Select the API connection you registered.
* **External Knowledge ID**: The identifier of the specific knowledge source within your external system, passed to your API as the `knowledge_id` field.
This is whatever ID your external service uses to distinguish between different knowledge bases. For example, a Bedrock knowledge base ARN or an ID you defined in your own system.
<Note>
The **External Knowledge API** and **External Knowledge ID** cannot be changed after creation. To use a different API or knowledge source, create a new external knowledge base.
</Note>
* **Retrieval Settings**:
* **Top K**: Maximum number of chunks to retrieve per query. Higher values return more results but may include less relevant content.
* **Score Threshold**: Minimum similarity score for returned chunks. Enable this to filter out low-relevance results. Use higher value for stricter relevance or lower value to include broader matches.
When disabled, all results up to the Top K limit are returned regardless of score.
Once created, the external knowledge base is available for use in your applications just like any built-in knowledge base. See [Integrate Knowledge Within Application](/en/self-host/use-dify/knowledge/integrate-knowledge-within-application) for details.
## Troubleshoot
### Connection Refused or Timeout
Dify routes outbound HTTP requests through a Squid-based SSRF proxy. If your external knowledge service runs on the same host as Dify or its domain is not allowlisted, the proxy blocks the request.
To allow connections, add your service's domain to the `allowed_domains` ACL in `docker/ssrf_proxy/squid.conf.template`:
```text theme={null}
acl allowed_domains dstdomain .marketplace.dify.ai .your-kb-service.com
```
Restart the SSRF proxy container after editing.
### API Response Format Issues
If retrieval fails or returns unexpected results, verify your API response against the [External Knowledge API specification](/en/self-host/use-dify/knowledge/external-knowledge-api#response).
Common issues:
* The `metadata` field in each record must be an object (`{}`), not `null`. A `null` value causes errors in the retrieval pipeline.
* The `content` and `score` fields must be present in every record.
# Configure the Chunk Settings
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text
## What is Chunking?
Documents imported into knowledge bases are split into smaller segments called **chunks**. Think of chunking like organizing a large book into chapters and paragraphs: you can't quickly find specific information in one massive block of text, but well-organized sections make retrieval efficient.
When users ask questions, the system searches through these chunks for relevant information and provides it to the LLM as context. Without chunking, processing entire documents for every query would be slow and inefficient.
**Key Chunk Parameters**
* **Delimiter**: The character or sequence where text is split. For example, `\n\n` splits at paragraph breaks, `\n` at line breaks.
<Note>
Delimiters are removed during chunking. For example, using `A` as the delimiter splits `CBACD` into `CB` and `CD`.
To avoid information loss, use non-content characters that don't naturally appear in your documents.
</Note>
* **Maximum chunk length**: The maximum size of each chunk in characters. Text exceeding this limit is force-split regardless of delimiter settings.
## Choose a Chunk Mode
<Note>
The chunk mode cannot be changed once the knowledge base is created. However, chunk settings like the delimiter and maximum chunk length can be adjusted at any time.
</Note>
### Mode Overview
<Tabs>
<Tab title="General">
In General mode, all chunks share the same settings. Matched chunks are returned directly as retrieval results.
**Chunk Settings**
Beyond delimiter and maximum chunk length, you can also configure **Chunk overlap** to specify how many characters overlap between adjacent chunks. This helps preserve semantic connections and prevents important information from being split across chunk boundaries.
For example, with a 50-character overlap, the last 50 characters of one chunk will also appear as the first 50 characters of the next chunk.
</Tab>
<Tab title="Parent-child">
In Parent-child mode, text is split into two tiers: smaller **child chunks** and larger **parent chunks**. When a query matches a child chunk, its entire parent chunk is returned as the retrieval result.
This solves a common retrieval dilemma: smaller chunks enable precise query matching but lack context, while larger chunks provide rich context but reduce retrieval accuracy.
Parent-child mode balances both: retrieving with precision and responding with context.
**Parent Chunk Settings**
Parent chunks can be created in **Paragraph** or **Full Doc** mode.
<Tabs>
<Tab title="Paragraph">
The document is split into multiple parent chunks based on the specified delimiter and maximum chunk length.
Suitable for lengthy documents with well-structured sections where each section provides meaningful context independently.
</Tab>
<Tab title="Full Doc">
The entire document serves as a single parent chunk.
Suitable for small, cohesive documents where the full context is essential for understanding any specific detail.
<Note>
In **Full Doc** mode:
* Only the first 10,000 tokens are processed. Content beyond this limit will be truncated.
* The parent chunk cannot be edited once created. To modify it, you must upload a new document.
</Note>
</Tab>
</Tabs>
**Child Chunk Settings**
Each parent chunk is further split into child chunks using their own delimiter and maximum chunk length settings.
</Tab>
</Tabs>
### Quick Comparison
| Dimension | General Mode | Parent-child Mode |
| :---------------------------------------------------------------------------------------------------- | :----------------------------------------------------- | :------------------------------------------------------------------------------------------------ |
| Chunking Strategy | Single-tier: all chunks use the same settings | Two-tier: separate settings for parent and child chunks |
| Retrieval Workflow | Matched chunks are directly returned | Child chunks are used for matching queries; parent chunks are returned to provide broader context |
| Compatible [Index Method](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods) | High Quality, Economical | High Quality only |
| Best For | Simple, self-contained content like glossaries or FAQs | Information-dense documents like technical manuals or research papers where context matters |
## Pre-process Text Before Chunking
Before splitting text into chunks, you can clean up irrelevant content to improve retrieval quality.
* **Replace consecutive spaces, newlines, and tabs**
* Three or more consecutive newlines → two newlines
* Multiple spaces → single space
* Tabs, form feeds, and special Unicode spaces → regular space
* **Remove all URLs and email addresses**
<Info>
This setting is ignored in **Full Doc** mode.
</Info>
## Enable Summary Auto-Gen
Automatically generate summaries for all chunks to enhance their retrievability.
Summaries are embedded and indexed for retrieval as well. When a summary matches a query, its corresponding chunk is also returned.
You can manually edit auto-generated summaries or regenerate them for specific documents later. See [Manage Knowledge Content](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents) for details.
<Tip>
If you select a vision-capable LLM, summaries will be generated based on both the chunk text and any attached images.
</Tip>
## Preview Chunks
Click **Preview** to see how your content will be chunked. A limited number of chunks will be displayed for a quick review.
If the results don't perfectly match your expectations, choose the closest configuration; you can manually fine-tune chunks later. See [Manage Knowledge Content](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents) for details.
For multiple documents, click the file name at the top of the preview panel to switch between them.
# Upload Local Files
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/readme
<Note>
Once a knowledge base is created, its data source cannot be changed later.
</Note>
When creating a ready-to-use knowledge base, you can upload local files as its data source:
1. Click **Knowledge** > **Create** > **Create a ready-to-use knowledge base**.
2. Select **Import from file** as the data source, then upload your files.
* Maximum number of files per upload: 5 (set via `UPLOAD_FILE_BATCH_LIMIT`)
* Maximum file size: 15 MB (set via `UPLOAD_FILE_SIZE_LIMIT`)
***
**For Images in Uploaded Files**
JPG, JPEG, PNG, and GIF images under 2 MB are automatically extracted as attachments to their corresponding chunks. These images can be managed independently and are returned alongside their chunks during retrieval.
URLs of extracted images remain in the chunk text, but you can safely remove these URLs to keep the text clean; this won't affect the extracted images.
If you select a multimodal embedding model (marked with a **Vision** icon) in index settings, the extracted images will also be embedded and indexed for retrieval.
Each chunk supports up to 10 image attachments (set via `SINGLE_CHUNK_ATTACHMENT_LIMIT`); images beyond this limit will not be extracted. The image size limit is governed by `ATTACHMENT_IMAGE_FILE_SIZE_LIMIT`.
The above extraction rule applies to:
* Images embedded in DOCX and XLSX files
<Tip>
Images embedded in other file types (e.g., PDF) can be extracted by using appropriate document extraction plugins in [knowledge pipelines](/en/self-host/use-dify/knowledge/knowledge-pipeline/readme).
</Tip>
* Images referenced via accessible URLs using the following Markdown syntax in any file type:
* ``
* ``
# Sync Data from Notion
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/sync-from-notion
Dify datasets support importing from Notion and setting up **synchronization** so that data updates in Notion are automatically synced to Dify.
<Info>
Before you can authorize Notion, create a Notion integration and set the corresponding environment variables. See [Configure the Notion Integration](#configure-the-notion-integration) below.
</Info>
### Authorization Verification
1. When creating a dataset and selecting the data source, click **Sync from Notion Content -- Bind Now** and follow the prompts to complete the authorization verification.
2. Alternatively, you can go to **Settings -- Data Sources -- Add Data Source**, click on the Notion source **Bind**, and complete the authorization verification.
<Frame>
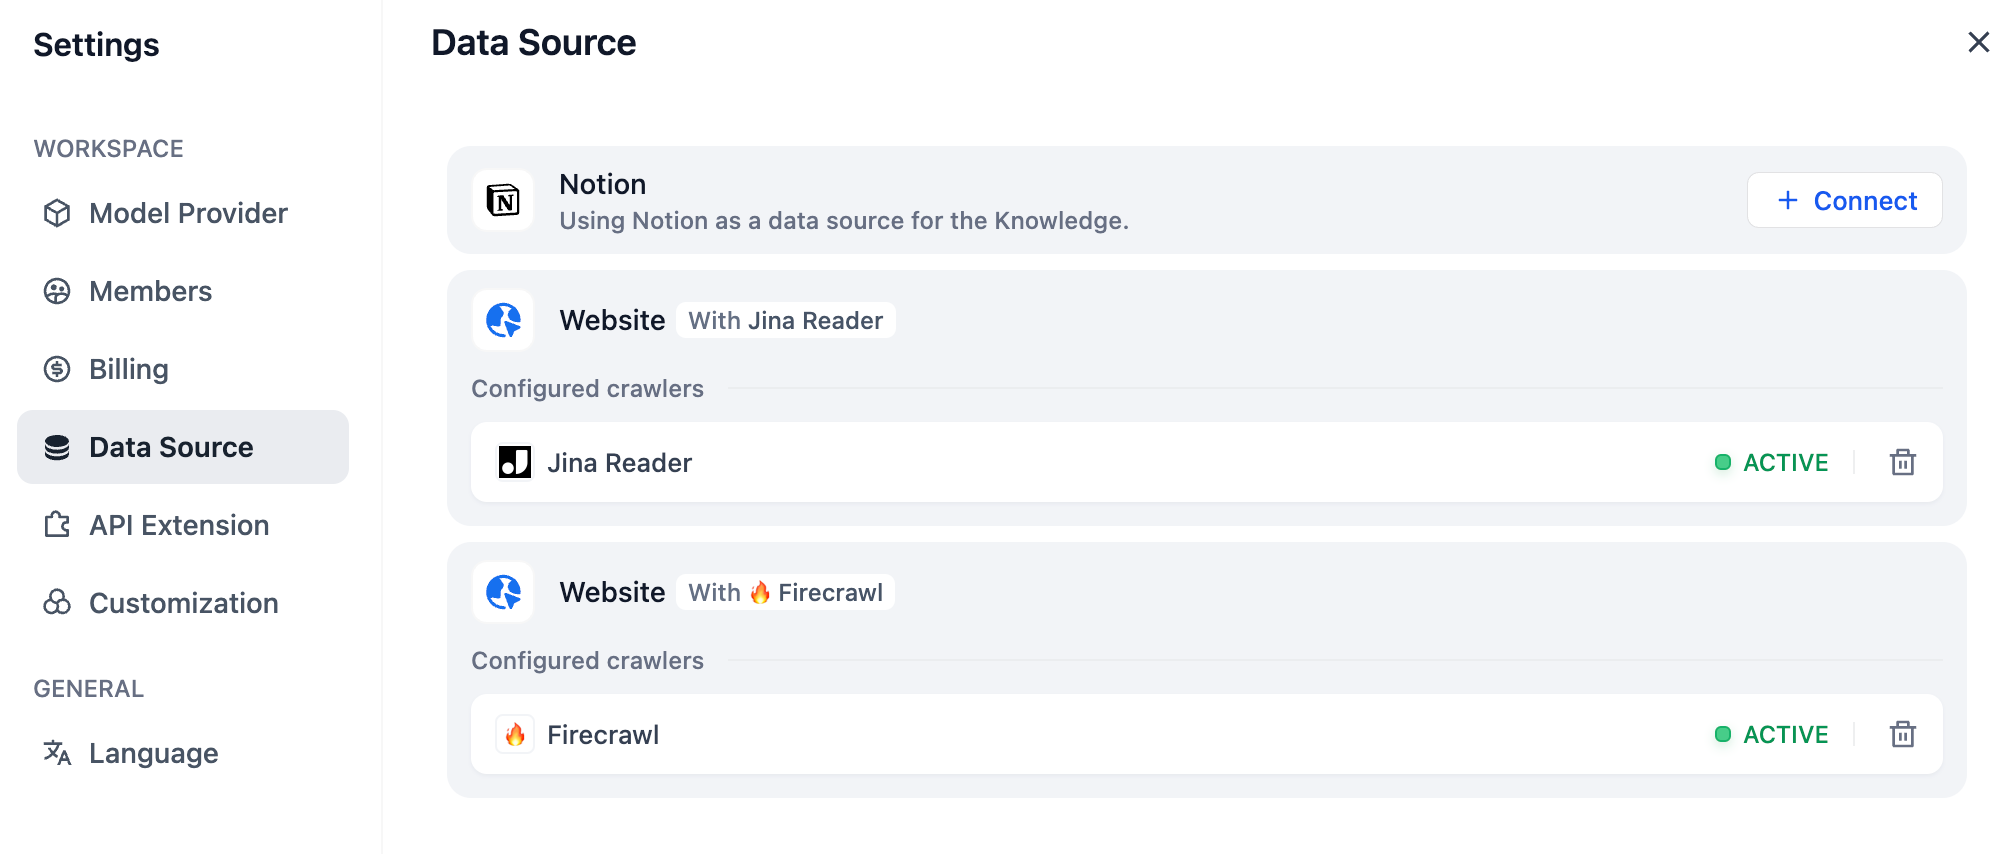
</Frame>
### Import Notion Data
After completing the authorization verification, go to the create dataset page, click **Sync from Notion Content**, and select the authorized pages you need to import.
<Frame>
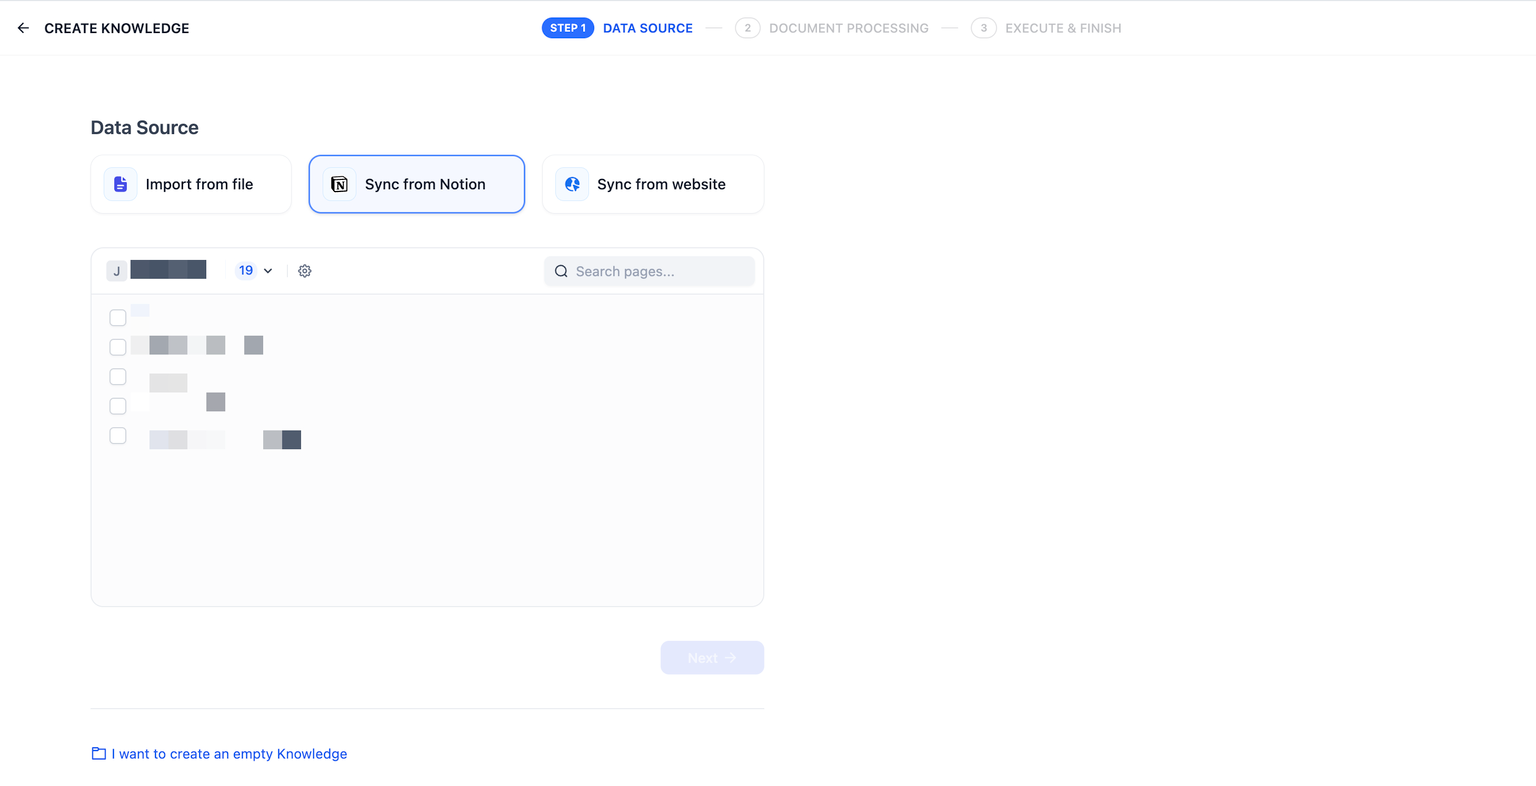
</Frame>
### Chunking and Cleaning
Next, choose a [chunking mode](/en/self-host/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text) and [indexing method](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods) for your knowledge base, then save it and wait for the automatically processing. Dify not only supports importing standard Notion pages but can also consolidate and save page attributes from database-type pages.
<Note>
Images and files cannot be imported, and data from tables will be converted to text.
</Note>
<Frame>
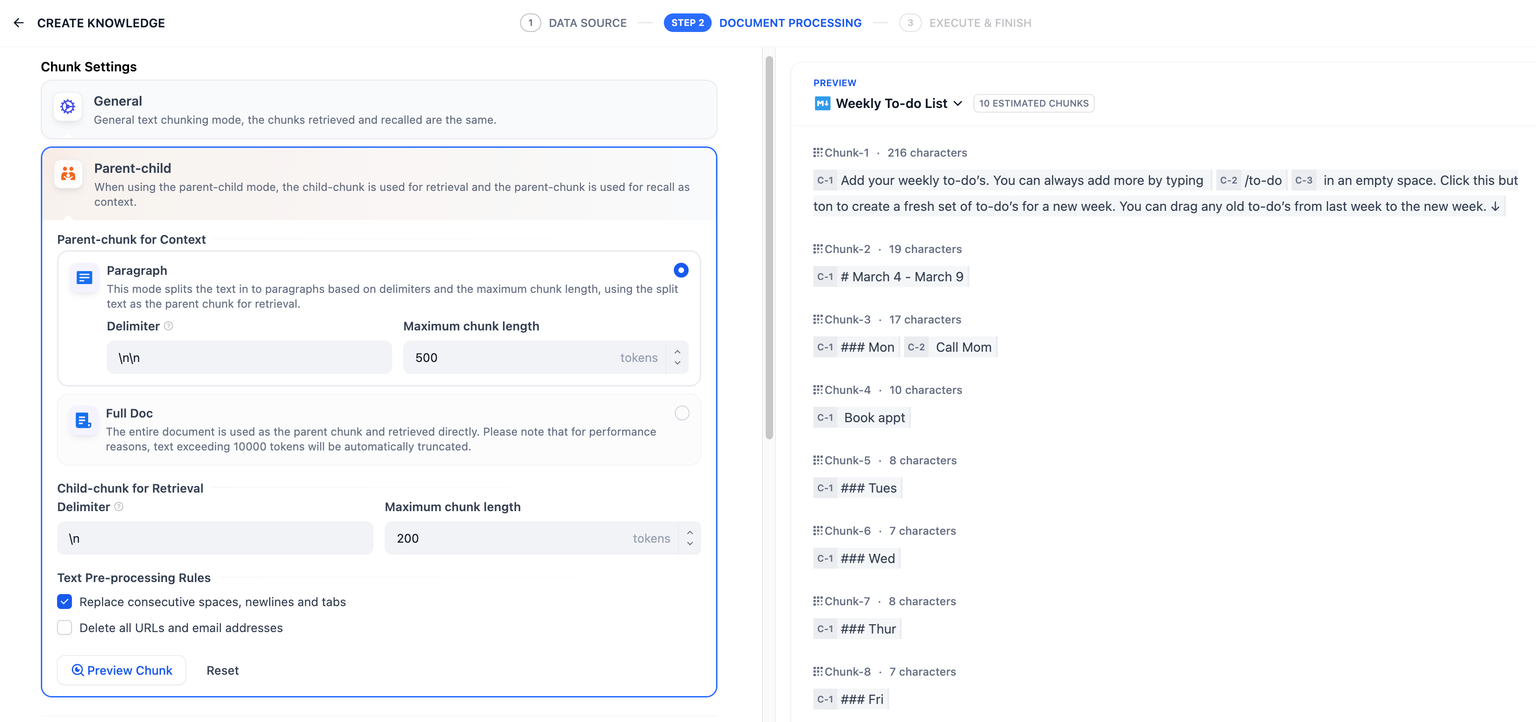
</Frame>
### Synchronize Notion Data
If your Notion content has been updated, you can sync the changes by clicking the **Sync** button for the corresponding page in the document list of your knowledge base. Syncing involves an embedding process, which will consume tokens from your embedding model.
<Frame>
</Frame>
### Configure the Notion Integration
Notion offers two integration options: **internal integration** and **public integration**. Pick one based on whether the integration will only be used inside your own Notion workspace (internal) or distributed for others to install (public). For more details, refer to the [official Notion documentation](https://developers.notion.com/guides/get-started/authorization).
#### Use an internal integration
Create an integration in the Notion [integration settings page](https://www.notion.so/my-integrations). All integrations start as internal by default and are associated with the Notion workspace you choose, so you need to be the workspace owner to create one.
Click **New integration**. The type is **Internal** by default and cannot be modified. Select the associated workspace, enter the integration name, upload a logo, and click **Submit**.
<Frame>
</Frame>
Update the integration's settings as needed under the **Capabilities** tab, then click **Show** under **Secrets** to copy the secret.
<Frame>
</Frame>
In your Dify deployment's `.env` file, configure the following environment variables:
```
NOTION_INTEGRATION_TYPE=internal
NOTION_INTERNAL_SECRET=your-internal-secret
```
#### Use a public integration
Upgrade the internal integration to a public integration. Navigate to the integration's **Distribution** page and toggle the switch to make it public. You'll need to fill in additional information in the **Organization Information** form, including company name, website, and redirect URL, then click **Submit**.
<Frame>
</Frame>
Once the integration is public, retrieve the integration key from the **Keys** tab:
<Frame>
</Frame>
In your Dify deployment's `.env` file, configure the following environment variables:
```
NOTION_INTEGRATION_TYPE=public
NOTION_CLIENT_SECRET=your-client-secret
NOTION_CLIENT_ID=your-client-id
```
Restart Dify to pick up the new environment variables. You can then authorize Notion and import data following the steps above.
# Import Data from Website
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/sync-from-website
The knowledge base supports crawling content from public web pages using third-party tools such as [Jina Reader](https://jina.ai/reader/) and [Firecrawl](https://www.firecrawl.dev/), parsing it into Markdown content, and importing it into the knowledge base.
<Info>
[Firecrawl](https://www.firecrawl.dev/) and [Jina Reader](https://jina.ai/reader/) are both open-source web parsing tools that can convert web pages into clean Markdown format text that is easy for LLMs to recognize, while providing easy-to-use API services.
</Info>
The following sections will introduce the usage methods for Firecrawl and Jina Reader respectively.
## Firecrawl
### **1. Configure Firecrawl API credentials**
Click on the avatar in the upper right corner, then go to the **DataSource** page, and click the **Configure** button next to Firecrawl.
<Frame>
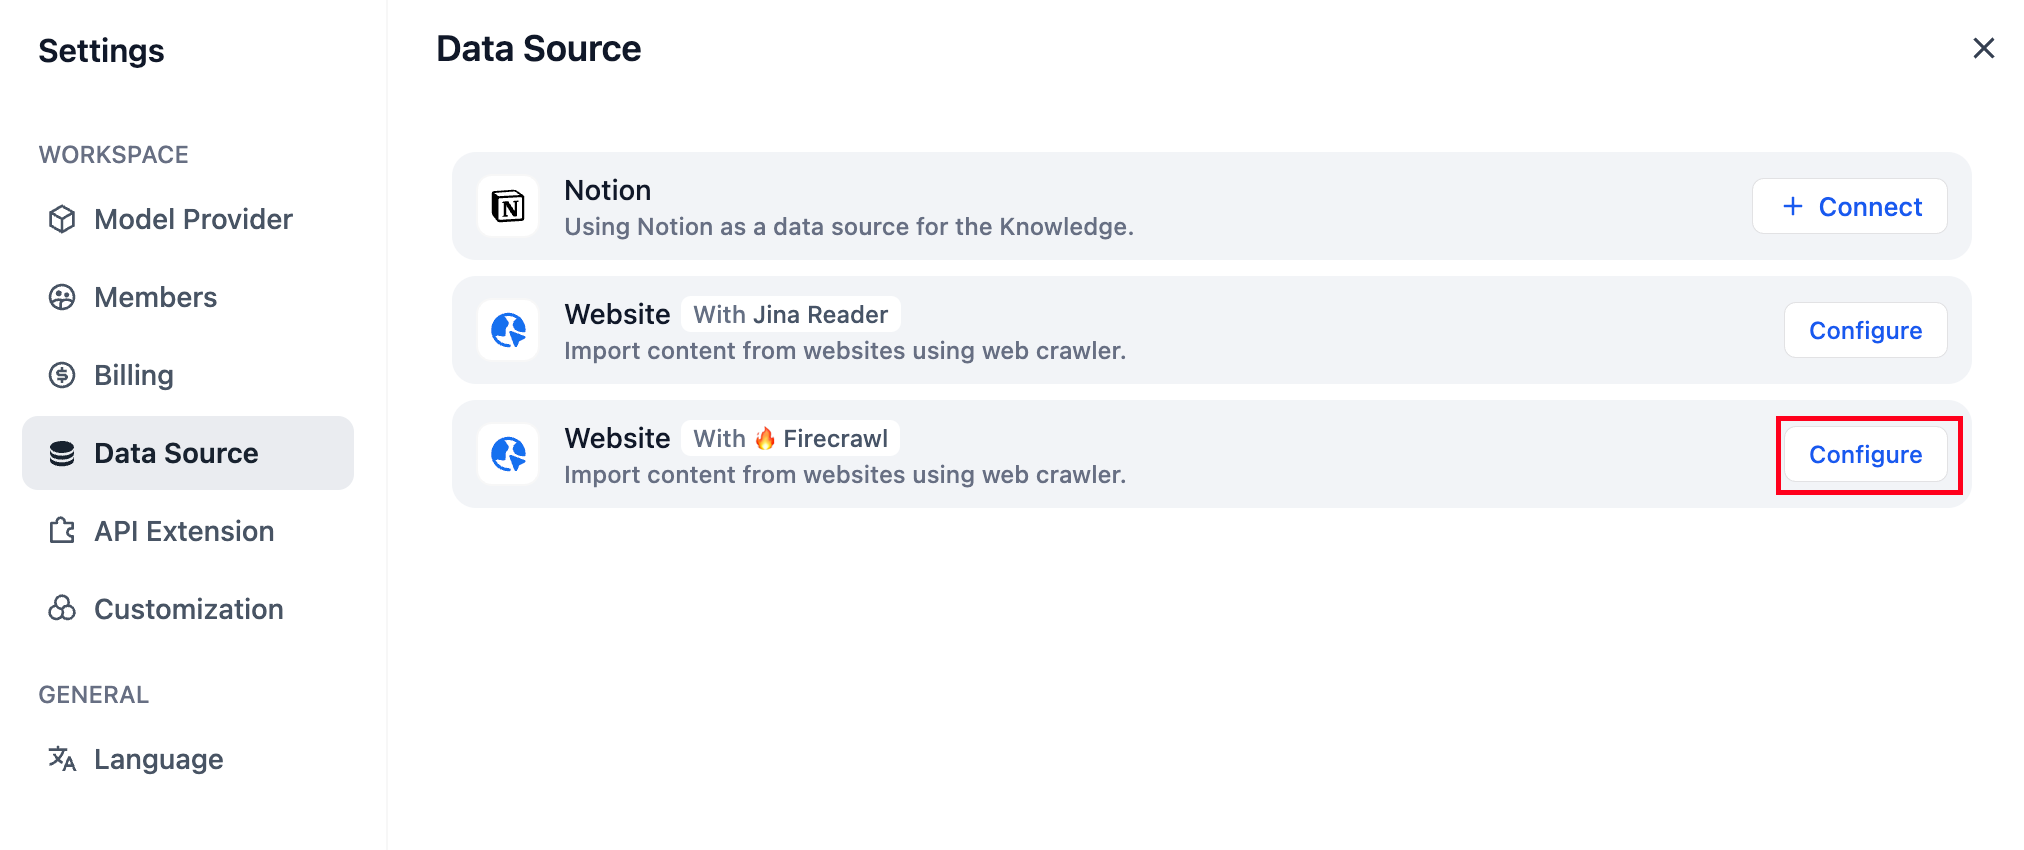
</Frame>
Log in to the [Firecrawl website](https://www.firecrawl.dev/) to complete registration, get your API Key, and then enter and save it in Dify.
<Frame>

</Frame>
### 2. Scrape target webpage
On the knowledge base creation page, select **Sync from website**, choose Firecrawl as the provider, and enter the target URL to be crawled.
The configuration options include: Whether to crawl sub-pages, Page crawling limit, Page scraping max depth, Excluded paths, Include only paths, and Content extraction scope. After completing the configuration, click **Run** to preview the parsed pages.
<Frame>
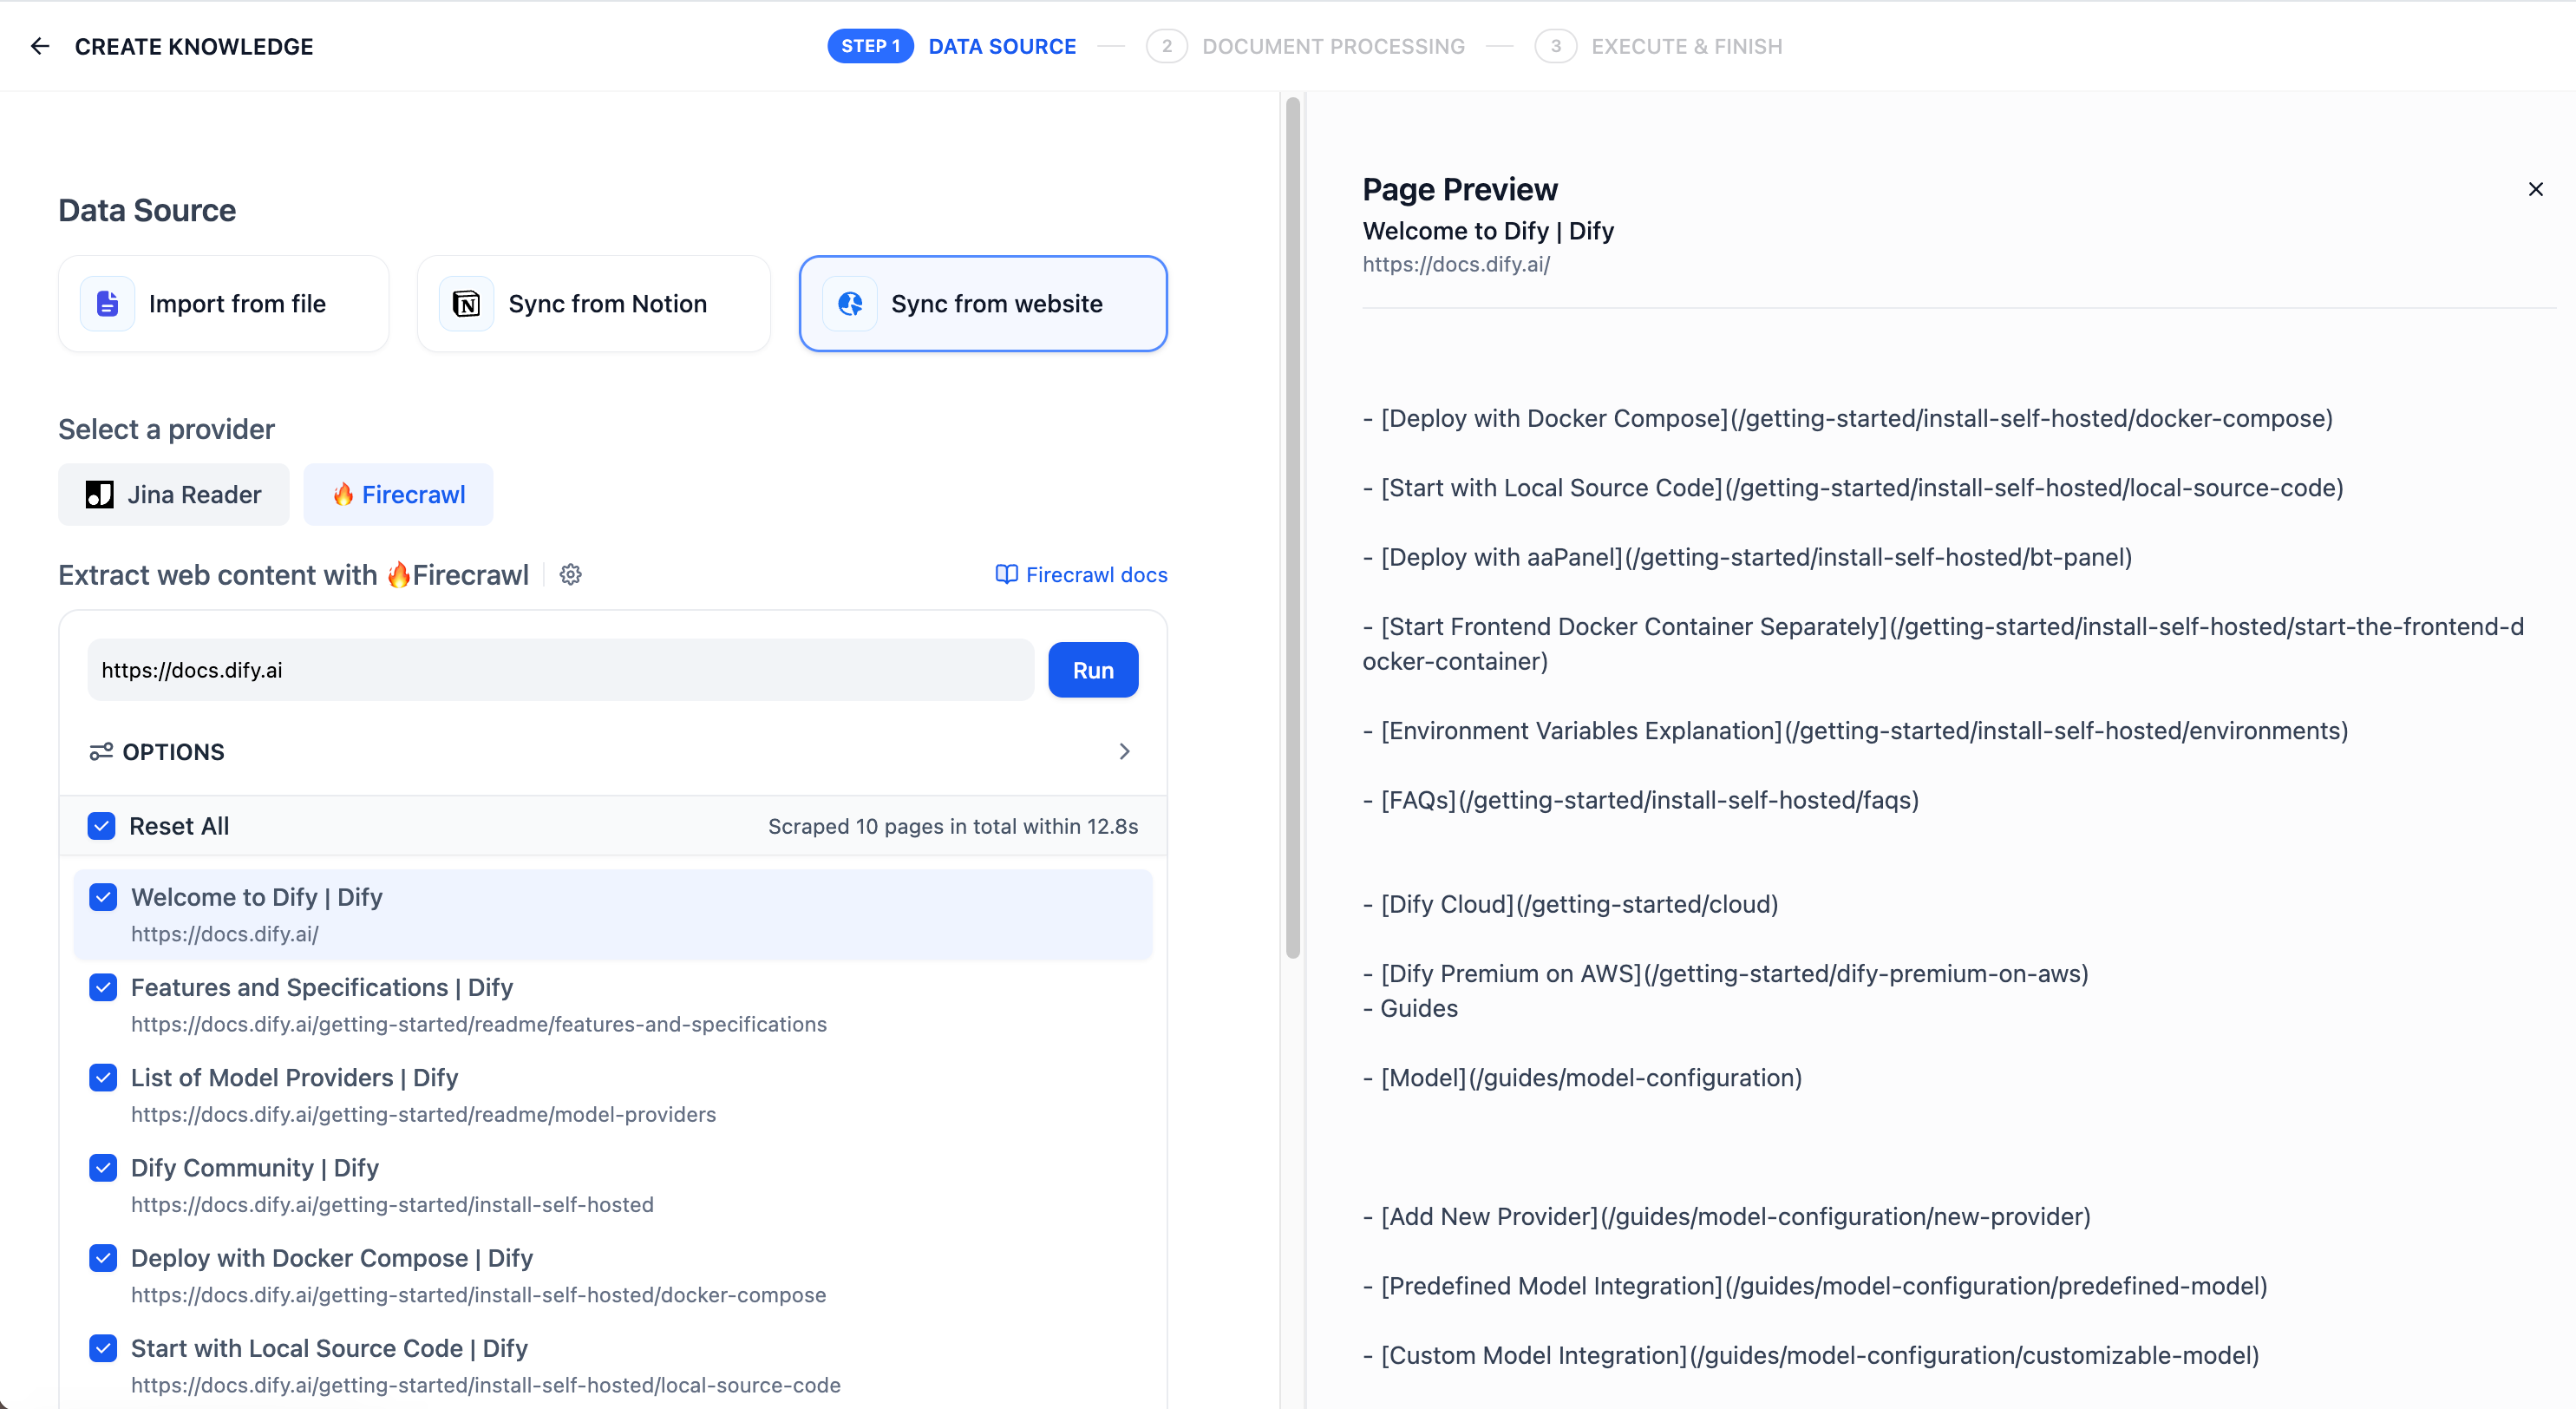
</Frame>
### 3. Review import results
After importing the parsed text from the webpage, it is stored in the knowledge base documents. View the import results and click **Add URL** to continue importing new web pages.
## Jina Reader
### 1. Configure Jina Reader Credentials
Click on the avatar in the upper right corner, then go to the **DataSource** page, and click the **Configure** button next to Jina Reader.
<Frame>
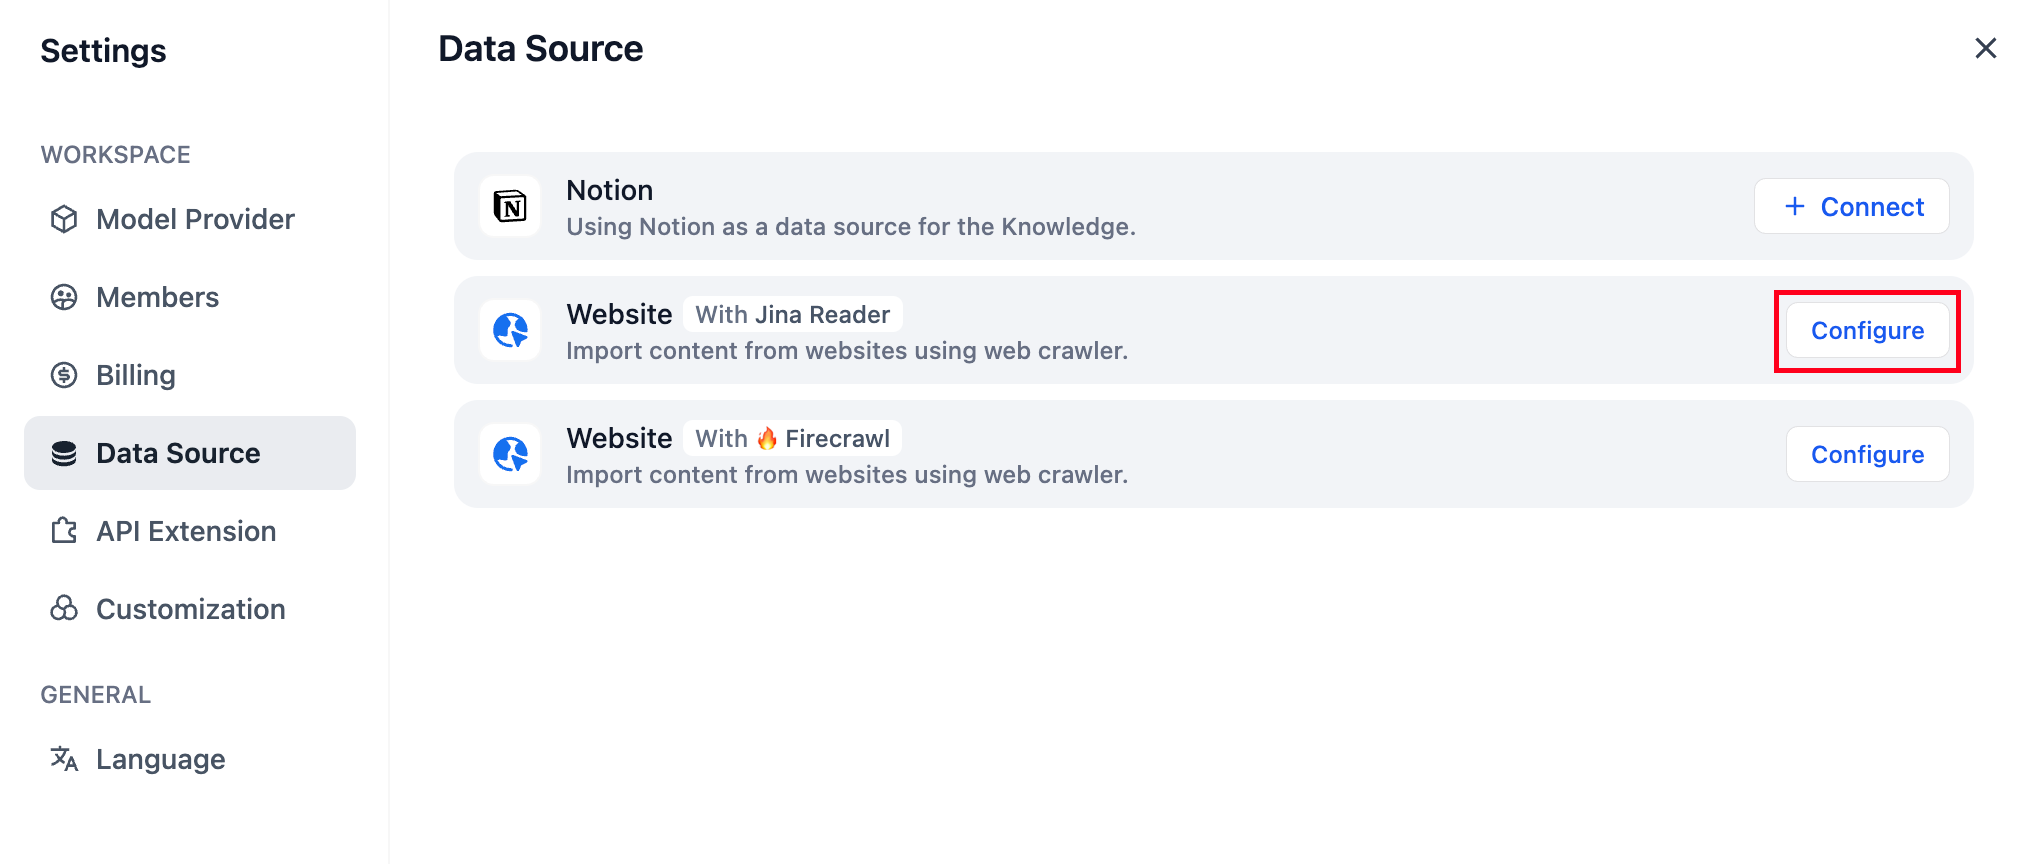
</Frame>
Log in to the [Jina Reader website](https://jina.ai/reader/), complete registration, obtain the API Key, then fill it in and save.
### 2. Use Jina Reader to Crawl Web Content
On the knowledge base creation page, select **Sync from website**, choose Jina Reader as the provider, and enter the target URL to be crawled.
<Frame>
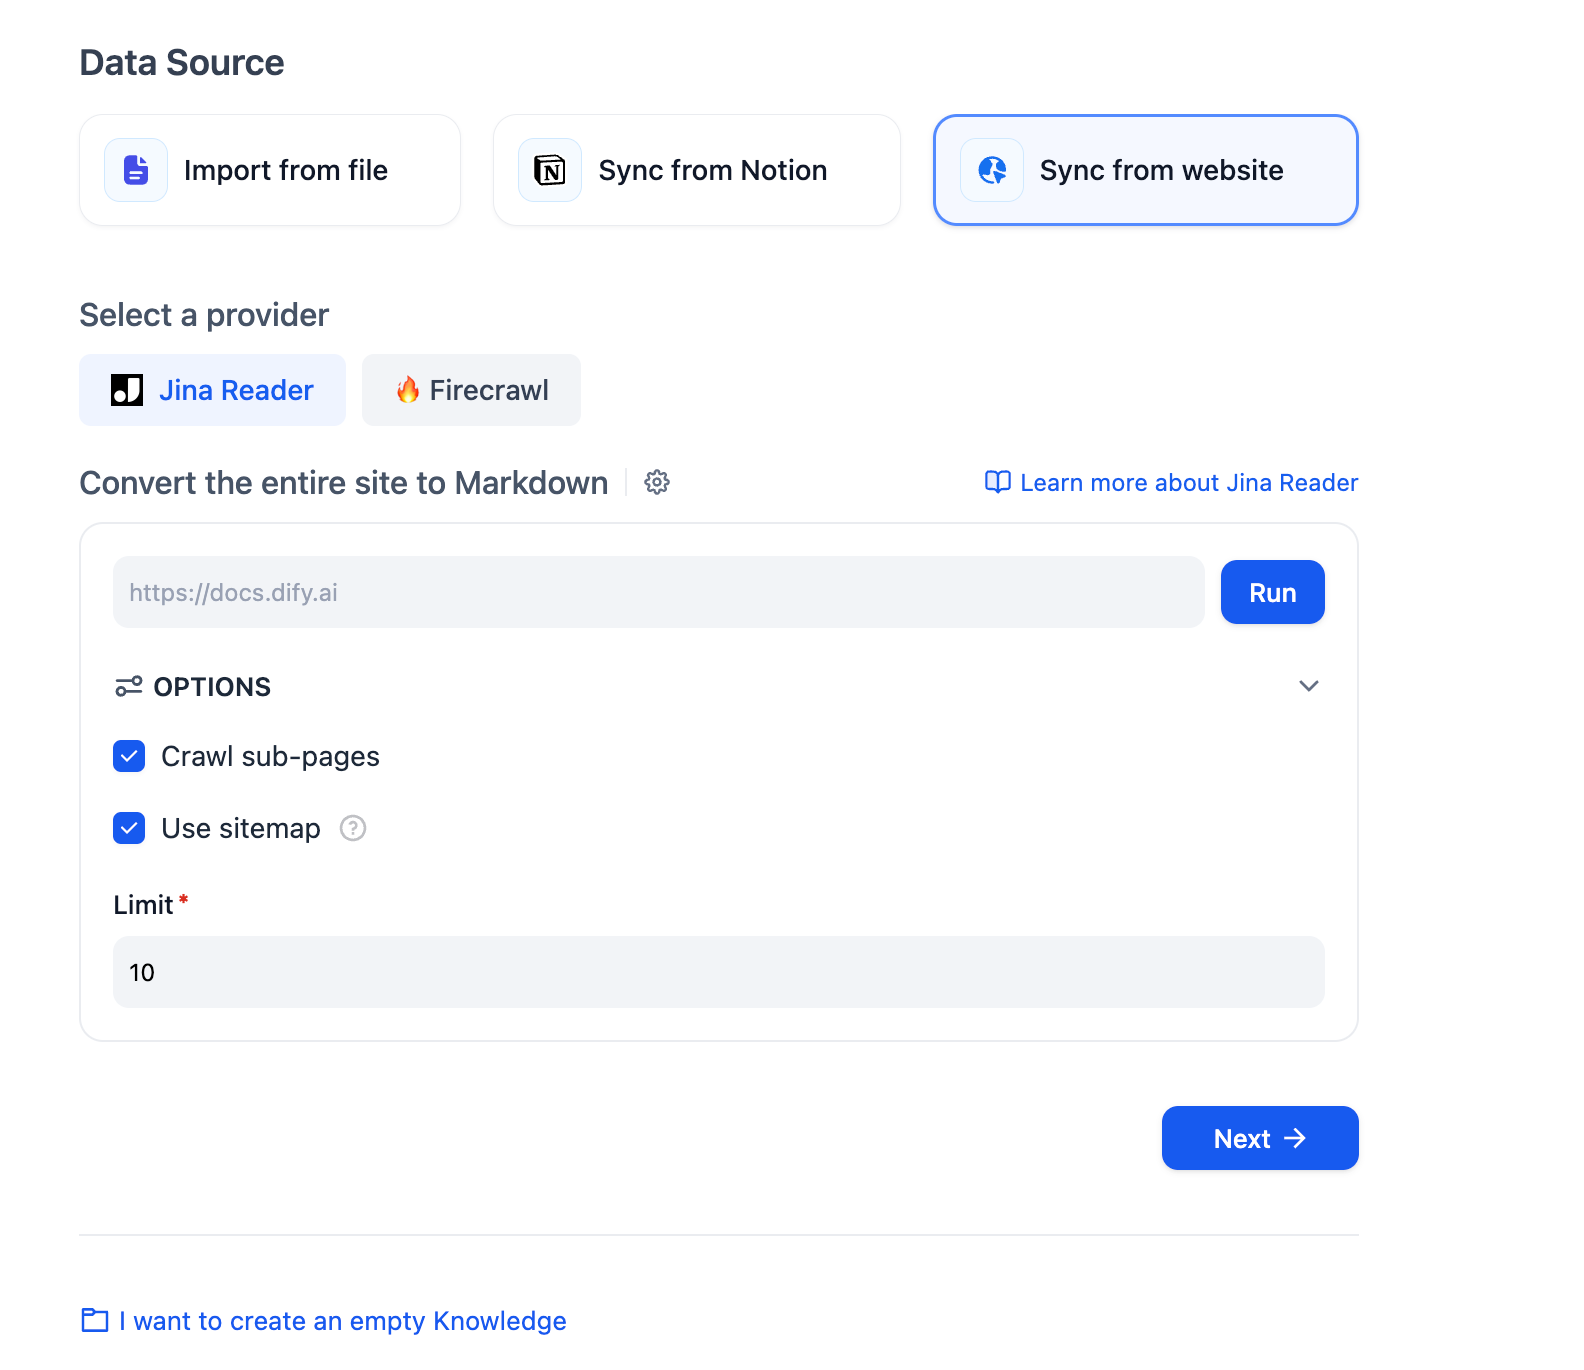
</Frame>
Configuration options include: whether to crawl subpages, maximum number of pages to crawl, and whether to use sitemap for crawling. After completing the configuration, click the **Run** button to preview the page links to be crawled.
<Frame>
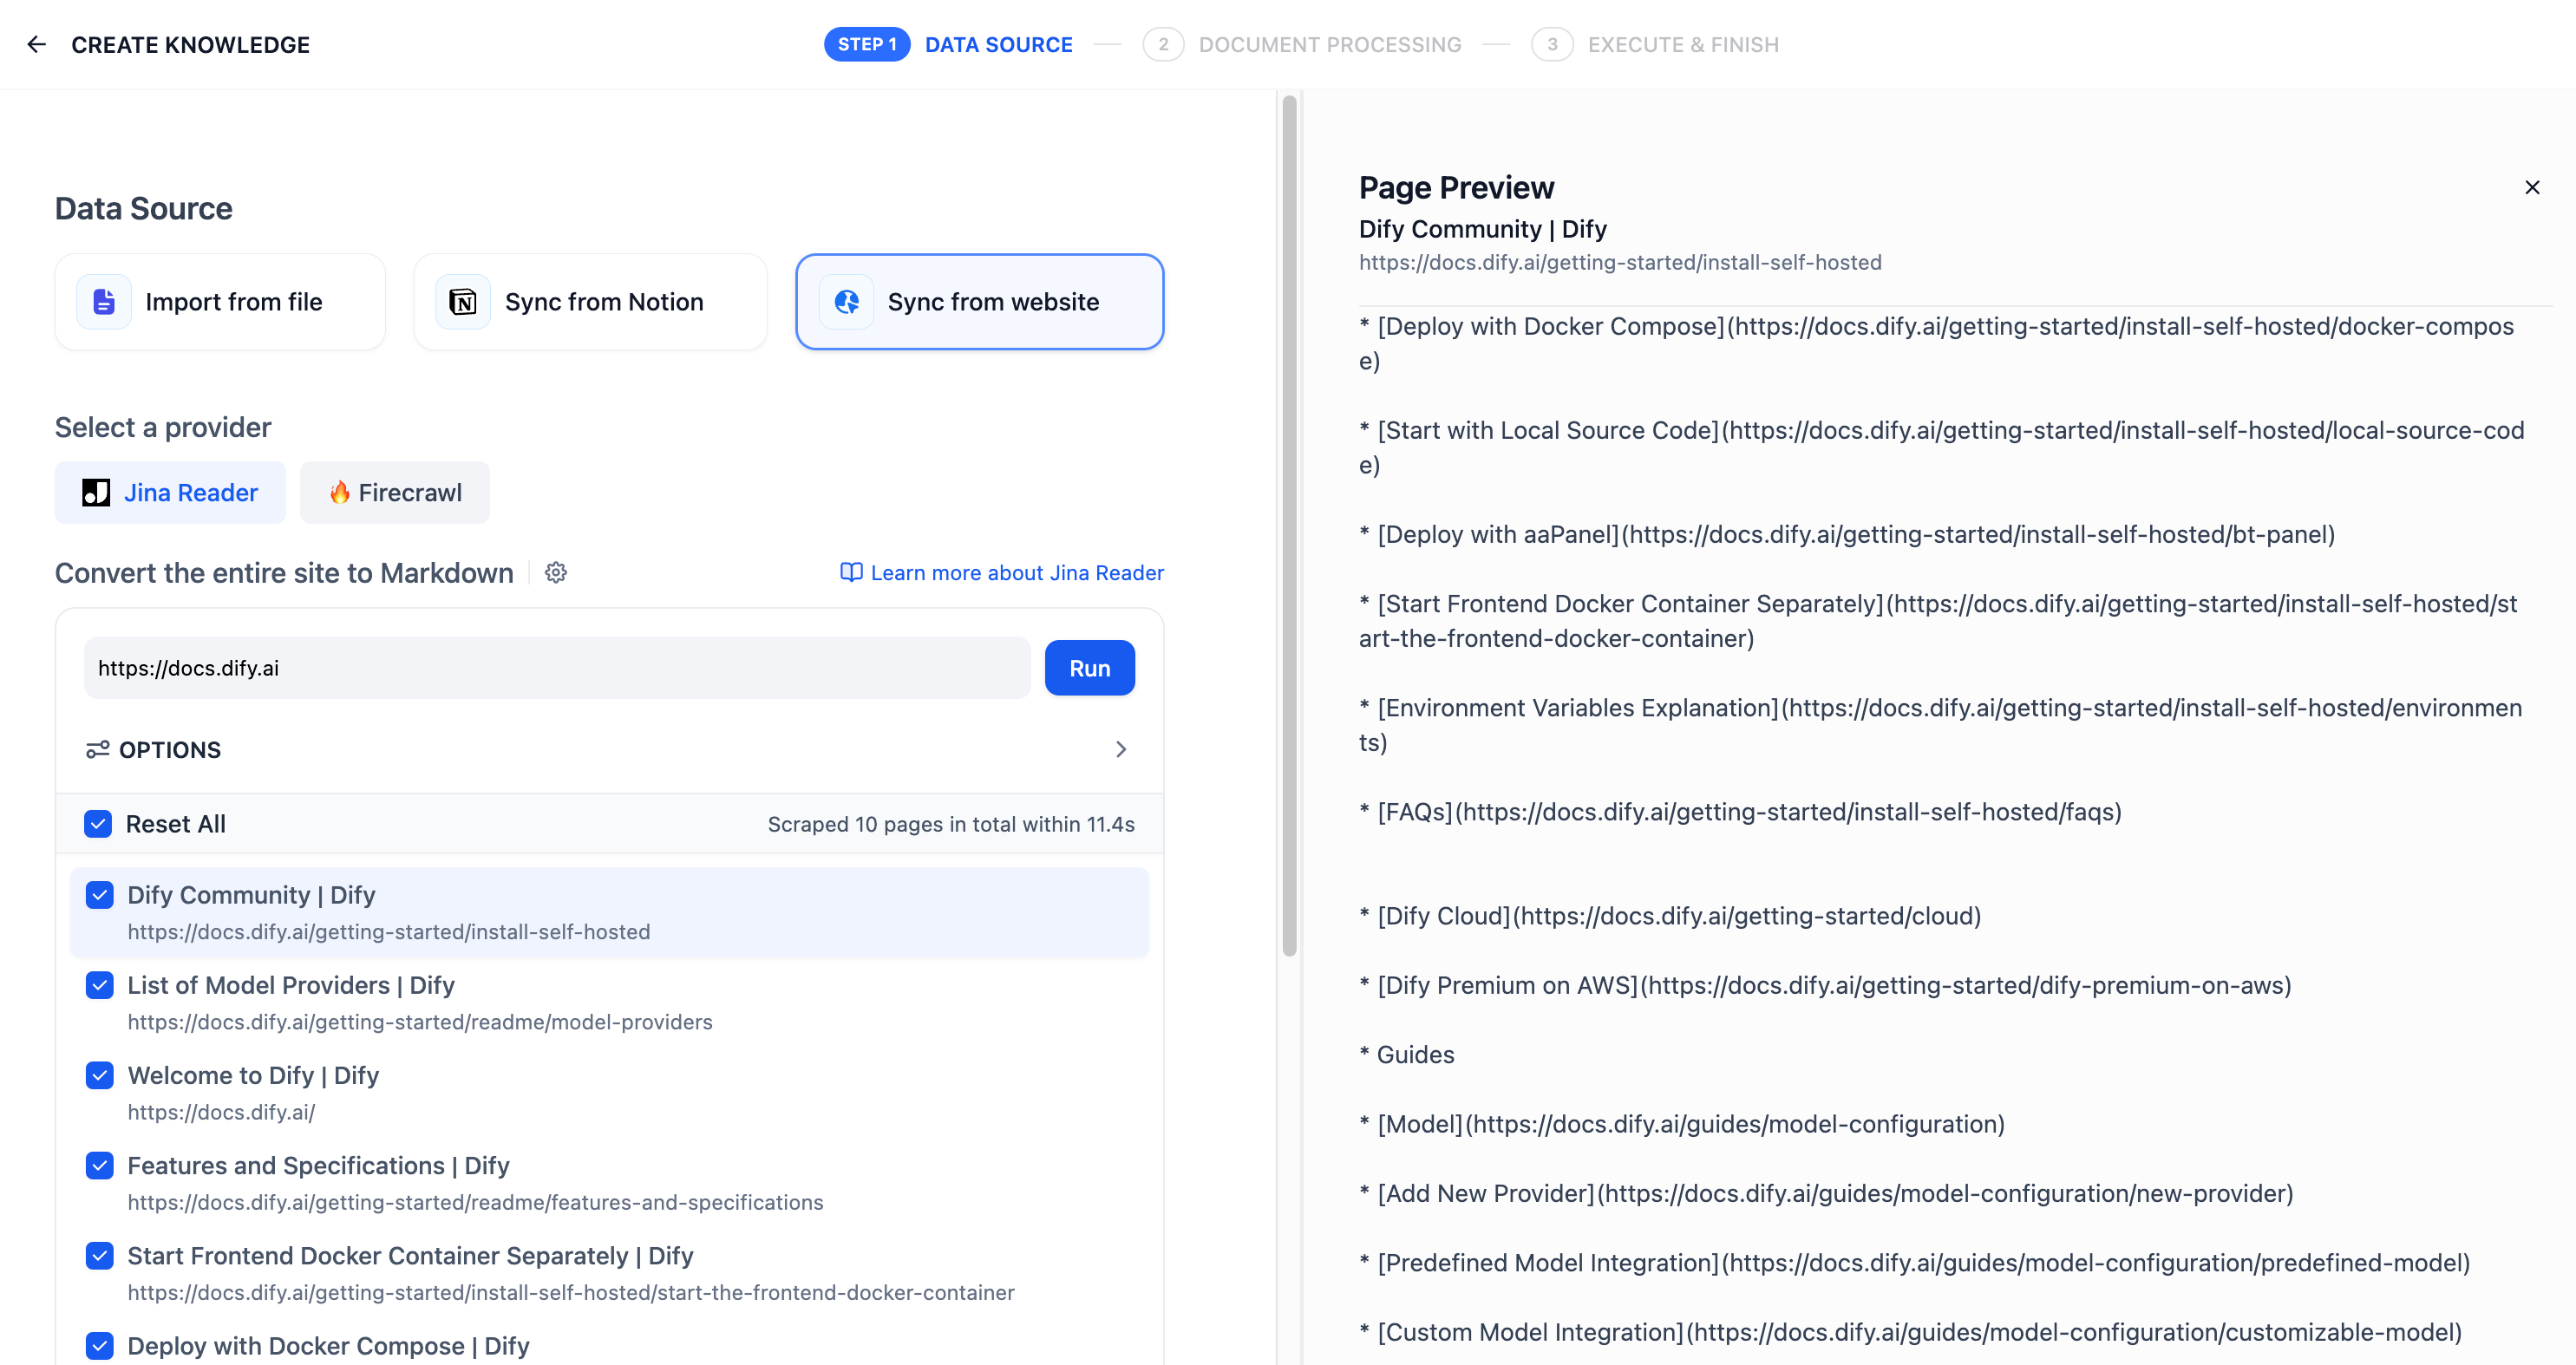
</Frame>
After importing the parsed text from web pages into the knowledge base, you can review the imported results in the documents section. To add more web pages, click the **Add URL** button on the right to continue importing new pages.
<Frame>
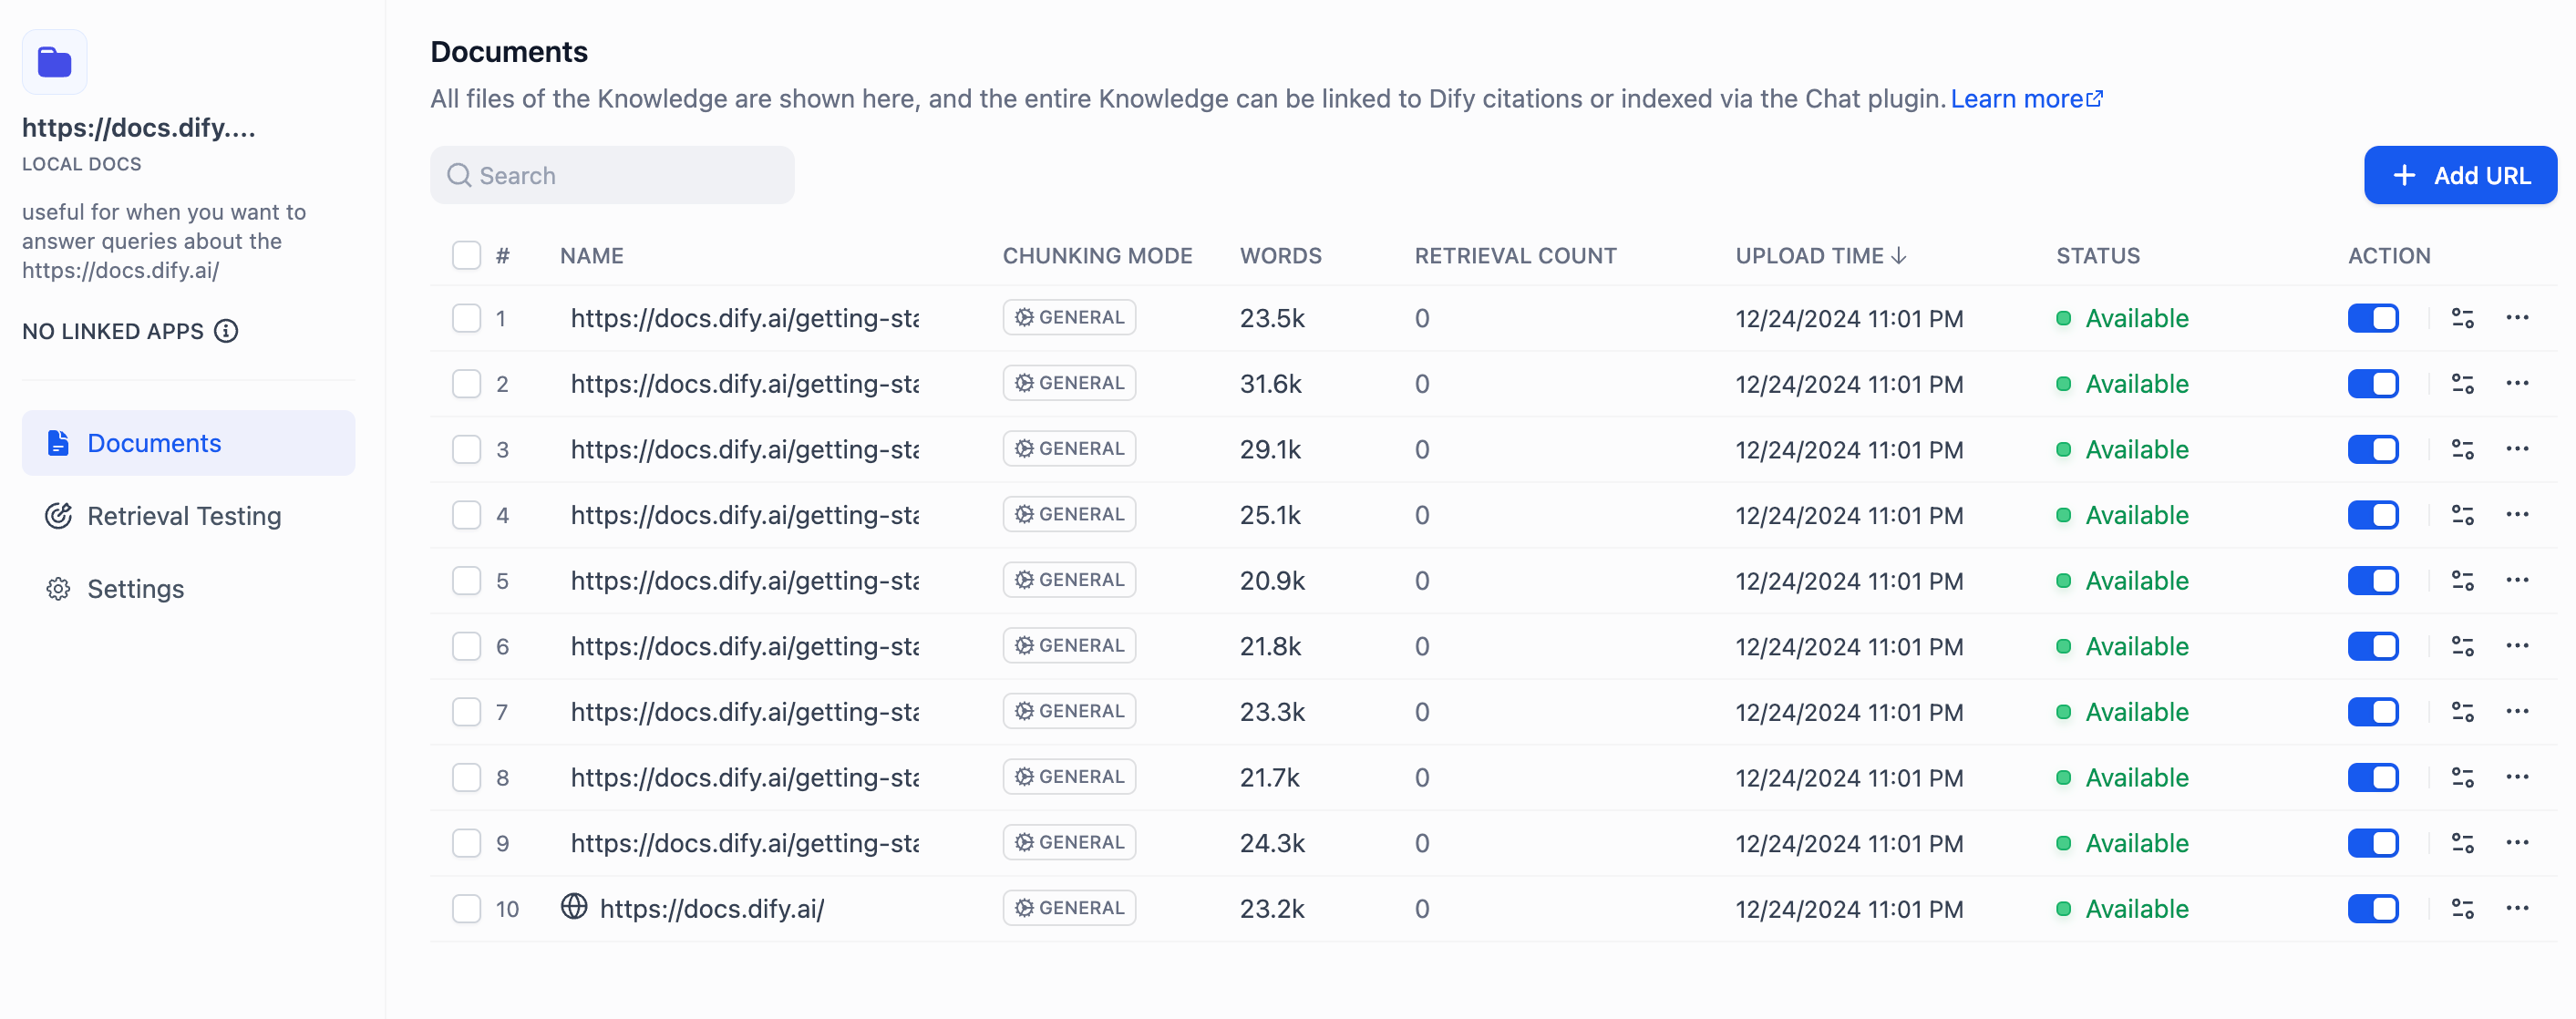
</Frame>
After crawling is complete, the content from the web pages will be incorporated into the knowledge base.
# Create a Ready-to-Use Knowledge Base
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/introduction
To create a ready-to-use knowledge base:
1. Click **Knowledge** > **Create** > **Create a ready-to-use knowledge base**, then [upload local files](/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/readme), [sync data from Notion](/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/sync-from-notion), or [webpages](/en/self-host/use-dify/knowledge/create-knowledge/import-text-data/sync-from-website), or create an empty knowledge base.
2. [Configure the chunk settings](/en/self-host/use-dify/knowledge/create-knowledge/chunking-and-cleaning-text) and preview the chunking results. This stage involves content preprocessing and structuring, where long texts are divided into multiple smaller chunks.
3. [Specify the index method and retrieval settings](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods). Once the knowledge base receives a user query, it searches existing documents according to preset retrieval methods and extracts highly relevant content chunks.
4. Wait for the data processing to complete.
<Frame>
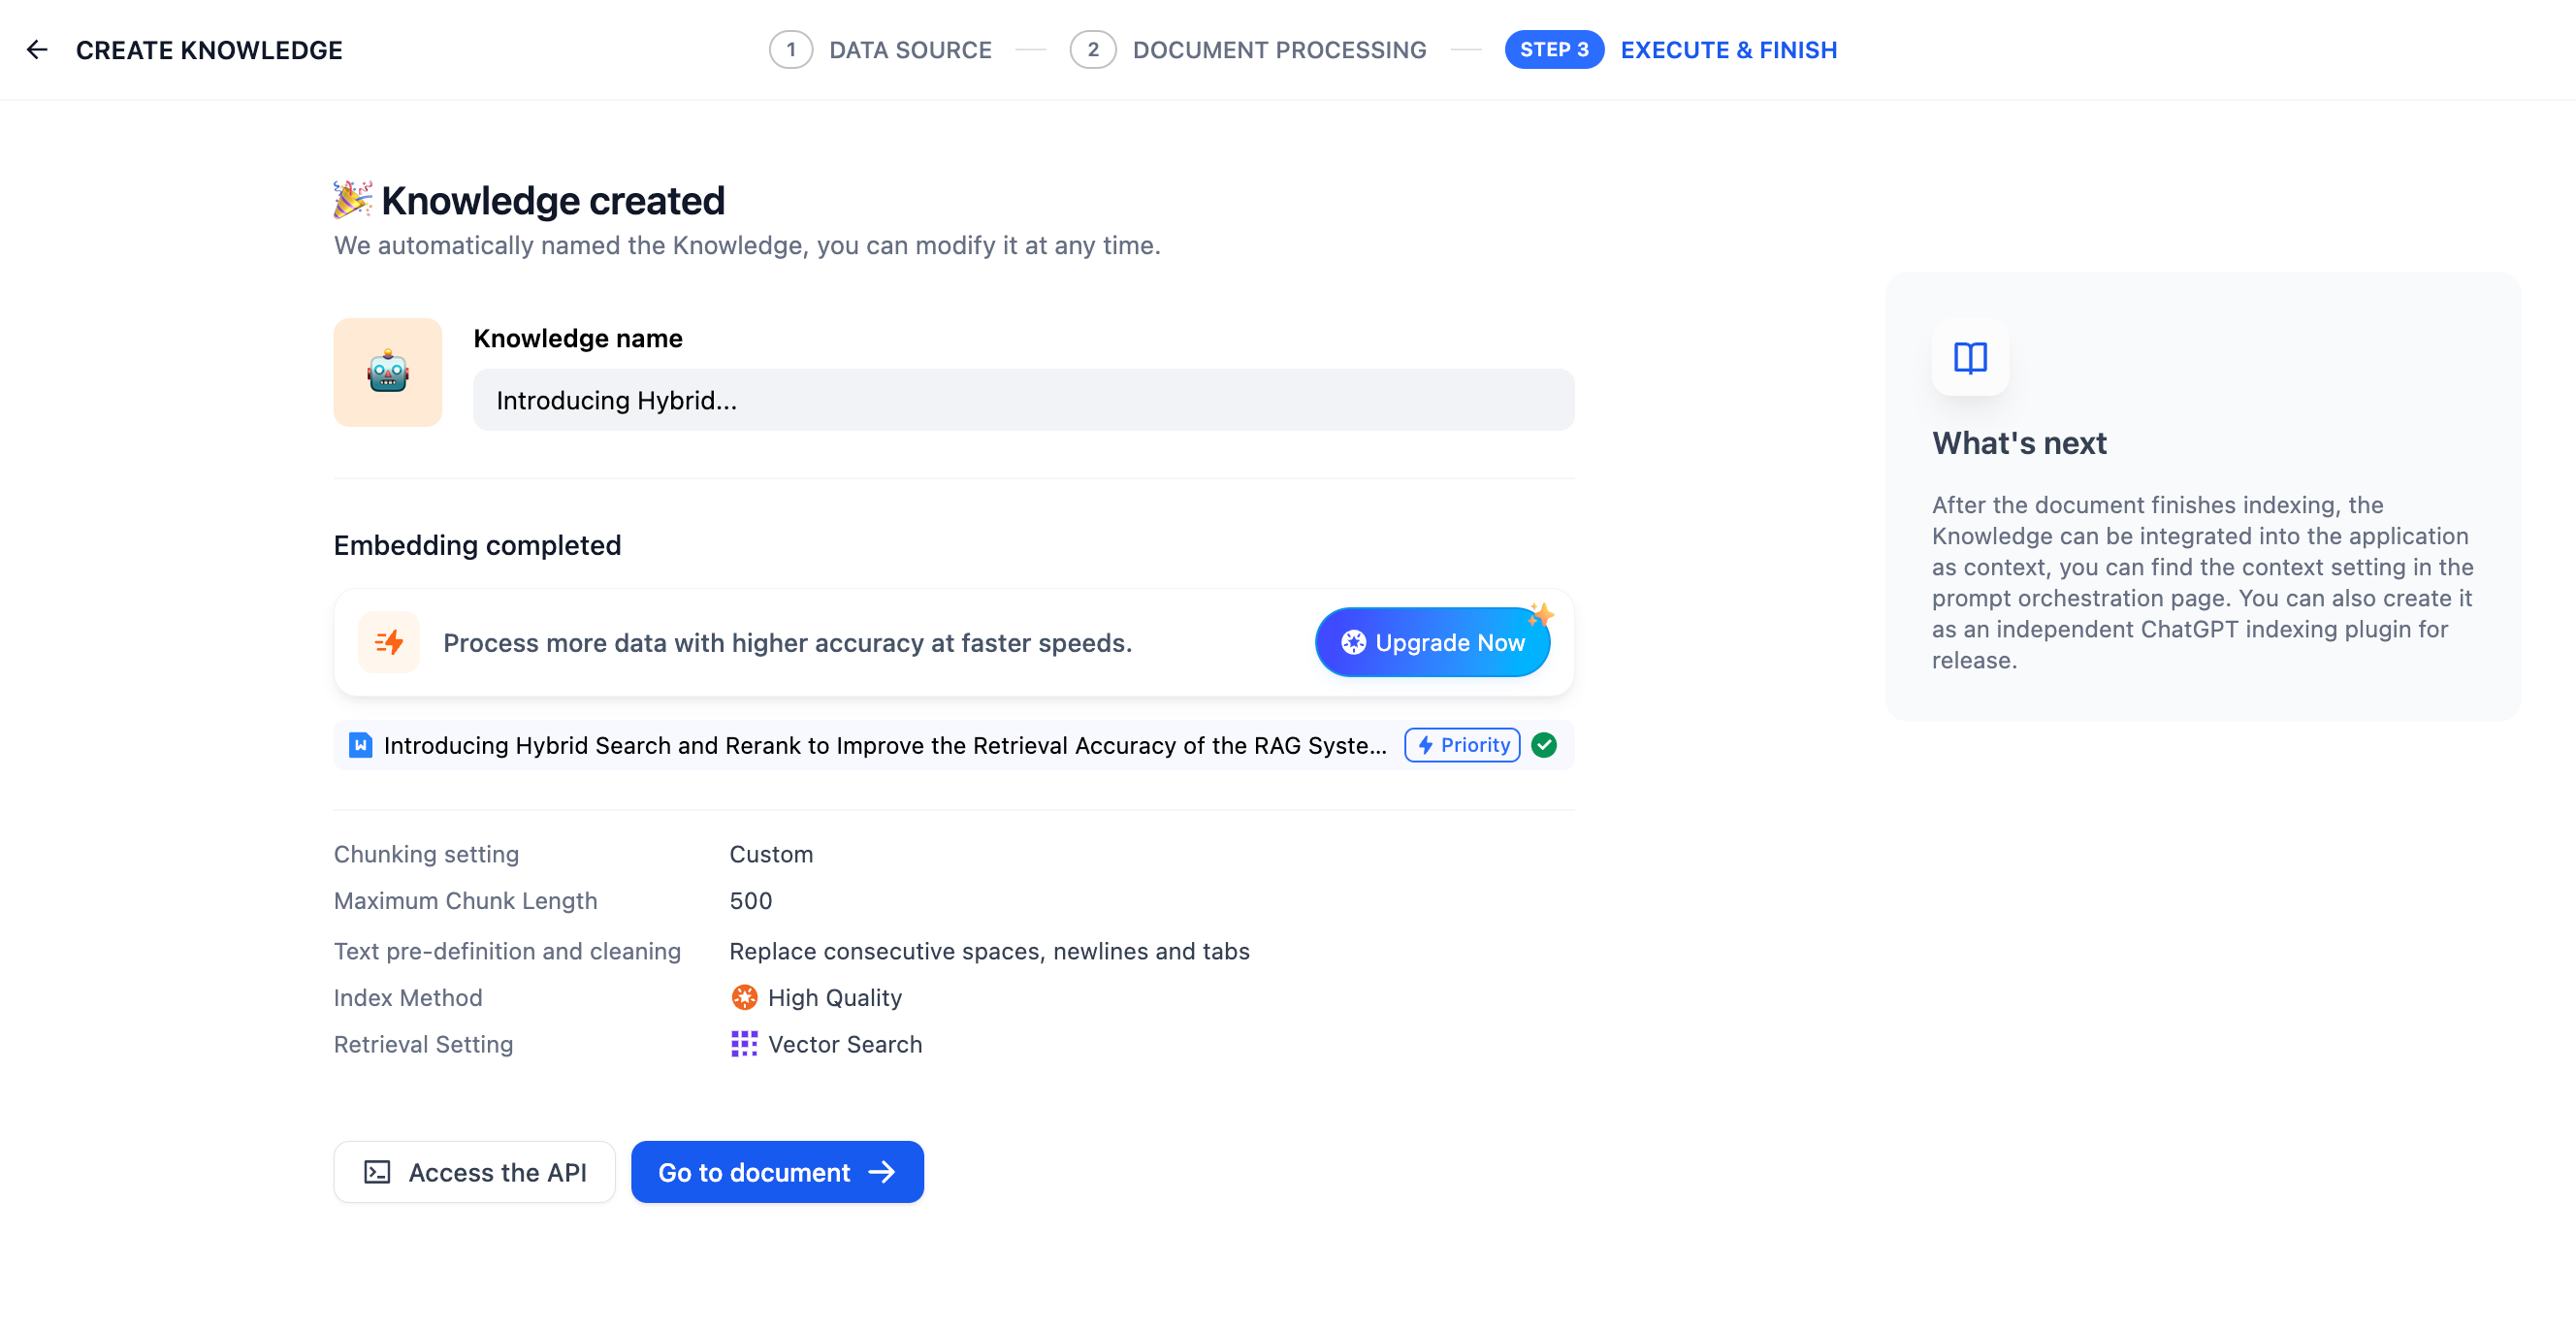
</Frame>
# Specify the Index Method and Retrieval Settings
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods
After selecting the chunking mode, the next step is to define the index method for structured content.
## Select the Index Method
Similar to the search engines use efficient indexing algorithms to match search results most relevant to user queries, the selected index method directly impacts the retrieval efficiency of the LLM and the accuracy of its responses to knowledge base content.
The knowledge base offers two index methods: **High-Quality** and **Economical**, each with different retrieval setting options.
<Tabs>
<Tab title="High Quality">
<Note>
Once a knowledge base is created in the High Quality index method, it cannot switch to Economical later.
</Note>
The High Quality index method uses an embedding model to convert content chunks into vector representations. This process is called embedding.
Think of these vectors as coordinates in a multi-dimensional space—the closer two points are, the more similar their meanings. This allows the system to find relevant information based on semantic similarity, not just exact keyword matches.
<Tip>
To enable cross-modal retrieval—retrieving both text and images based on semantic relevance—select a multimodal embedding model (marked with a **Vision** icon). Images extracted from documents will then be embedded and indexed for retrieval.
Knowledge bases using such embedding models are labeled **Multimodal** on their cards.
<Frame>
<img alt="Multimodal Knowledge Base" />
</Frame>
</Tip>
The High-Quality index method supports three retrieval strategies: vector search, full-text search, or hybrid search. Learn more in [Configure the Retrieval Settings](#configure-the-retrieval-settings).
### Q\&A Mode
When this mode is enabled, the system segments the uploaded text and automatically generates Q\&A pairs for each segment after summarizing its content.
Compared with the common **Q to P** strategy (user questions matched with text paragraphs), the Q\&A mode uses a **Q to Q** strategy (questions matched with questions).
This approach is particularly effective because the text in FAQ documents **is often written in natural language with complete grammatical structures**.
> The **Q to Q** strategy makes the matching between questions and answers clearer and better supports scenarios with high-frequency or highly similar questions.
<Frame>
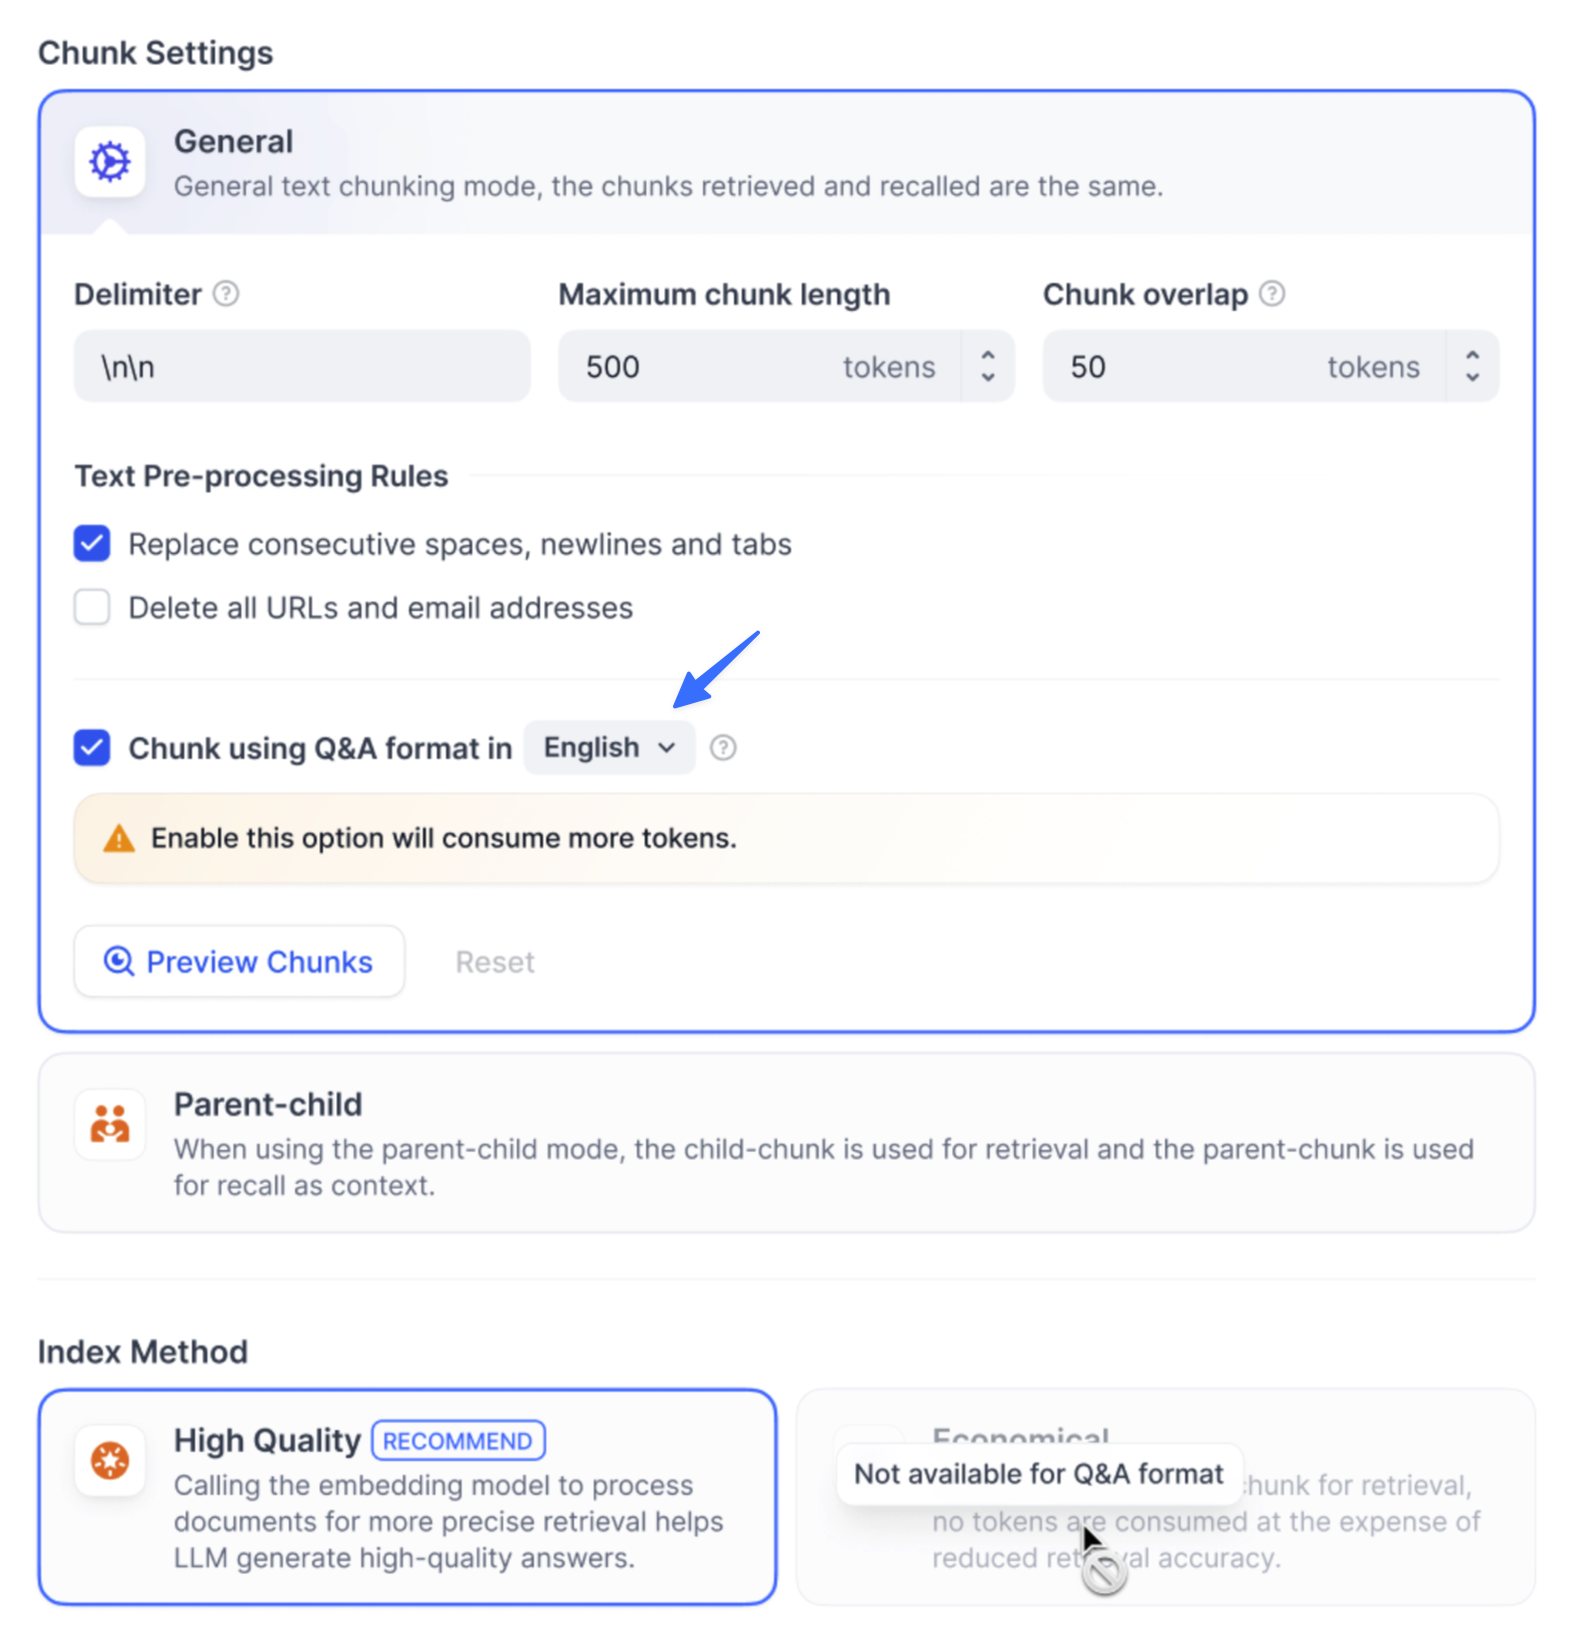
</Frame>
When a user asks a question, the system identifies the most similar question and returns the corresponding chunk as the answer. This approach is more precise, as it directly matches the user’s query, helping them retrieve the exact information they need.
<Frame>
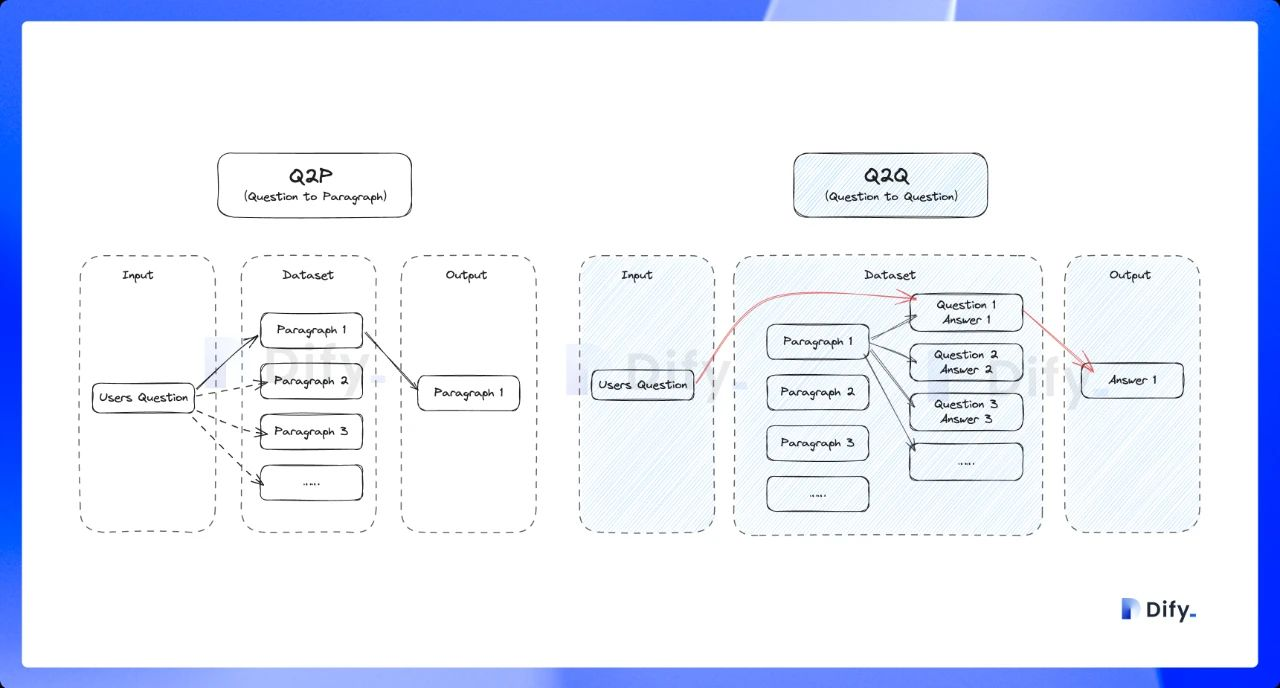
</Frame>
</Tab>
<Tab title="Economical">
Using 10 keywords per chunk for retrieval, no tokens are consumed at the expense of reduced retrieval accuracy. For the retrieved blocks, only the inverted index method is provided to select the most relevant blocks.
If the performance of the economical indexing method does not meet your expectations, you can upgrade to the High-Quality indexing method in the Knowledge settings page.
<Frame>
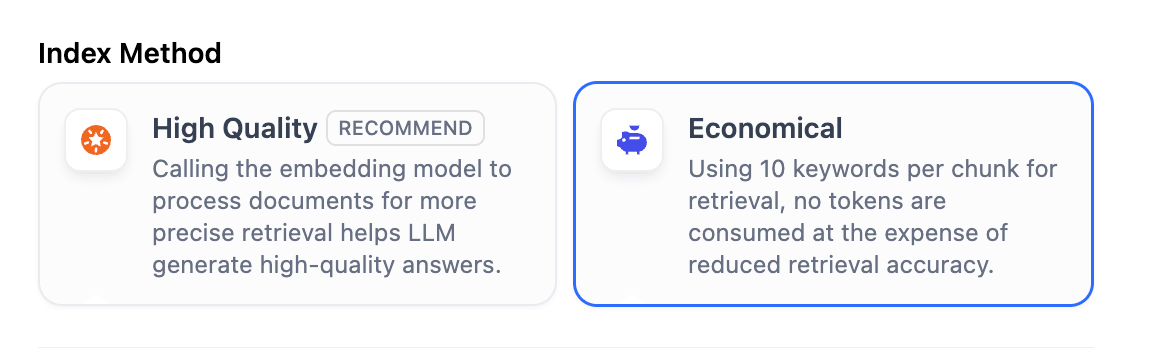
</Frame>
</Tab>
</Tabs>
## Configure the Retrieval Settings
Once the knowledge base receives a user query, it searches existing documents according to preset retrieval methods and extracts highly relevant content chunks. These chunks provide essential context for the LLM, ultimately affecting the accuracy and credibility of its answers.
Common retrieval methods include:
1. Semantic Retrieval based on vector similarity—where text chunks and queries are converted into vectors and matched via similarity scoring.
2. Keyword Matching using an inverted index (a standard search engine technique). Both methods are supported in Dify’s knowledge base.
Both retrieval methods are supported in Dify’s knowledge base. The specific retrieval options available depend on the chosen indexing method.
<Tabs>
<Tab title="High Quality">
**High Quality**
In the **High-Quality** Indexing Method, Dify offers three retrieval settings: **Vector Search, Full-Text Search, and Hybrid Search**.
<Frame>
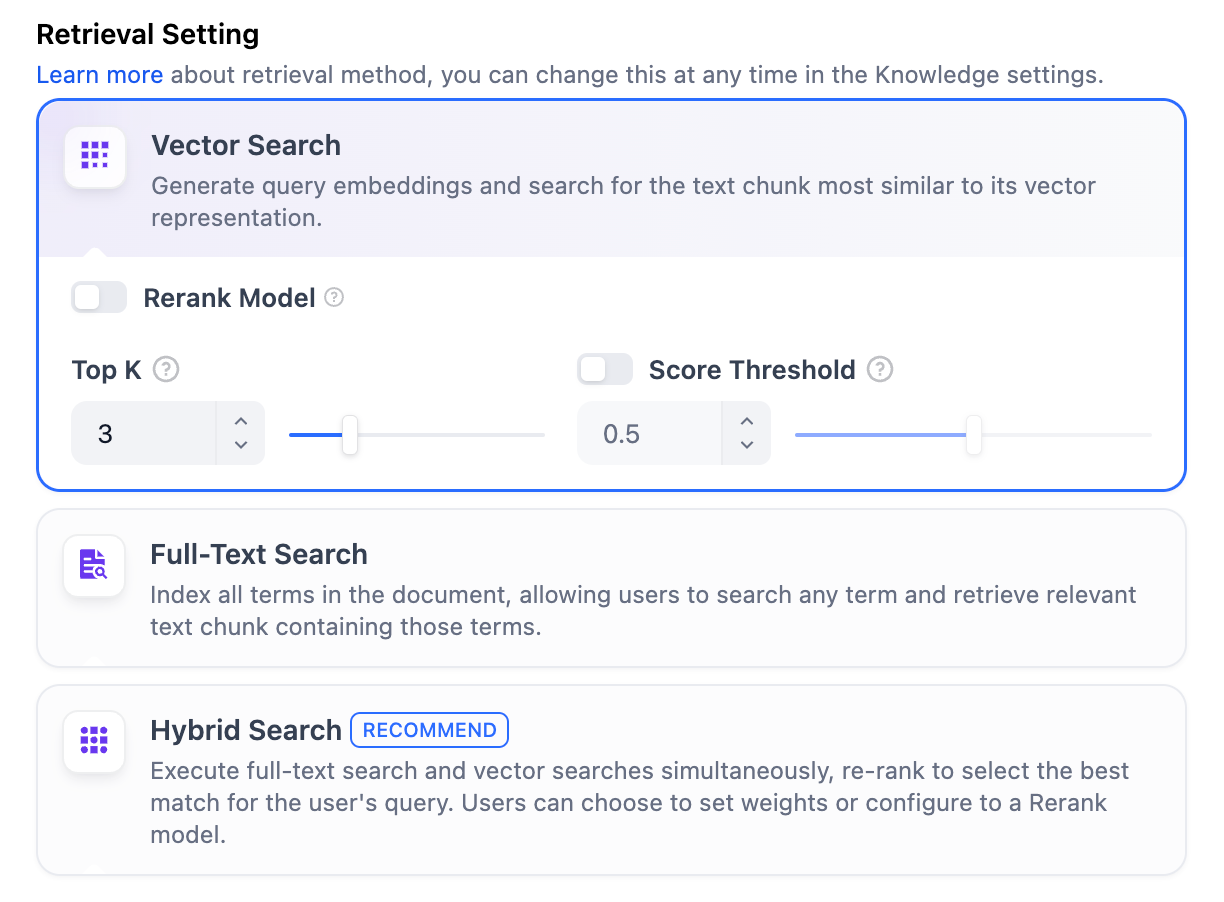
</Frame>
**Vector Search**
**Definition**: Vectorize the user’s question to generate a query vector, then compare it with the corresponding text vectors in the knowledge base to find the nearest chunks.
<Frame>
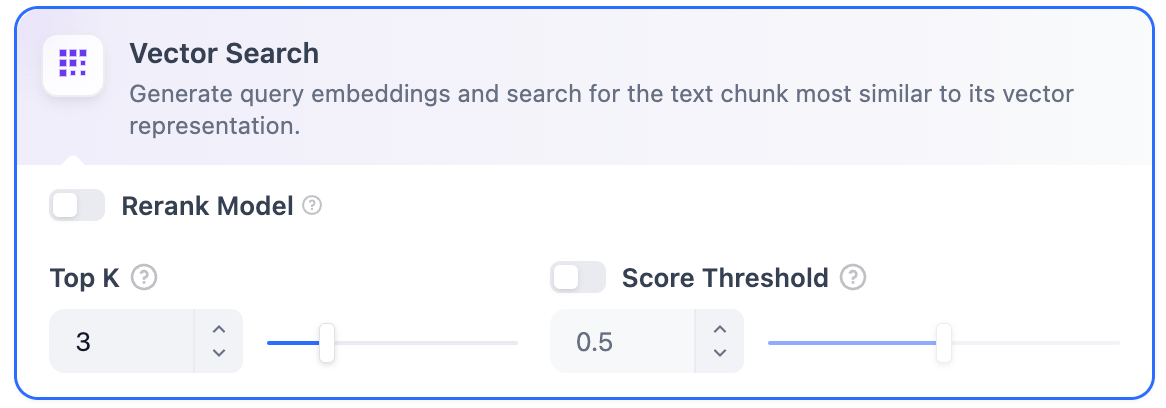
</Frame>
**Vector Search Settings**:
**Rerank Model**: Disabled by default. When enabled, a third-party Rerank model will sort the text chunks returned by Vector Search to optimize results. This helps the LLM access more precise information and improve output quality. Before enabling this option, go to **Integrations** > **Model Provider** and configure the Rerank model's API key.
<Note>
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
</Note>
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
> The TopK and Score configurations are only effective during the Rerank phase. Therefore, to apply either of these settings, it is necessary to add and enable a Rerank model.
**Full-Text Search**
**Definition**: Indexing all terms in the document, allowing users to query any terms and return text fragments containing those terms.
<Frame>
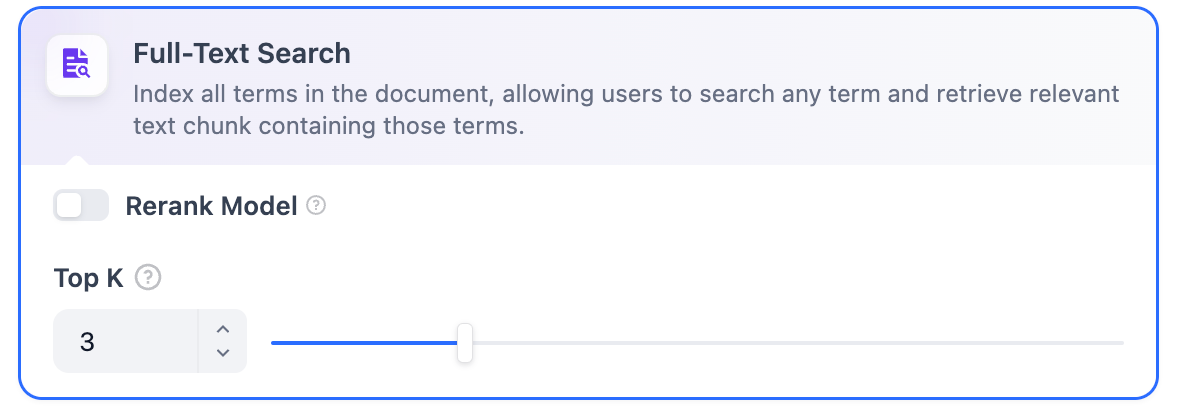
</Frame>
**Rerank Model**: Disabled by default. When enabled, a third-party Rerank model will sort the text chunks returned by Full-Text Search to optimize results. This helps the LLM access more precise information and improve output quality. Before enabling this option, go to **Integrations** > **Model Provider** and configure the Rerank model's API key.
<Note>
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
</Note>
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
> The TopK and Score configurations are only effective during the Rerank phase. Therefore, to apply either of these settings, it is necessary to add and enable a Rerank model.
**Hybrid Search**
**Definition**: This process combines full-text search and vector search, performing both simultaneously. It includes a reordering step to select the best-matching results from both search outcomes based on the user’s query.
<Frame>
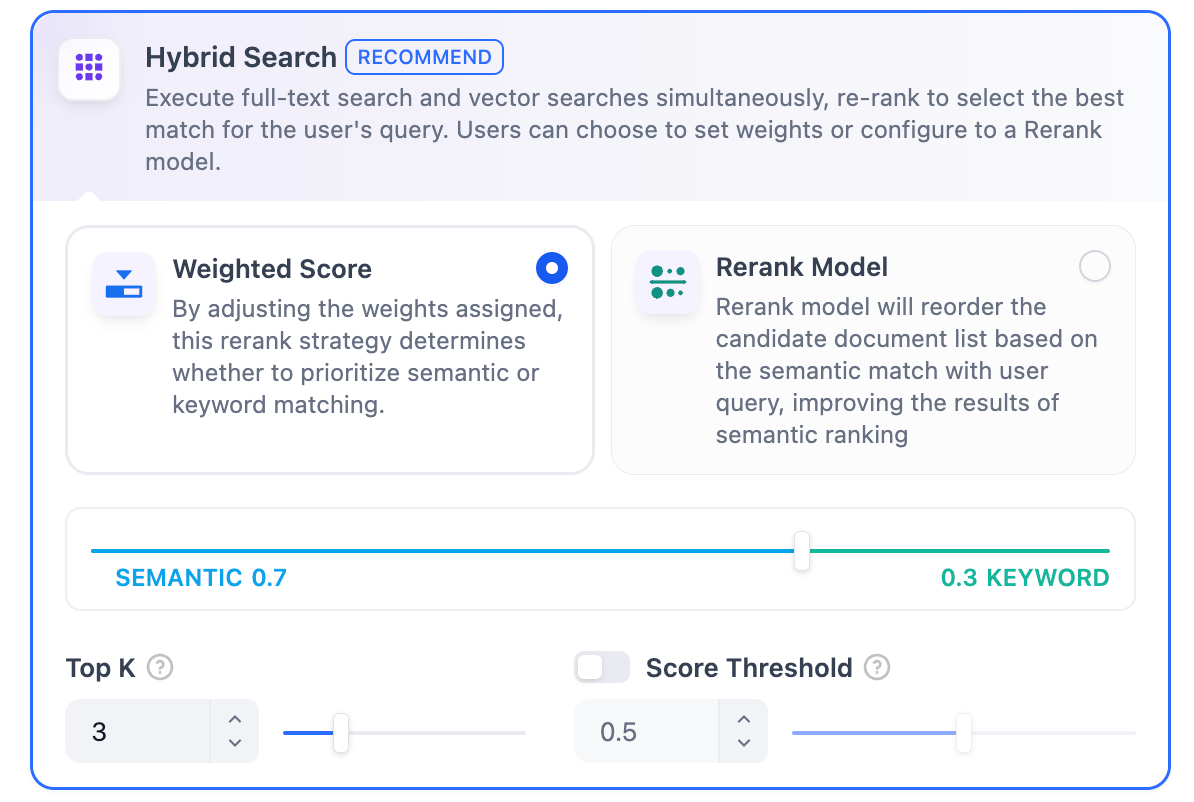
</Frame>
In this mode, you can specify **"Weight settings"** without needing to configure the Rerank model API, or enable **Rerank model** for retrieval.
* **Weight Settings**
This feature enables users to set custom weights for semantic priority and keyword priority. Keyword search refers to performing a full-text search within the knowledge base, while semantic search involves vector search within the knowledge base.
* **Semantic Value of 1**
This activates only the semantic search mode. Utilizing embedding models, even if the exact terms from the query do not appear in the knowledge base, the search can delve deeper by calculating vector distances, thus returning relevant content. Additionally, when dealing with multilingual content, semantic search can capture meaning across different languages, providing more accurate cross-language search results.
* **Keyword Value of 1**
This activates only the keyword search mode. It performs a full match against the input text in the knowledge base, suitable for scenarios where the user knows the exact information or terminology. This approach consumes fewer computational resources and is ideal for quick searches within a large document knowledge base.
* **Custom Keyword and Semantic Weights**
In addition to enabling only semantic search or keyword search, we provide flexible custom weight settings. You can continuously adjust the weights of the two methods to identify the optimal weight ratio that suits your business scenario.
**Rerank Model**
Disabled by default. When enabled, a third-party Rerank model will sort the text chunks returned by Hybrid Search to optimize results. This helps the LLM access more precise information and improve output quality. Before enabling this option, go to **Integrations** > **Model Provider** and configure the Rerank model's API key.
<Note>
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
</Note>
> Enabling this feature will consume tokens from the Rerank model. For more details, refer to the associated model’s pricing page.
The **"Weight Settings"** and **"Rerank Model"** settings support the following options:
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
**Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
</Tab>
<Tab title="Economical">
**Economical**
In **Economical Indexing** mode, only the inverted index approach is available. An inverted index is a data structure designed for fast keyword retrieval within documents, commonly used in online search engines. Inverted indexing supports only the **TopK** setting.
**TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
<p>
<Frame>
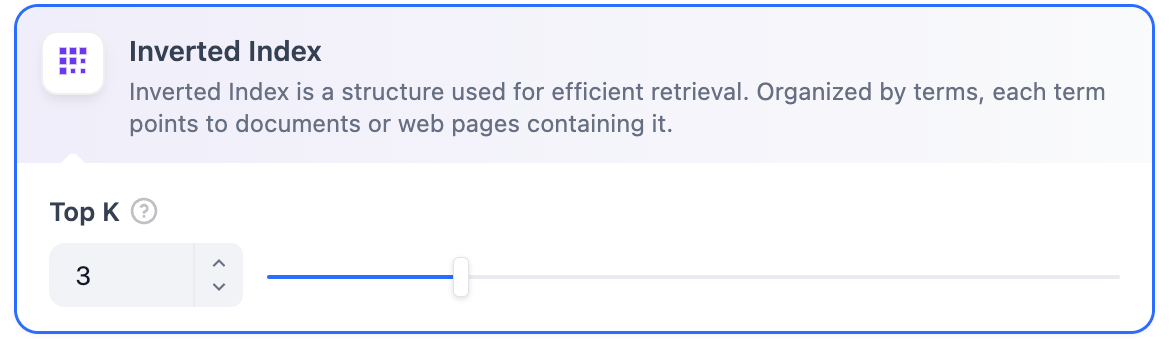
</Frame>
</p>
</Tab>
</Tabs>
### Reference
After specifying the retrieval settings, you can refer to the following documentation to review how keywords match with content chunks in different scenarios.
<Card title="Test Knowledge Retrieval" icon="link" href="/en/self-host/use-dify/knowledge/test-retrieval">
Learn how to test and cite your knowledge base retrieval
</Card>
# External Knowledge API
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/external-knowledge-api
API specification that your external knowledge service must implement to integrate with Dify
This page defines the API contract your external knowledge service must implement for Dify to retrieve content from it. Once your API is ready, see [Connect to External Knowledge Base](/en/self-host/use-dify/knowledge/connect-external-knowledge-base) to register it in Dify.
## Authentication
Dify sends the API Key you configured as a Bearer token in every request:
```text theme={null}
Authorization: Bearer {API_KEY}
```
You define the authentication logic on your side. Dify only passes the key—it does not validate it.
## Request
```text theme={null}
POST {your-endpoint}/retrieval
Content-Type: application/json
Authorization: Bearer {API_KEY}
```
Dify appends `/retrieval` to the endpoint URL you configured. If you registered `https://your-service.com`, Dify sends requests to `https://your-service.com/retrieval`.
### Body
| Property | Required | Type | Description |
| :------------------- | :------- | :----- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `knowledge_id` | Yes | string | The identifier of the knowledge source in your external system. This is the value you entered in the **External Knowledge ID** field when connecting. Use it to route queries to the correct knowledge source. |
| `query` | Yes | string | The user's search query. |
| `retrieval_setting` | Yes | object | Retrieval parameters. See [below](#retrieval_setting). |
| `metadata_condition` | No | object | Metadata filtering conditions. See [below](#metadata_condition). |
#### `retrieval_setting`
| Property | Required | Type | Description |
| :---------------- | :------- | :---- | :--------------------------------------------------------------------------------------------- |
| `top_k` | Yes | int | Maximum number of results to return. |
| `score_threshold` | Yes | float | Minimum similarity score (0-1). When score threshold is disabled in Dify, this value is `0.0`. |
#### `metadata_condition`
<Info>
Dify passes metadata conditions to your API but does not currently provide a UI for users to configure them. This parameter is available for programmatic use only.
</Info>
| Property | Required | Type | Description |
| :----------------- | :------- | :------------- | :----------------------------- |
| `logical_operator` | No | string | `and` or `or`. Default: `and`. |
| `conditions` | Yes | array\[object] | List of filter conditions. |
Each object in `conditions`:
| Property | Required | Type | Description |
| :-------------------- | :------- | :-------------------------------- | :-------------------------------------------------------- |
| `name` | Yes | string | Metadata field name to filter on. |
| `comparison_operator` | Yes | string | Comparison operator. See supported values below. |
| `value` | No | string, number, or array\[string] | Comparison value. Omit when using `empty` or `not empty`. |
<Accordion title="Supported Comparison Operators">
| Operator | Description |
| :------------- | :--------------------------------- |
| `contains` | Contains a value |
| `not contains` | Does not contain a value |
| `start with` | Starts with a value |
| `end with` | Ends with a value |
| `is` | Equals a value |
| `is not` | Does not equal a value |
| `in` | Matches any value in a list |
| `not in` | Does not match any value in a list |
| `empty` | Is empty |
| `not empty` | Is not empty |
| `=` | Equals (numeric) |
| `≠` | Not equal (numeric) |
| `>` | Greater than |
| `<` | Less than |
| `≥` | Greater than or equal to |
| `≤` | Less than or equal to |
| `before` | Before a date |
| `after` | After a date |
</Accordion>
### Example Request
```json theme={null}
{
"knowledge_id": "your-knowledge-id",
"query": "What is Dify?",
"retrieval_setting": {
"top_k": 3,
"score_threshold": 0.5
}
}
```
## Response
Return HTTP 200 with a JSON body containing a `records` array. If no results match the query, return an empty array: `{"records": []}`.
### `records`
| Property | Type | Description |
| :--------- | :----- | :----------------------------------------------------------------------------- |
| `content` | string | The retrieved text chunk. Dify uses this as the context passed to the LLM. |
| `score` | float | Similarity score (0–1). Used for score threshold filtering and result ranking. |
| `title` | string | Source document title. |
| `metadata` | object | Arbitrary key-value pairs preserved by Dify. |
Dify does not reject records with missing fields, but omitting `content` or `score` will produce incomplete or unranked results.
<Warning>
If you include `metadata` in a record, it must be an object (`{}`), not `null`. A `null` metadata value causes errors in Dify's retrieval pipeline.
</Warning>
### Example Response
```json theme={null}
{
"records": [
{
"content": "This is the document for external knowledge.",
"score": 0.98,
"title": "knowledge.txt",
"metadata": {
"path": "s3://dify/knowledge.txt",
"description": "dify knowledge document"
}
},
{
"content": "The Innovation Engine for GenAI Applications",
"score": 0.66,
"title": "introduce.txt",
"metadata": {}
}
]
}
```
## Error Handling
Dify checks the HTTP status code of your response. A non-200 status raises an error that surfaces to the user.
You can optionally return structured error information in JSON:
| Property | Type | Description |
| :----------- | :----- | :------------------------------------------ |
| `error_code` | int | An application-level error code you define. |
| `error_msg` | string | A human-readable error description. |
The following are suggested error codes. These are conventions, not enforced by Dify:
| Code | Suggested Usage |
| :--- | :---------------------------------- |
| 1001 | Invalid Authorization header format |
| 1002 | Authorization failed |
| 2001 | Knowledge base not found |
### Example Error Response
```json theme={null}
{
"error_code": 1002,
"error_msg": "Authorization failed. Please check your API key."
}
```
# Integrate Knowledge within Apps
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/integrate-knowledge-within-application
### Create an Application Integrated with Knowledge Base
A **"Knowledge Base"** can be used as an external information source to provide precise answers to user questions via LLM. You can associate an existing knowledge base with any [application type](/en/learn/key-concepts#dify-app) in Dify.
Taking a chat assistant as an example, the process is as follows:
1. Go to **Knowledge**, create a **ready-to-use knowledge base**, and upload your file
2. Go to **Studio**, create an application, and select **Chatbot**
3. Enter **Context**, click **Add**, and select one of the knowledge bases you created
4. Use **Metadata Filtering** to refine document search in your knowledge base
5. In **Context Settings -- Retrieval Setting**, configure the **Retrieval Setting**
6. Enable **Citation and Attribution** in **Add Features**
7. In **Debug and Preview**, input user questions related to the knowledge base for debugging
8. After debugging, click **Publish** button to make an AI application based on your own knowledge!
### Connect Knowledge and Set Retrieval Mode
In applications that utilize multiple knowledge bases, it is essential to configure the retrieval mode to enhance the precision of retrieved content. To set the retrieval mode for the knowledge bases, navigate to **Context -- Retrieval Settings -- Rerank Setting**.
#### Retrieval Setting
The retriever scans all knowledge bases linked to the application for text content relevant to the user's question. The results are then consolidated. Below is the technical flowchart for the Multi-path Retrieval mode:
<Frame>
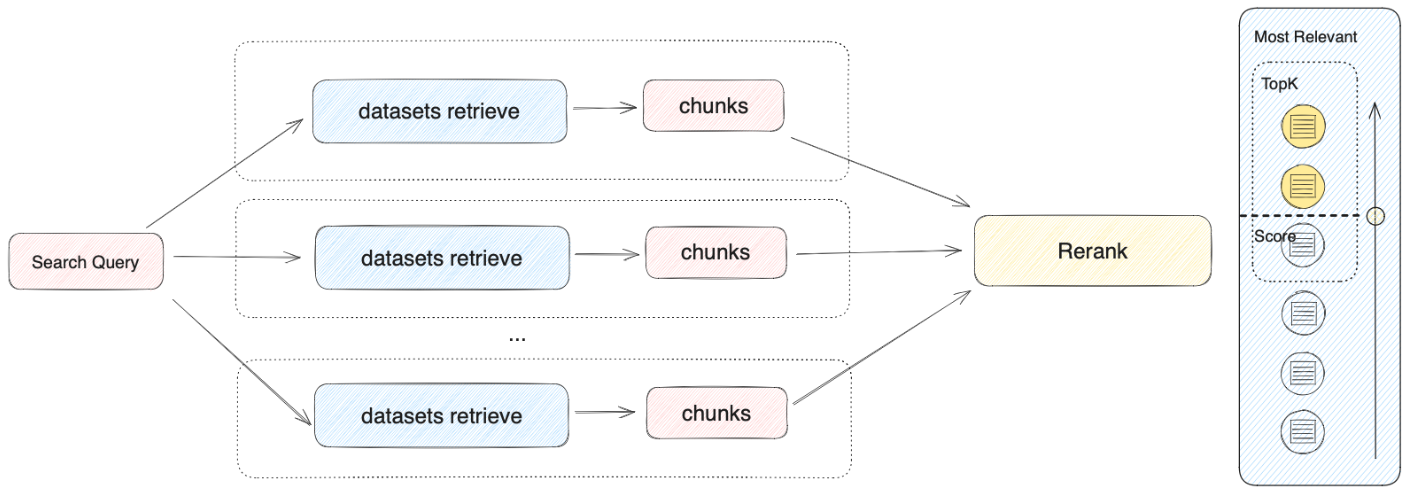
</Frame>
This method simultaneously queries all knowledge bases connected in **"Context"**, seeking relevant text chucks across multiple knowledge bases, collecting all content that aligns with the user's question, and ultimately applying the Rerank strategy to identify the most appropriate content to respond to the user. This retrieval approach offers more comprehensive and accurate results by leveraging multiple knowledge bases simultaneously.
<Frame>
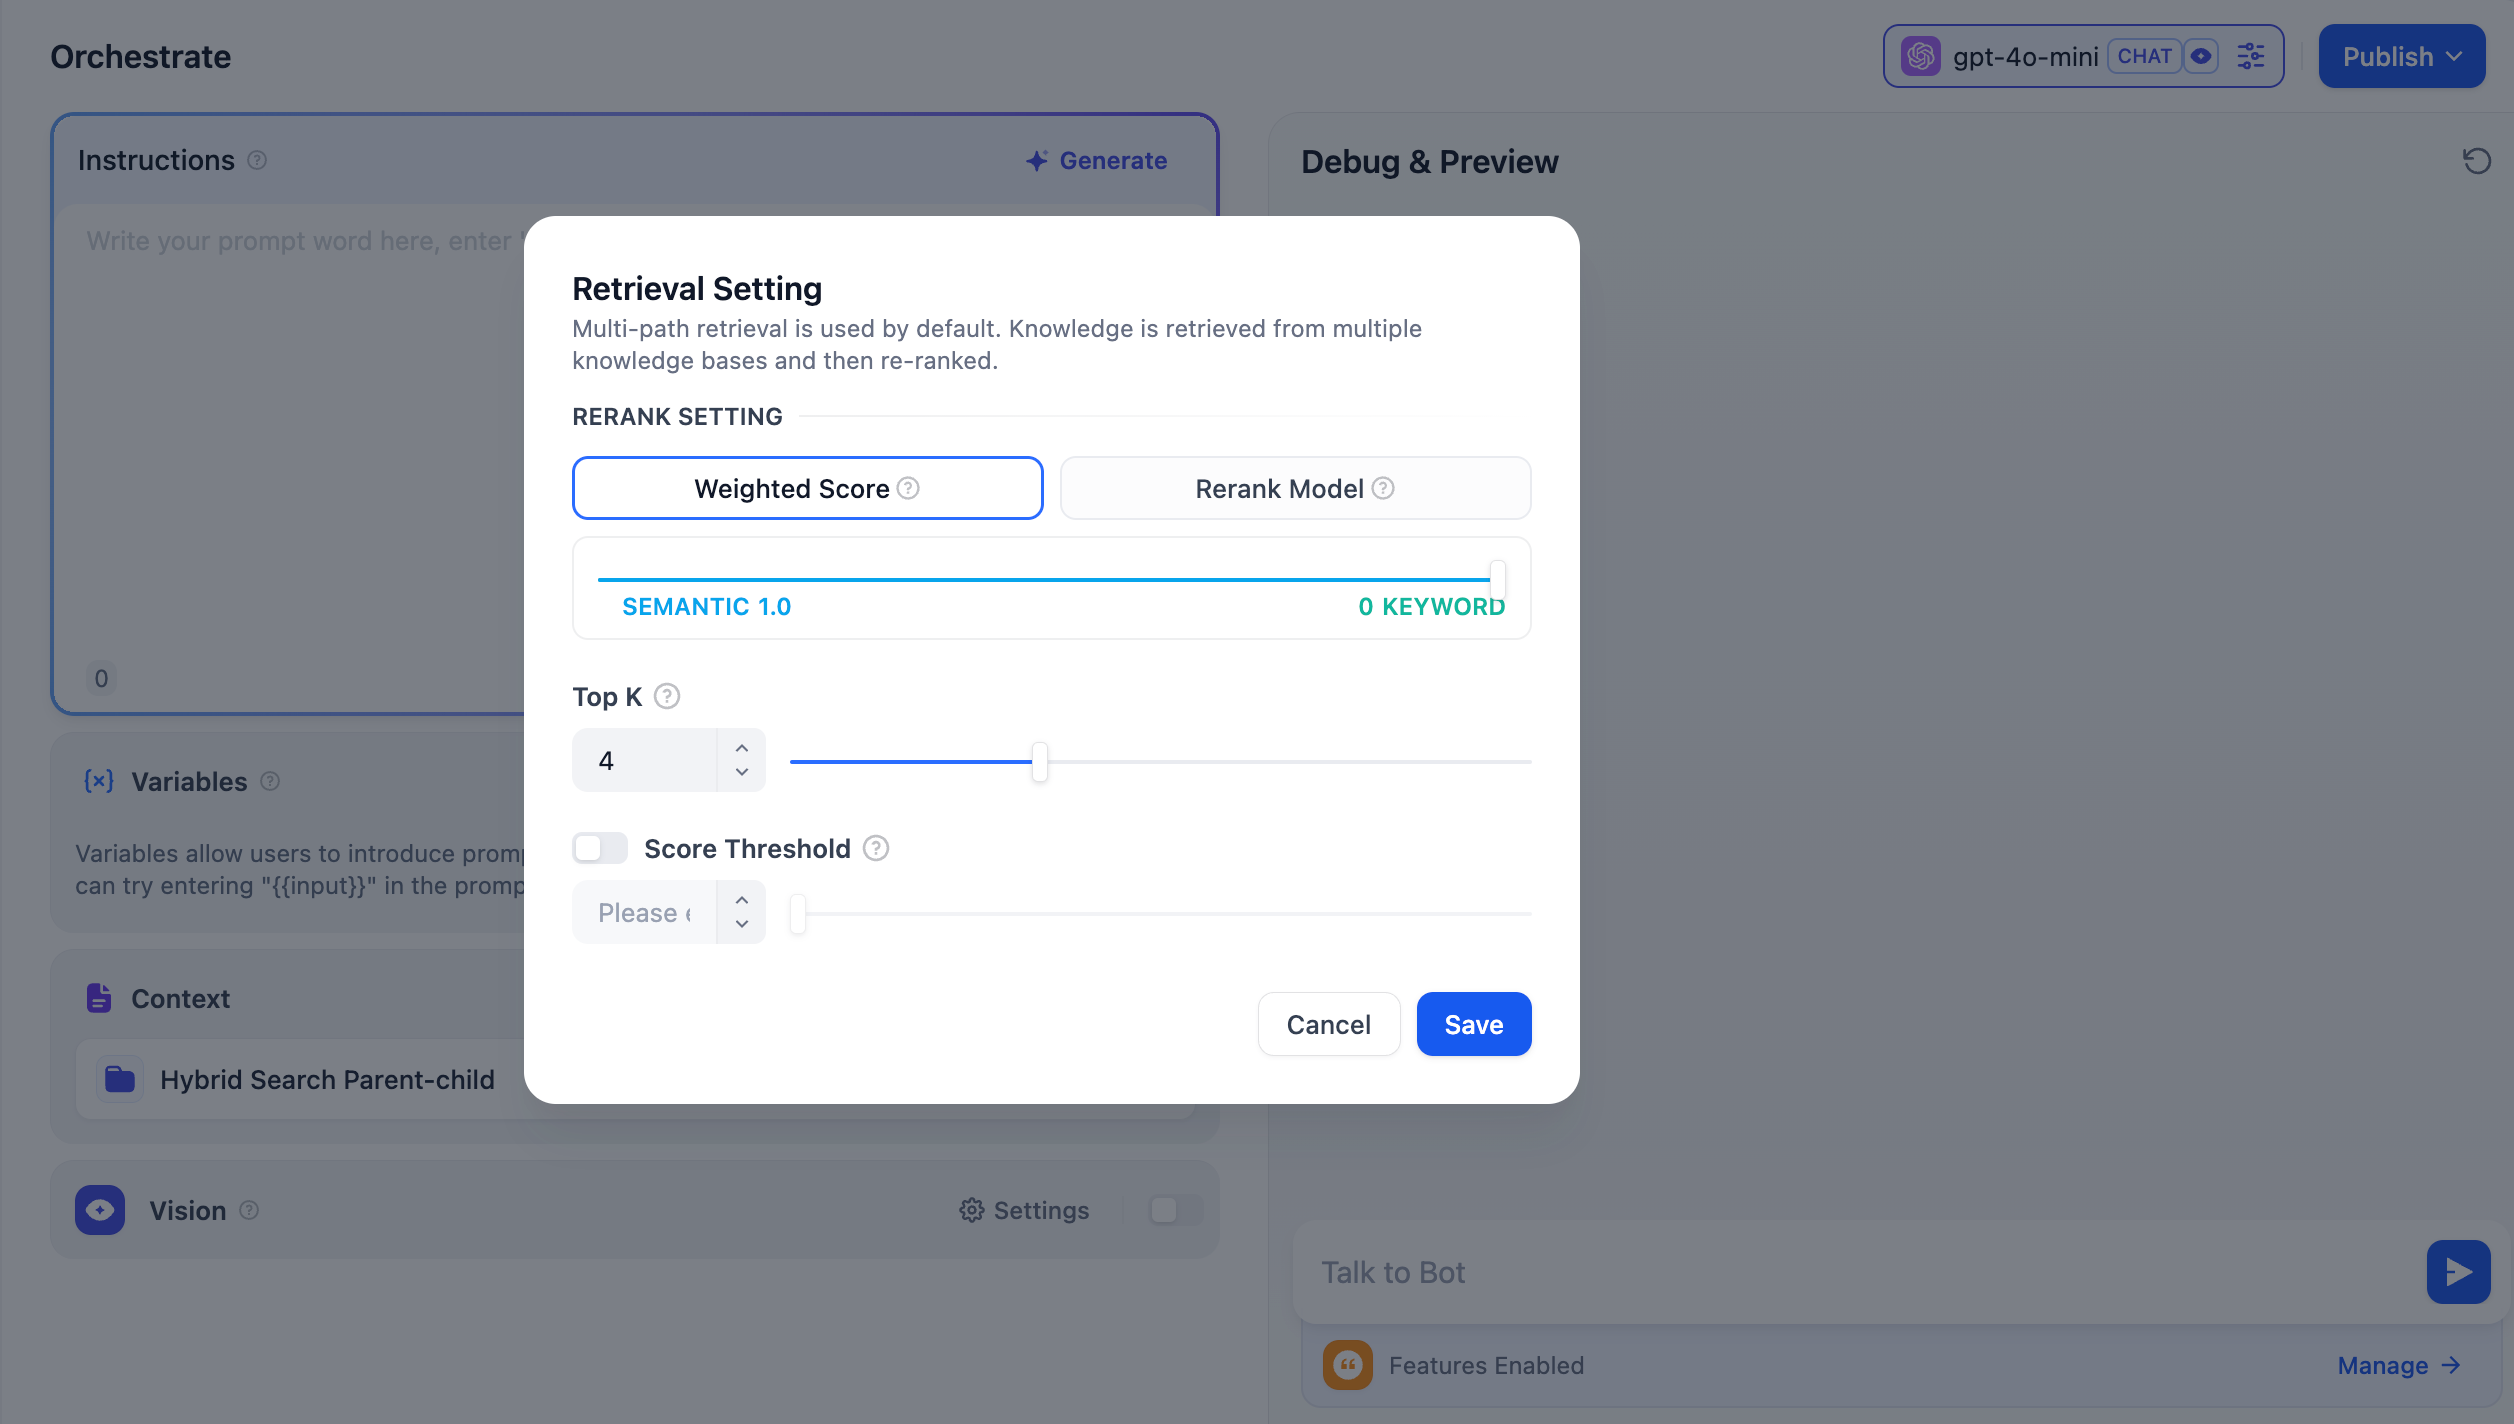
</Frame>
For instance, in application A, with three knowledge bases K1, K2, and K3. When a user send a question, multiple relevant pieces of content will be retrieved and combined from these knowledge bases. To ensure the most pertinent content is identified, the Rerank strategy is employed to find the content that best relates to the user's query, enhancing the precision and reliability of the results.
In practical Q\&A scenarios, the sources of content and retrieval methods for each knowledge base may differ. To manage the mixed content returned from retrieval, the Rerank strategy acts as a refined sorting mechanism. It ensures that the candidate content aligns well with the user's question, optimizing the ranking of results across multiple knowledge bases to identify the most suitable content, thereby improving answer quality and overall user experience.
Considering the costs associated with using Rerank and the needs of the business, the multi-path retrieval mode provides two Rerank settings:
**Weighted Score**
This setting uses internal scoring mechanisms and does not require an external Rerank model, thus **avoiding any additional processing costs**. You can select the most appropriate content matching strategy by adjusting the weight ratio sliders for semantics or keywords.
* **Semantic Value of 1**
This mode activates semantic retrieval only. By utilizing the Embedding model, the search depth can be enhanced even if the exact words from the query do not appear in the knowledge base, as it calculates vector distances to return the relevant content. Furthermore, when dealing with multilingual content, semantic retrieval can capture meanings across different languages, yielding more accurate cross-language search results.
* **Keyword Value of 1**
This mode activates keyword retrieval only. It matches the user's input text against the full text of the knowledge base, making it ideal for scenarios where the user knows the exact information or terminology. This method is resource-efficient, making it suitable for quickly retrieving information from large document repositories.
* **Custom Keyword and Semantic Weights**
In addition to enabling only semantic or keyword retrieval modes, we offer flexible custom Weight Score. You can determine the best weight ratio for your business scenario by continuously adjusting the weights of both.
**Rerank Model**
The Rerank model is an external scoring system that calculates the similarity score between the user's question and each candidate document provided, improving the results of semantic ranking and returning a list of documents sorted by similarity score from high to low.
While this method incurs some additional costs, it is more adept at handling complex knowledge base content, such as content that combines semantic queries and keyword matches, or cases involving multilingual returned content.
Dify currently supports multiple Rerank models. To use external Rerank models, you'll need to provide an API Key. Enter the API Key for the Rerank model (such as Cohere, Jina AI, etc.) on the "Model Provider" page.
<Frame>
</Frame>
**Adjustable Parameters**
* **TopK**: Determines how many text chunks, deemed most similar to the user’s query, are retrieved. It also automatically adjusts the number of chunks based on the chosen model’s context window. The default value is **3**, and higher numbers will recall more text chunks.
* **Score Threshold**: Sets the minimum similarity score required for a chunk to be retrieved. Only chunks exceeding this score are retrieved. The default value is **0.5**. Higher thresholds demand greater similarity and thus result in fewer chunks being retrieved.
### Metadata Filtering
#### Chatflow/Workflow
The **Knowledge Retrieval** node allows you to filter documents using metadata fields.
#### Steps
1. Select Filter Mode:
* **Disabled (Default)**: No metadata filtering.
* **Automatic**: Filters auto-configure from query variables in the **Knowledge Retrieval** node.
> Note: Automatic Mode requires model selection for document retrieval.
<Frame>
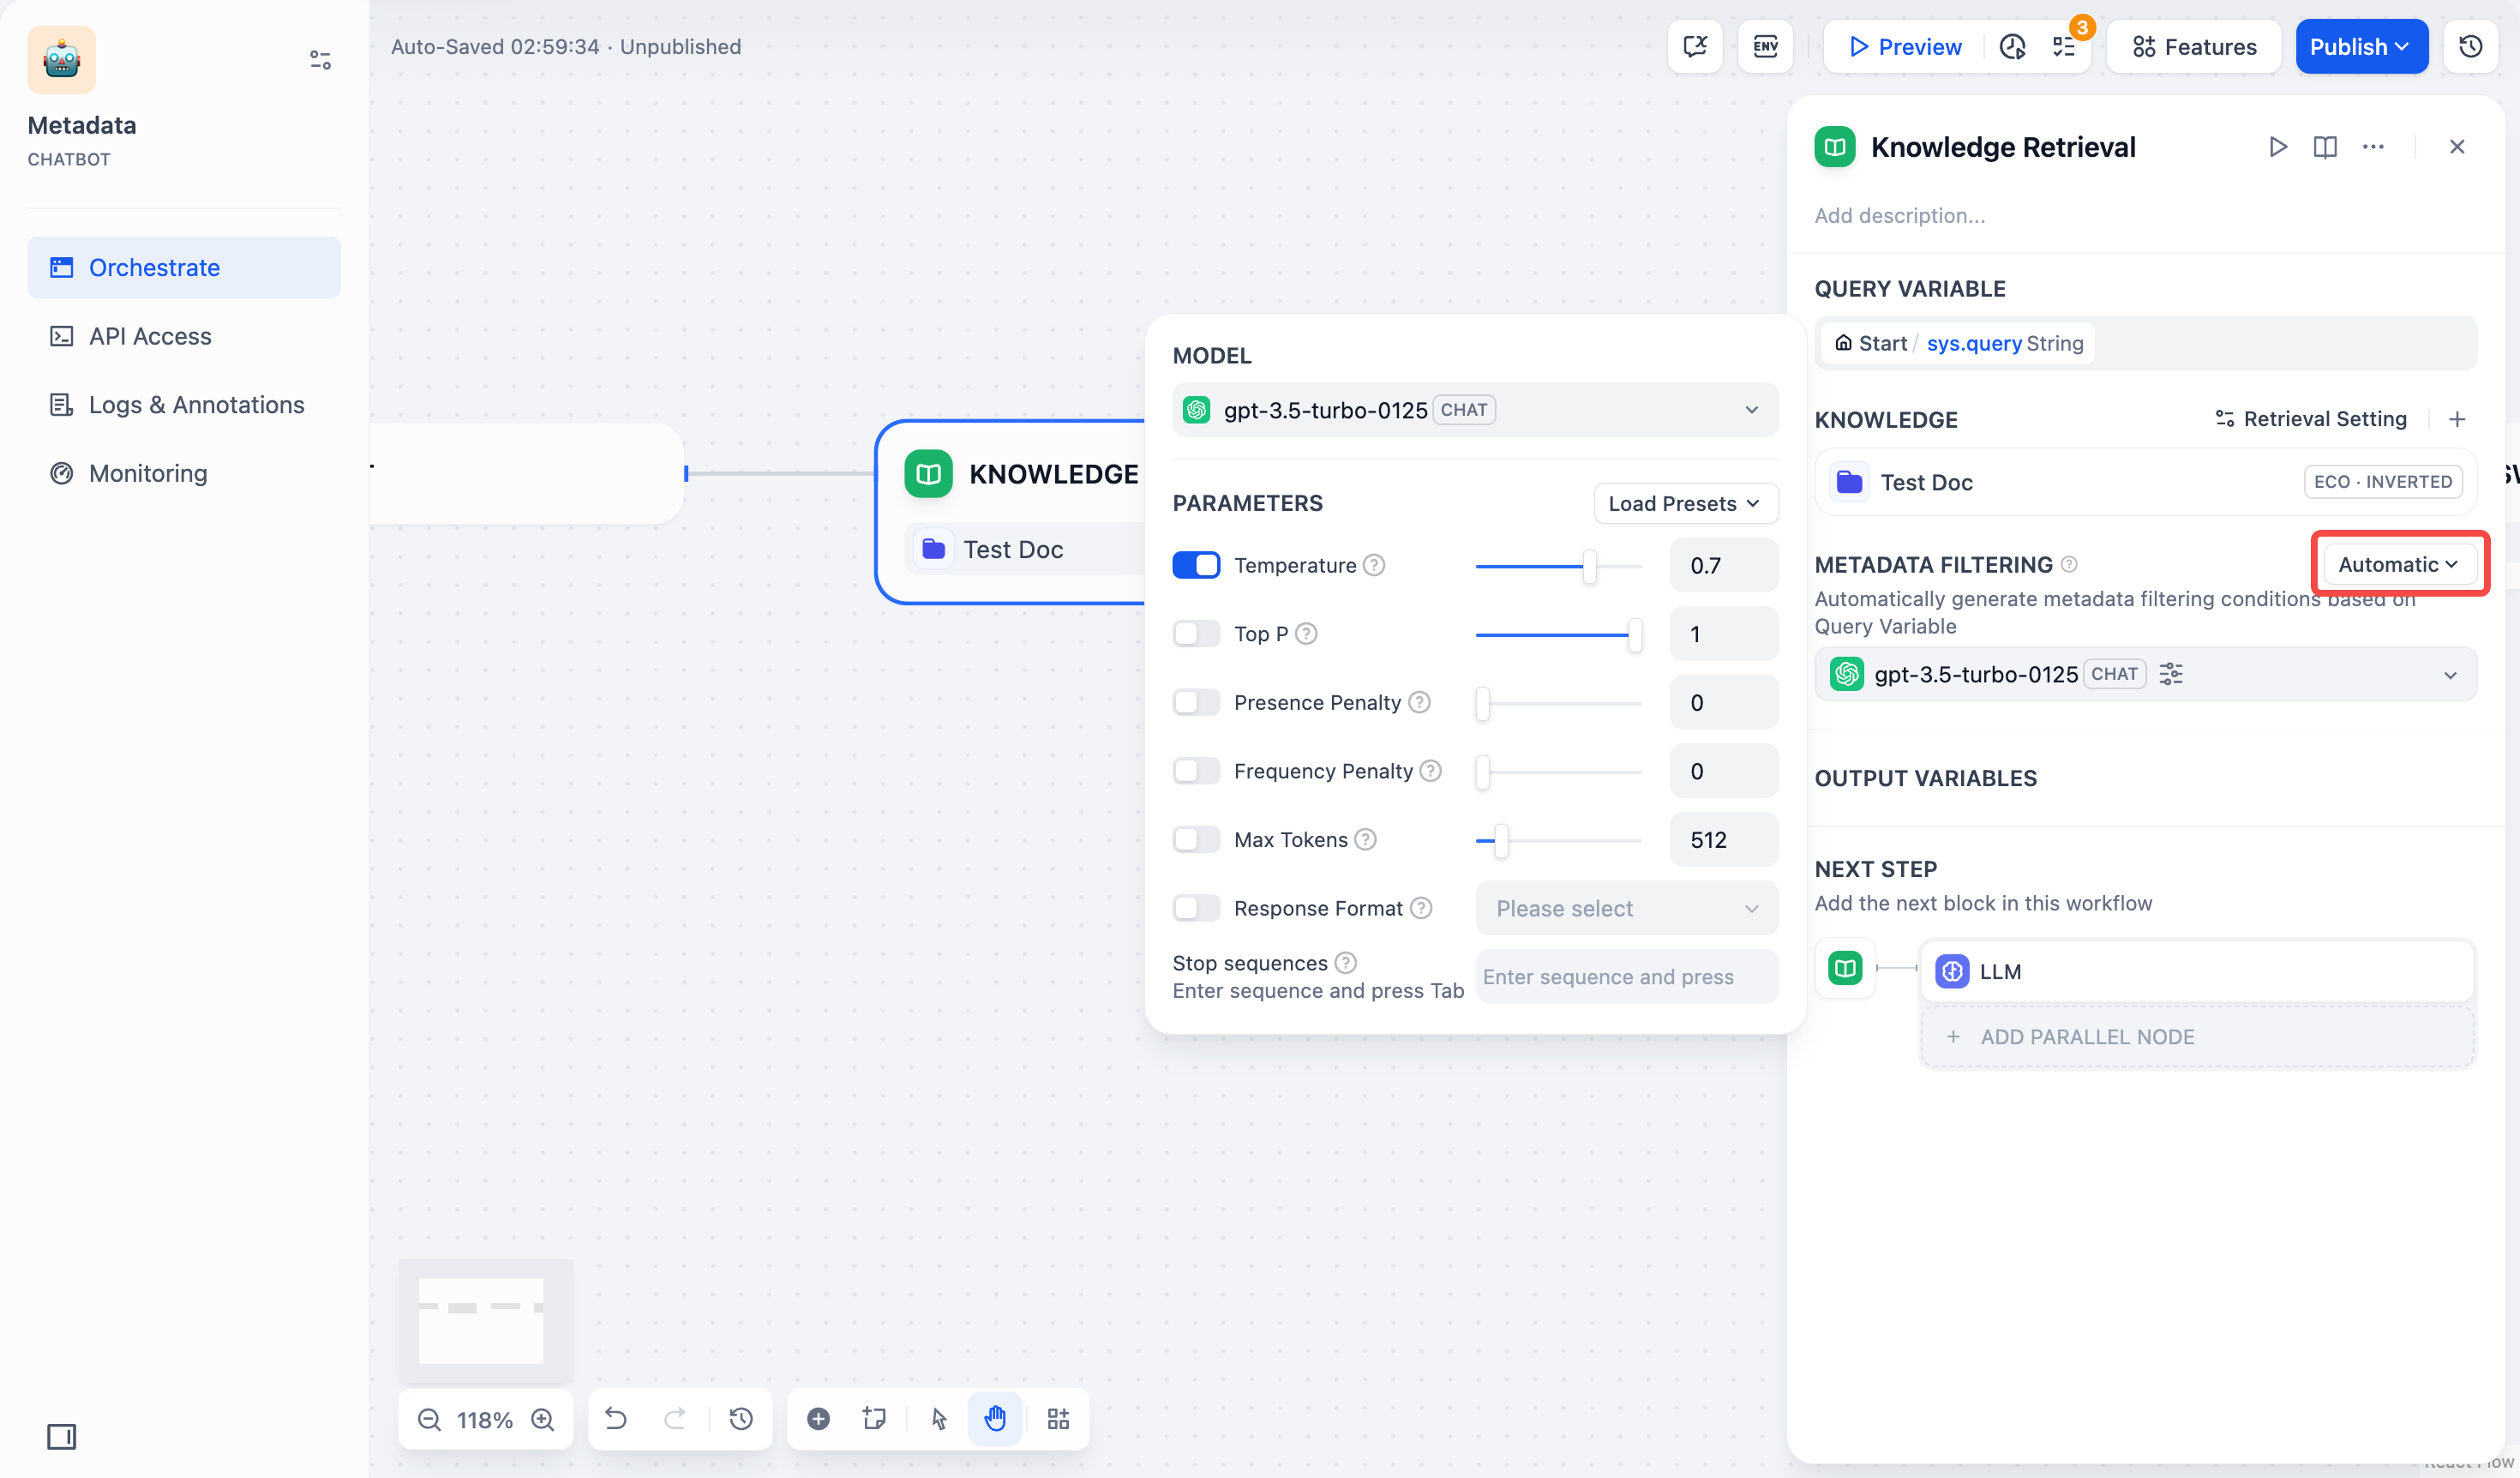
</Frame>
* **Manual**: Configure filters manually.
<Frame>
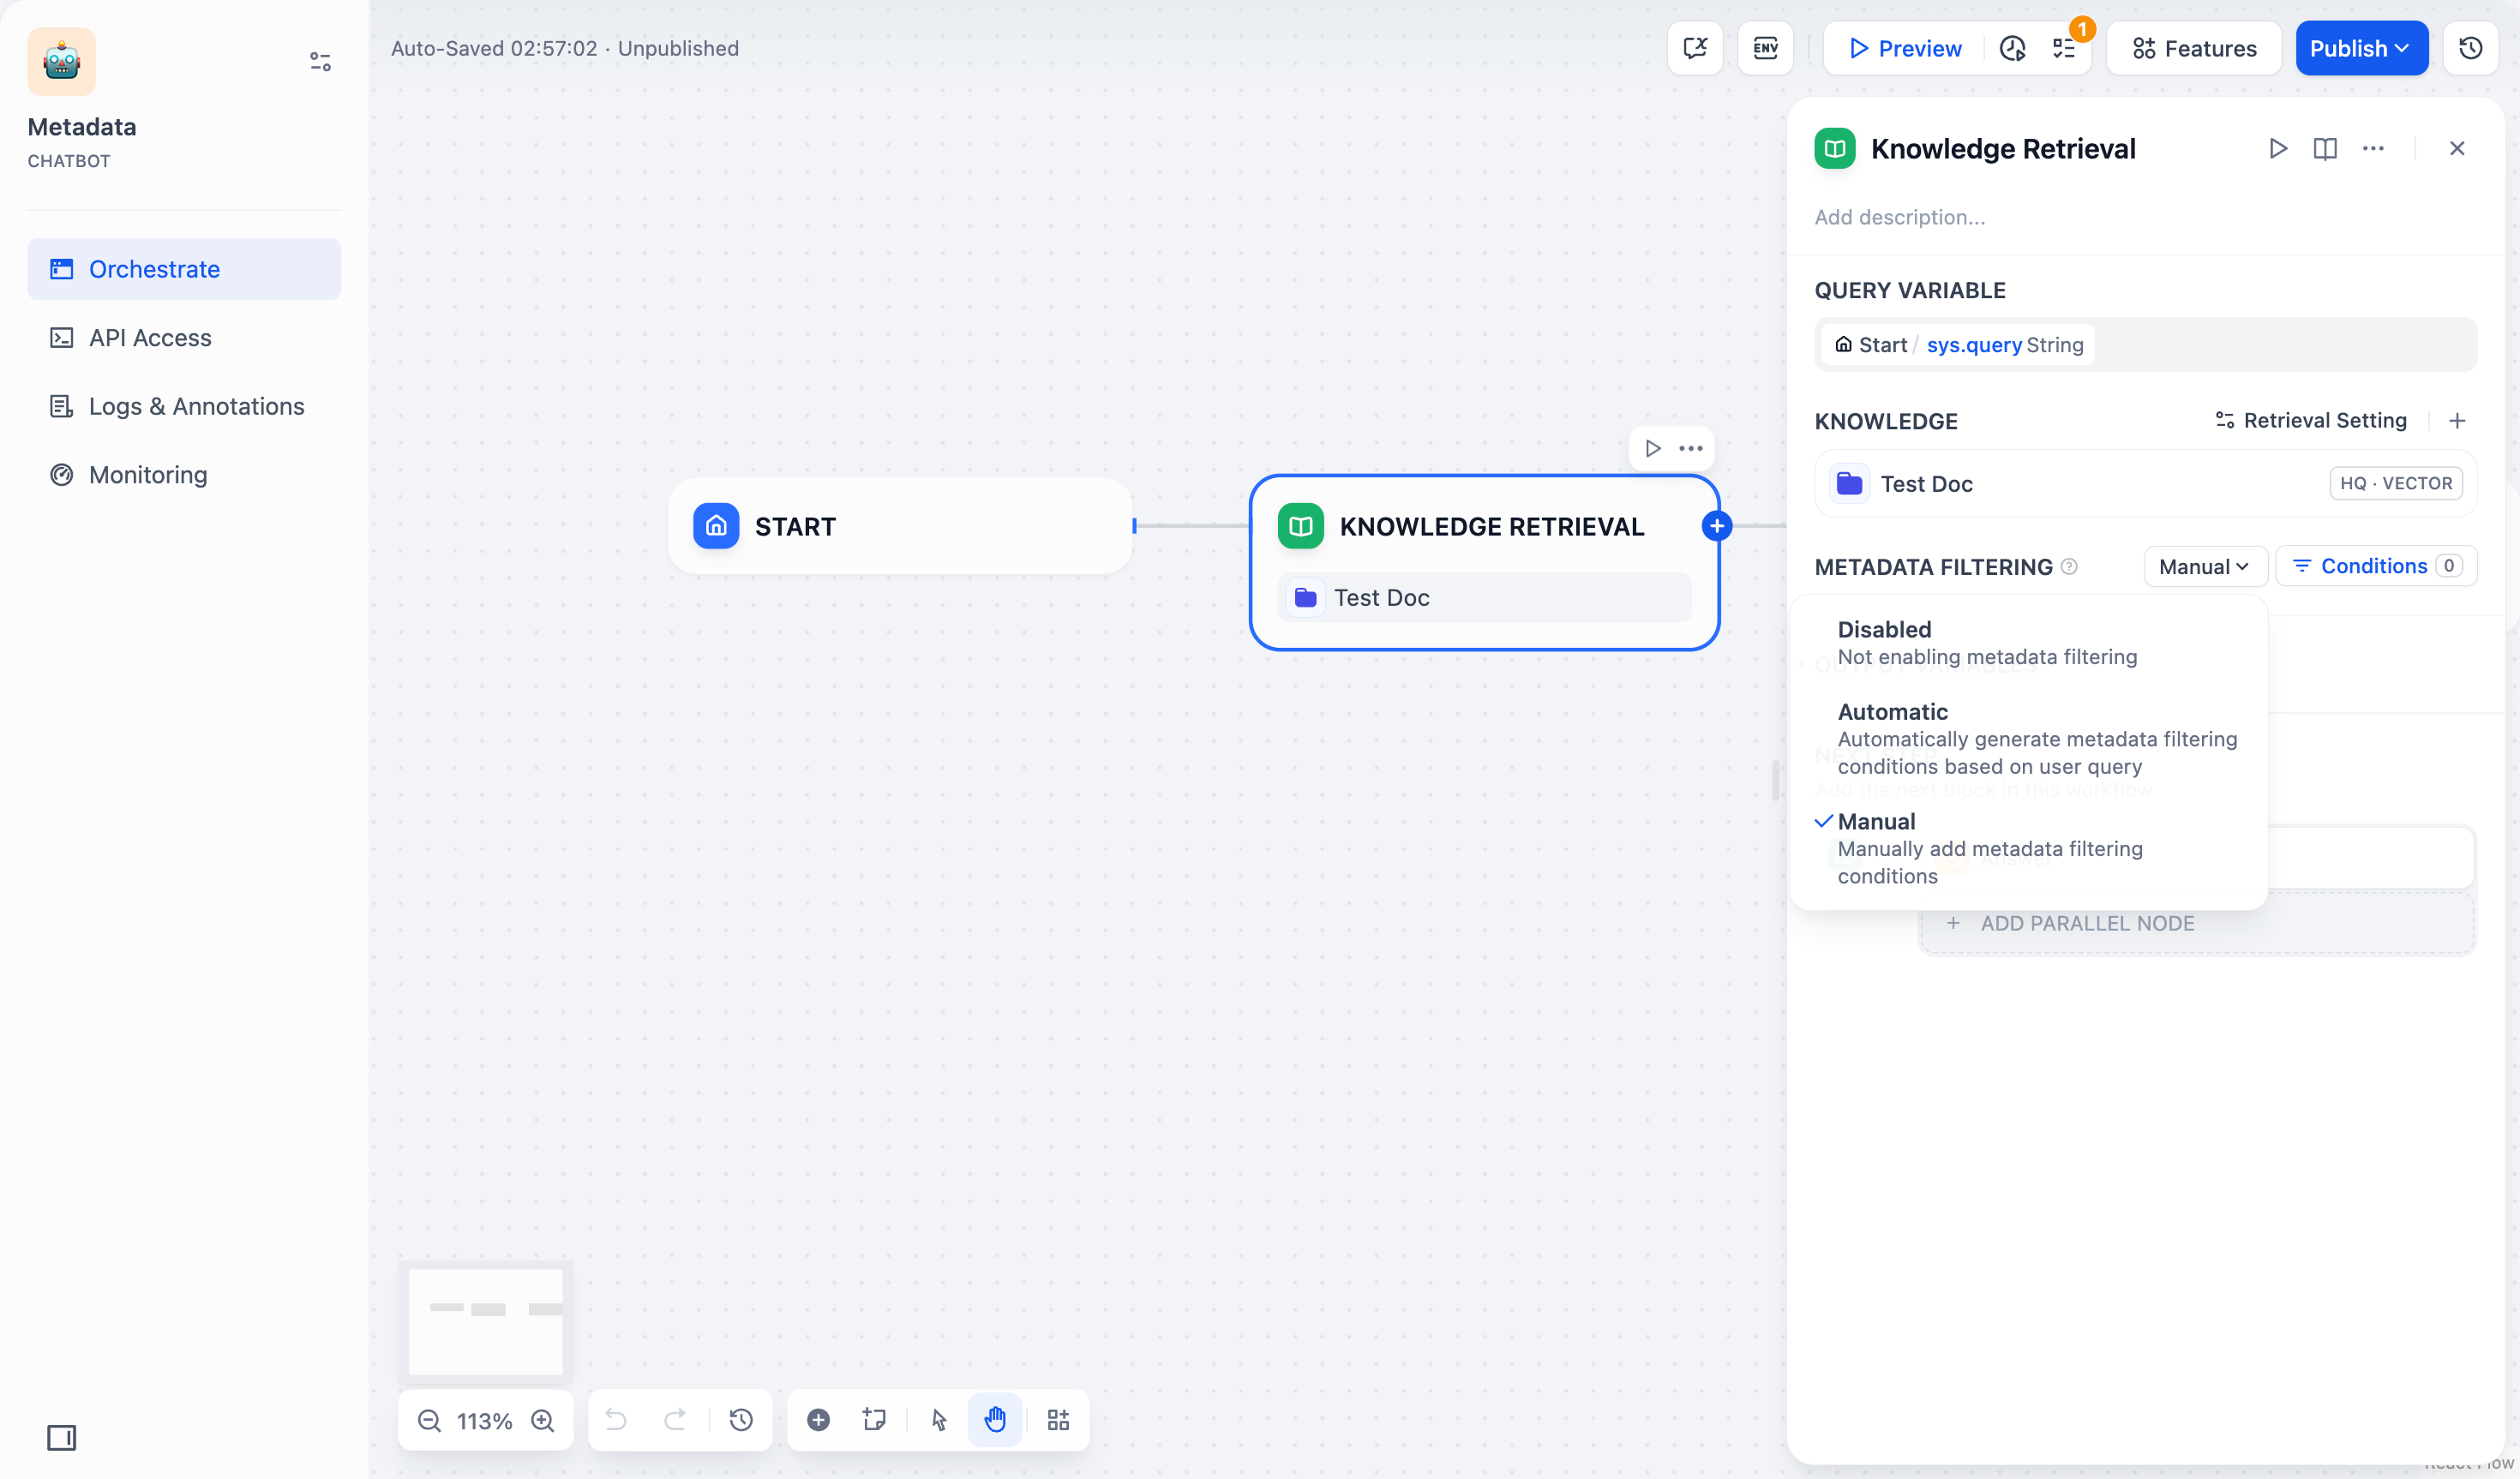
</Frame>
2. For Manual Mode, follow these steps:
1. Click **Conditions** to open the configuration panel.
<Frame>
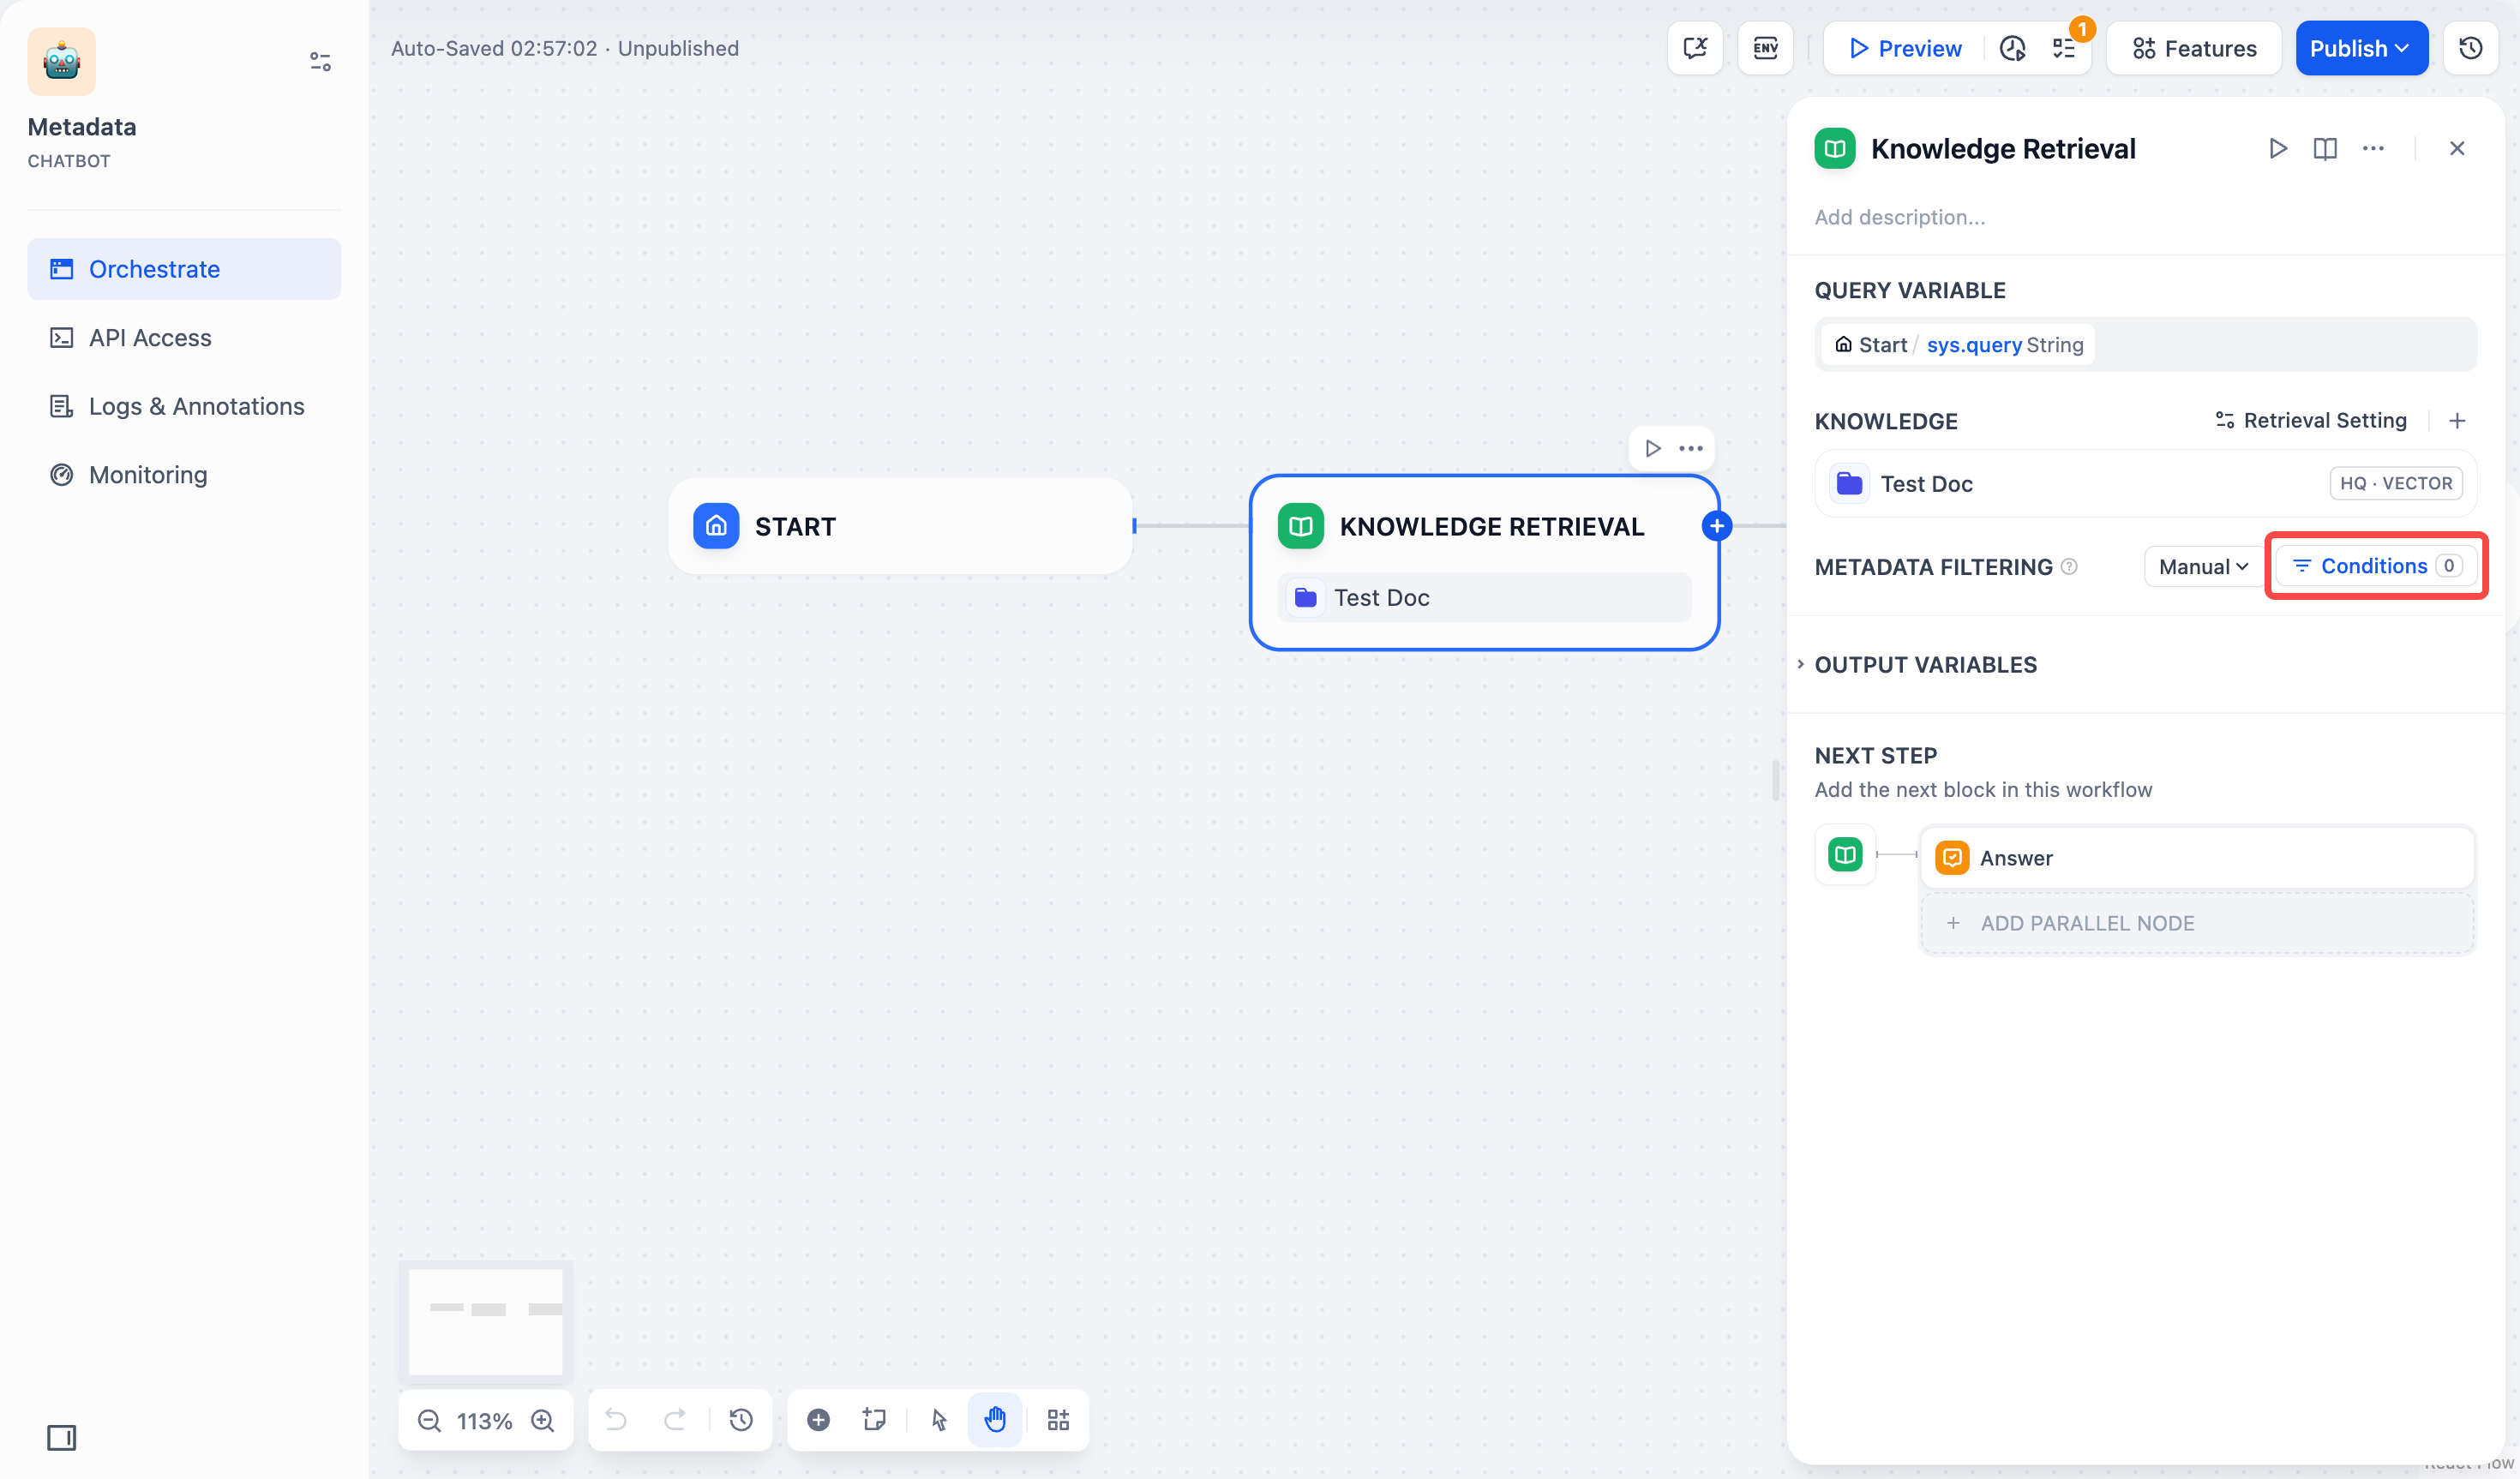
</Frame>
2. Click **+Add Condition**:
* Select metadata fields within your chosen knowledge base from the dropdown list.
> Note: When multiple knowledge bases are selected, only common metadata fields are shown in the list.
* Use the search box to find specific fields.
<Frame>
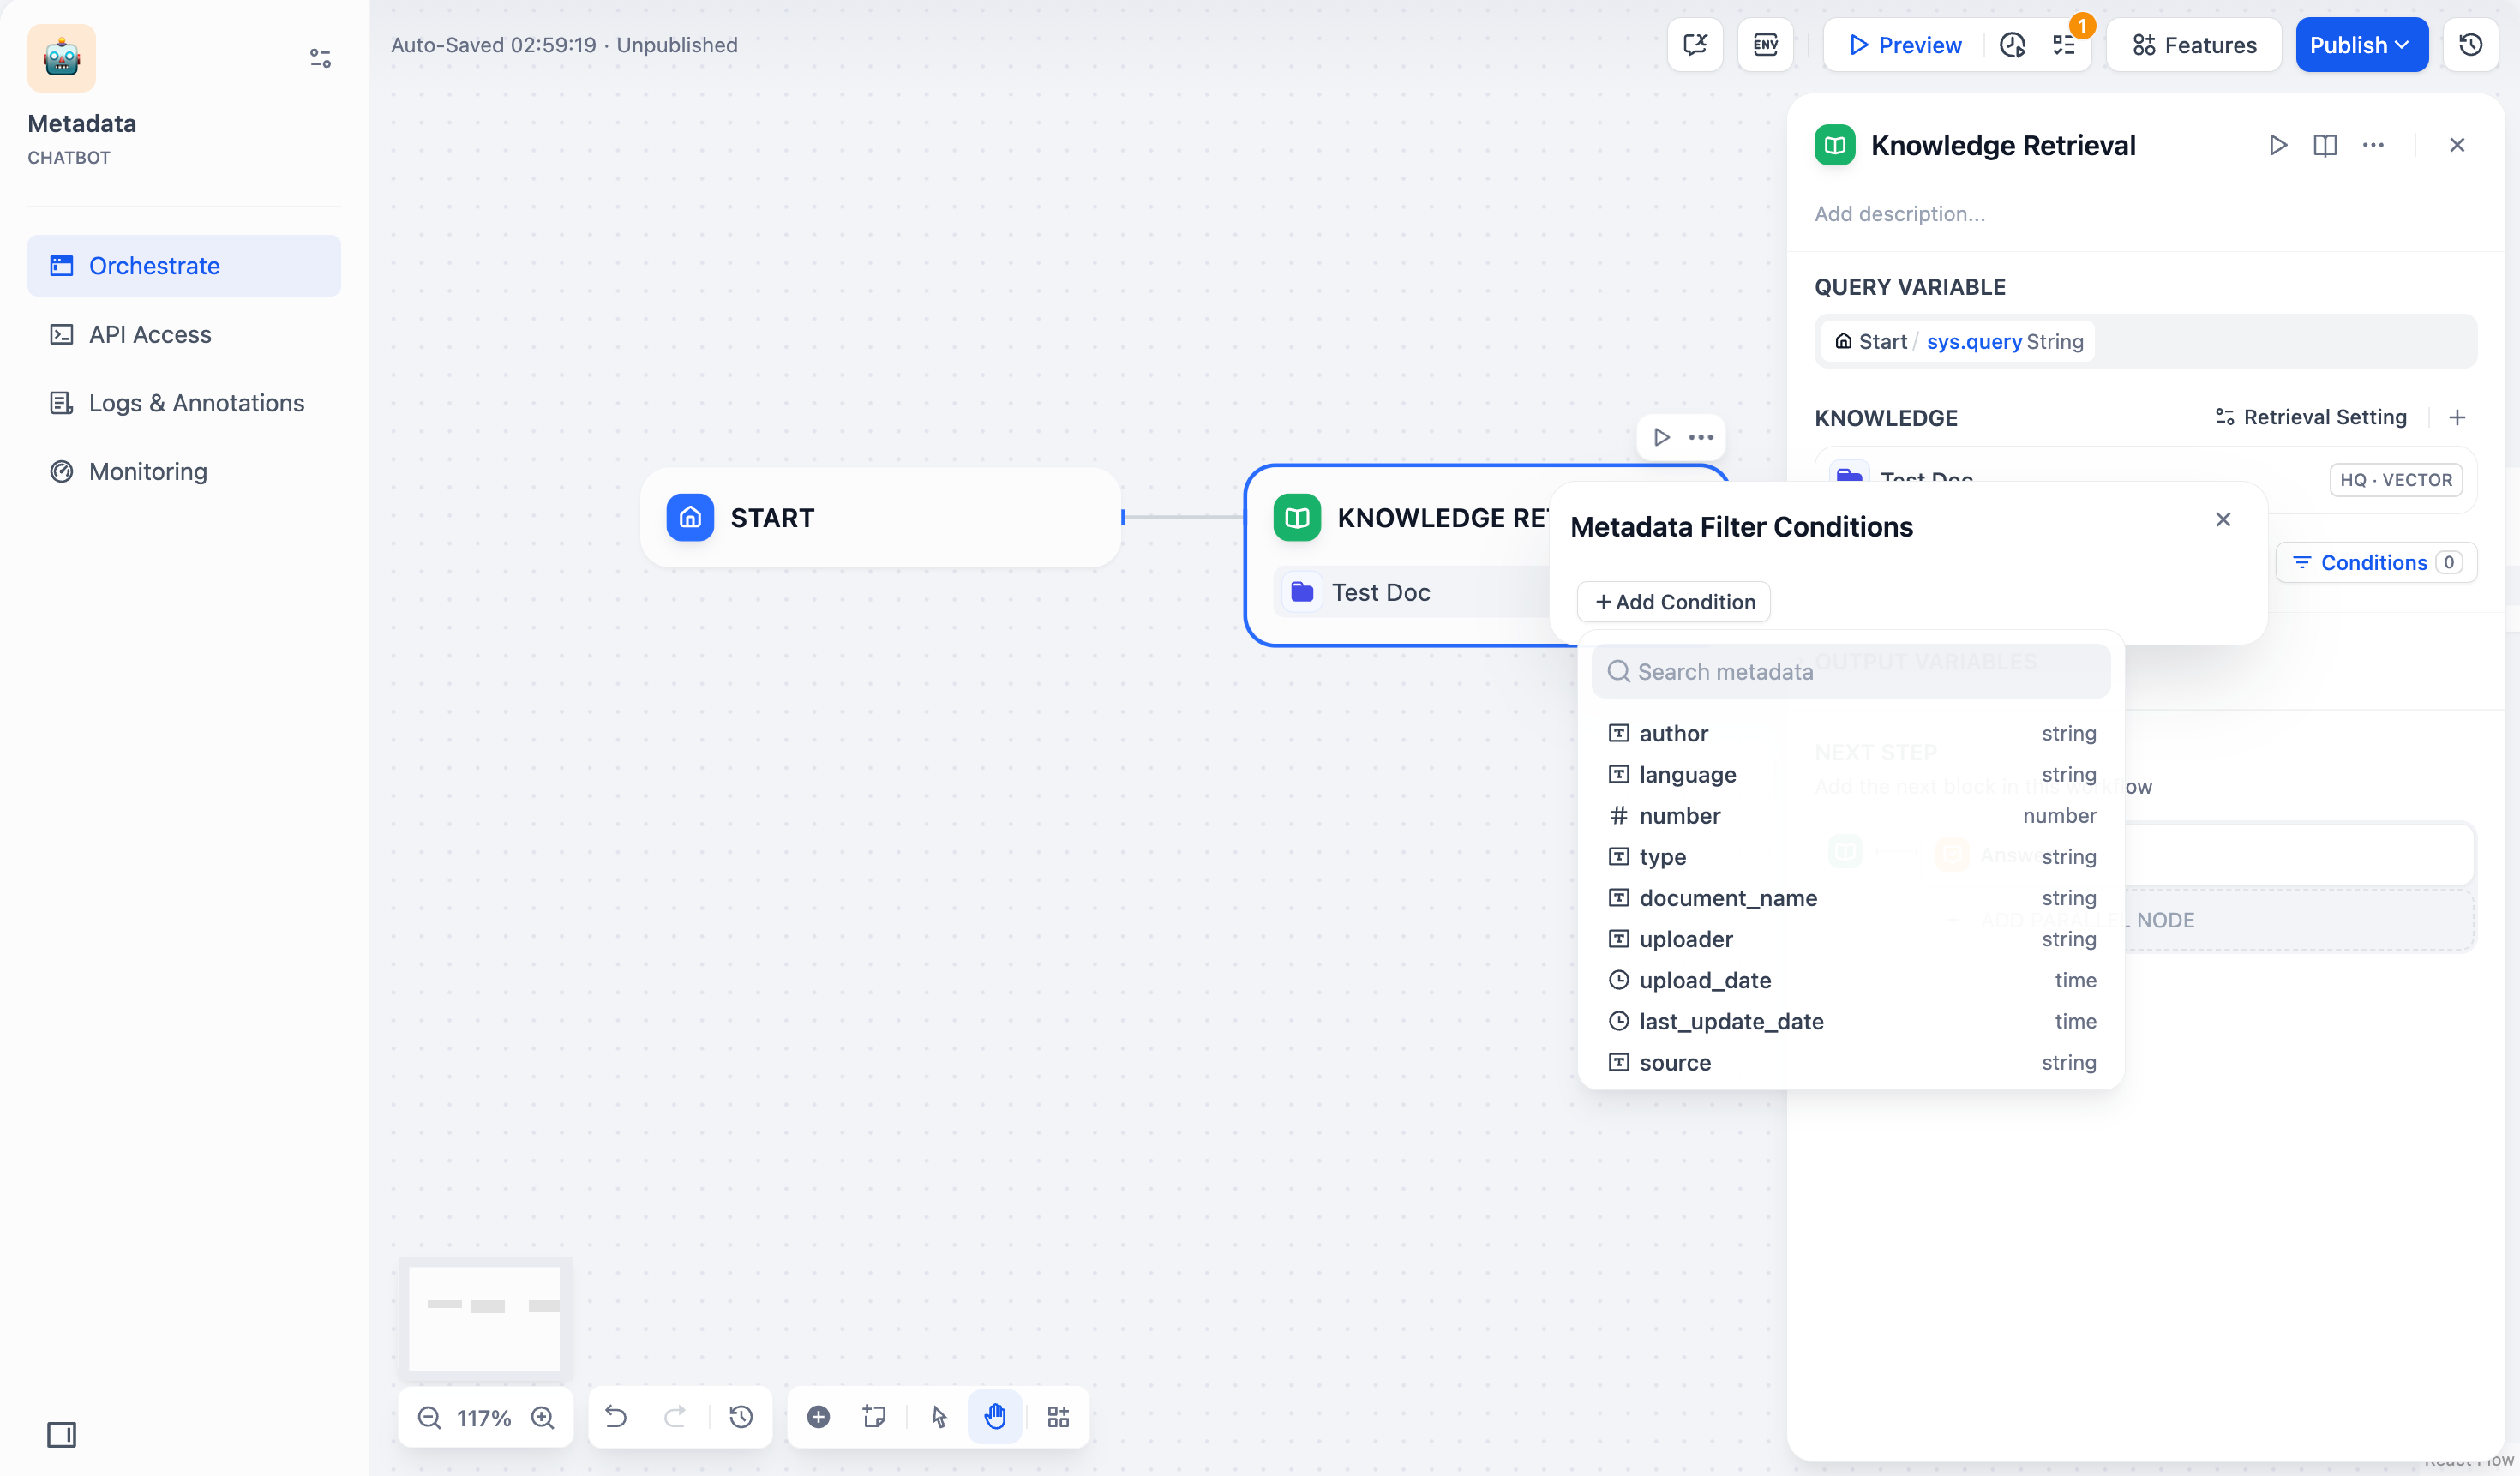
</Frame>
3. Click **+Add Condition** to add more fields.
<Frame>
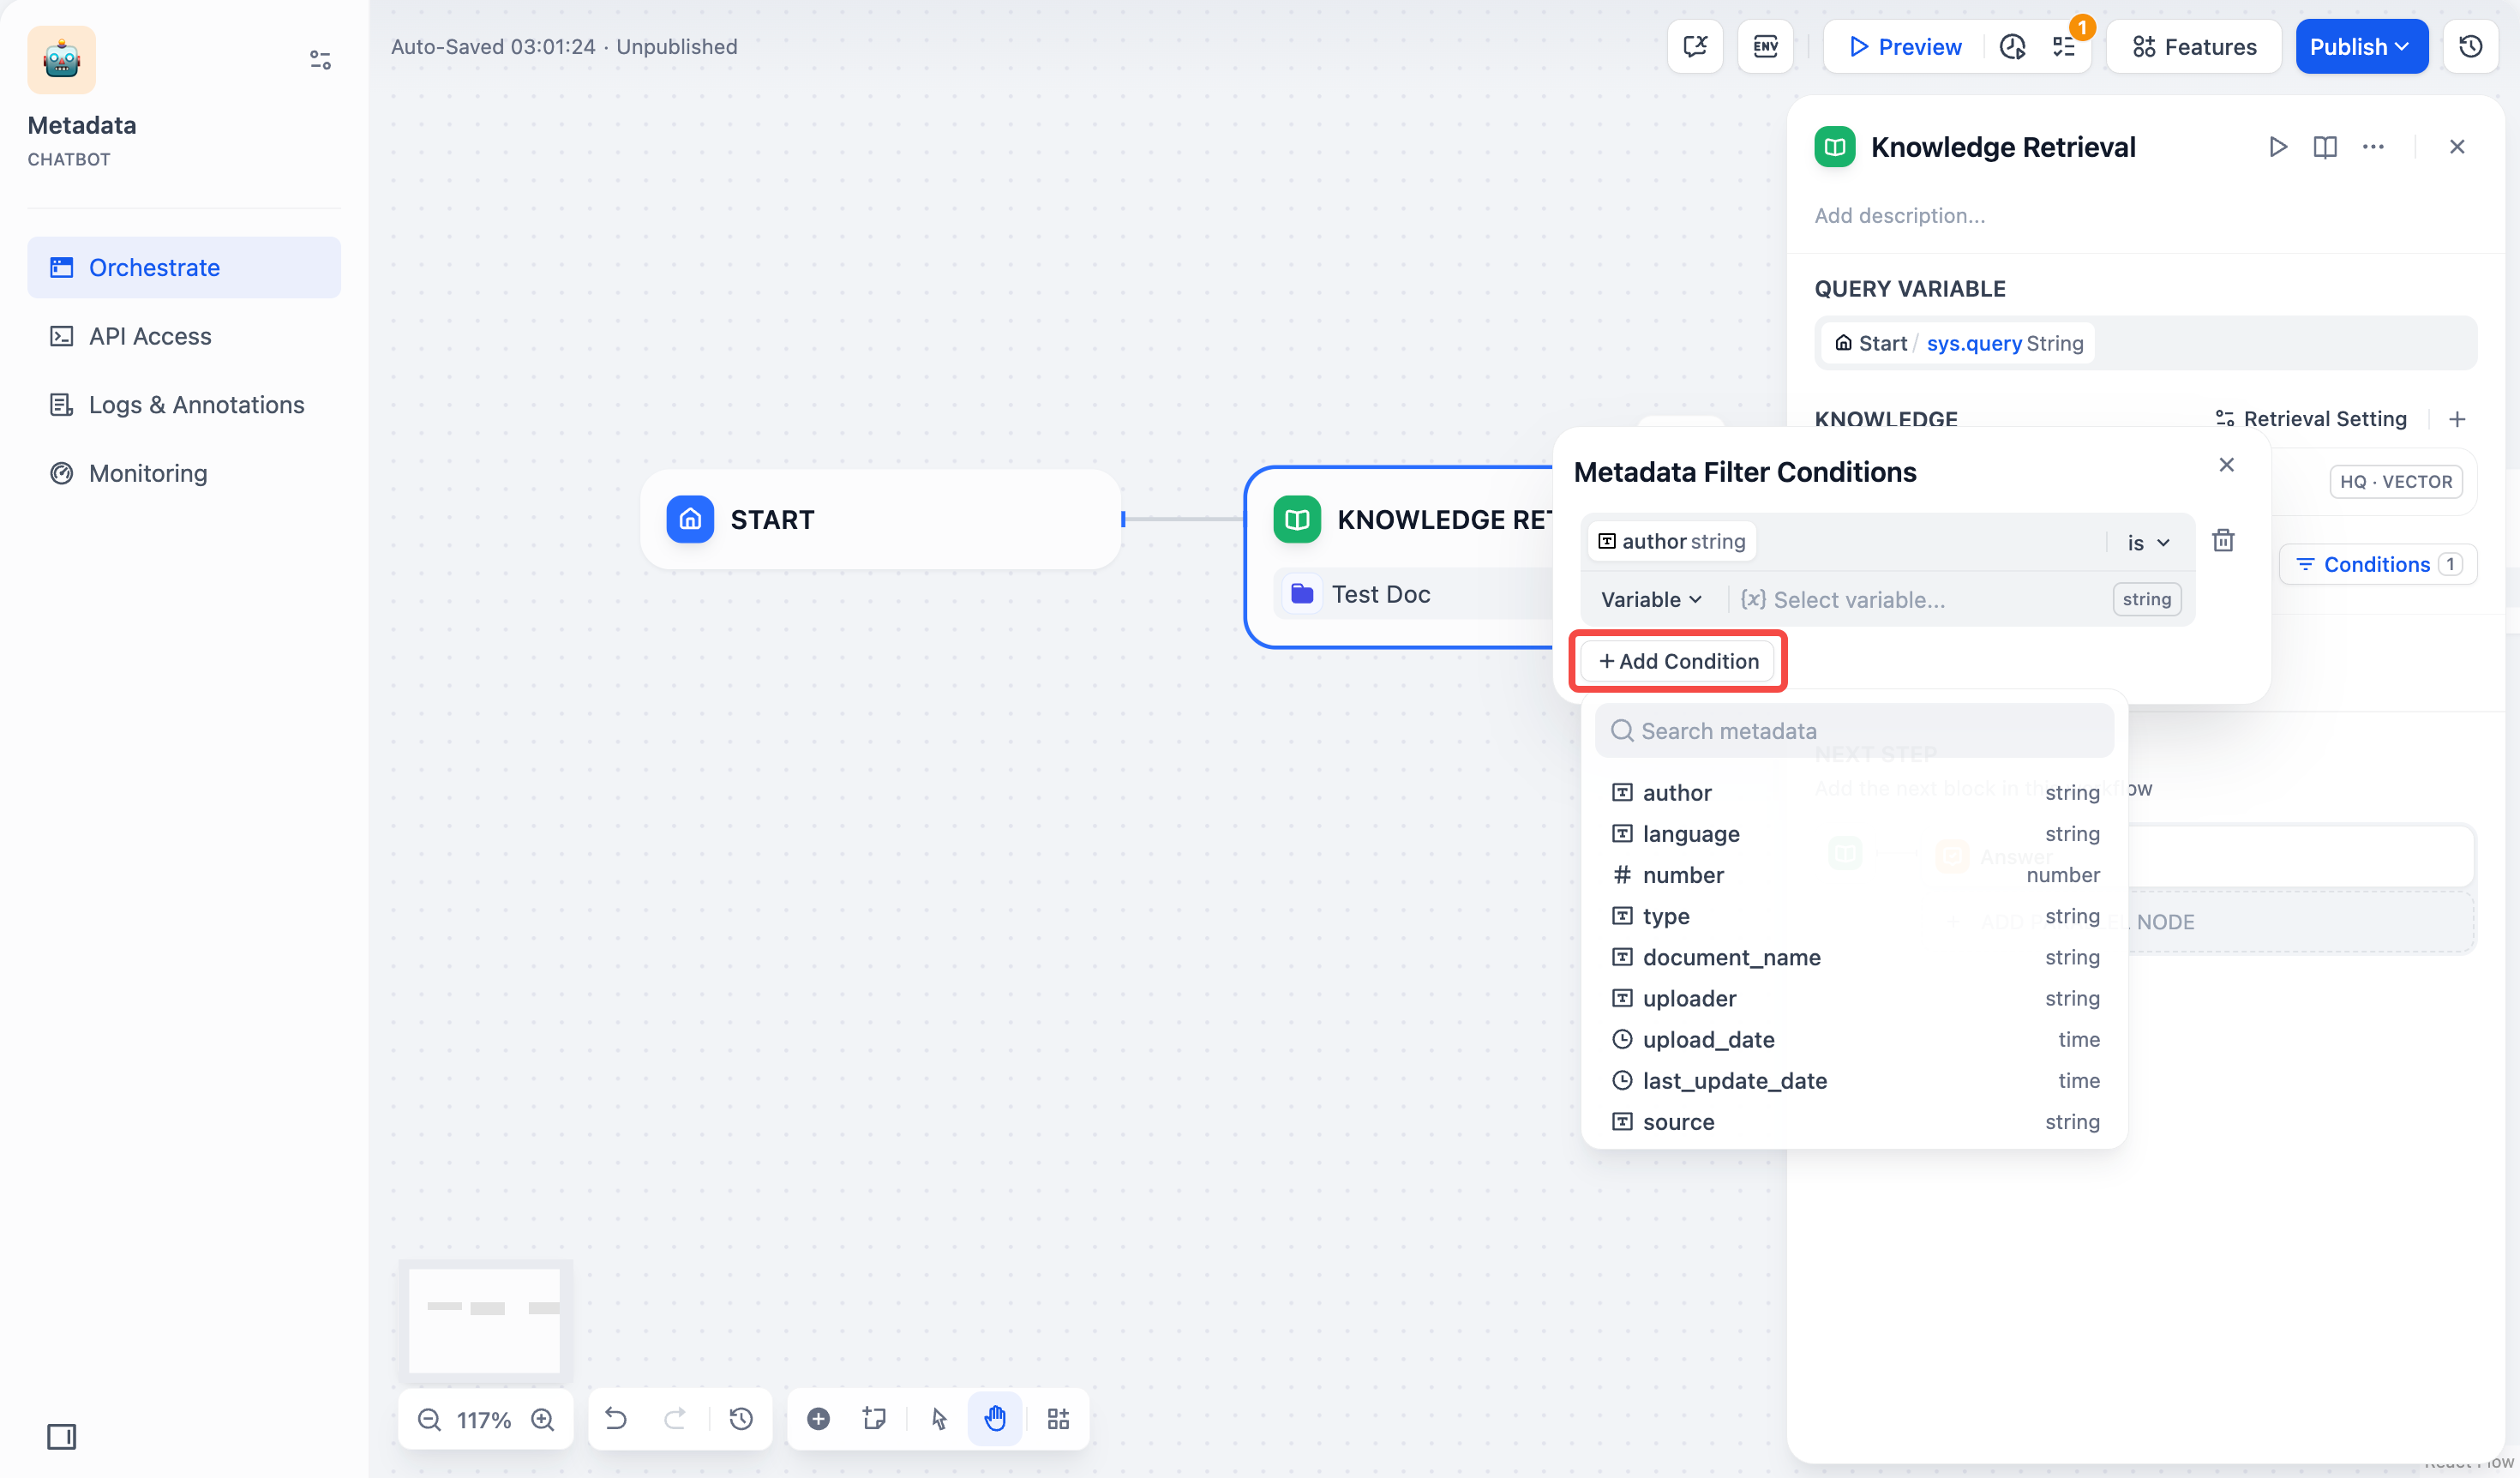
</Frame>
4. Configure filter conditions:
| Field Type | Operator | Description and Examples |
| ---------- | ------------ | ----------------------------------------------------------------------------------------------------------------------------- |
| String | is | Exact match required. Example: `is "Published"` returns only documents marked exactly as "Published". |
| | is not | Excludes exact matches. Example: `is not "Draft"` returns all documents except those marked as "Draft". |
| | is empty | Returns documents where the field has no value. |
| | is not empty | Returns documents where the field has any value. |
| | contains | Matches partial text. Example: `contains "Report"` returns "Monthly Report", "Annual Report", etc. |
| | not contains | Excludes documents containing specified text. Example: `not contains "Draft"` returns documents without "Draft" in the field. |
| | starts with | Matches text at beginning. Example: `starts with "Doc"` returns "Doc1", "Document", etc. |
| | ends with | Matches text at end. Example: `ends with "2024"` returns "Report 2024", "Summary 2024", etc. |
| Number | = | Exact number match. Example: `= 10` returns documents marked with exactly 10. |
| | ≠ | Excludes specific number. Example: `≠ 5` returns all documents except those marked with 5. |
| | > | Greater than. Example: `> 100` returns documents with values above 100. |
| | \< | Less than. Example: `< 50` returns documents with values below 50. |
| | ≥ | Greater than or equal to. Example: `≥ 20` returns documents with values 20 or higher. |
| | ≤ | Less than or equal to. Example: `≤ 200` returns documents with values 200 or lower. |
| | is empty | Field has no value assigned. For example, `is empty` returns all documents where this field has no number assigned. |
| | is not empty | Field has a value assigned. For example, `is not empty` returns all documents where this field has a number assigned. |
| Date | is | Exact date match. Example: `is "2024-01-01"` returns documents dated January 1, 2024. |
| | before | Prior to date. Example: `before "2024-01-01"` returns documents dated before January 1, 2024. |
| | after | After date. Example: `after "2024-01-01"` returns documents dated after January 1, 2024. |
| | is empty | Returns documents with no date value. |
| | is not empty | Returns documents with any date value. |
5. Add filter values:
* **Variable**: Select from existing **Chatflow/Workflow** variables.
<Frame>
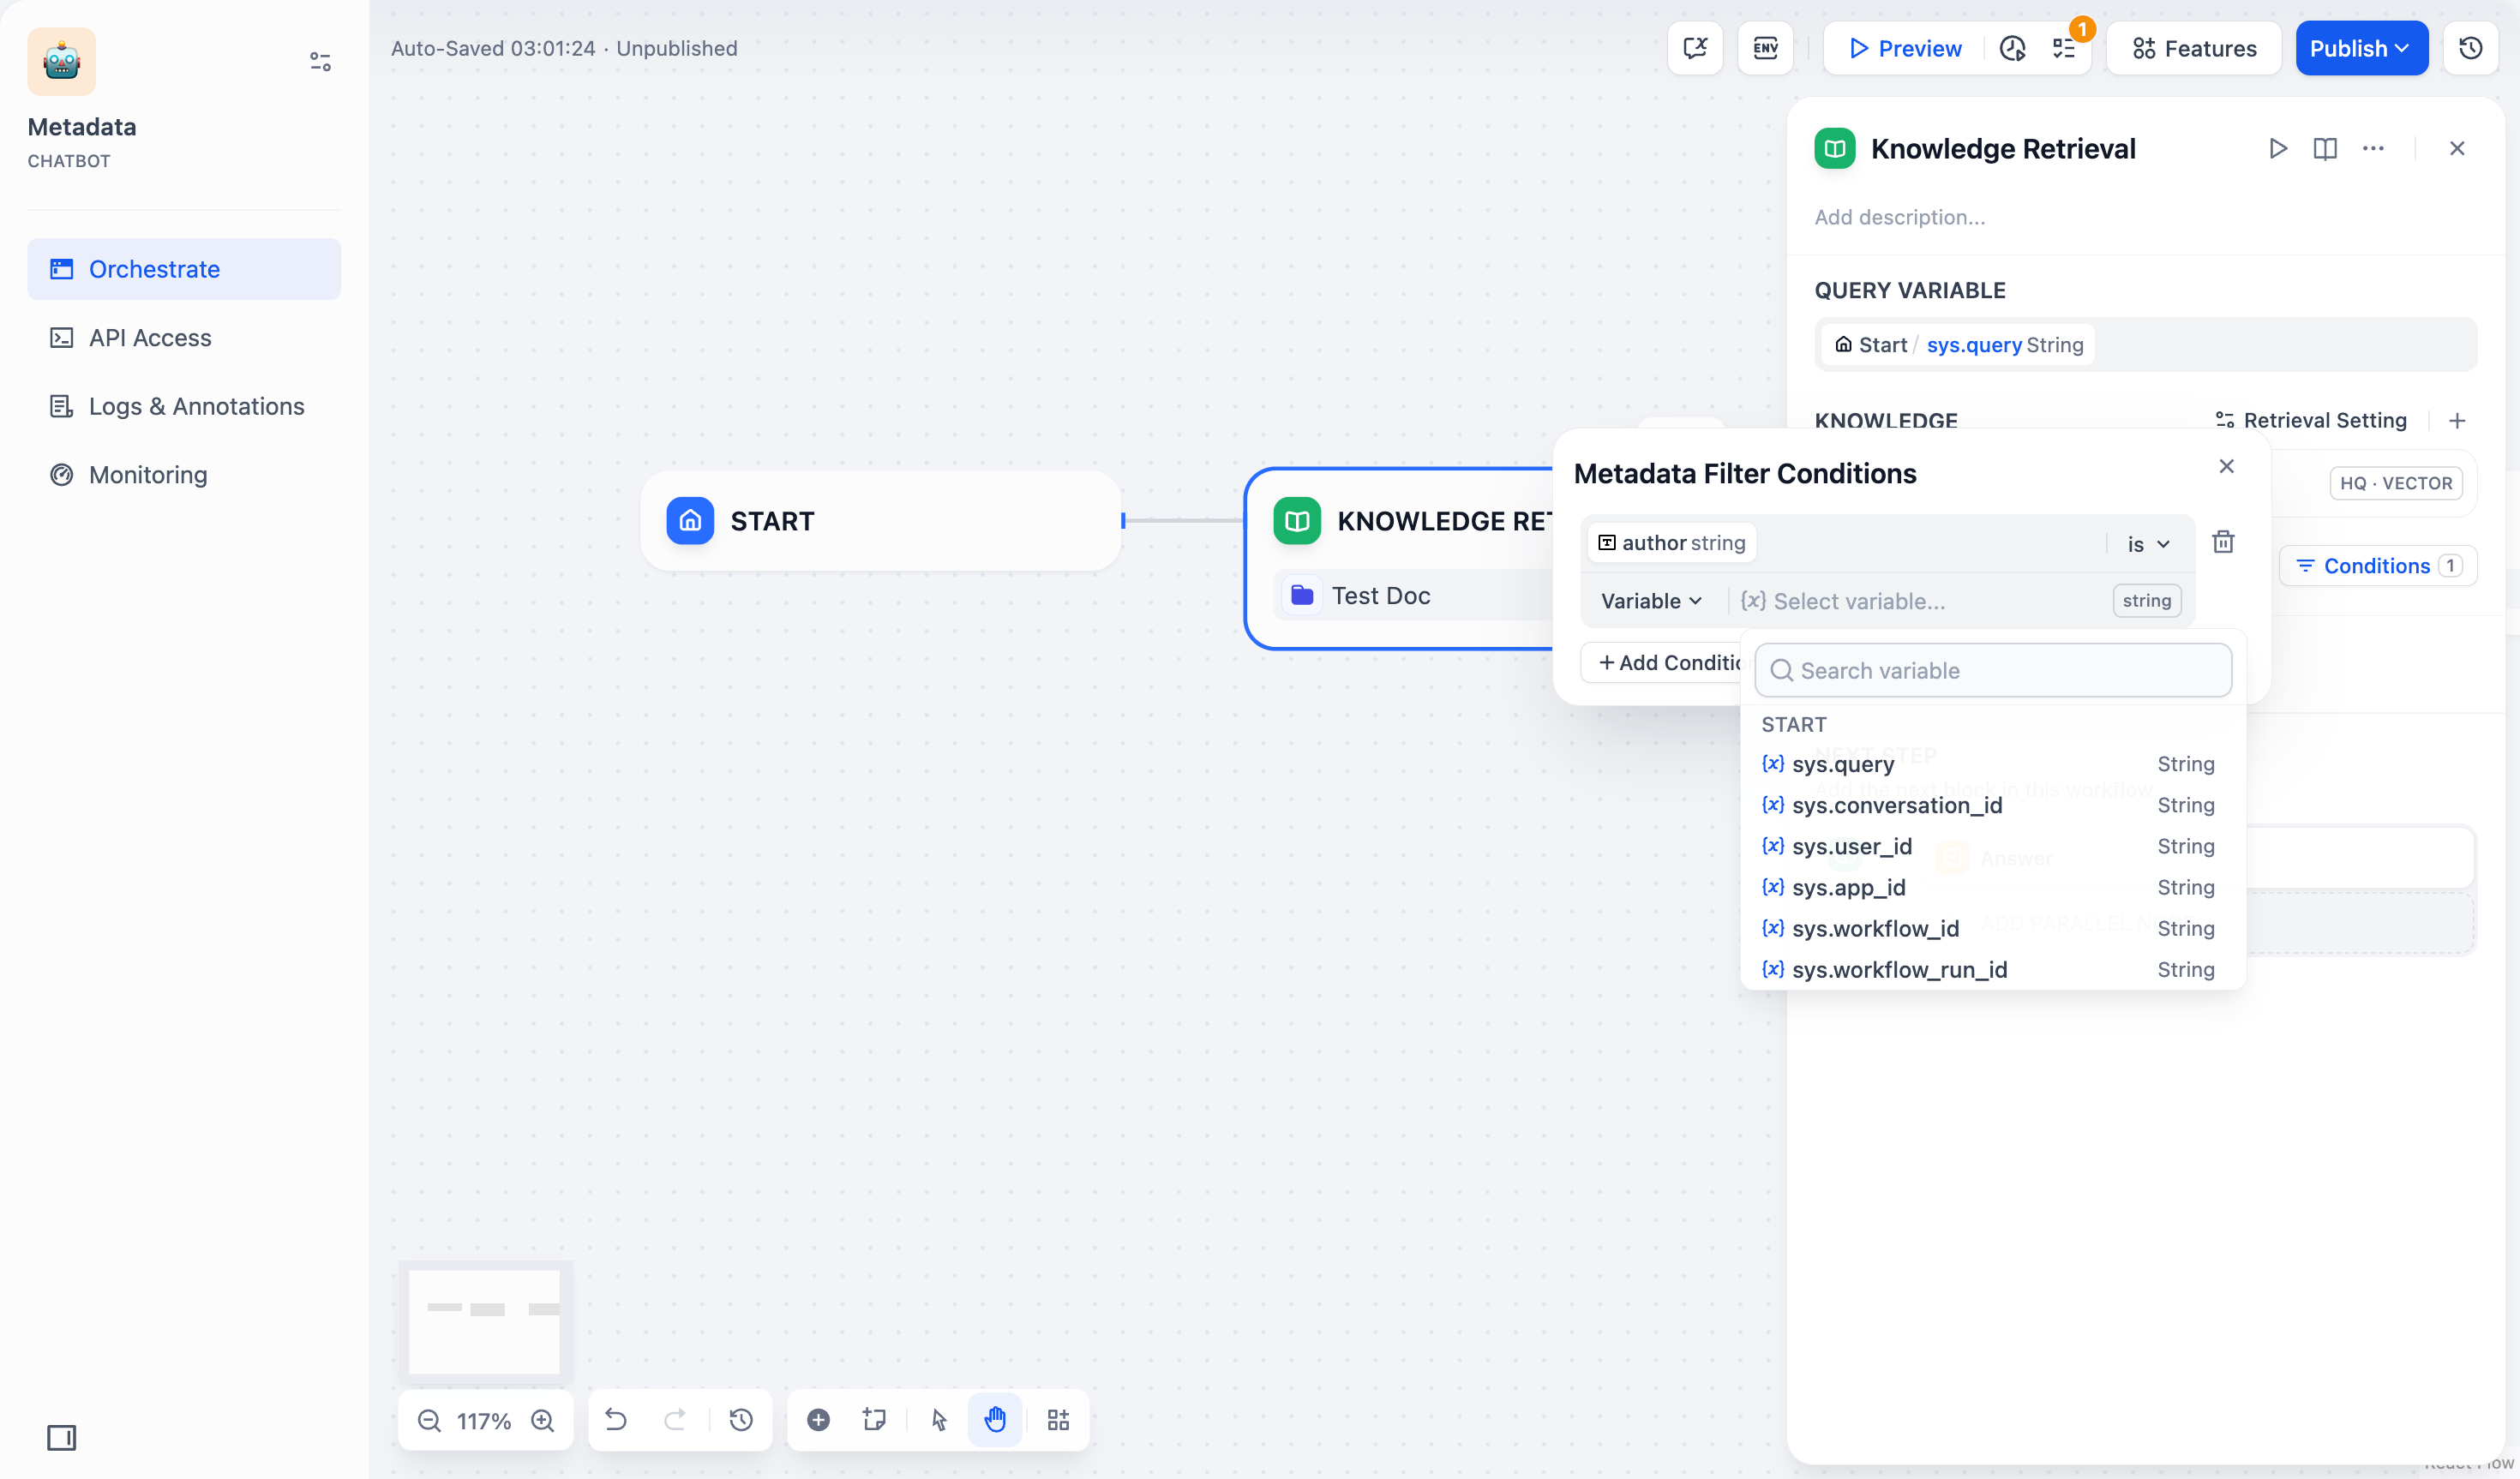
</Frame>
* **Constant**: Enter specific values.
> Time-type fields can only be filtered by constants The date picker is for time-type fields.
<Frame>
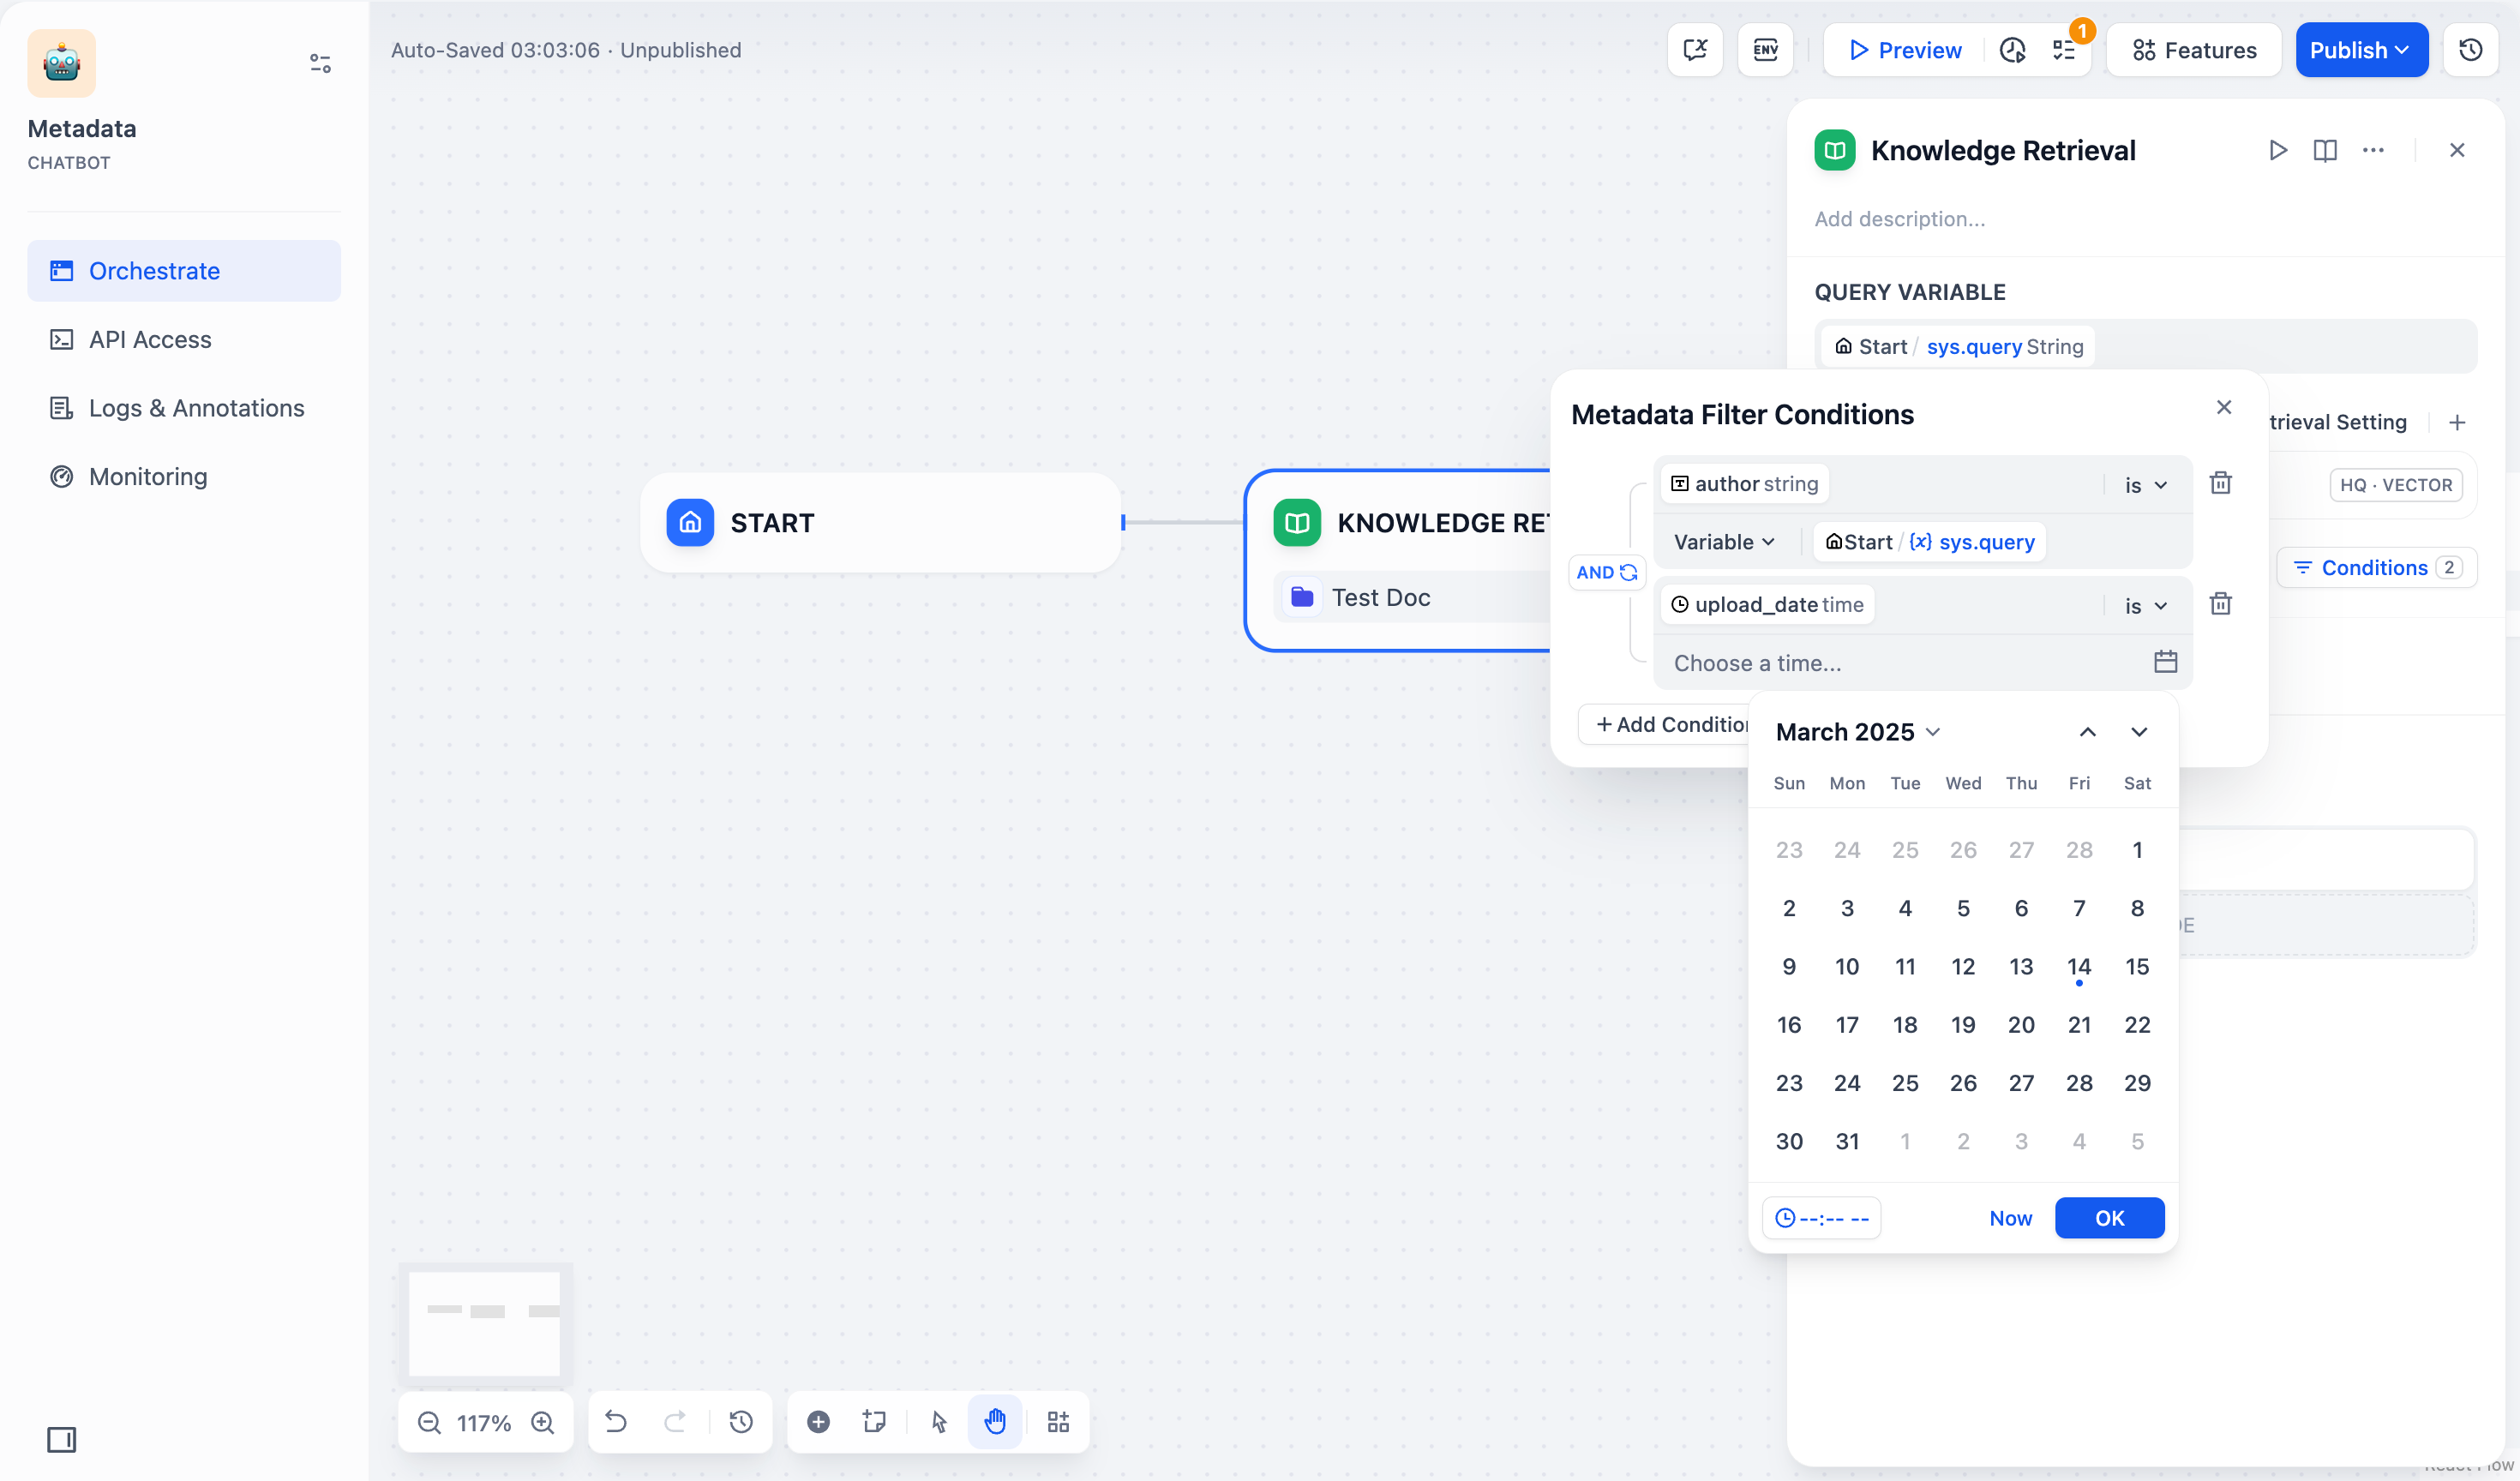
</Frame>
<Info>
Filter values are case-sensitive and require exact matches. Example: a filter `starts with "App"` or `contains "App"` will match "Apple" but not "apple" or "APPLE".
</Info>
6. Set logic operators:
* `AND`: Match all conditions
* `OR`: Match any condition
<Frame>
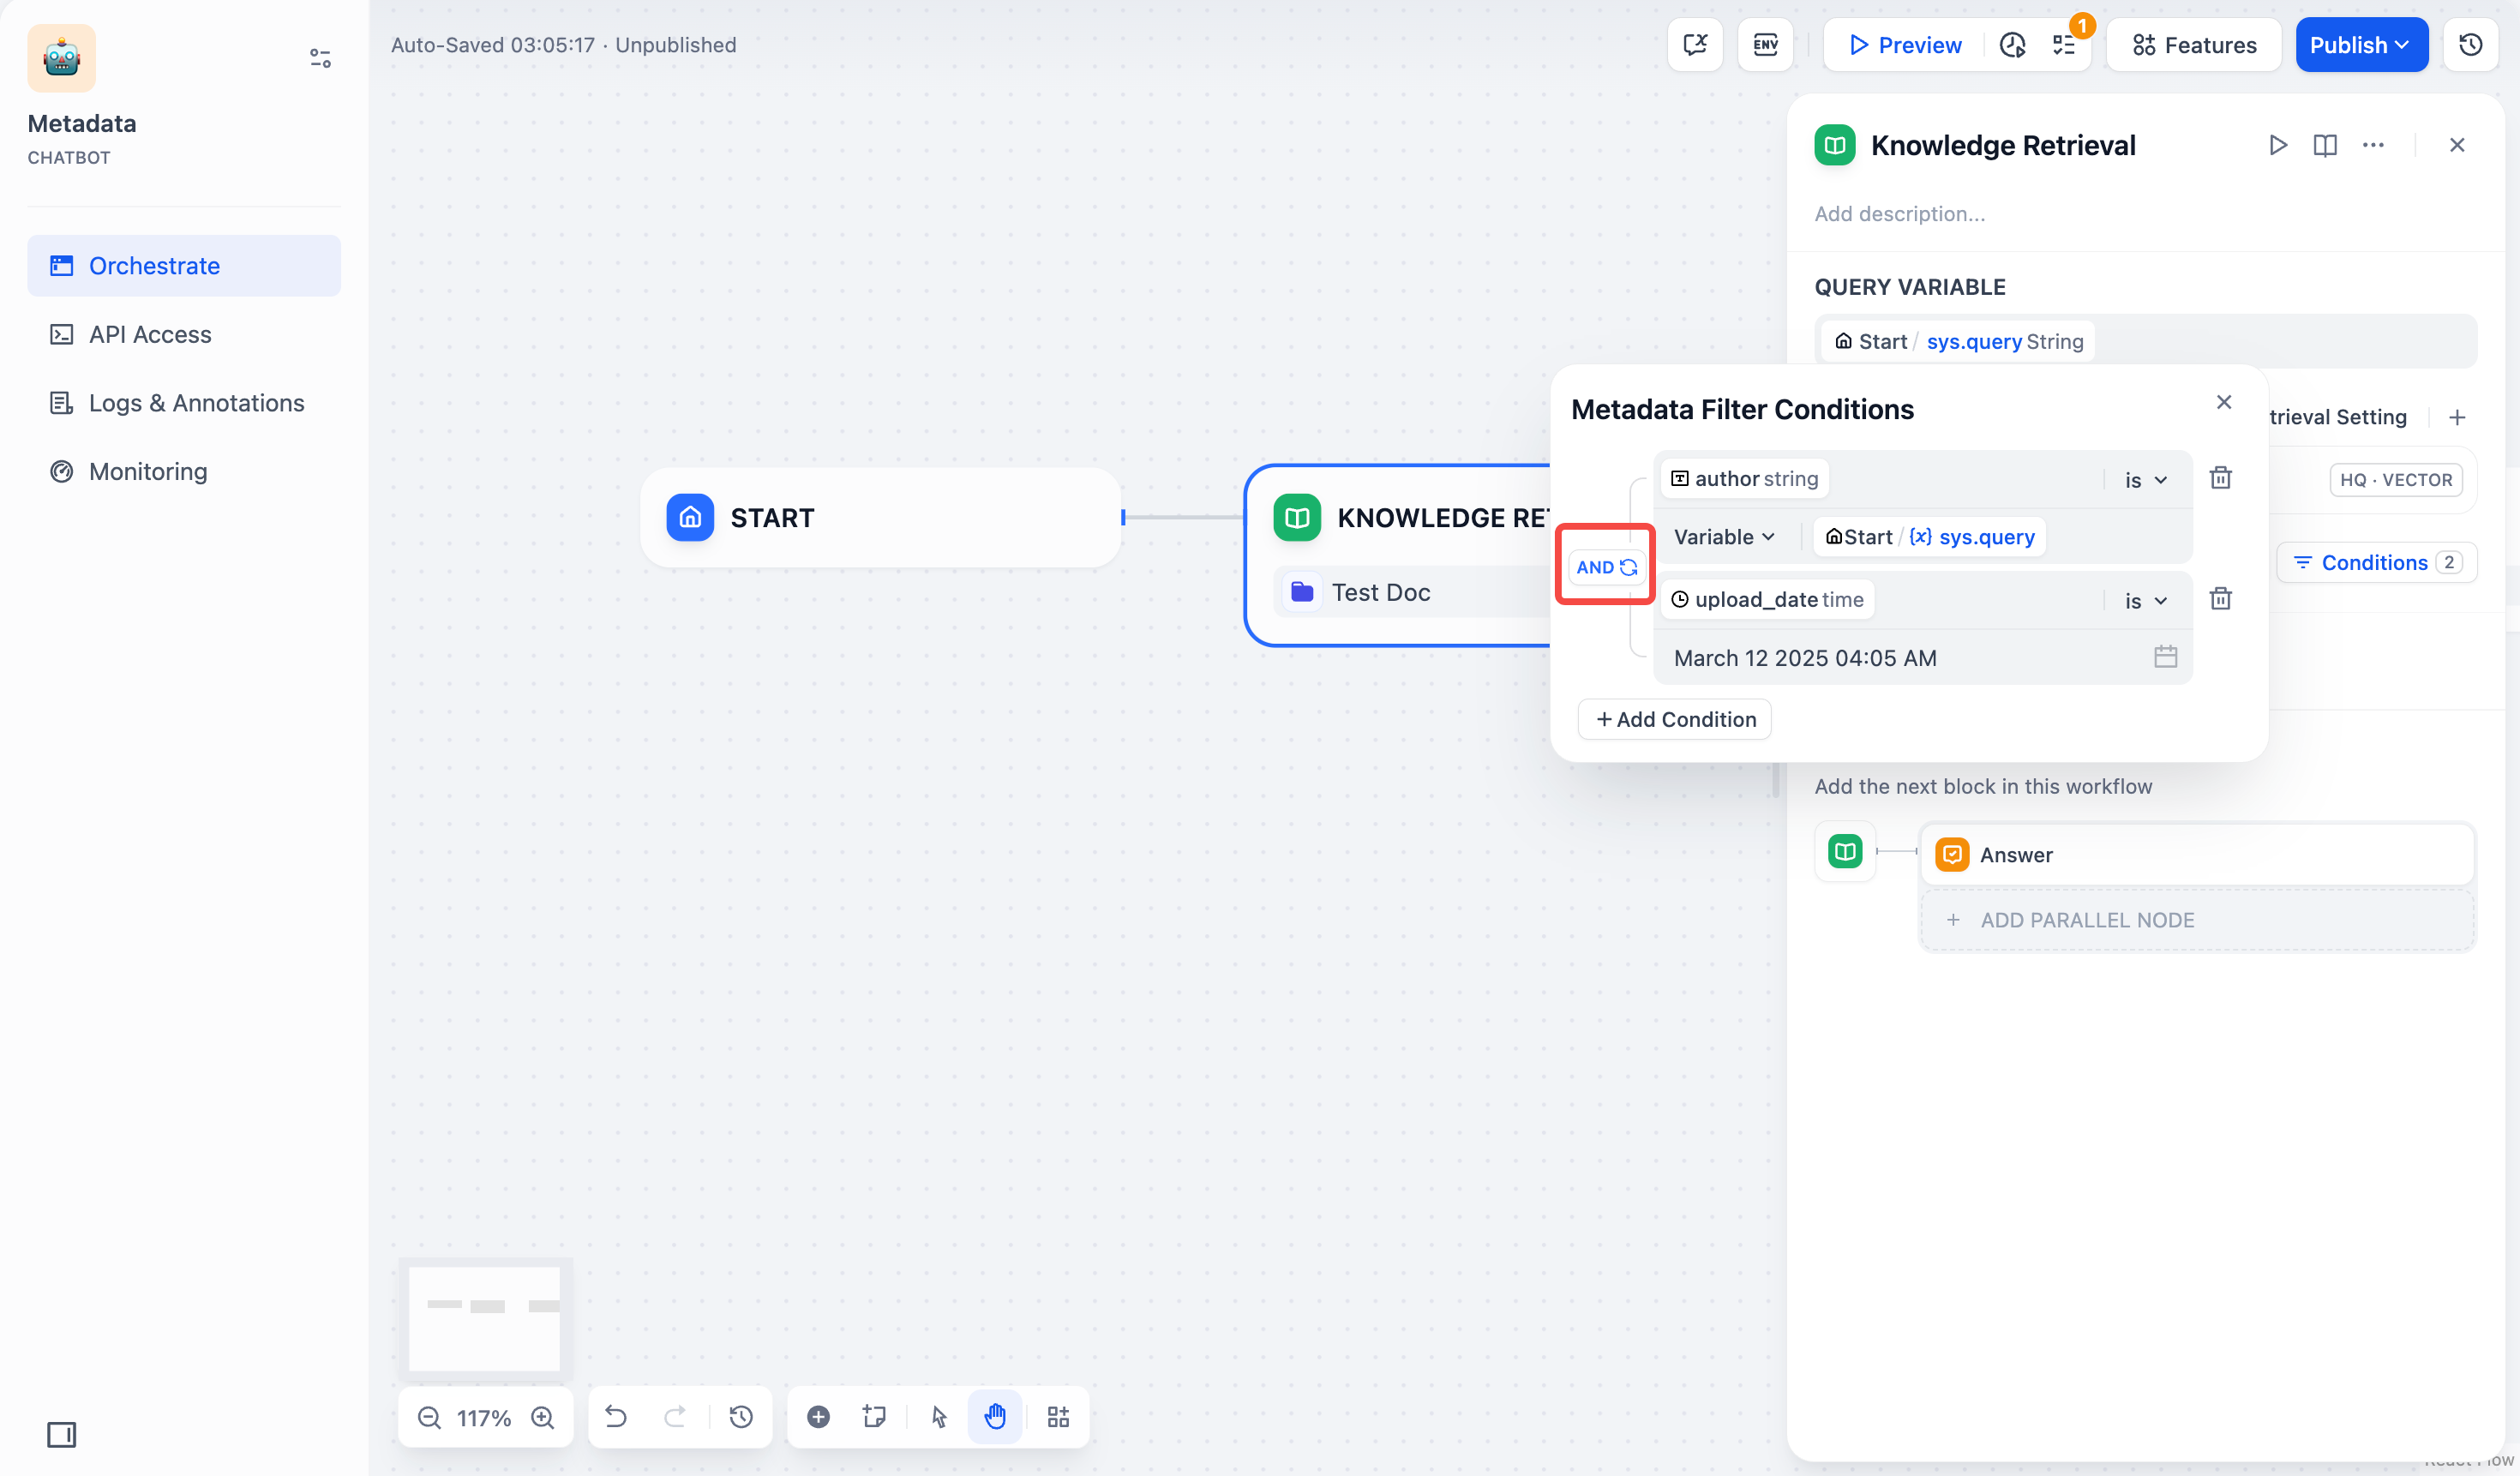
</Frame>
7. Click outside the panel to save your settings.
#### Chatbot
Access **Metadata Filtering** below **Knowledge** (bottom-left). Configuration steps are the same as in **Chatflow/Workflow**.
<Frame>
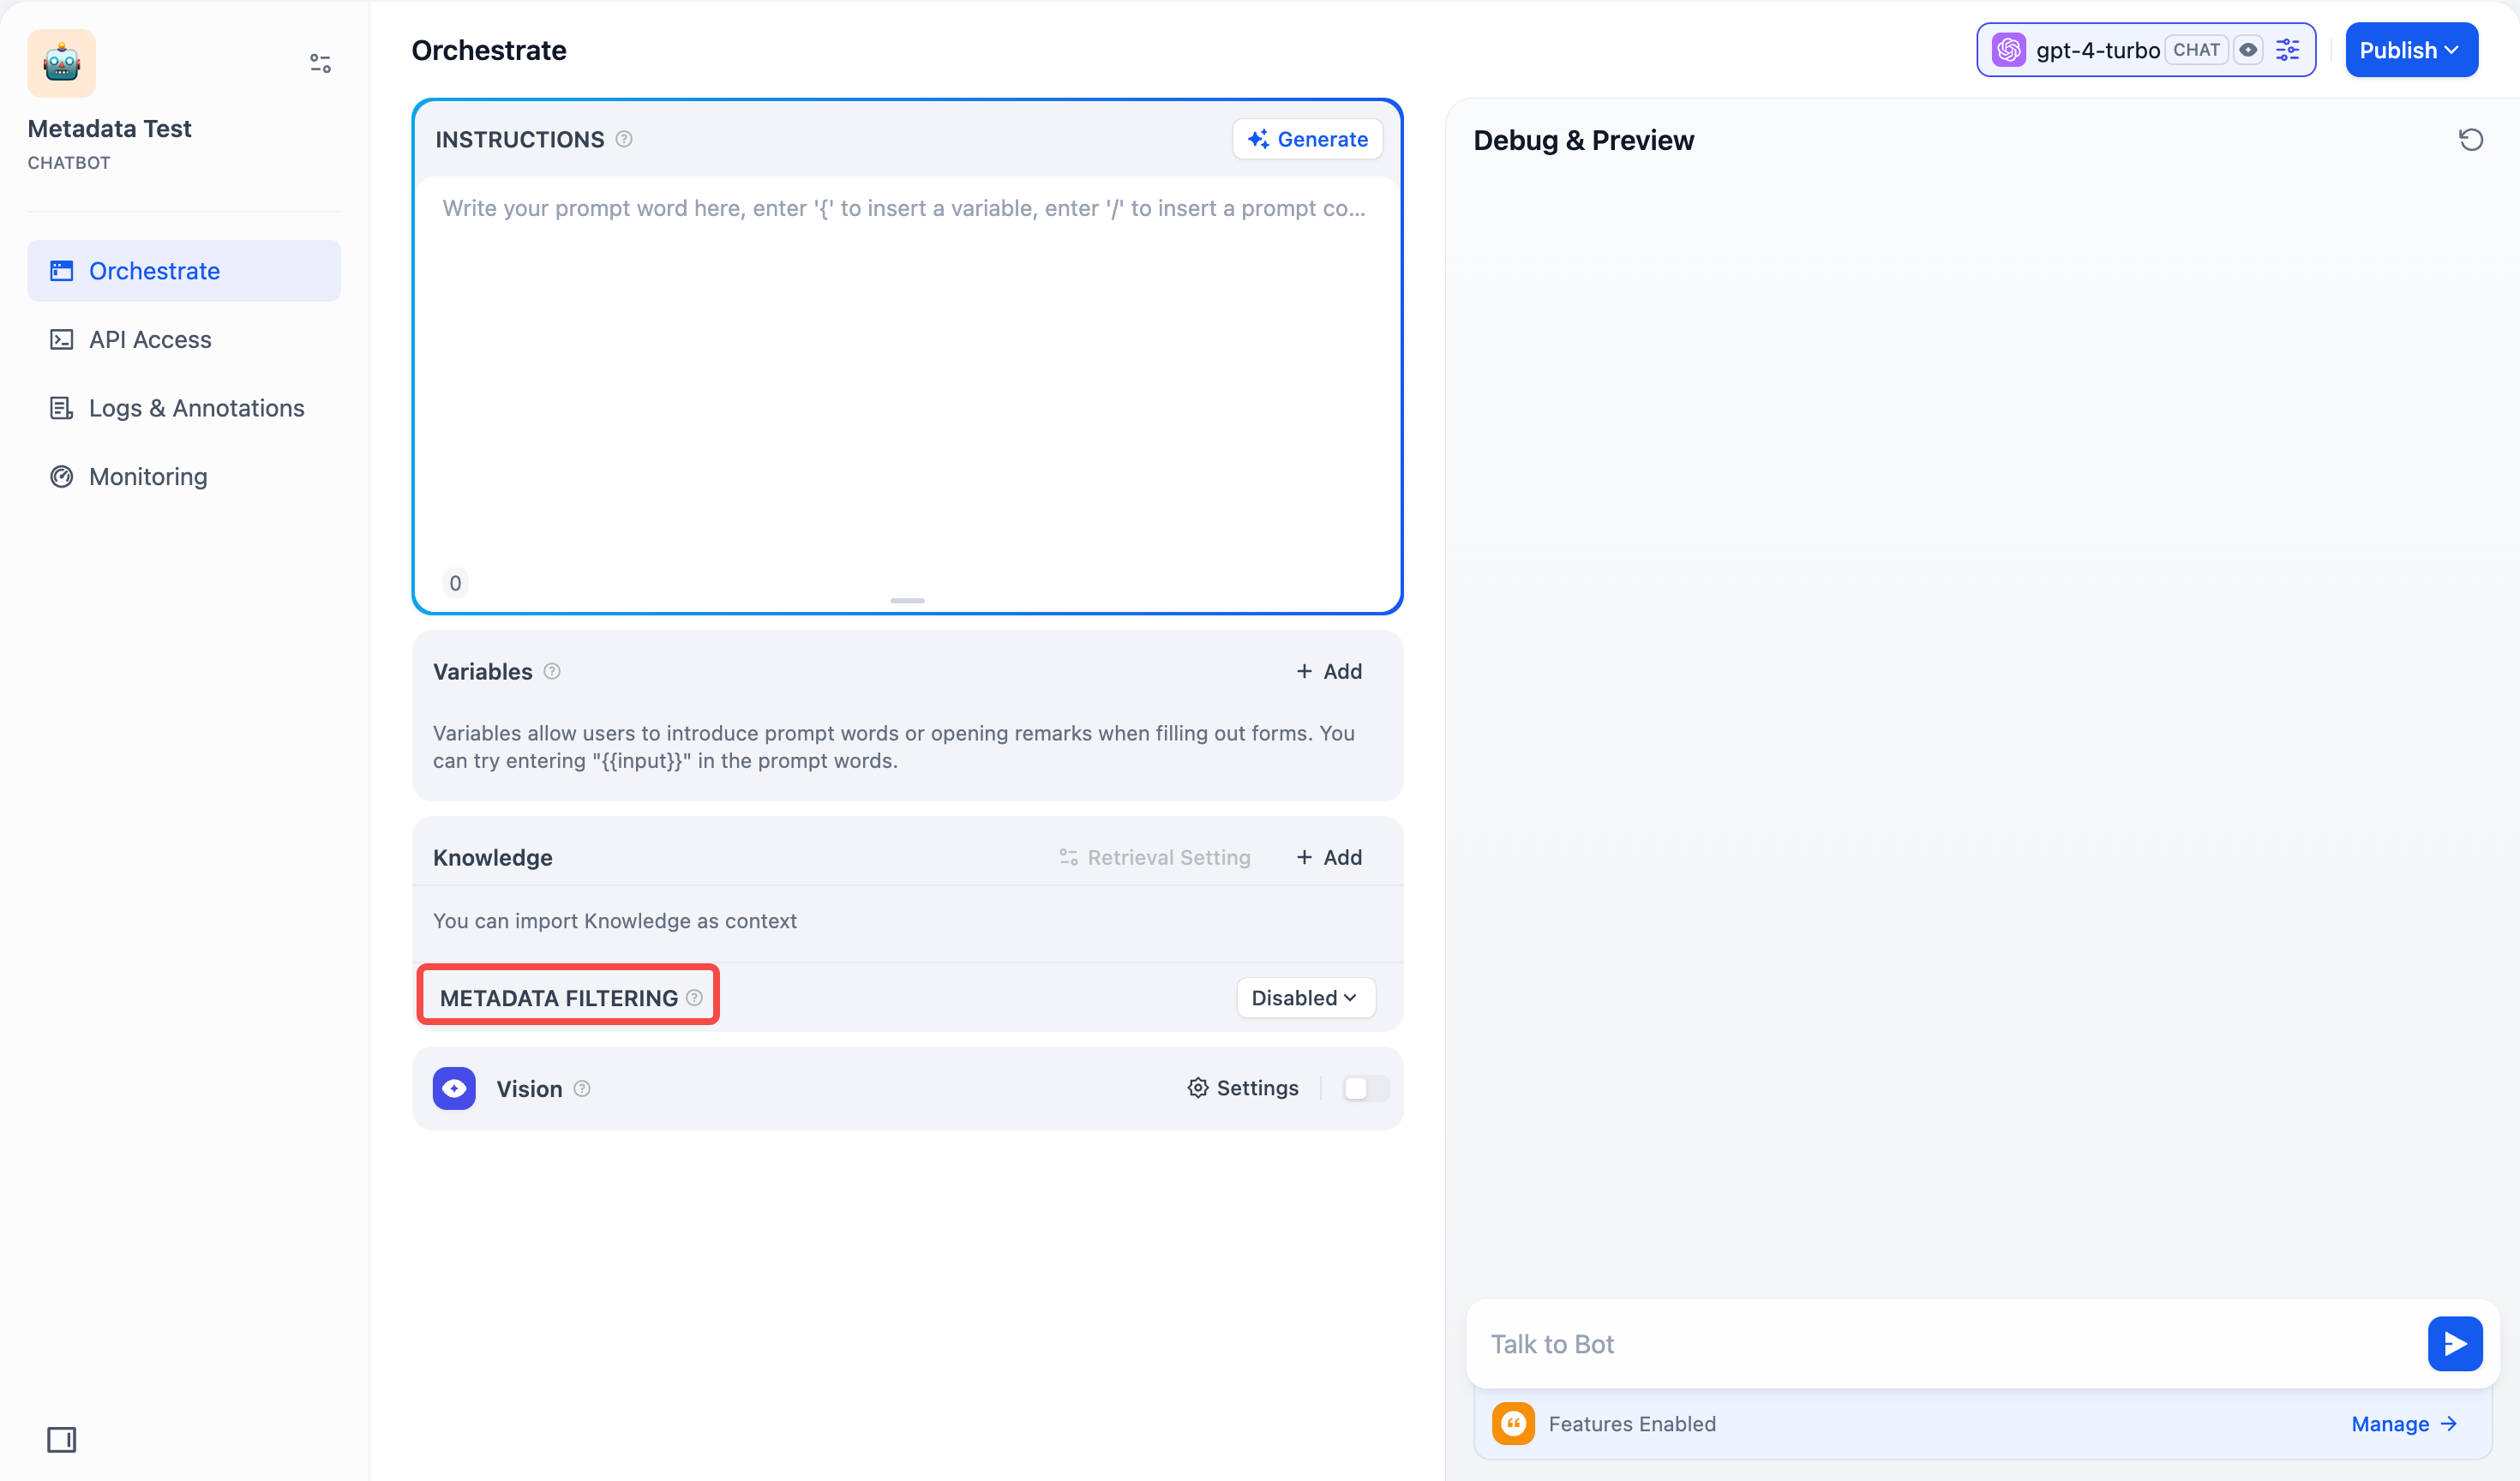
</Frame>
### View Linked Applications in the Knowledge Base
On the left side of the knowledge base, you can see all linked Apps. Hover over the circular icon to view the list of all linked apps. Click the jump button on the right to quickly browser them.
<Frame>
</Frame>
### Frequently Asked Questions
11. **How should I choose Rerank settings in multi-recall mode?**
If users know the exact information or terminology, you can use keyword search for precise matching. In that case, set **"Keywords" to 1** under Weight Settings.
If the knowledge base doesn't contain the exact terms or if a cross-lingual query is involved, we recommend setting **"Semantic" to 1** under Weight Settings.
If you are familiar with real user queries and want to adjust the ratio of semantics to keywords, they can manually tweak the ratio under **Weight Settings**.
If the knowledge base is complex, making simple semantic or keyword matches insufficient—and you need highly accurate answers and are willing to pay more—consider using a **Rerank Model** for content retrieval.
2. **What should I do if I encounter issues finding the "Weight Score" or the requirement to configure a Rerank model?**
Here's how the knowledge base retrieval method affects Multi-path Retrieval:
<Frame>
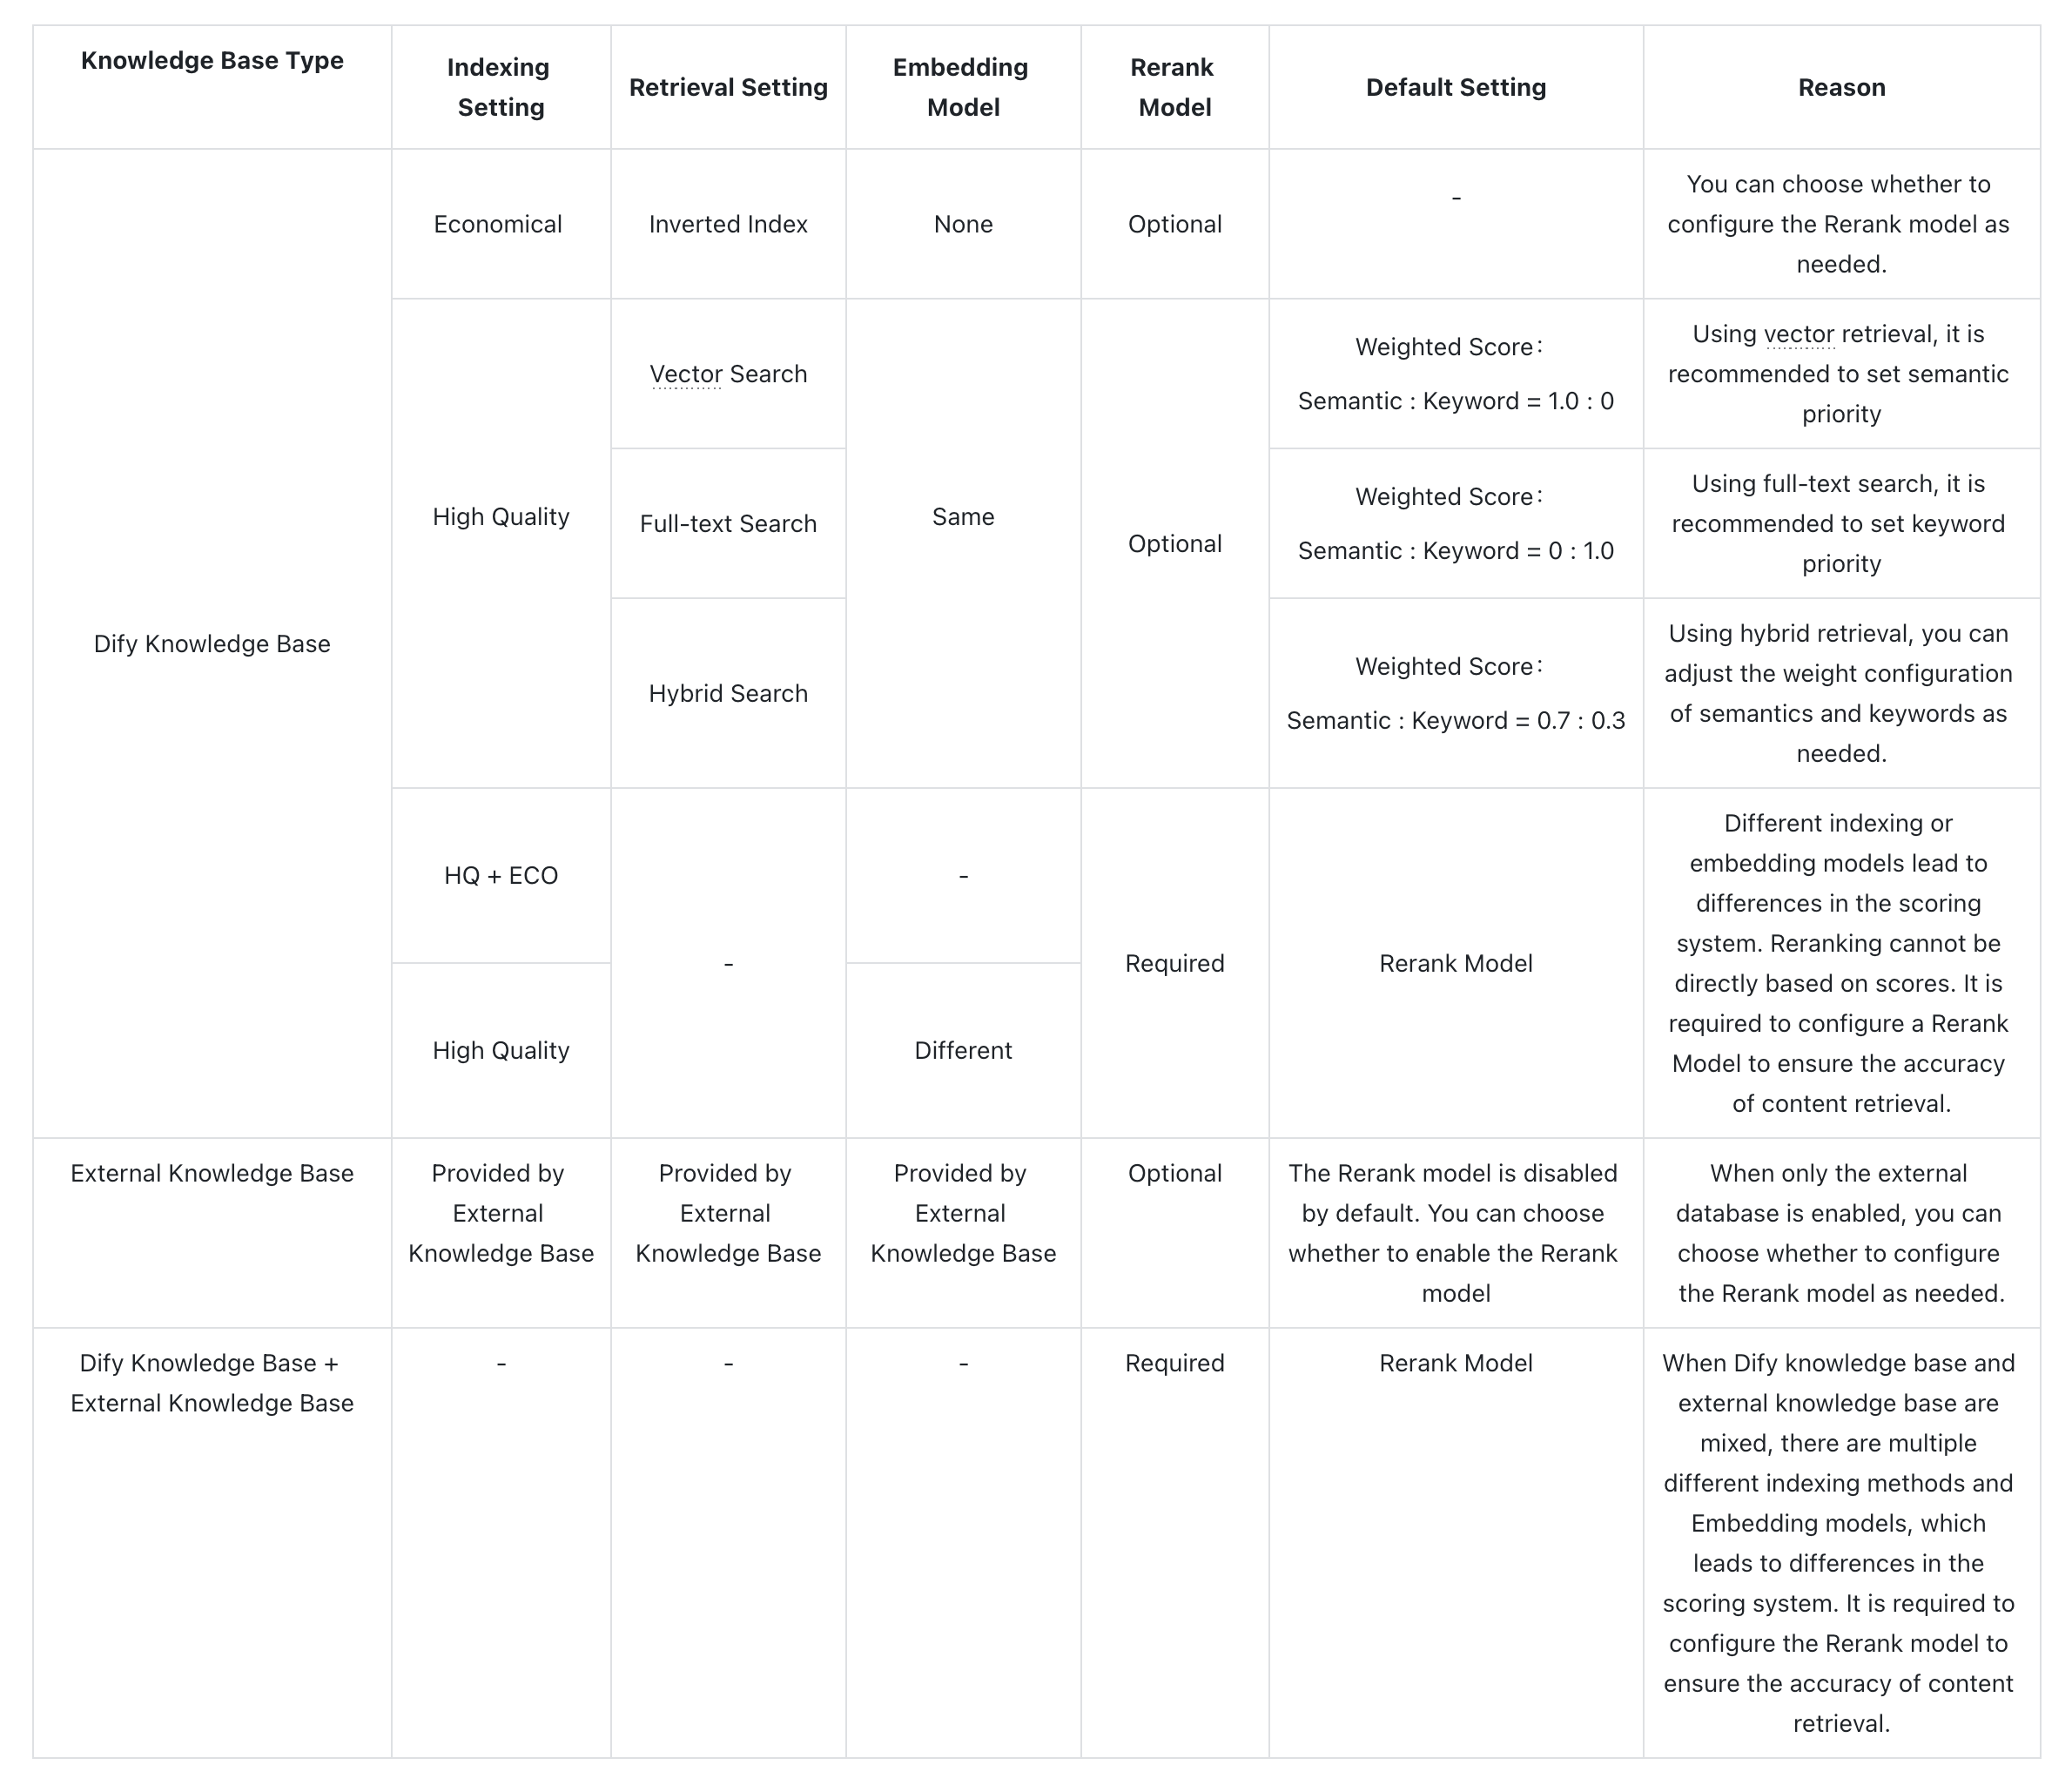
</Frame>
3. **What should I do if I cannot adjust the "Weight Score" when referencing multiple knowledge bases and an error message appears?**
This issue occurs because the embedding models used in the multiple referenced knowledge bases are inconsistent, prompting this notification to avoid conflicts in retrieval content. It is advisable to set and enable the Rerank model in the "Model Provider" or unify the retrieval settings of the knowledge bases.
4. **Why can't I find the "Weight Score" option in multi-recall mode, and only see the Rerank model?**
Please check whether your knowledge base is using the "Economical" index mode. If so, switch it to the "High Quality" index mode.
# Authorize Data Source
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/authorize-data-source
Dify supports connections to various external data sources. To ensure data security and access control, different data sources require appropriate authorization configurations. Dify provides two main authorization methods: **API Key** and **OAuth**.
## Access Data Source Authorization
In Dify, you can access data source authorization through the following two methods:
### I. Knowledge Pipeline Orchestration
When orchestrating a knowledge pipeline, select the data source node that requires authorization. Click **Connect** on the right panel.
<Frame>
<img alt="Knowledge Pipeline Authorization" />
</Frame>
### II. Settings
Click your avatar in the upper right corner and select **Settings**. Navigate to **Data Sources** and find the data source you wish to authorize.
<Frame>
<img alt="Settings Authorization" />
</Frame>
## Supported Data Source Authorization
| Data Source | API Key | OAuth |
| ------------ | ------- | ----- |
| Notion | ✅ | ✅ |
| Jina Reader | ✅ | |
| Firecrawl | ✅ | |
| Google Drive | | ✅ |
| Dropbox | | ✅ |
| OneDrive | | ✅ |
## Authorization Processes
### API Key Authorization
API Key authorization is a key-based authentication method suitable for enterprise-level services and developer tools. You need to generate API Keys from the corresponding service providers and configure them in Dify.
#### Process
1. On the **Data Source** page, navigate to the corresponding data source. Click **Configure** and then **Add API Key**.
<Frame>
<img alt="Add API Key" />
</Frame>
2. In the pop-up window, fill in the **Authorization Name** and **API Key**. Click **Save** to complete the setup.
<Frame>
<img alt="API Key Configuration" />
</Frame>
The API key will be securely encrypted. Once completed, you can start using the data source (e.g., Jina Reader) for knowledge pipeline orchestration.
<Frame>
<img alt="API Key Complete" />
</Frame>
### OAuth Authorization
OAuth is an open standard authorization protocol that allows users to authorize third-party applications to access their resources on specific service providers without exposing passwords.
#### Process
1. On the **Data Source** page, select an OAuth-supported data source. Click **Configure** and then **Add OAuth**.
<Frame>
<img alt="Add OAuth" />
</Frame>
2. Review the permission scope and click **Allow Access**.
<div>
<div>
<Frame>
<img alt="OAuth Permissions" />
</Frame>
</div>
<div>
<Frame>
<img alt="OAuth Allow" />
</Frame>
</div>
</div>
#### OAuth Client Settings
Authorize a data source with a custom OAuth client: register an OAuth application on the third-party platform, then provide its **Client ID** and **Client Secret** in Dify. This is especially useful when you have specific security or compliance requirements.
<Frame>
<img alt="OAuth Client Settings" />
</Frame>
**Process for Custom OAuth**
1. On the **Data Source** page, select an OAuth-supported data source. Click **Configure** and then the **Setting icon** on the right side of **Add OAuth**.
<Frame>
<img alt="Custom OAuth Settings" />
</Frame>
2. Choose **Custom**, enter the **Client ID** and **Client Secret**. Click **Save and Authorize** to complete the authorization.
<Frame>
<img alt="Custom OAuth Configuration" />
</Frame>
# Step 1: Create Knowledge Pipeline
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/create-knowledge-pipeline
Navigate to **Knowledge** at the top, then click **Create** > **Build a custom knowledge base**. There are three ways for you to get started.
### Build from Scratch
<Frame>
<img alt="Build from Scratch" />
</Frame>
Click Blank Knowledge Pipeline to build a custom pipeline from scratch. Choose this option when you need custom processing strategies based on specific data source and business requirements.
### Templates
Dify offers two types of templates: **Built-in Pipeline** and **Customized**. Both template cards display name of knowledge base, description, and tags (including chunk structure).
<Frame>
<img alt="Create Knowledge Pipeline 4 01" />
</Frame>
#### Built-in Pipeline
Built-in pipelines are official knowledge base templates pre-configured by Dify. These templates are optimized for common document structures and use cases. Simply click **Choose** to get started.
<Frame>
<img alt="Built-in Templates" />
</Frame>
**Types**
| Name | Chunk Structure | Index Method | Retrieval Setting | Description |
| ------------------- | ----------------- | ------------ | ------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| General Mode-ECO | General | Economical | Inverted Index | Divide document content into smaller paragraphs, directly used for matching user queries and retrieval. |
| Parent-child-HQ | Parent-Child | High Quality | Hybrid Search | Adopt advanced chunking strategy, dividing document text into larger parent chunks and smaller child chunks. The parent chunks contain child chunks which ensure both retrieval precision and maintain contextual integrity. |
| Simple Q\&A | Question & Answer | High Quality | Vector Search | Convert tabular data into question-answer format, using question matching to quickly hit corresponding answer information. |
| LLM Generated Q\&A | Question & Answer | High Quality | Vector Search | Generate structured question-answer pairs with large language models based on original text paragraphs. Find relevant answer by using question matching mechanism. |
| Convert to Markdown | Parent-child | High Quality | Hybrid Search - Weighted Score | Designed for Office native file formats such as DOCX, XLSX, and PPTX, converting them to Markdown format for better information processing. ⚠️ Note: PDF files are not recommended. |
To preview the selected built-in pipeline, click **Details** on any template card. Then, check information in the popup window, including: orchestration structure, pipeline description, and chunk structure. Click **Use this Knowledge Pipeline** for orchestration.
<Frame>
<img alt="Template Details" />
</Frame>
#### Customized
<Frame>
<img alt="Customized Templates" />
</Frame>
Customized templates are user-created and published knowledge pipeline. You can choose a template to start, export the DSL, or view detailed information for any template.
<Frame>
<img alt="Template Actions" />
</Frame>
To create a knowledge base from a template, click **Choose** on the template card. You can also create knowledge base by clicking **Use this Knowledge Pipeline** when previewing a template. Click **More** to edit pipeline information, export pipeline, or delete the template.
### Import Pipeline
<Frame>
<img alt="Import DSL" />
</Frame>
Import a pipeline of a previously exported knowledge pipeline to quickly reuse existing configurations and modify them for different scenarios or requirements. Navigate to the bottom left of the page and click **Import from a DSL File**. Dify DSL is a YAML-based standard that defines AI application configurations, including model parameters, prompt design, and workflow orchestration. Similar to workflow DSL, knowledge pipeline uses the same YAML format standard to define processing workflows and configurations within a knowledge base.
What's in a knowledge pipeline DSL:
| Name | Description |
| ----------------------- | ------------------------------------------------------------------ |
| Data Sources | Local files, websites, online documents, online drive, web crawler |
| Data Processing | Document extraction, content chunking, cleaning strategies |
| Knowledge Configuration | Indexing methods, retrieval settings, storage parameters |
| Node Orchestration | Arrangement and sequence |
| User Input Form | Custom parameter fields (if configured) |
# Step 2: Orchestrate Knowledge Pipeline
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/knowledge-pipeline-orchestration
Imagine setting up a factory production line where each station (node) performs a specific task, and you connect them to assemble widgets into a final product. This is knowledge pipeline orchestration—a visual workflow builder that allows you to configure data processing sequences through a drag-and-drop interface. It provides control over document ingestion, processing, chunking, indexing, and retrieval strategies.
In this section, you'll learn about the knowledge pipeline process, understand different nodes, how to configure them, and customize your own data processing workflows to efficiently manage and optimize your knowledge base.
### Interface Status
When entering the knowledge pipeline orchestration canvas, you’ll see:
* **Tab Status**: Documents, Retrieval Test, and Settings tabs will be grayed out and unavailable at the moment
* **Essential Steps**: You must complete knowledge pipeline orchestration and publishing before uploading files
Your starting point depends on the template choice you made previously. If you chose **Blank Knowledge Pipeline**, you'll see a canvas that contains Knowledge Base node only. There'll be a note with guide next to the node that walks you through the general steps of pipeline creation.
<Frame>
<img alt="Blank Pipeline" />
</Frame>
If you selected a specific pipeline template, there'll be a ready-to-use workflow that you can use or modify on the canvas right away.
<Frame>
<img alt="Template Pipeline" />
</Frame>
## The Complete Knowledge Pipeline Process
Before we get started, let's break down the knowledge pipeline process to understand how your documents are transformed into a searchable knowledge base.
The knowledge pipeline includes these key steps:
<Tip>
Data Source → Data Processing (Extractor + Chunker) → Knowledge Base Node (Chunk Structure + Retrieval Setting) → User Input Field → Test & Publish
</Tip>
1. **Data Source**: Content from various data sources (local files, Notion, web pages, etc.)
2. **Data Processing**: Process and transform data content
* Extractor: Parse and structure document content
* Chunker: Split structured content into manageable segments
3. **Knowledge Base**: Set up chunk structure and retrieval settings
4. **User Input Field**: Define parameters that pipeline users need to input for data processing
5. **Test & Publish**: Validate and officially activate the knowledge base
***
## Step 1: Data Source
In a knowledge base, you can choose single or multiple data sources. Currently, Dify supports 4 types of data sources: **file upload, online drive, online documents, and web crawler**.
Visit the [Dify Marketplace](https://marketplace.dify.ai) for more data sources.
### File Upload
Upload local files through drag-and-drop or file selection.
<div>
<div>
<Frame>
<img alt="Knowledge Pipeline Orchestration 01" />
</Frame>
</div>
<div>
**Configuration Options**
| Item | Description |
| ------------- | ------------------------------------------------------------------------------------------------- |
| File Format | Support PDF, XLSX, DOCX, etc. Users can customize their selection |
| Upload Method | Upload local files or folders through drag-and-drop or file selection. Batch upload is supported. |
**Limitations**
| Item | Description |
| ------------- | ---------------------------------------------------------------- |
| File Quantity | Default 20 files per upload |
| File Size | Default 15MB per file; configurable via `UPLOAD_FILE_SIZE_LIMIT` |
| Storage | Bound only by the storage backend you configure |
**Output Variables**
| Output Variable | Format |
| --------------- | --------------- |
| `{x} Document` | Single document |
</div>
</div>
***
### Online Document
#### Notion
Integrate with your Notion workspace to seamlessly import pages and databases, always keeping your knowledge base automatically updated.
<div>
<div>
<Frame>
<img alt="Notion" />
</Frame>
</div>
<div>
**Configuration Options**
| Item | Option | Output Variable | Description |
| --------- | -------- | --------------- | ------------------------------------ |
| Extractor | Enabled | `{x} Content` | Structured and processed information |
| | Disabled | `{x} Document` | Original text |
</div>
</div>
***
### Web Crawler
Transform web content into formats that can be easily read by large language models. The knowledge base supports Jina Reader and Firecrawl.
#### Jina Reader
An open-source web parsing tool providing simple and easy-to-use API services, suitable for fast crawling and processing web content.
<div>
<div>
<Frame>
<img alt="Jina Reader" />
</Frame>
</div>
<div>
**Parameter Configuration**
| Parameter | Type | Description |
| ---------------- | -------- | ------------------------------------ |
| URL | Required | Target webpage address |
| Crawl sub-page | Optional | Whether to crawl linked pages |
| Use sitemap | Optional | Crawl by using website sitemap |
| Limit | Required | Set maximum number of pages to crawl |
| Enable Extractor | Optional | Choose data extraction method |
</div>
</div>
#### Firecrawl
An open-source web parsing tool that provides more refined crawling control options and API services. It supports deep crawling of complex website structures, recommended for batch processing and precise control.
<div>
<div>
<Frame>
<img alt="Knowledge Pipeline Orchestration 04" />
</Frame>
</div>
<div>
**Parameter Configuration**
| Parameter | Type | Description |
| ------------------------- | -------- | -------------------------------------------------------------------------- |
| URL | Required | Target webpage address |
| Limit | Required | Set maximum number of pages to crawl |
| Crawl sub-page | Optional | Whether to crawl linked pages |
| Max depth | Optional | How many levels deep the crawler will traverse from the starting URL |
| Exclude paths | Optional | Specify URL patterns that should not be crawled |
| Include only paths | Optional | Crawl specified paths only |
| Extractor | Optional | Choose data processing method |
| Extract Only Main Content | Optional | Isolate and retrieve the primary, meaningful text and media from a webpage |
</div>
</div>
***
### Online Drive
Connect your online cloud storage services (e.g., Google Drive, Dropbox, OneDrive) and let Dify automatically retrieve your files. Simply select and import the documents you need for processing, without manually downloading and re-uploading files.
<Tip>
Need help with authorization? Please check [Authorize Data Source](/en/self-host/use-dify/knowledge/knowledge-pipeline/authorize-data-source) for detailed guidance on authorizing different data sources.
</Tip>
***
## Step 2: Set Up Data Processing Tools
In this stage, these tools extract, chunk, and transform the content for optimal knowledge base storage and retrieval. Think of this step like meal preparation. We clean raw materials up, chop them into bite-sized pieces, and organize everything, so the dish can be cooked up quickly when someone orders it.
<Tip>
To develop a custom data processing plugin that extracts multimodal data for multimodal embedding and retrieval, see [Build Tool Plugins for Multimodal Data Processing in Knowledge Pipelines](/en/develop-plugin/dev-guides-and-walkthroughs/develop-multimodal-data-processing-tool).
</Tip>
### Doc Processor
Documents come in different formats - PDF, XLSX, DOCX. However, LLM can't read these files directly. That's where extractors come in. They support multiple formats and handle the conversion, so your content is ready for the next step of the LLMs.
You can choose Dify's Doc Extractor to process files, or select tools based on your needs from Marketplace which offers Dify Extractor and third-party tools such as Unstructured.
<Accordion title="For images in documents">
Images in documents can be extracted using appropriate document processors. Extracted images are attached to their corresponding chunks, can be managed independently, and are returned alongside those chunks during retrieval.
URLs of extracted images remain in the chunk text, but you can safely remove these URLs to keep the text clean—this won't affect the extracted images.
Each chunk supports up to 10 image attachments; images beyond this limit will not be extracted.
If no images are extracted by the selected processor, Dify will automatically extract JPG, JPEG, PNG, and GIF images under 2 MB that are referenced via accessible URLs using the following Markdown syntax:
* ``
* ``
<Tip>
Adjust these limits via environment variables:
* Maximum image size: `ATTACHMENT_IMAGE_FILE_SIZE_LIMIT`
* Maximum number of attachments per chunk: `SINGLE_CHUNK_ATTACHMENT_LIMIT`
</Tip>
If you select a multimodal embedding model (marked with a **Vision** icon) in index settings, the extracted images will also be embedded and indexed for retrieval.
</Accordion>
#### Doc Extractor
<Frame>
<img alt="Knowledge Pipeline Orchestration 4 01" />
</Frame>
As an information processing center, document extractor node identifies and reads files from input variables, extracts information, and finally converts them into a format that works with the next node.
<Tip>
For more information, please refer to the [Document Extractor](/en/self-host/use-dify/nodes/doc-extractor).
</Tip>
#### Dify Extractor
Dify Extractor is a built-in document parser presented by Dify. It supports multiple common file formats and is specially optimized for Doc files. It can extract and store images from documents and return image URLs.
<Frame>
<img alt="Dify Extractor" />
</Frame>
#### Unstructured
<div>
<div>
<Frame>
<img alt="Unstructured" />
</Frame>
</div>
<div>
[Unstructured](https://marketplace.dify.ai/plugin/langgenius/unstructured) transforms documents into structured, machine-readable formats with highly customizable processing strategies. It offers multiple extraction strategies (auto, hi\_res, fast, OCR-only) and chunking methods (by\_title, by\_page, by\_similarity) to handle diverse document types, offering detailed element-level metadata including coordinates, confidence scores, and layout information. It's recommended for enterprise document workflows, processing of mixed file types, and cases that require precise control over document processing parameters.
</div>
</div>
<Tip>
Explore more tools in the [Dify Marketplace](https://marketplace.dify.ai).
</Tip>
***
### Chunker
Similar to human limited attention span, large language models cannot process huge amount of information simultaneously. Therefore, after information extraction, the chunker splits large document content into smaller and manageable segments (called "chunks").
Different documents require different chunking strategies. A product manual works best when split by product features, while research papers should be divided by logical sections. Dify offers 3 types of chunkers for various document types and use cases.
#### Overview of Different Chunkers
| Chunker Type | Highlights | Best for |
| -------------------- | ----------------------------------------------------- | ----------------------------------------------------- |
| General Chunker | Fixed-size chunks with customizable delimiters | Simple documents with basic structure |
| Parent-child Chunker | Dual-layer structure: precise matching + rich context | Complex documents requiring rich context preservation |
| Q\&A Processor | Processes question-answer pairs from spreadsheets | Structured Q\&A data from CSV/Excel files |
#### Common Text Pre-processing Rules
All chunkers support these text cleaning options:
| Preprocessing Option | Description |
| --------------------------------------------- | ---------------------------------------------------------------------------------- |
| Replace consecutive spaces, newlines and tabs | Clean up formatting by replacing multiple whitespace characters with single spaces |
| Remove all URLs and email addresses | Automatically detect and remove web links and email addresses from text |
#### General Chunker
Basic document chunking processing, suitable for documents with relatively simple structures. You can configure text chunking and text preprocessing rules according to the following configuration.
**Input and Output Variable**
| Type | Variable | Description |
| --------------- | ------------------ | --------------------------------------------------------------------------- |
| Input Variable | `{x} Content` | Complete document content that the chunker will split into smaller segments |
| Output Variable | `{x} Array[Chunk]` | Array of chunked content, each segment optimized for retrieval and analysis |
**Chunk Settings**
| Configuration Item | Description |
| -------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Delimiter | Default value is `\n` (line breaks for paragraph segmentation). You can customize chunking rules following regex. The system will automatically execute segmentation when the delimiter appears in text. |
| Maximum Chunk Length | Specifies the maximum character limit within a segment. When this length is exceeded, forced segmentation will occur. |
| Chunk Overlap | When segmenting data, there is some overlap between segments. This overlap helps improve information retention and analysis accuracy, enhancing recall effectiveness. |
#### Parent-child Chunker
By using a dual-layer segmentation structure to resolve the contradiction between context and accuracy, parent-child clunker achieves the balance between precise matching and comprehensive contextual information in Retrieval Augmented Generation (RAG) systems.
**How Parent-child Chunker Works**
Child Chunks for query matching: Small, precise information segments (usually single sentences) to match user queries with high accuracy.
Parent Chunks provide rich context: Larger content blocks (paragraphs, sections, or entire documents) that contain the matching child chunks, giving the large language model (LLM) comprehensive background information.
| Type | Variable | Description |
| --------------- | ------------------------ | --------------------------------------------------------------------------- |
| Input Variable | `{x} Content` | Complete document content that the chunker will split into smaller segments |
| Output Variable | `{x} Array[ParentChunk]` | Array of parent chunks |
**Chunk Settings**
| Configuration Item | Description |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------- |
| Parent Delimiter | Set delimiter for parent chunk splitting |
| Parent Maximum Chunk Length | Set maximum character count for parent chunks |
| Child Delimiter | Set delimiter for child chunk splitting |
| Child Maximum Chunk Length | Set maximum character count for child chunks |
| Parent Mode | Choose between Paragraph (split text into paragraphs) or "Full Document" (use entire document as parent chunk) for direct retrieval |
#### Q\&A Processor
Combining extraction and chunking in one node, Q\&A Processor is specifically designed for structured Q\&A datasets from CSV and Excel files. Perfect for FAQ lists, shift schedules, and any spreadsheet data with clear question-answer pairs.
**Input and Output Variable**
| Type | Variable | Description |
| --------------- | -------------------- | ------------- |
| Input Variable | `{x} Document` | A single file |
| Output Variable | `{x} Array[QAChunk]` | QA chunk |
**Variable Configuration**
| Configuration Item | Description |
| -------------------------- | ------------------------------ |
| Column Number for Question | Set content column as question |
| Column Number for Answer | Set column answer as answer |
***
## Step 3: Configure Knowledge Base Node
Now that your documents are processed and chunked, it's time to set up how they'll be stored and retrieved. Here, you can select different indexing methods and retrieval strategies based on your specific needs.
Knowledge base node configuration includes: Input Variable, Chunk Structure, Index Method, and Retrieval Settings.
### Chunk Structure
<Frame>
<img alt="Chunk Structure" />
</Frame>
Chunk structure determines how the knowledge base organizes and indexes your document content. Choose the structure mode that best fits your document type, use case, and cost.
The knowledge base supports three chunk modes: **General Mode, Parent-child Mode, and Q\&A Mode**. If you're creating a knowledge base for the first time, we recommend choosing Parent-child Mode.
<Warning>
**Important Reminder**: Chunk structure cannot be modified once saved and published. Please choose carefully.
</Warning>
#### General Mode
Suitable for most standard document processing scenarios. It provides flexible indexing options—you can choose appropriate indexing methods based on different quality and cost requirements.
General mode supports both high-quality and economical indexing methods, as well as various retrieval settings.
#### Parent-child Mode
It provides precise matching and corresponding contextual information during retrieval, suitable for professional documents that need to maintain complete context.
Parent-child mode supports HQ (High Quality) mode only, offering child chunks for query matching and parent chunks for contextual information during retrieval.
#### Q\&A Mode
Create documents that pair questions with answers when using structured question-answer data. These documents are indexed based on the question portion, enabling the system to retrieve relevant answers based on query similarity.
Q\&A Mode supports HQ (High Quality) mode only.
### Input Variable
Input variables receive processing results from data processing nodes as the data source for knowledge base. You need to connect the output from chunker to the knowledge base as input.
The node supports different types of standard inputs based on the selected chunk structure:
* **General Mode**: x Array\[Chunk] - General chunk array
* **Parent-child Mode**: x Array\[ParentChunk] - Parent chunk array
* **Q\&A Mode**: x Array\[QAChunk] - Q\&A chunk array
### Index Method & Retrieval Settings
The index method determines how your knowledge base builds content indexes, while retrieval settings provide corresponding retrieval strategies based on the selected index method.
Think of it in this way: the index method determines how to organize your documents, while retrieval settings tell users what methods they can use to find documents.
The knowledge base provides two index methods: **High Quality** and **Economical**, each offering different retrieval setting options.
The High Quality method uses embedding models to convert chunks into numerical vectors, helping to compress and store large amounts of information more effectively. This enables the system to find semantically relevant accurate answers even when the user's question wording doesn't exactly match the document.
<Tip>
To enable cross-modal retrieval—retrieving both text and images based on semantic relevance—select a multimodal embedding model (marked with a **Vision** icon). Images extracted from documents will then be embedded and indexed for retrieval.
Knowledge bases using such embedding models are labeled **Multimodal** on their cards.
<Frame>
<img alt="Multimodal Knowledge Base" />
</Frame>
</Tip>
In the Economical method, each block uses 10 keywords for retrieval without calling embedding models, generating no costs.
<Info>
For more details, see [Specify the Index Method and Retrieval Settings](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods).
</Info>
| Index Method | Available Retrieval Settings | Description |
| ------------ | ---------------------------- | ----------------------------------------------------------------------- |
| High Quality | Vector Retrieval | Understand deeper meaning of queries based on semantic similarity |
| | Full-text Retrieval | Keyword-based retrieval providing comprehensive search capabilities |
| | Hybrid Retrieval | Combine both semantic and keywords |
| Economical | Inverted Index | Common search engine retrieval method, matches queries with key content |
<Note>
If the selected embedding model is multimodal, select a multimodal rerank model (marked with a **Vision** icon) as well. Otherwise, retrieved images will be excluded from reranking and the retrieval results.
</Note>
You can also refer to the table below for information on configuring chunk structure, index methods, parameters, and retrieval settings.
| Chunk Structure | Index Methods | Parameters | Retrieval Settings |
| ----------------- | -------------------------------------------- | ------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
| General mode | High Quality <br /> <br /> <br /> Economical | Embedding Model <br /> <br /> <br /> Number of Keywords | Vector Retrieval <br /> Full-text Retrieval <br /> Hybrid Retrieval <br /> Inverted Index |
| Parent-child Mode | High Quality Only | Embedding Model | Vector Retrieval <br /> Full-text Retrieval <br /> Hybrid Retrieval |
| Q\&A Mode | High Quality Only | Embedding Model | Vector Retrieval <br /> Full-text Retrieval <br /> Hybrid Retrieval |
### Summary Auto-Gen
Automatically generate summaries for all chunks to enhance their retrievability.
Summaries are embedded and indexed for retrieval as well. When a summary matches a query, its corresponding chunk is also returned.
You can manually edit auto-generated summaries or regenerate them for specific documents later. See [Manage Knowledge Content](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents) for details.
<Tip>
If you select a vision-capable LLM, summaries will be generated based on both the chunk text and any attached images.
</Tip>
***
## Step 4: Create User Input Form
User input forms are essential for collecting the initial information your pipeline needs to run effectively. Similar to [the User Input node](/en/self-host/use-dify/nodes/user-input) in workflow, this form gathers necessary details from users - such as files to upload, specific parameters for document processing - ensuring your pipeline has all the information it needs to deliver accurate results.
This way, you can create specialized input forms for different use scenarios, improving pipeline flexibility and usability for various data sources or document processing steps.
### Create User Input Form
There're two ways to create user input field:
1. **Pipeline Orchestration Interface**\
Click on the **Input field** to start creating and configuring input forms.\\
<Frame>
<img alt="" />
</Frame>
2. **Node Parameter Panel**\
Select a node. Then, in parameter input on the right-side panel, click + Create user input for new input items. New input items will also be collected in the Input Field. !\[Node Parameter Panel]\(/images/use-dify/knowledge/knowledge-pipeline-orchestration-10.png)
### Add User Input Fields
#### Unique Inputs for Each Entrance
<Frame>
<img alt="Knowledge Pipeline Orchestration 11" />
</Frame>
These inputs are specific to each data source and its downstream nodes. Users only need to fill out these fields when selecting the corresponding data source, such as different URLs for different data sources.
**How to create**: Click the `+` button on the right side of a data source to add fields for that specific data source. These fields can only be referenced by that data source and its subsequently connected nodes. <img alt="These Inputs Are Specific to Each Data Source and Its Downstream Nodes" />
#### Global Inputs for All Entrances
<Frame>
<img alt="Knowledge Pipeline Orchestration 13" />
</Frame>
Global shared inputs can be referenced by all nodes. These inputs are suitable for universal processing parameters, such as delimiters, maximum chunk length, document processing configurations, etc. Users need to fill out these fields regardless of which data source they choose.
**How to create**: Click the `+` button on the right side of Global Inputs to add fields that can be referenced by any node.
### Supported Input Field Types
The knowledge pipeline supports seven types of input variables:
<div>
<div>
<Frame>
<img alt="Knowledge Pipeline Orchestration 14" />
</Frame>
</div>
<div>
| Field Type | Description |
| ---------- | --------------------------------------------------------------------------------------------------- |
| Text | Short text input by knowledge base users, maximum length 256 characters |
| Paragraph | Long text input for longer character strings |
| Select | Fixed options preset by the orchestrator for users to choose from, users cannot add custom content |
| Boolean | Only true/false values |
| Number | Only accepts numerical input |
| Single | Upload a single file, supports multiple file types (documents, images, audio, and other file types) |
| File List | Batch file upload, supports multiple file types (documents, images, audio, and other file types) |
</div>
</div>
<Tip>
For more information about supported field types, see [User Input](/en/self-host/use-dify/nodes/user-input).
</Tip>
### Field Configuration Options
All input field types include: required, optional, and additional settings. You can set whether fields are required by checking the appropriate option.
| Setting | Name | Description | Example |
| ------------------------- | ------------- | ----------------------------------------------------------------------- | -------------------------------------------------------- |
| Required Settings | Variable Name | Internal system identifier, usually named using English and underscores | `user_email` |
| | Display Name | Interface display name, usually concise and readable text | User Email |
| Type-specific Settings | | Special requirements for different field types | Text field max length 100 characters |
| Additional Settings | Default Value | Default value when user hasn't provided input | Number field defaults to 0, text field defaults to empty |
| | Placeholder | Hint text displayed when input box is empty | "Please enter your email" |
| | Tooltip | Explanatory text to guide user input, usually displayed on mouse hover | "Please enter a valid email address" |
| Special Optional Settings | | Additional setting options based on different field types | Validation of email format |
After completing configuration, click the preview button in the upper right corner to browse the form preview interface. You can drag and adjust field groupings. If an exclamation mark appears, it indicates that the reference is invalid after moving.
<Frame>
<img alt="Knowledge Pipeline Orchestration 15" />
</Frame>
***
## Step 5: Name the Knowledge Base
<Frame>
<img alt="Name Knowledge Base" />
</Frame>
By default, the knowledge base name will be "Untitled + number", permissions are set to "Only me", and the icon will be an orange book. If you import it from a DSL file, it will use the saved icon.
Edit knowledge base information by clicking **Settings** in the left panel and fill in the information below:
* **Name & Icon**\
Pick a name for your knowledge base.\
Choose an emoji, upload an image, or paste an image URL as the icon of this knowledge base.
* **Knowledge Description**\
Provide a brief description of your knowledge base. This helps the AI better understand and retrieve your data. If left empty, Dify will apply the default retrieval strategy.
* **Permissions**\
Select the appropriate access permissions from the dropdown menu.
***
## Step 6: Testing
You're almost there! This is the final step of the knowledge pipeline orchestration.
After completing the orchestration, you need to validate all the configuration first. Then, do some running tests and confirm all the settings. Finally, publish the knowledge pipeline.
### Configuration Completeness Check
Before testing, it's recommended to check the completeness of your configuration to avoid test failures due to missing configurations.
Click the checklist button in the upper right corner, and the system will display any missing parts.
<Frame>
<img alt="Knowledge Pipeline Orchestration 16" />
</Frame>
After completing all configurations, you can preview the knowledge base pipeline's operation through test runs, confirm that all settings are accurate, and then proceed with publishing.
### Test Run
<Frame>
<img alt="Knowledge Pipeline Orchestration 17" />
</Frame>
1. **Start Test**: Click the "Test Run" button in the upper right corner
2. **Import Test File**: Import files in the data source window that pops up on the right
<Warning>
**Important Note**: For better debugging and observation, only one file upload is allowed per test run.
</Warning>
3. **Fill Parameters**: After successful import, fill in corresponding parameters according to the user input form you configured earlier
4. **Start Test Run**: Click next step to start testing the entire pipeline
During testing, you can access [History Logs](/en/self-host/use-dify/monitor/logs) (track all run records with timestamps, execution status, and input/output summaries) and [Variable Inspector](/en/self-host/use-dify/debug/variable-inspect) (a dashboard at the bottom showing input/output data for each node to help identify issues and verify data flow) for efficient troubleshooting and error fixing.
<Frame>
<img alt="Testing Tools" />
</Frame>
# Step 5: Manage and Use Knowledge Base
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/manage-knowledge-base
After creating your knowledge base, continuous management and optimization will provide accurate contextual information for your applications. These are the options for follow-up maintenance.
### Knowledge Pipeline
View and modify your orchestrated pipeline nodes and configurations.
<Tip>
Find more information in [Manage Knowledge](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents).
</Tip>
<Frame>
<img alt="Knowledge Management" />
</Frame>
# Step 3: Publish Knowledge Pipeline
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/publish-knowledge-pipeline
After completing pipeline orchestration and debugging, click **Publish** and **Confirm** in the pop-up window.
<div>
<div>
<Frame>
<img alt="Publish Confirmation" />
</Frame>
</div>
<div>
<Frame>
<img alt="Publish Success" />
</Frame>
</div>
</div>
<Warning>
Important reminder: Once published, the chunk structure cannot be modified.
</Warning>
<div>
<div>
<Frame>
<img alt="Publish Complete" />
</Frame>
</div>
<div>
Once it is published, you can:<br /><br />
**Add Documents (Go to add documents)**\
Click this option to jump to the knowledge base data source selection interface, where you can directly upload documents.<br /><br />
**Access API (Access API Reference)**\
Go to the API documentation page where you can get the knowledge base API calling methods and instructions.<br /><br />
**Publish as a Knowledge Pipeline**\
Optionally use **Publish as a Knowledge Pipeline** to save it as a reusable template that will appear in the Customized section for future use.
</div>
</div>
# Build a Custom Knowledge Base
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/readme
To build a custom knowledge base, you design a knowledge pipeline. A knowledge pipeline is a document processing workflow that transforms raw data into searchable knowledge bases. As with orchestrating a workflow, you can visually combine and configure different processing nodes and tools to optimize data processing for better accuracy and relevance.
Every knowledge pipeline normally follows a structured flow through four key steps:
**Data Sources → Data Extraction → Data Processing → Knowledge Storage**
Each step serves a specific purpose: gathering content from various sources, converting it to processable text, refining it for search, and storing it in a format that enables fast, accurate retrieval.
Dify provides built-in pipeline templates that is optimized for certain use cases, or you can also create knowledge pipelines from scratch. In this session, we will go through creating options, general process of building knowledge pipelines, and how to manage it.
<Steps>
<Step>
<Card title="Step 1: Create Knowledge Pipeline" href="/en/self-host/use-dify/knowledge/knowledge-pipeline/create-knowledge-pipeline">
Start from built-in templates, blank knowledge pipeline or import existing pipeline.
</Card>
</Step>
<Step>
<Card title="Step 2: Orchestrate Knowledge Pipeline" href="/en/self-host/use-dify/knowledge/knowledge-pipeline/knowledge-pipeline-orchestration">
Get to know how the knowledge pipeline works, orchestrate different nodes and make sure it’s ready to use.
</Card>
</Step>
<Step>
<Card title="Step 3: Publish Knowledge Pipeline" href="/en/self-host/use-dify/knowledge/knowledge-pipeline/publish-knowledge-pipeline">
Let's make it ready for document processing.
</Card>
</Step>
<Step>
<Card title="Step 4: Upload Files" href="/en/self-host/use-dify/knowledge/knowledge-pipeline/upload-files">
Add documents and process them into the searchable knowledge base.
</Card>
</Step>
<Step>
<Card title="Step 5: Manage and Use Knowledge Base" href="/en/self-host/use-dify/knowledge/knowledge-pipeline/manage-knowledge-base">
Maintain documents, test retrieval, modify settings, and more.
</Card>
</Step>
</Steps>
# Step 4: Upload Files
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/knowledge-pipeline/upload-files
After publishing knowledge pipeline, there're two ways to upload files as below:
A: Click **Go to Documents** in the success notification to add or manage documents. After entering Documents page, click **Add File** to upload.
<div>
<div>
<Frame>
<img alt="Option A-1" />
</Frame>
</div>
<div>
<Frame>
<img alt="Option A-2" />
</Frame>
</div>
</div>
B: Click **Go to Add Documents** to add documents.
<div>
<div>
<Frame>
<img alt="Option B-1" />
</Frame>
</div>
<div>
<Frame>
<img alt="Option B-2" />
</Frame>
</div>
</div>
### Upload Process
1. **Select Data Source**\
Choose from the data source types configured in your pipeline. Dify currently supports 4 types of data sources: File Upload (pdf, docx, etc.), Online Drive (Google Drive, OneDrive, etc.), Online Doc (Notion), and Web Crawler (Jina Reader, Firecrawl).
Please visit [Dify Marketplace](https://marketplace.dify.ai/) to install additional data sources.
2. **Fill in Processing Parameters and Preview**\
If you configured user input fields during pipeline orchestration, users will need to fill in the required parameters and variables at this step. After completing the form, click **Preview** to see chunking results. Click **Save & Process** to complete knowledge base creation and start data processing.
<Warning>
Important reminder: Chunk structure remains consistent with the pipeline configuration and won't change with user input parameters.
</Warning>
<Frame>
<img alt="Parameter Input" />
</Frame>
3. **Process Documents**\
Track the progress of document processing. After embedding is completed, click **Go to Document**.
<Frame>
<img alt="Processing Progress" />
</Frame>
4. **Access Documents List**\
Click **Go to Documents** to view the Documents page, where you can browse all uploaded file, processing status, etc.
<Frame>
<img alt="Documents List" />
</Frame>
# Manage Knowledge Settings
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/manage-knowledge/introduction
<Info>
Only the workspace owner, administrators, and editors can modify the knowledge base settings.
</Info>
In a knowledge base, click the **Settings** icon in the left sidebar to enter its settings page.
| Settings | Description |
| :----------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Name & Icon | Identifies the knowledge base. |
| Description | Indicates the knowledge base's purpose and content. |
| Permissions | Defines which workspace members can access the knowledge base.<Note>Members granted access to a knowledge base have all the permissions listed in [Manage Knowledge Content](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents).</Note> |
| Index Method | Defines how document chunks are processed and organized for retrieval. For more details, see [Select the Index Method](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods#select-the-index-method). |
| Embedding Model | Specifies the embedding model used to convert document chunks into vector representations.<Info>Changing the embedding model will re-embed all chunks.</Info> |
| Summary Auto-Gen | Automatically generate summaries for document chunks.<Info>Once enabled, this only applies to newly added documents and chunks. For existing chunks, select the document(s) in the document list and click **Generate summary**.</Info> |
| Retrieval Settings | Defines how the knowledge base retrieves relevant content. For more details, see [Configure the Retrieval Settings](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods#configure-the-retrieval-settings). |
# Manage Knowledge Content
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents
## Manage Documents
In a knowledge base, each imported item—whether a local file, a Notion page, or a web page—becomes a document.
From the document list, you can view and manage all these documents to keep your knowledge accurate, relevant, and up-to-date.
<Tip>
Click the knowledge base name at the top to quickly switch between knowledge bases.
</Tip>
<Frame>
<img alt="Manage Knowledge Documents" />
</Frame>
| Action | Description |
| :-------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Add | Import a new document. |
| Modify Chunk Settings | Modify a document's chunking settings (excluding the chunk structure).<Info>Each document can have its own chunking settings, while the chunk structure is shared across the knowledge base and cannot be changed once set.</Info> |
| Delete | Permanently remove a document. **Deletion cannot be undone**. |
| Enable / Disable | Temporarily include or exclude a document from retrieval. |
| Generate Summary | Automatically generates summaries for all chunks in a document. Available when **Summary Auto-Gen** is enabled.<Note>Existing summaries will be overwritten.</Note> |
| Archive / Unarchive | Archive a document that you no longer need for retrieval but still want to keep. Archived documents are read-only and can be unarchived at any time. |
| Edit | Modify the content of a document by editing its chunks. See [Manage Chunks](#manage-chunks) for details. |
| Rename | Change the name of a document. |
## Manage Chunks
According to its chunk settings, every document is split into content chunks—the basic units for retrieval.
From the chunk list within a document, you can view and manage all its chunks to improve the retrieval efficiency and accuracy.
<Tip>
Click the document name in the upper-left corner to quickly switch between documents.
</Tip>
<Frame>
<img alt="Manage Knowledge Chunks" />
</Frame>
| Action | Description |
| :----------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Add | Add one or batch add multiple new chunks. <br /><br />For documents chunked with Parent-child mode, both new parent and child chunks can be added. |
| Delete | Permanently remove a chunk. **Deletion cannot be undone**. |
| Enable / Disable | Temporarily include or exclude a chunk from retrieval. Disabled chunks cannot be edited. |
| Edit | Modify the content of a chunk. Edited chunks are marked **Edited**.<br /><br />For knowledge bases using the Parent-child chunk mode: <ul><li>When editing a parent chunk, you can choose to regenerate its child chunks or keep them unchanged.</li><li>Editing a child chunk does not update its parent chunk. </li></ul> |
| Add / Edit / Delete Keywords | Add or modify keywords (up to 10) for a chunk to improve its retrievability. Only available for knowledge bases using the Economical index method. |
| Add / Delete Image Attachments | Remove images extracted from documents or upload new ones within their corresponding chunk.<br /><br />URLs of extracted images remain in the chunk text, but you can safely remove these URLs to keep the text clean—this won't affect the extracted images. <Note>Each chunk can have up to 10 image attachments by default, which are returned alongside it during retrieval. Images beyond this limit will not be extracted. Adjust the limit via the `SINGLE_CHUNK_ATTACHMENT_LIMIT` environment variable.</Note><Tip>If you select a multimodal embedding model (marked with a **Vision** icon), the extracted images will also be embedded and indexed for retrieval.</Tip> |
| Add / Edit / Delete Summary | Add, modify, or remove a summary for a chunk.<br /><br />Summaries are embedded and indexed for retrieval as well. When a summary matches a query, its corresponding chunk is also returned.<Tip>Add identical summaries to multiple chunks to enable grouped retrieval, allowing related chunks to be returned together (subject to the Top K limit).</Tip> |
## Best Practices
### Check Chunk Quality
After a document is chunked, carefully review each chunk to ensure it's semantically complete and appropriately sized for optimal retrieval accuracy and response relevance.
Common issues to watch for:
* Chunks are **too short**—may lack sufficient context, leading to semantic loss and inaccurate answers.
* Chunks are **too long**—may include irrelevant information, introducing semantic noise and lowering retrieval precision.
* Chunks are **semantically incomplete**—caused by forced chunking that cuts through sentences or paragraphs, resulting in missing or misleading content during retrieval.
### Use Child Chunks as Retrieval Hooks for Parent Chunks
For documents chunked with Parent-child mode, the system searches across child chunks but returns the parent chunks. Since editing a child chunk does not update its parent, you can treat child chunks as semantic tags or retrieval hints for their parent chunks.
To do this, rewrite child chunks into **keywords**, **summaries**, or **common user queries**. For example, if a parent chunk covers technical "LED Status Indicators", you could rephrase its child chunks as:
* *blinking light, won't turn on, red light, connection error, frozen* (keywords)
* *Guide to interpreting LED colors and troubleshooting hardware power or pairing issues* (summaries)
* *What does a solid red light mean?* (queries)
### Use Summaries to Bridge Query-Content Gaps
While high-quality indexing enables semantic search, raw chunks can still be hard to retrieve when they are too specific, noisy, or structurally complex to align well with user queries.
Summaries bridge this gap by providing a condensed semantic layer that makes the chunk's core intent explicit.
Use summaries when:
* **User queries differ from document language**: For technical documentation written formally, add summaries in the way users actually ask questions.
* **Concepts are implicit or buried in details**: Add high-level summaries that surface the core concepts and intent, so the chunk can be matched without relying on small details scattered across the text.
* **Raw text is non-textual**: When a chunk is primarily code, tables, logs, transcripts, or otherwise hard to match semantically, add descriptive summaries that clearly label what the chunk contains.
* **Related chunks should be retrieved together**: Apply identical summaries to a series of related chunks to enable grouped retrieval. This semantic glue allows multiple parts of a topic to be retrieved together, providing richer context.
<Info>
The number of returned related chunks is subject to the Top K limit defined in the retrieval settings.
</Info>
# Manage Document Metadata
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/metadata
## What is Metadata?
### Overview
Metadata is information that describes your data - essentially "data about data". Just as a book has a table of contents to help you understand its structure, metadata provides context about your data's content, origin, purpose, etc., making it easier for you to find and manage information in your knowledge base.
This guide aims to help you understand metadata and effectively manage your knowledge base.
### Core Concepts
* **Field**: The label of a metadata field (e.g., "author", "language").
* **Value**: The information stored in a metadata field (e.g., "Jack", "English").
<Frame>

</Frame>
* **Value Count**: The number of values contained in a metadata field, including duplicates. (e.g., "3").
<Frame>

</Frame>
* **Value Type**: The type of value a field can contain.
* Dify supports three value types:
* String: For text-based information
* Number: For numerical data
* Time: For dates/timestamps
<Frame>

</Frame>
## How to Manage My Metadata?
### Manage Metadata Fields in the Knowledge Base
You can create, modify, and delete metadata fields in the knowledge base.
> Any changes you make to metadata fields here affect your knowledge base globally.
#### Get Started with the Metadata Panel
**Access the Metadata Panel**
To access the Metadata Panel, go to **Knowledge Base** page and click **Metadata**.
<Frame>

</Frame>
<Frame>

</Frame>
**Built-in vs Custom Metadata**
<table>
<thead>
<tr>
<th />
<th>Built-in Metadata</th>
<th>Custom Metadata</th>
</tr>
</thead>
<tbody>
<tr>
<td>Location</td>
<td>Lower section of the Metadata panel</td>
<td>Upper section of the Metadata panel</td>
</tr>
<tr>
<td>Activation</td>
<td>Disabled by default; requires manual activation</td>
<td>Add as needed</td>
</tr>
<tr>
<td>Generation</td>
<td>System automatically extracts and generates field values</td>
<td>User-defined and manually added</td>
</tr>
<tr>
<td>Editing</td>
<td>Fields and values cannot be modified once generated</td>
<td>Fields and values can be edited or deleted</td>
</tr>
<tr>
<td>Scope</td>
<td>Applies to all existing and new documents when enabled</td>
<td>Stored in metadata list; requires manual assignment to documents</td>
</tr>
<tr>
<td>Fields</td>
<td>
System-defined fields include:
<ul>
<li>document\_name (string)</li>
<li>uploader (string)</li>
<li>upload\_date (time)</li>
<li>last\_update\_date (time)</li>
<li>source (string)</li>
</ul>
</td>
<td>No default fields; all fields must be manually created</td>
</tr>
<tr>
<td>Value Types</td>
<td>
<ul>
<li>String: For text values</li>
<li>Number: For numerical values</li>
<li>Time: For dates and timestamps</li>
</ul>
</td>
<td>
<ul>
<li>String: For text values</li>
<li>Number: For numerical values</li>
<li>Time: For dates and timestamps</li>
</ul>
</td>
</tr>
</tbody>
</table>
#### Create New Metadata Fields
To create a new metadata field:
1. Click **+Add Metadata** to open the **New Metadata** dialog.
<Frame>

</Frame>
2. Choose the value type.
3. Name the field.
> Naming rules: Use lowercase letters, numbers, and underscores only.
<Frame>

</Frame>
4. Click **Save** to apply changes.
<Frame>

</Frame>
#### Edit Metadata Fields
To edit a metadata field:
1. Click the edit icon next to a field to open the **Rename** dialog.
<Frame>

</Frame>
2. Enter the new name in the **Name** field.
> Note: You can only modify the field name, not the value type.
<Frame>

</Frame>
3. Click **Save** to apply changes.
> Note: Field changes update across all related documents in your knowledge base.
<Frame>

</Frame>
#### Delete Metadata Fields
To delete a metadata field, click the delete icon next to a field to delete it.
> Note: Deleting a field deletes it and all its values from all documents in your knowledge base.
<Frame>

</Frame>
### Edit Metadata
#### Bulk Edit Metadata in the Metadata Editor
You can edit metadata in bulk in the knowledge base.
**Access the Metadata Editor**
To access the Metadata Editor:
1. In the knowledge base, select documents using the checkboxes on the left.
<Frame>
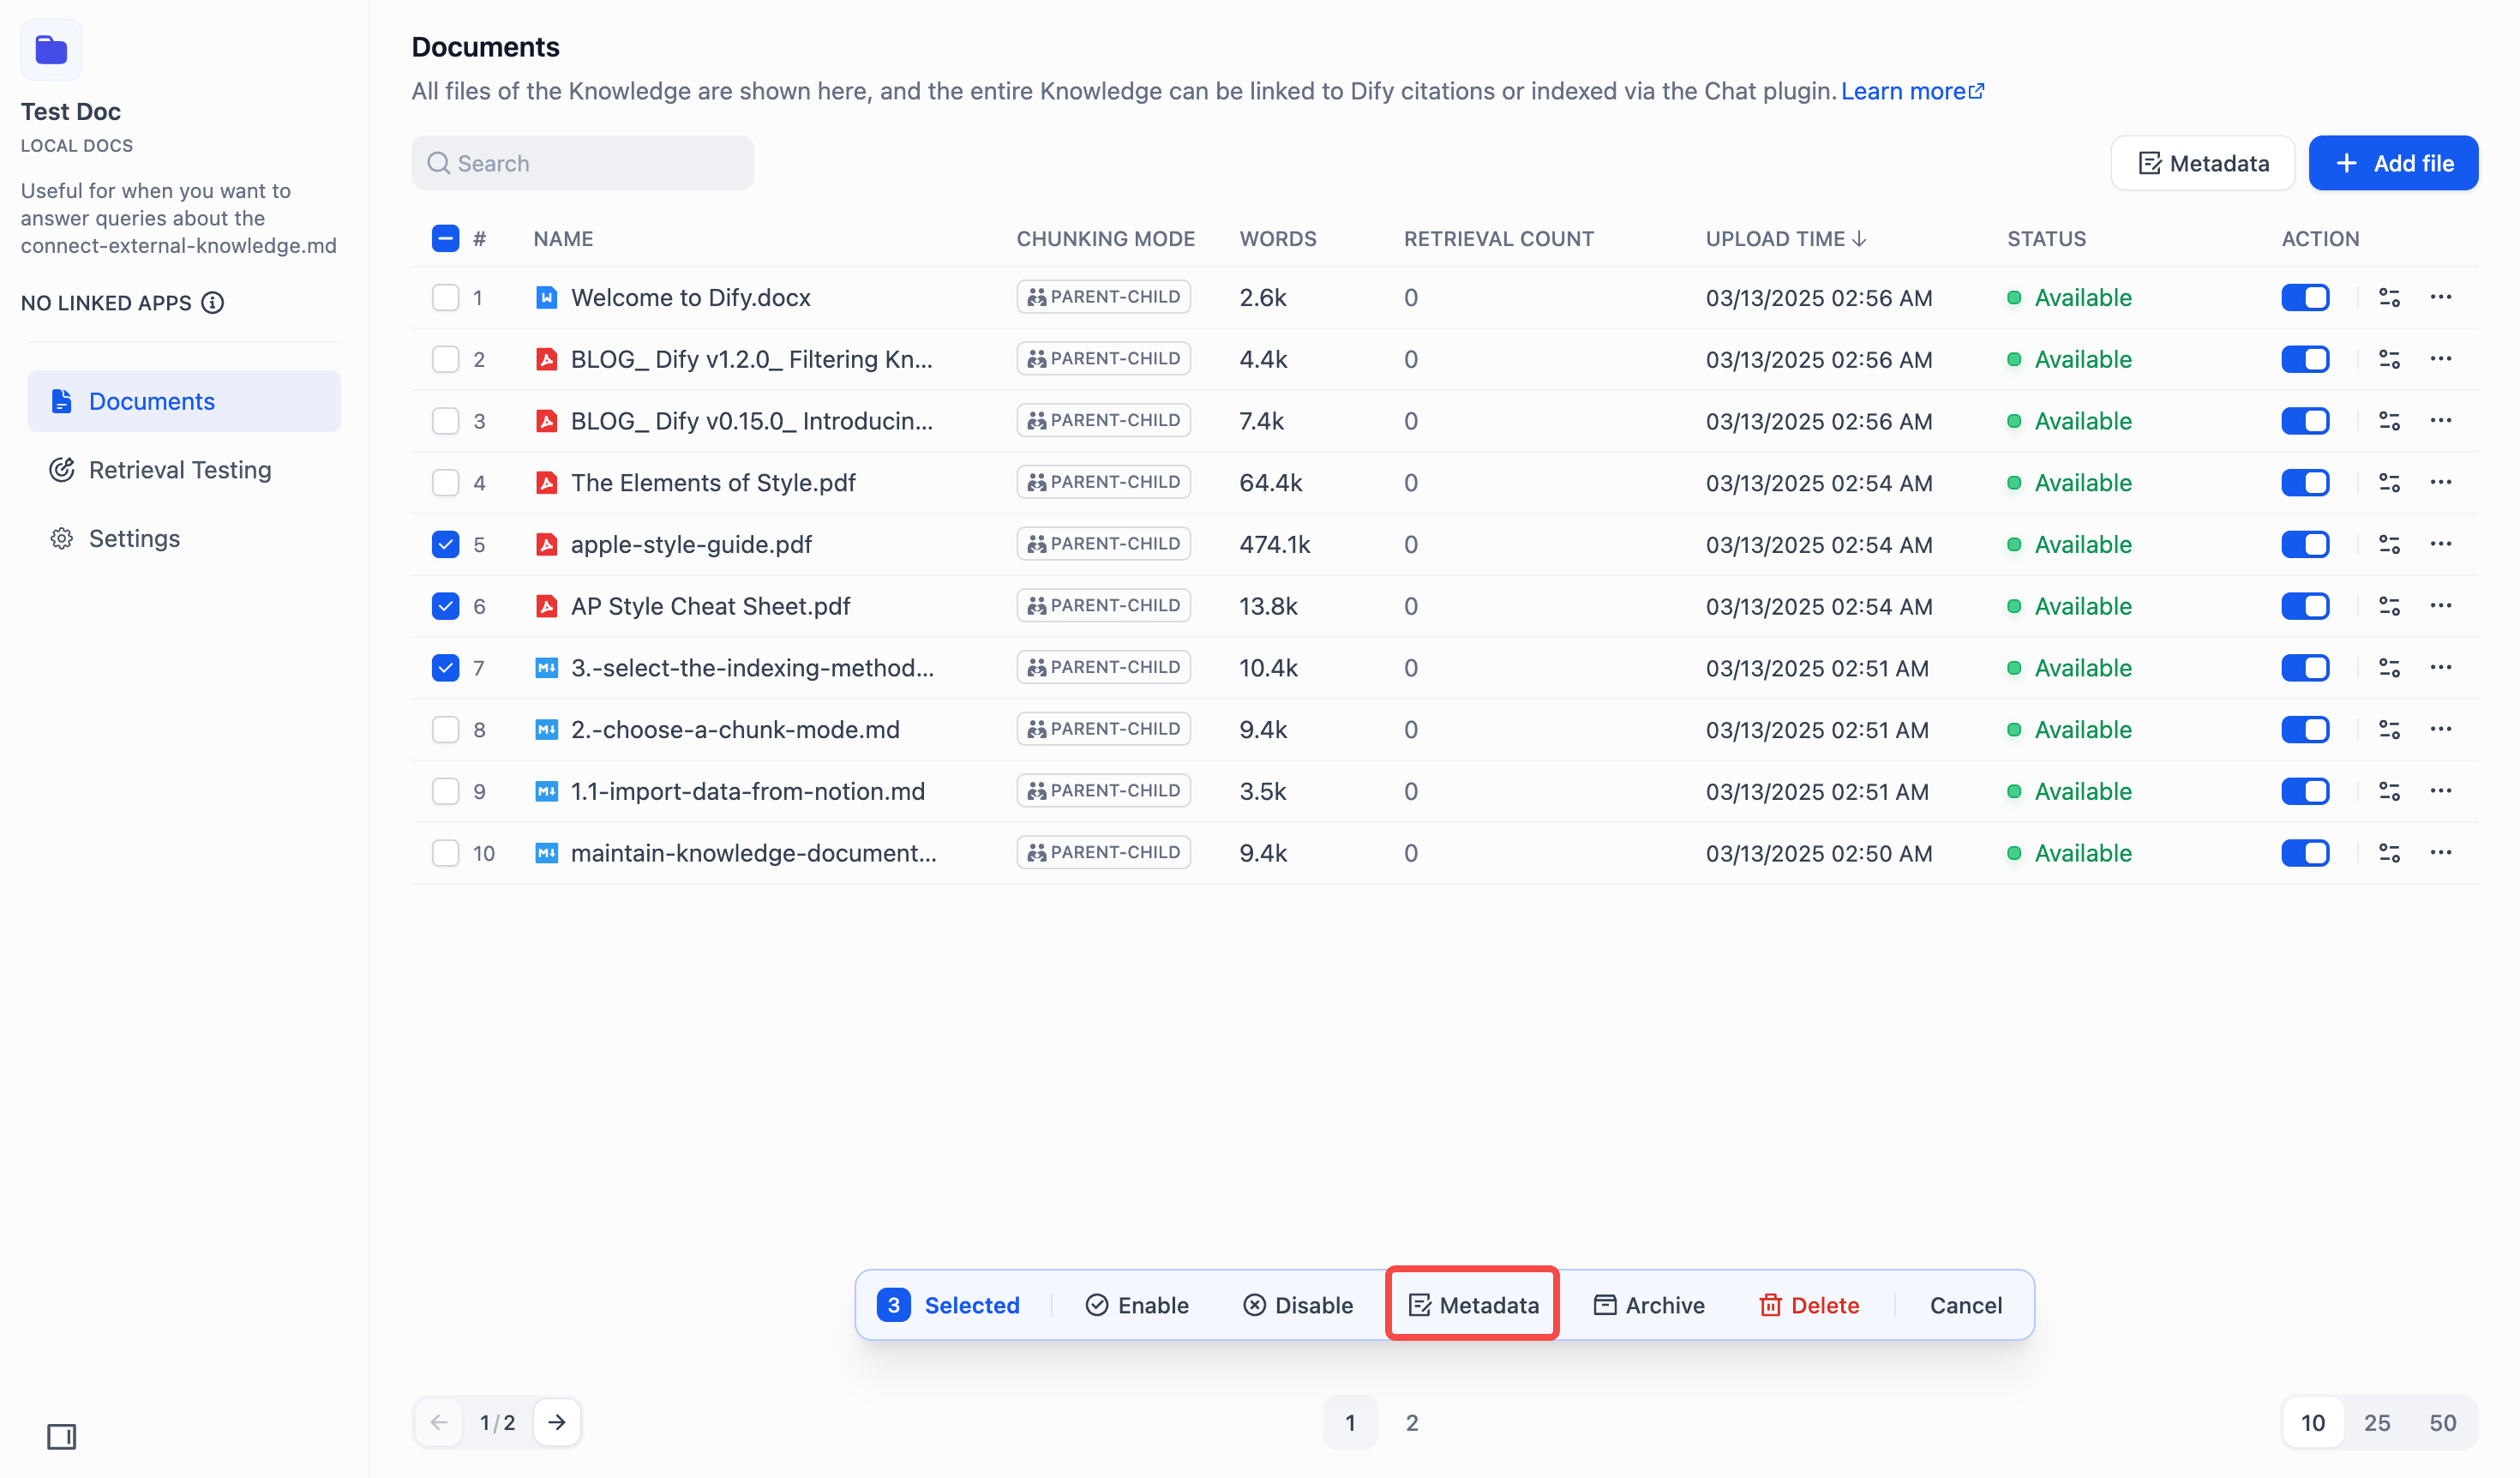
</Frame>
2. Click **Metadata** in the bottom action bar to open the Metadata Editor.
<Frame>

</Frame>
**Bulk Add Metadata**
To add metadata in bulk:
1. Click **+Add Metadata** in the editor to:
<Frame>

</Frame>
* Add existing fields from the dropdown or from the search box.
<Frame>

</Frame>
* Create new fields via **+New Metadata**.
> New fields are automatically added to the knowledge base.
<Frame>

</Frame>
* Access the Metadata Panel to manage metadata fields via **Manage**.
<Frame>

</Frame>
2. *(Optional)* Enter values for new fields.
<Frame>

</Frame>
> The date picker is for time-type fields.
<Frame>

</Frame>
3. Click **Save** to apply changes.
**Bulk Update Metadata**
To update metadata in bulk:
1. In the editor:
* **Add Values**: Type directly in the field boxes.
* **Reset Values**: Click the blue dot that appears on hover.
<Frame>

</Frame>
* **Delete Values**: Clear the field or delete the **Multiple Value** card.
<Frame>

</Frame>
* **Delete fields**: Click the delete icon (fields appear struck through and grayed out).
> Note: This only deletes the field from this document, not from your knowledge base.
<Frame>

</Frame>
2. Click **Save** to apply changes.
**Set Update Scope**
Use **Apply to All Documents** to control changes:
* **Unchecked (Default)**: Updates only documents that already have the field.
* **Checked**: Adds or updates fields across all selected documents.
<Frame>

</Frame>
#### Edit Metadata on the Document Details Page
You can edit a single document's metadata on its details page.
**Access Metadata Edit Mode**
To edit a single document's metadata:
On the document details page, click **Start labeling** to begin editing.
<Frame>

</Frame>
<Frame>

</Frame>
**Add Metadata**
To add a single document's metadata fields and values:
1. Click **+Add Metadata** to:
<Frame>

</Frame>
* Create new fields via **+New Metadata**.
> New fields are automatically added to the knowledge base.
<Frame>

</Frame>
* Add existing fields from the dropdown or from the search box.
<Frame>

</Frame>
* Access the Metadata Panel via **Manage**.
<Frame>

</Frame>
2. *(Optional)* Enter values for new fields.
<Frame>

</Frame>
3. Click **Save** to apply changes.
**Edit Metadata**
To update a single document's metadata fields and values:
1. Click **Edit** in the top right to begin editing.
<Frame>

</Frame>
2. Edit metadata:
* **Update Values**: Type directly in value fields or delete it.
> Note: You can only modify the value, not the value name.
* **Delete Fields**: Click the delete icon.
> Note: This only deletes the field from this document, not from your knowledge base.
<Frame>

</Frame>
3. Click **Save** to apply changes.
## How to Filter Documents with Metadata?
See **Metadata Filtering** in *[Integrate Knowledge Base within Application](/en/self-host/use-dify/knowledge/integrate-knowledge-within-application)*.
## FAQ
* **What can I do with metadata?**
* Find information faster with smart filtering.
* Control access to sensitive content.
* Organize data more effectively.
* Automate workflows based on metadata rules.
* **Fields vs Values: What is the difference?**
| | Definition | Characteristics | Examples |
| ------------------------------------------ | -------------------------------------------------------------------- | --------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------- |
| Metadata Fields in the Metadata Panel | System-defined attributes that describe document properties | Global fields accessible across all documents in the knowledge base | Author, Type, Date, etc. |
| Metadata Value on a document's detail page | Custom metadata tagged according to individual document requirements | Unique metadata values assigned based on document content and context | The "Author" field in Document A is set to "Mary" value, while in Document B it is set to "John" value. |
* **How do different delete options work?**
| Action | Steps | Impact | Outcome |
| ---------------------------------------- | ------------------------------------------------------- | ------------------------------ | -------------------------------------------------------------------- |
| Delete field in the Metadata Panel | In the Metadata Panel, click delete icon next to field | Global - affects all documents | Field and all values permanently deleted from the knowledge base |
| Delete field in the Metadata Editor | In the Metadata Editor, click delete icon next to field | Selected documents only | Field deleted from selected documents; remains in the knowledge base |
| Delete field on the document detail page | In the Edit Mode, click delete icon next to field | Current document only | Field deleted from current document; remains in the knowledge base |
# Knowledge
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/readme
## Introduction
Knowledge in Dify is a collection of your own data that can be integrated into your AI apps. It allows you to provide LLMs with domain-specific information as context, ensuring their responses are more accurate, relevant, and less prone to hallucinations.
This is made possible through Retrieval-Augmented Generation (RAG). It means that instead of relying solely on its pre-trained public data, the LLM uses your custom knowledge as an additional source of truth:
1. (Retrieval) When a user asks a question, the system first **retrieves the most relevant** information from the incorporated knowledge.
2. (Augmented) This retrieved information is then combined with the user's original query and sent to the LLM as **augmented context**.
3. (Generation) The LLM uses this context to generate a **more precise** answer.
Knowledge is stored and managed in knowledge bases. You can create multiple knowledge bases, each tailored to different domains, use cases, or data sources, and selectively integrate them into your application as needed.
## Build with Knowledge
With Dify knowledge, you can build AI apps that are grounded in your own data and domain-specific expertise. Here are some common use cases:
* **Customer support chatbots**: Build smarter support bots that provide accurate answers from your up-to-date product documentation, FAQs, and troubleshooting guides.
* **Internal knowledge portals**: Build AI-powered search and Q\&A systems for employees to quickly access company policies and procedures.
* **Content generation tools**: Build intelligent writing tools that generate reports, articles, or emails based on specific background materials.
* **Research & analysis applications**: Build applications that assist in research by retrieving and summarizing information from specific knowledge repositories like academic papers, market reports, or legal documents.
## Create Knowledge
* **[Create a ready-to-use knowledge base](/en/self-host/use-dify/knowledge/create-knowledge/introduction)**: Import data, define processing rules, and let Dify handle the rest. Fast and beginner-friendly.
* **[Build a custom knowledge base](/en/self-host/use-dify/knowledge/knowledge-pipeline/readme)**: Orchestrate more complex, flexible data processing workflows with custom steps and various integrations.
* **[Connect to an external knowledge base](/en/self-host/use-dify/knowledge/connect-external-knowledge-base)**: Sync directly from external knowledge bases via APIs to leverage existing data without migration.
## Manage & Optimize Knowledge
* **[Manage content](/en/self-host/use-dify/knowledge/manage-knowledge/maintain-knowledge-documents)**: View, add, modify, or delete documents and chunks to keep your knowledge current, accurate, and retrieval-ready.
* **[Test and validate retrieval](/en/self-host/use-dify/knowledge/test-retrieval)**: Simulate user queries to test how well your knowledge base retrieves relevant information.
* **[Enhance retrieval with metadata](/en/self-host/use-dify/knowledge/metadata)**: Add metadata to documents to enable filter-based searches and further improve retrieval precision.
* **[Adjust knowledge base settings](/en/self-host/use-dify/knowledge/manage-knowledge/introduction)**: Modify the index method, embedding model, and retrieval strategy at any time.
## Use Knowledge
**[Integrate into applications](/en/self-host/use-dify/knowledge/integrate-knowledge-within-application)**: Ground your AI app in your own knowledge.
***
**Read More**:
* [Dify v1.1.0: Filtering Knowledge Retrieval with Customized Metadata](https://dify.ai/blog/dify-v1-1-0-filtering-knowledge-retrieval-with-customized-metadata)
* [Dify v0.15.0: Introducing Parent-child Retrieval for Enhanced Knowledge](https://dify.ai/blog/introducing-parent-child-retrieval-for-enhanced-knowledge)
* [Introducing Hybrid Search and Rerank to Improve the Retrieval Accuracy of the RAG System](https://dify.ai/blog/hybrid-search-rerank-rag-improvement)
* [Dify.AI's New Dataset Feature Enhancements: Citations and Attributions](https://dify.ai/blog/difyai-new-dataset-features)
* [Text Embedding: Basic Concepts and Implementation Principles](https://dify.ai/blog/text-embedding-basic-concepts-and-implementation-principles)
* [Enhance Dify RAG with InfraNodus: Expand Your LLM's Context](https://dify.ai/blog/enhance-dify-rag-with-infranodus-expand-your-llm-s-context)
* [Dify.AI x Jina AI: Dify now Integrates Jina Embedding Model](https://dify.ai/blog/integrating-jina-embeddings-v2-dify-enhancing-rag-applications)
# Test Knowledge Retrieval
Source: https://docs.dify.ai/en/self-host/use-dify/knowledge/test-retrieval
In a knowledge base, click the **Retrieval Testing** icon in the left sidebar to enter the testing page.
Here, you can simulate user queries to test how well the knowledge base retrieves relevant information and experiment with different retrieval settings for optimal performance.
<Note>
Retrieval settings adjusted here are temporary and only apply to the current test session.
</Note>
<Tip>
For more about retrieval settings, see [Configure the Retrieval Settings](/en/self-host/use-dify/knowledge/create-knowledge/setting-indexing-methods#configure-the-retrieval-settings).
</Tip>
The **Records** section logs all retrieval events associated with this knowledge base, including:
* Queries tested directly on the **Retrieval Testing** page
* Retrieval requests made by any linked app—whether during test runs or in production
<Info>
Test retrievals and regular retrievals share the same API endpoint.
</Info>
# Dashboard
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/analysis
Monitor performance, costs, and user engagement through Dify's built-in analytics dashboard
The dashboard tracks four metrics over time to show how your application performs:
<Frame>
<img alt="Monitoring Dashboard" />
</Frame>
**Total Messages**: Conversation volume\
**Active Users**: Users with meaningful interactions (more than one exchange)\
**Average User Interactions**: Engagement depth per session\
**Token Usage**: Resource consumption and costs
Use the time selector to view trends over different periods. Click **"Tracing app performance"** to connect external observability platforms like Langfuse or LangSmith for deeper analytics.
# Annotation System
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/annotation-reply
Build a curated library of high-quality responses to improve consistency and bypass AI generation
Annotations let you create a curated library of perfect responses for specific questions. When users ask similar questions, Dify returns your pre-written answers instead of generating new responses, ensuring consistency and eliminating AI hallucinations for critical topics.
## When to Use Annotations
**Enterprise Standards**
Create definitive answers for policy questions, product information, or customer service scenarios where consistency is critical.
**Rapid Prototyping**
Quickly improve demo applications by curating high-quality responses without retraining models or complex prompt engineering.
**Quality Assurance**
Ensure certain sensitive or important questions always receive your approved responses rather than potentially variable AI-generated content.
## How Annotations Work
When annotation reply is enabled:
1. User asks a question
2. System searches existing annotations for semantic matches
3. If a match above the similarity threshold is found, returns the curated response
4. If no match, proceeds with normal AI generation
5. Track which annotations get used and how often
This creates a "fast path" for known good answers while maintaining AI flexibility for new questions.
## Set Up Annotations
**Enable in App Configuration**
Navigate to **Orchestrate → Add Features** and enable annotation reply. Configure the similarity threshold and embedding model for matching.
**Similarity Threshold**: Higher values require closer matches. Start with moderate settings and adjust based on hit rates.
**Embedding Model**: Used to vectorize questions for semantic matching. Changing the model regenerates all embeddings.
## Create Annotations
**From Conversations**
In debug mode or logs, click on AI responses and edit them into the perfect answer. Save as an annotation for future use.
**Bulk Import**
Download the template, create Q\&A pairs in the specified format, and upload for batch annotation creation.
**Manual Entry**
Add annotations directly in **Annotations** with custom questions and responses.
## Manage Annotation Quality
**Hit Tracking**
Monitor which annotations are matched, how often they're used, and the similarity scores of matches. This shows which annotations provide value.
**Continuous Refinement**
Review hit history to improve annotation coverage and accuracy. Questions that consistently miss your annotations indicate gaps in coverage.
**A/B Testing**
Compare user satisfaction rates before and after annotation implementation to measure impact.
## Annotation Analytics
**Hit Rate Analysis**
Track which annotations are frequently matched and which are never used. Remove unused annotations and expand successful patterns.
**Question Patterns**
Identify common user question types that would benefit from annotation coverage.
**Match Quality**
Review similarity scores to ensure annotations are triggering for appropriate questions without false matches.
# Integrate with Alibaba Cloud Monitor
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-aliyun
Send traces and metrics from Dify applications to Alibaba Cloud Monitor (ARMS) via OpenTelemetry
## What is Alibaba Cloud Monitor
Alibaba Cloud provides a fully managed, maintenance-free observability platform that enables one-click monitoring, tracing, and evaluation of Dify applications.
<Info>
Alibaba Cloud Monitor natively supports Python/Golang/Java applications through [LoongSuite](https://github.com/alibaba/loongsuite-python-agent) agents and open-source OpenTelemetry agents. In addition to one-click monitoring of Dify LLM applications, it also supports end-to-end observability of Dify components and their upstream and downstream dependencies through non-invasive agents.
For more details, please refer to the [Cloud Monitor documentation](https://www.alibabacloud.com/help/en/cms/cloudmonitor-1-0/product-overview/what-is-cloudmonitor?spm=a3c0i.63551.2277339270.1.76c7112eeKEvSr).
</Info>
## How to Configure Alibaba Cloud Monitor
### 1. Get Alibaba Cloud Endpoint and License Key
1. Log in to the [ARMS console](https://account.alibabacloud.com/login/login.htm?spm=5176.12901015-2.0.0.68d74b84XRatpU), and click **Integration Center** in the left navigation bar.
2. In the **Server-side Applications** area, click the **OpenTelemetry** card.
3. In the **OpenTelemetry** panel that appears, select **gRPC** as the export protocol, and select the connection method and region according to your actual deployment.
<Frame>
</Frame>
4. Save the **Public Endpoint** and **Authentication Token (License Key)**.
<Note>
The Endpoint does not include a port number, for example `http://tracing-cn-heyuan.arms.aliyun.com`.
</Note>
### 2. Configure Cloud Monitor in Dify
<Info>
Requires Dify v1.6.0 or later.
</Info>
1. Log in to the Dify console and navigate to the application you want to monitor.
2. Open **Monitoring** in the left navigation bar.
3. Click **Tracing app performance**, then click **Configure** in the **Cloud Monitor** area.
<Frame>
</Frame>
4. In the dialog that appears, enter the **License Key** and **Endpoint** obtained in step 1, and customize the **App Name** (the application name displayed in the ARMS console), then click **Save & Enable**.
## View Monitoring Data in Alibaba Cloud Monitor
After configuration, debug or production data from applications in Dify can be monitored in Cloud Monitor.
### Method 1: Jump to ARMS Console from Dify Application
In the Dify console, select an application with tracing enabled, go to **Tracing Configuration**, and click **View** in the **Cloud Monitor** area.
### Method 2: View Directly in ARMS Console
Go to the corresponding Dify application in the **LLM Application Monitoring > Application List** page of the ARMS console.
## Access More Data
Cloud Monitor provides multi-language non-invasive agents that support accessing various components of the Dify cluster to achieve end-to-end tracing.
| Dify Component | Agent | Details |
| -------------- | ----------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Nginx | OpenTelemetry Agent | [Use OpenTelemetry for Nginx Tracing](https://www.alibabacloud.com/help/en/opentelemetry/user-guide/use-opentelemetry-to-perform-tracing-analysis-on-nginx?spm=a2c63.l28256.help-menu-search-90275.d_1) |
| API | LoongSuite-Python Agent | [loongsuite-python-agent](https://github.com/alibaba/loongsuite-python-agent/blob/main/README.md) |
| Sandbox | LoongSuite-Go Agent | [loongsuite-go-agent](https://github.com/alibaba/loongsuite-go-agent/blob/main/README.md) |
| Worker | OpenTelemetry Agent | [Submit Python Application Data via OpenTelemetry](https://www.alibabacloud.com/help/en/opentelemetry/user-guide/use-managed-service-for-opentelemetry-to-submit-the-trace-data-of-python-applications?spm=a2c63.p38356.help-menu-90275.d_2_0_5_0.18ee53a4EGoGuS) |
| Plugin-Daemon | LoongSuite-Go Agent | [loongsuite-go-agent](https://github.com/alibaba/loongsuite-go-agent/blob/main/README.md) |
## Monitoring Data List
Cloud Monitor supports collecting data from Dify's Workflow/Chatflow/Chat/Agent applications, including execution details of workflows and workflow nodes, covering model calls, tool calls, knowledge retrieval, execution details of various process nodes, as well as metadata such as conversations and user information.
### Workflow/Chatflow Trace Information
<table>
<thead>
<tr>
<th>Workflow</th>
<th>Alibaba Cloud Monitor Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_id</td>
<td>Unique identifier of the Workflow</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>Conversation ID</td>
</tr>
<tr>
<td>workflow\_run\_id</td>
<td>ID of this run</td>
</tr>
<tr>
<td>tenant\_id</td>
<td>Tenant ID</td>
</tr>
<tr>
<td>elapsed\_time</td>
<td>Duration of this run</td>
</tr>
<tr>
<td>status</td>
<td>Run status</td>
</tr>
<tr>
<td>version</td>
<td>Workflow version</td>
</tr>
<tr>
<td>total\_tokens</td>
<td>Total tokens used in this run</td>
</tr>
<tr>
<td>file\_list</td>
<td>List of processed files</td>
</tr>
<tr>
<td>triggered\_from</td>
<td>Source that triggered this run</td>
</tr>
<tr>
<td>workflow\_run\_inputs</td>
<td>Input data for this run</td>
</tr>
<tr>
<td>workflow\_run\_outputs</td>
<td>Output data for this run</td>
</tr>
<tr>
<td>error</td>
<td>Errors that occurred during this run</td>
</tr>
<tr>
<td>query</td>
<td>Query used during runtime</td>
</tr>
<tr>
<td>workflow\_app\_log\_id</td>
<td>Workflow application log ID</td>
</tr>
<tr>
<td>message\_id</td>
<td>Associated message ID</td>
</tr>
<tr>
<td>start\_time</td>
<td>Run start time</td>
</tr>
<tr>
<td>end\_time</td>
<td>Run end time</td>
</tr>
</tbody>
</table>
**Workflow Trace Metadata**
* workflow\_id - Unique identifier of the Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of this run
* tenant\_id - Tenant ID
* elapsed\_time - Duration of this run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in this run
* file\_list - List of processed files
* triggered\_from - Trigger source
### Message Trace Information
<table>
<thead>
<tr>
<th>Message</th>
<th>Alibaba Cloud Monitor Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>Message ID</td>
</tr>
<tr>
<td>message\_data</td>
<td>Message data</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>User's session\_id</td>
</tr>
<tr>
<td>conversation\_model</td>
<td>Conversation model</td>
</tr>
<tr>
<td>message\_tokens</td>
<td>Number of tokens in the message</td>
</tr>
<tr>
<td>answer\_tokens</td>
<td>Number of tokens in the answer</td>
</tr>
<tr>
<td>total\_tokens</td>
<td>Total tokens in message and answer</td>
</tr>
<tr>
<td>error</td>
<td>Error information</td>
</tr>
<tr>
<td>inputs</td>
<td>Input data</td>
</tr>
<tr>
<td>outputs</td>
<td>Output data</td>
</tr>
<tr>
<td>file\_list</td>
<td>List of processed files</td>
</tr>
<tr>
<td>start\_time</td>
<td>Start time</td>
</tr>
<tr>
<td>end\_time</td>
<td>End time</td>
</tr>
<tr>
<td>message\_file\_data</td>
<td>File data associated with the message</td>
</tr>
<tr>
<td>conversation\_mode</td>
<td>Conversation mode</td>
</tr>
</tbody>
</table>
**Message Trace Metadata**
* conversation\_id - ID of the conversation to which the message belongs
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether it is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
* message\_id - Message ID
### Dataset Retrieval Trace Information
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>Alibaba Cloud Monitor Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>Message ID</td>
</tr>
<tr>
<td>inputs</td>
<td>Input content</td>
</tr>
<tr>
<td>documents</td>
<td>Document data</td>
</tr>
<tr>
<td>start\_time</td>
<td>Start time</td>
</tr>
<tr>
<td>end\_time</td>
<td>End time</td>
</tr>
<tr>
<td>message\_data</td>
<td>Message data</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Metadata**
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether it is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
### Tool Trace Information
<table>
<thead>
<tr>
<th>Tool</th>
<th>Alibaba Cloud Monitor Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>Message ID</td>
</tr>
<tr>
<td>tool\_name</td>
<td>Tool name</td>
</tr>
<tr>
<td>start\_time</td>
<td>Start time</td>
</tr>
<tr>
<td>end\_time</td>
<td>End time</td>
</tr>
<tr>
<td>tool\_inputs</td>
<td>Tool inputs</td>
</tr>
<tr>
<td>tool\_outputs</td>
<td>Tool outputs</td>
</tr>
<tr>
<td>message\_data</td>
<td>Message data</td>
</tr>
<tr>
<td>error</td>
<td>Error information (if any)</td>
</tr>
<tr>
<td>inputs</td>
<td>Input content of the message</td>
</tr>
<tr>
<td>outputs</td>
<td>Answer content of the message</td>
</tr>
<tr>
<td>tool\_config</td>
<td>Tool configuration</td>
</tr>
<tr>
<td>time\_cost</td>
<td>Time cost</td>
</tr>
<tr>
<td>tool\_parameters</td>
<td>Tool parameters</td>
</tr>
<tr>
<td>file\_url</td>
<td>URL of associated file</td>
</tr>
</tbody>
</table>
**Tool Trace Metadata**
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Creator role
* created\_user\_id - Creator user ID
# Integrate with Arize
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-arize
### What is Arize
[Arize AX](https://arize.com/products/ax/) is [Arize AI](https://arize.com/?utm_source=dify-docs\&utm_medium=partner\&utm_campaign=partner-docs\&utm_content=integrate-arize-self-host)'s full-featured platform for observability, online and offline evaluation, monitoring, and experimentation in LLM and agent-driven applications. Built for production teams, AI-native companies, and enterprises, it runs as a managed cloud service or an enterprise self-hosted deployment.
If you'd rather run an open-source stack for local development, experimentation, or single-container self-hosting, set up the [Phoenix integration](/en/self-host/use-dify/monitor/integrations/integrate-phoenix) instead.
Once traces are flowing, see Arize's [agent evaluation guide](https://arize.com/guides/ai-agent-handbook/agent-evaluation/) and [LLM evaluation guide](https://arize.com/resources/llm-evaluation/) for how to use them to debug failures, evaluate agent behavior, and monitor model quality.
### How to Configure Arize
#### 1. Register/Login to [Arize](https://app.arize.com/auth/join)
#### 2. Get your Arize API Key
Retrieve your Arize API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
<Frame>

</Frame>
#### 3. Integrate Arize with Dify
Configure Arize in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>

</Frame>
After clicking configure, paste the **API Key**, **Space ID** and **project name** created in Arize into the configuration and save.
<Frame>

</Frame>
Once successfully saved, you can view the monitoring status on the current page.
<Frame>

</Frame>
### Monitoring Data List
#### **Workflow/Chatflow Trace Information**
**Used to track workflows and chatflows**
<table>
<thead>
<tr>
<th>Workflow</th>
<th>Arize Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_app\_log\_id/workflow\_run\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>error</td>
<td>error</td>
</tr>
<tr>
<td>\[workflow]</td>
<td>tags</td>
</tr>
<tr>
<td>"conversation\_id/none for workflow"</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
<table>
<thead>
<tr>
<th>Chat</th>
<th>Arize LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"llm"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>tags</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
<table>
<thead>
<tr>
<th>Moderation</th>
<th>Arize Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>“moderation"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["moderation"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
<table>
<thead>
<tr>
<th>Suggested Question</th>
<th>Arize LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"suggested\_question"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["suggested\_question"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>Arize Retriever</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"dataset\_retrieval"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["dataset\_retrieval"]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
<table>
<thead>
<tr>
<th>Tool</th>
<th>Arize Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>tool\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["tool", tool\_name]</td>
<td>tags</td>
</tr>
</tbody>
</table>
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
<table>
<thead>
<tr>
<th>Generate Name</th>
<th>Arize Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"generate\_conversation\_name"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["generate\_name"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Langfuse
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-langfuse
### What is Langfuse
Langfuse is an open-source LLM engineering platform that helps teams collaborate on debugging, analyzing, and iterating their applications.
<Info>
Introduction to Langfuse: [https://langfuse.com/](https://langfuse.com/)
</Info>
### How to Configure Langfuse
1. Register and log in to Langfuse on the [official website](https://langfuse.com/)
2. Create a project in Langfuse. After logging in, click **New** on the homepage to create your own project. The **project** will be used to associate with **applications** in Dify for data monitoring.
<Frame>
</Frame>
Edit a name for the project.
<Frame>
</Frame>
3. Create project API credentials. In the left sidebar of the project, click **Settings** to open the settings.
<Frame>
</Frame>
In Settings, click **Create API Keys** to create project API credentials.
<Frame>
</Frame>
Copy and save the **Secret Key**, **Public Key**, and **Host**.
<Frame>
</Frame>
4. Configure Langfuse in Dify. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>
</Frame>
After clicking configure, paste the **Secret Key, Public Key, Host** created in Langfuse into the configuration and save.
<Frame>
</Frame>
Once successfully saved, you can view the status on the current page. If it shows as started, it is being monitored.
<Frame>
</Frame>
### View Monitoring Data in Langfuse
After configuration, debugging or production data of the application in Dify can be viewed in Langfuse.
<Frame>
</Frame>
<Frame>
</Frame>
### List of monitoring data
#### Trace the information of Workflow and Chatflow
**Tracing Workflow and Chatflow**
<table>
<thead>
<tr>
<th>Workflow</th>
<th>LangFuse Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_app\_log\_id/workflow\_run\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>error</td>
<td>level</td>
</tr>
<tr>
<td>error</td>
<td>status\_message</td>
</tr>
<tr>
<td>\[workflow]</td>
<td>tags</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>session\_id</td>
</tr>
<tr>
<td>conversion\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Workflow Trace Info**
* workflow\_id - Unique ID of Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - Workflow ID of this runtime
* tenant\_id - Tenant ID
* elapsed\_time - Elapsed time at this runtime
* status - Runtime status
* version - Workflow version
* total\_tokens - Total token used at this runtime
* file\_list - List of files processed
* triggered\_from - Source that triggered this runtime
* workflow\_run\_inputs - Input of this workflow
* workflow\_run\_outputs - Output of this workflow
* error - Error Message
* query - Queries used at runtime
* workflow\_app\_log\_id - Workflow Application Log ID
* message\_id - Relevant Message ID
* start\_time - Start time of this runtime
* end\_time - End time of this runtime
* workflow node executions - Workflow node runtime information
* Metadata
* workflow\_id - Unique ID of Workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - Workflow ID of this runtime
* tenant\_id - Tenant ID
* elapsed\_time - Elapsed time at this runtime
* status - Operational state
* version - Workflow version
* total\_tokens - Total token used at this runtime
* file\_list - List of files processed
* triggered\_from - Source that triggered this runtime
#### Message Trace Info
**For trace llm conversation**
<table>
<thead>
<tr>
<th>Message</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>error</td>
<td>level</td>
</tr>
<tr>
<td>error</td>
<td>status\_message</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>tags</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>session\_id</td>
</tr>
<tr>
<td>conversion\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - Session ID for user
* conversation\_model - Conversation model
* message\_tokens - Message tokens
* answer\_tokens - Answer Tokens
* total\_tokens - Total Tokens from Message and Answer
* error - Error Message
* inputs - Input data
* outputs - Output data
* file\_list - List of files processed
* start\_time - Start time
* end\_time - End time
* message\_file\_data - Message of relevant file data
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending account's ID
* agent\_based - Whether agent based
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message source
* message\_id - Message ID
#### Moderation Trace Information
**Used to track conversation moderation**
<table>
<thead>
<tr>
<th>Moderation</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>moderation</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\[moderation]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* user\_id - user ID
* workflow\_app\_log\_id workflow\_app\_log\_id
* inputs - Input data for review
* message\_data - Message Data
* flagged - Whether it is flagged for attention
* action - Specific actions to implement
* preset\_response - Preset response
* start\_time - Start time of review
* end\_time - End time of review
* Metadata
* message\_id - Message ID
* action - Specific actions to implement
* preset\_response - Preset response
#### Suggested Question Trace Information
**Used to track suggested questions**
<table>
<thead>
<tr>
<th>Suggested Question</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>suggested\_question</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\[suggested\_question]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input data
* outputs - Output data
* start\_time - Start time
* end\_time - End time
* total\_tokens - Total tokens
* status - Message Status
* error - Error Message
* from\_account\_id - Sending account ID
* agent\_based - Whether agent based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Message status
* Metadata
* message\_id - Message ID
* ls\_provider - Model Provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending Account ID
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message source
#### Dataset Retrieval Trace Information
**Used to track knowledge base retrieval**
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>dataset\_retrieval</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\[dataset\_retrieval]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input Message
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model Provider
* ls\_model\_name - Model ID
* status - Model status
* from\_end\_user\_id - Sending user's ID
* from\_account\_id - Sending account's ID
* agent\_based - Whether agent based
* workflow\_run\_id - Workflow ID of this runtime
* from\_source - Message Source
#### Tool Trace Information
**Used to track tool invocation**
<table>
<thead>
<tr>
<th>Tool</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>tool\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["tool", tool\_name]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_observation\_id</td>
</tr>
</tbody>
</table>
**Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool Name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error Message, if exist
* inputs - Input of Message
* outputs - Output of Message
* tool\_config - Tool config
* time\_cost - Time cost
* tool\_parameters - Tool Parameters
* file\_url - URL of relevant files
* Metadata
* message\_id - Message ID
* tool\_name - Tool Name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool config
* time\_cost - Time. cost
* error - Error Message
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Created by role
* created\_user\_id - Created user ID
#### Generate Name Trace
**Used to track conversation title generation**
<table>
<thead>
<tr>
<th>Generate Name</th>
<th>LangFuse Generation/Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>user\_id</td>
</tr>
<tr>
<td>generate\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>input</td>
</tr>
<tr>
<td>outputs</td>
<td>output</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\[generate\_name]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated session name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
### Langfuse Prompt Management
The [Langfuse Prompt Management Plugin](https://github.com/gao-ai-com/dify-plugin-langfuse) (community maintained) lets you use prompts that are [managed and versioned in Langfuse](https://langfuse.com/docs/prompt-management/get-started) in your Dify applications, enhancing your LLM application development workflow. Key features include:
* **Get Prompt**: Fetch specific prompts managed in Langfuse.
* **Search Prompts**: Search for prompts in Langfuse using various filters.
* **Update Prompt**: Create new versions of prompts in Langfuse and set tags/labels.
This integration streamlines the process of managing and versioning your prompts, contributing to more efficient development and iteration cycles. You can find the plugin and installation instructions [here](https://github.com/gao-ai-com/dify-plugin-langfuse).
# Integrate with LangSmith
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-langsmith
### What is LangSmith
LangSmith is a platform for building production-grade LLM applications. It is used for developing, collaborating, testing, deploying, and monitoring LLM applications.
<Info>
For more details, please refer to [LangSmith](https://www.langchain.com/langsmith).
</Info>
### How to Configure LangSmith
#### 1. Register/Login to [LangSmith](https://www.langchain.com/langsmith)
#### 2. Create a Project
Create a project in LangSmith. After logging in, click **New Project** on the homepage to create your own project. The **project** will be used to associate with **applications** in Dify for data monitoring.
<Frame>
</Frame>
Once created, you can view all created projects in the Projects section.
<Frame>
</Frame>
#### 3. Create Project Credentials
Find the project settings **Settings** in the left sidebar.
<Frame>
</Frame>
Click **Create API Key** to create project credentials.
<Frame>
</Frame>
Select **Personal Access Token** for subsequent API authentication.
<Frame>
</Frame>
Copy and save the created API key.
<Frame>
</Frame>
#### 4. Integrate LangSmith with Dify
Configure LangSmith in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>
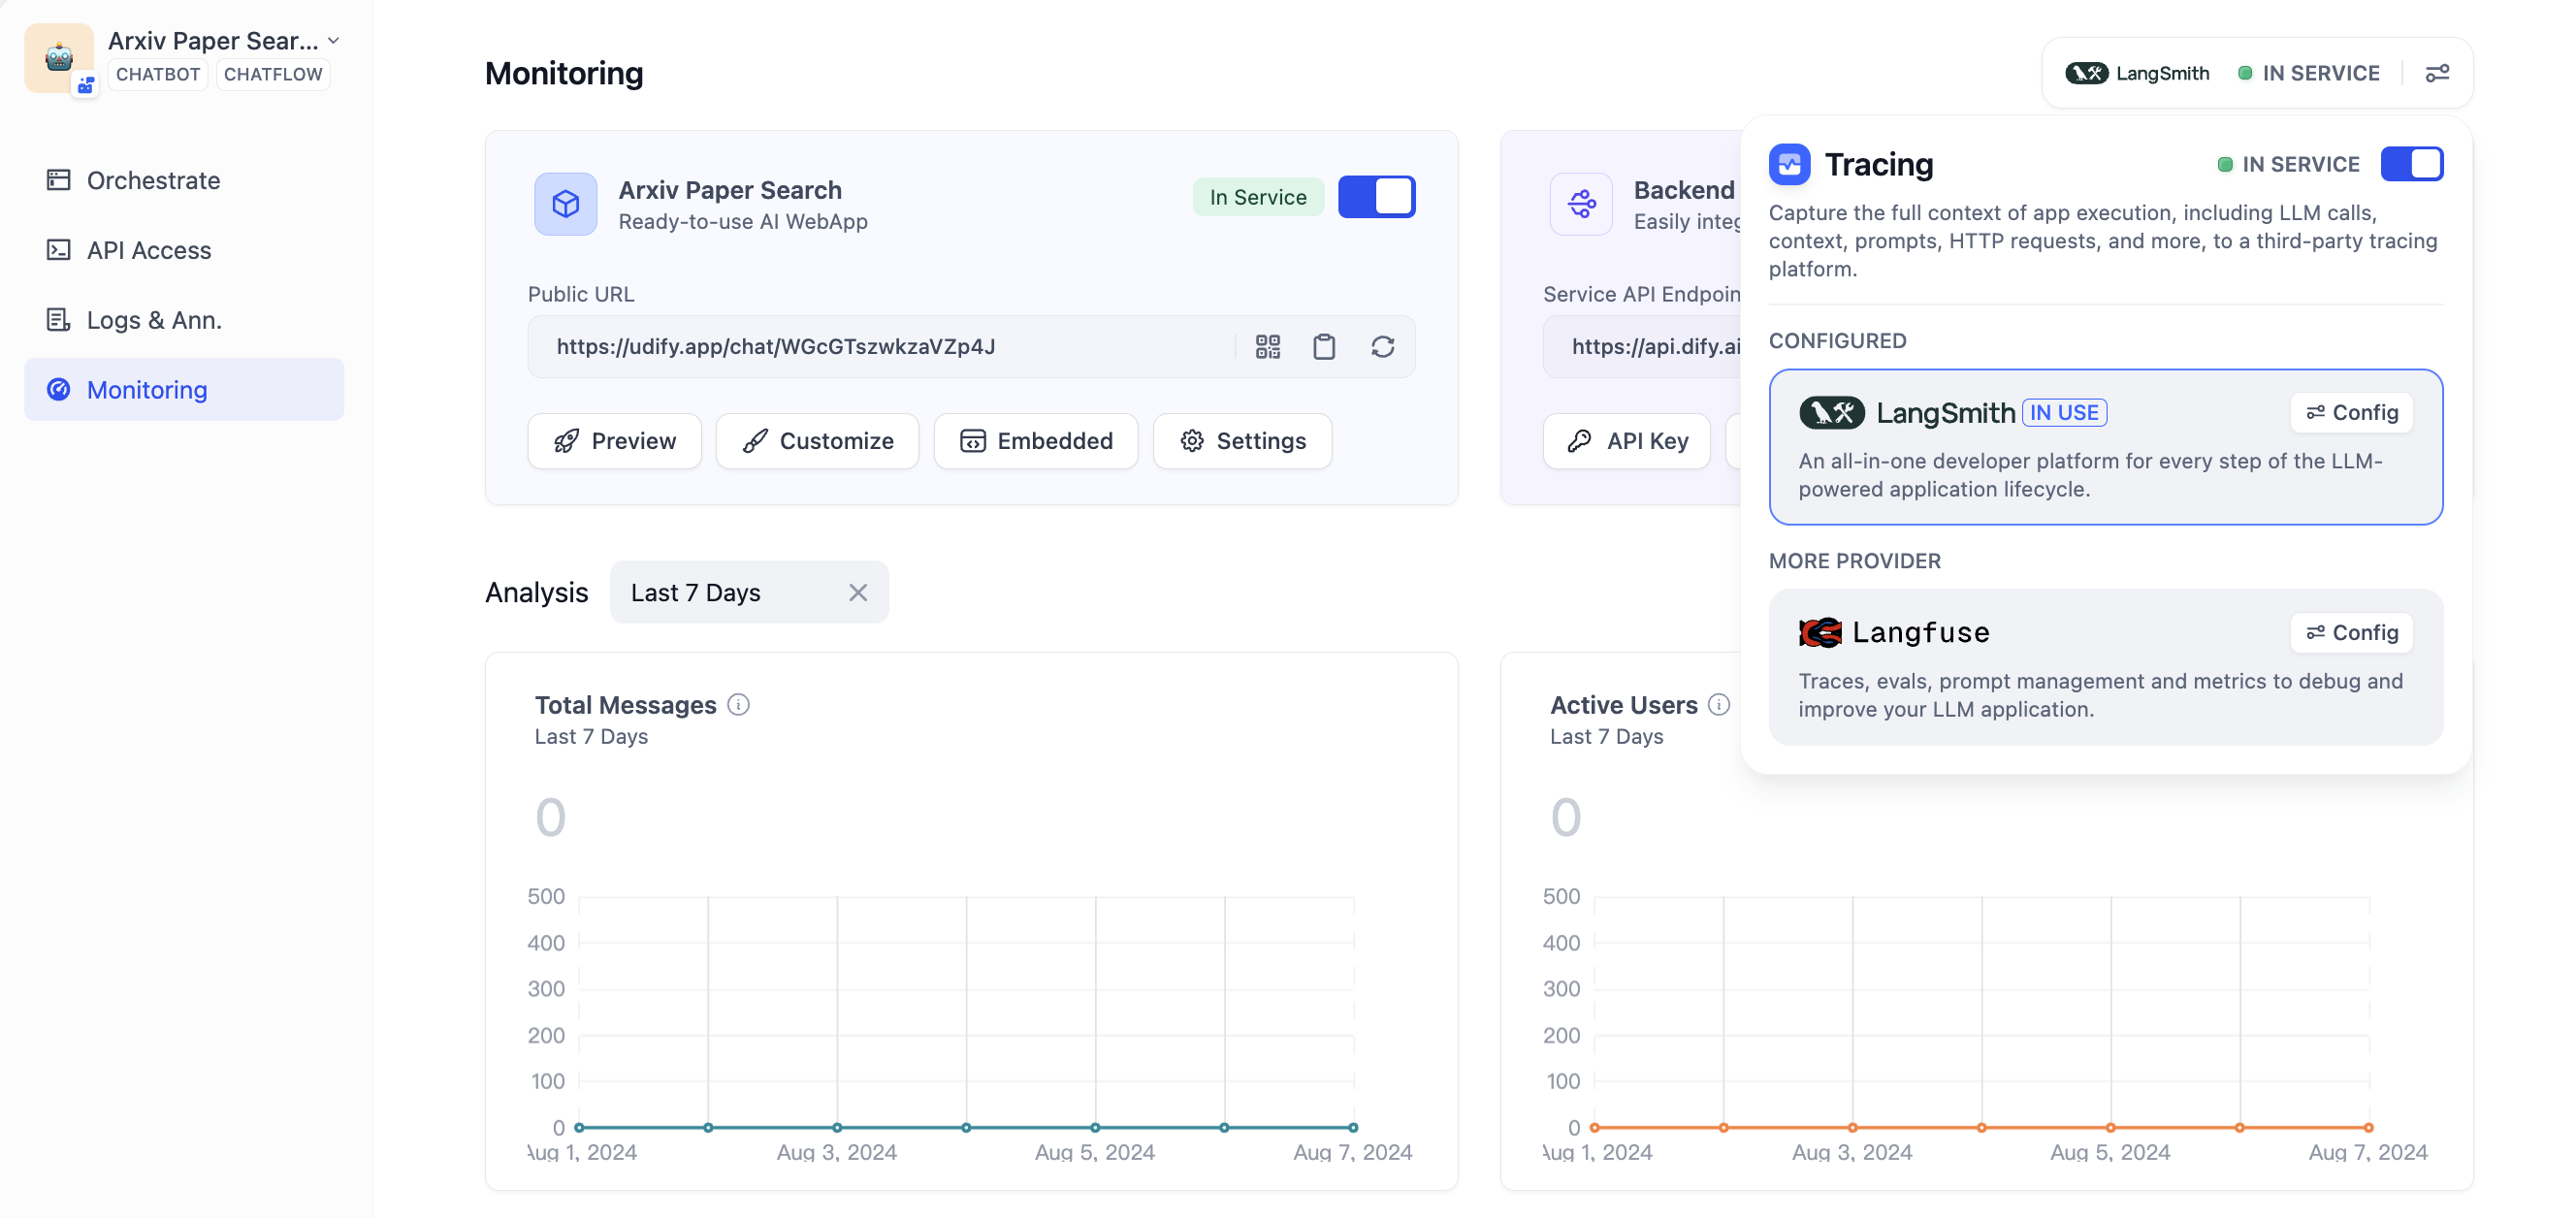
</Frame>
After clicking configure, paste the **API Key** and **project name** created in LangSmith into the configuration and save.
<Frame>
</Frame>
<Info>
The configured project name needs to match the project set in LangSmith. If the project names do not match, LangSmith will automatically create a new project during data synchronization.
</Info>
Once successfully saved, you can view the monitoring status on the current page.
<Frame>
</Frame>
### View Monitoring Data in LangSmith
Once configured, the debug or production data from applications within Dify can be monitored in LangSmith.
<Frame>
</Frame>
When you switch to LangSmith, you can view detailed operation logs of Dify applications in the dashboard.
<Frame>
</Frame>
Detailed LLM operation logs through LangSmith will help you optimize the performance of your Dify application.
<Frame>
</Frame>
### Monitoring Data List
#### **Workflow/Chatflow Trace Information**
**Used to track workflows and chatflows**
<table>
<thead>
<tr>
<th>Workflow</th>
<th>LangSmith Chain</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_app\_log\_id/workflow\_run\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>error</td>
<td>error</td>
</tr>
<tr>
<td>\[workflow]</td>
<td>tags</td>
</tr>
<tr>
<td>"conversation\_id/none for workflow"</td>
<td>conversation\_id in metadata</td>
</tr>
<tr>
<td>conversion\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
<table>
<thead>
<tr>
<th>Chat</th>
<th>LangSmith LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>error</td>
<td>error</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>tags</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>conversation\_id in metadata</td>
</tr>
<tr>
<td>conversion\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
<table>
<thead>
<tr>
<th>Moderation</th>
<th>LangSmith Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>“moderation"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>\[moderation]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
<table>
<thead>
<tr>
<th>Suggested Question</th>
<th>LangSmith LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>suggested\_question</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>\[suggested\_question]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>LangSmith Retriever</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>dataset\_retrieval</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>\[dataset\_retrieval]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
<table>
<thead>
<tr>
<th>Tool</th>
<th>LangSmith Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>tool\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>\["tool", tool\_name]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
<table>
<thead>
<tr>
<th>Generate Name</th>
<th>LangSmith Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>generate\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>extra</td>
</tr>
<tr>
<td>\[generate\_name]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Opik
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-opik
### What is Opik
Opik is an open-source platform designed for evaluating, testing, and monitoring large language model (LLM) applications. Developed by Comet, it aims to facilitate more intuitive collaboration, testing, and monitoring of LLM-based applications.
<Info>
For more details, please refer to [Opik](https://www.comet.com/site/products/opik/).
</Info>
***
### How to Configure Opik
#### 1. Register/Login to [Opik](https://www.comet.com/signup?from=llm)
#### 2. Get your Opik API Key
Retrieve your Opik API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
<Frame>
</Frame>
#### 3. Integrate Opik with Dify
Configure Opik in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>
</Frame>
After clicking configure, paste the **API Key** and **project name** created in Opik into the configuration and save.
<Frame>
</Frame>
Once successfully saved, you can view the monitoring status on the current page.
### View Monitoring Data in Opik
Once configured, you can debug or use the Dify application as usual. All usage history can be monitored in Opik.
<Frame>
</Frame>
When you switch to Opik, you can view detailed operation logs of Dify applications in the dashboard.
<Frame>
</Frame>
Detailed LLM operation logs through Opik will help you optimize the performance of your Dify application.
<Frame>
</Frame>
### Monitoring Data List
#### **Workflow/Chatflow Trace Information**
**Used to track workflows and chatflows**
<table>
<thead>
<tr>
<th>Workflow</th>
<th>Opik Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_app\_log\_id/workflow\_run\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>error</td>
<td>error</td>
</tr>
<tr>
<td>\[workflow]</td>
<td>tags</td>
</tr>
<tr>
<td>"conversation\_id/none for workflow"</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
<table>
<thead>
<tr>
<th>Chat</th>
<th>Opik LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"llm"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>tags</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
<table>
<thead>
<tr>
<th>Moderation</th>
<th>Opik Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>“moderation"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["moderation"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
<table>
<thead>
<tr>
<th>Suggested Question</th>
<th>Opik LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"suggested\_question"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["suggested\_question"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>Opik Retriever</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"dataset\_retrieval"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["dataset\_retrieval"]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
<table>
<thead>
<tr>
<th>Tool</th>
<th>Opik Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>tool\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["tool", tool\_name]</td>
<td>tags</td>
</tr>
</tbody>
</table>
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
<table>
<thead>
<tr>
<th>Generate Name</th>
<th>Opik Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"generate\_conversation\_name"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["generate\_name"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with Phoenix
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-phoenix
### What is Phoenix
[Arize Phoenix](https://arize.com/phoenix/) is the open-source, OpenTelemetry-based platform from [Arize AI](https://arize.com/?utm_source=dify-docs\&utm_medium=partner\&utm_campaign=partner-docs\&utm_content=integrate-phoenix-self-host) for observability, evaluation, prompt engineering, and experimentation with LLM workflows and agents.
Run Phoenix locally during development, self-host it on your own infrastructure (a single container is enough to start), or use Arize's hosted [Phoenix Cloud](#how-to-configure-phoenix-cloud).
If you need the full-featured platform built for production teams, AI-native companies, and enterprises, set up [Arize AX](https://arize.com/products/ax/) through the [Arize integration](/en/self-host/use-dify/monitor/integrations/integrate-arize) instead.
Once traces are flowing, see Arize's [agent evaluation guide](https://arize.com/guides/ai-agent-handbook/agent-evaluation/) and [LLM evaluation guide](https://arize.com/resources/llm-evaluation/) for how to use them to debug failures, evaluate agent behavior, and monitor model quality.
### How to Configure Phoenix
#### 1. Register/Login to [Phoenix](https://app.arize.com/auth/phoenix/signup)
#### 2. Get your Phoenix API Key
Retrieve your Phoenix API Key from the user menu at the top-right. Click on **API Key**, then on the API Key to copy it:
<Frame>

</Frame>
#### 3. Integrate Phoenix with Dify
Configure Phoenix in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>

</Frame>
After clicking configure, paste the **API Key** and **project name** created in Phoenix into the configuration and save.
<Frame>

</Frame>
Once successfully saved, you can view the monitoring status on the current page.
<Frame>

</Frame>
### How to Configure Phoenix Cloud
#### 1. Register/Login to [Phoenix Cloud](https://app.arize.com/auth/phoenix/signup)
#### 2. Create your Phoenix Space
You can create your Phoenix Space from the user menu at the top-right. Click on **Create Space**, then provide a unique URL identifier for your space:
<Frame>

</Frame>
Once successfully saved, you can view the space status on the overview page.
<Frame>

</Frame>
#### 3. Create your Phoenix API Key
After launching your space, you can create your Phoenix API Key from the **Settings** option in the user menu at the bottom-left. Click on **System Key**, then provide a name for your Phoenix API Key:
<Frame>

</Frame>
#### 4. Integrate Phoenix Cloud with Dify
Configure Phoenix in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>

</Frame>
After clicking configure, paste the **API Key** and **project name** along with **Space Hostname** created in Phoenix Cloud into the configuration and save.
<Frame>

</Frame>
Once successfully saved, you can view the monitoring status on the current page.
<Frame>

</Frame>
### Monitoring Data List
#### **Workflow/Chatflow Trace Information**
**Used to track workflows and chatflows**
<table>
<thead>
<tr>
<th>Workflow</th>
<th>Phoenix Trace</th>
</tr>
</thead>
<tbody>
<tr>
<td>workflow\_app\_log\_id/workflow\_run\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>error</td>
<td>error</td>
</tr>
<tr>
<td>\[workflow]</td>
<td>tags</td>
</tr>
<tr>
<td>"conversation\_id/none for workflow"</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
<table>
<thead>
<tr>
<th>Chat</th>
<th>Phoenix LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>message\_id</td>
<td>id</td>
</tr>
<tr>
<td>user\_session\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"llm"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>Model token consumption</td>
<td>usage\_metadata</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["message", conversation\_mode]</td>
<td>tags</td>
</tr>
<tr>
<td>conversation\_id</td>
<td>conversation\_id in metadata</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
<table>
<thead>
<tr>
<th>Moderation</th>
<th>Phoenix Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>“moderation"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["moderation"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
<table>
<thead>
<tr>
<th>Suggested Question</th>
<th>Phoenix LLM</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"suggested\_question"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["suggested\_question"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
<table>
<thead>
<tr>
<th>Dataset Retrieval</th>
<th>Phoenix Retriever</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"dataset\_retrieval"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["dataset\_retrieval"]</td>
<td>tags</td>
</tr>
<tr>
<td>message\_id</td>
<td>parent\_run\_id</td>
</tr>
</tbody>
</table>
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
<table>
<thead>
<tr>
<th>Tool</th>
<th>Phoenix Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>tool\_name</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["tool", tool\_name]</td>
<td>tags</td>
</tr>
</tbody>
</table>
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
<table>
<thead>
<tr>
<th>Generate Name</th>
<th>Phoenix Tool</th>
</tr>
</thead>
<tbody>
<tr>
<td>user\_id</td>
<td>- placed in metadata</td>
</tr>
<tr>
<td>"generate\_conversation\_name"</td>
<td>name</td>
</tr>
<tr>
<td>start\_time</td>
<td>start\_time</td>
</tr>
<tr>
<td>end\_time</td>
<td>end\_time</td>
</tr>
<tr>
<td>inputs</td>
<td>inputs</td>
</tr>
<tr>
<td>outputs</td>
<td>outputs</td>
</tr>
<tr>
<td>metadata</td>
<td>metadata</td>
</tr>
<tr>
<td>\["generate\_name"]</td>
<td>tags</td>
</tr>
</tbody>
</table>
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Integrate with W&B Weave
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/integrations/integrate-weave
Send traces from Dify applications to W&B Weave for LLM observability
<Info>
**Prerequisites**: Dify v1.3.1 or later.
</Info>
### What is W\&B Weave
Weights & Biases (W\&B) Weave is a framework for tracking, experimenting with, evaluating, deploying, and improving LLM-based applications. Designed for flexibility and scalability, Weave supports every stage of your LLM application development workflow.
<Info>
For more details, please refer to [Weave](https://docs.wandb.ai/weave).
</Info>
### How to Configure Weave
#### 1. Register/Login
Register/Login to [W\&B Weave](https://wandb.ai/signup) and get your API key. Then, copy your API key from [here](https://wandb.ai/authorize).
#### 2. Integrate W\&B Weave with Dify
Configure Weave in the Dify application. Open the application you need to monitor, open **Monitoring** in the side menu, and select **Tracing app performance** on the page.
<Frame>
</Frame>
After clicking configure, paste the **API Key** and **project name**, also specify the **W\&B entity**(optionally, default is your username) into the configuration and save.
<Frame>
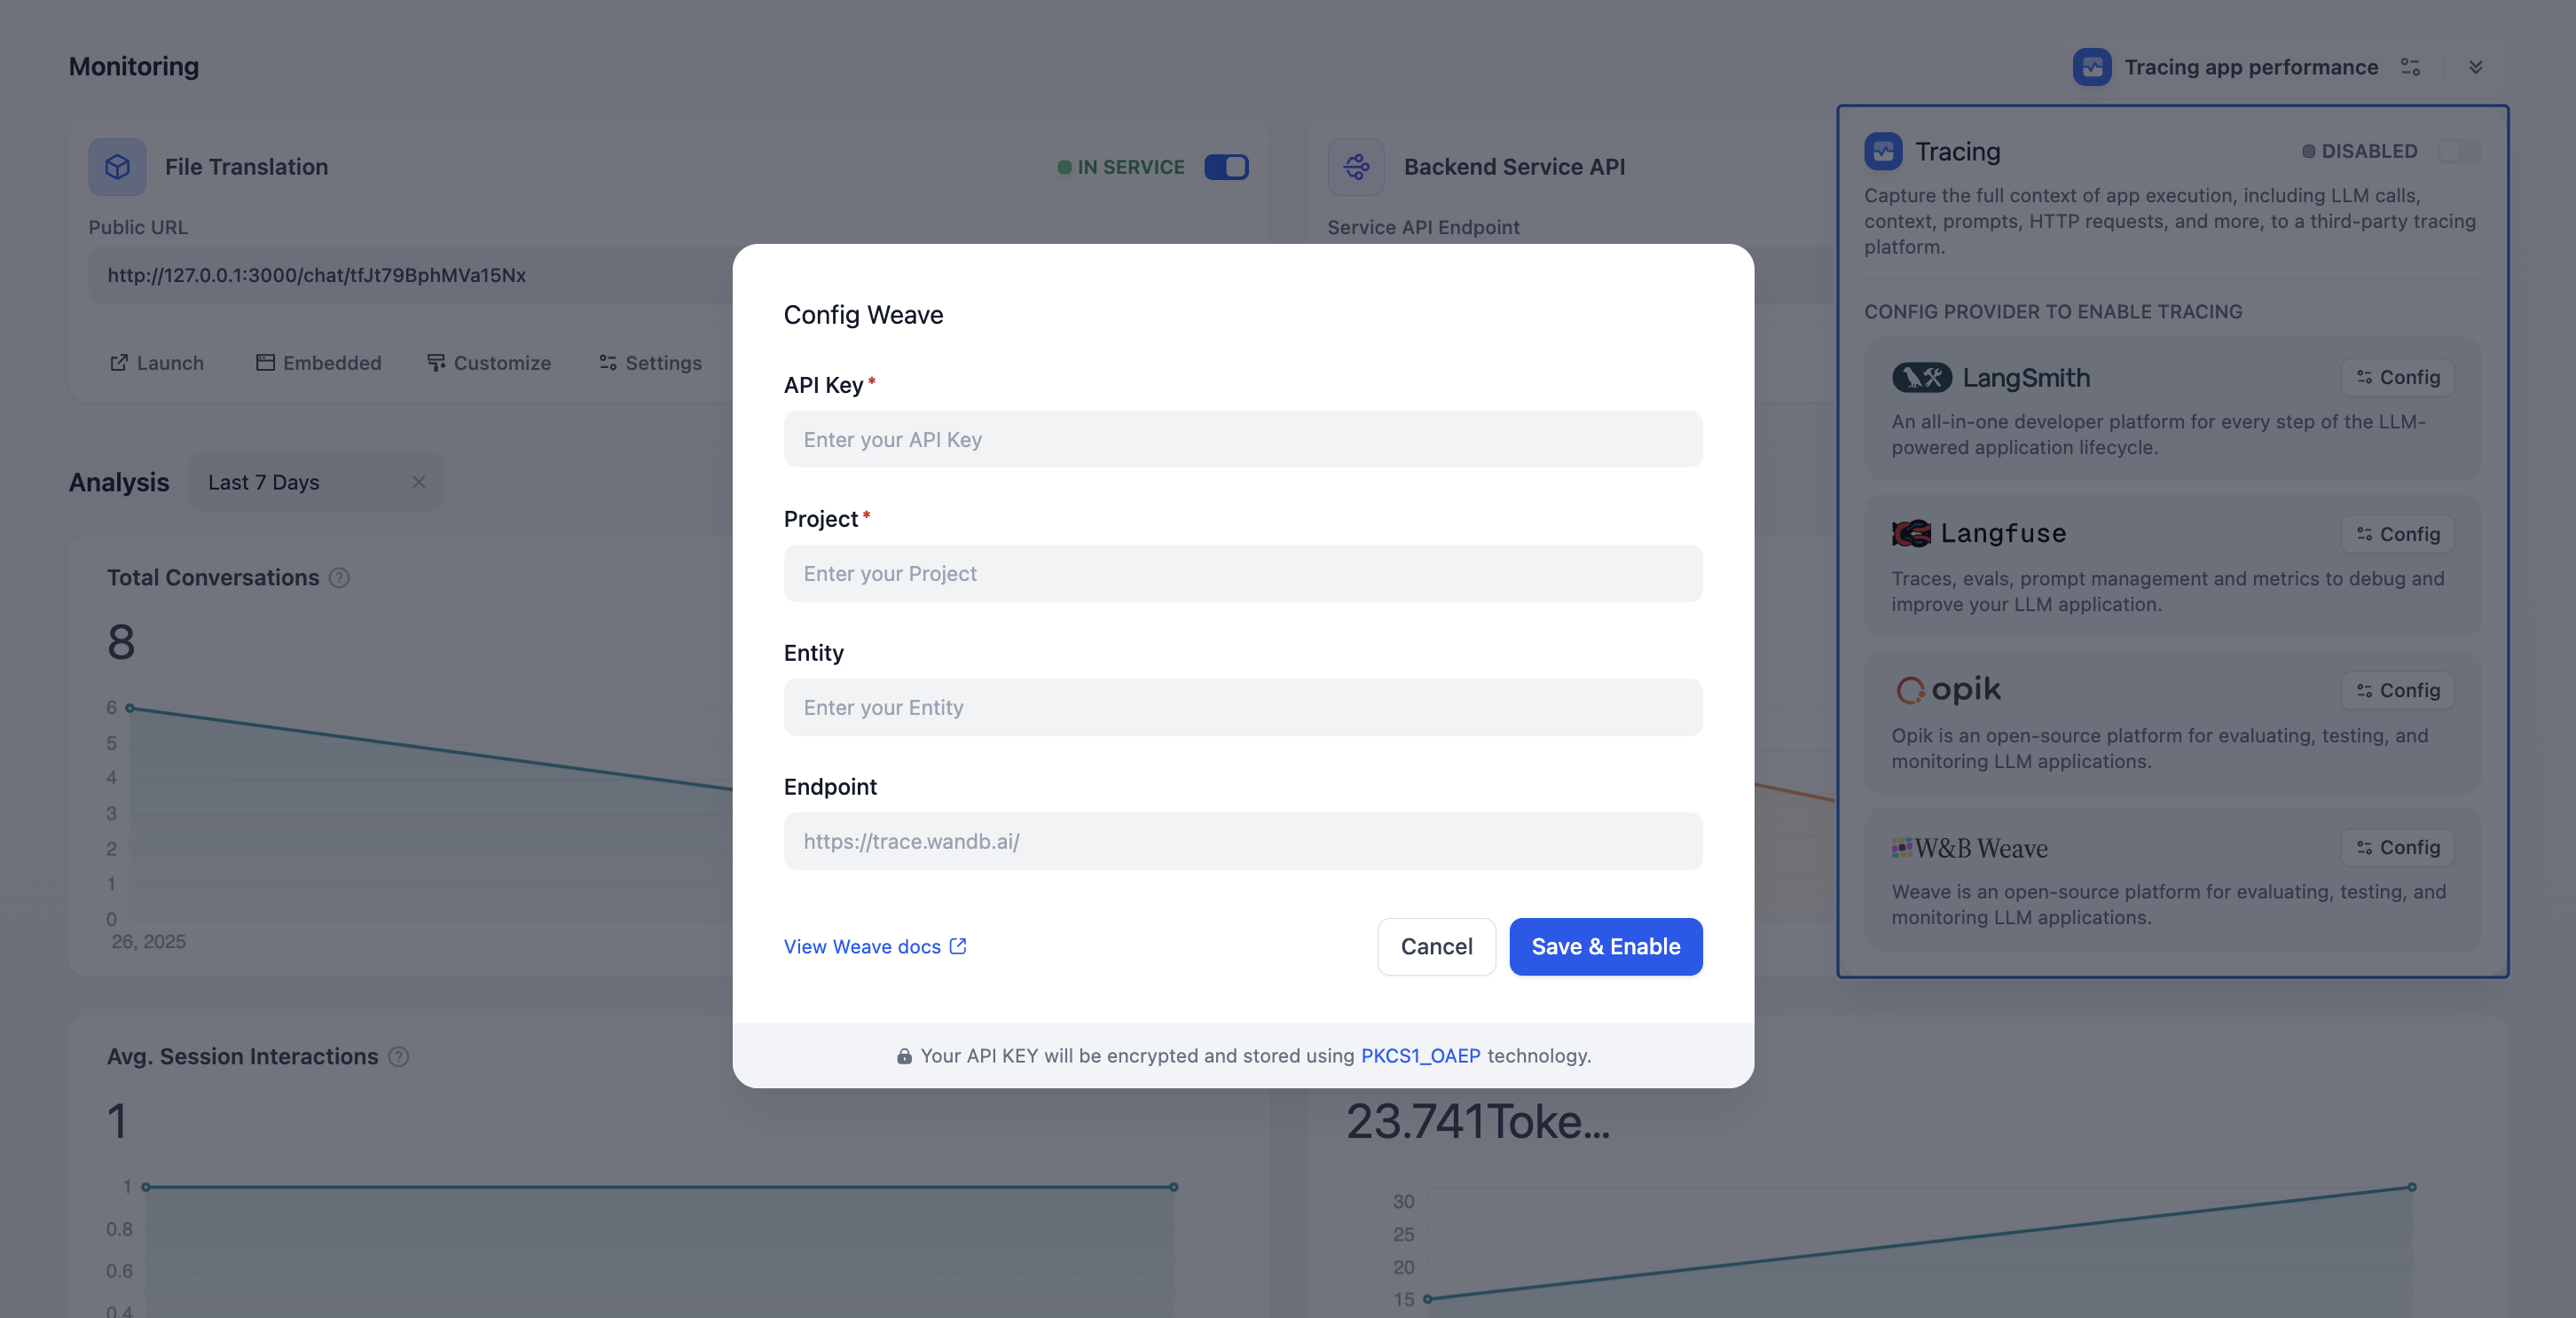
</Frame>
Once successfully saved, you can view the monitoring status on the current page.
<Frame>
</Frame>
### View Monitoring Data in Weave
Once configured, the debug or production data from applications within Dify can be monitored in Weave.
<Frame>
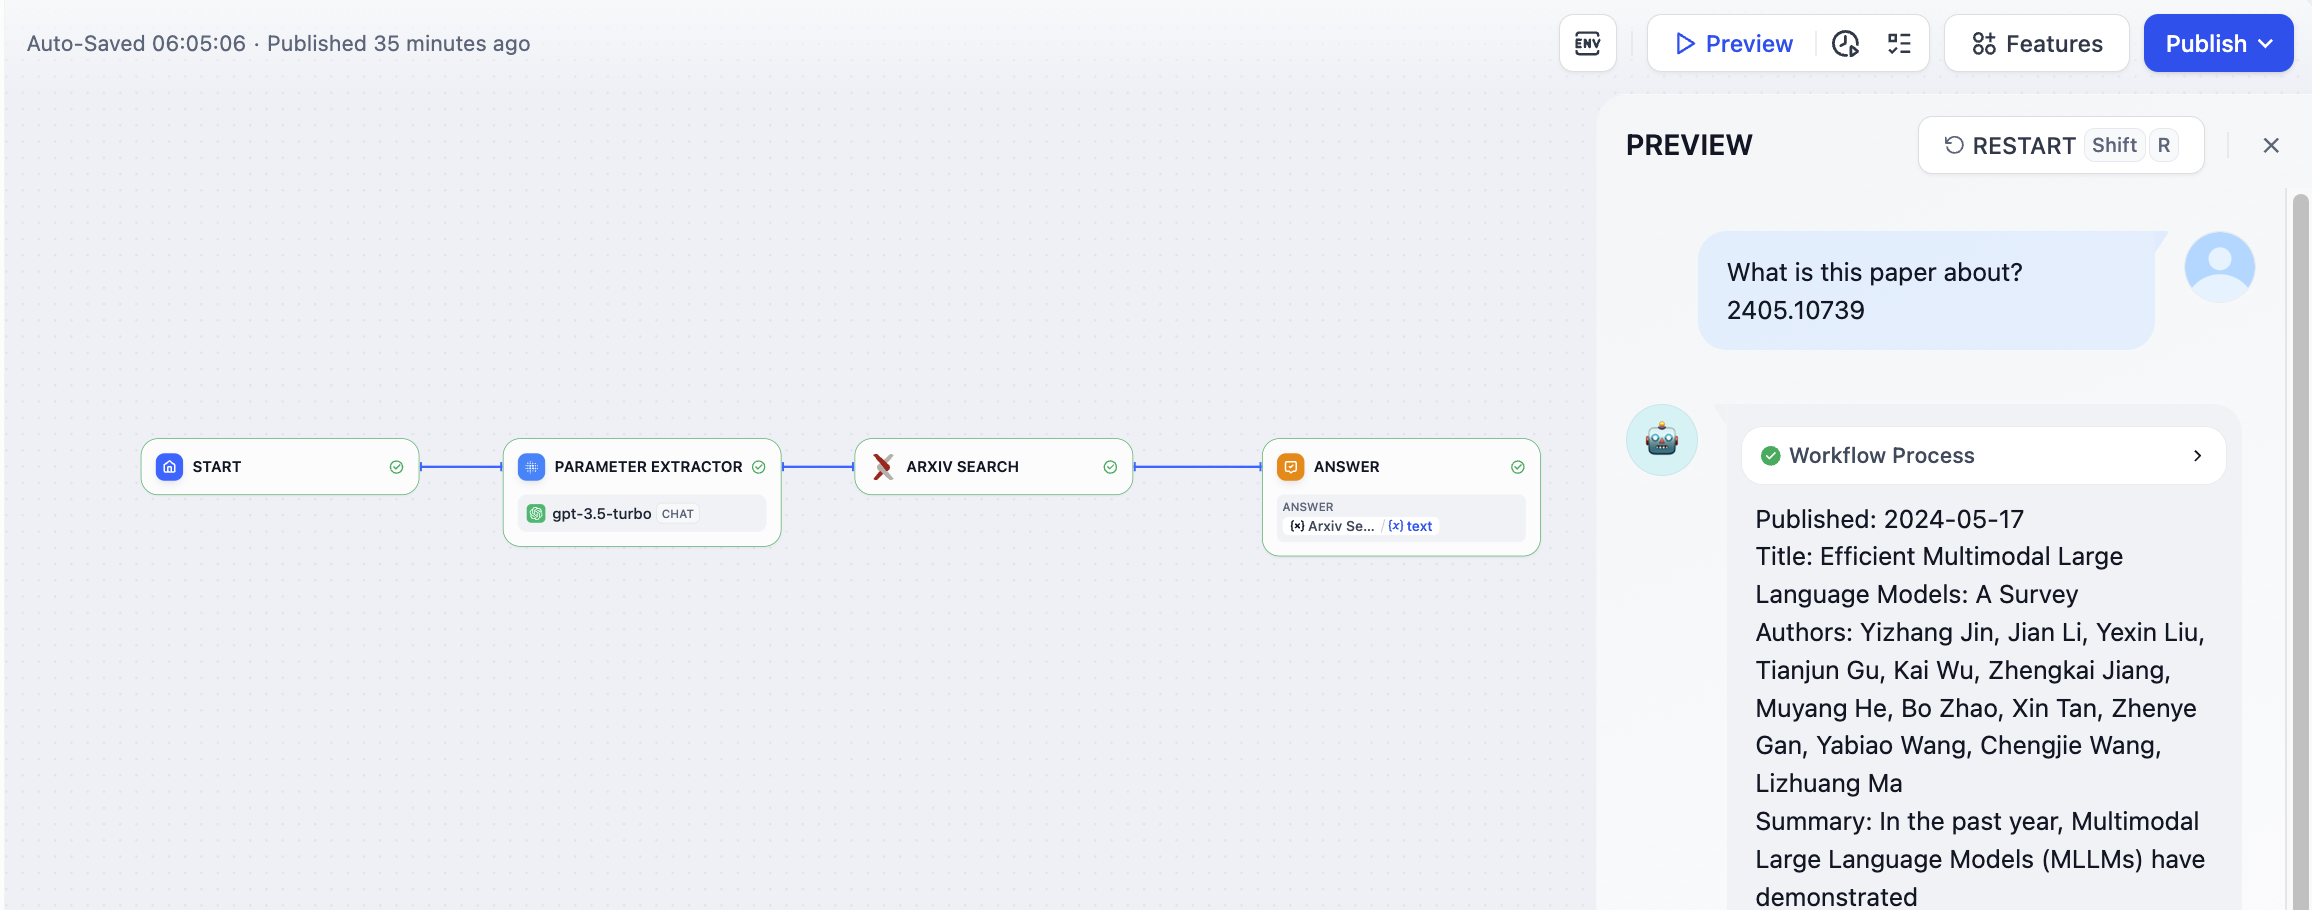
</Frame>
When you switch to Weave, you can view detailed operation logs of Dify applications in the dashboard.
<Frame>
</Frame>
Detailed LLM operation logs through Weave will help you optimize the performance of your Dify application.
### Monitoring Data List
#### **Workflow/Chatflow Trace Information**
**Used to track workflows and chatflows**
| Workflow | Weave Trace |
| ---------------------------------------- | ---------------------------- |
| workflow\_app\_log\_id/workflow\_run\_id | id |
| user\_session\_id | placed in metadata |
| workflow\_\{id} | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| Model token consumption | usage\_metadata |
| metadata | extra |
| error | error |
| workflow | tags |
| "conversation\_id/none for workflow" | conversation\_id in metadata |
| conversion\_id | parent\_run\_id |
**Workflow Trace Info**
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
* workflow\_run\_inputs - Input data for the current run
* workflow\_run\_outputs - Output data for the current run
* error - Errors encountered during the current run
* query - Query used during the run
* workflow\_app\_log\_id - Workflow application log ID
* message\_id - Associated message ID
* start\_time - Start time of the run
* end\_time - End time of the run
* workflow node executions - Information about workflow node executions
* Metadata
* workflow\_id - Unique identifier of the workflow
* conversation\_id - Conversation ID
* workflow\_run\_id - ID of the current run
* tenant\_id - Tenant ID
* elapsed\_time - Time taken for the current run
* status - Run status
* version - Workflow version
* total\_tokens - Total tokens used in the current run
* file\_list - List of processed files
* triggered\_from - Source that triggered the current run
#### **Message Trace Information**
**Used to track LLM-related conversations**
| Chat | Weave Trace |
| ----------------------------- | ---------------------------- |
| message\_id | id |
| user\_session\_id | placed in metadata |
| "message\_\{id}" | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| Model token consumption | usage\_metadata |
| metadata | extra |
| error | error |
| "message", conversation\_mode | tags |
| conversation\_id | conversation\_id in metadata |
| conversion\_id | parent\_run\_id |
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* user\_session\_id - User session ID
* conversation\_model - Conversation mode
* message\_tokens - Number of tokens in the message
* answer\_tokens - Number of tokens in the answer
* total\_tokens - Total number of tokens in the message and answer
* error - Error information
* inputs - Input data
* outputs - Output data
* file\_list - List of processed files
* start\_time - Start time
* end\_time - End time
* message\_file\_data - File data associated with the message
* conversation\_mode - Conversation mode
* Metadata
* conversation\_id - Conversation ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Moderation Trace Information**
**Used to track conversation moderation**
| Moderation | Weave Trace |
| ------------ | ------------------ |
| user\_id | placed in metadata |
| “moderation" | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| metadata | extra |
| moderation | tags |
| message\_id | parent\_run\_id |
**Moderation Trace Info**
* message\_id - Message ID
* user\_id: User ID
* workflow\_app\_log\_id - Workflow application log ID
* inputs - Moderation input data
* message\_data - Message data
* flagged - Whether the content is flagged for attention
* action - Specific actions taken
* preset\_response - Preset response
* start\_time - Moderation start time
* end\_time - Moderation end time
* Metadata
* message\_id - Message ID
* action - Specific actions taken
* preset\_response - Preset response
#### **Suggested Question Trace Information**
**Used to track suggested questions**
| Suggested Question | Weave Trace |
| ------------------- | ------------------ |
| user\_id | placed in metadata |
| suggested\_question | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| metadata | extra |
| suggested\_question | tags |
| message\_id | parent\_run\_id |
**Message Trace Info**
* message\_id - Message ID
* message\_data - Message data
* inputs - Input content
* outputs - Output content
* start\_time - Start time
* end\_time - End time
* total\_tokens - Number of tokens
* status - Message status
* error - Error information
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* from\_source - Message source
* model\_provider - Model provider
* model\_id - Model ID
* suggested\_question - Suggested question
* level - Status level
* status\_message - Status message
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Dataset Retrieval Trace Information**
**Used to track knowledge base retrieval**
| Dataset Retrieval | Weave Trace |
| ------------------ | ------------------ |
| user\_id | placed in metadata |
| dataset\_retrieval | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| metadata | extra |
| dataset\_retrieval | tags |
| message\_id | parent\_run\_id |
**Dataset Retrieval Trace Info**
* message\_id - Message ID
* inputs - Input content
* documents - Document data
* start\_time - Start time
* end\_time - End time
* message\_data - Message data
* Metadata
* message\_id - Message ID
* ls\_provider - Model provider
* ls\_model\_name - Model ID
* status - Message status
* from\_end\_user\_id - ID of the sending user
* from\_account\_id - ID of the sending account
* agent\_based - Whether the message is agent-based
* workflow\_run\_id - Workflow run ID
* from\_source - Message source
#### **Tool Trace Information**
**Used to track tool invocation**
| Tool | Weave Trace |
| ------------------ | ------------------ |
| user\_id | placed in metadata |
| tool\_name | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| metadata | extra |
| "tool", tool\_name | tags |
| message\_id | parent\_run\_id |
#### **Tool Trace Info**
* message\_id - Message ID
* tool\_name - Tool name
* start\_time - Start time
* end\_time - End time
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* message\_data - Message data
* error - Error information, if any
* inputs - Inputs for the message
* outputs - Outputs of the message
* tool\_config - Tool configuration
* time\_cost - Time cost
* tool\_parameters - Tool parameters
* file\_url - URL of the associated file
* Metadata
* message\_id - Message ID
* tool\_name - Tool name
* tool\_inputs - Tool inputs
* tool\_outputs - Tool outputs
* tool\_config - Tool configuration
* time\_cost - Time cost
* error - Error information, if any
* tool\_parameters - Tool parameters
* message\_file\_id - Message file ID
* created\_by\_role - Role of the creator
* created\_user\_id - User ID of the creator
**Generate Name Trace Information**
**Used to track conversation title generation**
| Generate Name | Weave Trace |
| -------------- | ------------------ |
| user\_id | placed in metadata |
| generate\_name | name |
| start\_time | start\_time |
| end\_time | end\_time |
| inputs | inputs |
| outputs | outputs |
| metadata | extra |
| generate\_name | tags |
**Generate Name Trace Info**
* conversation\_id - Conversation ID
* inputs - Input data
* outputs - Generated conversation name
* start\_time - Start time
* end\_time - End time
* tenant\_id - Tenant ID
* Metadata
* conversation\_id - Conversation ID
* tenant\_id - Tenant ID
# Logs
Source: https://docs.dify.ai/en/self-host/use-dify/monitor/logs
Browse and inspect your app's conversation and run logs, and configure log retention
In the **Logs** tab of any app, see how it is actually used: what people asked or submitted, how the app responded, and what feedback came back.
Chat-based apps (Chatbot, Chatflow, Agent) and Text Generator apps log conversations; Workflow apps log runs.
## What Gets Logged
Logs capture real usage from every channel: the web app, the API, and apps opened from the **WEB APPS** list on **Home**. For Workflow apps, runs started by [triggers](/en/self-host/use-dify/nodes/trigger/overview) are logged too.
End-user feedback (thumbs up/down and comments) is stored with the messages it refers to.
Test sessions from the app editor are excluded for Chatflow and Workflow apps (**Preview** and **Test Run**). For other app types they are listed, under the team member's account.
## Browse Logs
Each row is one conversation or one run. Most columns explain themselves, but a few deserve context:
* **Title** is generated from the conversation's first message.
* **End User or Account** shows a session ID for web app and API usage, or the team member's account for usage inside Dify.
* **User Rate** counts end users' likes and dislikes; **Op. Rate** (operator rate) counts your team's. Both aggregate across the whole conversation.
* **Trigger By** (Workflow apps) shows what started each run:
* **WebApp**: The published web app, or a call through the API
* **Webhook**: A webhook trigger receiving a request
* **Schedule**: A schedule trigger reaching its scheduled time
* **Integration**: An event from a connected integration
To find a conversation, search words from its messages or the end user's session ID. To find a workflow run, search its inputs or outputs, or paste the run ID.
## Inspect a Conversation
Click a row to open the full message thread. When you hover over an answer, you can:
* See its token spend and latency.
* Open the log behind it: the raw prompt, an Agent app's tool iterations, or a Chatflow message's node-by-node trace.
* Rate the answer as team feedback; a dislike can carry a comment explaining what went wrong. Team ratings fill the **Op. Rate** column, separate from end-user feedback.
* Add an annotation pairing the question with an improved reply. See [Annotation System](/en/self-host/use-dify/monitor/annotation-reply) for how annotated replies take effect.
To share a log entry with a teammate, copy its link in your browser's address bar.
## Inspect a Run
For Workflow apps, click a run to open its result, its inputs and outputs with status and token totals, and a node-by-node trace that pinpoints where a run failed or slowed down.
To reproduce an issue, click **Test With Params**: the workflow re-runs in the editor with this run's inputs.
<Frame>
<img alt="Test With Params" />
</Frame>
## Log Retention
<Warning>
Logs contain complete user conversations and may include sensitive information. Ensure your application complies with local data privacy regulations: publish a privacy policy and obtain user consent where required.
Deleting conversations or cleaning up old logs does not erase the files uploaded in them.
</Warning>
Logs are retained indefinitely by default. To clean up old logs on a schedule:
* **Workflow run logs**: set `WORKFLOW_LOG_CLEANUP_ENABLED` to `true`, and `WORKFLOW_LOG_RETENTION_DAYS` to the number of days to keep (default 30). See [Workflow Log Cleanup](/en/self-host/deploy/configuration/environments#workflow-log-cleanup) for details.
* **Conversation messages**: set `ENABLE_CLEAN_MESSAGES` to `true`, and `SANDBOX_EXPIRED_RECORDS_RETENTION_DAYS` to the number of days to keep (default 30).
Cleanup runs as a scheduled daily task; nothing is deleted the moment you set the variables. Consider shorter retention windows for applications that handle sensitive data.
# Document Extractor
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/doc-extractor
Extract text content from uploaded documents for AI processing
The Document Extractor node converts uploaded files into text that LLMs can process. Since language models can't directly read document formats like PDF or DOCX, this node serves as the essential bridge between file uploads and AI analysis.
<Frame>
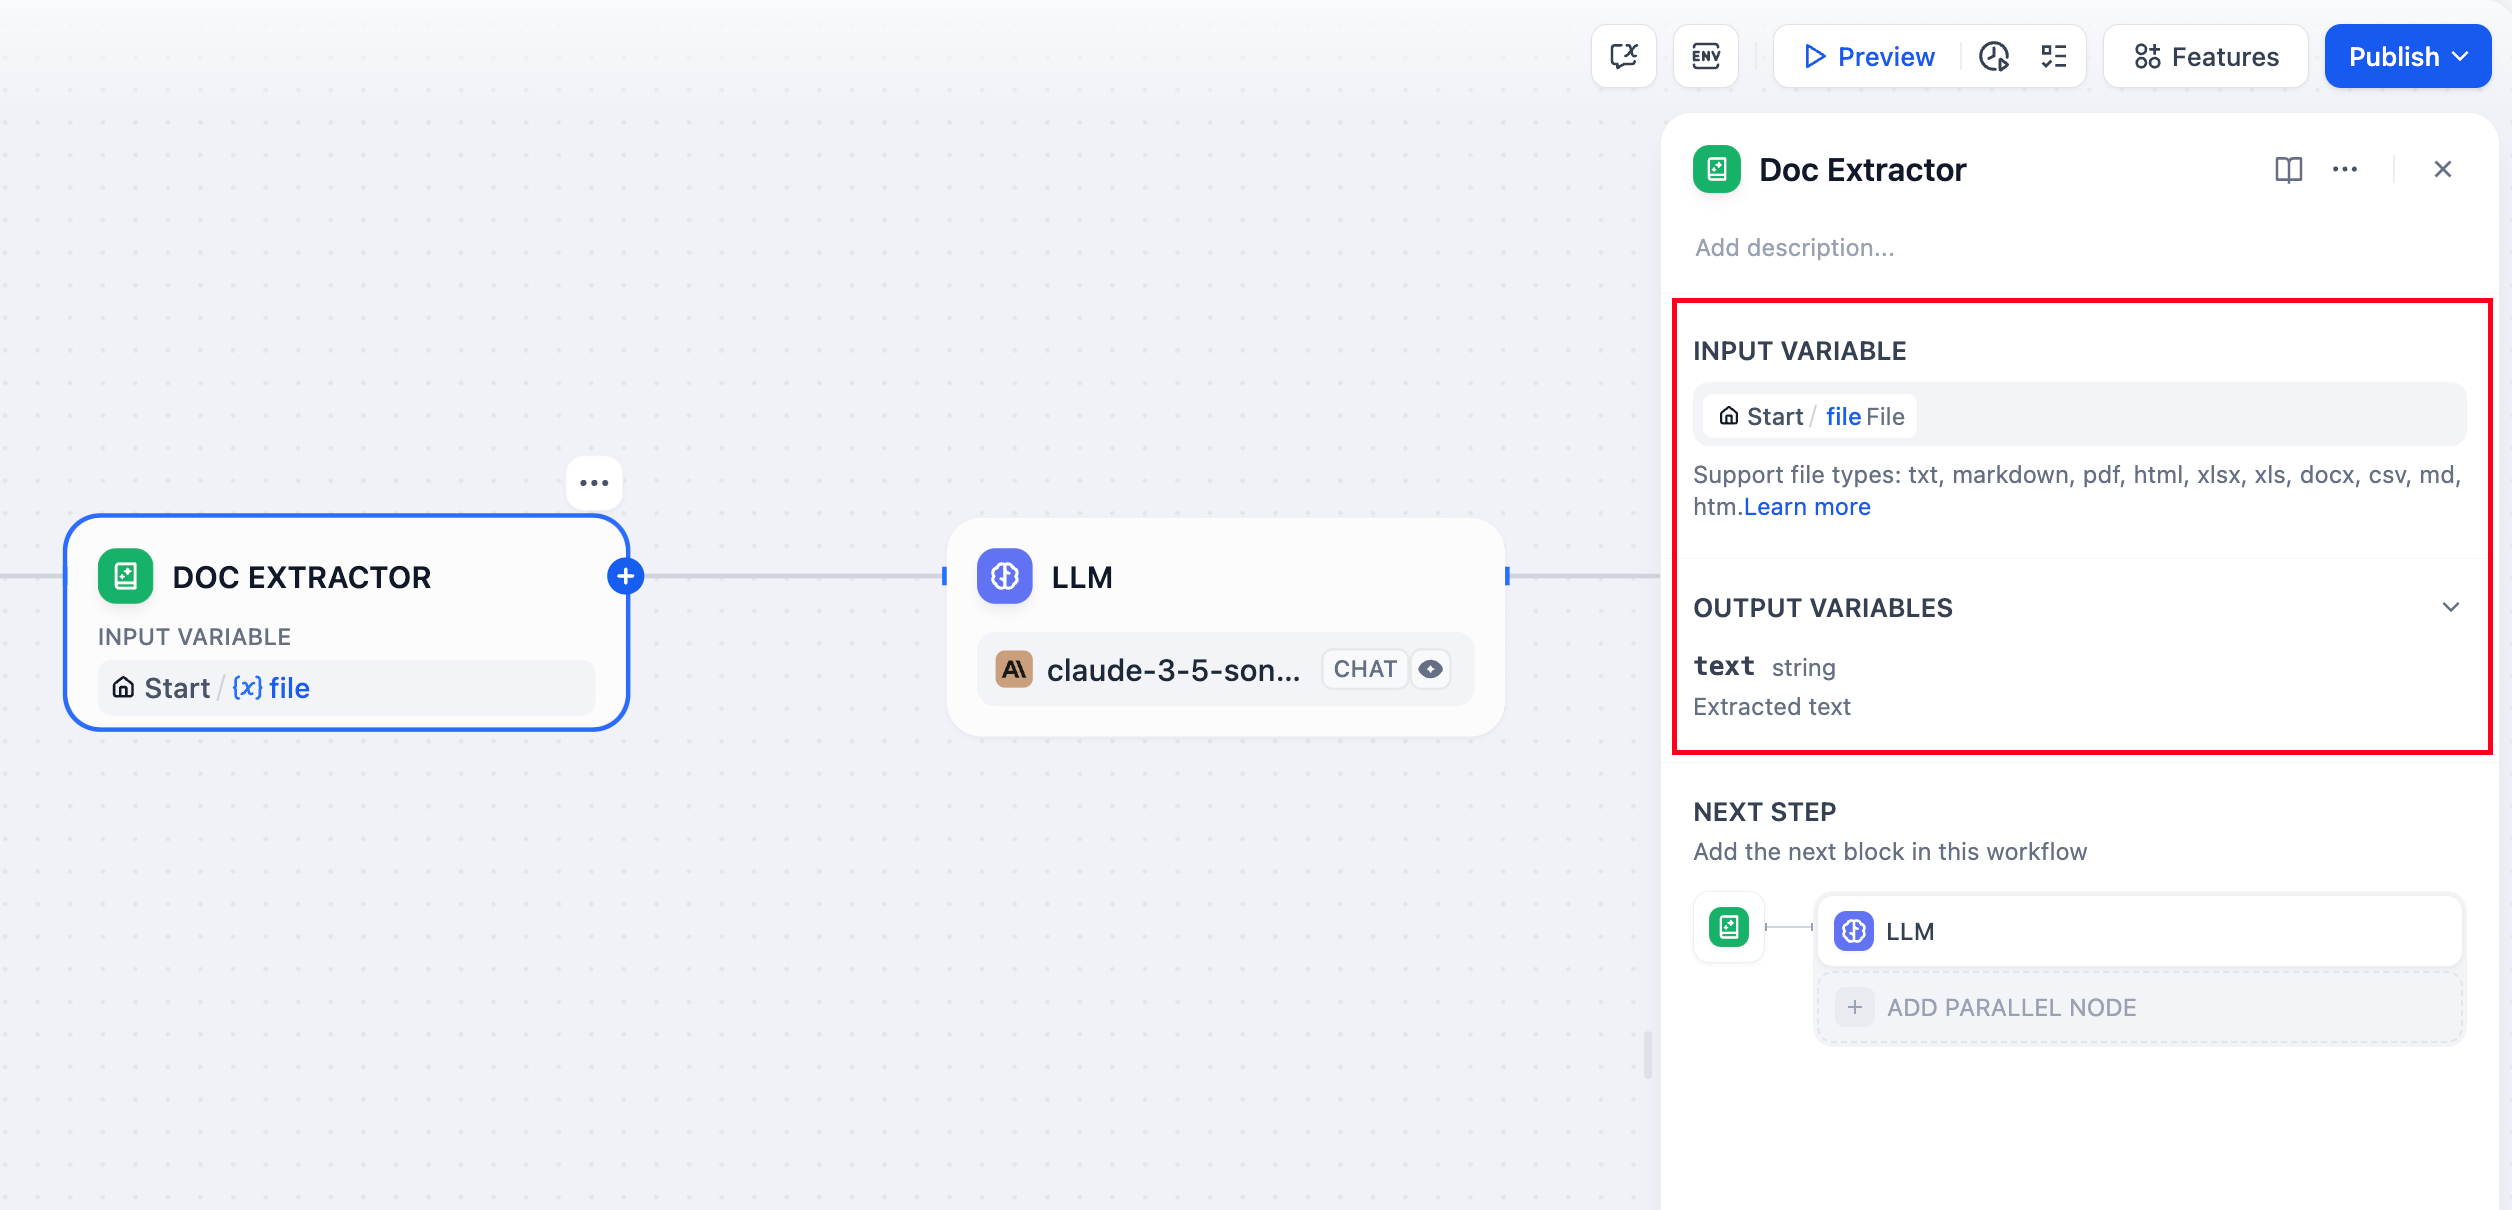
</Frame>
## Supported File Types
The node handles most text-based document formats:
**Text Documents** - TXT, Markdown, HTML files with direct text content
**Office Documents** - DOCX files from Microsoft Word and compatible applications
**PDF Documents** - Text-based PDFs
**Office Files** - DOCX files parse directly, with tables converted to Markdown. DOC and ODT files require [Unstructured processing](#external-dependencies).
**Spreadsheets** - Excel (.xls/.xlsx) and CSV files converted to Markdown tables
**Presentations** - PowerPoint (.ppt/.pptx) files processed via Unstructured API
**Email Formats** - EML and MSG files for email content extraction
**Specialized Formats** - EPUB books, VTT subtitles, JSON/YAML data, and Properties files
Files containing primarily binary content like images, audio, or video require specialized processing tools or external services.
## Input and Output
### Input Configuration
Configure the node to accept either:
**Single File** input from a file variable (typically from the Start node)
**Multiple Files** as an array for batch document processing
### Output Structure
The node outputs extracted text content:
* Single file input produces a `string` containing the extracted text
* Multiple file input produces an `array[string]` with each file's content
The output variable is named `text` and contains the raw text content ready for downstream processing.
## Implementation Example
Here's a complete document Q\&A workflow using the Document Extractor:
<Frame>
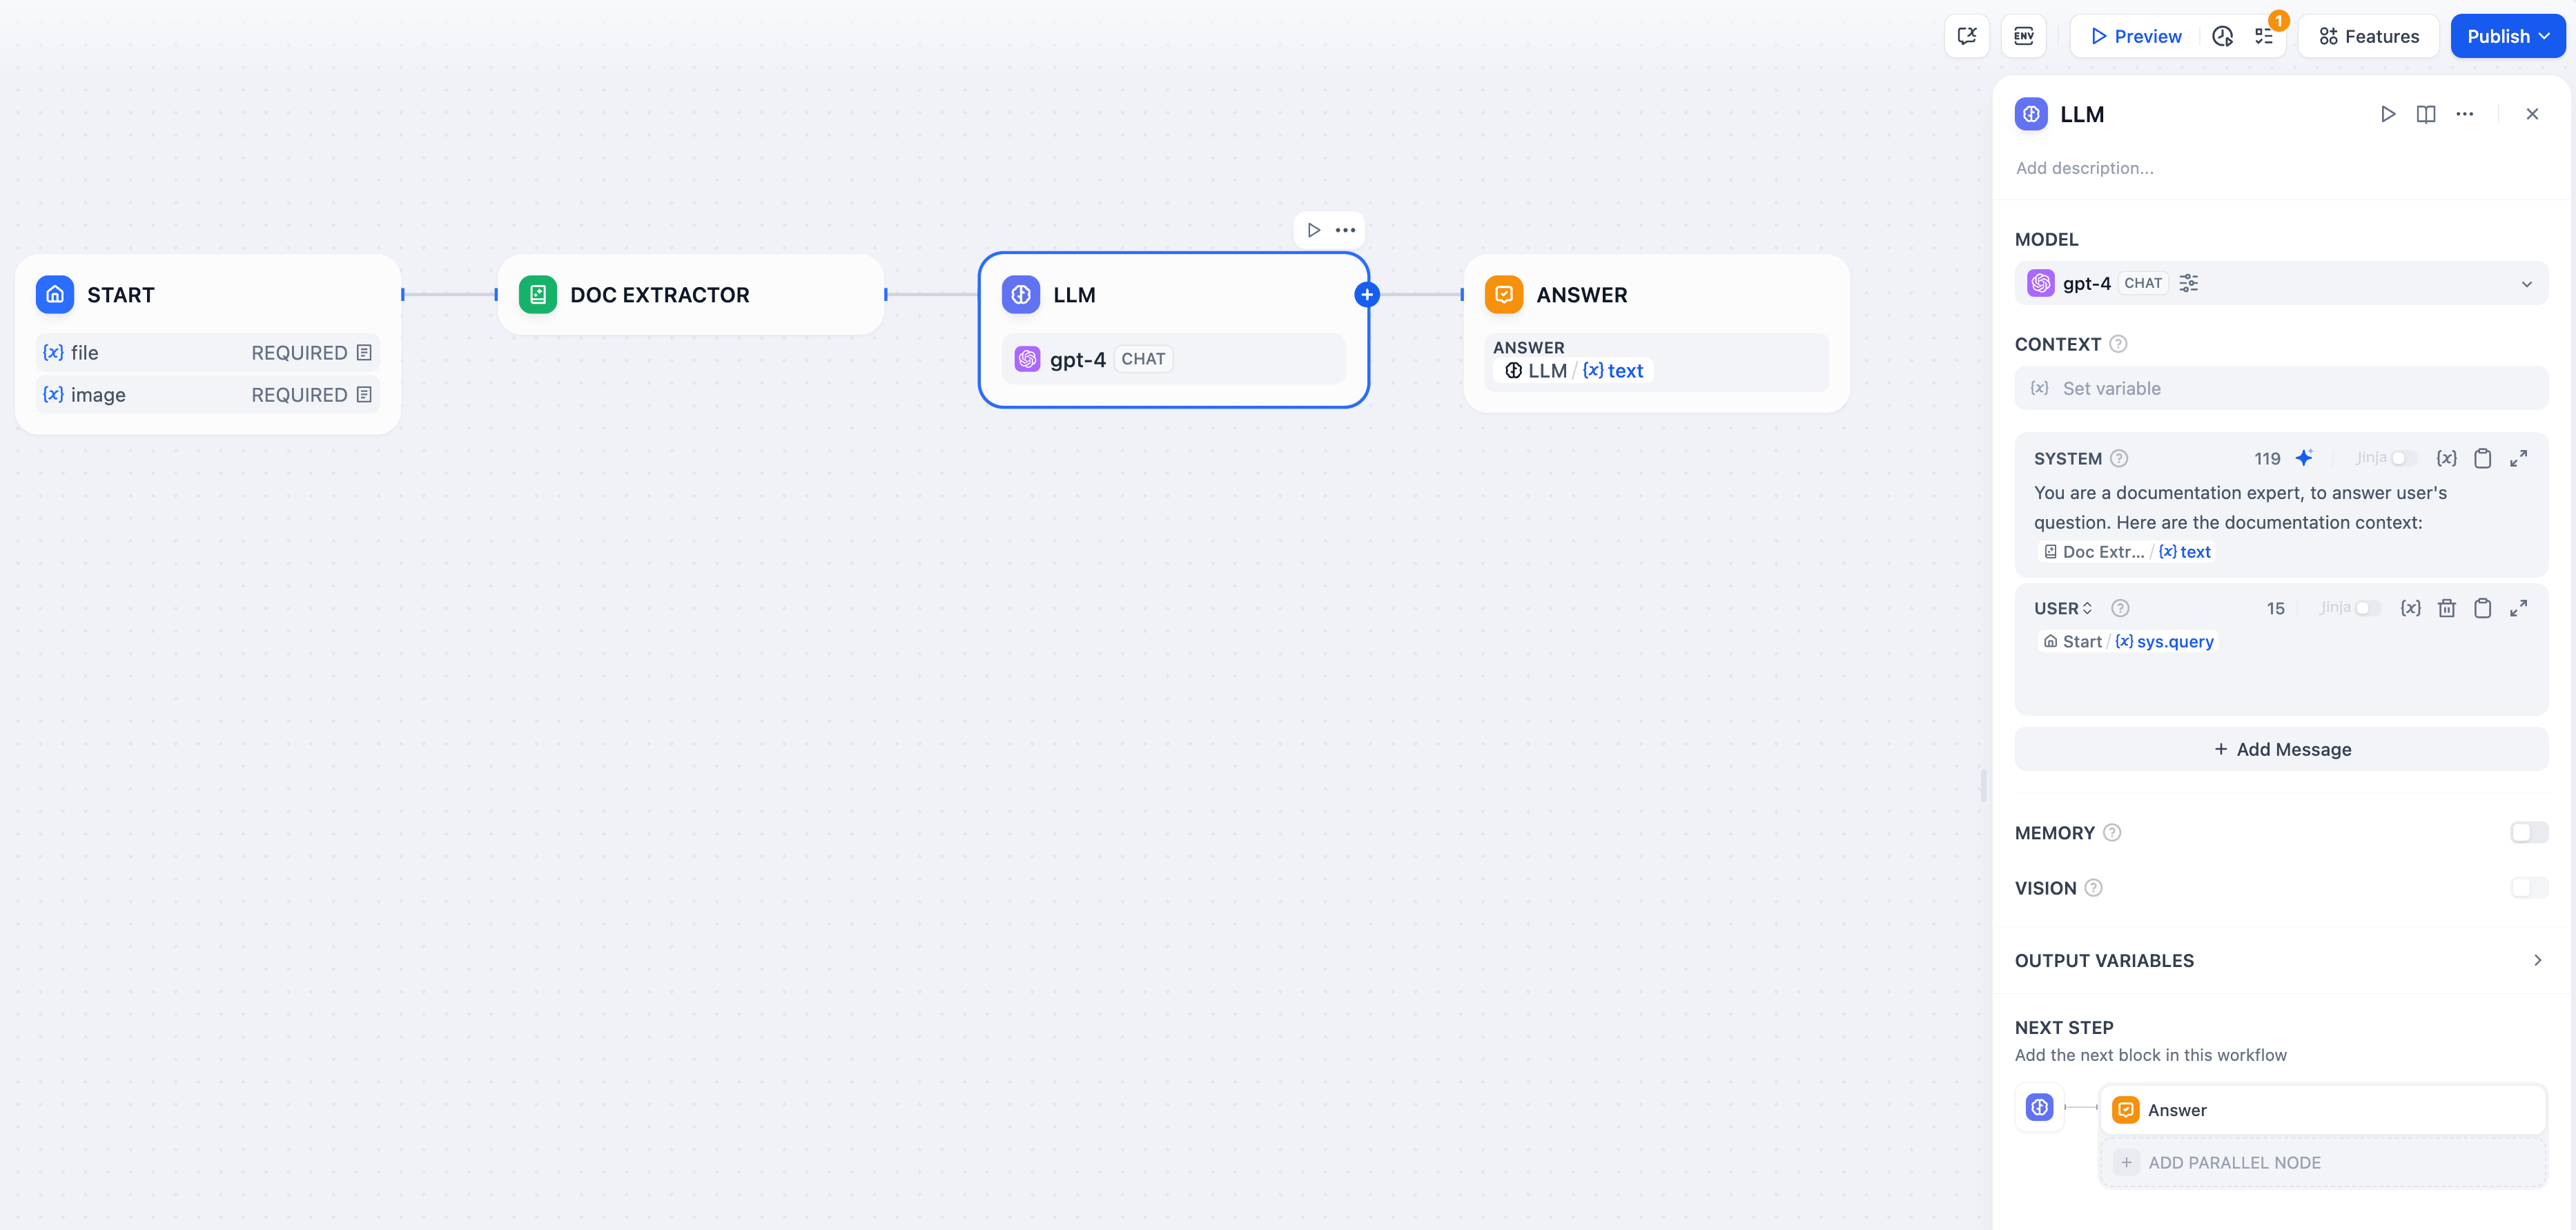
</Frame>
### Workflow Setup
**File Upload Configuration** - Enable file input in your Start node to accept document uploads from users.
**Text Extraction** - Connect the Document Extractor to process uploaded files and extract their text content.
**AI Processing** - Use the extracted text in LLM prompts for analysis, summarization, or question answering.
<Frame>
</Frame>
<Frame>
</Frame>
## Processing Considerations
The Document Extractor uses specialized parsing libraries optimized for different file formats. It preserves text structure and formatting where possible, making extracted content more useful for LLM processing.
### File Format Processing
**Encoding Detection** - Uses chardet library to automatically detect file encoding with UTF-8 fallback for text-based files
**Table Conversion** - Excel and CSV data becomes Markdown tables for better LLM comprehension
**Document Structure** - DOCX files maintain paragraph and table ordering with proper table-to-Markdown conversion
**Multi-line Content** - VTT subtitle files merge consecutive utterances by the same speaker
### External Dependencies
Some file formats require the **Unstructured API** service configured via `UNSTRUCTURED_API_URL` and `UNSTRUCTURED_API_KEY`:
* DOC files (legacy Word documents)
* PowerPoint presentations (if using API processing)
* EPUB books (if using API processing)
* ODT documents (if using API processing)
For very large documents, consider the LLM's context limits and implement chunking strategies if needed. The extracted text maintains the original document's logical structure to preserve meaning and context.
# HTTP Request
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/http-request
Connect to external APIs and web services
The HTTP Request node connects your workflow to external APIs and web services. Use it to fetch data, send webhooks, upload files, or integrate with any service that accepts HTTP requests.
<Frame>
</Frame>
## HTTP Methods
The node supports all standard HTTP methods for different types of operations:
<Tabs>
<Tab title="Data Retrieval">
**GET** retrieves data from servers without modifying anything. Use for fetching user profiles, searching databases, or getting current status.
**HEAD** gets response headers without the full response body. Useful for checking if resources exist or getting metadata.
</Tab>
<Tab title="Data Submission">
**POST** sends data to servers, typically for creating new resources. Use for form submissions, file uploads, or sending JSON payloads.
**PUT** creates or completely replaces resources. Use when you want to set the entire state of a resource.
**PATCH** makes partial updates to existing resources. Use when you only need to modify specific fields.
</Tab>
<Tab title="Resource Management">
**DELETE** removes resources from servers. Use for deleting files, user accounts, or any resource that should be removed.
</Tab>
</Tabs>
## Configuration
Configure every aspect of your HTTP request including URL, headers, query parameters, request body, and authentication. Variables from previous workflow nodes can be dynamically inserted anywhere in your request configuration.
### Variable Substitution
Reference workflow variables using double curly braces: `{{variable_name}}`. Dify supports deep object access, so you can extract nested values like `{{api_response.data.items[0].id}}` from previous HTTP responses.
Secret-type environment variable values are masked in workflow run logs and in this node's request log.
### Timeout Configuration
HTTP requests have configurable timeouts to prevent hanging:
* **Connect timeout**: Maximum time to establish connection
* **Read timeout**: Maximum time to read response data
* **Write timeout**: Maximum time to send request data
Timeouts are enforced to maintain workflow performance and prevent resource exhaustion.
### Authentication
The node supports multiple authentication types:
**No Auth** (`type: "no-auth"`) - No authentication headers added
**API Key** (`type: "api-key"`) with three subtypes:
* **Basic** (`type: "basic"`) - Adds Basic Auth header with base64 encoding
* **Bearer** (`type: "bearer"`) - Adds `Authorization: Bearer <token>` header
* **Custom** (`type: "custom"`) - Adds custom header with specified name and value
### Request Body
Choose the appropriate body type based on your API requirements:
* **JSON** for structured data
* **Form Data** for traditional web forms
* **Binary** for file uploads
* **Raw Text** for custom content types
## File Detection
The HTTP Request node automatically detects file responses using sophisticated logic:
1. **Content-Disposition analysis** - Checks for `attachment` disposition or filename parameters
2. **MIME type evaluation** - Analyzes content types to distinguish text from binary
3. **Content sampling** - For ambiguous types, samples first 1024 bytes to detect text patterns
Text-based responses (JSON, XML, HTML, etc.) are treated as regular data, while binary content becomes file variables.
## File Operations
The HTTP Request node handles file uploads and downloads seamlessly:
<Frame>
</Frame>
**File Uploads** use the binary request body option. Select file variables from previous nodes to send files to external services for document storage, media processing, or backup.
**File Downloads** are automatically handled when responses contain file content. Downloaded files become available as file variables for use in downstream nodes.
## Error Handling and Retries
Configure robust error handling for production workflows that depend on external services:
<Frame>
</Frame>
**Retry Settings** automatically retry failed requests up to 10 times with configurable intervals (maximum 5000ms). This handles temporary network issues or service unavailability.
<Frame>
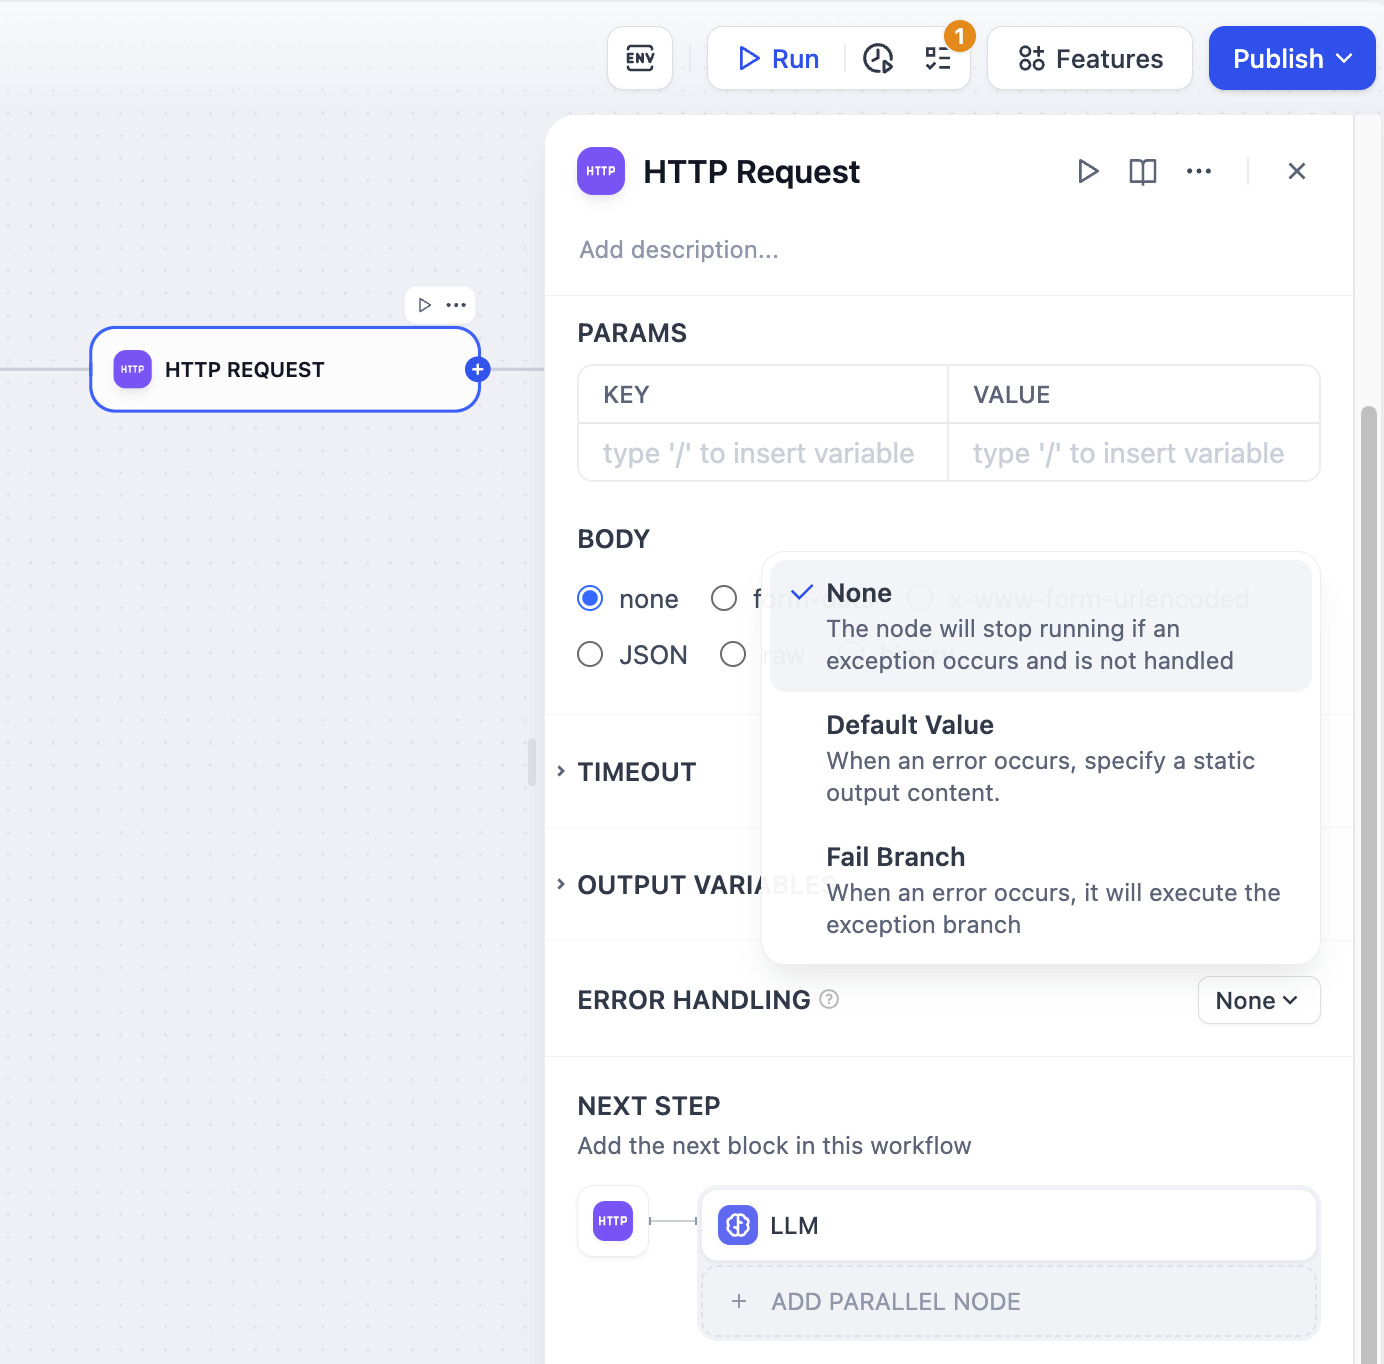
</Frame>
**Error Handling** defines alternative workflow paths when HTTP requests fail, ensuring your workflow continues executing even when external APIs are unavailable.
## Response Processing
HTTP responses become structured variables in subsequent nodes with separate access to:
* **Response Body** - The main content returned by the API
* **Status Code** - HTTP status for conditional logic
* **Headers** - Response metadata as key-value pairs
* **Files** - Any file content returned by the API
* **Size Information** - Content size in bytes with readable formatting (KB/MB)
### SSL Verification
SSL certificate verification is configurable per node (`ssl_verify` parameter). This allows connections to internal services with self-signed certificates while maintaining security for external APIs.
<Frame>
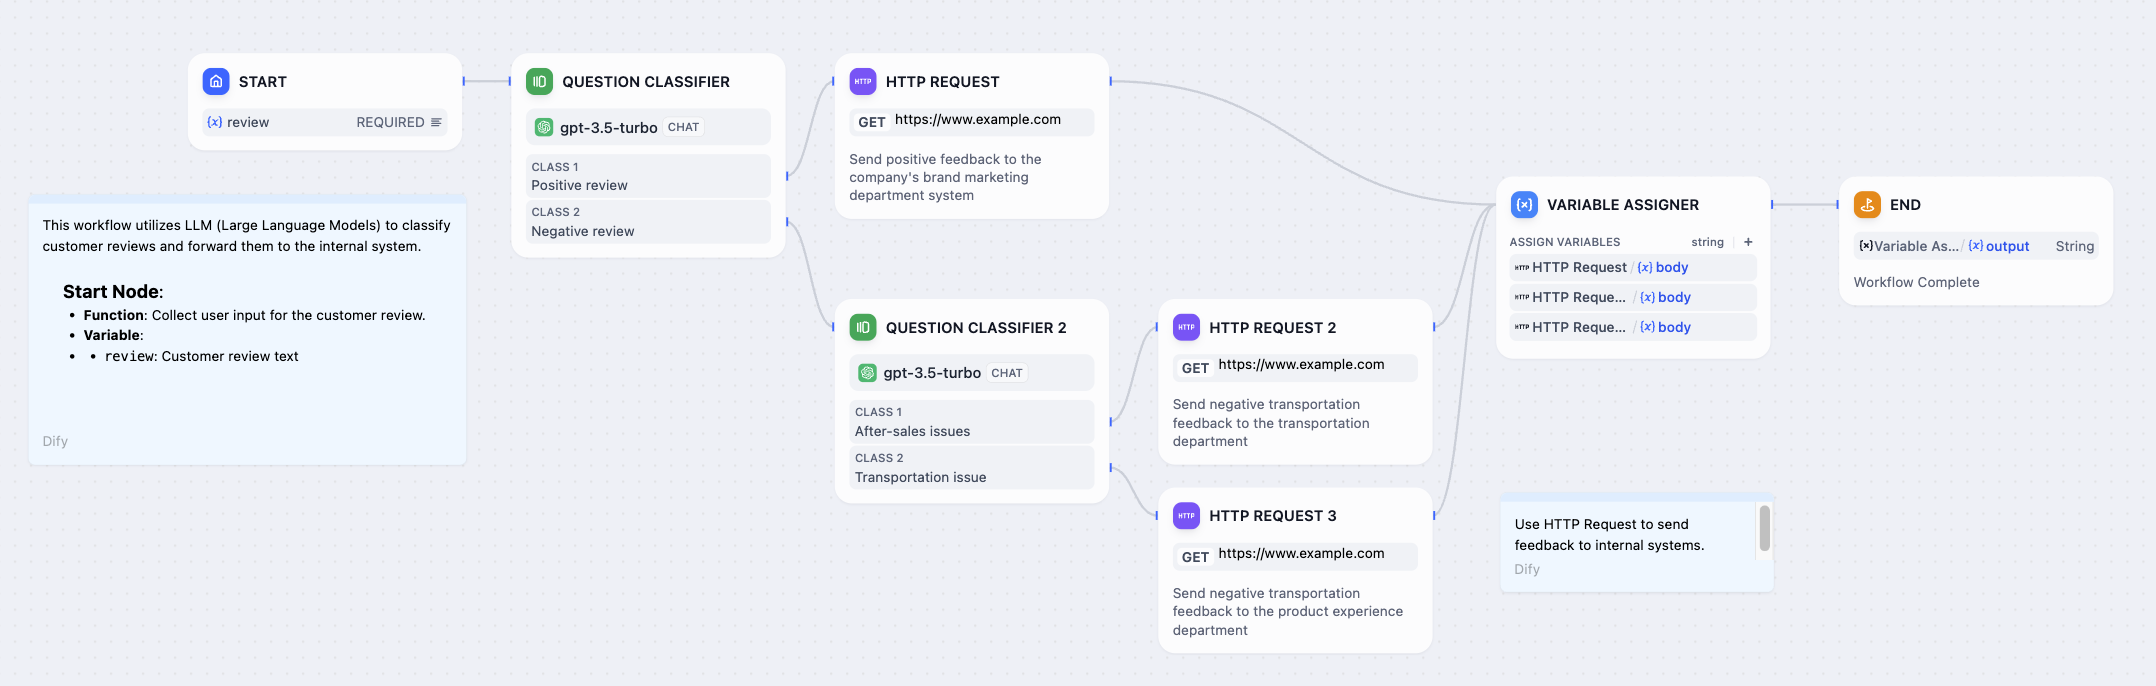
</Frame>
# List Operator
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/list-operator
Filter, sort, and select elements from arrays
The List Operator node processes arrays by filtering, sorting, and selecting specific elements. Use it when you need to work with mixed file uploads, large datasets, or any array data that requires separation or organization before downstream processing.
Supported input data types include `array[string]`, `array[number]`, `array[file]`, and `array[boolean]`.
<Frame>
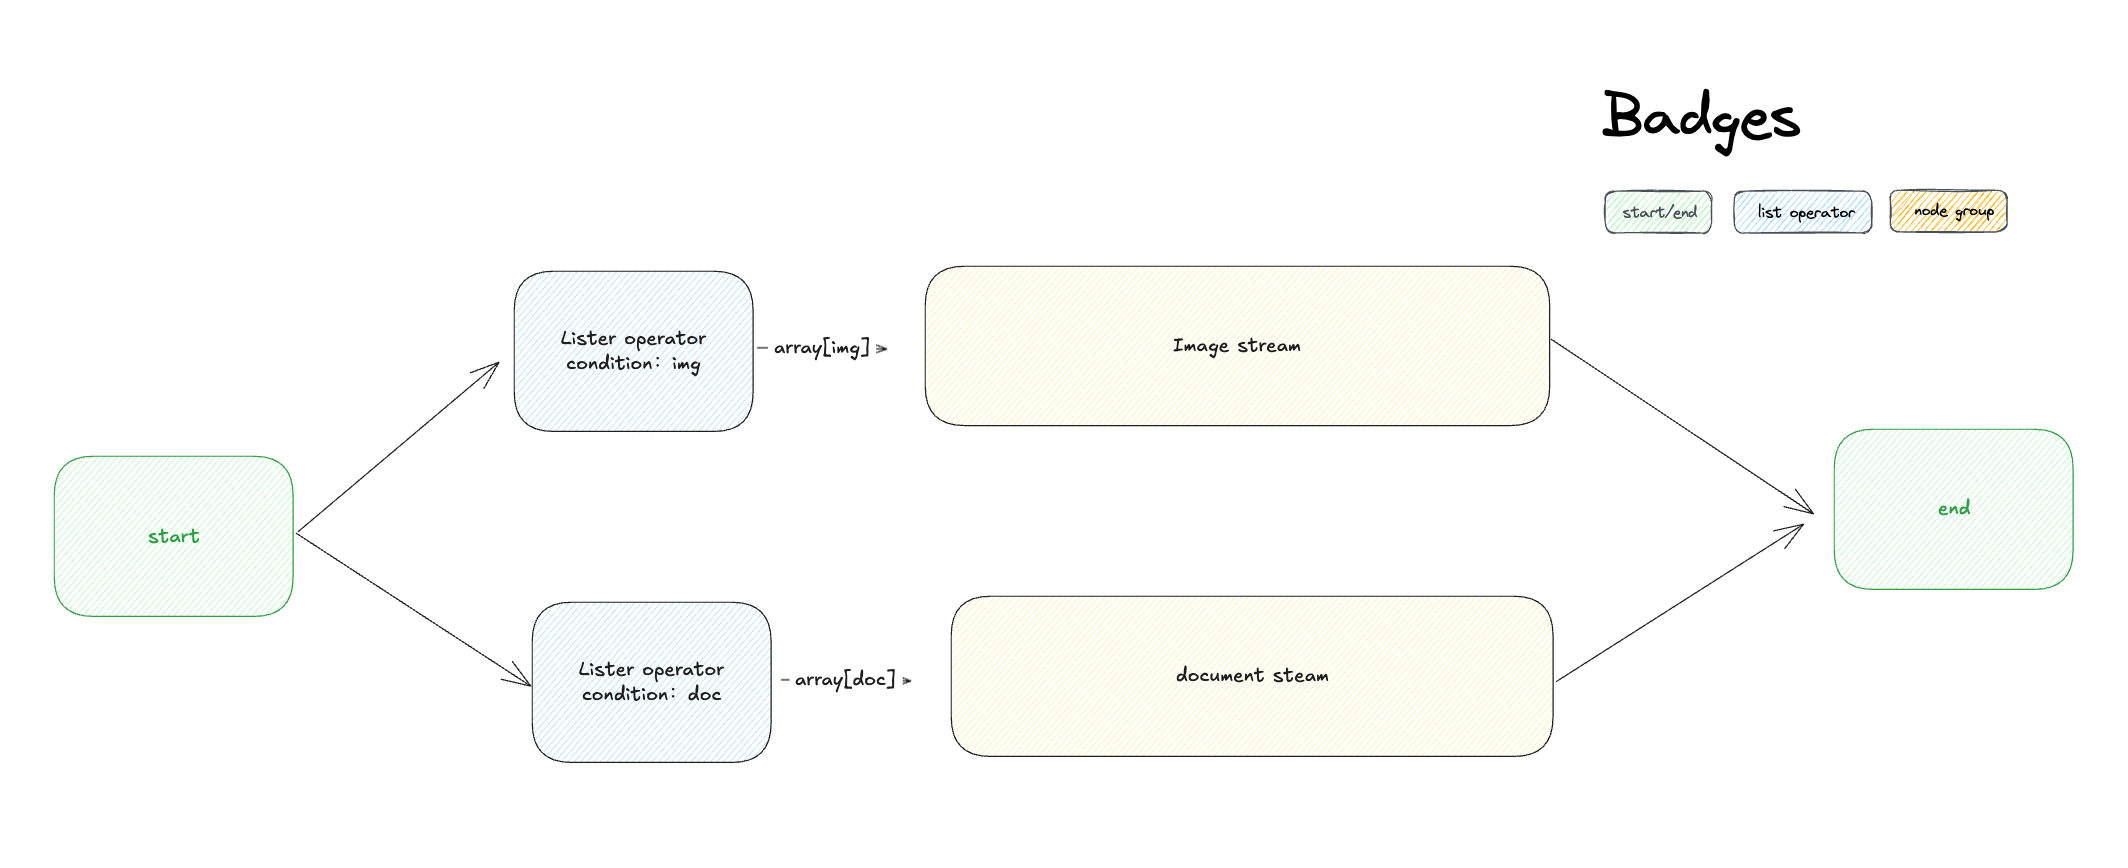
</Frame>
## The Array Processing Problem
Most workflow nodes expect single values, not arrays. When you have mixed content like `[image.png, document.pdf, audio.mp3]` in one variable, you need to separate this into focused streams that downstream nodes can process effectively.
The List Operator acts as an intelligent router, using filters to separate mixed arrays and prepare them for specialized processing.
<Frame>
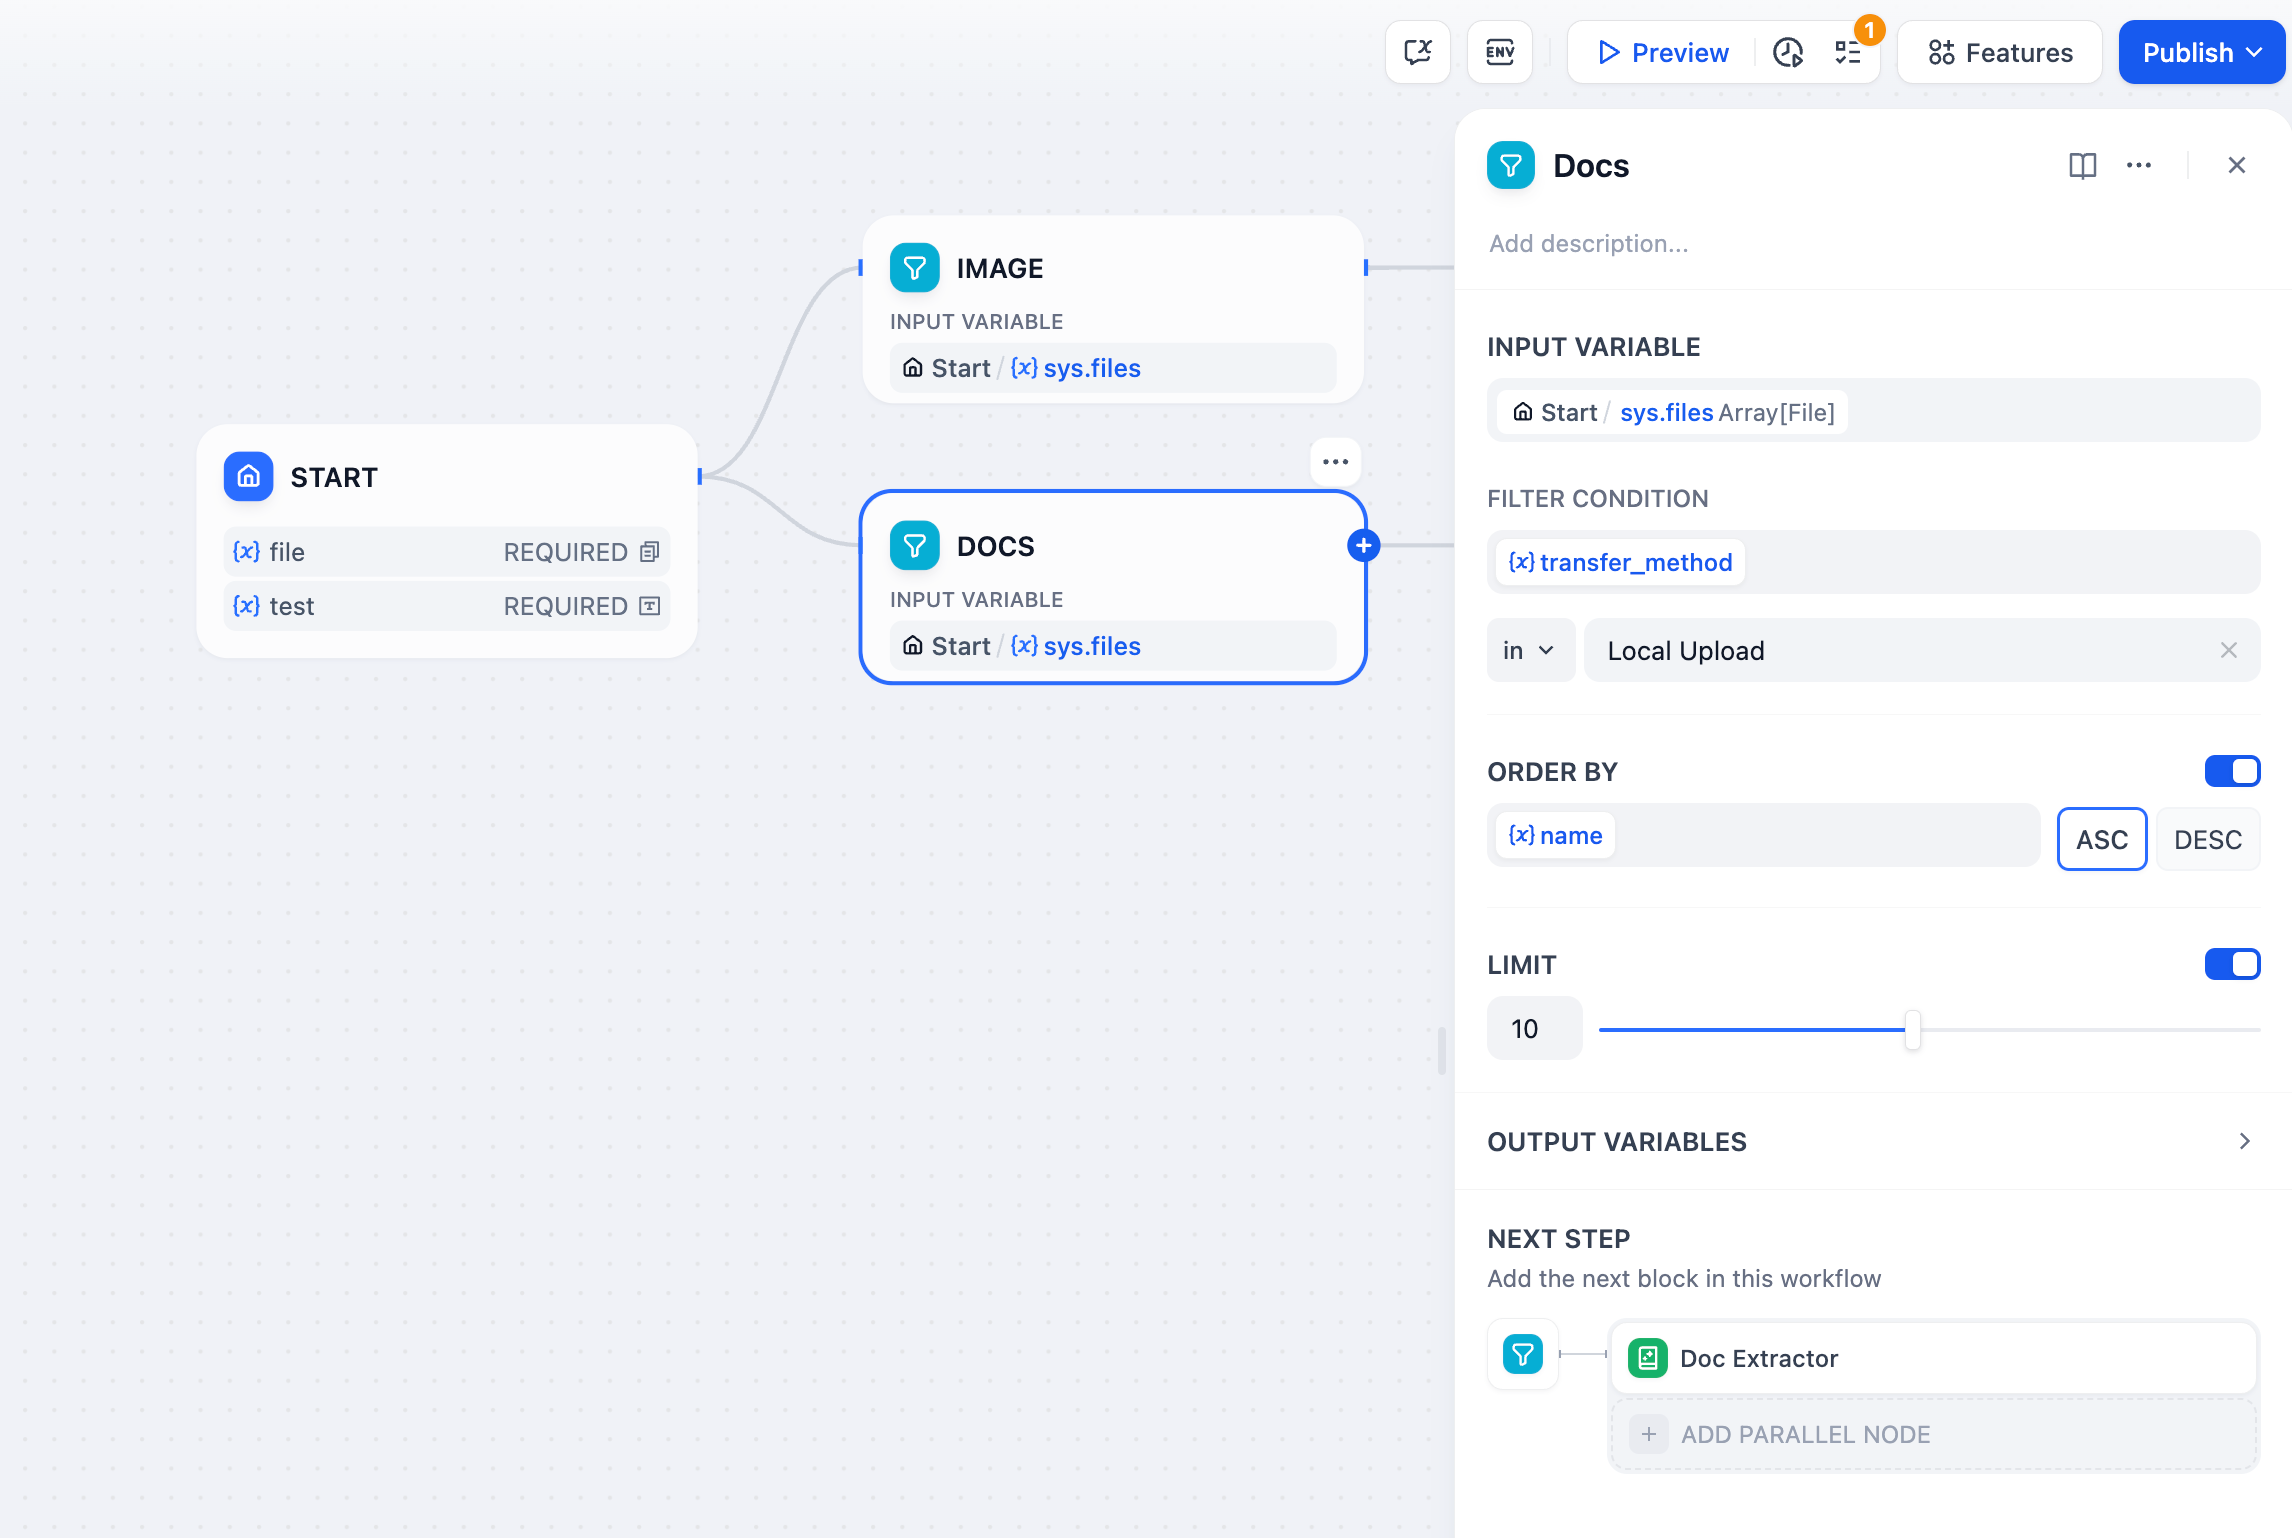
</Frame>
## Operations
### Filtering
Extract specific items based on their attributes. For file arrays, filter by:
<Tabs>
<Tab title="Content Properties">
**Type** - Filter by content category: image, document, audio, video
**MIME Type** - Precise content type identification (image/jpeg, application/pdf, etc.)
**Extension** - File extensions (.pdf, .jpg, .mp3, .docx, etc.)
</Tab>
<Tab title="File Properties">
**Size** - File size constraints for processing limits
**Name** - Filename patterns or specific names
**Transfer Method** - Distinguish between local uploads and URL-based files
</Tab>
</Tabs>
### Sorting
Organize filtered results by any attribute:
**Ascending (ASC)** - Smallest to largest values, A-Z alphabetical order
**Descending (DESC)** - Largest to smallest values, Z-A reverse order
### Selection
Choose specific elements from the processed array:
**Take First N** - Select the first 1-20 items after filtering and sorting
**First Record** - Return only the first matching element as a single value
**Last Record** - Return only the last matching element as a single value
## Output Variables
**result** - Complete filtered and sorted array for bulk processing
**first\_record** - Single element from the beginning, perfect for "primary" or "latest" item selection
**last\_record** - Single element from the end, useful for "most recent" or "final" selection
## Mixed File Processing Example
Handle workflows where users upload both documents and images:
<Frame>
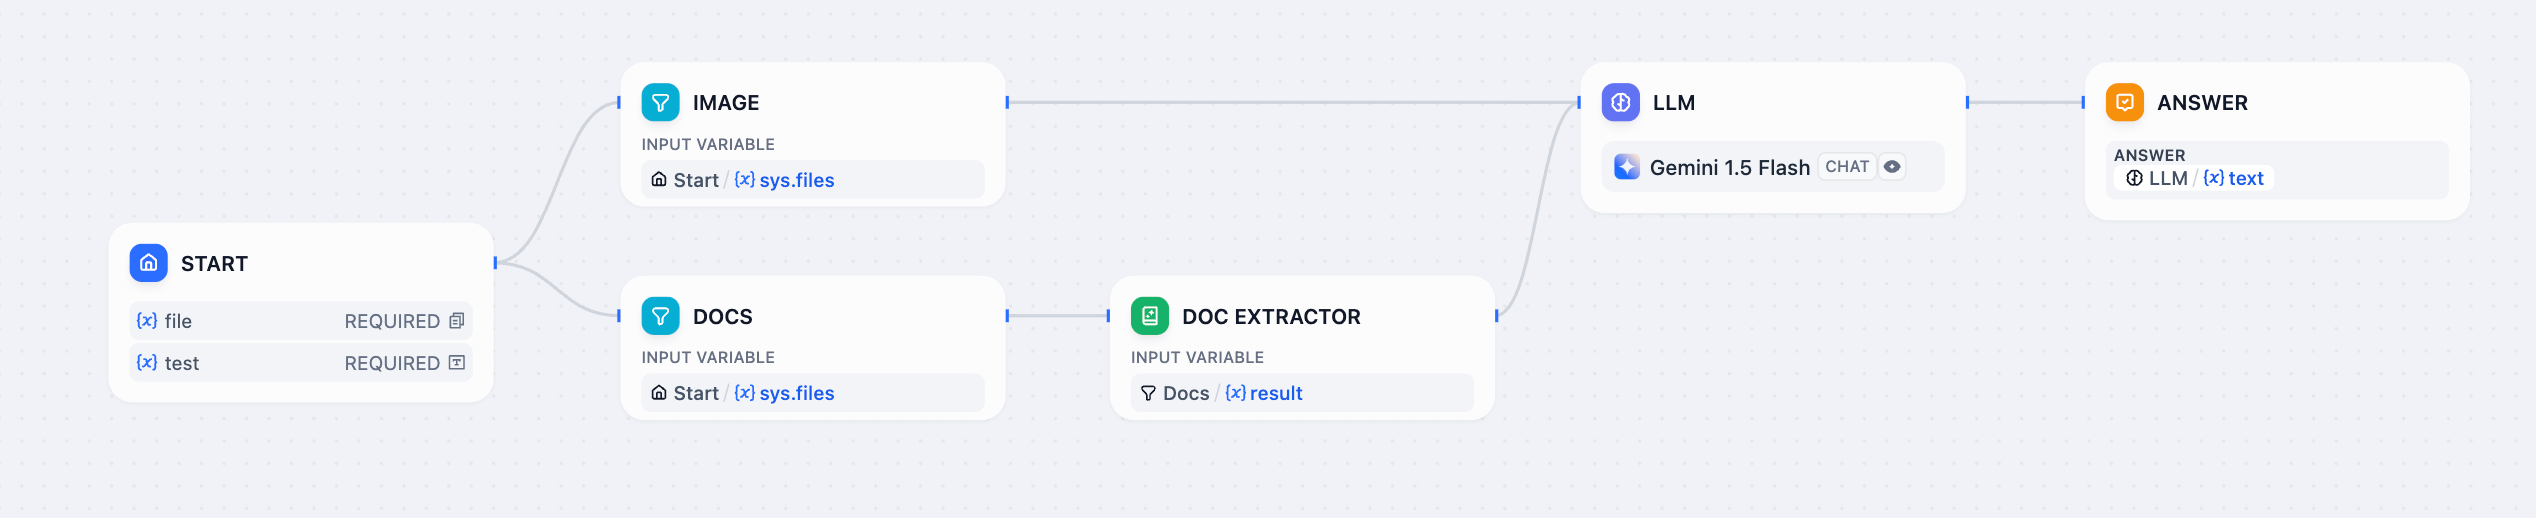
</Frame>
**Implementation Steps**:
1. **Configure Mixed Uploads** - Enable file upload features to accept multiple file types
2. **Split by Type** - Use separate List Operator nodes with different filters:
* Filter for `type = "image"` → route to LLM with vision capabilities
* Filter for `type = "document"` → route to Document Extractor
3. **Process Appropriately** - Images get analyzed directly, documents get text extraction
4. **Combine Results** - Merge processed outputs into unified responses
This pattern automatically routes different file types to appropriate processors, creating seamless multi-modal user experiences.
# Parameter Extractor
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/parameter-extractor
Convert natural language to structured data using LLM intelligence
The Parameter Extractor node converts unstructured text into structured data using LLM intelligence. It bridges the gap between natural language input and the structured parameters that tools, APIs, and other workflow nodes require.
## Configuration
### Input and Model Selection
Select the **Input Variable** containing the text you want to extract parameters from. This typically comes from user input, LLM responses, or other workflow nodes.
Choose a **Model** with strong structured output capabilities. The Parameter Extractor relies on the LLM's ability to understand context and generate structured JSON responses.
### Parameter Definition
Define the parameters you want to extract by specifying:
* **Parameter Name** - The key that will appear in the output JSON
* **Data Type** - String, number, boolean, array, or object
* **Description** - Helps the LLM understand what to extract
* **Required Status** - Whether the parameter must be present
You can manually define parameters or **quickly import from existing tools** to match the parameter requirements of downstream nodes.
### Extraction Instructions
Write clear instructions describing what information to extract and how to format it. Providing examples in your instructions improves extraction accuracy and consistency for complex parameters.
<Frame>
</Frame>
## Advanced Configuration
### Inference Mode
Choose between two extraction approaches based on your model's capabilities:
**Function Call/Tool Call** uses the model's structured output features for reliable parameter extraction with strong type compliance.
**Prompt-based** relies on pure prompting for models that may not support function calling or when prompt-based extraction performs better.
### Memory
Enable memory to include conversation history when extracting parameters. This helps the LLM understand context in interactive dialogues and improves extraction accuracy for conversational workflows.
## Output Variables
The node provides both extracted parameters and built-in status variables:
**Extracted Parameters** appear as individual variables matching your parameter definitions, ready for use in downstream nodes.
**Built-in Variables** include status information:
* `__is_success` - Extraction success status (1 for success, 0 for failure)
* `__reason` - Error description when extraction fails
<Frame>
</Frame>
# Tool Node
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/tools
Connect to external services and APIs
Add [Dify tools](/en/self-host/use-dify/workspace/tools) to your workflows as standalone nodes.
This lets your workflows interact with external services and APIs to access real-time data and perform actions, like web searches, database queries, or content processing.
**To add and configure a tool node**:
1. On the canvas, click **Add Node** > **Tools**, then select an action from an available tool.
2. Optional: If a tool requires authentication, select an existing credential or create a new one.
<Info>
To change the default credential, go to **Integrations** > **Tools** > **Tool Plugin**.
</Info>
3. Complete any other required tool settings.
# Variable Aggregator
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/variable-aggregator
Converge exclusive workflow branches into a single output
Use the Variable Aggregator node to converge **exclusive** workflow branches into a single output, so you only need to define downstream processing once.
Nodes like If/Else and Question Classifier create exclusive branches—only one path executes per run. When these branches produce the same type of output, you would normally duplicate downstream nodes on every branch.
The Variable Aggregator eliminates this duplication. It provides a single output variable for downstream nodes to reference, regardless of which branch ran.
<Frame>
<img alt="Without Variable Aggregator" />
</Frame>
<Frame>
<img alt="With Variable Aggregator" />
</Frame>
<Note>
The Variable Aggregator is designed for exclusive branches where **only one path runs at a time**. It does not combine outputs from multiple branches that execute in parallel.
To merge results from parallel branches, use a [Code](/en/self-host/use-dify/nodes/code) or [Template](/en/self-host/use-dify/nodes/template) node.
</Note>
## Select the Variables to Converge
From each branch, add variables that need the same downstream processing. All variables must share the same data type.
Supported types: `string`, `number`, `object`, `boolean`, `array`, `file`.
The node outputs whichever variable has a value at runtime. Since only one branch executes, only one variable will have a value, and that value becomes the node's output.
## Converge Multiple Sets of Variables
When you have multiple sets of variables that each need to be converged separately, enable **Aggregation Group** to create groups within a single Variable Aggregator.
Each group converges its own set of variables and produces a separate output.
# Variable Assigner
Source: https://docs.dify.ai/en/self-host/use-dify/nodes/variable-assigner
Manage persistent conversation variables in Chatflow applications
The Variable Assigner node manages persistent data in Chatflow applications by writing to conversation variables (Understand the different types of variables [here](/en/learn/key-concepts#variables)). Unlike regular workflow variables that reset with each execution, conversation variables persist throughout an entire chat session.
<Frame>

</Frame>
## Conversation Variables vs Workflow Variables
**Workflow Variables** exist only during a single workflow execution and reset when the workflow completes.
**Conversation Variables** persist across multiple conversation turns within the same chat session, enabling stateful interactions and contextual memory.
This persistence enables contextual conversations, user personalization, stateful workflows, and progress tracking across multiple user interactions.
## Configuration
Configure which conversation variables to update and specify their source data. You can assign multiple variables in a single node.
<Frame>

</Frame>
**Variable** - Select the conversation variable to write to
**Set Variable** - Choose the source data from upstream workflow nodes
**Operation Mode** - Determine how to update the variable (overwrite, append, clear, etc.)
## Operation Modes
Different variable types support different operations based on their data structure:
<Tabs>
<Tab title="String">
* **Overwrite** - Replace with another string variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
</Tab>
<Tab title="Number">
* **Overwrite** - Replace with another number variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
* **Arithmetic** - Add, subtract, multiply, or divide the current value by another number
</Tab>
<Tab title="Boolean">
* **Overwrite** - Replace with another boolean variable
* **Clear** - Remove the current value
* **Set** - Manually assign a fixed value
</Tab>
<Tab title="Object">
* **Overwrite** - Replace with another object variable
* **Clear** - Remove the current value
* **Set** - Manually define the object structure and values
</Tab>
<Tab title="Array">
* **Overwrite** - Replace with another array variable of the same type
* **Clear** - Remove all elements from the array
* **Append** - Add a single element to the end of the array
* **Extend** - Add all elements from another array of the same type
* **Remove First/Last** - Remove the first or last element from the array
<Tip>
Array operations are particularly powerful for building memory systems, checklists, and conversation histories that grow over time.
</Tip>
</Tab>
</Tabs>
## Common Implementation Patterns
### Smart Memory System
Build chatbots that automatically detect and store important information from conversations:
<Frame>

</Frame>
The system analyzes user input for memorable facts, extracts structured information, and appends it to a persistent memories array for future reference in conversations.
### User Preferences Storage
Store user preferences like language settings, notification preferences, or display options:
<Frame>

</Frame>
Use **Overwrite** mode to capture initial preferences from user input, then reference them in all subsequent LLM responses for personalized interactions.
### Progressive Checklists
Build guided workflows that track completion status across multiple conversation turns:
<Frame>

</Frame>
Use array conversation variables to track completed items. The Variable Assigner updates the checklist each turn, while the LLM references it to guide users through remaining tasks.
# Overview
Source: https://docs.dify.ai/en/self-host/use-dify/publish/README
Get your Dify applications into users' hands with web apps, APIs, embeds, and integrations
You've built something great in Dify. Now let's get it to your users. Every Dify application becomes available in multiple ways automatically—choose what works best for your situation.
## Start with Web Apps
Your fastest path to sharing is through web apps. These are generated automatically when you create any application and work immediately without setup.
<Steps>
<Step title="Hit Publish">
Click **Publish** in your app to activate the latest version.
</Step>
<Step title="Copy the URL">
Find your web app link on the app's **Access Point** tab.
</Step>
<Step title="Share immediately">
Send the link to users—they can start using your app right away.
</Step>
</Steps>
<Tip>
Web apps work on any device and automatically adapt to screen sizes. No app store approvals or installation required.
</Tip>
## Publishing Options
<CardGroup>
<Card title="Web Apps" icon="globe" href="/en/self-host/use-dify/publish/webapp/chatflow-webapp">
Instant, shareable applications. Perfect for testing ideas or serving end users directly.
</Card>
<Card title="API Integration" icon="code" href="/en/api-reference/guides/get-started">
Build AI into your existing products. Full control over user experience and data flow.
</Card>
<Card title="Embed on Websites" icon="window" href="/en/self-host/use-dify/publish/webapp/embedding-in-websites">
Deploy your web app as chat widgets or inline frames on any website.
</Card>
<Card title="MCP Server" icon="plug" href="/en/self-host/use-dify/publish/publish-mcp">
Connect to AI tools like Claude Desktop and Cursor. Great for development workflows.
</Card>
</CardGroup>
## How Publishing Works
When you publish an app, Dify creates a web app and API endpoint with your latest configuration:
* **Web apps** update immediately with new features and responses
* **API endpoints** serve the latest model and workflow configurations
* **Website embeds** (which display your web app) automatically reflect all changes
* **MCP servers** provide access to current app capabilities
<Warning>
Publishing replaces your live app with the current configuration. Users will immediately see changes in their next interaction.
</Warning>
## Choose Your Approach
<AccordionGroup>
<Accordion title="I want immediate user feedback">
Use **Web Apps**. Share a link and start collecting feedback within minutes. Perfect for validating ideas or serving non-technical users.
</Accordion>
<Accordion title="I'm building a product">
Use **API Integration**. You control the interface, user authentication, and data handling. Your app becomes part of your product ecosystem.
</Accordion>
<Accordion title="I have an existing website">
Use **Embed on Websites**. Display your web app as a chat widget or inline frame on your current site. Works with any website technology.
</Accordion>
<Accordion title="I want to extend AI tools">
Use **MCP Server**. Make your app available to Claude Desktop, Cursor, and other AI development environments as a native tool.
</Accordion>
</AccordionGroup>
## Publishing Best Practices
Before you share your app, ensure you've configured these settings:
* **App description** - Helps users understand what your app does
* **Icon and branding** - Makes your app recognizable and professional
* **Access controls** - Decide if your app should be public or require authentication
* **Rate limits** - Protect your app from overuse (especially important for API access)
<Check>
All publishing methods use the same app configuration. Set it once, publish everywhere.
</Check>
# MCP Server
Source: https://docs.dify.ai/en/self-host/use-dify/publish/publish-mcp
Expose your Dify applications as MCP servers for integration with Claude Desktop, Cursor, and other AI development tools
Dify now supports exposing your applications as [MCP](https://modelcontextprotocol.io/docs/getting-started/intro) (Model Context Protocol) servers, enabling seamless integration with AI assistants like Claude Desktop and development environments like Cursor. This allows these tools to directly interact with your Dify apps as if they were native extensions.
<Note>
If you're looking to use MCP tools within Dify workflows & agents, see [here](/en/self-host/use-dify/workspace/tools#mcp).
</Note>
## Configure Your Dify App as an MCP Server
On your app's **Access Point** tab, find the **MCP Server** card. The feature is disabled by default. When you toggle it on, Dify generates a unique MCP Server address for your application. This address serves as the connection point for external tools.
<Danger>
Your MCP Server URL contains authentication credentials, so treat it like an API key. If you suspect it's been compromised, use the regenerate button to create a new URL. The old one will immediately stop working.
</Danger>
## Integration with Claude Desktop
To connect your Dify app to Claude Desktop, you'll need to add a Claude integration. Go to your Claude Profile > Settings > Integrations > Add integration. Replace the Integration URL with your Dify app's Server URL.
## Integration with Cursor
For Cursor, create or edit the `.cursor/mcp.json` file in your project root:
```json theme={null}
{
"mcpServers": {
"your-server-name": {
"url": "your-server-url"
}
}
}
```
Simply replace the URL with your Dify app's MCP Server address. Cursor will automatically detect this configuration and make your Dify app available as a tool. You can add multiple Dify apps by including additional entries in the `mcpServers` object.
## Practical Considerations
* Descriptiveness
When designing descriptions for your tool and its input parameters, think about how an AI would interpret them. Clear, specific descriptions lead to better invocations. Instead of "input data," specify "JSON object containing user profile with required fields: name, email, preferences."
* Latency
The MCP protocol handles the communication layer, but your Dify app's performance still matters. If your app typically takes 30 seconds to process, that latency will be felt in the client application. Consider adding progress indicators or breaking complex workflows into smaller, faster operations.
# Publish Apps to Marketplace
Source: https://docs.dify.ai/en/self-host/use-dify/publish/publish-to-marketplace
Publish your apps to Dify Marketplace and share them with the world
Publish your apps as templates to Dify Marketplace, where other Dify users can discover and use them.
## Submit a Template
To publish a template, submit it through the [Creator Center](https://creators.dify.ai). After you submit, the template enters **Pending** status while we review it. Once approved, it's published to Marketplace.
While a template is **Pending**, you can withdraw it at any time. Withdrawing returns it to **Draft**, where you can edit any part of the template before resubmitting.
<Note>
Before submission:
* Make sure all plugins used in the app are **installed directly from Marketplace**.
* Run the app at least once on the latest Community Edition to confirm it works as expected. Marketplace reviews app templates for compatibility against the latest Community Edition release.
</Note>
### Submit as Individual or Organization
You can submit templates under your personal account or an organization.
* **Individual**: For independent creators. When you first log in to the Creator Center, you're signed in with your personal account by default.
* **Organization**: For teams that want to build and manage templates together. To get started, click your avatar in the top-left corner and click **Create an organization**, then invite members to collaborate.
You can switch between your personal account and organizations anytime.
### Submission Methods
<Tabs>
<Tab title="From Dify Studio">
In your app, click **Publish** > **Publish Update**, then click **Publish to Marketplace**.
This takes you to the Creator Center with your app file automatically uploaded. Fill in the template details and submit for review.
</Tab>
<Tab title="In the Creator Center">
Export your app, then go to the Creator Center and upload the export file. Fill in the template details and submit for review.
</Tab>
</Tabs>
## Update a Published Template
How you update a published template depends on what you want to change.
* **To change anything inside the app** (its prompts, tools, model settings, and so on)
Submit the updated app as a new template. This creates a separate listing rather than replacing the original, so you can manually unpublish the old version once the new one is published.
* **To change only the listing** (such as the Overview or Setup steps)
Unpublish the template to take it off Marketplace and return it to **Draft**. Make your edits, then resubmit for review.
## Template Writing Guidelines
### Language Requirements
Keep the template library consistent and searchable.
**The following fields must be written in English**:
* Template name
* Overview
* Setup steps
**Inside the app, you can use any language (e.g. Chinese) for**:
* Node names
* Prompts / system messages
* Messages shown to end-users
If your template mainly targets non-English users, you can add a tag in the title. For example, `Stock Investment Analysis Copilot [ZH]`.
### Template Name & Icon
From the name alone, users should know where it runs and what it does.
* Use a short English phrase, typically 3–7 words.
* Recommended pattern: \[Channel / target] + \[core task], for example:
* WeChat Customer Support Bot
* CSV Data Analyzer with Natural Language
* Internal Docs Q\&A Assistant
* GitHub Issue Triage Agent
* Include keywords users might search for: channel names (Slack, WeChat, Email, Notion) and task names (Summarizer, Assistant, Generator, Bot).
* Use an icon that clearly reflects the template's theme and purpose, rather than the default avatar.
### Categories
Help users discover your template when browsing or filtering by category.
* Select only **1–3** categories that best describe your template.
* Do not check every category just for exposure.
### Language
Help users discover your template via the language filter.
* Select the language your template is designed for in real usage.
* This refers to the language of the template's use case, input, or output, **not** the title or overview (which must be in English).
### Overview
In 2–4 English sentences, explain what it does and who it is for.
<Info>You don't need to list prerequisites, inputs, or outputs here.</Info>
**Recommended structure**
1. Sentence 1: **What it does**
A one-sentence summary of the main function.
2. Sentence 2–3: **Who and when**
Typical user roles or scenarios (support team, marketers, founders, individual knowledge workers, etc.).
<Accordion title="Example: Description for Stock Investment Analysis Copilot">
This template creates a stock investment analysis copilot that uses Yahoo Finance tools to fetch news, analytics, and ticker data for any listed company.
It helps investors and analysts quickly generate structured research summaries, compare companies, and prepare reports without manually switching between multiple finance websites.
</Accordion>
### Setup Steps
Write Setup steps as a numbered Markdown list (1., 2., 3.), with one short sentence per step, starting with a verb.
A new user should be able to get the template running in a few minutes just by following these steps.
**Writing principles**
1. Follow the real setup order, usually:
1. Use/import the template
2. Connect accounts / add API keys
3. Connect data sources (docs, databases, sheets, etc.)
4. Optional customization (assistant name, tone, filters)
5. Activate the workflow and run a test
2. Each step should answer:
* Where to click in the UI
* What to configure or fill in
3. Aim for 3–8 steps. Too few feels incomplete; too many feels overwhelming.
<Accordion title="Example: Setup Steps for Stock Investment Analysis Copilot (Yahoo Finance tools)">
1) Click **Use template** to copy the "Investment Analysis Copilot (Yahoo Finance)" agent into your workspace.
2) Go to **Integrations** > **Model Provider** and add your LLM API key. For example, OpenAI, Anthropic, or another supported provider.
3) Open the agent's **Orchestrate** page and make sure the Yahoo Finance tools are enabled in the **Tools** section:
* `yahoo Analytics`
* `yahoo News`
* `yahoo Ticker`
4. (Optional) Customize the analysis style:
* In the **INSTRUCTIONS** area, adjust the system prompt to match your target users. For example, tone, report length, preferred language, or risk preference.
* Update the suggested questions in the **Debug & Preview** panel if you want different example queries.
5. Click **Publish** to make the agent available, then use the preview panel to test it:
* Enter a company name or ticker (e.g., `Nvidia`, `AAPL`, `TSLA`).
* Confirm that the copilot calls the Yahoo Finance tools and returns a structured investment analysis report.
</Accordion>
### Quick Checklist Before You Submit
* The name is a short English phrase that clearly shows where it runs and what it does.
* The overview uses 2–4 English sentences to explain the value and typical use cases.
* Only 1–3 relevant categories are selected.
* Setup steps are a clear numbered list.
* Internal workflow texts and prompts are written in appropriate languages for your target users.
# Chat Web Apps
Source: https://docs.dify.ai/en/self-host/use-dify/publish/webapp/chatflow-webapp
Turn your Chatflow into a fully-featured conversation interface with persistent history and interactive features
Chat web apps transform your Chatflow into a complete conversation experience. Users get persistent chat sessions, smart interactions, and all the features you've configured—without installing anything.
## How Chat Apps Work
Your Chatflow automatically becomes a web app when you publish it. The system creates a responsive interface that:
* **Maintains conversation context** across user sessions
* **Inherits all orchestration settings** from your Chatflow configuration
* **Adapts to any screen size** from mobile to desktop
* **Handles user authentication** if you've enabled access controls
<Tip>
Unlike single-use text generators, chat apps maintain conversation memory and let users build on previous exchanges.
</Tip>
## Interactive Features
Your web app automatically includes these capabilities based on your Chatflow settings:
<CardGroup>
<Card title="Pre-conversation Forms" icon="clipboard-list">
Collect context before chatting starts—better than asking mid-conversation
</Card>
<Card title="AI Conversation Starters" icon="message">
Eliminate the blank page problem with helpful opening messages
</Card>
<Card title="Smart Follow-ups" icon="arrow-right">
System generates 3 contextual next questions after each response
</Card>
<Card title="Voice Input" icon="microphone">
Speech-to-text lets users talk instead of type
</Card>
<Card title="Source Citations" icon="quote">
References show exactly where information comes from
</Card>
<Card title="Response Feedback" icon="thumbs-up">
Users can rate responses to help improve your app
</Card>
</CardGroup>
## Pre-conversation Setup
When your Chatflow uses variables, users complete a form before chatting starts. This front-loads context gathering instead of interrupting the conversation flow.
<Frame>

</Frame>
Here's how the user experience works:
<Steps>
<Step title="User lands on your app">
They see a clean form requesting necessary context information.
</Step>
<Step title="Form completion unlocks chat">
The "Start Conversation" button activates only after required fields are filled.
</Step>
<Step title="AI has full context">
The conversation begins with all the background information it needs.
</Step>
</Steps>
<Warning>
Every form field adds friction. Only ask for information that meaningfully improves responses.
</Warning>
## Conversation Experience
Once chatting begins, users get an interface designed for natural interaction:
<Frame>

</Frame>
Every AI response includes these actions:
* **Copy button** - One-click copying for easy sharing or note-taking
* **Feedback buttons** - Like/dislike ratings to improve your app over time
* **Follow-up suggestions** - AI generates 3 contextually relevant next questions
## Session Management
Users can manage multiple conversation threads like modern messaging apps:
<Frame>

</Frame>
**Conversation Controls**:
* **Start new** - Begin fresh conversations without losing context from previous ones
* **Pin important** - Keep crucial conversations accessible at the top of the list
* **Delete finished** - Clean up conversations that are no longer relevant
<Info>
Each conversation thread maintains its own memory and context. Users can seamlessly switch between different topics or projects.
</Info>
## Conversation Openers
Enable conversation openers to eliminate the intimidating blank chat screen:
<Frame>

</Frame>
When users start new conversations, the AI proactively introduces itself and explains its capabilities. This immediately shows users what they can accomplish and increases engagement.
<Tip>
Conversation openers work especially well for specialized apps where users might not know all available features.
</Tip>
## Follow-up Questions
The system automatically generates contextual follow-up questions after each AI response:
<Frame>

</Frame>
These suggestions are:
* **Contextually relevant** to the current conversation topic
* **Dynamically generated** based on the AI's response
* **Clickable shortcuts** that help users explore deeper or pivot to related topics
## Voice Input
Speech-to-text transforms your chat app into a voice-first experience:
<Frame>

</Frame>
**How it works**:
1. The microphone button appears when you enable speech-to-text in your Chatflow
2. Users click to start recording their question
3. Speech converts to text in real-time as they speak
4. They can edit the text before sending or send immediately
<Warning>
Users must grant microphone permissions in their browser. The app will prompt for this permission when they first try to use voice input.
</Warning>
## Citations and Attributions
When this feature is enabled, if the AI references content from the knowledge base while answering a user question, the specific knowledge sources will be displayed below the response.
Citations build user trust by providing transparency about information sources. Users can click through to verify details or explore source materials further.
# Embed Your Web App
Source: https://docs.dify.ai/en/self-host/use-dify/publish/webapp/embedding-in-websites
Deploy your published web app on any website through iframes, chat widgets, or custom integrations
Your published web app can be embedded directly into any website. This isn't a separate publishing method: it's how you deploy the same web app you've already created, just presented within your existing website instead of as a standalone page.
## How Web App Embedding Works
When you publish an app in Dify, you get a web app URL. You can share this URL directly, or embed the same app into your website using these methods:
<CardGroup>
<Card title="Chat Bubble Widget" icon="comment">
Your web app as a floating button that visitors click to open the full interface
</Card>
<Card title="Iframe Integration" icon="window">
Your web app embedded directly in page content, always visible and ready
</Card>
<Card title="JavaScript Control" icon="code">
Advanced embedding with custom styling and behavior control
</Card>
<Card title="Responsive Design" icon="mobile">
Same web app adapts automatically to any presentation format
</Card>
</CardGroup>
<Info>
All embedding methods use your published web app. Changes to your app configuration automatically apply everywhere it's embedded.
</Info>
## Chat Bubble Widget
The chat bubble presents your web app as a floating button. Visitors click it to open your app in an overlay, keeping them on your page while accessing your AI features.
### Configuration Options
The chat bubble can be customized through the `difyChatbotConfig` object:
```javascript theme={null}
window.difyChatbotConfig = {
// Required: Your app's token from Dify
token: 'YOUR_TOKEN',
// Optional: Environment settings
isDev: false,
baseUrl: 'http://your-dify-host', // Auto-set based on isDev
// Optional: Visual customization
containerProps: {
style: {
right: '20px',
bottom: '20px'
},
className: 'custom-chat-button'
},
// Optional: Interactive behavior
draggable: false, // Allow users to drag the button
dragAxis: 'both', // 'x', 'y', or 'both'
// Optional: Pre-fill user context
inputs: {
name: "John Doe", // Variable names from your Dify app
department: "Support"
},
// Optional: System variables for tracking
systemVariables: {
user_id: 'USER_123',
conversation_id: 'CONV_456'
},
// Optional: User profile information
userVariables: {
avatar_url: 'https://example.com/avatar.jpg',
name: 'John Doe'
}
}
```
<Steps>
<Step title="Get your embed token">
In your Dify app, open the **Access Point** tab and click **Embed Into Site** on the **Web App** card to find your unique token.
</Step>
<Step title="Add the script">
Include the configuration and Dify's embed script in your website's HTML.
</Step>
<Step title="Customize appearance">
Adjust the `containerProps` to match your website's design.
</Step>
<Step title="Test functionality">
Open your website and try the chat button to ensure everything works correctly.
</Step>
</Steps>
## Iframe Integration
Embed your web app directly into your page content. This displays your app as an integral part of your website:
```html theme={null}
<iframe
src="http://your-dify-host/chatbot/YOUR_APP_TOKEN"
width="100%"
height="600"
frameborder="0">
</iframe>
```
### Why Use Iframe Embedding
* **Always visible**: Your web app is immediately accessible, not hidden behind a button
* **Full functionality**: Everything from your web app works identically in the iframe
* **Page integration**: Appears as native content, not an overlay
* **Simple setup**: Just HTML, no JavaScript configuration needed
### Customization Options
**Size and Position**:
```html theme={null}
<iframe
src="http://your-dify-host/chatbot/YOUR_APP_TOKEN"
width="400px"
height="500px"
style="border: 1px solid #ccc; border-radius: 8px;">
</iframe>
```
**Responsive Design**:
```html theme={null}
<div style="position: relative; width: 100%; height: 0; padding-bottom: 75%;">
<iframe
src="http://your-dify-host/chatbot/YOUR_APP_TOKEN"
style="position: absolute; top: 0; left: 0; width: 100%; height: 100%;"
frameborder="0">
</iframe>
</div>
```
## Choose Your Embedding Method
<AccordionGroup>
<Accordion title="Customer Support Apps">
**Chat bubble** works best, staying out of the way until needed. The floating button lets visitors continue browsing while having quick access to help.
</Accordion>
<Accordion title="Form & Workflow Apps">
**Iframe embed** for dedicated pages where the app is the main content. Visitors see and use your app immediately without extra clicks.
</Accordion>
<Accordion title="Product Demonstrations">
**Iframe embed** on landing pages to let visitors try your AI capabilities instantly. No barriers between interest and engagement.
</Accordion>
<Accordion title="Multi-page Integration">
**Chat bubble** when you want the same app accessible across your entire site. One embed code provides access from every page.
</Accordion>
</AccordionGroup>
## Advanced Configuration
You can override the default button style using CSS variables or the `containerProps` option. Apply these methods based on CSS specificity to achieve your desired customizations.
### 1. Modify CSS Variables
The following CSS variables are supported for customization:
```css theme={null}
/* Button distance to bottom, default is `1rem` */
--dify-chatbot-bubble-button-bottom
/* Button distance to right, default is `1rem` */
--dify-chatbot-bubble-button-right
/* Button distance to left, default is `unset` */
--dify-chatbot-bubble-button-left
/* Button distance to top, default is `unset` */
--dify-chatbot-bubble-button-top
/* Button background color, default is `#155EEF` */
--dify-chatbot-bubble-button-bg-color
/* Button width, default is `50px` */
--dify-chatbot-bubble-button-width
/* Button height, default is `50px` */
--dify-chatbot-bubble-button-height
/* Button border radius, default is `25px` */
--dify-chatbot-bubble-button-border-radius
/* Button box shadow, default is `rgba(0, 0, 0, 0.2) 0px 4px 8px 0px)` */
--dify-chatbot-bubble-button-box-shadow
/* Button hover transform, default is `scale(1.1)` */
--dify-chatbot-bubble-button-hover-transform
```
To change the background color to #ABCDEF, add this CSS:
```css theme={null}
#dify-chatbot-bubble-button {
--dify-chatbot-bubble-button-bg-color: #ABCDEF;
}
```
### 2. Use `containerProps`
Set inline styles using the `style` attribute:
```javascript theme={null}
window.difyChatbotConfig = {
// ... other configurations
containerProps: {
style: {
backgroundColor: '#ABCDEF',
width: '60px',
height: '60px',
borderRadius: '30px',
},
// For minor style overrides, you can also use a string value for the `style` attribute:
// style: 'background-color: #ABCDEF; width: 60px;',
},
}
```
Apply CSS classes using the `className` attribute:
```javascript theme={null}
window.difyChatbotConfig = {
// ... other configurations
containerProps: {
className: 'dify-chatbot-bubble-button-custom my-custom-class',
},
}
```
### 3. Pass `inputs`
There are four types of inputs supported:
1. **`text-input`**: Accepts any value. The input string will be truncated if its length exceeds the maximum allowed length.
2. **`paragraph`**: Similar to `text-input`, it accepts any value and truncates the string if it's longer than the maximum length.
3. **`number`**: Accepts a number or a numerical string. If a string is provided, it will be converted to a number using the `Number` function.
4. **`options`**: Accepts any value, provided it matches one of the pre-configured options.
Example configuration:
```javascript theme={null}
window.difyChatbotConfig = {
// Other configuration settings...
inputs: {
name: 'apple',
},
}
```
Note: When using the embed.js script to create an iframe, each input value will be processed (compressed using GZIP and encoded in base64) before being appended to the URL.
For example, the URL with processed input values will look like this:
`http://localhost/chatbot/{token}?name=H4sIAKUlmWYA%2FwWAIQ0AAACDsl7gLuiv2PQEUNAuqQUAAAA%3D`
## Troubleshooting
**Widget not appearing**:
* Verify your app token matches what's shown under **Embed Into Site** on the app's **Access Point** tab
* Check that configuration loads before the embed script
* Look for JavaScript errors in browser console
**Iframe not loading**:
* Confirm the web app URL includes your correct token
* Ensure your site allows iframe content (check Content Security Policy)
* Both your site and Dify app should use HTTPS
<Warning>
Your web app must be published before embedding. If you update your app configuration, republish to see changes in embedded versions.
</Warning>
# Settings
Source: https://docs.dify.ai/en/self-host/use-dify/publish/webapp/web-app-settings
Configure branding, basic access controls, and user experience settings for your published web applications
Web app settings control how your published applications look and behave for end users. Every Dify application automatically generates a web interface that adapts to different devices and screen sizes.
## How Settings Work
Your web app reflects your application's current configuration. When you modify settings and click **Publish**, changes flow immediately to the live web application that users are accessing.
<Info>
Web apps are public by default. Anyone with the URL can access them, which works well for demos, public tools, and customer-facing applications.
</Info>
## Branding and Appearance
Make your web app look professional and recognizable:
<CardGroup>
<Card title="App Identity" icon="id-card">
Set your app name, description, and icon to create a clear first impression
</Card>
<Card title="Visual Design" icon="palette">
Choose colors, themes, and layout options that match your brand
</Card>
<Card title="Language Settings" icon="globe">
Configure interface language for your target audience
</Card>
<Card title="Legal Pages" icon="scale-balanced">
Add copyright information and privacy policy links for compliance
</Card>
</CardGroup>
### Essential Branding Elements
**App Icon and Name**
* Your icon appears in browser tabs and when users bookmark your app
* Choose a clear, recognizable name that explains what your app does
* Icons can be images or emojis; pick what fits your app's personality
**Description and Messaging**
* Write a concise description that helps users understand your app's purpose
* This text appears on the app's landing page and in search results
* Keep it under 160 characters for best results
**Input Placeholder**
* Replace the default hint text in the chat input box with a prompt of your own, up to 64 characters
* Available for chat-style apps (Chatbot, Agent, and Chatflow); leave it empty to keep the default
**Visual Consistency**
* Choose colors that align with your brand
* Consider your audience when selecting light or dark themes
* Test your app on different devices to ensure it looks good everywhere
## Access Controls
Web apps are public by default. Anyone with the URL can open them, which works well for demos, public tools, and customer-facing applications.
<Tip>
On Dify Enterprise, you can restrict who opens a web app with authentication, member-level access, and external-user management. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
**Privacy and Legal**:
* Add copyright information and privacy policy links
* Configure data handling preferences
* Set terms of service for compliance
## Feature Inheritance
Your web app automatically includes features you've enabled in your app configuration:
**Interactive Features**:
* Conversation openers and suggested follow-ups
* Pre-conversation forms for context gathering
* Voice input and speech-to-text capabilities
* Source citations and reference links
* Feedback collection and rating systems
**Functionality**:
* All workflow steps and AI model configurations
* Knowledge base integrations and tool connections
* Custom prompts and response formatting
* Rate limiting and usage controls
<Warning>
Disabling features in your app configuration immediately removes them from the published web app.
</Warning>
## App Types and Behavior
Your web app automatically adapts its interface based on your app type:
<Tabs>
<Tab title="Chat Apps">
**Interface**: Conversation-style with message history
**Features**: Persistent sessions, conversation management, real-time responses
**Best for**: Customer support, consulting tools, interactive assistants
</Tab>
<Tab title="Workflow Apps">
**Interface**: Form-based with result display
**Features**: Single runs, batch processing, result saving
**Best for**: Content generation, data processing, analysis tools
</Tab>
</Tabs>
## Deployment Options
Once published, your web app can be accessed in multiple ways:
<CardGroup>
<Card title="Direct Link" icon="link">
Share the web app URL for immediate access
</Card>
<Card title="Website Embedding" icon="window" href="/en/self-host/use-dify/publish/webapp/embedding-in-websites">
Deploy as chat widgets or iframes on existing websites
</Card>
</CardGroup>
## Publishing Best Practices
Before sharing your web app:
<Steps>
<Step title="Test the user experience">
Try your app on different devices and browsers to ensure it works smoothly.
</Step>
<Step title="Configure essential settings">
Set up your app name, icon, description, and any required legal information.
</Step>
<Step title="Review access controls">
Decide if your app should be public or require authentication.
</Step>
<Step title="Choose deployment method">
Determine whether to share directly or embed on your website.
</Step>
</Steps>
<Tip>
Your web app configuration applies everywhere it's deployed. Changes to settings automatically update embedded versions too.
</Tip>
# Workflow Web Apps
Source: https://docs.dify.ai/en/self-host/use-dify/publish/webapp/workflow-webapp
Turn your workflows into powerful web applications with batch processing, result management, and streamlined user experiences
Workflow web apps transform your Dify workflows into production-ready applications that handle everything from single runs to large-scale batch operations. Users get a clean interface for input, real-time processing feedback, and comprehensive result management.
## How Workflow Apps Work
When you publish a workflow, Dify automatically creates a web interface that:
* **Collects input parameters** through forms based on your workflow's start variables
* **Processes requests** using your complete workflow logic
* **Handles results** with built-in saving, copying, and management features
* **Scales automatically** from single runs to batch processing hundreds of items
<Info>
Unlike chat apps that maintain conversation context, Workflow apps are designed for discrete tasks that produce specific outputs.
</Info>
<CardGroup>
<Card title="Single Execution" icon="play">
Run workflows one at a time with immediate results and feedback
</Card>
<Card title="Batch Processing" icon="layer-group">
Process hundreds of inputs simultaneously with CSV upload/download
</Card>
<Card title="Result Management" icon="bookmark">
Save, organize, and export outputs with built-in storage
</Card>
<Card title="More Like This" icon="copy">
Generate variations of successful outputs automatically
</Card>
</CardGroup>
## Single Execution
The default mode for Workflow apps handles individual requests with real-time processing:
<Frame>

</Frame>
**User Experience**:
1. **Fill input form**: Users provide parameters based on your workflow's start variables
2. **Click run**: The workflow executes with real-time progress indication
3. **View results**: Output appears with immediate access to copy, save, and feedback options
4. **Take actions**: Users can save important results, provide feedback, or generate similar outputs
Each result includes built-in actions:
* **Copy**: One-click copying to clipboard for easy sharing
* **Save**: Store results in the app's saved items for later access
* **Feedback**: Like/dislike ratings to help improve your workflow
* **More like this**: Generate variations based on the current result (if enabled)
## Batch Processing
When you need to run the same workflow on multiple inputs, batch processing handles hundreds of executions simultaneously:
<Tip>
Perfect for tasks like generating content for multiple topics, processing customer data, or analyzing large datasets.
</Tip>
### Set Up Batch Runs
<Steps>
<Step title="Switch to batch mode">
Click the **Run Batch** tab to access batch processing features.
<Frame>

</Frame>
</Step>
<Step title="Get the CSV template">
Download the template file to see the required column structure for your workflow's input variables.
<Frame>

</Frame>
</Step>
<Step title="Prepare your data">
Fill the template with your input data. Each row becomes one workflow execution.
</Step>
<Step title="Upload and run">
Upload your completed CSV file and start batch processing.
<Frame>

</Frame>
</Step>
</Steps>
### Batch Processing Benefits
* **Parallel execution**: Multiple workflow runs happen simultaneously
* **Progress tracking**: Real-time updates on completion status
* **Bulk export**: Download all results as a CSV file when finished
* **Error handling**: Failed items are clearly marked with error details
<Warning>
CSV files must use Unicode encoding to prevent import failures. When saving from Excel or similar tools, explicitly select "Unicode (UTF-8)" encoding.
</Warning>
## Result Management
Workflow apps include comprehensive result management to help users organize and reuse outputs:
### Save Results
<Frame>

</Frame>
**How saving works**:
* Users click **Save** on any result they want to keep
* Saved items appear in the dedicated **Saved** tab
* Each saved result includes the original inputs and full outputs
* Users can organize saved results and access them anytime
<Info>
Saved results persist across user sessions, making Workflow apps useful for building personal libraries of outputs.
</Info>
### Generate Variations
When you enable **More like this** in your workflow settings, users can generate variations of successful results:
<Frame>

</Frame>
**How it works**:
1. User gets a result they like
2. They click **More like this** to generate similar outputs
3. The workflow runs again with slight variations to produce different but related results
4. Users can iterate until they find the perfect output
<Tip>
**More like this** works especially well for creative workflows like content generation, where users want to explore different approaches to the same topic.
</Tip>
# Custom Endpoints
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/api-extension/api-extension
You can extend module capabilities through custom endpoints. Currently, the following extension types are supported:
* `moderation` Sensitive content moderation
* `external_data_tool` External data tools
Before extending module capabilities, you need to prepare an API and an API Key for authentication.
In addition to developing the corresponding module capabilities, you also need to follow the specifications below to ensure Dify correctly calls the API.
## API Specification
Dify will call your interface with the following specification:
```
POST {Your-API-Endpoint}
```
### Header
| Header | Value | Desc |
| --------------- | ------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `Content-Type` | application/json | The request content is in JSON format. |
| `Authorization` | Bearer \{api\_key} | The API Key is transmitted as a Token. You need to parse the `api_key` and verify that it matches the provided API Key to ensure interface security. |
### Request Body
```
{
"point": string, // Extension point, different modules may contain multiple extension points
"params": {
... // Parameters passed to each module extension point
}
}
```
### API Response
```
{
... // Content returned by the API, see the specification design of different modules for different extension point returns
}
```
## Validation
When configuring a custom endpoint in Dify, Dify will send a request to the API Endpoint to verify API availability.
When the API Endpoint receives `point=ping`, the interface should return `result=pong`, as follows:
### Header
```
Content-Type: application/json
Authorization: Bearer {api_key}
```
### Request Body
```
{
"point": "ping"
}
```
### Expected API Response
```
{
"result": "pong"
}
```
## Example
Here we use an external data tool as an example, where the scenario is to retrieve external weather information by region as context.
### API Example
```
POST https://fake-domain.com/api/dify/receive
```
**Header**
```
Content-Type: application/json
Authorization: Bearer 123456
```
**Request Body**
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
**API Response**
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
### Code Example
The code is based on the Python FastAPI framework.
1. Install dependencies
```
pip install fastapi[all] uvicorn
```
2. Write code according to the interface specification
```
from fastapi import FastAPI, Body, HTTPException, Header
from pydantic import BaseModel
app = FastAPI()
class InputData(BaseModel):
point: str
params: dict = {}
@app.post("/api/dify/receive")
async def dify_receive(data: InputData = Body(...), authorization: str = Header(None)):
"""
Receive API query data from Dify.
"""
expected_api_key = "123456" # TODO Your API key of this API
auth_scheme, _, api_key = authorization.partition(' ')
if auth_scheme.lower() != "bearer" or api_key != expected_api_key:
raise HTTPException(status_code=401, detail="Unauthorized")
point = data.point
# for debug
print(f"point: {point}")
if point == "ping":
return {
"result": "pong"
}
if point == "app.external_data_tool.query":
return handle_app_external_data_tool_query(params=data.params)
# elif point == "{point name}":
# TODO other point implementation here
raise HTTPException(status_code=400, detail="Not implemented")
def handle_app_external_data_tool_query(params: dict):
app_id = params.get("app_id")
tool_variable = params.get("tool_variable")
inputs = params.get("inputs")
query = params.get("query")
# for debug
print(f"app_id: {app_id}")
print(f"tool_variable: {tool_variable}")
print(f"inputs: {inputs}")
print(f"query: {query}")
# TODO your external data tool query implementation here,
# return must be a dict with key "result", and the value is the query result
if inputs.get("location") == "London":
return {
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind "
"Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
else:
return {"result": "Unknown city"}
```
3. Start the API service. The default port is 8000, the complete API address is: `http://127.0.0.1:8000/api/dify/receive`, and the configured API Key is `123456`.
```
uvicorn main:app --reload --host 0.0.0.0
```
4. Configure this API in Dify.
5. Select this custom endpoint in the App.
When debugging the App, Dify will request the configured API and send the following content (example):
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
The API response is:
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
## Local Debugging
To debug a custom endpoint that runs on your local machine while Dify is deployed elsewhere, you can use [Ngrok](https://ngrok.com) to expose the local endpoint to the public internet so your Dify instance can reach it. Steps:
1. Go to [https://ngrok.com](https://ngrok.com), register and download the Ngrok file.
<Frame>

</Frame>
2. After downloading, go to the download directory, extract the archive according to the instructions below, and execute the initialization script in the instructions.
```shell theme={null}
unzip /path/to/ngrok.zip
./ngrok config add-authtoken your-token
```
3. Check the port of your local API service:
<Frame>

</Frame>
And run the following command to start:
```shell theme={null}
./ngrok http port-number
```
A successful startup example looks like this:
<Frame>

</Frame>
4. Find the Forwarding address, as shown above: `https://177e-159-223-41-52.ngrok-free.app` (this is an example domain, please replace with your own), which is the public domain.
Following the example above, we expose the locally started service endpoint and replace the code example interface: `http://127.0.0.1:8000/api/dify/receive` with `https://177e-159-223-41-52.ngrok-free.app/api/dify/receive`
This API endpoint can now be accessed publicly. At this point, we can configure this API endpoint in Dify for local code debugging. For configuration steps, please refer to [External Data Tool](/en/self-host/use-dify/workspace/api-extension/external-data-tool-api-extension).
## Deploy Custom Endpoints Using Cloudflare Workers
We recommend using Cloudflare Workers to deploy your custom endpoints because Cloudflare Workers can conveniently provide a public network address and can be used for free.
For detailed instructions, see [Deploy Custom Endpoints Using Cloudflare Workers](/en/self-host/use-dify/workspace/api-extension/cloudflare-worker).
# Deploy Custom Endpoints Using Cloudflare Workers
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/api-extension/cloudflare-worker
## Procedure
Since Dify custom endpoints require a publicly accessible address as the API Endpoint, the endpoint needs to be deployed to a public address.
Here we use Cloudflare Workers to deploy the custom endpoint.
Clone the [Example GitHub Repository](https://github.com/crazywoola/dify-extension-workers). This repository contains a simple custom endpoint that can be modified as a starting point.
```bash theme={null}
git clone https://github.com/crazywoola/dify-extension-workers.git
cp wrangler.toml.example wrangler.toml
```
Open the `wrangler.toml` file and modify `name` and `compatibility_date` to your application name and compatibility date.
The configuration we need to pay attention to here is the `TOKEN` in `vars`. When adding a custom endpoint in Dify, we need to fill in this Token. For security reasons, we recommend using a random string as the Token. You should not write the Token directly in the source code, but pass it through environment variables. Therefore, please do not commit wrangler.toml to your code repository.
```toml theme={null}
name = "dify-extension-example"
compatibility_date = "2023-01-01"
[vars]
TOKEN = "bananaiscool"
```
This custom endpoint will return a random Breaking Bad quote. You can modify the logic of this custom endpoint in `src/index.ts`. This example demonstrates how to interact with third-party APIs.
```typescript theme={null}
// ⬇️ implement your logic here ⬇️
// point === "app.external_data_tool.query"
// https://api.breakingbadquotes.xyz/v1/quotes
const count = params?.inputs?.count ?? 1;
const url = `https://api.breakingbadquotes.xyz/v1/quotes/${count}`;
const result = await fetch(url).then(res => res.text())
// ⬆️ implement your logic here ⬆️
```
This repository simplifies all configurations except business logic. You can directly use `npm` commands to deploy your custom endpoint.
```bash theme={null}
npm install
npm run deploy
```
After successful deployment, you will get a public address that you can add in Dify as the custom endpoint. Please note not to omit the `endpoint` path. The specific definition of this path can be found in `src/index.ts`.
<Frame>

</Frame>
Alternatively, you can use the `npm run dev` command to deploy locally for testing.
```bash theme={null}
npm install
npm run dev
```
Related output:
```bash theme={null}
$ npm run dev
> dev
> wrangler dev src/index.ts
⛅️ wrangler 3.99.0
-------------------
Your worker has access to the following bindings:
- Vars:
- TOKEN: "ban****ool"
⎔ Starting local server...
[wrangler:inf] Ready on http://localhost:58445
```
After that, you can use tools like Postman for local interface debugging.
## About Bearer Auth
```typescript theme={null}
import { bearerAuth } from "hono/bearer-auth";
(c, next) => {
const auth = bearerAuth({ token: c.env.TOKEN });
return auth(c, next);
},
```
Our Bearer validation logic is in the above code. We use the `hono/bearer-auth` package to implement Bearer validation. You can use `c.env.TOKEN` in `src/index.ts` to get the Token.
## About Parameter Validation
```typescript theme={null}
import { z } from "zod";
import { zValidator } from "@hono/zod-validator";
const schema = z.object({
point: z.union([
z.literal("ping"),
z.literal("app.external_data_tool.query"),
]), // Restricts 'point' to two specific values
params: z
.object({
app_id: z.string().optional(),
tool_variable: z.string().optional(),
inputs: z.record(z.any()).optional(),
query: z.any().optional(), // string or null
})
.optional(),
});
```
We use `zod` to define parameter types here. You can use `zValidator` in `src/index.ts` to validate parameters. Use `const { point, params } = c.req.valid("json");` to get the validated parameters.
The `point` here has only two values, so we use `z.union` to define it. `params` is an optional parameter, so we use `z.optional` to define it. There will be an `inputs` parameter, which is a `Record<string, any>` type. This type represents an object with string keys and any values. This type can represent any object. You can use `params?.inputs?.count` in `src/index.ts` to get the `count` parameter.
## Get Cloudflare Workers Logs
```bash theme={null}
wrangler tail
```
***
**Reference**:
* [Cloudflare Workers](https://workers.cloudflare.com/)
* [Cloudflare Workers CLI](https://developers.cloudflare.com/workers/cli-wrangler/install-update)
* [Example GitHub Repository](https://github.com/crazywoola/dify-extension-workers)
# External Data Tool
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/api-extension/external-data-tool-api-extension
When creating AI applications, you can use external tools to obtain additional data through [Custom Endpoints](/en/self-host/use-dify/workspace/api-extension/api-extension) and assemble it into the prompt as additional information for the LLM.
## Extension Point
`app.external_data_tool.query`: Application external data tool query extension point.
This extension point passes the application variable content input by the end user and the conversation input content (fixed parameter for conversational applications) to the API as parameters.
You need to implement the corresponding tool query logic and return query results as string type.
### Request Body
```
{
"point": "app.external_data_tool.query", // Extension point type, fixed as app.external_data_tool.query
"params": {
"app_id": string, // Application ID
"tool_variable": string, // External data tool variable name, indicating the source of the corresponding variable tool call
"inputs": { // Variable values passed by end user, key is variable name, value is variable value
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Current conversation input content from end user, fixed parameter for conversational applications.
}
}
```
**Example**:
```
{
"point": "app.external_data_tool.query",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"tool_variable": "weather_retrieve",
"inputs": {
"location": "London"
},
"query": "How's the weather today?"
}
}
```
### API Response
```
{
"result": string
}
```
**Example**:
```
{
"result": "City: London\nTemperature: 10°C\nRealFeel®: 8°C\nAir Quality: Poor\nWind Direction: ENE\nWind Speed: 8 km/h\nWind Gusts: 14 km/h\nPrecipitation: Light rain"
}
```
# Sensitive Content Moderation
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/api-extension/moderation-api-extension
This module is used to review the content input by end users and the content output by LLM in applications. It is divided into two extension point types.
## Extension Points
* `app.moderation.input`: End user input content review extension point
* Used to review variable content passed in by end users and conversation input content in conversational applications.
* `app.moderation.output`: LLM output content review extension point
* Used to review content output by LLM.
* When the LLM output is streaming, the output content will be segmented into 100-character chunks for API requests to avoid delayed reviews when output content is lengthy.
### app.moderation.input
When **Content Moderation > Review Input Content** is enabled in applications such as Chatflow, Agent, or Chatbot, Dify will send the following HTTP POST request to the corresponding custom endpoint:
#### Request Body
```
{
"point": "app.moderation.input", // Extension point type, fixed as app.moderation.input
"params": {
"app_id": string, // Application ID
"inputs": { // Variable values passed by end user, key is variable name, value is variable value
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Current conversation input content from end user, fixed parameter for conversational applications.
}
}
```
**Example**:
```
{
"point": "app.moderation.input",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"inputs": {
"var_1": "My SSN is 123-45-6789.",
"var_2": "My phone number is 123-456-7890."
},
"query": "Please help me update my account."
}
}
```
#### API Response
```
{
"flagged": bool, // Whether it violates validation rules
"action": string, // Action: direct_output outputs preset response; overridden overwrites input variable values
"preset_response": string, // Preset response (returned only when action=direct_output)
"inputs": { // Variable values passed by end user, key is variable name, value is variable value (returned only when action=overridden)
"var_1": "value_1",
"var_2": "value_2",
...
},
"query": string | null // Overwritten current conversation input content from end user, fixed parameter for conversational applications. (returned only when action=overridden)
}
```
**Example**:
* `action=direct_output`
```
{
"flagged": true,
"action": "direct_output",
"preset_response": "Your content violates our usage policy."
}
```
* `action=overridden`
```
{
"flagged": true,
"action": "overridden",
"inputs": {
"var_1": "My SSN is ***-**-****.",
"var_2": "My phone number is ***-***-****."
},
"query": "Please help me update my account."
}
```
### app.moderation.output
When **Content Moderation > Review Output Content** is enabled in applications such as Chatflow, Agent, or Chat Assistant, Dify will send the following HTTP POST request to the corresponding custom endpoint:
#### Request Body
```
{
"point": "app.moderation.output", // Extension point type, fixed as app.moderation.output
"params": {
"app_id": string, // Application ID
"text": string // LLM response content. When LLM output is streaming, this is content segmented into 100-character chunks.
}
}
```
**Example**:
```
{
"point": "app.moderation.output",
"params": {
"app_id": "61248ab4-1125-45be-ae32-0ce91334d021",
"text": "My SSN is 123-45-6789."
}
}
```
#### API Response
```
{
"flagged": bool, // Whether it violates validation rules
"action": string, // Action: direct_output outputs preset response; overridden overwrites input variable values
"preset_response": string, // Preset response (returned only when action=direct_output)
"text": string // Overwritten LLM response content. (returned only when action=overridden)
}
```
**Example**:
* `action=direct_output`
```
{
"flagged": true,
"action": "direct_output",
"preset_response": "Your content violates our usage policy."
}
```
* `action=overridden`
```
{
"flagged": true,
"action": "overridden",
"text": "My SSN is ***-**-****."
}
```
## Code Example
Below is a piece of `src/index.ts` code that can be deployed on Cloudflare. (For complete Cloudflare usage, please refer to [this documentation](/en/self-host/use-dify/workspace/api-extension/cloudflare-worker))
The code works by performing keyword matching to filter both Input (content entered by users) and Output (content returned by the model). Users can modify the matching logic according to their needs.
```
import { Hono } from "hono";
import { bearerAuth } from "hono/bearer-auth";
import { z } from "zod";
import { zValidator } from "@hono/zod-validator";
import { generateSchema } from '@anatine/zod-openapi';
type Bindings = {
TOKEN: string;
};
const app = new Hono<{ Bindings: Bindings }>();
// API format validation ⬇️
const schema = z.object({
point: z.union([
z.literal("ping"),
z.literal("app.external_data_tool.query"),
z.literal("app.moderation.input"),
z.literal("app.moderation.output"),
]), // Restricts 'point' to two specific values
params: z
.object({
app_id: z.string().optional(),
tool_variable: z.string().optional(),
inputs: z.record(z.any()).optional(),
query: z.any(),
text: z.any()
})
.optional(),
});
// Generate OpenAPI schema
app.get("/", (c) => {
return c.json(generateSchema(schema));
});
app.post(
"/",
(c, next) => {
const auth = bearerAuth({ token: c.env.TOKEN });
return auth(c, next);
},
zValidator("json", schema),
async (c) => {
const { point, params } = c.req.valid("json");
if (point === "ping") {
return c.json({
result: "pong",
});
}
// ⬇️ implement your logic here ⬇️
// point === "app.external_data_tool.query"
else if (point === "app.moderation.input"){
// Input check ⬇️
const inputkeywords = ["input filter test 1", "input filter test 2", "input filter test 3"];
if (inputkeywords.some(keyword => params.query.includes(keyword)))
{
return c.json({
"flagged": true,
"action": "direct_output",
"preset_response": "The input contains illegal content. Please try a different question!"
});
} else {
return c.json({
"flagged": false,
"action": "direct_output",
"preset_response": "Input is normal"
});
}
// Input check complete
}
else {
// Output check ⬇️
const outputkeywords = ["output filter test 1", "output filter test 2", "output filter test 3"];
if (outputkeywords.some(keyword => params.text.includes(keyword)))
{
return c.json({
"flagged": true,
"action": "direct_output",
"preset_response": "The output contains sensitive content and has been filtered by the system. Please try a different question!"
});
}
else {
return c.json({
"flagged": false,
"action": "direct_output",
"preset_response": "Output is normal"
});
};
}
// Output check complete
}
);
export default app;
```
# Manage Apps
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/app-management
Organize, maintain, and share your AI applications with powerful management tools and best practices
Managing your apps well is crucial for productive AI development. Dify provides comprehensive tools to organize, share, and maintain your applications throughout their lifecycle.
## App Organization
<CardGroup>
<Card title="Edit & Customize" icon="edit">
Update names, descriptions, icons, and branding for better organization
</Card>
<Card title="Duplicate & Template" icon="copy">
Create variations or use existing apps as templates for new projects
</Card>
<Card title="Import & Export" icon="right-left">
Share apps between workspaces using Dify's DSL format
</Card>
<Card title="Lifecycle Management" icon="recycle">
Safely delete apps when no longer needed
</Card>
</CardGroup>
## Edit Application Information
Keep your apps organized with clear, descriptive information:
<Frame>

</Frame>
<Steps>
<Step title="Access app settings">
Click "Edit info" in the upper left corner of your application.
</Step>
<Step title="Update details">
Modify the icon, name, or description to better reflect the app's purpose.
</Step>
<Step title="Consider your team">
Use names and descriptions that help team members understand what the app does.
</Step>
</Steps>
<Tip>
Use consistent naming conventions across your workspace. Consider prefixes like "Draft-", "Test-", or "Prod-" to indicate app status.
</Tip>
## Create App Variations
Duplication is perfect for creating variations or starting new projects from existing work:
**When to duplicate**:
* Creating A/B test versions with different prompts or models
* Adapting an app for different audiences or use cases
* Starting a new project based on successful patterns
* Creating backups before major changes
**How duplication works**:
* All configuration, prompts, and workflows are copied
* The new app gets a default name you can customize
* Original app remains unchanged
* Both apps run independently
## App Export and Import
Dify's DSL (Domain Specific Language) format lets you share apps between workspaces and teams:
<Frame>

</Frame>
### Export Applications
**Two ways to export**:
1. **From Studio page** - Click "Export DSL" in the application menu
2. **From orchestration** - Click "Export DSL" in the upper left corner
**What gets exported**:
* App configuration and metadata
* Workflow orchestration and node settings
* Model parameters and prompt templates
* Knowledge base connections (not the data itself)
**What doesn't get exported**:
* API keys for third-party tools (security measure)
* Actual knowledge base content
* Usage logs and analytics data
<Warning>
If your app uses Secret-type environment variables, you'll be asked whether to include them in the export. Be careful with sensitive information.
</Warning>
<Frame>

</Frame>
### Import Applications
<Frame>

</Frame>
**Import process**:
1. Upload your DSL file (YAML format)
2. System checks version compatibility
3. Warning appears if DSL version is older than current platform
4. App is created with all configurations from the file
**Version compatibility**: Importing a DSL file created on a newer Dify version may require upgrading first.
<Info>
Dify DSL is the AI application engineering standard (v0.6+) that captures complete app configurations in YAML format.
</Info>
## Safe App Deletion
Before deleting apps, understand the impact:
**What gets deleted**:
* All app configurations and prompts
* Workflow orchestration and settings
* Usage logs and analytics
* Published web apps and API access
* All user conversations and data
**Impact on users**:
* Published web apps stop working immediately
* API calls start returning errors
* All existing user sessions are terminated
<Steps>
<Step title="Consider alternatives">
Could you duplicate the app for backup, or just unpublish instead of deleting?
</Step>
<Step title="Notify stakeholders">
Let team members and users know about planned deletions.
</Step>
<Step title="Export if needed">
Create DSL backups of valuable configurations before deletion.
</Step>
<Step title="Confirm deletion">
Click "Delete" and confirm—this action cannot be undone.
</Step>
</Steps>
<Warning>
App deletion is permanent and cannot be undone. All associated data, logs, and user access will be lost immediately.
</Warning>
# Model Providers
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/model-providers
Add model providers to your workspace so your apps can use LLMs, embedding models, and other AI services
Every Dify app needs at least one model provider. Install a provider, add your API key, and all apps in the workspace can use its models.
<Warning>
API keys grant workspace-wide model access and trigger direct billing through each provider's account. Only the workspace owner and admins can manage providers.
</Warning>
## Add a Provider
1. In **Integrations** > **Model Provider**, browse the **Install model providers** section or visit the [Marketplace](https://marketplace.dify.ai/) for more options.
2. After installing, click **Setup** on the provider card and enter your API key (and any other required credentials, such as a custom endpoint URL or organization ID). Dify validates the credentials before making the provider available.
## Add a Custom Model
A provider's models are ready as soon as you connect it, so you only add one by hand when the model you need isn't listed, such as a brand-new or fine-tuned model.
Click **Add Model** on the provider's card, then give the model a name and its credentials. Providers that serve only a fixed set of models don't offer this option.
<Info>
If the model you add matches the name and type of an existing one, Dify attaches the new key to that model instead of creating a duplicate.
</Info>
## Manage Your Keys
Add more than one key to a provider when you want to keep development and production apart or spread usage across several accounts.
* For a provider's own models, click **Configure** on its card to manage the keys they share.
<Frame>
<img alt="Manage Credentials for a Provider's Models" />
</Frame>
* For a custom model you added, click **Configure** on that model to manage its own keys.
<Columns>
<Frame>
<img alt="Custom Model Configuration" />
</Frame>
<Frame>
<img alt="Custom Model Credentials" />
</Frame>
</Columns>
<Warning>
A custom model relies on its own keys. Deleting its only key removes the model too.
</Warning>
To view every custom model's keys in one place, click **Manage Credentials** on the provider card.
<Frame>
<img alt="Manage Credentials for All Custom Models" />
</Frame>
Keys stay here even after the custom model is removed, so you can re-add the model later without re-entering its keys.
<Frame>
<img alt="Re-add a Removed Model" />
</Frame>
## Choose the Models Apps Use by Default
Apps and nodes that don't pick a model fall back to your workspace defaults. Click **Default Models** at the top-right corner to set one for each job:
* **System Reasoning Model**: the default for general LLM tasks.
* **Embedding Model**: indexes and retrieves knowledge base content.
* **Rerank Model**: reorders retrieval results by relevance.
* **Speech-to-Text Model**: turns audio into text.
* **Text-to-Speech Model**: turns text into audio.
# Personal Settings
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/personal-account-management
Manage your profile, login, and interface preferences
Your personal account holds your profile, language preferences, and login credentials. Your role and permissions within the workspace are set by the workspace Owner or an Admin.
## Account Setup
The administrator account is created during installation, using the email and password set at deploy time. Additional accounts are added by invitation from a workspace Owner or Admin.
## Profile Management
Update your profile information in **Settings → Account → Profile**.
**Profile picture**: Upload a custom avatar. This replaces the default initials-based avatar.
**Display name**: How you appear to other workspace members. Choose something that helps teammates identify you.
**Email address**: Your primary login credential and unique identifier.
## Language and Interface
**Display language**: Available languages include English, Simplified Chinese, and Traditional Chinese. This setting affects interface elements but not your application content.
**Change language**: Click your avatar, choose **Language**, then select your preferred language.
## Login Methods
Sign in with your email address and password. The credentials are the ones set when the administrator account was created at install time, or provisioned later by an Owner or Admin.
<Tip>
On Dify Enterprise, you can sign in with OAuth or SAML single sign-on instead of a password. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
## Security
Use a strong, unique password and rotate it regularly. Don't share login credentials with others.
# Integrations
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/plugins
Connect Dify to model providers, tools, data sources, and external services
Integrations connect your Dify apps to the outside world. They supply the model providers that power your apps, the tools your agents and workflows call, the data sources behind your knowledge bases, and the services that extend what you build.
Install an integration once, and every app in your workspace can use it. Browse and manage them all from **Integrations**.
## Integration Types
* [**Model Provider**](/en/self-host/use-dify/workspace/model-providers): The models that power your apps, from LLMs to embedding and rerank models.
* [**Tool**](/en/self-host/use-dify/workspace/tools): Capabilities your agents and workflows can call, including tool plugins, MCP servers, published workflows, and OpenAPI services.
* [**Data Source**](/en/self-host/use-dify/knowledge/knowledge-pipeline/authorize-data-source): External content for pipeline-built knowledge bases, such as Google Drive or Notion pages.
* [**Trigger**](/en/self-host/use-dify/nodes/trigger/plugin-trigger): Start a workflow automatically when an external event fires.
* **Agent Strategy**: The reasoning strategy an [Agent node](/en/self-host/use-dify/nodes/agent) follows to make decisions, select and call tools, and act on the results.
* [**Custom Endpoint**](/en/self-host/use-dify/workspace/api-extension/api-extension): Connect your own API to add content moderation or external data tools to your apps.
* **Extension**: Integrations that expose custom HTTP endpoints, extending Dify with capabilities the other categories don't cover.
## Install Integrations
Add integrations from three sources:
* [**Marketplace**](https://marketplace.dify.ai/): Official and partner integrations, tested and maintained.
* **GitHub**: Install from any public repository by URL and version.
* **Local upload**: Custom `.zip` packages for private or internal integrations.
<Tip>
On Dify Enterprise, admins can restrict installation across the deployment, limiting it to official integrations, official plus verified partners, or marketplace installs only. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
## Permissions and Updates
The workspace owner and admins can set two workspace-wide permissions for integrations, each to **Everyone**, **Admins**, or **No one**:
* **Who can install and manage integrations**: Installing, upgrading, and removing. Defaults to **Everyone**.
* **Who can debug integrations**: Access to the debugging key. Defaults to **No one**.
Integrations can also be set to update automatically. Each category (tools, models, data sources, and so on) has its own update strategy (off, patch versions only, or always the latest), applied to every integration in the category or a chosen subset.
## Build Your Own
<Info>
Need an integration that doesn't exist yet? Build it with Dify's plugin SDK, then keep it private or publish it to the Marketplace. See [Develop a Plugin](/en/develop-plugin/getting-started/getting-started-dify-plugin).
</Info>
# Overview
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/readme
Workspaces are the foundational organizational unit in Dify—everything your team builds, configures, and manages exists within a workspace
A workspace is your team's complete AI environment in Dify. It contains and isolates everything your organization needs: applications, knowledge bases, team members, model configurations, and integrations.
## The Workspace Mental Model
Every resource in Dify belongs to a workspace. When you create an app, it inherits the workspace's model configurations. When you add team members, they get access to workspace resources based on their role. When you configure models or install integrations, they become available to the entire workspace.
This workspace-first design means your resources are completely isolated from other organizations, team members can only access what they're permitted to see, and you configure models once for the entire workspace.
## Workspace Creation
One workspace is created during installation, with the administrator email and password set during setup.
<Tip>
On Dify Enterprise, you can run multiple workspaces for complete isolation between legal entities, regulatory environments, or client projects. [Contact sales](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
## How Resources Connect
Applications you build can use any model providers configured in the workspace, access all workspace knowledge bases, and use installed integrations. Team members see applications based on their workspace permissions.
Workspace roles determine access across all resources:
* **Owners** control model providers and workspace settings
* **Admins** manage team members and configure models and integrations
* **Editors** build applications and manage knowledge bases
* **Members** use published applications
# Manage Members
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/team-members-management
Add teammates to your workspace and manage the roles that control their access
Workspace members are added and managed in **Settings** > **Members**. Each member's access is determined by the role they hold.
## Roles
There are four built-in roles:
* **Owner**: Full control of the workspace. One per workspace.
* **Admin**: Manage members and model providers, plus everything an Editor can do.
* **Editor**: Create, edit, and delete apps and knowledge bases.
* **Normal**: Use published apps only.
<Info>
The Owner, Admin, and Editor roles can *create* knowledge bases, while who can *see and use* an existing one is controlled in its own settings. See [Manage Knowledge Settings](/en/self-host/use-dify/knowledge/manage-knowledge/introduction) for details.
</Info>
<Tip>
On Dify Enterprise, you can create custom roles and grant members granular access to apps and knowledge bases. [**Contact sales**](https://share-na2.hsforms.com/14-09ff5HS92Sh4m3f4yrcw40s9fk) to learn more.
</Tip>
## Add Members
The Owner and Admins can add members.
<Note>
**Prerequisites:**
* Set `CONSOLE_WEB_URL` to an address invitees can reach, not `localhost`. Every invitation link is built from it.
* Configure an email service with `MAIL_TYPE` so Dify can email invitations.
See [`CONSOLE_WEB_URL`](/en/self-host/deploy/configuration/environments#console_web_url) and [Mail Configuration](/en/self-host/deploy/configuration/environments#mail-configuration) for details.
</Note>
Select **Add**, enter one or more email addresses, choose a role, and send the invitation. An invitation link will be emailed to each address. The links also appear in the **Invitation sent** dialog, where you can copy and share directly.
Invitation links expire after 72 hours by default (configurable via `INVITE_EXPIRY_HOURS`); if someone doesn't accept in time, invite again to send a fresh link.
## Manage Members
**Change a role:** The Owner and Admins can change any member's role, and it takes effect on the member's next action, even if they're currently signed in. The Owner's role can only be changed through an ownership transfer.
**Remove a member:** The Owner and Admins can remove any member. This revokes the member's workspace access right away. The apps and knowledge bases they created stay in the workspace. The Owner can't be removed.
**Transfer ownership:** Only the Owner can transfer ownership. The transfer is confirmed with a verification code emailed to the Owner. Once verified, the chosen member becomes the new Owner and the previous Owner becomes an Admin.
<Note>
Because the verification code is sent by email, ownership transfer requires a configured email service (`MAIL_TYPE`). See [Mail Configuration](/en/self-host/deploy/configuration/environments#mail-configuration) for details.
</Note>
## Troubleshooting
| Symptom | What to check |
| :------------------------------------------------------ | :------------------------------------------------------------------------------------------------------------------------------------------------- |
| Invitees don't receive the invitation email | Email is sent only when `MAIL_TYPE` is configured. The invitation link can also be copied from the **Invitation sent** dialog and shared directly. |
| An invitation link won't open, or points to `localhost` | Every link is built from `CONSOLE_WEB_URL`. Set it to an address invitees can reach. |
| An invitation link has expired | Links last 72 hours by default. Invite the same email again to issue a new one. |
| Ownership transfer never sends a code | The code is emailed to the Owner, so `MAIL_TYPE` must be configured. |
# Dify Tools
Source: https://docs.dify.ai/en/self-host/use-dify/workspace/tools
Manage tools that enable LLMs to interact with external services and APIs
Add tools to your apps so the LLM can call external services and APIs to access real-time data or perform actions, such as web searches, database queries, or content processing.
Use tools in:
* Workflow / Chatflow apps, as standalone [Tool nodes](/en/self-host/use-dify/nodes/tools) or within [Agent nodes](/en/self-host/use-dify/nodes/agent#classic-agent)
* [Agent apps](/en/self-host/use-dify/build/new-agent/build#tools)
* [Legacy Agent apps](/en/self-host/use-dify/build/agent#extend-the-agent-with-dify-tools)
Manage all your tools from **Integrations** > **Tools**.
## Tool Types
<Tabs>
<Tab title="Tool Plugin">
Ready-to-use tools from Dify and the community for common utilities and popular services. Built-in ones like Current Time work out of the box; install more from the [Marketplace](https://marketplace.dify.ai/).
Some tool plugins, such as Google and GitHub, need authentication first. Set workspace-level credentials in **Integrations** > **Tools** > **Tool Plugin**, or in the tool's settings inside an app or node.
</Tab>
<Tab title="Swagger API">
Integrate a service that isn't available as a tool plugin by importing its OpenAPI (Swagger) specification.
Paste the schema, import it from a URL, or start from the provided example, and Dify generates the tool interface for you.
</Tab>
<Tab title="Workflow">
Turn any Workflow that starts with a User Input node into a tool, so you can reuse multi-step logic across apps. Chatflows cannot be used as tools.
<Frame>
<img alt="Workflow as Tool" />
</Frame>
</Tab>
<Tab title="MCP">
Connect an [MCP server](https://modelcontextprotocol.io/) to import its tools into Dify. An MCP server wraps external resources, such as databases, file systems, or APIs, and exposes them through a standard interface, so your apps can call them like any other tool.
<Tip>
To publish one of your own Dify apps *as* an MCP server instead, see [Publish as an MCP Server](/en/self-host/use-dify/publish/publish-mcp).
</Tip>
### Connect an MCP Server
<Info>
Only MCP servers with [HTTP transport](https://modelcontextprotocol.io/docs/learn/architecture#transport-layer) are supported.
</Info>
Add a server by providing its URL, a name, and a unique server identifier. Dify connects, authorizes if needed, and imports the server's tools so your apps can call them.
You can update the tool list later to pull the server's latest tools, though doing so can break an app if a tool it uses is removed or changed.
<Note>
* Apps reference a server by its identifier. If you change it later, the server's tools stop working in apps that used the old one; re-add the tools in each affected app to restore them.
* Exported apps reference servers by identifier too, so to run one in another workspace, recreate the same servers there with matching identifiers.
</Note>
### Authentication
**Dynamic Client Registration** (on by default) lets Dify obtain OAuth credentials from the server automatically, so you don't register an application yourself. Leave it on whenever the server supports it.
Turn it off when the server doesn't support automatic registration, or when you must use your team's existing OAuth application. Enter its **Client ID** and **Client Secret**, then register the redirect URL Dify shows.
### Advanced Options
#### Custom Headers
Send additional HTTP headers with every request to the server. Commonly used for servers that authenticate with a static token or API key (e.g., `Authorization: Bearer <token>`) rather than OAuth, but applicable whenever the server expects custom headers.
Header values can also be dynamic: `{{request.headers.X-Custom-Auth}}` is replaced at call time with the `X-Custom-Auth` header of the HTTP request that triggered the run (a Service API call, for example), letting you pass each caller's credentials through to the server.
A header the request doesn't carry resolves to an empty value; when a run has no originating HTTP request, the placeholder text is sent unchanged.
#### Timeouts
Control how long Dify waits on the server. Raise the request timeout when the server is slow to respond, and the SSE read timeout for long-running, streamed results. Change them only if you hit timeout errors.
</Tab>
</Tabs>
# Configure Annotation Reply
Source: https://docs.dify.ai/en/api-reference/annotations/configure-annotation-reply
/en/api-reference/openapi_service.json post /apps/annotation-reply/{action}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Enables or disables annotation reply for the app. Runs asynchronously; track progress with [Get Annotation Reply Job Status](/en/api-reference/annotations/get-annotation-reply-job-status).
The body is validated before the action runs, so `score_threshold`, `embedding_provider_name`, and `embedding_model_name` are required even for `disable`.
# Create Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/create-annotation
/en/api-reference/openapi_service.json post /apps/annotations
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Creates an annotation. Annotations are predefined question-answer pairs the app returns directly on a match, instead of generating a fresh response.
# Delete Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/delete-annotation
/en/api-reference/openapi_service.json delete /apps/annotations/{annotation_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Deletes an annotation and its associated hit history.
# Get Annotation Reply Job Status
Source: https://docs.dify.ai/en/api-reference/annotations/get-annotation-reply-job-status
/en/api-reference/openapi_service.json get /apps/annotation-reply/{action}/status/{job_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Returns the status of an annotation reply configuration job started by [Configure Annotation Reply](/en/api-reference/annotations/configure-annotation-reply).
# List Annotations
Source: https://docs.dify.ai/en/api-reference/annotations/list-annotations
/en/api-reference/openapi_service.json get /apps/annotations
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Lists the app's annotations, optionally filtered by keyword.
# Update Annotation
Source: https://docs.dify.ai/en/api-reference/annotations/update-annotation
/en/api-reference/openapi_service.json put /apps/annotations/{annotation_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Updates an annotation's question and answer.
# Get App Info
Source: https://docs.dify.ai/en/api-reference/applications/get-app-info
/en/api-reference/openapi_service.json get /info
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns basic information about the app: name, description, tags, mode, and author.
# Get App Meta
Source: https://docs.dify.ai/en/api-reference/applications/get-app-meta
/en/api-reference/openapi_service.json get /meta
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the display icons for the tools this app uses, keyed by tool name.
# Get App Parameters
Source: https://docs.dify.ai/en/api-reference/applications/get-app-parameters
/en/api-reference/openapi_service.json get /parameters
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the app's front-end configuration: the opening statement and suggested questions, feature toggles, the user input form, and file-upload limits. Use it to render the app's inputs and apply the correct upload limits.
# Get App WebApp Settings
Source: https://docs.dify.ai/en/api-reference/applications/get-app-webapp-settings
/en/api-reference/openapi_service.json get /site
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns the branding and display settings for the app's hosted web app, such as its title, icon, theme colors, and default language.
# Convert Audio to Text
Source: https://docs.dify.ai/en/api-reference/audio/convert-audio-to-text
/en/api-reference/openapi_service.json post /audio-to-text
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Transcribes an uploaded audio file to text using the workspace's default speech-to-text model.
# Convert Text to Audio
Source: https://docs.dify.ai/en/api-reference/audio/convert-text-to-audio
/en/api-reference/openapi_service.json post /text-to-audio
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Converts text to speech audio. Pass `text` to synthesize arbitrary text, or `message_id` to voice an existing message's answer.
# Get Next Suggested Questions
Source: https://docs.dify.ai/en/api-reference/chat-messages/get-next-suggested-questions
/en/api-reference/openapi_service.json get /messages/{message_id}/suggested
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Returns the follow-up questions suggested for a message.
# Send Chat Message
Source: https://docs.dify.ai/en/api-reference/chat-messages/send-chat-message
/en/api-reference/openapi_service.json post /chat-messages
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Sends a message to a chat app and returns the assistant's reply. The events in the streaming response vary by app type.
# Stop Chat Message Generation
Source: https://docs.dify.ai/en/api-reference/chat-messages/stop-chat-message-generation
/en/api-reference/openapi_service.json post /chat-messages/{task_id}/stop
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Stops a chat message generation task. Only supported in `streaming` mode.
# Create Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/create-child-chunk
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks
Create a child chunk under a parent chunk. Intended for documents that use the parent-child (`hierarchical_model`) chunking mode.
# Create Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/create-chunks
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments
Create one or more chunks within a document.
# Delete Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/delete-child-chunk
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks/{child_chunk_id}
Permanently delete a child chunk from its parent chunk.
# Delete Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/delete-chunk
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Permanently delete a chunk from the document.
# Get Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/get-chunk
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Retrieve the full details of a single chunk.
# List Child Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/list-child-chunks
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks
Returns a paginated list of child chunks under a specific parent chunk.
# List Chunks
Source: https://docs.dify.ai/en/api-reference/chunks/list-chunks
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/segments
Returns a paginated list of chunks within a document, optionally filtered by keyword or indexing status.
# Update Child Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/update-child-chunk
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}/child_chunks/{child_chunk_id}
Update the content of an existing child chunk.
# Update Chunk
Source: https://docs.dify.ai/en/api-reference/chunks/update-chunk
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/segments/{segment_id}
Update a chunk's fields. The update re-triggers indexing for that chunk.
# Send Completion Message
Source: https://docs.dify.ai/en/api-reference/completion-messages/send-completion-message
/en/api-reference/openapi_service.json post /completion-messages
**Available for**: Text Generator apps.
Sends a request to a text-generation app and returns the generated text.
# Stop Completion Message Generation
Source: https://docs.dify.ai/en/api-reference/completion-messages/stop-completion-message-generation
/en/api-reference/openapi_service.json post /completion-messages/{task_id}/stop
**Available for**: Text Generator apps.
Stops a completion message generation task. Only supported in `streaming` mode.
# Delete Conversation
Source: https://docs.dify.ai/en/api-reference/conversations/delete-conversation
/en/api-reference/openapi_service.json delete /conversations/{conversation_id}
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Deletes a conversation.
# List Conversation Messages
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversation-messages
/en/api-reference/openapi_service.json get /messages
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Returns a conversation's message history, newest first. Pass `first_id` to page backward into older messages.
# List Conversation Variables
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversation-variables
/en/api-reference/openapi_service.json get /conversations/{conversation_id}/variables
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Lists the variables stored in a conversation.
# List Conversations
Source: https://docs.dify.ai/en/api-reference/conversations/list-conversations
/en/api-reference/openapi_service.json get /conversations
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Lists an end user's conversations, most recently active first.
# Rename Conversation
Source: https://docs.dify.ai/en/api-reference/conversations/rename-conversation
/en/api-reference/openapi_service.json post /conversations/{conversation_id}/name
**Available for**: Chatflow, Agent, Chatbot, Legacy Agent apps.
Renames a conversation, or auto-generates a name from its messages when `auto_generate` is `true`. The name is what clients display in a multi-conversation list.
# Update Conversation Variable
Source: https://docs.dify.ai/en/api-reference/conversations/update-conversation-variable
/en/api-reference/openapi_service.json put /conversations/{conversation_id}/variables/{variable_id}
**Available for**: Chatflow, Chatbot, Legacy Agent apps.
Updates a conversation variable's value. The new value must match the variable's existing type.
# Create Document by File
Source: https://docs.dify.ai/en/api-reference/documents/create-document-by-file
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/document/create-by-file
Creates a document in a knowledge base from an uploaded file. Common formats such as PDF, TXT, and DOCX are supported. Indexing runs asynchronously; track it with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Create Document by Text
Source: https://docs.dify.ai/en/api-reference/documents/create-document-by-text
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/document/create-by-text
Creates a document in a knowledge base from raw text. Indexing runs asynchronously; track it with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Delete Document
Source: https://docs.dify.ai/en/api-reference/documents/delete-document
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/documents/{document_id}
Permanently deletes a document and all its chunks from the knowledge base.
# Download Document
Source: https://docs.dify.ai/en/api-reference/documents/download-document
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}/download
Returns a signed URL for downloading a document's original uploaded file.
# Download Documents as ZIP
Source: https://docs.dify.ai/en/api-reference/documents/download-documents-as-zip
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/download-zip
Downloads one or more documents as a single ZIP archive. Only documents that were uploaded as files can be included.
# Get Document
Source: https://docs.dify.ai/en/api-reference/documents/get-document
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{document_id}
Returns detailed information for a single document.
# Get Document Indexing Status
Source: https://docs.dify.ai/en/api-reference/documents/get-document-indexing-status
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents/{batch}/indexing-status
Returns indexing progress for every document in a batch: the current stage and chunk completion counts. Poll until each `indexing_status` reaches `completed` or `error`. Status advances through `waiting` → `parsing` → `cleaning` → `splitting` → `indexing` → `completed`.
# List Documents
Source: https://docs.dify.ai/en/api-reference/documents/list-documents
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/documents
Returns a paginated list of documents in a knowledge base.
# Update Document
Source: https://docs.dify.ai/en/api-reference/documents/update-document
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/{document_id}
Updates a document by uploading a new file, then re-indexes it. This is the canonical endpoint for file-based document updates. Track progress with the returned `batch` ID via [Get Document Indexing Status](/en/api-reference/documents/get-document-indexing-status).
# Update Document by File
Source: https://docs.dify.ai/en/api-reference/documents/update-document-by-file
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/update-by-file
Deprecated. Use [Update Document](/en/api-reference/documents/update-document) instead. Updates a document by uploading a new file, then re-indexes it.
# Update Document by Text
Source: https://docs.dify.ai/en/api-reference/documents/update-document-by-text
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/{document_id}/update-by-text
Updates a document's text content, name, or processing configuration. Re-indexes the document when its text changes.
# Update Document Status in Batch
Source: https://docs.dify.ai/en/api-reference/documents/update-document-status-in-batch
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/documents/status/{action}
Enables, disables, archives, or unarchives multiple documents in one request.
# Get End User Info
Source: https://docs.dify.ai/en/api-reference/end-users/get-end-user-info
/en/api-reference/openapi_service.json get /end-users/{end_user_id}
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Returns an end user's details by ID. Useful for resolving an end-user ID returned by another endpoint, such as `created_by` in the [Upload File](/en/api-reference/files/upload-file) response.
# List App Feedbacks
Source: https://docs.dify.ai/en/api-reference/feedback/list-app-feedbacks
/en/api-reference/openapi_service.json get /app/feedbacks
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Returns a paginated list of all feedback on the app's messages, including both end-user and admin submissions.
# Submit Message Feedback
Source: https://docs.dify.ai/en/api-reference/feedback/submit-message-feedback
/en/api-reference/openapi_service.json post /messages/{message_id}/feedbacks
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Records a `like` or `dislike` rating, plus an optional comment, on a message. Submitting `null` for `rating` revokes the message's existing feedback.
# Download File
Source: https://docs.dify.ai/en/api-reference/files/download-file
/en/api-reference/openapi_service.json get /files/{file_id}/preview
**Available for**: Chatflow, Chatbot, Legacy Agent, Text Generator apps.
Returns the raw bytes of a file previously returned by [Upload File](/en/api-reference/files/upload-file). A file is reachable only through the app whose messages reference it.
# Upload File
Source: https://docs.dify.ai/en/api-reference/files/upload-file
/en/api-reference/openapi_service.json post /files/upload
**Available for**: Chatflow, Workflow, Agent, Chatbot, Legacy Agent, Text Generator apps.
Uploads a file and returns its `id` for later requests to reference. The file belongs to the uploading end user: only requests carrying the same `user` can reference it.
Which file types an app actually consumes depends on its file-upload settings; read them from [Get App Parameters](/en/api-reference/applications/get-app-parameters).
# Handle Errors and Rate Limits
Source: https://docs.dify.ai/en/api-reference/guides/errors
The error envelope, what each status class means, and which failures are worth retrying
Every documented error uses the same three-field JSON envelope:
```json theme={null}
{
"code": "invalid_param",
"message": "user is required",
"status": 400
}
```
`status` mirrors the HTTP status; `code` is the stable identifier to branch on; `message` is human-readable detail. Each endpoint page lists exactly which codes it can raise.
## Status Classes at a Glance
| Status | Meaning | Typical codes |
| :-------- | :---------------------------------------------------------------- | :------------------------------------------------------------------------- |
| 400 | The request or the app's configuration is invalid | `invalid_param`, `bad_request`, `app_unavailable`, provider errors (below) |
| 401 | Missing or invalid API key | `unauthorized` |
| 403 | The key can't act here: access restrictions or plan limits | `forbidden` |
| 404 | The resource doesn't exist or isn't visible to this key or `user` | `not_found` |
| 413 / 415 | A file is too large or of an unsupported type | `file_too_large`, `unsupported_file_type` |
| 429 | Too many requests right now, or a quota is exhausted | `too_many_requests`, `rate_limit_error` |
| 500 | Something failed on Dify's side | `internal_server_error` |
## Provider Errors Are Configuration Errors
Four common 400 codes point at the app's model setup rather than your request:
* `provider_not_initialize`: no valid model credentials
* `provider_quota_exceeded`: the model provider's own quota ran out
* `model_currently_not_support`: the model isn't currently supported
* `completion_request_error`: an error occurred while making a completion request
For these errors, retrying won't help. Fix the app's model configuration in Dify.
## Rate Limits and Quotas
The two 429 codes mean different things:
* `too_many_requests` is a concurrency ceiling—too many simultaneous requests for the app right now. Back off and retry.
* `rate_limit_error` is a plan quota on Dify Cloud, such as workflow executions. Retrying won't clear it; it resets with the quota period or a plan change.
On Dify Cloud, knowledge write endpoints also enforce plan limits as `403` responses. These carry the same `forbidden` code as access restrictions—the `message` is what tells you it's a plan limit, so don't build a switch on `code` alone for 403s.
## Errors Inside Streams
Once a stream opens, the HTTP status is already `200`: failures arrive as an `error` event and end the stream. The event's `code` values are the same ones documented here—classify them with the same rules. See [Consume Streaming Responses](/en/api-reference/guides/streaming) for details.
## What to Retry
* **Retry with backoff**: `too_many_requests`, `500`, and network failures.
* **Don't retry as-is**: validation errors (fix the request first), authorization failures, or quota errors (they won't clear until the quota does).
* **Fix, don't retry**: a `404` from a resume call means the wrong `user` or a run that doesn't exist. Correct the identifier instead.
# Get Human Input Form
Source: https://docs.dify.ai/en/api-reference/human-input/get-human-input-form
/en/api-reference/openapi_service.json get /form/human_input/{form_token}
**Available for**: Chatflow, Workflow apps.
Returns the contents of a paused Human Input form. Requires web app delivery.
For the full sequence of Human Input calls, see [Human Input Flow](/en/api-reference/guides/human-input-flow).
# Submit Human Input Form
Source: https://docs.dify.ai/en/api-reference/human-input/submit-human-input-form
/en/api-reference/openapi_service.json post /form/human_input/{form_token}
**Available for**: Chatflow, Workflow apps.
Submits the recipient's response to a paused Human Input form. On acceptance the workflow resumes; follow the resumed run via [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events). Requires web app delivery.
# Create an Empty Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/create-an-empty-knowledge-base
/en/api-reference/openapi_service.json post /datasets
Creates an empty knowledge base. Add documents to it with [Create Document by Text](/en/api-reference/documents/create-document-by-text) or [Create Document by File](/en/api-reference/documents/create-document-by-file).
# Delete Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/delete-knowledge-base
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}
Permanently deletes a knowledge base and all of its documents.
# Get Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/get-knowledge-base
/en/api-reference/openapi_service.json get /datasets/{dataset_id}
Returns detailed information about a knowledge base, including its embedding model, retrieval configuration, and document statistics.
# List Knowledge Bases
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/list-knowledge-bases
/en/api-reference/openapi_service.json get /datasets
Returns a paginated list of knowledge bases, optionally filtered by keyword or tags.
# Retrieve Chunks from a Knowledge Base / Test Retrieval
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/retrieve-chunks-from-a-knowledge-base-test-retrieval
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/retrieve
Searches a knowledge base and returns the chunks most relevant to the query, for both production retrieval and test retrieval.
# Update Knowledge Base
Source: https://docs.dify.ai/en/api-reference/knowledge-bases/update-knowledge-base
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}
Updates a knowledge base. Only the fields included in the request body are changed.
# List Datasource Plugins
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/list-datasource-plugins
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/pipeline/datasource-plugins
Returns the datasource nodes configured in the knowledge pipeline, each with the plugin it uses and the metadata needed to run it.
# Run Datasource Node
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/run-datasource-node
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/pipeline/datasource/nodes/{node_id}/run
Runs a single datasource node in the knowledge pipeline and streams its execution events.
# Run Pipeline
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/run-pipeline
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/pipeline/run
Runs the full knowledge pipeline over one or more datasources. `response_mode` selects a streaming or blocking response.
# Upload Pipeline File
Source: https://docs.dify.ai/en/api-reference/knowledge-pipeline/upload-pipeline-file
/en/api-reference/openapi_service.json post /datasets/pipeline/file-upload
Uploads a file for use in a knowledge pipeline. Use the returned `id` as the `reference` of a `local_file` item in [Run Pipeline](/en/api-reference/knowledge-pipeline/run-pipeline).
# Create Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/create-metadata-field
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/metadata
Create a custom metadata field for annotating documents in the knowledge base with structured information.
# Delete Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/delete-metadata-field
/en/api-reference/openapi_service.json delete /datasets/{dataset_id}/metadata/{metadata_id}
Permanently delete a custom metadata field. Documents that used the field lose their values for it.
# Get Built-in Metadata Fields
Source: https://docs.dify.ai/en/api-reference/metadata/get-built-in-metadata-fields
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/metadata/built-in
Returns the built-in metadata fields provided by the system.
# List Metadata Fields
Source: https://docs.dify.ai/en/api-reference/metadata/list-metadata-fields
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/metadata
Returns all metadata fields for the knowledge base, both custom and built-in, with the count of documents using each field.
# Update Built-in Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/update-built-in-metadata-field
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/metadata/built-in/{action}
Enable or disable built-in metadata fields for the knowledge base.
# Update Document Metadata in Batch
Source: https://docs.dify.ai/en/api-reference/metadata/update-document-metadata-in-batch
/en/api-reference/openapi_service.json post /datasets/{dataset_id}/documents/metadata
Update metadata values for multiple documents in a single request.
# Update Metadata Field
Source: https://docs.dify.ai/en/api-reference/metadata/update-metadata-field
/en/api-reference/openapi_service.json patch /datasets/{dataset_id}/metadata/{metadata_id}
Rename a custom metadata field.
# Get Available Models
Source: https://docs.dify.ai/en/api-reference/models/get-available-models
/en/api-reference/openapi_service.json get /workspaces/current/models/model-types/{model_type}
Returns the available models of a given type. Use it to find the `text-embedding` and `rerank` models to configure on a knowledge base.
# Create Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/create-knowledge-tag
/en/api-reference/openapi_service.json post /datasets/tags
Create a tag for organizing knowledge bases.
# Create Tag Binding
Source: https://docs.dify.ai/en/api-reference/tags/create-tag-binding
/en/api-reference/openapi_service.json post /datasets/tags/binding
Bind one or more tags to a knowledge base. A knowledge base can have multiple tags.
# Delete Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/delete-knowledge-tag
/en/api-reference/openapi_service.json delete /datasets/tags
Permanently delete a knowledge base tag. Does not delete the knowledge bases that were tagged.
# Delete Tag Binding
Source: https://docs.dify.ai/en/api-reference/tags/delete-tag-binding
/en/api-reference/openapi_service.json post /datasets/tags/unbinding
Remove one or more tags from a knowledge base.
# Get Knowledge Base Tags
Source: https://docs.dify.ai/en/api-reference/tags/get-knowledge-base-tags
/en/api-reference/openapi_service.json get /datasets/{dataset_id}/tags
Returns the tags bound to a knowledge base.
# List Knowledge Tags
Source: https://docs.dify.ai/en/api-reference/tags/list-knowledge-tags
/en/api-reference/openapi_service.json get /datasets/tags
Returns all knowledge base tags in the workspace.
# Update Knowledge Tag
Source: https://docs.dify.ai/en/api-reference/tags/update-knowledge-tag
/en/api-reference/openapi_service.json patch /datasets/tags
Rename a knowledge base tag.
# Get Workflow Run Detail
Source: https://docs.dify.ai/en/api-reference/workflow-runs/get-workflow-run-detail
/en/api-reference/openapi_service.json get /workflows/run/{workflow_run_id}
**Available for**: Chatflow, Workflow apps.
Get a single workflow run's status, inputs, outputs, and execution metrics.
# List Workflow Logs
Source: https://docs.dify.ai/en/api-reference/workflow-runs/list-workflow-logs
/en/api-reference/openapi_service.json get /workflows/logs
**Available for**: Chatflow, Workflow apps.
List past workflow runs with optional filters. Each entry is a run-level summary (status, token usage, step count, and timing), not a node-by-node execution log.
To follow a run's node-level events, stream it instead:
- **A run you start**: use [Run Workflow](/en/api-reference/workflow-runs/run-workflow) in streaming mode, which emits `node_started` and `node_finished` as the run executes.
- **A run already in progress**: call [Stream Workflow Events](/en/api-reference/workflow-runs/stream-workflow-events) with `include_state_snapshot=true` to replay each executed node's status, then stream the rest.
A finished run's node-level logs aren't available through the Service API.
# Run Workflow
Source: https://docs.dify.ai/en/api-reference/workflow-runs/run-workflow
/en/api-reference/openapi_service.json post /workflows/run
**Available for**: Workflow apps.
Run the app's published workflow and return its outputs, either in a single `blocking` response or as a `streaming` Server-Sent Events feed. Requires a published workflow.
# Run Workflow by ID
Source: https://docs.dify.ai/en/api-reference/workflow-runs/run-workflow-by-id
/en/api-reference/openapi_service.json post /workflows/{workflow_id}/run
**Available for**: Workflow apps.
Run a specific published workflow version, identified by the `workflow_id` in the path. Request body, response, and streaming behavior match [Run Workflow](/en/api-reference/workflow-runs/run-workflow); only the executed version differs.
# Stop Workflow Task
Source: https://docs.dify.ai/en/api-reference/workflow-runs/stop-workflow-task
/en/api-reference/openapi_service.json post /workflows/tasks/{task_id}/stop
**Available for**: Workflow apps.
Stop a running workflow task. Only supported in `streaming` mode.
# Stream Workflow Events
Source: https://docs.dify.ai/en/api-reference/workflow-runs/stream-workflow-events
/en/api-reference/openapi_service.json get /workflow/{workflow_run_id}/events
**Available for**: Chatflow, Workflow apps.
Resume the [Server-Sent Events stream](/en/api-reference/guides/streaming) for a workflow run after a pause or a dropped SSE connection. For runs that have already finished, the stream emits a single `workflow_finished` event and closes.
To check an in-progress run's node-level status and progress, call it with `include_state_snapshot=true`: the stream replays each already-executed node's status before streaming new events.
# Authenticate
Source: https://docs.dify.ai/en/cli/authenticate
Sign in to your Dify host from the CLI, see where your token is stored, and manage your session
You sign in through your browser, using the OAuth 2.0 device flow; `difyctl` never sees your password.
## Sign In
<Note>
On a self-hosted deployment, set both `OPENAPI_ENABLED` and `ENABLE_OAUTH_BEARER` to `true` before you sign in. See [Dify CLI and Programmatic API](/en/self-host/deploy/configuration/environments#dify-cli-and-programmatic-api) for the full variable reference.
</Note>
<Steps>
<Step title="Run the login command">
Pass your Dify host's URL. For Dify Cloud, use `https://cloud.dify.ai`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
`difyctl` prints a one-time code, opens the verification URL in your default browser, and waits:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
<Tip>
To skip the auto-open, pass `--no-browser`.
</Tip>
If no browser opens (normal over SSH and in headless sessions), open the URL yourself on any device.
</Step>
<Step title="Approve the sign-in in your browser">
In the browser tab that opens, sign in with your Dify credentials and enter the one-time code.
The code expires after 15 minutes. If it expired, re-run `difyctl auth login` to get a fresh one.
</Step>
<Step title="Confirm the session">
Back in the terminal:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
The second line is your workspace.
</Step>
</Steps>
## Sign In Again
If a command fails with `auth_expired` (exit code 4), the server has expired or revoked your session.
Run `difyctl auth login` again. You don't need to sign out first, and the new sign-in refreshes your stored token.
## Check Who You're Signed In As
```bash theme={null}
difyctl auth whoami
```
```text theme={null}
<your-email> (<your-name>)
```
To read the identity from a script, add `--json`:
```bash theme={null}
difyctl auth whoami --json
```
You'll get the same fields as a JSON object, plus your account ID:
```json theme={null}
{"id":"3c90c3cc-0d44-4b50-8888-8dd25736052a","email":"<your-email>","name":"<your-name>"}
```
## Sign Out
```bash theme={null}
difyctl auth logout
```
```text theme={null}
✓ Logged out of cloud.dify.ai
```
This revokes the session on the server and deletes the token and session entry from your machine. If the server-side revocation fails, your local credentials are cleared anyway.
## Where Your Token Lives
Signing in stores an OAuth bearer token, recognizable by its `dfoa_` prefix. It represents you: whatever your account can do in your workspace, the token can do from the CLI.
`difyctl` keeps the token in your operating system's credential store when one is available: Keychain on macOS, Credential Manager on Windows, Secret Service on Linux. If no credential store responds, it falls back to a `tokens.yml` file with `0600` permissions in the `difyctl` config directory.
`difyctl` picks the store once when you sign in, and the session uses it from then on. Session metadata (hosts, accounts, workspaces) lives alongside the token in `hosts.yml`.
The config directory is `~/.config/difyctl` on macOS and Linux (Linux honors `XDG_CONFIG_HOME`) and `%APPDATA%\difyctl` on Windows. Set [`DIFY_CONFIG_DIR`](/en/cli/reference/environment-variables) to override it.
## Troubleshooting
| Problem | What to do |
| :---------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| The browser never opens | Copy the URL from the terminal and open it on any device. |
| The host is rejected | Only `https://` hosts are accepted; a host without a scheme defaults to `https://`. For a plain `http://` host, or an `https://` host with a self-signed or invalid TLS certificate (local development only), add `--insecure`. |
| A later command fails with `auth_expired` | Your session expired or was revoked. [Sign in again](#sign-in-again). |
For everything else, see the full [Troubleshooting](/en/cli/troubleshooting) page.
# Common Tasks
Source: https://docs.dify.ai/en/cli/common-tasks
Copy-paste commands for the difyctl tasks you'll run most often
All commands below assume you're [signed in](/en/cli/authenticate).
## Send a Message
Send a message to a Chatbot, Chatflow, Agent, or Text Generator app by passing it as a positional argument to [`difyctl run app`](/en/cli/reference/apps#run-an-app). The reply prints to stdout.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
# save just the reply to a file; hints and errors go to stderr, not stdout
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "Summarize this week's tickets" > reply.txt
```
## Run a Workflow
Pass the inputs as a single JSON object with [`--inputs`](/en/cli/reference/apps#run-an-app) instead of a positional message. The outputs print to stdout as JSON.
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report"}'
# read large input sets from a file instead
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs-file inputs.json
```
## Find Your Apps
List the apps in your workspace with [`difyctl get app`](/en/cli/reference/apps#list-your-apps). Narrow the list with `--name` or `--mode`.
```bash theme={null}
difyctl get app
# filter by name substring or mode
difyctl get app --name report --mode workflow
# list apps from every workspace you belong to
difyctl get app -A
```
## Stream a Long Response
Add [`--stream`](/en/cli/reference/apps#run-an-app) to print the response as it's generated instead of all at once at the end.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "Draft a launch announcement" --stream
```
## Continue a Conversation
Copy the conversation ID from the hint that follows each Chatbot or Chatflow reply, then pass it back with [`--conversation`](/en/cli/reference/apps#run-an-app) to continue the same conversation.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
# hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "And on weekends?" --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
## Get JSON Output for Scripts
Add [`-o json`](/en/cli/reference/output-formats-and-exit-codes) to any command to get the raw response as pipe-friendly JSON.
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?" -o json | jq -r '.answer'
# extract fields from list output the same way
difyctl get app -o json | jq -r '.data[].id'
# get just the IDs, one per line, no jq needed
difyctl get app -o name
```
## Switch Your Workspace <Badge>Cloud</Badge>
Change your active workspace with [`difyctl use workspace`](/en/cli/reference/workspaces#switch-your-workspace-cloud). List available workspaces with `get workspace`.
```bash theme={null}
difyctl get workspace
difyctl use workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
# ✓ Switched to Marketing (9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c)
# one-off: run a single command against another workspace without switching
difyctl get app --workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
## Inspect an App's Inputs
Before running an unfamiliar app, check its app type and input schema with [`difyctl describe app`](/en/cli/reference/apps#inspect-an-app): names, types, and which inputs are required.
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
# get the schema as JSON to build --inputs programmatically
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b -o json
```
# Install difyctl
Source: https://docs.dify.ai/en/cli/install
Install difyctl with a one-line script or a manual binary download
`difyctl` is a standalone binary with no runtime dependencies. The install script detects your platform, downloads the matching build from Dify's GitHub Releases, verifies its checksum, and puts the binary in place.
<Note>
`difyctl` was introduced with Dify 1.15.0. Each build targets a specific Dify version, so install the one that matches your server (see `DIFY_VERSION` below).
</Note>
## Install
<Steps>
<Step title="Run the Installer">
`difyctl` ships a build with each Dify release, and the installer fetches the latest by default.
<Tabs>
<Tab title="macOS / Linux">
Supported platforms: macOS and Linux, x64 and arm64.
```bash theme={null}
curl -fsSL https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install-cli.sh | sh
```
The script installs to `~/.local/bin/difyctl` and tells you if that directory isn't on your `PATH`.
</Tab>
<Tab title="Windows">
Supported platform: x64.
```powershell theme={null}
irm https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install.ps1 | iex
```
The script installs to `%LOCALAPPDATA%\difyctl\bin\difyctl.exe` and prints the command to add that directory to your `PATH` if it isn't already there.
</Tab>
<Tab title="Manual Download">
1. From [Dify's GitHub Releases](https://github.com/langgenius/dify/releases), pick the release that matches your server's Dify version and download two assets:
* The binary for your platform (`difyctl-v<version>-<os>-<arch>`)
* The checksum manifest (`difyctl-v<version>-checksums.txt`)
2. Compute the binary's SHA-256 hash and compare it with the matching entry in the checksums file.
If the values differ, the download is corrupted or was tampered with; delete it and download again.
<CodeGroup>
```bash macOS / Linux theme={null}
shasum -a 256 difyctl-v<version>-<os>-<arch>
```
```powershell Windows theme={null}
Get-FileHash difyctl-v<version>-windows-x64.exe
```
</CodeGroup>
3. Put the binary on your `PATH`:
<CodeGroup>
```bash macOS / Linux theme={null}
chmod +x difyctl-v<version>-<os>-<arch>
mv difyctl-v<version>-<os>-<arch> ~/.local/bin/difyctl
```
```powershell Windows theme={null}
New-Item -ItemType Directory -Force "$env:LOCALAPPDATA\difyctl\bin" | Out-Null
Move-Item difyctl-v<version>-windows-x64.exe "$env:LOCALAPPDATA\difyctl\bin\difyctl.exe"
```
</CodeGroup>
</Tab>
</Tabs>
<Tip>
To customize the install, set any of these environment variables on the install command.
| Variable | Description | Example |
| ----------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------- |
| `DIFY_VERSION` | The Dify release tag to install `difyctl` from, matching a tag on [Dify's Releases](https://github.com/langgenius/dify/releases).<br /><br />Defaults to the latest release; set it to your server's release tag when your server isn't on the latest. | `1.16.1` |
| `DIFYCTL_VERSION` | Pin a specific `difyctl` build. Used only when `DIFY_VERSION` is unset. | `0.2.0-alpha` |
| `DIFYCTL_PREFIX` | The install directory (default `~/.local`). The binary lands in `<prefix>/bin`. | `/usr/local` |
For example:
<CodeGroup>
```bash macOS / Linux theme={null}
curl -fsSL https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install-cli.sh | DIFY_VERSION=1.16.1 sh
```
```powershell Windows theme={null}
# PowerShell has no inline form; this applies for the rest of your session
$env:DIFY_VERSION = "1.16.1"
irm https://raw.githubusercontent.com/langgenius/dify/main/cli/scripts/install.ps1 | iex
```
</CodeGroup>
</Tip>
</Step>
<Step title="Verify the Install">
```bash theme={null}
difyctl version
```
You should see a `Client:` block with the version and platform.
If you get `command not found` instead, the install directory isn't on your `PATH`. Add it:
<CodeGroup>
```bash macOS / Linux theme={null}
# add to ~/.zshrc or ~/.bashrc; running it inline only lasts until the session ends
export PATH="$HOME/.local/bin:$PATH"
```
```powershell Windows theme={null}
[Environment]::SetEnvironmentVariable('PATH', "$env:LOCALAPPDATA\difyctl\bin;$env:PATH", 'User')
```
</CodeGroup>
</Step>
</Steps>
## Update
To update `difyctl`, re-run the install script; it replaces the binary in place. To move to a specific Dify version, set `DIFY_VERSION` as above.
## Uninstall
<CodeGroup>
```bash macOS / Linux theme={null}
rm ~/.local/bin/difyctl
```
```powershell Windows theme={null}
Remove-Item -Recurse "$env:LOCALAPPDATA\difyctl"
```
</CodeGroup>
To sign out before uninstalling, run [`difyctl auth logout`](/en/cli/reference/auth-and-contexts#sign-out).
## Next Steps
With `difyctl` installed, head to the [Quick Start](/en/cli/quick-start) to sign in and run your first app.
# Authenticate Where Your Agent Runs
Source: https://docs.dify.ai/en/cli/integrate-agents/auth-for-agent-deployments
Put a difyctl session on the server or container where your agent runs, so it can call Dify apps unattended
Your agent never logs in. It reuses the `difyctl` session on the machine where it runs. How you get it there depends on the machine:
* **Your own machine**: [sign in](/en/cli/authenticate) and you're set.
* **A server or VM you can log into**: sign in on it (Option 1).
* **A container, CI runner, or prebaked image**: copy a session in (Option 2).
## Option 1: Sign In on the Machine
Sign in on the target machine as the account the agent should act as. The agent inherits everything that account can reach.
For Dify Cloud, use `https://cloud.dify.ai` for `--host`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url). Pass `--no-browser` when the machine has no browser:
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai --no-browser
```
`difyctl` prints a one-time code and a verification URL. Open the URL on any device, sign in, and enter the code. The session is written to the machine the moment you approve. For the full walkthrough, see [Authenticate](/en/cli/authenticate#sign-in).
Confirm it landed:
```bash theme={null}
difyctl auth whoami
```
```text theme={null}
<your-email> (<your-name>)
```
## Option 2: Copy a Session You Already Have
Use this when you can't sign in on the target itself, like a prebaked image or an ephemeral container.
<Steps>
<Step title="Sign in on a machine without an OS keychain">
Use a headless Linux server or a container. Without a keychain, `difyctl` saves the token to `tokens.yml` in the [config directory](/en/cli/authenticate#where-your-token-lives), making the entire directory portable.
Before copying, confirm `tokens.yml` exists in the config directory (`~/.config/difyctl` by default). If it's missing, a keychain captured the token instead, and there's no supported way to export it. Sign in directly on the target with [Option 1](#option-1-sign-in-on-the-machine).
</Step>
<Step title="Copy the config directory to the target">
After copying, point `difyctl` at it with [`DIFY_CONFIG_DIR`](/en/cli/reference/environment-variables). For a container, mount the directory at runtime instead of baking it into the image:
```bash theme={null}
docker run \
-v /path/to/difyctl-config:/config:ro \
-e DIFY_CONFIG_DIR=/config \
your-agent-image
```
`tokens.yml` is a live credential. Keep its `0600` permissions and keep it out of images and version control. The mount is read-only because an agent that only runs apps never writes to the config directory.
</Step>
</Steps>
## When the Session Expires
A server-expired or revoked session surfaces as exit code 4 with `error.code` `auth_expired`. The agent can't recover on its own: a new session takes a person approving the sign-in, the same one-time-code step as Option 1.
So it should stop and surface the failure for a human to [sign in again](/en/cli/authenticate#sign-in-again), not retry. See [Handle Errors and Retries](/en/cli/integrate-agents/error-handling-and-retries-for-agents#branch-on-the-exit-code) for how to branch on it.
To revoke a session you suspect is compromised, run [`auth devices revoke`](/en/cli/reference/auth-and-contexts#revoke-sessions) from any signed-in machine.
# Handle Errors and Retries
Source: https://docs.dify.ai/en/cli/integrate-agents/error-handling-and-retries-for-agents
Make your agent fail safely on difyctl errors: branch on exit codes, parse the error, detect paused workflows, and retry only what's safe
Your agent needs four pieces of failure logic to drive `difyctl` safely: read the right channel, branch on the exit code, treat a paused workflow as success, and retry only what's safe to retry.
## Read the Right Channel
Run every programmatic invocation with `-o json`. The channel discipline is strict and you can build on it:
* **Success**: the payload is on stdout as parseable JSON with no ANSI codes, and stderr is empty.
* **Failure**: stdout is empty, and stderr is a structured JSON object. The entire trimmed stderr parses as JSON.
* **Paused**: a Workflow that stops for human input also exits `0` on the success channel, with `"status": "paused"` on stdout. [Treat it as success](#a-pause-is-success-not-an-error), not failure.
So the parse rule is: exit code first, then `JSON.parse(stdout)` on success and `JSON.parse(stderr)` on failure. See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes#errors) for the error object's fields and a full sample.
## Branch on the Exit Code
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes#exit-codes) for the full exit-code table. For an agent, the branches that matter:
* **Exit `7`—rate limited**: The server returned a 429. Back off and retry.
* **Exit `4`—auth**: No session, or the session expired. Re-establish the session before doing anything else. Don't retry the same command as-is, which just burns calls. See [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments).
* **Exit `1`—generic or server error**: Network failure, server error, app not found, or an unknown flag or command. Parse the error object and inspect `error.code`. Don't blindly retry.
* **Exit `2`—invalid input**: The CLI rejected a value before any request went out: malformed `--inputs` JSON, a non-UUID app ID, or an out-of-range flag such as `--limit 0`. Fix the call; retrying it unchanged fails the same way.
* **A paused run is exit `0`**: A workflow that hit a human-input step exits `0` with `"status": "paused"` on stdout, not an error. It's [handled separately](#a-pause-is-success-not-an-error).
## A Pause Is Success, Not an Error
A Workflow or Chatflow app with a human-input step pauses mid-run. The command exits `0` and reports the pause on stdout. There is nothing on stderr to catch. An agent that only checks exit codes will mistake the pause for a completed run, so the completion check must read the payload:
```python theme={null}
import json, subprocess
r = subprocess.run(
["difyctl", "run", "app", app_id, "--inputs", json.dumps(inputs), "-o", "json"],
capture_output=True, text=True,
)
if r.returncode == 0:
payload = json.loads(r.stdout)
if payload.get("status") == "paused":
# Success-with-pending: collect input, then resume with
# payload["form_token"] and payload["workflow_run_id"].
...
```
See [When a Workflow Pauses](/en/cli/reference/apps#when-a-workflow-pauses) for the full paused payload, the resume command, and the expiry rules. A resumed run can pause again at a later step, so run the same check after every `resume app`.
## Branch on `error.code`
The error object's `error.code` is a stable machine identifier: the same failure produces the same code across calls, so you write the branching logic once. Group your branches by recovery action rather than enumerating every code:
* **Re-authenticate, then retry**: `not_logged_in`, `auth_expired`. Both exit 4.
* **Retry with backoff**: `network_connection`, `server_5xx`. Transient infrastructure trouble.
* **Don't retry, inspect**: `server_4xx_other`. The server rejected the request: wrong app ID, bad inputs, or insufficient permissions. The `message` carries the server's reason.
* **Fix the invocation**: the usage codes that arrive with exit 2.
The error object also carries a human-readable `hint` with a suggested recovery action. Log it to speed up debugging.
When the failure came from the server, the error object may also include `error.server`, the server's own error body. Its `server.code` (for example `not_found`) distinguishes rejection reasons more finely than `server_4xx_other` if your loop needs that granularity.
## Retry Deliberately
`difyctl` already retries idempotent requests (GET, PUT, DELETE) on transient failures with exponential backoff. See [Global Flags](/en/cli/reference/global-flags#http-retries) for the budget and the `--http-retry` override.
What it never retries automatically is POST, and that's the call that matters: every `run app` is a POST. When `run app` fails mid-flight, the CLI doesn't know whether the server already started executing, so by default it won't re-send.
The one opt-in is [`run app --retry-on-limit`](/en/cli/reference/apps#run-an-app), which retries specifically on a 429 with bounded backoff. It stays off by default because an app run isn't idempotent.
The same applies to your agent's logic: re-running a failed `run app` is a new execution, not a resume of the old one. For a Chatbot, that's usually acceptable (re-ask the question). For a Workflow with side effects, gate the retry on what the workflow does.
Keep agent-side retries for the transient errors above, cap the attempts, and log every retry decision. An agent that silently re-runs writes is the failure mode the [`effect` labels](/en/cli/reference/help#machine-readable-help) exist to prevent. Every command in `difyctl help -o json` is tagged `read`, `write`, or `destructive`, so your loop can gate auto-retry on the tag and never re-send a `write` blindly.
# Install the difyctl Skill
Source: https://docs.dify.ai/en/cli/integrate-agents/install-the-difyctl-skill
Give your coding agent access to your Dify apps by installing one skill file
Run [`difyctl skills install`](/en/cli/reference/skills#install-the-skill) to write a skill file for the coding agents on your machine. The agent picks it up and onboards itself from there.
The installed `SKILL.md` is a bootstrap, not a manual. It tells the agent the one thing that matters: run [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help) and treat that output as the source of truth.
At runtime, the agent reads the full command surface from the installed `difyctl`.
## When to Use the Skill
* Your agent runtime reads skills: Claude Code, Codex, OpenCode, Cursor, pi, or anything else that picks up `SKILL.md` files from a skill directory.
* The agent can run shell commands. The skill drives `difyctl` through the agent's shell tool.
* You want zero maintenance: the skill never goes stale, because it lists no commands.
If your runtime doesn't read skills, your agent can still drive `difyctl` directly by reading [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help) at runtime.
## Prerequisites
* [Install](/en/cli/install) `difyctl` and [sign in](/en/cli/authenticate) on the machine the agent runs on, so it can reuse your session. For a server or container, see [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments).
* Use a coding agent that reads skills and can run shell commands. A sandboxed agent with no shell access can't use the skill.
* Launch the agent at least once before installing, so its config directory exists for `difyctl skills install` to find.
## Steps
<Steps>
<Step title="Preview where the skill will land">
Without `--yes`, the command is a dry run:
```bash theme={null}
difyctl skills install
```
```text theme={null}
Detected 1 agent: claude-code
would write to claude-code: /Users/you/.claude/skills/difyctl/SKILL.md
Re-run with --yes to write.
Agent not listed? Install into its directory with `difyctl skills install <dir>`.
```
</Step>
<Step title="Write the skill">
`--yes` writes to every detected agent. Pass `--agent <name>` to write to just one.
```bash theme={null}
difyctl skills install --yes
```
```text theme={null}
wrote /Users/you/.claude/skills/difyctl/SKILL.md
```
</Step>
<Step title="Start a fresh agent session">
Start a new session so the agent indexes the skill it just received.
</Step>
</Steps>
<Info>
See the [Skills reference page](/en/cli/reference/skills) for detection, target paths per agent, and the `--agent`, `--stdout`, and explicit-directory forms.
</Info>
## Test
The install prints the path it wrote; open that file to confirm the skill is there. Then check that the agent actually uses it:
1. **Discovery**: In a fresh session, ask the agent: *"What can you do with `difyctl`?"* A correctly onboarded agent runs `difyctl help -o json` and answers from its output rather than guessing commands.
2. **End to end**: Ask the agent to list your Dify apps and run one. Watch for `difyctl get app -o json` followed by a `describe`/`run` sequence with real IDs from the list.
3. **Pause handling**: If you have a Workflow or Chatflow app with a human-input step, ask the agent to run it. A paused run [exits 0 and reports `"status": "paused"` on stdout](/en/cli/reference/apps#when-a-workflow-pauses). The agent should recognize the pause and offer to resume, not report a failure or retry the run.
## Troubleshooting
| Problem | What to do |
| :---------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| The agent isn't detected | Its config directory (for example `~/.claude`) doesn't exist until the agent has run at least once. Launch it once, or target the directory explicitly with `difyctl skills install <dir> --yes`. |
| The skill is installed but the agent ignores it | Most agents index skills at session start, so start a new session. If it still doesn't load, point the installer at the directory your agent reads skills from. |
| Commands fail with exit code 4 | The agent has no session to reuse. Sign in on its machine first: see [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments). |
| The skill is older than the CLI | The skill carries a version stamp and tells the agent to compare it against `difyctl version`. If they differ, re-run `difyctl skills install --yes` to overwrite it. |
For everything else, see the full [Troubleshooting](/en/cli/troubleshooting) page.
# Integrate Your Agents with Dify Apps
Source: https://docs.dify.ai/en/cli/integrate-agents/overview
Call your Dify apps from any coding agent through difyctl, with no API to integrate or SDK to install
Your agent can call your Dify apps as tools. It runs `difyctl` as an ordinary subprocess and reads the JSON it prints back. `difyctl` describes itself, so the agent discovers your apps, runs them, and reads the results on its own.
## What the Agent Does on Its Own
The agent drives a four-step loop, with no glue code from you:
1. **Discover** the apps in your workspace.
2. **Inspect** one to learn the inputs it expects.
3. **Run** it with those inputs.
4. **Parse** the JSON result.
The agent doesn't work from a hard-coded command list. `difyctl` describes itself through [`difyctl help -o json`](/en/cli/reference/help#machine-readable-help), and the agent reads that at runtime, so it always tracks the current CLI.
## Before You Start: Sign In Where the Agent Runs
The agent doesn't log in. It runs `difyctl` and reuses whatever session exists on the machine where it runs, so get a session onto that machine first:
* **On your own machine**: a one-time browser [sign-in](/en/cli/authenticate).
* **On a server or in a container**: sign in on the machine, or copy a session onto it. See [Authenticate Where Your Agent Runs](/en/cli/integrate-agents/auth-for-agent-deployments) for details.
## Onboard Your Agent
The agent learns `difyctl` from `difyctl help -o json`. Pointing it there is the only setup, and how depends on the agent:
* **Reads skills** (Claude Code, Codex, and similar): [install the `difyctl` skill](/en/cli/integrate-agents/install-the-difyctl-skill). One command writes a small file that points the agent at `difyctl help -o json`, and it onboards itself from there. No integration code.
* **Doesn't read skills**: point it there yourself. Add a line to the agent's system prompt or instructions, such as "to work with Dify, run `difyctl help -o json` and use the commands it lists." That's the hand-off the skill otherwise does for you.
# Overview
Source: https://docs.dify.ai/en/cli/overview
Run your Dify apps from terminals, scripts, CI pipelines, and AI agents with the official Dify command-line interface `difyctl`
You build Dify apps in the browser, but the work that needs them often lives somewhere else: a shell script, a CI pipeline, an AI agent deciding which tool to call.
Dify CLI (difyctl) closes that gap: anything that can run a shell command can run your Dify apps.
## What You Can Do
* Run any Dify app from your terminal and capture its output.
* List the apps in your workspace and inspect the inputs each one expects.
* Stream long responses live, or get structured JSON for scripting.
* Sign in once with OAuth, then automate without storing passwords or API keys in scripts.
* Let your AI agents discover and call your Dify apps as tools.
## Get Started
First, [install `difyctl`](/en/cli/install). Then follow the [Quick Start](/en/cli/quick-start) to sign in and run your first app.
<Tip>
Want an AI agent to run your Dify apps as tools? Once `difyctl` is installed, start with [Integrate Your Agents with Dify](/en/cli/integrate-agents/overview).
</Tip>
# Quick Start
Source: https://docs.dify.ai/en/cli/quick-start
Run your first Dify app from the command line in under 5 minutes
Before you start, make sure `difyctl` is [installed](/en/cli/install).
<Note>
On a self-hosted deployment, set both `OPENAPI_ENABLED` and `ENABLE_OAUTH_BEARER` to `true` before you sign in. See [Dify CLI and Programmatic API](/en/self-host/deploy/configuration/environments#dify-cli-and-programmatic-api) for the full variable reference.
</Note>
## Step 1: Sign In
1. Sign in to your Dify host.
For Dify Cloud, use `https://cloud.dify.ai`; on a self-hosted deployment, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
`difyctl` prints a one-time code and a verification URL, then waits:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
2. Open the URL in a browser, enter the code, and sign in. Return to the terminal and you'll see:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
## Step 2: Find Your App
List the apps in your workspace:
```bash theme={null}
difyctl get app
```
You should see something like this:
```text theme={null}
NAME ID MODE UPDATED
Customer FAQ 0a1b2c3d-4e5f-6789-abcd-ef0123456789 chat 2026-06-08T03:14:27.521839
Daily Report 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b workflow 2026-06-05T22:41:09.812016
```
Copy the ID of the app you want to run. The examples below use the two IDs from this table.
## Step 3: Run Your App
How you pass input depends on the app type.
<Tabs>
<Tab title="Chatbot / Chatflow / Agent / Text Generator">
Pass your message as a positional argument:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
```
The reply prints to stdout. For Chatbot, Chatflow, and Agent apps, a hint also prints to stderr so you can continue the same conversation later:
```text theme={null}
Our business hours are Monday through Friday, 9am to 6pm PT.
hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
</Tab>
<Tab title="Workflow">
Pass inputs as a single JSON object with `--inputs`:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report","audience":"executives"}'
```
The workflow's outputs print to stdout as JSON:
```json theme={null}
{"summary":"Q3 revenue grew 14% YoY...","sections":["revenue","costs","outlook"]}
```
</Tab>
</Tabs>
## Next Steps
* **The everyday commands, copy-paste ready**: [Common Tasks](/en/cli/common-tasks)
* **Where your token lives and how sessions work**: [Authenticate](/en/cli/authenticate)
* **Everything else you can do with `difyctl`**: [Command Index](/en/cli/reference/command-index)
# Apps
Source: https://docs.dify.ai/en/cli/reference/apps
List, inspect, run, resume, export, and import your Dify apps from the CLI
Every app task maps to one command, and all of them accept the [global flags](/en/cli/reference/global-flags).
* [`difyctl get app`](#list-your-apps) lists your apps
* [`describe app`](#inspect-an-app) shows one app's details and inputs
* [`run app`](#run-an-app) invokes one
* [`resume app`](#resume-a-paused-workflow) continues a workflow that [paused for human input](#when-a-workflow-pauses)
* [`export studio-app`](#export-an-app) / [`import studio-app`](#import-an-app) exports / imports apps as DSL files
## List Your Apps
```text theme={null}
difyctl get app [app-id] [flags]
```
<Tip>
For the everyday invocations, see [Find Your Apps](/en/cli/common-tasks#find-your-apps) in Common Tasks.
</Tip>
### Arguments
* `[app-id]`: optional. The ID of one app to show. Omit it to list every app in your workspace.
### Flags
| Flag | Type | Default | Description |
| :------------------------------------------ | :------ | :--------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--name <substring>` | string | none | Filter to apps whose name contains this text. |
| `--mode <mode>` | string | none | Filter by app type, named by its API mode: <ul><li>`chat` (Chatbot)</li><li>`advanced-chat` (Chatflow)</li><li>`agent-chat` (Agent)</li><li>`workflow` (Workflow)</li><li>`completion` (Text Generator)</li></ul> |
| `--page <n>` | integer | `1` | Page number. |
| `--limit <n>` | integer | `20` | Page size, 1 to 200. The flag wins, then [`DIFY_LIMIT`](/en/cli/reference/environment-variables). |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
| `-A, --all-workspaces` <Badge>Cloud</Badge> | boolean | `false` | List apps across every workspace your token can see. |
| `-o <format>` | string | none | Output format: `json`, `yaml`, `name`, or `wide`. Omit the flag for the default table. |
### Examples
List the apps in your workspace:
```bash theme={null}
difyctl get app
```
List apps across every workspace you belong to:
```bash theme={null}
difyctl get app -A
```
Find Workflow apps whose name contains "report":
```bash theme={null}
difyctl get app --name report --mode workflow
```
Print app IDs only, one per line, for shell loops:
```bash theme={null}
difyctl get app -o name
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default | An aligned table. The `MODE` column is each app's API mode name (see [`--mode`](#list-your-apps) for the mapping to app types). |
| `-o wide` | The table plus a `WORKSPACE` column. |
| `-o json`, `-o yaml` | A `data` array of the apps, plus the paging fields `page` (current page), `limit` (page size), `total` (apps matched), and `has_more` (whether more pages remain). |
| `-o name` | The app IDs, one per line. |
Default table:
```text theme={null}
NAME ID MODE UPDATED
Customer FAQ 0a1b2c3d-4e5f-6789-abcd-ef0123456789 chat 2026-06-08T03:14:27.521839
Daily Report 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b workflow 2026-06-05T22:41:09.812016
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------ |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as a `--limit` outside 1 to 200 |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Inspect an App
```text theme={null}
difyctl describe app <app-id> [flags]
```
`describe app` answers the question you have before running an unfamiliar app: what type of app is it, is its API enabled, and what inputs does it expect.
### Arguments
* `<app-id>`: required. The ID of the app to inspect.
### Flags
| Flag | Type | Default | Description |
| :------------ | :------ | :------ | :----------------------------------------------------------------------------------------- |
| `--refresh` | boolean | `false` | Bypass the local app-info cache and fetch fresh details. Use after an app was republished. |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Inspect an app before running it:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Extract the input schema for building `--inputs` programmatically:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b -o json | jq '.input_schema'
```
Re-fetch after republishing the app:
```bash theme={null}
difyctl describe app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --refresh
```
### Output
| Format | What stdout gets |
| :------------------- | :--------------------------------------------------------------------------------- |
| default (`text`) | An aligned field block, then the app's parameters (including the user input form). |
| `-o json`, `-o yaml` | Three top-level keys: `info`, `parameters`, and `input_schema` (detailed below). |
Default text view:
```text theme={null}
Name: Daily Report
ID: 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
Mode: workflow
Updated: 2026-06-05T22:41:09.812016
Service API: true
Parameters:
{
"opening_statement": null,
"suggested_questions": [],
"user_input_form": [
{
"text-input": {
"label": "topic",
"variable": "topic",
"required": true,
"default": ""
}
}
],
"file_upload": null,
"system_parameters": {
"file_size_limit": 15,
"image_file_size_limit": 10,
"audio_file_size_limit": 50,
"video_file_size_limit": 100,
"workflow_file_upload_limit": 10
}
}
```
A `Description:` row appears when the app has one, and an `Agent: true` row when the app is agentic.
Under `-o json`, the three keys are:
* `info` - the metadata fields shown above, from `Name` to `Service API`
* `parameters` - the parameters block shown above
* `input_schema` - a normalized list of the app's inputs, the field the `jq '.input_schema'` example reads
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------- |
| `0` | Success |
| `1` | Network or server error, including app not found |
| `2` | Usage error, including a non-UUID `<app-id>` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Run an App
```text theme={null}
difyctl run app <app-id> [message] [flags]
```
`run app` is one command for all app types. The CLI reads the app's type and dispatches to the right endpoint. What changes is how you pass input and the response shape:
* **Chatbot, Chatflow, Agent**: take a positional message, print the reply to stdout, and print a conversation hint to stderr.
* **Text Generator**: takes a positional message and prints the completion to stdout. No conversational state, no hint.
* **Workflow**: takes a JSON object via `--inputs` and prints its outputs to stdout. A workflow whose output is a single string prints it raw. Anything else prints as compact JSON.
### Arguments
* `<app-id>`: required. The ID of the app to run, from [`get app`](#list-your-apps).
* `[message]`: the user message, for Chatbot, Chatflow, Agent, and Text Generator apps. Workflow apps reject a positional message, so pass their inputs with `--inputs`.
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :----------------- | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `--inputs <json>` | string | none | Input variables as one JSON object, e.g. `--inputs '{"topic":"Q3"}'`. Required for Workflow apps. Mutually exclusive with `--inputs-file`. |
| `--inputs-file <path>` | string | none | Read the inputs object from a JSON file instead. |
| `--file <key=value>` | string, repeatable | none | Named file input. `key=@path` uploads a local file. `key=https://…` passes a remote URL without uploading. The key is the input variable name. |
| `--conversation <id>` | string | none | Continue an existing conversation. The ID comes from the stderr hint or the JSON response of an earlier run. |
| `--workflow-id <id>` | string | none | Pin the run to a specific published workflow version. Workflow and Chatflow apps only. |
| `--stream` | boolean | `false` | Print the output live as it's generated, instead of all at once at the end. |
| `--think` | boolean | `false` | Print the model's thinking to stderr when the model exposes it, whether as inline `<think>` blocks or a separate reasoning stream.<br /><br />Without this flag, that thinking is hidden. |
| `--retry-on-limit` | boolean | `false` | On a 429 rate limit, wait and retry the run instead of failing with exit `7`. Off by default, since a run isn't idempotent. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Send a message to a Chatbot, Chatflow, Agent, or Text Generator app:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?"
```
Run a Workflow app with structured inputs:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"quarterly report","audience":"executives"}'
```
Attach a local file to a file-type input variable:
```bash theme={null}
difyctl run app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --inputs '{"topic":"contract review"}' --file document=@./contract.pdf
```
Continue an earlier conversation:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "And on weekends?" --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
Get the raw response as JSON for scripts and agents:
```bash theme={null}
difyctl run app 0a1b2c3d-4e5f-6789-abcd-ef0123456789 "What are your business hours?" -o json | jq -r '.answer'
```
### Output
| Format | What stdout gets |
| :------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default (`text`) | The reply (Chatbot, Chatflow, Agent, Text Generator) or the workflow's output, as plain text. |
| `-o json`, `-o yaml` | The full server payload, including `answer` and `conversation_id` for conversational apps, plus the model's reasoning under `metadata.reasoning` when present. |
The response body goes to stdout. Everything else (hints, progress, errors) goes to stderr, so piping and redirection stay clean. After a reply from a Chatbot, Chatflow, or Agent app, stderr carries the conversation hint:
```text theme={null}
hint: continue this conversation with --conversation 4f7d8c2a-9b1e-4c6d-8a3f-5e2b7c9d0a1f
```
With `--stream`, output prints incrementally as the server produces it. If a run fails with HTTP 422 right after an app was republished, the CLI clears its app-metadata cache and hints to run the command again.
Errors print to stderr. Under `-o json` they arrive as a structured JSON object with a stable `code` field. See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the error shape.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------------------- |
| `0` | Success, including a workflow that [paused for human input](#when-a-workflow-pauses) |
| `1` | Network or server error, including app not found |
| `2` | Usage error: invalid `--inputs` JSON, or a positional message passed to a Workflow app |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
### When a Workflow Pauses
Workflow and Chatflow apps can include human-input steps. When a run reaches one, it pauses instead of finishing: the command **exits 0** (a pause is not a failure), prints the pause to stdout, and prints a ready-to-run resume command to stderr:
```text theme={null}
! Workflow paused — input required
Node: Review draft
Message: Approve the report before it is published.
Actions: [approve] Approve [reject] Reject
Inputs: - comment — Reviewer comment
! workflow paused — resume with:
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --action approve
```
With `-o json`, stdout gets the pause as a JSON object instead:
```json theme={null}
{
"status": "paused",
"app_id": "7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b",
"task_id": "c4a8e2f6-1b3d-4a5c-9e7f-2d8b6c0a4e1f",
"workflow_run_id": "8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b",
"form_id": "5d9c3b7a-2e4f-4c6d-8b0a-1f3e5d7c9b2a",
"node_id": "1749876543210",
"node_title": "Review draft",
"form_token": "k3J9mQ2xWv8pL5nR7tY4bA",
"form_content": "Approve the report before it is published.",
"inputs": [
{
"output_variable_name": "comment",
"label": "Reviewer comment",
"type": "text-input",
"required": false
}
],
"actions": [
{ "id": "approve", "title": "Approve" },
{ "id": "reject", "title": "Reject" }
],
"display_in_ui": true,
"resolved_default_values": {},
"expiration_time": 1781712000
}
```
For scripts and agents: a paused run and a completed run both exit 0, so don't branch on the exit code. Run workflows with `-o json` and check stdout for `"status": "paused"`. Three fields drive the resume: `form_token`, `workflow_run_id`, and (when the form offers more than one action) the action `id`. Forms expire at `expiration_time` (Unix epoch seconds).
When the workflow delivers its form through email or another external channel, `form_token` is `null` and the run can't be resumed from the CLI.
## Resume a Paused Workflow
```text theme={null}
difyctl resume app <app-id> <form-token> --workflow-run-id <id> [flags]
```
`resume app` submits the form a paused workflow is waiting on, then attaches to the run and prints its output exactly like `run app`.
### Arguments
* `<app-id>`: required. The `app_id` from the pause payload.
* `<form-token>`: required. The `form_token` from the pause payload. Tokens are single-use, so resuming with an already-consumed token returns an error.
### Flags
| Flag | Type | Default | Description |
| :----------------------- | :------ | :------------ | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--workflow-run-id <id>` | string | required | The `workflow_run_id` from the pause payload. |
| `--action <id>` | string | auto-selected | Which form action to take, by `id` from the pause payload's `actions`.<br /><br />Optional when the form has exactly one action, required when it has several. |
| `--inputs <json>` | string | none | Values for the form's inputs as one JSON object, keyed by each input's `output_variable_name`.<br /><br />Mutually exclusive with `--inputs-file`. |
| `--inputs-file <path>` | string | none | Read the form values from a JSON file instead. |
| `--with-history` | boolean | `false` | Replay the output of already-executed nodes before attaching to the live stream. |
| `--stream` | boolean | `false` | Print the output live as it's generated, instead of all at once at the end. |
| `--think` | boolean | `false` | Print the model's thinking to stderr when the model exposes it, whether as inline `<think>` blocks or a separate reasoning stream.<br /><br />Without this flag, that thinking is hidden. |
| `-o <format>` | string | `text` | Output format: `json`, `yaml`, or `text`. |
### Examples
Approve a single-action form, providing its input values:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --inputs '{"comment":"Looks good"}'
```
Pick an action when the form offers several:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --action reject --inputs '{"comment":"Numbers need a re-check"}'
```
Read the form values from a file:
```bash theme={null}
difyctl resume app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b k3J9mQ2xWv8pL5nR7tY4bA --workflow-run-id 8e1f2a3b-4c5d-6e7f-8a9b-0c1d2e3f4a5b --inputs-file form.json
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------- |
| default (`text`) | The workflow's output as the run completes. stderr confirms the submission and the finish. |
| `-o json`, `-o yaml` | The run result as one document, just like `run app` (a pause payload if it pauses again). |
In the default text output, stderr confirms the submission, the workflow's output prints to stdout as the run completes, and stderr confirms the finish:
```text theme={null}
✓ form submitted
workflow execution resumed
✓ workflow finished
```
A resumed workflow can pause again at a later human-input node. You then get a new pause payload and resume again with the new token.
### Exit Codes
| Code | Meaning |
| :--- | :-------------------------------------------------------------------------------------------- |
| `0` | Success, including the run pausing again at a later node |
| `1` | Error, including a consumed form token, or omitting `--action` on a form with several actions |
| `2` | Usage error |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Export an App
```text theme={null}
difyctl export studio-app <app-id> [flags]
```
`export studio-app` writes the app's full definition as a DSL YAML document, for versioning, backup, or [importing](#import-an-app) elsewhere.
For Workflow and Chatflow apps, export returns the current draft, not the published version that `run app` executes. Use `--workflow-id` to export a specific published version instead. Chatbot, Agent, and Text Generator apps export the published version.
### Arguments
* `<app-id>`: required. The ID of the app to export, from [`get app`](#list-your-apps).
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :------ | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `-o, --output <path>` | string | none | Write the DSL to this file instead of stdout.<br /><br />On this command, `-o` is the output file path, not the output-format selector. |
| `--include-secret` | boolean | `false` | Include encrypted secret values in the exported DSL. |
| `--workflow-id <id>` | string | none | Export a specific published workflow version by ID, instead of the default draft.<br /><br />Workflow and Chatflow apps only. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Run against another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
### Examples
Print an app's DSL to stdout:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Write it to a file:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --output ./daily-report.yaml
```
Export a specific published version:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --workflow-id c7e4a1b9-3f82-4d6a-9e15-0b8c2d7f4a63
```
Export with secret values included:
```bash theme={null}
difyctl export studio-app 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b --include-secret
```
### Output
The DSL YAML document prints to stdout: a `kind: app` header, a `version` field, and the full app definition. With `--output`, the same content is written to the file and stderr confirms it:
```text theme={null}
DSL written to ./daily-report.yaml
```
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------- |
| `0` | Success |
| `1` | Network or server error, including app not found |
| `2` | Usage error, including a missing `<app-id>` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Import an App
```text theme={null}
difyctl import studio-app (--from-file <path> | --from-url <url>) [flags]
```
`import studio-app` creates an app from a DSL YAML document, or overwrites an existing one with `--app-id`.
For Workflow and Chatflow apps, it writes the definition to the app's draft. `run app` uses the published version, so publish the app in Dify after importing for the change to take effect.
### Flags
| Flag | Type | Default | Description |
| :-------------------------------------- | :----- | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `-f, --from-file <path>` | string | none | Import DSL from a local file. Exactly one of `--from-file` or `--from-url` is required. |
| `--from-url <url>` | string | none | Import DSL from an HTTP(S) URL. |
| `--name <name>` | string | from DSL | Override the app name. |
| `--description <text>` | string | from DSL | Override the app description. |
| `--app-id <id>` | string | none | Overwrite an existing app instead of creating a new one.<br /><br />Workflow and Chatflow apps only. |
| `--icon-type <type>` | string | from DSL | Override the icon type. |
| `--icon <icon>` | string | from DSL | Override the icon. |
| `--icon-background <color>` | string | from DSL | Override the icon background color. |
| `--workspace <id>` <Badge>Cloud</Badge> | string | active workspace | Import into another workspace for this invocation only.<br /><br />For how `difyctl` resolves the workspace, see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace). |
### Examples
Import an app from a local DSL file:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml
```
Import under a different name:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml --name "Daily Report (staging)"
```
Overwrite an existing app with an updated DSL:
```bash theme={null}
difyctl import studio-app --from-file ./daily-report.yaml --app-id 7f3e9a2b-1c4d-4e8f-9a0b-2d5c8e1f4a7b
```
Import directly from a URL:
```bash theme={null}
difyctl import studio-app --from-url https://example.com/templates/daily-report.yaml
```
### Output
All status lines go to stderr; stdout stays empty. On success, stderr reports the new app's ID:
```text theme={null}
Import completed: app 9b4f2c8e-6a1d-4e3f-b7a5-0c8d2e6f4a9b
```
If the DSL was written for a different DSL version, the CLI confirms it for you and notes both versions on stderr.
If the app depends on plugins that aren't installed in the workspace, stderr lists them under `Missing plugin dependencies` after the import. Install them before using the app.
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------------------------------------------------- |
| `0` | Success, including imports with warnings |
| `1` | Error, including a missing or conflicting `--from-file`/`--from-url`, or a failed import |
| `2` | Usage error, including a `--from-file` path that doesn't exist |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
# Auth and Contexts
Source: https://docs.dify.ai/en/cli/reference/auth-and-contexts
Sign in, manage sessions, and switch between saved hosts and accounts
`difyctl` can hold sign-ins for several Dify hosts and accounts at once. Each host and account pair is a context: its metadata lives in `hosts.yml` in the [config directory](/en/cli/reference/environment-variables), and its bearer token lives in your OS credential store (with a protected file fallback).
Each task maps to one command:
* [`difyctl auth login`](#sign-in) signs you in to a host
* [`auth whoami`](#check-your-active-identity) prints the identity you're signed in as
* [`auth list`](#list-your-saved-contexts) lists your saved contexts
* [`auth logout`](#sign-out) signs you out of the active host
* [`use host`](#switch-the-active-host) / [`use account`](#switch-the-active-account) switch the active context
* [`auth devices list`](#list-your-active-sessions) lists your active sessions
* [`auth devices revoke`](#revoke-sessions) revokes sessions you don't recognize
For the step-by-step sign-in walkthrough, see [Authenticate](/en/cli/authenticate).
## Sign In
```text theme={null}
difyctl auth login [flags]
```
`auth login` runs the OAuth 2.0 device flow: it prints a one-time code and a verification URL, opens the URL in your browser, and waits for you to approve the sign-in there. The CLI never sees your password.
### Flags
| Flag | Type | Default | Description |
| :------------- | :------ | :------ | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--host <url>` | string | none | The Dify host to sign in to: <ul><li>For Dify Cloud, use `https://cloud.dify.ai`. </li><li>On self-hosted Dify, use the [console API URL](/en/self-host/deploy/configuration/environments#console_api_url).</li></ul>A URL without a scheme gets `https://`.<br /><br />In a terminal, omit it and enter your host; in a non-interactive session (script, CI, pipe), the flag is required. |
| `--no-browser` | boolean | false | Don't auto-open the browser; print the verification URL only. |
| `--insecure` | boolean | false | Allow `http://` hosts, and accept `https://` hosts whose TLS certificate is self-signed or invalid (local development only). |
### Examples
Sign in to your Dify host:
```bash theme={null}
difyctl auth login --host https://cloud.dify.ai
```
Sign in from an SSH session, opening the verification URL on another device:
```bash theme={null}
difyctl auth login --no-browser
```
### Output
The code prompt goes to stderr, then a spinner waits for the browser-side approval:
```text theme={null}
! Copy this one-time code: WDJP-XKLM
Open: https://cloud.dify.ai/device
```
On success, the confirmation goes to stdout:
```text theme={null}
✓ Logged in to cloud.dify.ai as <your-email> (<your-name>)
Workspace: <your-workspace>
```
The `Workspace:` line is your default workspace.
Each sign-in also registers a server-side session, labeled `difyctl on <hostname>`. Run [`auth devices list`](#list-your-active-sessions) to see all your sessions. Signing in to a host you're already signed in to refreshes that context's stored token.
### Exit Codes
| Code | Meaning |
| :--- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `0` | Signed in |
| `1` | Network or server error |
| `2` | Usage error, such as a missing `--host` outside a terminal or a non-`https` host without `--insecure` |
| `4` | The sign-in was denied (`access_denied`), or the code expired before you approved it (`expired_token`) |
| `6` | A version mismatch: the server is too old for this `difyctl` (checked before the session is saved), or this `difyctl` is too old for the server (HTTP `426`). Also when the server has no device-flow sign-in endpoint (`unsupported_endpoint`) |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Check Your Active Identity
```text theme={null}
difyctl auth whoami [flags]
```
`auth whoami` prints who the active context belongs to. It reads the stored context without contacting the server, so it answers "which identity is active", not "is the token still valid". It exits `0` even if the session has expired server-side.
### Flags
| Flag | Type | Default | Description |
| :------- | :------ | :------ | :---------------------------------------- |
| `--json` | boolean | false | Emit JSON instead of the plain-text line. |
### Examples
```bash theme={null}
difyctl auth whoami
```
For scripts:
```bash theme={null}
difyctl auth whoami --json
```
### Output
```text theme={null}
<your-email> (<your-name>)
```
The `--json` output is a single line with `id`, `email`, and `name`:
```json theme={null}
{"id":"3c90c3cc-0d44-4b50-8888-8dd25736052a","email":"<your-email>","name":"<your-name>"}
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------ |
| `0` | An active context exists |
| `4` | Not signed in (`not_logged_in`) |
## List Your Saved Contexts
```text theme={null}
difyctl auth list [flags]
```
`auth list` shows every stored host and account pair and marks the active one. Like `auth whoami`, it is purely local and never contacts the server.
### Flags
| Flag | Type | Default | Description |
| :------------ | :----- | :------ | :----------------------------------------------------------------------------- |
| `-o <format>` | string | none | Output format: `json`, `yaml`, or `name`. Omit the flag for the default table. |
### Examples
```bash theme={null}
difyctl auth list
```
### Output
| Format | What stdout gets |
| :------------------- | :--------------------------------------------------------------------------- |
| default | A table of your contexts: host, account, and an active marker. |
| `-o json`, `-o yaml` | A `contexts` array, each entry with `host`, `account`, `name`, and `active`. |
| `-o name` | The account emails, one per line. |
Default table:
```text theme={null}
HOST ACCOUNT ACTIVE
cloud.dify.ai you@company.com (Your Name) *
dify.internal.acme.com you@acme.com (Your Name)
```
`-o json`:
```json theme={null}
{
"contexts": [
{
"host": "cloud.dify.ai",
"account": "you@company.com",
"name": "Your Name",
"active": true
},
{
"host": "dify.internal.acme.com",
"account": "you@acme.com",
"name": "Your Name",
"active": false
}
]
}
```
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------- |
| `0` | Success, including when no contexts are stored |
| `2` | Usage error, such as an unsupported `-o` value |
## Sign Out
```text theme={null}
difyctl auth logout
```
`auth logout` revokes the active context's session on the server, then deletes its token and `hosts.yml` entry from your machine. Other saved contexts are untouched.
The local cleanup always happens. If the server-side revoke fails, `difyctl` prints a warning on stderr and clears your credentials anyway.
The same applies when the token sits in an OS keychain that can't be read at sign-out (locked, or no desktop session): the revoke is skipped and the local cleanup still runs.
### Flags
None.
### Examples
```bash theme={null}
difyctl auth logout
```
### Output
```text theme={null}
✓ Logged out of cloud.dify.ai
```
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------ |
| `0` | Signed out |
| `4` | Not signed in (`not_logged_in`) |
## Switch the Active Host
```text theme={null}
difyctl use host [flags]
```
`use host` changes which stored host subsequent commands run against. It is local: it only re-points the active context among the sign-ins you already have. To add a new host, run [`auth login --host`](#sign-in) instead.
### Flags
| Flag | Type | Default | Description |
| :---------------- | :----- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--domain <host>` | string | none | The stored host to switch to, written as its bare domain (`cloud.dify.ai`), without a scheme.<br /><br />In a terminal, omit it and pick from your stored hosts. In a non-interactive session (script, CI, pipe), the flag is required. |
### Examples
Switch to a stored host by its domain:
```bash theme={null}
difyctl use host --domain dify.internal.acme.com
```
### Output
On success, the new active host is confirmed:
```text theme={null}
✓ Active host is now dify.internal.acme.com
```
A domain you haven't signed into fails as a usage error that lists your known hosts.
### Exit Codes
| Code | Meaning |
| :--- | :----------------------------------------------------------------------- |
| `0` | Switched |
| `2` | Usage error: an unknown host, or a missing `--domain` outside a terminal |
| `4` | No stored sign-ins (`not_logged_in`) |
## Switch the Active Account
```text theme={null}
difyctl use account [flags]
```
`use account` changes which stored account is active on the current host. Like `use host`, it is local and only switches between sign-ins you already have.
### Flags
| Flag | Type | Default | Description |
| :---------------- | :----- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--email <email>` | string | none | The account to switch to.<br /><br />In a terminal, omit it and pick from your stored accounts; in a non-interactive session (script, CI, pipe), the flag is required. |
### Examples
Switch to another account on the active host:
```bash theme={null}
difyctl use account --email teammate-bot@company.com
```
### Output
On success, the new active account is confirmed:
```text theme={null}
✓ Active account on cloud.dify.ai is now teammate-bot@company.com
```
An email that isn't stored on the active host fails as a usage error that lists your known accounts. An account whose stored token is gone (revoked, or cleared by a [session revoke](#revoke-sessions)) fails with a not-logged-in error and a hint to sign in again.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------- |
| `0` | Switched |
| `2` | Usage error: an unknown account, or a missing `--email` outside a terminal |
| `4` | No stored sign-in on this host, or no credential for the chosen account |
## List Your Active Sessions
```text theme={null}
difyctl auth devices list [flags]
```
Every device-flow sign-in registers a server-side session, labeled `difyctl on <hostname>` by default. `auth devices list` shows the sessions active for your account so you can spot and [revoke](#revoke-sessions) ones you don't recognize.
### Flags
| Flag | Type | Default | Description |
| :------------ | :------ | :------ | :------------------------------------------------------------------------------------------------ |
| `--json` | boolean | false | Emit JSON instead of the table. |
| `--page <n>` | integer | 1 | Page number. |
| `--limit <n>` | integer | 20 | Page size, 1 to 200. The flag wins, then [`DIFY_LIMIT`](/en/cli/reference/environment-variables). |
### Examples
List the sessions active for your account:
```bash theme={null}
difyctl auth devices list
```
### Output
```text theme={null}
DEVICE CREATED LAST USED CURRENT
difyctl on Yours-MacBook-Pro 2026-06-02T09:14:31Z 2026-06-11T08:02:17Z *
difyctl on build-runner-3 2026-05-28T11:40:09Z 2026-06-10T22:51:44Z
```
The table marks the session your current sign-in uses with `*`. `LAST USED` is empty for a session you haven't used since signing in.
`--json` prints a single line of JSON: a `data` array with one entry per session, plus the paging fields `page`, `limit`, `total`, and `has_more`. Each entry carries `id`, `prefix`, `client_id`, `device_label`, `created_at`, `last_used_at`, and `expires_at`.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------- |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as `--limit 0` |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
## Revoke Sessions
```text theme={null}
difyctl auth devices revoke [<target>] [flags]
```
`auth devices revoke` ends sessions server-side. The target matches by exact label first, then by exact session ID, then by case-insensitive label substring. A target that matches more than one session fails with the candidates listed, so pass an exact ID to disambiguate.
In a terminal, `difyctl` first asks you to confirm; pass `-y`/`--yes` to skip the prompt. Outside a terminal (a script or pipe), it revokes without prompting.
If you revoke the session your current sign-in uses, `difyctl` also clears that context's local credentials: you are signed out on this machine.
### Arguments
* `<target>`: a device label or session ID from [`auth devices list`](#list-your-active-sessions). Required unless `--all` is passed.
### Flags
| Flag | Type | Default | Description |
| :---------- | :------ | :------ | :------------------------------------------- |
| `--all` | boolean | false | Revoke every session except the current one. |
| `-y, --yes` | boolean | false | Skip the confirmation prompt. |
### Examples
Revoke one session by its label:
```bash theme={null}
difyctl auth devices revoke "difyctl on build-runner-3"
```
Sign out everywhere else, keeping this machine's session:
```bash theme={null}
difyctl auth devices revoke --all
```
### Output
On success, `difyctl` prints `✓ Revoked <N> session(s)`. A named target that matches nothing fails with `no session matches "<target>"`. `--all` with no other sessions prints `no sessions to revoke` and exits `0`.
### Exit Codes
| Code | Meaning |
| :--- | :-------------------------------------------------------------------------------------------------------------------- |
| `0` | Revoked, or nothing to revoke under `--all` |
| `1` | Network or server error |
| `2` | Usage error: no target and no `--all`, an ambiguous target, no matching session, or declining the confirmation prompt |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Command Index
Source: https://docs.dify.ai/en/cli/reference/command-index
Find any difyctl command by name, with a link to its full reference
| Command | What it does |
| :----------------------------------------------------------------------------------------------- | :--------------------------------------------------------- |
| [`auth devices list`](/en/cli/reference/auth-and-contexts#list-your-active-sessions) | List the active sessions for your account. |
| [`auth devices revoke`](/en/cli/reference/auth-and-contexts#revoke-sessions) | Revoke one session, or all but the current one. |
| [`auth list`](/en/cli/reference/auth-and-contexts#list-your-saved-contexts) | List your saved sign-in contexts. |
| [`auth login`](/en/cli/reference/auth-and-contexts#sign-in) | Sign in to a Dify host with the OAuth device flow. |
| [`auth logout`](/en/cli/reference/auth-and-contexts#sign-out) | Sign out of the active host. |
| [`auth whoami`](/en/cli/reference/auth-and-contexts#check-your-active-identity) | Print the identity you're signed in as. |
| [`describe app`](/en/cli/reference/apps#inspect-an-app) | Inspect one app's metadata and inputs. |
| [`env list`](/en/cli/reference/environment-variables#see-whats-set) | List the environment variables difyctl recognizes. |
| [`export studio-app`](/en/cli/reference/apps#export-an-app) | Export a studio app's DSL configuration as YAML. |
| [`get app`](/en/cli/reference/apps#list-your-apps) | List apps, or look up one app. |
| [`get workspace`](/en/cli/reference/workspaces#list-your-workspaces) | List the workspaces you belong to. |
| [`help`](/en/cli/reference/help) | Get help in the terminal, including machine-readable JSON. |
| [`import studio-app`](/en/cli/reference/apps#import-an-app) | Import a studio app from a DSL file or URL. |
| [`resume app`](/en/cli/reference/apps#resume-a-paused-workflow) | Resume a paused workflow run. |
| [`run app`](/en/cli/reference/apps#run-an-app) | Run an app and print the response. |
| [`skills install`](/en/cli/reference/skills#install-the-skill) | Install the difyctl skill into detected coding agents. |
| [`use account`](/en/cli/reference/auth-and-contexts#switch-the-active-account) | Switch the active account on the current host. |
| [`use host`](/en/cli/reference/auth-and-contexts#switch-the-active-host) | Switch the active Dify host. |
| [`use workspace`](/en/cli/reference/workspaces#switch-your-workspace-cloud) <Badge>Cloud</Badge> | Switch your active workspace. |
| [`version`](/en/cli/reference/version) | Show client and server versions and compatibility. |
[Global flags](/en/cli/reference/global-flags) work across commands.
For the output formats, errors, and exit codes, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
# Environment Variables
Source: https://docs.dify.ai/en/cli/reference/environment-variables
Set difyctl defaults for the current shell session with environment variables
Environment variables set defaults for the current shell session: every `difyctl` command you run in it picks them up. A command flag wins, then an environment variable. They're shell-scoped and last only as long as the session.
## Variables difyctl Reads
| Variable | What it controls | Default |
| :------------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------ |
| `DIFY_CONFIG_DIR` | Where `difyctl` keeps its configuration (`hosts.yml`). | macOS and Linux: `~/.config/difyctl` (Linux honors `XDG_CONFIG_HOME`)<br /><br />Windows: `%APPDATA%\difyctl` |
| `DIFY_LIMIT` | Default page size, 1 to 200, for list commands (`get app`, `auth devices list`). The `--limit` flag wins, then this variable. | `20` |
| `DIFY_WORKSPACE_ID` | The workspace `difyctl` commands run against. Must be a UUID. See [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace) for the resolution order. | none |
| `DIFYCTL_HTTP_RETRY` | Retry attempts for idempotent requests on transient failures (`0` disables retries). [`--http-retry`](/en/cli/reference/global-flags#http-retries) overrides it. | `3` |
An invalid value fails as a usage error (exit code `2`) rather than being silently ignored, for example a non-UUID `DIFY_WORKSPACE_ID`.
<Info>
Only the variables above change `difyctl`'s behavior. The others reported by the `env list` command are recognized but currently have no effect.
</Info>
## See What's Set
```text theme={null}
difyctl env list [flags]
```
`env list` shows the current value of each `difyctl` environment variable in your shell. It reads only your local environment and never calls the server, so it works before you sign in.
### Flags
| Flag | Type | Default | Description |
| :------- | :------ | :------ | :------------------------------------------------------ |
| `--json` | boolean | `false` | Print the inventory as a JSON array instead of a table. |
<Note>
`env list` takes `--json`, not the [`-o` global flag](/en/cli/reference/global-flags).
</Note>
### Examples
Check which variables are set in the current shell:
```bash theme={null}
difyctl env list
```
Get the same inventory as JSON:
```bash theme={null}
difyctl env list --json
```
### Output
Unset variables show `<unset>`, and sensitive variables never print their value (only `<set>` or `<unset>`). With `DIFY_LIMIT=50` exported:
```text theme={null}
NAME VALUE DESCRIPTION
DIFY_CONFIG_DIR <unset> Override the config-dir resolution (precedes XDG_CONFIG_HOME on Linux).
DIFY_FORMAT <unset> Default output format for list commands (table | json | yaml | wide | name).
DIFY_HOST <unset> Default Dify host (overridden by --host).
DIFY_LIMIT 50 Default page size for list commands (1..200).
DIFY_NO_PROGRESS <unset> Suppress progress spinners. Truthy values: 1, true, yes.
DIFY_PLAIN <unset> Disable ANSI colors and decorative output. Truthy values: 1, true, yes.
DIFY_TOKEN <unset> Bearer token for non-interactive auth.
DIFY_WORKSPACE_ID <unset> Workspace ID used for difyctl commands.
DIFYCTL_HTTP_RETRY <unset> HTTP retry count for GET/PUT/DELETE. 0 disables. Overrides --http-retry flag.
```
`--json` prints a JSON array, one entry per variable, masked the same way:
```json theme={null}
[
{
"name": "DIFY_CONFIG_DIR",
"description": "Override the config-dir resolution (precedes XDG_CONFIG_HOME on Linux).",
"sensitive": false,
"value": "<unset>"
}
]
```
### Exit Codes
| Code | Meaning |
| :--- | :------ |
| `0` | Success |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Global Flags
Source: https://docs.dify.ai/en/cli/reference/global-flags
Use these flags across difyctl commands to control output format, verbosity, and retry behavior
The flags below work across `difyctl` commands. `-v` and `-h` are universal, while `-o` and `--http-retry` are accepted by most but not all. Check a command's [reference](/en/cli/reference/command-index) for the flags it accepts.
| Flag | What it does |
| :---------------------------------------- | :-------------------------------------------------------------------- |
| [`-o, --output <format>`](#output-format) | Selects the output format: `json`, `yaml`, `name`, `wide`, or `text`. |
| [`-v, --verbose`](#verbose-mode) | Turns on verbose diagnostics on stderr. |
| [`--http-retry <n>`](#http-retries) | Sets the retry budget for idempotent requests. |
| [`-h, --help`](/en/cli/reference/help) | Show the command's help instead of running it. |
<Note>
Flags always follow the command: `difyctl get app -o json` works; `difyctl -o json get app` is read as an unknown command.
</Note>
## Output Format
To see which of the five formats a command supports, check its `--help` or the flags table on its reference page. If you repeat the flag, the last value wins.
`-o` also changes how failures render: under `-o json`, errors arrive as a machine-readable JSON object on stderr.
For the format schemas, defaults, and channel rules, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
<Note>
On [`export studio-app`](/en/cli/reference/apps#export-an-app), `-o` is the output file path, not a format selector.
</Note>
## Verbose Mode
`-v` adds verbose HTTP logging to stderr and includes the `raw_response` field (the raw server response, bearer tokens redacted) in error output.
Use it when a request fails and the normal error doesn't explain why.
## HTTP Retries
`difyctl` retries idempotent requests (GET, PUT, DELETE) on transient failures: network errors and HTTP 408, 413, 500, 502, 503, and 504 responses. POST requests are never retried. A 429 (rate limited) is handled separately and exits `7`, not retried by this budget.
The default budget is 3 attempts with exponential backoff (300 ms, doubling, capped at 30 s). Use `--http-retry 0` to disable retries.
The [`DIFYCTL_HTTP_RETRY`](/en/cli/reference/environment-variables) environment variable sets the same budget; if both are set, the flag takes priority.
## `--workspace` Is Not Global <Badge>Cloud</Badge>
`--workspace <id>` is per-command: it appears on commands that target workspace data and applies to that invocation only.
For where the flag sits in the precedence chain (flag, environment variable, stored default), see [How difyctl Picks a Workspace](/en/cli/reference/workspaces#how-difyctl-picks-a-workspace).
# Help
Source: https://docs.dify.ai/en/cli/reference/help
Get help in the terminal with per-command docs, guide topics, and machine-readable JSON
The `difyctl` help system covers four surfaces: the [top-level overview](#get-help), [per-command and group help](#help-for-one-command-or-group), [guide topics](#guide-topics), and a [machine-readable form](#machine-readable-help) of all of them. All help prints to stdout and exits `0`.
## Get Help
Four invocations show the same top-level overview:
```bash theme={null}
difyctl
difyctl help
difyctl --help
difyctl -h
```
The overview lists every command with its one-liner, three getting-started examples, the [global flags](/en/cli/reference/global-flags), and the [guide topics](#guide-topics). For the same inventory with links into this reference, see the [Command Index](/en/cli/reference/command-index).
## Help for One Command or Group
Append `--help` to any command, or put `help` in front of it:
```bash theme={null}
difyctl run app --help
difyctl help run app
```
Per-command help shows the command's description, usage line, arguments, flags with defaults, and examples.
Name a command group instead of a command to list the group's subcommands:
```bash theme={null}
difyctl auth --help
```
```text theme={null}
COMMANDS
auth devices list List active sessions for the current bearer
auth devices revoke Revoke one or all session devices
auth list List all authenticated contexts (host + account pairs)
auth login Sign in to Dify via OAuth device flow
auth logout Log out of the active Dify host
auth whoami Print the active subject's identity
```
A name that matches neither a command, a topic, nor a group fails with `unknown help topic: <name>`, suggestions, and exit code `1`.
## Guide Topics
Long-form topics ship inside the CLI, read with `difyctl help <topic>`:
| Topic | What it covers |
| :------------ | :---------------------------------------------------------------- |
| `account` | Onboarding guidance. |
| `environment` | The CLI's own descriptions of the `DIFY_*` environment variables. |
| `agent` | The cross-command contract for agents driving `difyctl`. |
These topics are built into the CLI. For which variables `difyctl` actually reads, see [Environment Variables](/en/cli/reference/environment-variables).
## Machine-Readable Help
Every help surface accepts `-o json` and `-o yaml`. The top-level form emits the complete command surface in one document:
```bash theme={null}
difyctl help -o json
```
The document has four top-level keys:
* `bin`, `contract`: exit codes, output formats, the shape of error output, and cross-command rules
* `commands`: one descriptor per command
* `topics`: the available guide topics by name, with each topic's text read via `difyctl help <topic>`
Per-command help in JSON returns just that command's descriptor:
```bash theme={null}
difyctl auth whoami --help -o json
```
```json theme={null}
{
"command": "auth whoami",
"description": "Print the active subject's identity",
"effect": "read",
"args": [],
"flags": [
{
"name": "json",
"char": null,
"type": "boolean",
"default": false,
"multiple": false,
"options": null,
"description": "emit JSON"
}
],
"examples": [
"difyctl auth whoami",
"difyctl auth whoami --json"
],
"agentGuide": null
}
```
Each descriptor carries the command's arguments and flags with types and defaults, an `effect` label (`read`, `write`, or `destructive`), and an `agentGuide` string where one exists. This is how coding agents discover `difyctl`.
## Exit Codes
| Code | Meaning |
| :--- | :--------------------------------- |
| `0` | Help printed |
| `1` | Unknown help topic or command name |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
# Output Formats and Exit Codes
Source: https://docs.dify.ai/en/cli/reference/output-formats-and-exit-codes
What each difyctl output format emits, how stdout and stderr split, how errors are structured, and what every exit code means
`difyctl` is built to be scripted: data goes to stdout while everything else goes to stderr, the [`-o` global flag](/en/cli/reference/global-flags) selects the output format, and failures exit with a predictable code.
## Output Formats
`-o <format>` selects how a command renders its result on stdout. Each command supports a subset of the five formats, listed in its `--help` and the Flags table on its reference page.
| Format | What stdout gets |
| :----- | :------------------------------------------------------------------------------------------------------------------------------------------ |
| `json` | The result as pretty-printed JSON (2-space indent). Unicode characters appear as-is, and null fields are an explicit `null`, never omitted. |
| `yaml` | The same data as YAML. |
| `name` | Bare resource IDs, one per line. Built for shell loops; no parsing needed. |
| `wide` | The default table plus extra columns. For example, `get app -o wide` adds a `WORKSPACE` column. |
| `text` | Human-readable text. The default for single-resource commands such as `describe app` and `run app`. |
Without `-o`, list commands such as `get app` print an aligned text table and other commands print text.
The JSON shapes are stable: list commands such as `get app` print a JSON object with the rows in an array, and two runs of the same command return the same top-level structure. For a command's exact JSON shape, see its reference page.
## Output Channels
| Channel | What lands there |
| :------ | :------------------------------------------------------------------------------------------------------------------------------ |
| stdout | Data: tables, JSON and YAML documents, IDs, run output, exported DSL |
| stderr | Everything else: errors, hints, progress spinners, status lines such as `✓ form submitted`, and reasoning streamed by `--think` |
The rules worth scripting against:
* On failure, stdout stays empty. You never have to filter error text out of captured data.
* On success, `get` and `describe` commands leave stderr empty; `run app` and `resume app` may print hints there.
* Progress spinners appear only in a terminal, on stderr, and are suppressed under `-o json`, `-o yaml`, and `-o name`.
* Piped output carries no ANSI color codes.
* If the consumer of a pipe exits early (`difyctl get app -o name | head -2`), `difyctl` exits `0` rather than failing on the broken pipe.
## Errors
Errors go to stderr. In the default human format, an error is a `code: message` line plus optional detail lines:
```text theme={null}
not_logged_in: not logged in
hint: run 'difyctl auth login'
```
When an HTTP request was involved, `request: <METHOD> <url>` and `http_status: <n>` lines follow.
When the server's reply carries Dify's standard error body, the header line shows the server's more specific code (`not_found`, `invalid_param`) instead of the CLI's transport-level code.
Per-field validation details follow as indented lines, and the server's hint appears when `difyctl` has none of its own.
Under `-o json`, the same error becomes a single-line JSON object on stderr:
```json theme={null}
{"error":{"code":"not_logged_in","message":"not logged in","hint":"run 'difyctl auth login'"}}
```
Only `-o json` switches error rendering: `-o yaml` failures print the human format.
| Field | Present | Meaning |
| :-------------- | :------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `code` | always | Stable machine-readable error code. Branch on this, never on message text. |
| `message` | always | Human-readable description. |
| `hint` | when known | The fastest fix, often a copy-pasteable command. |
| `http_status` | on HTTP failures | Status code of the failed request. |
| `method`, `url` | on HTTP failures | The request that failed. |
| `raw_response` | only with `-v` | The raw server response body, bearer tokens redacted. |
| `server` | on HTTP failures, when the reply is Dify's standard error body | The server's own error: `code`, `message`, `status`, plus optional `hint` and `details`. <br /><br />The top-level `code` stays the CLI's stable transport-level code; `server.code` carries the server's finer-grained reason. |
For what each code means and how to fix it, see [Troubleshooting](/en/cli/troubleshooting).
## Exit Codes
| Code | Meaning | Examples |
| :--- | :----------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `0` | Success | Also `--help`, `version`, and a workflow run that [paused for human input](#a-paused-workflow-run-exits-0). |
| `1` | Generic failure | Network and server errors (`network_connection`, `server_5xx`, `server_4xx_other`), unknown commands, unknown flags, an unreachable OS keychain (`keyring_unavailable`). |
| `2` | Usage error | An invalid flag value (`-o table`, `--limit 0`), a missing argument, a non-UUID app or workspace ID, `--inputs` that isn't a JSON object. |
| `4` | Authentication error | `not_logged_in`, `auth_expired`, `token_expired`, `access_denied`. |
| `6` | Version or compatibility error | `version_skew` (the server is older than this `difyctl` supports, or the server rejected this `difyctl` as too old with HTTP 426), `unsupported_endpoint` (the server lacks an endpoint this build needs), or an unreadable config file (`config_schema_unsupported`). |
| `7` | Rate limited | An HTTP 429 (`rate_limited`), kept distinct from `1` so a script can back off and retry. |
| `64` | Compatibility gate failed | Only [`version --check-compat`](/en/cli/reference/version#gate-scripts-on-compatibility): the server was not confirmed compatible. |
One nuance for strict scripts: parser-level mistakes (an unknown command, an unknown flag, a flag missing its value) exit `1` with a plain-text message, while an invalid value for a known flag exits `2`.
### A Paused Workflow Run Exits 0
A Workflow or Chatflow app can pause mid-run to collect human input. The pause is a successful outcome, not a failure: `run app` and `resume app` exit `0` and print a paused payload to stdout.
To detect a pause in a script or an agent, run with `-o json` and check stdout for `"status": "paused"`; don't branch on the exit code.
For the payload shape and the resume protocol, see [When a Workflow Pauses](/en/cli/reference/apps#when-a-workflow-pauses) on the Apps reference.
# Workspaces
Source: https://docs.dify.ai/en/cli/reference/workspaces
List your workspaces, switch the active one, and understand how difyctl resolves which workspace to use
`difyctl` works in one active workspace at a time, taken from a flag, an environment variable, or your stored default. For the order those take priority, see [How difyctl Picks a Workspace](#how-difyctl-picks-a-workspace).
* [`difyctl get workspace`](#list-your-workspaces) lists the workspaces you belong to
* [`use workspace`](#switch-your-workspace-cloud) switches the active one <Badge>Cloud</Badge>
Both accept the [global flags](/en/cli/reference/global-flags).
## List Your Workspaces
```text theme={null}
difyctl get workspace [flags]
```
### Flags
| Flag | Type | Default | Description |
| :------------ | :----- | :------ | :------------------------------------------------------------------------------------- |
| `-o <format>` | string | none | Output format: `json`, `yaml`, `name`, or `wide`. Omit the flag for the default table. |
### Examples
See your workspaces and which one is active:
```bash theme={null}
difyctl get workspace
```
Get the full list as JSON for scripts:
```bash theme={null}
difyctl get workspace -o json
```
Print workspace IDs only, one per line:
```bash theme={null}
difyctl get workspace -o name
```
### Output
| Format | What stdout gets |
| :------------------- | :----------------------------------------------------------------------------------------------------- |
| default | An aligned table. `CURRENT` marks your active workspace with `*`, and `ROLE` is your role in each one. |
| `-o wide` | The same columns. Workspaces have no wide-only columns. |
| `-o json`, `-o yaml` | A `workspaces` array, each entry carrying `id`, `name`, `role`, `status`, and `current`. |
| `-o name` | The workspace IDs, one per line. |
Default table:
```text theme={null}
ID NAME ROLE STATUS CURRENT
b4e8d2a6-7c3f-4a1e-9d5b-8f2c6e0a4d7b Acme Team owner normal *
9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c Marketing normal normal
```
`-o json`:
```json theme={null}
{
"workspaces": [
{
"id": "b4e8d2a6-7c3f-4a1e-9d5b-8f2c6e0a4d7b",
"name": "Acme Team",
"role": "owner",
"status": "normal",
"current": true
},
{
"id": "9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c",
"name": "Marketing",
"role": "normal",
"status": "normal",
"current": false
}
]
}
```
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------- |
| `0` | Success |
| `1` | Network or server error |
| `2` | Usage error, such as an unsupported `-o` value |
| `4` | Authentication failure |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Switch Your Workspace <Badge>Cloud</Badge>
```text theme={null}
difyctl use workspace [workspace-id] [flags]
```
`use workspace` switches your active workspace on the server first, then updates the stored default in `hosts.yml`. If the switch fails (the workspace doesn't exist, or you're not a member), your local state is left untouched.
<Tip>
For the everyday invocation, see [Switch Your Workspace](/en/cli/common-tasks#switch-your-workspace-cloud) in Common Tasks.
</Tip>
### Arguments
* `workspace-id`: the workspace to switch to, from [`get workspace`](#list-your-workspaces). In a terminal, omit it to pick from your workspaces, the current one marked `*`. In a non-interactive session (script, CI, pipe), it's required.
### Flags
Only the [global flags](/en/cli/reference/global-flags).
### Examples
Pick interactively from your workspaces:
```bash theme={null}
difyctl use workspace
```
Or look up the target yourself, then switch by ID (the form that works in scripts):
```bash theme={null}
difyctl get workspace
difyctl use workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
For a single command against another workspace, skip switching and pass `--workspace` instead:
```bash theme={null}
difyctl get app --workspace 9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c
```
### Output
On success, the new active workspace is confirmed on stdout:
```text theme={null}
✓ Switched to Marketing (9c2f4e6a-8b1d-4f3e-a5c7-0d9e2b4f6a8c)
```
The switch persists: every subsequent command runs against the new workspace until you switch again.
### Exit Codes
| Code | Meaning |
| :--- | :--------------------------------------------------------------------------------------- |
| `0` | Success |
| `1` | Workspace not found, or another server error |
| `2` | Usage error, such as omitting `workspace-id` where there's no terminal to pick in |
| `4` | Authentication failure, or no workspaces available when `use workspace` opens its picker |
| `7` | Rate limited (HTTP 429) |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## How difyctl Picks a Workspace
Apps live in exactly one workspace, so every command that targets one needs a workspace to run against. `difyctl` resolves it in this order, taking the first value it finds:
1. The `--workspace <id>` flag on the command itself. Applies to that invocation only.
2. The [`DIFY_WORKSPACE_ID`](/en/cli/reference/environment-variables) environment variable.
3. Your stored default, written to `hosts.yml` in the config directory when you sign in and updated by [`use workspace`](#switch-your-workspace-cloud).
If none of these yields a workspace, the command fails with exit code `2`.
Workspace IDs are UUIDs, so pass an ID from [`get workspace`](#list-your-workspaces), not a workspace name. A value that isn't a UUID fails as a usage error.
# Skills
Source: https://docs.dify.ai/en/cli/reference/skills
Install the agent skill so coding agents can drive difyctl
[`skills install`](#install-the-skill) writes the `difyctl` skill (a `SKILL.md` file) into the skill directories of the coding agents on your machine.
The skill deliberately lists no commands: it points the agent at `difyctl help -o json` and lets it discover the live command surface itself.
See the [help reference](/en/cli/reference/help#machine-readable-help) for that discovery surface, and [Install the difyctl Skill](/en/cli/integrate-agents/install-the-difyctl-skill) for the full integration.
## Install the Skill
```text theme={null}
difyctl skills install [dir] [flags]
```
This command is fully local: it needs no sign-in and never contacts a server.
### Arguments
* `dir`: optional. Install into this single directory, bypassing agent detection. The skill lands at `<dir>/SKILL.md`. Cannot be combined with `--agent`.
### Flags
| Flag | Type | Default | Description |
| :---------- | :----------------- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `-y, --yes` | boolean | `false` | Write the skill. Without it, the command is a dry run: it lists where the skill would land and writes nothing. |
| `--agent` | string, repeatable | none | Restrict the install to specific detected agents, using the names from [Agent Detection](#agent-detection).<br /><br />With no `--agent`, the skill installs into every detected agent. To install into several agents but not all, repeat the flag or pass a comma-separated list.<br /><br />Naming an agent that isn't detected is a usage error. |
| `--stdout` | boolean | `false` | Print the skill to stdout and write nothing. Cannot be combined with `--yes`, `--agent`, or `dir`. |
### Examples
Preview where the skill would be installed (dry run, the default):
```bash theme={null}
difyctl skills install
```
Install into every detected agent:
```bash theme={null}
difyctl skills install --yes
```
Install into one agent only:
```bash theme={null}
difyctl skills install --yes --agent claude-code
```
Install into several specific agents (repeat the flag or comma-separate):
```bash theme={null}
difyctl skills install --yes --agent claude-code --agent cursor
```
Install into an explicit directory, for an agent the CLI doesn't detect:
```bash theme={null}
difyctl skills install ./my-skills/difyctl --yes
```
Print the skill without writing anything:
```bash theme={null}
difyctl skills install --stdout
```
### Agent Detection
Detection checks whether each agent's configuration directory exists. The CLI never probes `PATH` or launches anything. The skill is written to each agent's documented user-level skill location:
| Agent | Detected when | Skill lands in |
| :------------ | :-------------------------- | :------------------------------------------- |
| `claude-code` | `~/.claude` exists | `~/.claude/skills/difyctl/SKILL.md` |
| `codex` | `~/.codex` exists | `~/.agents/skills/difyctl/SKILL.md` |
| `opencode` | `~/.config/opencode` exists | `~/.config/opencode/skills/difyctl/SKILL.md` |
| `cursor` | `~/.cursor` exists | `~/.cursor/skills/difyctl/SKILL.md` |
| `pi` | `~/.pi` exists | `~/.pi/agent/skills/difyctl/SKILL.md` |
An agent that's installed but has never been launched may not have its configuration directory yet. Install into its skill directory explicitly with `difyctl skills install <dir>`.
### Output
A dry run lists the detected agents and the target paths, then tells you how to proceed:
```text theme={null}
Detected 2 agents: claude-code, cursor
would write to claude-code: /Users/you/.claude/skills/difyctl/SKILL.md
would write to cursor: /Users/you/.cursor/skills/difyctl/SKILL.md
Re-run with --yes to write all, or --agent <name> to write only some.
Agent not listed? Install into its directory with `difyctl skills install <dir>`.
```
With `--yes`, each write is confirmed:
```text theme={null}
wrote /Users/you/.claude/skills/difyctl/SKILL.md
wrote /Users/you/.cursor/skills/difyctl/SKILL.md
```
When nothing is detected, the command explains the alternatives and exits 0:
```text theme={null}
No agents detected (looked for ~/.claude, ~/.codex, ~/.config/opencode, ~/.cursor, ~/.pi).
Install into a directory manually with `difyctl skills install <dir>`, or
print the skill with `difyctl skills install --stdout`.
```
The installed skill carries a version stamp matching the CLI that wrote it. Re-running `skills install --yes` after upgrading replaces the file with the current version. Re-running is always safe.
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------------------------------------------------------------------------------------ |
| `0` | Success, including a dry run and the nothing-detected case |
| `1` | Local failure, such as a target directory that isn't writable |
| `2` | Usage error: `--stdout` combined with a write option, `dir` combined with `--agent`, or `--agent` naming an agent that isn't detected |
# Version
Source: https://docs.dify.ai/en/cli/reference/version
Check your difyctl build and its compatibility with your Dify server
Run [`difyctl version`](#check-client-and-server-versions) to see which `difyctl` build you have and whether it works with your Dify server. It prints the client build, probes your active host, and reports a [compatibility verdict](#compatibility-verdicts).
In a script, [`--check-compat`](#gate-scripts-on-compatibility) turns that verdict into an exit code.
## Check Client and Server Versions
```text theme={null}
difyctl version [flags]
```
### Flags
| Flag | Type | Default | Description |
| :--------------- | :------ | :------ | :------------------------------------------------------- |
| `--short` | boolean | false | Print only the client semver (no server probe) and exit. |
| `--client` | boolean | false | Skip the server probe, so the verdict reports `unknown`. |
| `--check-compat` | boolean | false | Exit `64` unless the verdict is `compatible`. |
| `-o <format>` | string | text | Output format: `text`, `json`, or `yaml`. |
### Examples
Print the full report:
```bash theme={null}
difyctl version
```
Print just the client version, for scripts and bug reports:
```bash theme={null}
difyctl version --short
```
### Output
| Format | What stdout gets |
| :------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| default (`text`) | The full report: a `Client` block, a `Server` block, and a one-line `Compatibility` verdict. Builds on any channel other than `stable` append a warning recommending the stable channel. |
| `-o json`, `-o yaml` | The same report as three objects: <ul><li>`client` (`version`, `commit`, `buildDate`, `channel`, `platform`, `arch`)</li><li>`server` (`endpoint`, `reachable`, and on success `version` and `edition`)</li><li>`compat` (`minDify`, `maxDify`, `status`, `detail`)</li></ul> |
The default `text` report:
```text theme={null}
Client:
Version: 0.2.0-alpha (channel: alpha)
Commit: 9f3c2ab (built 2026-06-05)
Platform: darwin/arm64
Compat: dify >=1.16.0, <=1.16.0
Server:
Endpoint: https://cloud.dify.ai
Version: 1.16.0 (cloud)
Compatibility: ok — server 1.16.0 in [1.16.0, 1.16.0]
```
`--short` prints only the client semver:
```text theme={null}
0.2.0-alpha
```
`-o json`:
```json theme={null}
{
"client": {
"version": "0.2.0-alpha",
"commit": "9f3c2ab",
"buildDate": "2026-06-05",
"channel": "alpha",
"platform": "darwin",
"arch": "arm64"
},
"server": {
"endpoint": "https://cloud.dify.ai",
"reachable": true,
"version": "1.16.0",
"edition": "CLOUD"
},
"compat": {
"minDify": "1.16.0",
"maxDify": "1.16.0",
"status": "compatible",
"detail": "server 1.16.0 in [1.16.0, 1.16.0]"
}
}
```
This command exits `0` even when the server is unreachable or incompatible: the verdict is the report, not an error. Pass `--check-compat` (below) to turn it into an exit code. Other commands act on the verdict; see [How Commands React to an Incompatible Server](#how-commands-react-to-an-incompatible-server).
### Exit Codes
| Code | Meaning |
| :--- | :------------------------------------------------------ |
| `0` | Report printed, whatever the verdict |
| `64` | With `--check-compat`: the verdict was not `compatible` |
See [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes) for the full scheme.
## Compatibility Verdicts
`difyctl version` compares your build against the server's version and reports one of four verdicts. You don't need to be signed in, but you do need a stored host to probe.
The `text` report prints the **Shown as** label on its `Compatibility:` line; `-o json` reports the verdict name in `status`.
| Verdict | Shown as | Meaning |
| :----------- | :------------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------- |
| `compatible` | `ok` | The server version is inside the range this build supports. |
| `too_old` | `incompatible (server too old)` | The server is older than the minimum this build supports. |
| `too_new` | `incompatible (server too new)` | The server is newer than the maximum this build was tested against. |
| `unknown` | `unknown` | No verdict: no host configured, the server is unreachable, the probe was skipped with `--client`, or the server's version didn't parse. |
The `detail` field spells out the case, for example `server 1.14.0 is older than the minimum 1.16.0` or `server 1.16.0 in [1.16.0, 1.16.0]`.
## How Commands React to an Incompatible Server
`difyctl version` only reports the verdict. Every command that contacts the server acts on it before running, so a `too_old` server stops those commands until you resolve the mismatch:
* **`too_old`**: the command stops with exit [`6`](/en/cli/reference/output-formats-and-exit-codes) before doing its work, and tells you to upgrade the Dify server to at least the minimum this build supports (or [install the `difyctl` that matches your server](/en/cli/install)).
* **`too_new`**: the command runs; in an interactive terminal with text output, it also prints a throttled one-line warning to stderr.
* **`unknown`**: the command runs; there is nothing to gate on.
A server that clears the minimum version (`compatible` or `too_new`) is cached for about an hour per host, so the block check isn't repeated on every command. A `too_old` server is never cached, so it's re-checked each time and starts working as soon as you upgrade it.
Signing in with [`auth login`](/en/cli/reference/auth-and-contexts) runs the same check before it stores a session, so a mismatch surfaces at sign-in rather than on your first command.
The checks run in both directions: the verdicts above are `difyctl` judging your server, and your server also judges `difyctl`.
If your client is older than the server accepts, the server rejects the request with HTTP `426` and `difyctl` exits `6` with an upgrade message. This is why upgrading your Dify server can break an older `difyctl`: the server refuses the old client, even though that client's own verdict on a newer server is only a warning.
So the reliable path is to keep `difyctl` matched to your server: a newer server is tolerated with a warning, but an older one is refused.
## Gate Scripts on Compatibility
`--check-compat` makes the verdict scriptable: anything other than `compatible`, including every `unknown` case, exits `64`. `difyctl version` always probes the server live and never reads the compatibility cache, so a scripted gate reflects the current version; the flag only turns that verdict into an exit code.
The full report still goes to stdout in your chosen format, and the one-line reason goes to stderr, so `difyctl version -o json --check-compat | jq` works the same on both outcomes.
```bash theme={null}
difyctl version --check-compat || echo "difyctl and this Dify server are not a confirmed match"
```
Exit code `64` is specific to this flag. No other `difyctl` failure uses it.
# Troubleshooting
Source: https://docs.dify.ai/en/cli/troubleshooting
Fix common difyctl errors with their explanations, exit codes, and solutions
When `difyctl` encounters an error, it writes a message to stderr. With `-o json` active, errors are also single-line JSON with a stable `code` field and an actionable `hint`.
For the full exit-code table and error object shape, see [Output Formats and Exit Codes](/en/cli/reference/output-formats-and-exit-codes).
## Version Compatibility
### `version_skew` (difyctl and the server don't match)
`difyctl` ships with each Dify release and is matched to a server version, so a version change on either side can leave the two out of sync. It surfaces in two ways, both exiting `6`:
* **Your Dify server was upgraded** and your existing `difyctl` is now too old. The server rejects it with HTTP `426` and prints an upgrade message.
* **Your `difyctl` is newer than your server**, so it stops before sending the request, reporting that the server is older than it supports.
1. Confirm it's a version mismatch:
```bash theme={null}
difyctl version
```
A `Compatibility: incompatible …` line, or an upgrade message, confirms it.
2. Reinstall `difyctl` so it matches your server: set `DIFY_VERSION` to your server's Dify release tag (or omit it if your server runs the latest release), then re-run the install script. See [Install](/en/cli/install) for details.
Exit code: `6`.
## Authentication Errors
### `auth_expired`
Your session has expired and `difyctl` can no longer make authenticated requests.
1. Re-authenticate:
```bash theme={null}
difyctl auth login
```
2. Re-run the failed command.
Exit code: `4`.
### `not_logged_in`
No active session exists for the requested host.
1. Sign in:
```bash theme={null}
difyctl auth login --host <url>
```
2. Re-run the failed command.
Exit code: `4`.
### `access_denied`
You denied the sign-in request, or canceled it before approving, so nothing was authorized.
Re-run and approve the request:
```bash theme={null}
difyctl auth login
```
Exit code: `4`.
## App Errors
### App not found (HTTP 404)
The App ID you specified doesn't exist or isn't accessible to your token. Surfaces as `server_4xx_other` with HTTP status 404.
1. List apps you can access:
```bash theme={null}
difyctl get app
```
2. Verify the ID and re-run.
Exit code: `1`.
### Service API disabled (HTTP 403 from server)
The app exists, but its Service API is turned off in the Dify console. The app owner must enable it. A 403 surfaces as `server_4xx_other`.
Exit code: `1`.
## Workflow Errors
### Workflow validation error (HTTP 422)
A Workflow app rejected your inputs. The error message lists which required inputs are missing or invalid.
1. Inspect the app's input schema:
```bash theme={null}
difyctl describe app <id>
```
2. Update your `--inputs` JSON to match.
Exit code: `1`.
# Agent Strategy Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin
Build a Function Calling agent strategy from scratch, with a worked example showing how to give an LLM tools and let it autonomously fetch the current time
An **Agent Strategy Plugin** gives an LLM the reasoning and decision-making logic to choose tools, call them, and handle their results, so it can solve problems autonomously.
This guide walks through building a **Function Calling** strategy that lets the model fetch the current time on its own.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
For details on preparing the plugin development tool, see [CLI](/en/develop-plugin/getting-started/cli).
<Tip>
Run `dify version` in your terminal to confirm that the scaffolding tool is installed.
</Tip>
***
## 1. Initialize the Plugin Template
Run the following command to create a development template for your Agent plugin:
```bash theme={null}
dify plugin init
```
Follow the on-screen prompts; the comments below explain each choice.
```bash theme={null}
➜ Dify Plugins Developing dify plugin init
Edit profile of the plugin
Plugin name (press Enter to next step): # Enter the plugin name
Author (press Enter to next step): Author name # Enter the plugin author
Description (press Enter to next step): Description # Enter the plugin description
---
Select the language you want to use for plugin development, and press Enter to con
BTW, you need Python 3.12+ to develop the Plugin if you choose Python.
-> python # Select Python environment
go (not supported yet)
---
Based on the ability you want to extend, we have divided the Plugin into four type
- Tool: It's a tool provider, but not only limited to tools, you can implement an
- Model: Just a model provider, extending others is not allowed.
- Extension: Other times, you may only need a simple http service to extend the fu
- Agent Strategy: Implement your own logics here, just by focusing on Agent itself
What's more, we have provided the template for you, you can choose one of them b
tool
-> agent-strategy # Select Agent strategy template
llm
text-embedding
---
Configure the permissions of the plugin, use up and down to navigate, tab to sel
Backwards Invocation:
Tools:
Enabled: [✔] You can invoke tools inside Dify if it's enabled # Enabled by default
Models:
Enabled: [✔] You can invoke models inside Dify if it's enabled # Enabled by default
LLM: [✔] You can invoke LLM models inside Dify if it's enabled # Enabled by default
Text Embedding: [✘] You can invoke text embedding models inside Dify if it'
Rerank: [✘] You can invoke rerank models inside Dify if it's enabled
...
```
Initialization creates a folder with everything you need for plugin development:
```text theme={null}
├── GUIDE.md # User guide and documentation
├── PRIVACY.md # Privacy policy and data handling guidelines
├── README.md # Project overview and setup instructions
├── _assets/ # Static assets directory
│ └── icon.svg # Agent strategy provider icon/logo
├── main.py # Main application entry point
├── manifest.yaml # Basic plugin configuration
├── provider/ # Provider configurations directory
│ └── basic_agent.yaml # Your agent provider settings
├── requirements.txt # Python dependencies list
└── strategies/ # Strategy implementation directory
├── basic_agent.py # Basic agent strategy implementation
└── basic_agent.yaml # Basic agent strategy configuration
```
All key functionality for this plugin is in the `strategies/` directory.
***
## 2. Develop the Plugin
Agent Strategy Plugin development revolves around two files:
* **Plugin Declaration**: `strategies/basic_agent.yaml`
* **Plugin Implementation**: `strategies/basic_agent.py`
### 2.1 Define Parameters
Start by declaring the plugin's parameters in `strategies/basic_agent.yaml`. These parameters power the plugin's core features, such as calling an LLM or using tools.
We recommend starting with these four parameters:
* **`model`**: The large language model to call (e.g., GPT-4, GPT-4o-mini).
* **`tools`**: A list of tools that enhance your plugin's functionality.
* **`query`**: The user input or prompt content sent to the model.
* **`maximum_iterations`**: The maximum iteration count, which prevents excessive computation.
Example:
```yaml theme={null}
identity:
name: basic_agent # the name of the agent_strategy
author: novice # the author of the agent_strategy
label:
en_US: BasicAgent # the English label of the agent_strategy
description:
en_US: BasicAgent # the English description of the agent_strategy
parameters:
- name: model # the name of the model parameter
type: model-selector # model-type
scope: tool-call&llm # the scope of the parameter
required: true
label:
en_US: Model
zh_Hans: 模型
pt_BR: Model
- name: tools # the name of the tools parameter
type: array[tools] # the type of tool parameter
required: true
label:
en_US: Tools list
zh_Hans: 工具列表
pt_BR: Tools list
- name: query # the name of the query parameter
type: string # the type of query parameter
required: true
label:
en_US: Query
zh_Hans: 查询
pt_BR: Query
- name: maximum_iterations
type: number
required: false
default: 5
label:
en_US: Maxium Iterations
zh_Hans: 最大迭代次数
pt_BR: Maxium Iterations
max: 50 # if you set the max and min value, the display of the parameter will be a slider
min: 1
extra:
python:
source: strategies/basic_agent.py
```
Dify automatically renders a configuration interface from these parameter declarations:
<Frame>

</Frame>
### 2.2 Retrieve Parameters and Execute
When users fill out these fields, your plugin receives the submitted values. In `strategies/basic_agent.py`, define a Pydantic model that validates the incoming parameters:
```python theme={null}
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
```
Then parse the parameters in `_invoke` and run your strategy logic:
```python theme={null}
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
```
## 3. Invoke the Model
Invoking the model is central to an Agent strategy. Use `session.model.llm.invoke()` from the SDK to call an LLM for text generation, dialogue, and similar tasks.
For the LLM to drive tool calls, it must output structured arguments that match each tool's interface—input the tool can accept, derived from the user's instructions.
The method takes the following parameters:
* `model`
* `prompt_messages`
* `tools`
* `stop`
* `stream`
Method signature:
```python theme={null}
def invoke(
self,
model_config: LLMModelConfig,
prompt_messages: list[PromptMessage],
tools: list[PromptMessageTool] | None = None,
stop: list[str] | None = None,
stream: bool = True,
) -> Generator[LLMResultChunk, None, None] | LLMResult:...
```
For the full implementation, see the **Invoke Model** tab in the [sample code](#sample-code) below.
With this in place, the plugin calls the LLM whenever a user enters a command, builds tool-invocation parameters from the model's output, and lets the model dispatch the configured tools to complete complex tasks.
<Frame>

</Frame>
## 4. Invoke Tools
Once the model has produced tool parameters, the plugin must actually call the tools. Use `session.tool.invoke()` to make those requests.
The method takes the following parameters:
* `provider`
* `tool_name`
* `parameters`
Method signature:
```python theme={null}
def invoke(
self,
provider_type: ToolProviderType,
provider: str,
tool_name: str,
parameters: dict[str, Any],
) -> Generator[ToolInvokeMessage, None, None]:...
```
To let the LLM generate the tool-call parameters itself, feed the model's extracted tool calls into your invocation code:
```python theme={null}
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
```
Your plugin can now perform Function Calling automatically—for instance, retrieving the current time.
<Frame>

</Frame>
## 5. Create Logs
Complex tasks usually take multiple steps, and you need to track each step's result to analyze decisions and refine your strategy. The SDK's `create_log_message` and `finish_log_message` let you record state before and after each call, which speeds up problem diagnosis.
For example:
* Log a "starting model call" message before calling the model to show execution progress.
* Log a "call succeeded" message once the model responds, so its output can be traced end to end.
```python theme={null}
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
)
yield model_log
self.session.model.llm.invoke(...)
yield self.finish_log_message(
log=model_log,
data={
"output": response,
"tool_name": tool_call_names,
"tool_input": tool_call_inputs,
},
metadata={
"started_at": model_started_at,
"finished_at": time.perf_counter(),
"elapsed_time": time.perf_counter() - model_started_at,
"provider": params.model.provider,
},
)
```
Once set up, the workflow log shows the execution results:
<Frame>

</Frame>
When a task spans multiple rounds, set the `parent` parameter in your log calls to nest the logs hierarchically and keep them easy to follow:
```python theme={null}
function_call_round_log = self.create_log_message(
label="Function Call Round1 ",
data={},
metadata={},
)
yield function_call_round_log
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
# add parent log
parent=function_call_round_log,
)
yield model_log
```
### Sample Code
<Tabs>
<Tab title="Invoke Model">
The following code gives the Agent strategy plugin the ability to invoke the model:
```python theme={null}
import json
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
<Tab title="Handle Tools">
The following code invokes the model and sends well-formed requests to the tools it selects:
```python theme={null}
import json
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
<Tab title="Complete Example">
A complete sample that covers model invocation, tool handling, and multi-round logging:
```python theme={null}
import json
import time
from collections.abc import Generator
from typing import Any, cast
from dify_plugin.entities.agent import AgentInvokeMessage
from dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunk
from dify_plugin.entities.model.message import (
PromptMessageTool,
UserPromptMessage,
)
from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderType
from dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntity
from pydantic import BaseModel
class BasicParams(BaseModel):
maximum_iterations: int
model: AgentModelConfig
tools: list[ToolEntity]
query: str
class BasicAgentAgentStrategy(AgentStrategy):
def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]:
params = BasicParams(**parameters)
function_call_round_log = self.create_log_message(
label="Function Call Round1 ",
data={},
metadata={},
)
yield function_call_round_log
model_started_at = time.perf_counter()
model_log = self.create_log_message(
label=f"{params.model.model} Thought",
data={},
metadata={"start_at": model_started_at, "provider": params.model.provider},
status=ToolInvokeMessage.LogMessage.LogStatus.START,
parent=function_call_round_log,
)
yield model_log
chunks: Generator[LLMResultChunk, None, None] | LLMResult = (
self.session.model.llm.invoke(
model_config=LLMModelConfig(**params.model.model_dump(mode="json")),
prompt_messages=[UserPromptMessage(content=params.query)],
tools=[
self._convert_tool_to_prompt_message_tool(tool)
for tool in params.tools
],
stop=params.model.completion_params.get("stop", [])
if params.model.completion_params
else [],
stream=True,
)
)
response = ""
tool_calls = []
tool_instances = (
{tool.identity.name: tool for tool in params.tools} if params.tools else {}
)
tool_call_names = ""
tool_call_inputs = ""
for chunk in chunks:
# check if there is any tool call
if self.check_tool_calls(chunk):
tool_calls = self.extract_tool_calls(chunk)
tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls])
try:
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls},
ensure_ascii=False,
)
except json.JSONDecodeError:
# ensure ascii to avoid encoding error
tool_call_inputs = json.dumps(
{tool_call[1]: tool_call[2] for tool_call in tool_calls}
)
print(tool_call_names, tool_call_inputs)
if chunk.delta.message and chunk.delta.message.content:
if isinstance(chunk.delta.message.content, list):
for content in chunk.delta.message.content:
response += content.data
print(content.data, end="", flush=True)
else:
response += str(chunk.delta.message.content)
print(str(chunk.delta.message.content), end="", flush=True)
if chunk.delta.usage:
# usage of the model
usage = chunk.delta.usage
yield self.finish_log_message(
log=model_log,
data={
"output": response,
"tool_name": tool_call_names,
"tool_input": tool_call_inputs,
},
metadata={
"started_at": model_started_at,
"finished_at": time.perf_counter(),
"elapsed_time": time.perf_counter() - model_started_at,
"provider": params.model.provider,
},
)
yield self.create_text_message(
text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n"
)
result = ""
for tool_call_id, tool_call_name, tool_call_args in tool_calls:
tool_instance = tool_instances[tool_call_name]
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
if not tool_instance:
tool_invoke_responses = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": f"there is not a tool named {tool_call_name}",
}
else:
# invoke tool
tool_invoke_responses = self.session.tool.invoke(
provider_type=ToolProviderType.BUILT_IN,
provider=tool_instance.identity.provider,
tool_name=tool_instance.identity.name,
parameters={**tool_instance.runtime_parameters, **tool_call_args},
)
result = ""
for tool_invoke_response in tool_invoke_responses:
if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT:
result += cast(
ToolInvokeMessage.TextMessage, tool_invoke_response.message
).text
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK
):
result += (
f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}."
+ " please tell user to check it."
)
elif tool_invoke_response.type in {
ToolInvokeMessage.MessageType.IMAGE_LINK,
ToolInvokeMessage.MessageType.IMAGE,
}:
result += (
"image has been created and sent to user already, "
+ "you do not need to create it, just tell the user to check it now."
)
elif (
tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON
):
text = json.dumps(
cast(
ToolInvokeMessage.JsonMessage,
tool_invoke_response.message,
).json_object,
ensure_ascii=False,
)
result += f"tool response: {text}."
else:
result += f"tool response: {tool_invoke_response.message!r}."
tool_response = {
"tool_call_id": tool_call_id,
"tool_call_name": tool_call_name,
"tool_response": result,
}
yield self.create_text_message(result)
def _convert_tool_to_prompt_message_tool(
self, tool: ToolEntity
) -> PromptMessageTool:
"""
convert tool to prompt message tool
"""
message_tool = PromptMessageTool(
name=tool.identity.name,
description=tool.description.llm if tool.description else "",
parameters={
"type": "object",
"properties": {},
"required": [],
},
)
parameters = tool.parameters
for parameter in parameters:
if parameter.form != ToolParameter.ToolParameterForm.LLM:
continue
parameter_type = parameter.type
if parameter.type in {
ToolParameter.ToolParameterType.FILE,
ToolParameter.ToolParameterType.FILES,
}:
continue
enum = []
if parameter.type == ToolParameter.ToolParameterType.SELECT:
enum = (
[option.value for option in parameter.options]
if parameter.options
else []
)
message_tool.parameters["properties"][parameter.name] = {
"type": parameter_type,
"description": parameter.llm_description or "",
}
if len(enum) > 0:
message_tool.parameters["properties"][parameter.name]["enum"] = enum
if parameter.required:
message_tool.parameters["required"].append(parameter.name)
return message_tool
def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool:
"""
Check if there is any tool call in llm result chunk
"""
return bool(llm_result_chunk.delta.message.tool_calls)
def extract_tool_calls(
self, llm_result_chunk: LLMResultChunk
) -> list[tuple[str, str, dict[str, Any]]]:
"""
Extract tool calls from llm result chunk
Returns:
List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)]
"""
tool_calls = []
for prompt_message in llm_result_chunk.delta.message.tool_calls:
args = {}
if prompt_message.function.arguments != "":
args = json.loads(prompt_message.function.arguments)
tool_calls.append(
(
prompt_message.id,
prompt_message.function.name,
args,
)
)
return tool_calls
```
</Tab>
</Tabs>
## 6. Debug the Plugin
With the declaration file and implementation code complete, verify that the plugin runs correctly. Dify supports remote debugging: go to **Plugin Management** to obtain your debug key and remote server address.
<Frame>

</Frame>
In your plugin project, copy `.env.example` to `.env` and fill in the remote server address and debug key.
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Then run:
```bash theme={null}
python -m main
```
The plugin appears in your workspace, where team members can also access it.
<Frame>

</Frame>
## Package the Plugin (Optional)
Once everything works, package your plugin by running:
```bash theme={null}
# Replace ./basic_agent/ with your actual plugin project path.
dify plugin package ./basic_agent/
```
A file named `basic_agent.difypkg` (matching your plugin name) appears in your current folder. This is your final plugin package.
Congratulations! You've developed, tested, and packaged your Agent Strategy Plugin.
## Publish the Plugin (Optional)
You can now upload the package to the [Dify Plugins repository](https://github.com/langgenius/dify-plugins). Before doing so, ensure it meets the [Plugin Publishing Guidelines](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). Once approved, your code merges into the main branch, and the plugin automatically goes live on the [Dify Marketplace](https://marketplace.dify.ai/).
***
## Further Exploration
Complex tasks often need multiple rounds of thinking and tool calls, repeating the model invoke → tool use cycle until the task ends or the iteration limit is reached. Managing prompts well is crucial in this process. See the [complete Function Calling implementation](https://github.com/langgenius/dify-official-plugins/blob/main/agent-strategies/cot_agent/strategies/function_calling.py) for a standardized approach to letting models call external tools and handle their outputs.
# Cheatsheet
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet
A quick reference for Dify plugin development, covering environment setup, installation, the development process, and plugin types
## Environment Requirements
* Python version 3.12
* Dify plugin scaffold tool (`dify-plugin-daemon`)
For setup instructions, see [Initializing Development Tools](/en/develop-plugin/getting-started/cli).
## Obtain the Dify Plugin Development Package
Download the [Dify Plugin CLI](https://github.com/langgenius/dify-plugin-daemon/releases) from the GitHub releases page.
### Installation Methods for Different Platforms
**macOS [Brew](https://github.com/langgenius/homebrew-dify) (Global Installation)**:
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
After installation, open a new terminal window and enter the `dify version` command. If it outputs the version information, the installation was successful.
**macOS ARM (M Series Chips)**:
```bash theme={null}
# Download dify-plugin-darwin-arm64
chmod +x dify-plugin-darwin-arm64
./dify-plugin-darwin-arm64 version
```
**macOS Intel**:
```bash theme={null}
# Download dify-plugin-darwin-amd64
chmod +x dify-plugin-darwin-amd64
./dify-plugin-darwin-amd64 version
```
**Linux**:
```bash theme={null}
# Download dify-plugin-linux-amd64
chmod +x dify-plugin-linux-amd64
./dify-plugin-linux-amd64 version
```
**Global Installation (Recommended)**:
```bash theme={null}
# Rename and move to system path
# Example (macOS ARM)
mv dify-plugin-darwin-arm64 dify
sudo mv dify /usr/local/bin/
dify version
```
## Run the Development Package
The following examples use `dify` as the command. If you installed locally, replace the command accordingly—for example, `./dify-plugin-darwin-arm64 plugin init`.
## Plugin Development Process
### 1. Create a New Plugin
```bash theme={null}
./dify plugin init
```
Follow the prompts to configure the basic plugin information.
For a full walkthrough, see [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
### 2. Run in Development Mode
Configure the `.env` file, then run the following command in the plugin directory:
```bash theme={null}
python -m main
```
For debugging details, see [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin).
### 3. Package and Deploy
Package the plugin:
```bash theme={null}
cd ..
dify plugin package ./yourapp
```
For publishing details, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Plugin Categories
### Tool Labels
Category tags are defined in [`ToolLabelEnum`](https://github.com/langgenius/dify-plugin-sdks/blob/main/python/dify_plugin/entities/tool.py):
```python theme={null}
class ToolLabelEnum(Enum):
SEARCH = "search"
IMAGE = "image"
VIDEOS = "videos"
WEATHER = "weather"
FINANCE = "finance"
DESIGN = "design"
TRAVEL = "travel"
SOCIAL = "social"
NEWS = "news"
MEDICAL = "medical"
PRODUCTIVITY = "productivity"
EDUCATION = "education"
BUSINESS = "business"
ENTERTAINMENT = "entertainment"
UTILITIES = "utilities"
OTHER = "other"
```
## Plugin Type Reference
Dify supports several plugin types:
* **Tool plugin**: Integrate third-party APIs and services. See [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
* **Model plugin**: Integrate AI models. See [Model Plugin](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) and [Quick Integration of a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
* **Agent strategy plugin**: Customize Agent thinking and decision-making strategies. See [Agent Strategy Plugin](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
* **Extension plugin**: Extend Dify platform functionality, such as Endpoints and web apps. See [Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint).
* **Data source plugin**: Serve as the document data source and starting point for knowledge pipelines. See [Data Source Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin).
* **Trigger plugin**: Automatically trigger workflow execution on third-party events. See [Trigger Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin).
# Model Provider Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider
Build a model provider plugin, from project setup and provider configuration to model implementation, debugging, and publishing
## Prerequisites
* [Dify Plugin CLI](/en/develop-plugin/getting-started/cli)
* Basic Python programming skills and understanding of object-oriented programming
* Familiarity with the API documentation of the model provider you want to integrate
## Step 1: Create and Configure a New Plugin Project
### Initialize the Project
```bash theme={null}
dify plugin init
```
### Choose Model Plugin Template
Select the `LLM` type plugin template from the available options. This template provides a complete code structure for model integration.
<Frame>

</Frame>
### Configure Plugin Permissions
For a model provider plugin, configure the following essential permissions:
* **Models**: Base permission for model operations.
* **LLM**: Permission for large language model functionality.
* **Storage**: Permission for file operations (if needed).
<Frame>

</Frame>
### Directory Structure Overview
After initialization, your plugin project has a directory structure similar to this (assuming a provider named `my_provider` that supports LLM and Embedding):
```bash theme={null}
models/my_provider/
├── models # Model implementation and configuration directory
│ ├── llm # LLM type
│ │ ├── _position.yaml (Optional, controls sorting)
│ │ ├── model1.yaml # Configuration for specific model
│ │ └── llm.py # LLM implementation logic
│ └── text_embedding # Embedding type
│ ├── _position.yaml
│ ├── embedding-model.yaml
│ └── text_embedding.py
├── provider # Provider-level code directory
│ └── my_provider.py # Provider credential validation
└── manifest.yaml # Plugin manifest file
```
## Step 2: Understand Model Configuration Methods
Dify supports two model configuration methods that determine how users interact with your provider's models:
### Predefined Models (`predefined-model`)
Predefined models require only unified provider credentials. Once a user configures their API key or other authentication details for the provider, they can immediately access all predefined models.
**Example**: The OpenAI provider offers predefined models like `gpt-3.5-turbo-0125` and `gpt-4o-2024-05-13`. A user only needs to configure their OpenAI API key once to access all these models.
### Custom Models (`customizable-model`)
Custom models require additional configuration for each model instance. This approach is useful when models need individual parameters beyond the provider-level credentials.
**Example**: Xinference supports both LLM and Text Embedding, but each model has a unique `model_uid`. Users must configure this `model_uid` separately for each model they want to use.
The two configuration methods can coexist within a single provider. For instance, a provider might offer some predefined models while also allowing users to add custom models with specific configurations.
## Step 3: Create Model Provider Files
Creating a new model provider involves two main components:
* **Provider configuration YAML file**: Defines the provider's basic information, supported model types, and credential requirements.
* **Provider class implementation**: Implements authentication validation and other provider-level functionality.
### 3.1 Create the Model Provider Configuration File
The provider configuration is a YAML file that declares the provider's basic information, supported model types, configuration methods, and credential rules. Place it in the root directory of your plugin project.
Here's an annotated example of the `anthropic.yaml` configuration file:
```yaml theme={null}
# Basic provider identification
provider: anthropic # Provider ID (must be unique)
label:
en_US: Anthropic # Display name in UI
description:
en_US: Anthropic's powerful models, such as Claude 3.
zh_Hans: Anthropic 的强大模型,例如 Claude 3。
icon_small:
en_US: icon_s_en.svg # Small icon for provider (displayed in selection UI)
icon_large:
en_US: icon_l_en.svg # Large icon (displayed in detail views)
background: "#F0F0EB" # Background color for provider in UI
# Help information for users
help:
title:
en_US: Get your API Key from Anthropic
zh_Hans: 从 Anthropic 获取 API Key
url:
en_US: https://console.anthropic.com/account/keys
# Supported model types and configuration approach
supported_model_types:
- llm # This provider offers LLM models
configurate_methods:
- predefined-model # Uses predefined models approach
# Provider-level credential form definition
provider_credential_schema:
credential_form_schemas:
- variable: anthropic_api_key # Variable name for API key
label:
en_US: API Key
type: secret-input # Secure input for sensitive data
required: true
placeholder:
zh_Hans: 在此输入你的 API Key
en_US: Enter your API Key
- variable: anthropic_api_url
label:
en_US: API URL
type: text-input # Regular text input
required: false
placeholder:
zh_Hans: 在此输入你的 API URL
en_US: Enter your API URL
# Model configuration
models:
llm: # Configuration for LLM type models
predefined:
- "models/llm/*.yaml" # Pattern to locate model configuration files
position: "models/llm/_position.yaml" # File defining display order
# Implementation file locations
extra:
python:
provider_source: provider/anthropic.py # Provider class implementation
model_sources:
- "models/llm/llm.py" # Model implementation file
```
### Custom Model Configuration
If your provider supports custom models, add a `model_credential_schema` section defining the additional fields users must configure for each model. This is typical for providers that support fine-tuned models or require model-specific parameters.
Here's an example from the OpenAI provider:
```yaml theme={null}
model_credential_schema:
model: # Fine-tuned model name field
label:
en_US: Model Name
zh_Hans: 模型名称
placeholder:
en_US: Enter your model name
zh_Hans: 输入模型名称
credential_form_schemas:
- variable: openai_api_key
label:
en_US: API Key
type: secret-input
required: true
placeholder:
zh_Hans: 在此输入你的 API Key
en_US: Enter your API Key
- variable: openai_organization
label:
zh_Hans: 组织 ID
en_US: Organization
type: text-input
required: false
placeholder:
zh_Hans: 在此输入你的组织 ID
en_US: Enter your Organization ID
# Additional fields as needed...
```
For the complete model provider YAML specification, see [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema).
### 3.2 Write the Model Provider Code
Next, create a Python file for your provider class in the `/provider` directory, named after your provider (e.g., `anthropic.py`).
The provider class must inherit from `ModelProvider` and implement at least the `validate_provider_credentials` method:
```python theme={null}
import logging
from dify_plugin.entities.model import ModelType
from dify_plugin.errors.model import CredentialsValidateFailedError
from dify_plugin import ModelProvider
logger = logging.getLogger(__name__)
class AnthropicProvider(ModelProvider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
Validate provider credentials by testing them against the API.
This method should attempt to make a simple API call to verify
that the credentials are valid.
:param credentials: Provider credentials as defined in the YAML schema
:raises CredentialsValidateFailedError: If validation fails
"""
try:
# Get an instance of the LLM model type and use it to validate credentials
model_instance = self.get_model_instance(ModelType.LLM)
model_instance.validate_credentials(
model="claude-3-opus-20240229",
credentials=credentials
)
except CredentialsValidateFailedError as ex:
# Pass through credential validation errors
raise ex
except Exception as ex:
# Log and re-raise other exceptions
logger.exception(f"{self.get_provider_schema().provider} credentials validate failed")
raise ex
```
Dify calls `validate_provider_credentials` whenever a user saves provider credentials, so it should:
1. Attempt to validate the credentials by making a simple API call.
2. Return silently if validation succeeds.
3. Raise `CredentialsValidateFailedError` with a helpful message if validation fails.
#### For Custom Model Providers
For providers that exclusively use custom models (where each model requires its own configuration), you can implement a simpler provider class. For example, with Xinference:
```python theme={null}
from dify_plugin import ModelProvider
class XinferenceProvider(ModelProvider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
For custom-only model providers, validation happens at the model level.
This method exists to satisfy the abstract base class requirement.
"""
pass
```
## Step 4: Implement Model-Specific Code
After setting up your provider, implement the model-specific code that handles API calls for each model type you support. This involves:
1. Creating model configuration YAML files for each specific model.
2. Implementing the model type classes that handle API communication.
For detailed instructions, see:
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): Standards for integrating predefined models.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Standards for model configuration files.
### 4.1 Define Model Configuration (YAML)
For each specific model, create a YAML file in the appropriate model type directory (e.g., `models/llm/`) to define its properties, parameters, and features.
**Example (`claude-3-5-sonnet-20240620.yaml`)**:
```yaml theme={null}
model: claude-3-5-sonnet-20240620 # API identifier for the model
label:
en_US: claude-3-5-sonnet-20240620 # Display name in UI
model_type: llm # Must match directory type
features: # Special capabilities
- agent-thought
- vision
- tool-call
- stream-tool-call
- document
model_properties: # Inherent model properties
mode: chat # "chat" or "completion"
context_size: 200000 # Maximum context window
parameter_rules: # User-adjustable parameters
- name: temperature
use_template: temperature # Reference predefined template
- name: top_p
use_template: top_p
- name: max_tokens
use_template: max_tokens
required: true
default: 8192
min: 1
max: 8192
pricing: # Optional pricing information
input: '3.00'
output: '15.00'
unit: '0.000001' # Per million tokens
currency: USD
```
### 4.2 Implement Model Calling Code (Python)
Create a Python file for each model type you support (e.g., `llm.py` in the `models/llm/` directory). This class handles API communication, parameter transformation, and result formatting.
Here's an example implementation structure for an LLM:
```python theme={null}
import logging
from typing import Union, Generator, Optional, List
from dify_plugin.provider_kits.llm import LargeLanguageModel # Base class
from dify_plugin.provider_kits.llm import LLMResult, LLMResultChunk, LLMUsage # Result classes
from dify_plugin.provider_kits.llm import PromptMessage, PromptMessageTool # Message classes
from dify_plugin.errors.provider_error import InvokeError, InvokeAuthorizationError # Error classes
logger = logging.getLogger(__name__)
class MyProviderLargeLanguageModel(LargeLanguageModel):
def _invoke(self, model: str, credentials: dict, prompt_messages: List[PromptMessage],
model_parameters: dict, tools: Optional[List[PromptMessageTool]] = None,
stop: Optional[List[str]] = None, stream: bool = True,
user: Optional[str] = None) -> Union[LLMResult, Generator[LLMResultChunk, None, None]]:
"""
Core method for invoking the model API.
Parameters:
model: The model identifier to call
credentials: Authentication credentials
prompt_messages: List of messages to send
model_parameters: Parameters like temperature, max_tokens
tools: Optional tool definitions for function calling
stop: Optional list of stop sequences
stream: Whether to stream responses (True) or return complete response (False)
user: Optional user identifier for API tracking
Returns:
If stream=True: Generator yielding LLMResultChunk objects
If stream=False: Complete LLMResult object
"""
# Prepare API request parameters
api_params = self._prepare_api_params(
credentials, model_parameters, prompt_messages, tools, stop
)
try:
# Call appropriate helper method based on streaming preference
if stream:
return self._invoke_stream(model, api_params, user)
else:
return self._invoke_sync(model, api_params, user)
except Exception as e:
# Handle and map errors
self._handle_api_error(e)
def _invoke_stream(self, model: str, api_params: dict, user: Optional[str]) -> Generator[LLMResultChunk, None, None]:
"""Helper method for streaming API calls"""
# Implementation details for streaming calls
pass
def _invoke_sync(self, model: str, api_params: dict, user: Optional[str]) -> LLMResult:
"""Helper method for synchronous API calls"""
# Implementation details for synchronous calls
pass
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate that the credentials work for this specific model.
Called when a user tries to add or modify credentials.
"""
# Implementation for credential validation
pass
def get_num_tokens(self, model: str, credentials: dict,
prompt_messages: List[PromptMessage],
tools: Optional[List[PromptMessageTool]] = None) -> int:
"""
Estimate the number of tokens for given input.
Optional but recommended for accurate cost estimation.
"""
# Implementation for token counting
pass
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Define mapping from vendor-specific exceptions to Dify standard exceptions.
This helps standardize error handling across different providers.
"""
return {
InvokeAuthorizationError: [
# List vendor-specific auth errors here
],
# Other error mappings
}
```
The most important method to implement is `_invoke`, which handles the core API communication. This method should:
1. Transform Dify's standardized inputs into the format required by the provider's API.
2. Make the API call with proper error handling.
3. Transform the API response into Dify's standardized output format.
4. Handle both streaming and non-streaming modes.
## Step 5: Debug and Test Your Plugin
Dify supports remote debugging, so you can test your plugin during development:
1. In your Dify instance, go to **Plugin Management** and click **Debug Plugin** to get your debug key and server address.
2. Configure your local environment with these values in a `.env` file:
```dotenv theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=<your-dify-host>:5003
REMOTE_INSTALL_KEY=****-****-****-****-****
```
3. Run your plugin locally with `python -m main` and test it in Dify.
## Step 6: Package and Publish
When your plugin is ready:
1. Package it using the scaffolding tool:
```bash theme={null}
dify plugin package models/<provider_name>
```
2. Test the packaged plugin locally before submitting.
3. Submit a pull request to the [Dify official plugins repository](https://github.com/langgenius/dify-official-plugins).
For more details on the publishing process, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Reference Resources
* [Quick Integration of a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): How to add new models to existing providers.
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin): Return to the plugin development getting started guide.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Detailed model configuration specifications.
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Plugin manifest file configuration.
* [Dify Plugin SDK Reference](https://github.com/langgenius/dify-plugin-sdks): Base classes, data structures, and error types.
# Data Source Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin
Build a Dify 1.9.0+ data source plugin that feeds documents into the knowledge pipeline
Data source plugins, introduced in Dify 1.9.0, supply documents to a knowledge pipeline and serve as the starting point for the entire pipeline.
This guide covers the plugin architecture, code examples, and debugging methods you need to build and launch a data source plugin.
## Prerequisites
You should have a basic understanding of the knowledge pipeline and plugin development:
* [Step 2: Knowledge Pipeline Orchestration](/en/cloud/use-dify/knowledge/knowledge-pipeline/knowledge-pipeline-orchestration)
* [Dify Plugin Development: Hello World Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)
## Data Source Plugin Types
Dify supports three types of data source plugins: web crawler, online document, and online drive. Each type corresponds to a different parent class, and the class that implements your plugin's functionality must inherit from it.
<Info>
To learn how to inherit from a parent class to implement plugin functionality, see [Tool Plugin: Write the Tool Code](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin#4-write-the-tool-code).
</Info>
Each data source plugin type supports multiple data sources. For example:
* **Web Crawler**: Jina Reader, FireCrawl
* **Online Document**: Notion, Confluence, GitHub
* **Online Drive**: OneDrive, Google Drive, Box, AWS S3, Tencent COS
The relationship between data source types and data source plugin types is illustrated below.
<Frame>
<img alt="Data Source Type" />
</Frame>
## Develop a Data Source Plugin
### Create a Data Source Plugin
Create a data source plugin with the scaffolding command-line tool by selecting the `datasource` type. After you complete the setup, the tool generates the plugin project code.
```bash theme={null}
dify plugin init
```
<Frame>
<img alt="Datasource Plugin Init" />
</Frame>
<Info>
Typically, a data source plugin does not need to use other features of the Dify platform, so no additional permissions are required.
</Info>
#### Data Source Plugin Structure
A data source plugin consists of three main components:
* The `manifest.yaml` file: Describes the basic information about the plugin.
* The `provider` directory: Contains the plugin provider's description and authentication implementation code.
* The `datasources` directory: Contains the description and core logic for fetching data from the data source.
```text theme={null}
├── _assets
│ └── icon.svg
├── datasources
│ ├── your_datasource.py
│ └── your_datasource.yaml
├── main.py
├── manifest.yaml
├── PRIVACY.md
├── provider
│ ├── your_datasource.py
│ └── your_datasource.yaml
├── README.md
└── requirements.txt
```
#### Set the Correct Version and Tag
* In the `manifest.yaml` file, set the minimum supported Dify version:
```yaml theme={null}
minimum_dify_version: 1.9.0
```
* In the same file, add the following tag so the plugin appears under the data source category in the Dify Marketplace:
```yaml theme={null}
tags:
- rag
```
* In the `requirements.txt` file, set the plugin SDK version:
```text theme={null}
dify-plugin>=0.5.0,<0.6.0
```
### Add the Data Source Provider
#### Create the Provider YAML File
The content of a provider YAML file is essentially the same as that for tool plugins, with only the following two differences:
```yaml theme={null}
# Specify the provider type for the data source plugin: online_drive, online_document, or website_crawl
provider_type: online_drive # online_document, website_crawl
# Specify data sources
datasources:
- datasources/PluginName.yaml
```
<Info>
For more about creating a provider YAML file, see [Tool Plugin: Add Third-Party Service Credentials](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin#2-add-third-party-service-credentials).
</Info>
<Info>
Data source plugins support authentication via OAuth 2.0 or API Key.
To configure OAuth, see [Add OAuth Support to Your Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth).
</Info>
#### Create the Provider Code File
* With API Key authentication, the provider code file is identical to that of a tool plugin. You only need to change the provider class's parent class to `DatasourceProvider`.
```python theme={null}
class YourDatasourceProvider(DatasourceProvider):
def _validate_credentials(self, credentials: Mapping[str, Any]) -> None:
try:
"""
IMPLEMENT YOUR VALIDATION HERE
"""
except Exception as e:
raise ToolProviderCredentialValidationError(str(e))
```
* With OAuth authentication, data source plugins differ slightly from tool plugins: when obtaining access via OAuth, they can also return the username and avatar to display on the frontend. `_oauth_get_credentials` and `_oauth_refresh_credentials` must therefore return a `DatasourceOAuthCredentials` object containing `name`, `avatar_url`, `expires_at`, and `credentials`.
The `DatasourceOAuthCredentials` class is defined as follows:
```python theme={null}
class DatasourceOAuthCredentials(BaseModel):
name: str | None = Field(None, description="The name of the OAuth credential")
avatar_url: str | None = Field(None, description="The avatar url of the OAuth")
credentials: Mapping[str, Any] = Field(..., description="The credentials of the OAuth")
expires_at: int | None = Field(
default=-1,
description="""The expiration timestamp (in seconds since Unix epoch, UTC) of the credentials.
Set to -1 or None if the credentials do not expire.""",
)
```
The function signatures for `_oauth_get_authorization_url`, `_oauth_get_credentials`, and `_oauth_refresh_credentials` are as follows:
<Tabs>
<Tab title="_oauth_get_authorization_url">
```python theme={null}
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
"""
Generate the authorization URL for {{ .PluginName }} OAuth.
"""
try:
"""
IMPLEMENT YOUR AUTHORIZATION URL GENERATION HERE
"""
except Exception as e:
raise DatasourceOAuthError(str(e))
return ""
```
</Tab>
<Tab title="_oauth_get_credentials">
```python theme={null}
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> DatasourceOAuthCredentials:
"""
Exchange code for access_token.
"""
try:
"""
IMPLEMENT YOUR CREDENTIALS EXCHANGE HERE
"""
except Exception as e:
raise DatasourceOAuthError(str(e))
return DatasourceOAuthCredentials(
name="",
avatar_url="",
expires_at=-1,
credentials={},
)
```
</Tab>
<Tab title="_oauth_refresh_credentials">
```python theme={null}
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> DatasourceOAuthCredentials:
"""
Refresh the credentials
"""
return DatasourceOAuthCredentials(
name="",
avatar_url="",
expires_at=-1,
credentials={},
)
```
</Tab>
</Tabs>
### Add the Data Source
The YAML file format and data source code format vary across the three types of data sources.
#### Web Crawler
In the provider YAML file for a web crawler data source plugin, `output_schema` must always return four parameters: `source_url`, `content`, `title`, and `description`.
```yaml theme={null}
output_schema:
type: object
properties:
source_url:
type: string
description: the source url of the website
content:
type: string
description: the content from the website
title:
type: string
description: the title of the website
"description":
type: string
description: the description of the website
```
In the main logic code for a web crawler plugin, the class must inherit from `WebsiteCrawlDatasource` and implement the `_get_website_crawl` method, using the `create_crawl_message` method to return the crawl results.
To crawl multiple web pages and return them in batches, set `WebSiteInfo.status` to `processing` and call `create_crawl_message` for each batch of crawled pages. After all pages have been crawled, set `WebSiteInfo.status` to `completed`.
```python theme={null}
class YourDataSource(WebsiteCrawlDatasource):
def _get_website_crawl(
self, datasource_parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
crawl_res = WebSiteInfo(web_info_list=[], status="", total=0, completed=0)
crawl_res.status = "processing"
yield self.create_crawl_message(crawl_res)
### your crawl logic
...
crawl_res.status = "completed"
crawl_res.web_info_list = [
WebSiteInfoDetail(
title="",
source_url="",
description="",
content="",
)
]
crawl_res.total = 1
crawl_res.completed = 1
yield self.create_crawl_message(crawl_res)
```
#### Online Document
The return value for an online document data source plugin must include at least a `content` field to represent the document's content. For example:
```yaml theme={null}
output_schema:
type: object
properties:
workspace_id:
type: string
description: workspace id
page_id:
type: string
description: page id
content:
type: string
description: page content
```
In the main logic code for an online document plugin, the class must inherit from `OnlineDocumentDatasource` and implement two methods: `_get_pages` and `_get_content`.
When a user runs the plugin, it first calls the `_get_pages` method to retrieve a list of documents. After the user selects a document from the list, it then calls the `_get_content` method to fetch the document's content.
<Tabs>
<Tab title="_get_pages">
```python theme={null}
def _get_pages(self, datasource_parameters: dict[str, Any]) -> DatasourceGetPagesResponse:
# your get pages logic
response = requests.get(url, headers=headers, params=params, timeout=30)
pages = []
for item in response.json().get("results", []):
page = OnlineDocumentPage(
page_name=item.get("title", ""),
page_id=item.get("id", ""),
type="page",
last_edited_time=item.get("version", {}).get("createdAt", ""),
parent_id=item.get("parentId", ""),
page_icon=None,
)
pages.append(page)
online_document_info = OnlineDocumentInfo(
workspace_name=workspace_name,
workspace_icon=workspace_icon,
workspace_id=workspace_id,
pages=[page],
total=pages.length(),
)
return DatasourceGetPagesResponse(result=[online_document_info])
```
</Tab>
<Tab title="_get_content">
```python theme={null}
def _get_content(self, page: GetOnlineDocumentPageContentRequest) -> Generator[DatasourceMessage, None, None]:
# your fetch content logic, example
response = requests.get(url, headers=headers, params=params, timeout=30)
...
yield self.create_variable_message("content", "")
yield self.create_variable_message("page_id", "")
yield self.create_variable_message("workspace_id", "")
```
</Tab>
</Tabs>
#### Online Drive
An online drive data source plugin returns a file, so it must adhere to the following specification:
```yaml theme={null}
output_schema:
type: object
properties:
file:
$ref: "https://dify.ai/schemas/v1/file.json"
```
In the main logic code for an online drive plugin, the class must inherit from `OnlineDriveDatasource` and implement two methods: `_browse_files` and `_download_file`.
When a user runs the plugin, it first calls `_browse_files` to get a file list. At this point, `prefix` is empty, indicating a request for the root directory's file list. The list contains both folder and file entries. If the user opens a folder, `_browse_files` is called again, and the `prefix` in `OnlineDriveBrowseFilesRequest` is the folder ID used to retrieve the file list within that folder.
After a user selects a file, the plugin uses the `_download_file` method and the file ID to get the file's content. You can use the `_get_mime_type_from_filename` method to get the file's MIME type, allowing the pipeline to handle different file types appropriately.
When the file list contains multiple files, you can set `OnlineDriveFileBucket.is_truncated` to `True` and `OnlineDriveFileBucket.next_page_parameters` to the parameters needed to fetch the next page, such as the next page's request ID or URL, depending on the service provider.
<Tabs>
<Tab title="_browse_files">
```python theme={null}
def _browse_files(
self, request: OnlineDriveBrowseFilesRequest
) -> OnlineDriveBrowseFilesResponse:
credentials = self.runtime.credentials
bucket_name = request.bucket
prefix = request.prefix or "" # Allow empty prefix for root folder; When you browse the folder, the prefix is the folder id
max_keys = request.max_keys or 10
next_page_parameters = request.next_page_parameters or {}
files = []
files.append(OnlineDriveFile(
id="",
name="",
size=0,
type="folder" # or "file"
))
return OnlineDriveBrowseFilesResponse(result=[
OnlineDriveFileBucket(
bucket="",
files=files,
is_truncated=False,
next_page_parameters={}
)
])
```
</Tab>
<Tab title="_download_file">
```python theme={null}
def _download_file(self, request: OnlineDriveDownloadFileRequest) -> Generator[DatasourceMessage, None, None]:
credentials = self.runtime.credentials
file_id = request.id
file_content = bytes()
file_name = ""
mime_type = self._get_mime_type_from_filename(file_name)
yield self.create_blob_message(file_content, meta={
"file_name": file_name,
"mime_type": mime_type
})
def _get_mime_type_from_filename(self, filename: str) -> str:
"""Determine MIME type from file extension."""
import mimetypes
mime_type, _ = mimetypes.guess_type(filename)
return mime_type or "application/octet-stream"
```
</Tab>
</Tabs>
For storage services like AWS S3, the `prefix`, `bucket`, and `id` variables have special uses and can be applied flexibly as needed during development:
* `prefix`: Represents the file path prefix. For example, `prefix=container1/folder1/` retrieves the files or file list from the `folder1` folder in the `container1` bucket.
* `bucket`: Represents the file bucket. For example, `bucket=container1` retrieves the files or file list in the `container1` bucket. This field can be left blank for non-standard S3 protocol drives.
* `id`: Since the `_download_file` method does not use the `prefix` variable, the full file path must be included in the `id`. For example, `id=container1/folder1/file1.txt` indicates retrieving the `file1.txt` file from the `folder1` folder in the `container1` bucket.
<Tip>
For reference implementations, see the [official Google Drive plugin](https://github.com/langgenius/dify-official-plugins/blob/main/datasources/google_cloud_storage/datasources/google_cloud_storage.py) and the [official AWS S3 plugin](https://github.com/langgenius/dify-official-plugins/blob/main/datasources/aws_s3_storage/datasources/aws_s3_storage.py).
</Tip>
## Debug the Plugin
Data source plugins support two debugging methods: remote debugging and installing the plugin locally. Note the following:
* If the plugin uses OAuth authentication, the `redirect_uri` for remote debugging differs from that of a local plugin. Update the relevant configuration in your service provider's OAuth App accordingly.
* While data source plugins support single-step debugging, we still recommend testing them in a complete knowledge pipeline to ensure full functionality.
## Final Checks
Before packaging and publishing, make sure you've completed all of the following:
* Set the minimum supported Dify version to `1.9.0`.
* Set the SDK version to `dify-plugin>=0.5.0,<0.6.0`.
* Write the `README.md` and `PRIVACY.md` files.
* Include only English content in the code files.
* Replace the default icon with the data source provider's logo.
## Package and Publish
In the plugin directory, run the following command to generate a `.difypkg` plugin package:
```bash theme={null}
dify plugin package . -o your_datasource.difypkg
```
Next, you can:
* Import and use the plugin in your Dify environment.
* Publish the plugin to Dify Marketplace by submitting a pull request.
<Info>
For the plugin publishing process, see [Publishing Plugins](/en/develop-plugin/publishing/marketplace-listing/release-overview).
</Info>
# Slack Bot
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin
Build a Slack Bot plugin that connects a Dify app to Slack, from project setup through debugging and packaging
In this guide, you'll build an AI-powered Slack Bot that answers user questions right inside Slack. If you haven't developed a plugin before, read the [Plugin Development Quick Start Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) first.
## Project Background
A Slack Bot plugin lets your team chat with an LLM directly in Slack, putting AI where conversations already happen.
Slack is an open, real-time communication platform with a robust API, including a webhook-based event system that is straightforward to build on. This guide uses that system to create the Slack Bot plugin, illustrated in the diagram below:
<Frame>

</Frame>
<Note>
Two similar terms appear throughout this guide:
* **Slack Bot**: A chatbot on the Slack platform—a virtual user you can interact with in real time.
* **Slack Bot plugin**: A plugin in the Dify Marketplace that connects a Dify application with Slack. This guide shows you how to build it.
</Note>
### How It Works
1. **A user messages the Slack Bot**
When a user in Slack sends a message to the Bot, the Slack Bot immediately issues a webhook request to the Dify platform.
2. **Slack forwards the message to the Slack Bot plugin**
The Dify platform triggers the Slack Bot plugin, which relays the message to the Dify application—much like an email system delivering to a recipient's address. You establish this connection by setting up a Slack webhook address through Slack's API and entering it in the plugin. The plugin processes the Slack request and forwards it to the Dify application, where the LLM analyzes the input and generates a response.
3. **The plugin returns the response to Slack**
Once the plugin receives the reply from the Dify application, it sends the LLM's answer back along the same route to the Slack Bot, so users get the response right where they're chatting.
## Prerequisites
* **Dify plugin development tool**: See [Initializing the Development Tool](/en/develop-plugin/getting-started/cli).
* **Python environment (version 3.12)**: See the [Python official downloads page](https://www.python.org/downloads/).
* **A Slack App with an OAuth token**: See the steps below.
To create the Slack App, go to the [Slack API platform](https://api.slack.com/apps), create an app from scratch, and pick the workspace where it will be deployed.
<Frame>

</Frame>
1. **Enable Webhooks**:
<Frame>

</Frame>
2. **Install the App in Your Slack Workspace**:
<Frame>

</Frame>
3. **Obtain an OAuth Token** for plugin development:
<Frame>

</Frame>
## 1. Develop the Plugin
Before you start coding, make sure you've read [Quick Start: Developing an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) or have built a Dify plugin before.
### 1.1 Initialize the Project
Run the following command to set up your plugin development environment:
```bash theme={null}
dify plugin init
```
Follow the prompts to provide basic project info. Select the `extension` template, and grant both `Apps` and `Endpoints` permissions.
For additional details on reverse-invoking Dify services within a plugin, see [Reverse Invocation: App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app).
<Frame>

</Frame>
### 1.2 Edit the Configuration Form
The plugin needs two pieces of information: which Dify app handles the replies, and the Slack App token that authenticates the bot's responses. Add both fields to the plugin's form.
Modify the YAML file in the `group` directory (for example, `group/slack.yaml`). The form's filename comes from the information you provided when creating the plugin, so adjust the path accordingly.
**Sample Code**:
`slack.yaml`
```yaml theme={null}
settings:
- name: bot_token
type: secret-input
required: true
label:
en_US: Bot Token
zh_Hans: Bot Token
pt_BR: Token do Bot
ja_JP: Bot Token
placeholder:
en_US: Please input your Bot Token
zh_Hans: 请输入你的 Bot Token
pt_BR: Por favor, insira seu Token do Bot
ja_JP: ボットトークンを入力してください
- name: allow_retry
type: boolean
required: false
label:
en_US: Allow Retry
zh_Hans: 允许重试
pt_BR: Permitir Retentativas
ja_JP: 再試行を許可
default: false
- name: app
type: app-selector
required: true
label:
en_US: App
zh_Hans: 应用
pt_BR: App
ja_JP: アプリ
placeholder:
en_US: the app you want to use to answer Slack messages
zh_Hans: 你想要用来回答 Slack 消息的应用
pt_BR: o app que você deseja usar para responder mensagens do Slack
ja_JP: あなたが Slack メッセージに回答するために使用するアプリ
endpoints:
- endpoints/slack.yaml
```
Two configuration fields deserve a closer look:
```yaml theme={null}
- name: app
type: app-selector
scope: chat
```
* **`type`**: Set to `app-selector`, which lets users forward messages to a specific Dify app when using this plugin.
* **`scope`**: Set to `chat`, meaning the plugin can only interact with app types such as agent, chatbot, or Chatflow.
Finally, in the `endpoints/slack.yaml` file, change the request method to `POST` so the endpoint can handle incoming Slack messages.
**Sample Code**:
`endpoints/slack.yaml`
```yaml theme={null}
path: "/"
method: "POST"
extra:
python:
source: "endpoints/slack.py"
```
## 2. Edit the Function Code
Modify the `endpoints/slack.py` file and add the following code:
```python theme={null}
import json
import traceback
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
from slack_sdk import WebClient
from slack_sdk.errors import SlackApiError
class SlackEndpoint(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
retry_num = r.headers.get("X-Slack-Retry-Num")
if (not settings.get("allow_retry") and (r.headers.get("X-Slack-Retry-Reason") == "http_timeout" or ((retry_num is not None and int(retry_num) > 0)))):
return Response(status=200, response="ok")
data = r.get_json()
# Handle Slack URL verification challenge
if data.get("type") == "url_verification":
return Response(
response=json.dumps({"challenge": data.get("challenge")}),
status=200,
content_type="application/json"
)
if (data.get("type") == "event_callback"):
event = data.get("event")
if (event.get("type") == "app_mention"):
message = event.get("text", "")
if message.startswith("<@"):
message = message.split("> ", 1)[1] if "> " in message else message
channel = event.get("channel", "")
blocks = event.get("blocks", [])
blocks[0]["elements"][0]["elements"] = blocks[0].get("elements")[0].get("elements")[1:]
token = settings.get("bot_token")
client = WebClient(token=token)
try:
response = self.session.app.chat.invoke(
app_id=settings["app"]["app_id"],
query=message,
inputs={},
response_mode="blocking",
)
try:
blocks[0]["elements"][0]["elements"][0]["text"] = response.get("answer")
result = client.chat_postMessage(
channel=channel,
text=response.get("answer"),
blocks=blocks
)
return Response(
status=200,
response=json.dumps(result),
content_type="application/json"
)
except SlackApiError as e:
raise e
except Exception as e:
err = traceback.format_exc()
return Response(
status=200,
response="Sorry, I'm having trouble processing your request. Please try again later." + str(err),
content_type="text/plain",
)
else:
return Response(status=200, response="ok")
else:
return Response(status=200, response="ok")
else:
return Response(status=200, response="ok")
```
## 3. Debug the Plugin
Go to the Dify platform and obtain the remote debugging address and key for your plugin.
<Frame>

</Frame>
Back in your plugin project, copy the `.env.example` file, rename it to `.env`, and fill in the debugging details:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Start the plugin:
```bash theme={null}
python -m main
```
You should now see the plugin installed in your Workspace on Dify's plugin management page, where other team members can also access it.
### Configure the Plugin Endpoint
On Dify's plugin management page, locate the newly installed test plugin and create a new endpoint. Enter a name and your **Bot Token**, then select the app you want to connect.
<Frame>

</Frame>
After saving, a **POST** request URL is generated:
<Frame>

</Frame>
Next, complete the Slack App setup:
1. **Enable Event Subscriptions**
<Frame>

</Frame>
Paste the POST request URL you generated above.
<Frame>

</Frame>
2. **Grant Required Permissions**
<Frame>

</Frame>
***
## 4. Verify the Plugin
The plugin calls the Dify application through `self.session.app.chat.invoke`, passing in parameters such as `app_id` and `query`, and returns the response to the Slack Bot. Run `python -m main` again to restart the plugin, then check that Slack displays the Dify app's reply:
<Frame>

</Frame>
***
## 5. Package the Plugin (Optional)
Once you confirm the plugin works correctly, package it with the following command. The command produces a `slack_bot.difypkg` file in the current directory—your final plugin package. For detailed packaging steps, see [Package as a Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file).
```bash theme={null}
# Replace ./slack_bot with your actual plugin project path.
dify plugin package ./slack_bot
```
Congratulations—you've developed, tested, and packaged a plugin!
***
## 6. Publish the Plugin (Optional)
You can now upload it to the [Dify Marketplace repository](https://github.com/langgenius/dify-plugins) for public release. Before publishing, ensure your plugin meets the [Publishing to Dify Marketplace Guidelines](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). Once approved, your code is merged into the main branch, and the plugin goes live on the [Dify Marketplace](https://marketplace.dify.ai/).
***
## Related Resources
* [Plugin Development Basics](/en/develop-plugin/getting-started/getting-started-dify-plugin): Comprehensive overview of Dify plugin development
* [Plugin Development Quick Start Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin): Start developing plugins from scratch
* [Develop an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Extension plugin development
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): How to call Dify platform capabilities
* [Reverse Invocation: App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app): How to call apps within the platform
* [Publishing Plugins](/en/develop-plugin/publishing/marketplace-listing/release-overview): The publishing process
* [Publishing to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace): Marketplace publishing guide
* [Endpoint Detailed Definition](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Endpoint reference
## Further Reading
For a complete Dify plugin project example, visit the [GitHub repository](https://github.com/langgenius/dify-plugins). You'll also find additional plugins with full source code and implementation details.
To explore more about plugin development, see the following:
**Quick Starts**:
* [Develop an Extension Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint)
* [Develop a Model Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)
* [Bundle Plugins: Packaging Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
**Plugin Interface Docs**:
* [Defining Plugin Information via Manifest File](/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest): Manifest structure
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Endpoint reference
* [Reverse Invocation](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Calling Dify capabilities from a plugin
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Tool specifications
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Model schema reference
# Flomo Tool (10-min)
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-flomo-plugin
Build a functional Dify tool plugin that connects to the Flomo note-taking service end-to-end in about ten minutes
## What You'll Build
By the end of this guide, you'll have created a Dify plugin that:
* Connects to the Flomo note-taking API
* Allows users to save notes from AI conversations directly to Flomo
* Handles authentication and error states properly
* Is ready for distribution in the Dify Marketplace
<CardGroup>
<Card title="Time required" icon="clock">
10 minutes
</Card>
<Card title="Prerequisites" icon="list-check">
Basic Python knowledge and a Flomo account
</Card>
</CardGroup>
## Step 1: Install the Dify Plugin CLI and Create a Project
<Steps>
<Step title="Install Dify Plugin CLI">
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Download the latest binary from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases). Pick `dify-plugin-linux-amd64` for x86\_64 or `dify-plugin-linux-arm64` for ARM.
```bash theme={null}
chmod +x dify-plugin-linux-amd64
sudo mv dify-plugin-linux-amd64 /usr/local/bin/dify
```
</Tab>
</Tabs>
Verify the installation:
```bash theme={null}
dify version
```
</Step>
<Step title="Initialize a plugin project">
Create a new plugin project using:
```bash theme={null}
dify plugin init
```
Follow the prompts to set up your plugin:
* Name it `flomo`
* Select `tool` as the plugin type
* Complete the other required fields
</Step>
<Step title="Navigate to the project">
```bash theme={null}
cd flomo
```
The project contains the basic structure for your plugin with all necessary files.
</Step>
</Steps>
## Step 2: Define Your Plugin Manifest
<Info>
The `manifest.yaml` file defines your plugin's metadata, permissions, and capabilities.
</Info>
Create a `manifest.yaml` file:
```yaml theme={null}
version: 0.0.4
type: plugin
author: yourname
label:
en_US: Flomo
zh_Hans: Flomo 浮墨笔记
created_at: "2023-10-01T00:00:00Z"
icon: icon.png
resource:
memory: 67108864 # 64MB
permission:
storage:
enabled: false
plugins:
tools:
- provider/flomo.yaml
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: 3.12
entrypoint: main
```
## Step 3: Create the Tool Definition
A tool plugin uses two YAML files: a **provider** file that declares credentials and lists the tools, and one **tool** file per callable tool. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the full schema.
Create `provider/flomo.yaml`:
```yaml theme={null}
identity:
author: yourname
name: flomo
label:
en_US: Flomo Note
zh_Hans: Flomo 浮墨笔记
description:
en_US: Add notes to your Flomo account directly from Dify.
zh_Hans: 直接从 Dify 添加笔记到您的 Flomo 账户。
icon: icon.png
credentials_for_provider:
api_url:
type: secret-input
required: true
label:
en_US: API URL
zh_Hans: API URL
placeholder:
en_US: https://flomoapp.com/iwh/{token}/{secret}/
help:
en_US: Flomo API URL from your Flomo account settings.
zh_Hans: 从您的 Flomo 账户设置中获取的 API URL。
tools:
- tools/flomo.yaml
extra:
python:
source: provider/flomo.py
```
Create `tools/flomo.yaml`:
```yaml theme={null}
identity:
name: flomo
author: yourname
label:
en_US: Save to Flomo
zh_Hans: 保存到 Flomo
description:
human:
en_US: Save the conversation content as a Flomo note.
zh_Hans: 将对话内容保存为 Flomo 笔记。
llm: >
Saves content to the user's Flomo account. Use this tool when the user
asks to save, capture, or remember the current message. Takes a single
`content` parameter containing the text to save.
parameters:
- name: content
type: string
required: true
label:
en_US: Note content
zh_Hans: 笔记内容
human_description:
en_US: Content to save as a note in Flomo.
zh_Hans: 要保存为 Flomo 笔记的内容。
llm_description: The text to save as a Flomo note.
form: llm
extra:
python:
source: tools/flomo.py
```
## Step 4: Implement Core Utility Functions
Create a utility module in `utils/flomo_utils.py` for API interaction:
<CodeGroup>
```python utils/flomo_utils.py theme={null}
import requests
def send_flomo_note(api_url: str, content: str) -> None:
"""
Send a note to Flomo via the API URL. Raises requests.RequestException on network errors,
and ValueError on invalid status codes or input.
"""
api_url = api_url.strip()
if not api_url:
raise ValueError("API URL is required and cannot be empty.")
if not api_url.startswith('https://flomoapp.com/iwh/'):
raise ValueError(
"API URL should be in the format: https://flomoapp.com/iwh/{token}/{secret}/"
)
if not content:
raise ValueError("Content cannot be empty.")
headers = {'Content-Type': 'application/json'}
response = requests.post(api_url, json={"content": content}, headers=headers, timeout=10)
if response.status_code != 200:
raise ValueError(f"API URL is not valid. Received status code: {response.status_code}")
```
</CodeGroup>
## Step 5: Implement the Tool Provider
The Tool Provider handles credential validation. Create `provider/flomo.py`:
<CodeGroup>
```python provider/flomo.py theme={null}
from typing import Any
from dify_plugin import ToolProvider
from dify_plugin.errors.tool import ToolProviderCredentialValidationError
import requests
from utils.flomo_utils import send_flomo_note
class FlomoProvider(ToolProvider):
def _validate_credentials(self, credentials: dict[str, Any]) -> None:
try:
api_url = credentials.get('api_url', '').strip()
# Use utility for validation and sending test note
send_flomo_note(api_url, "Hello, #flomo https://flomoapp.com")
except ValueError as e:
raise ToolProviderCredentialValidationError(str(e))
except requests.RequestException as e:
raise ToolProviderCredentialValidationError(f"Connection error: {str(e)}")
```
</CodeGroup>
## Step 6: Implement the Tool
The Tool class handles actual API calls when the user invokes the plugin. Create `tools/flomo.py`:
<CodeGroup>
```python tools/flomo.py theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
import requests
from utils.flomo_utils import send_flomo_note
class FlomoTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
content = tool_parameters.get("content", "")
api_url = self.runtime.credentials.get("api_url", "")
try:
send_flomo_note(api_url, content)
except ValueError as e:
yield self.create_text_message(str(e))
return
except requests.RequestException as e:
yield self.create_text_message(f"Connection error: {str(e)}")
return
# Return success message and structured data
yield self.create_text_message(
"Note created successfully! Your content has been sent to Flomo."
)
yield self.create_json_message({
"status": "success",
"content": content,
})
```
</CodeGroup>
<Warning>
Always handle exceptions gracefully and return user-friendly error messages. Remember that your plugin represents your brand in the Dify ecosystem.
</Warning>
## Step 7: Test Your Plugin
<Steps>
<Step title="Set up debug environment">
Copy the example environment file:
```bash theme={null}
cp .env.example .env
```
Edit the `.env` file with your Dify environment details:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=your_debug_key
```
You can find your debug URL and key in the Dify dashboard: click the **Plugins** icon in the top-right corner, then click the debug icon. Copy the **API Key** and **Host Address** (the host already includes the port).
</Step>
<Step title="Install dependencies and run">
```bash theme={null}
pip install -r requirements.txt
python -m main
```
Your plugin will connect to your Dify instance in debug mode.
</Step>
<Step title="Test functionality">
In your Dify instance, open the **Plugins** page and find your plugin (marked as **debugging**). Add your Flomo API credentials and test sending a note.
</Step>
</Steps>
## Step 8: Package and Distribute
When you're ready to share your plugin:
```bash theme={null}
dify plugin package ./
```
This creates a `plugin.difypkg` file you can upload to the Dify Marketplace.
## FAQ and Troubleshooting
<AccordionGroup title="Common issues and troubleshooting">
<Accordion title="Plugin doesn't appear in debug mode">
Make sure your `.env` file is properly configured and you're using the correct debug key.
</Accordion>
<Accordion title="API authentication errors">
Double-check your Flomo API URL format. It should be in the form: `https://flomoapp.com/iwh/{token}/{secret}/`
</Accordion>
<Accordion title="Packaging fails">
Ensure all required files are present and the `manifest.yaml` structure is valid.
</Accordion>
</AccordionGroup>
## Summary
You've built a functioning Dify plugin that connects with an external API service. The same pattern works for integrating with thousands of services—from databases and search engines to productivity tools and custom APIs.
<CardGroup>
<Card title="Documentation" icon="book">
Write your `README.md` in English (en\_US) describing functionality, setup, and usage examples
</Card>
<Card title="Localization" icon="language">
Create additional README files like `readme/README_zh_Hans.md` for other languages
</Card>
</CardGroup>
<CheckList>
<CheckListItem>
Add a privacy policy (PRIVACY.md) if publishing your plugin
</CheckListItem>
<CheckListItem>
Include comprehensive examples in documentation
</CheckListItem>
<CheckListItem>
Test thoroughly with various document sizes and formats
</CheckListItem>
</CheckList>
# Markdown Exporter
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-md-exporter
Learn how to create a plugin that exports conversations to different document formats
## What You'll Build
You'll build a practical Dify plugin that exports conversations into popular document formats. By the end, your plugin will:
* Convert markdown text to Word documents (.docx)
* Export conversations as PDF files
* Handle file creation with proper formatting
* Provide a clean user experience for document exports
<CardGroup>
<Card title="Time required" icon="clock">
15 minutes
</Card>
<Card title="Prerequisites" icon="list-check">
Basic Python knowledge and familiarity with document manipulation libraries
</Card>
</CardGroup>
## Step 1: Set Up Your Environment
<Steps>
<Step title="Install the Dify Plugin CLI">
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Get the latest Dify Plugin CLI from the [Dify GitHub releases page](https://github.com/langgenius/dify-plugin-daemon/releases).
```bash theme={null}
# Download appropriate version
chmod +x dify-plugin-linux-amd64
mv dify-plugin-linux-amd64 dify
sudo mv dify /usr/local/bin/
```
</Tab>
</Tabs>
Verify installation:
```bash theme={null}
dify version
```
</Step>
<Step title="Create the plugin project">
Initialize a new plugin project:
```bash theme={null}
dify plugin init
```
Follow the prompts:
* **Name**: `md_exporter`
* **Type**: `tool`
* Complete the remaining details as prompted.
</Step>
</Steps>
## Step 2: Define the Plugin Manifest
Create the `manifest.yaml` file to define your plugin's metadata:
```yaml theme={null}
version: 0.0.4
type: plugin
author: your_username
label:
en_US: Markdown Exporter
zh_Hans: Markdown导出工具
created_at: "2025-09-30T00:00:00Z"
icon: icon.png
resource:
memory: 134217728 # 128MB
permission:
storage:
enabled: true # We need storage for temp files
plugins:
tools:
- word_export.yaml
- pdf_export.yaml
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: 3.12
entrypoint: main
```
## Step 3: Define the Word Export Tool
Create a `word_export.yaml` file to define the Word document export tool:
```yaml theme={null}
identity:
author: your_username
name: word_export
label:
en_US: Export to Word
zh_Hans: 导出为Word文档
description:
human:
en_US: Export conversation content to a Word document (.docx)
zh_Hans: 将对话内容导出为Word文档(.docx)
llm: >
A tool that converts markdown text to a Word document (.docx) format.
Use this tool when the user wants to save or export the conversation
content as a Word document. The input text should be in markdown format.
credential_schema: {} # No credentials needed
tool_schema:
markdown_content:
type: string
required: true
label:
en_US: Markdown Content
zh_Hans: Markdown内容
human_description:
en_US: The markdown content to convert to Word format
zh_Hans: 要转换为Word格式的Markdown内容
document_name:
type: string
required: false
label:
en_US: Document Name
zh_Hans: 文档名称
human_description:
en_US: Name for the exported document (without extension)
zh_Hans: 导出文档的名称(无需扩展名)
```
## Step 4: Define the PDF Export Tool
Create a `pdf_export.yaml` file for PDF exports:
```yaml theme={null}
identity:
author: your_username
name: pdf_export
label:
en_US: Export to PDF
zh_Hans: 导出为PDF文档
description:
human:
en_US: Export conversation content to a PDF document
zh_Hans: 将对话内容导出为PDF文档
llm: >
A tool that converts markdown text to a PDF document.
Use this tool when the user wants to save or export the conversation
content as a PDF file. The input text should be in markdown format.
credential_schema: {} # No credentials needed
tool_schema:
markdown_content:
type: string
required: true
label:
en_US: Markdown Content
zh_Hans: Markdown内容
human_description:
en_US: The markdown content to convert to PDF format
zh_Hans: 要转换为PDF格式的Markdown内容
document_name:
type: string
required: false
label:
en_US: Document Name
zh_Hans: 文档名称
human_description:
en_US: Name for the exported document (without extension)
zh_Hans: 导出文档的名称(无需扩展名)
```
## Step 5: Install Required Dependencies
Create or update `requirements.txt` with the necessary libraries:
```text theme={null}
python-docx>=0.8.11
markdown>=3.4.1
weasyprint>=59.0
beautifulsoup4>=4.12.2
```
## Step 6: Implement the Word Export
Create a utility module in `utils/docx_utils.py`:
<CodeGroup>
```python utils/docx_utils.py theme={null}
import os
import tempfile
import uuid
from docx import Document
from docx.shared import Pt
from docx.enum.text import WD_PARAGRAPH_ALIGNMENT
import markdown
from bs4 import BeautifulSoup
def convert_markdown_to_docx(markdown_text, document_name=None):
"""
Convert markdown text to a Word document and return the file path
"""
if not document_name:
document_name = f"exported_document_{uuid.uuid4().hex[:8]}"
# Convert markdown to HTML
html = markdown.markdown(markdown_text)
soup = BeautifulSoup(html, 'html.parser')
# Create a new Word document
doc = Document()
# Process HTML elements and add to document
for element in soup.find_all(['h1', 'h2', 'h3', 'h4', 'p', 'ul', 'ol']):
if element.name == 'h1':
heading = doc.add_heading(element.text.strip(), level=1)
heading.alignment = WD_PARAGRAPH_ALIGNMENT.CENTER
elif element.name == 'h2':
doc.add_heading(element.text.strip(), level=2)
elif element.name == 'h3':
doc.add_heading(element.text.strip(), level=3)
elif element.name == 'h4':
doc.add_heading(element.text.strip(), level=4)
elif element.name == 'p':
paragraph = doc.add_paragraph(element.text.strip())
elif element.name in ('ul', 'ol'):
for li in element.find_all('li'):
doc.add_paragraph(li.text.strip(), style='ListBullet')
# Create temp directory if it doesn't exist
temp_dir = tempfile.gettempdir()
if not os.path.exists(temp_dir):
os.makedirs(temp_dir)
# Save the document
file_path = os.path.join(temp_dir, f"{document_name}.docx")
doc.save(file_path)
return file_path
```
</CodeGroup>
## Step 7: Implement the PDF Export
Create a utility module in `utils/pdf_utils.py`:
<CodeGroup>
```python utils/pdf_utils.py theme={null}
import os
import tempfile
import uuid
import markdown
from weasyprint import HTML, CSS
from weasyprint.text.fonts import FontConfiguration
def convert_markdown_to_pdf(markdown_text, document_name=None):
"""
Convert markdown text to a PDF document and return the file path
"""
if not document_name:
document_name = f"exported_document_{uuid.uuid4().hex[:8]}"
# Convert markdown to HTML
html_content = markdown.markdown(markdown_text)
# Add basic styling
styled_html = f"""
<!DOCTYPE html>
<html>
<head>
<meta charset="UTF-8">
<title>{document_name}</title>
<style>
body {{ font-family: Arial, sans-serif; margin: 40px; line-height: 1.6; }}
h1 {{ text-align: center; color: #333; }}
h2, h3, h4 {{ color: #444; margin-top: 20px; }}
p {{ margin-bottom: 15px; }}
ul, ol {{ margin-left: 20px; }}
</style>
</head>
<body>
{html_content}
</body>
</html>
"""
# Create temp directory if it doesn't exist
temp_dir = tempfile.gettempdir()
if not os.path.exists(temp_dir):
os.makedirs(temp_dir)
# Output file path
file_path = os.path.join(temp_dir, f"{document_name}.pdf")
# Configure fonts
font_config = FontConfiguration()
# Render PDF
HTML(string=styled_html).write_pdf(
file_path,
stylesheets=[],
font_config=font_config
)
return file_path
```
</CodeGroup>
## Step 8: Create the Tool Implementations
First, create the Word export tool in `tools/word_export.py`:
<CodeGroup>
```python tools/word_export.py theme={null}
import os
import base64
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from utils.docx_utils import convert_markdown_to_docx
class WordExportTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Extract parameters
markdown_content = tool_parameters.get("markdown_content", "")
document_name = tool_parameters.get("document_name", "exported_document")
if not markdown_content:
yield self.create_text_message("Error: No content provided for export.")
return
try:
# Convert markdown to Word
file_path = convert_markdown_to_docx(markdown_content, document_name)
# Read the file as binary
with open(file_path, 'rb') as file:
file_content = file.read()
# Encode as base64
file_base64 = base64.b64encode(file_content).decode('utf-8')
# Return success message and file
yield self.create_text_message(
f"Document exported successfully as Word (.docx) format."
)
yield self.create_file_message(
file_name=f"{document_name}.docx",
file_content=file_base64,
mime_type="application/vnd.openxmlformats-officedocument.wordprocessingml.document"
)
except Exception as e:
yield self.create_text_message(f"Error exporting to Word: {str(e)}")
return
```
</CodeGroup>
Next, create the PDF export tool in `tools/pdf_export.py`:
<CodeGroup>
```python tools/pdf_export.py theme={null}
import os
import base64
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from utils.pdf_utils import convert_markdown_to_pdf
class PDFExportTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Extract parameters
markdown_content = tool_parameters.get("markdown_content", "")
document_name = tool_parameters.get("document_name", "exported_document")
if not markdown_content:
yield self.create_text_message("Error: No content provided for export.")
return
try:
# Convert markdown to PDF
file_path = convert_markdown_to_pdf(markdown_content, document_name)
# Read the file as binary
with open(file_path, 'rb') as file:
file_content = file.read()
# Encode as base64
file_base64 = base64.b64encode(file_content).decode('utf-8')
# Return success message and file
yield self.create_text_message(
f"Document exported successfully as PDF format."
)
yield self.create_file_message(
file_name=f"{document_name}.pdf",
file_content=file_base64,
mime_type="application/pdf"
)
except Exception as e:
yield self.create_text_message(f"Error exporting to PDF: {str(e)}")
return
```
</CodeGroup>
## Step 9: Create the Entrypoint
Create a `main.py` file at the root of your project:
<CodeGroup>
```python main.py theme={null}
from dify_plugin import PluginRunner
from tools.word_export import WordExportTool
from tools.pdf_export import PDFExportTool
plugin = PluginRunner(
tools=[
WordExportTool(),
PDFExportTool(),
],
providers=[] # No credential providers needed
)
```
</CodeGroup>
## Step 10: Test Your Plugin
<Steps>
<Step title="Set up your debug environment">
First, create your `.env` file from the template:
```bash theme={null}
cp .env.example .env
```
Configure it with your Dify environment details:
```dotenv theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=your_debug_key
```
</Step>
<Step title="Install dependencies">
```bash theme={null}
pip install -r requirements.txt
```
</Step>
<Step title="Start the plugin in debug mode">
```bash theme={null}
python -m main
```
</Step>
</Steps>
## Step 11: Package for Distribution
When you're ready to share your plugin:
```bash theme={null}
dify plugin package ./
```
This creates a `plugin.difypkg` file for distribution.
## Creative Use Cases
<CardGroup>
<Card title="Report generation" icon="file-lines">
Use this plugin to convert analysis summaries into professional reports for clients
</Card>
<Card title="Session documentation" icon="book">
Export coaching or consulting session notes as formatted documents
</Card>
</CardGroup>
## Beyond the Basics
Here are some interesting ways to extend this plugin:
* **Custom templates**: Add company branding or personalized styles.
* **Multi-format support**: Expand to export as HTML, Markdown, or other formats.
* **Image handling**: Process and include images from conversations.
* **Table support**: Implement proper formatting for data tables.
* **Collaborative editing**: Add integration with Google Docs or similar platforms.
<Accordion title="Technical Insights">
The core challenge in document conversion is maintaining formatting and structure. This plugin first converts markdown to HTML as an intermediate format, then processes that HTML into the target format.
The two-step process provides flexibility: you can support additional formats by adding new output modules that work with the HTML representation.
For PDF generation, the plugin uses WeasyPrint because it offers high-quality PDF rendering with CSS support. For Word documents, python-docx provides granular control over document structure.
</Accordion>
## Summary
You've built a practical plugin that lets users export conversations in professional document formats, bridging the gap between AI conversations and traditional document workflows.
<CardGroup>
<Card title="Documentation" icon="book">
Write your README.md in English (en\_US) describing functionality, setup, and usage examples
</Card>
<Card title="Localization" icon="language">
Create additional README files like `readme/README_zh_Hans.md` for other languages
</Card>
</CardGroup>
<CheckList>
<CheckListItem>
Add a privacy policy (PRIVACY.md) if publishing your plugin
</CheckListItem>
<CheckListItem>
Include comprehensive examples in documentation
</CheckListItem>
<CheckListItem>
Test thoroughly with various document sizes and formats
</CheckListItem>
</CheckList>
# Multimodal Tool
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/develop-multimodal-data-processing-tool
Configure a tool plugin to emit images, audio, or video so the Knowledge Base node can embed multimodal outputs alongside text
In knowledge pipelines, the Knowledge Base node supports input in two multimodal data formats: `multimodal-Parent-Child` and `multimodal-General`.
For the Knowledge Base node to recognize and embed a tool plugin's multimodal output (such as text, images, audio, or video), complete two configurations:
* **In the tool code file**: Call the tool session interface to upload files and construct the `files` object.
* **In the tool provider YAML file**: Declare the `output_schema` as either `multimodal-Parent-Child` or `multimodal-General`.
## Upload Files and Construct File Objects
When processing multimodal data such as images, first upload the file through Dify's tool session to obtain the file metadata.
The following example, taken from the official **Dify Extractor** plugin, shows how to upload a file and construct a `files` object.
```python theme={null}
# Upload the file using the tool session
file_res = self._tool.session.file.upload(
file_name, # filename
file_blob, # file binary data
mime_type, # MIME type, e.g., "image/png"
)
# Generate a Markdown image reference using the file preview URL
image_url = f""
```
The upload interface returns an `UploadFileResponse` object containing the file information:
```python theme={null}
from enum import Enum
from pydantic import BaseModel
class UploadFileResponse(BaseModel):
class Type(str, Enum):
DOCUMENT = "document"
IMAGE = "image"
VIDEO = "video"
AUDIO = "audio"
@classmethod
def from_mime_type(cls, mime_type: str):
if mime_type.startswith("image/"):
return cls.IMAGE
if mime_type.startswith("video/"):
return cls.VIDEO
if mime_type.startswith("audio/"):
return cls.AUDIO
return cls.DOCUMENT
id: str
name: str
size: int
extension: str
mime_type: str
type: Type | None = None
preview_url: str | None = None
```
Map the file information (`name`, `size`, `extension`, `mime_type`, and so on) to the `files` field in the multimodal output structure.
<CodeGroup>
```json multimodal_parent_child_structure highlight={22-62} expandable theme={null}
{
"$id": "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json",
"$schema": "http://json-schema.org/draft-07/schema#",
"version": "1.0.0",
"type": "object",
"title": "Multimodal Parent-Child Structure",
"description": "Schema for multimodal parent-child structure (v1)",
"properties": {
"parent_mode": {
"type": "string",
"description": "The mode of parent-child relationship"
},
"parent_child_chunks": {
"type": "array",
"items": {
"type": "object",
"properties": {
"parent_content": {
"type": "string",
"description": "The parent content"
},
"files": {
"type": "array",
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"description": "file name"
},
"size": {
"type": "number",
"description": "file size"
},
"extension": {
"type": "string",
"description": "file extension"
},
"type": {
"type": "string",
"description": "file type"
},
"mime_type": {
"type": "string",
"description": "file mime type"
},
"transfer_method": {
"type": "string",
"description": "file transfer method"
},
"url": {
"type": "string",
"description": "file url"
},
"related_id": {
"type": "string",
"description": "file related id"
}
},
"required": ["name", "size", "extension", "type", "mime_type", "transfer_method", "url", "related_id"]
},
"description": "List of files"
},
"child_contents": {
"type": "array",
"items": {
"type": "string"
},
"description": "List of child contents"
}
},
"required": ["parent_content", "child_contents"]
},
"description": "List of parent-child chunk pairs"
}
},
"required": ["parent_mode", "parent_child_chunks"]
}
```
```json multimodal_general_structure highlight={18-56} expandable theme={null}
{
"$id": "https://dify.ai/schemas/v1/multimodal_general_structure.json",
"$schema": "http://json-schema.org/draft-07/schema#",
"version": "1.0.0",
"type": "array",
"title": "Multimodal General Structure",
"description": "Schema for multimodal general structure (v1) - array of objects",
"properties": {
"general_chunks": {
"type": "array",
"items": {
"type": "object",
"properties": {
"content": {
"type": "string",
"description": "The content"
},
"files": {
"type": "array",
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"description": "file name"
},
"size": {
"type": "number",
"description": "file size"
},
"extension": {
"type": "string",
"description": "file extension"
},
"type": {
"type": "string",
"description": "file type"
},
"mime_type": {
"type": "string",
"description": "file mime type"
},
"transfer_method": {
"type": "string",
"description": "file transfer method"
},
"url": {
"type": "string",
"description": "file url"
},
"related_id": {
"type": "string",
"description": "file related id"
}
},
"description": "List of files"
}
}
},
"required": ["content"]
},
"description": "List of content and files"
}
}
}
```
</CodeGroup>
## Declare Multimodal Output Structure
Dify's official JSON schemas define the structure of multimodal data.
To let the Knowledge Base node recognize the plugin's multimodal output type, point the `result` field under `output_schema` in the plugin's provider YAML file to the corresponding official schema URL.
```yaml theme={null}
output_schema:
type: object
properties:
result:
# multimodal-Parent-Child
$ref: "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json"
# multimodal-General
# $ref: "https://dify.ai/schemas/v1/multimodal_general_structure.json"
```
For example, a complete YAML configuration using `multimodal-Parent-Child` looks like this:
```yaml expandable theme={null}
identity:
name: multimodal_tool
author: langgenius
label:
en_US: multimodal tool
zh_Hans: 多模态提取器
pt_BR: multimodal tool
description:
human:
en_US: Process documents into multimodal-Parent-Child chunk structures
zh_Hans: 将文档处理为多模态父子分块结构
pt_BR: Processar documentos em estruturas de divisão pai-filho
llm: Processes documents into hierarchical multimodal-Parent-Child chunk structures
parameters:
- name: input_text
human_description:
en_US: The text you want to chunk.
zh_Hans: 输入文本
pt_BR: Conteúdo de Entrada
label:
en_US: Input Content
zh_Hans: 输入文本
pt_BR: Conteúdo de Entrada
llm_description: The text you want to chunk.
required: true
type: string
form: llm
output_schema:
type: object
properties:
result:
$ref: "https://dify.ai/schemas/v1/multimodal_parent_child_structure.json"
extra:
python:
source: tools/parent_child_chunk.py
```
# Endpoint Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/endpoint
Define, configure, and implement HTTP Endpoints in a Dify plugin, using the Neko Cat project as an example
Endpoints are HTTP interfaces exposed by a plugin for integration with external systems. This guide explains their structure using the [Neko Cat](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/neko) project as an example. For the complete plugin code, see the [GitHub repository](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/neko).
## Group Definition
An Endpoint group is a collection of multiple Endpoints. When you create a new Endpoint in a Dify plugin, you may need to fill in the following configuration.
<Frame>

</Frame>
Besides the **Endpoint Name**, you can add form items by writing the group's configuration. After saving, you can see the multiple interfaces the group contains, all sharing the same configuration.
<Frame>

</Frame>
### Structure
* **`settings`** (map\[string] [ProviderConfig](/en/develop-plugin/features-and-specs/plugin-types/general-specifications#providerconfig)): Endpoint configuration definition.
* **`endpoints`** (list\[string], required): Points to the specific `endpoint` interface definitions.
```yaml theme={null}
settings:
api_key:
type: secret-input
required: true
label:
en_US: API key
zh_Hans: API key
ja_Jp: API key
pt_BR: API key
placeholder:
en_US: Please input your API key
zh_Hans: 请输入你的 API key
ja_Jp: あなたの API key を入れてください
pt_BR: Por favor, insira sua chave API
endpoints:
- endpoints/duck.yaml
- endpoints/neko.yaml
```
## Interface Definition
* **`path`** (string): Follows the Werkzeug interface standard.
* **`method`** (string): Interface method; supports only `HEAD`, `GET`, `POST`, `PUT`, `DELETE`, and `OPTIONS`.
* **`extra`** (object): Configuration information beyond the basic details.
* **`python`** (object)
* **`source`** (string): The source code that implements this interface.
```yaml theme={null}
path: "/duck/<app_id>"
method: "GET"
extra:
python:
source: "endpoints/duck.py"
```
## Interface Implementation
Implement a subclass of `dify_plugin.Endpoint` and its `_invoke` method.
* **Input parameters**
* **`r`** (Request): The `Request` object from `werkzeug`.
* **`values`** (Mapping): Path parameters parsed from the path.
* **`settings`** (Mapping): Configuration information for this Endpoint.
* **Return**
* A `Response` object from `werkzeug`; streaming responses are supported.
* Returning a string directly is not supported.
Example code:
```python theme={null}
import json
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
class Duck(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
app_id = values["app_id"]
def generator():
yield f"{app_id} <br>"
return Response(generator(), status=200, content_type="text/html")
```
## Notes
* Endpoints are only instantiated when the plugin is called; they are not long-running services.
* Pay attention to security when developing Endpoints, and avoid executing dangerous operations.
* Endpoints can handle webhook callbacks or provide interfaces for other systems to connect to.
If you're new to plugin development, start with [Getting Started with Plugin Development](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) and the [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet).
## Related Resources
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin): The overall architecture of plugin development.
* [Neko Cat Example](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): An example of extension plugin development.
* [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Common structures like ProviderConfig.
* [Develop a Slack Bot Plugin Example](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin): Another plugin development example.
* [Getting Started with Plugin Development](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin): Develop a plugin from scratch.
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app): Use the reverse invocation feature.
# Tool OAuth
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth
Replace manual API-key entry with an OAuth authorization flow so users grant access to third-party services with one click
<Frame>
<img alt="OAuth Authorize Example" />
</Frame>
This guide teaches you how to build [OAuth](https://oauth.net/2/) support into your tool plugin.
OAuth is a better way to authorize tool plugins that need to access user data from third-party services, like Gmail or GitHub. Instead of requiring the user to manually enter API keys, OAuth lets the tool act on behalf of the user with their explicit consent.
## Background
OAuth in Dify involves **two separate flows** that developers should understand and design for.
```mermaid theme={null}
sequenceDiagram
autonumber
participant Admin as Admin / Developer
participant Service as Third-party Service
participant Dify
participant User
rect rgb(235, 245, 255)
Note over Admin,Dify: Flow 1: One-time OAuth client setup
Admin->>Service: Register OAuth app
Service-->>Admin: client_id + client_secret
Admin->>Dify: Configure plugin OAuth client
end
rect rgb(245, 255, 235)
Note over User,Service: Flow 2: Per-user authorization
User->>Dify: Click "Authorize"
Dify->>Service: Redirect to consent screen
User->>Service: Approve
Service-->>Dify: Authorization code
Dify->>Service: Exchange for access token
Service-->>Dify: Access + refresh tokens
Dify-->>User: Tool ready to use
end
```
### Flow 1: OAuth Client Setup (Admin / Developer Flow)
<Note>
On Dify Cloud, the Dify team creates OAuth apps for popular tool plugins and sets up OAuth clients, so users don't need to configure this themselves.
Admins of self-hosted Dify instances must go through this setup flow.
</Note>
Admins or developers of a Dify instance first register an OAuth app with the third-party service as a trusted application. This provides the credentials needed to configure the Dify tool provider as an OAuth client.
As an example, here are the steps to set up an OAuth client for Dify's Gmail tool provider:
<AccordionGroup>
<Accordion title="Create a Google Cloud Project">
1. Go to [Google Cloud Console](https://console.cloud.google.com) and create a new project, or select an existing one.
2. Enable the required APIs (e.g., Gmail API).
</Accordion>
<Accordion title="Configure the OAuth Consent Screen">
1. Navigate to **APIs & Services** > **OAuth consent screen**.
2. Choose the **External** user type for public plugins.
3. Fill in the application name, user support email, and developer contact.
4. Add authorized domains if needed.
5. For testing, add test users in the **Test users** section.
</Accordion>
<Accordion title="Create OAuth 2.0 Credentials">
1. Go to **APIs & Services** > **Credentials**.
2. Click **Create Credentials** > **OAuth 2.0 Client IDs**.
3. Choose the **Web application** type.
4. A `client_id` and a `client_secret` will be generated. Save these as the credentials.
</Accordion>
<Accordion title="Enter Credentials in Dify">
Enter the `client_id` and `client_secret` in the OAuth Client configuration popup to set up the tool provider as a client.
<Frame>
<img alt="OAuth Client Settings Dialog" />
</Frame>
</Accordion>
<Accordion title="Authorize Redirect URI">
Register the redirect URI generated by Dify on the Google OAuth Client's page:
<Frame>
<img alt="OAuth Google Redirect URI" />
</Frame>
<Info>
Dify displays the `redirect_uri` in the OAuth Client configuration popup. It usually follows the format:
```bash theme={null}
https://{your-dify-domain}/console/api/oauth/plugin/{plugin-id}/{provider-name}/{tool-name}/callback
```
For self-hosted Dify, `your-dify-domain` should match `CONSOLE_WEB_URL`.
</Info>
</Accordion>
</AccordionGroup>
<Tip>
Each service has unique requirements, so always consult the specific OAuth documentation for the services you're integrating with.
</Tip>
### Flow 2: User Authorization (Dify User Flow)
After configuring OAuth clients, individual Dify users can now authorize your plugin to access their personal accounts.
<Frame>
<img alt="OAuth User Authorization" />
</Frame>
## Implementation
### 1. Define OAuth Schema in Provider Manifest
The `oauth_schema` section of the provider manifest tells Dify what credentials your plugin's OAuth setup needs and what the OAuth flow produces. Setting up OAuth requires two schemas:
#### client\_schema
Defines the input for OAuth client setup:
```yaml gmail.yaml theme={null}
oauth_schema:
client_schema:
- name: "client_id"
type: "secret-input"
required: true
url: "https://developers.google.com/identity/protocols/oauth2"
- name: "client_secret"
type: "secret-input"
required: true
```
<Info>
The `url` field links to the third-party service's help documentation, giving admins and developers a reference during setup.
</Info>
#### credentials\_schema
Specifies what the user authorization flow produces (Dify manages these automatically):
```yaml theme={null}
# also under oauth_schema
credentials_schema:
- name: "access_token"
type: "secret-input"
- name: "refresh_token"
type: "secret-input"
- name: "expires_at"
type: "secret-input"
```
<Info>
Include `oauth_schema` and `credentials_for_provider` together to offer both OAuth and API key authentication options.
</Info>
### 2. Complete Required OAuth Methods in Tool Provider
Add these imports where your `ToolProvider` is implemented:
```python theme={null}
from dify_plugin.entities.oauth import ToolOAuthCredentials
from dify_plugin.errors.tool import ToolProviderCredentialValidationError, ToolProviderOAuthError
```
Your `ToolProvider` class must implement these three OAuth methods (using `GmailProvider` as an example):
<Warning>
Never return the `client_secret` in the credentials of `ToolOAuthCredentials`; doing so could lead to security issues.
</Warning>
<CodeGroup>
```python _oauth_get_authorization_url expandable theme={null}
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
"""
Generate the authorization URL using credentials from OAuth Client Setup Flow.
This URL is where users grant permissions.
"""
# Generate random state for CSRF protection (recommended for all OAuth flows)
state = secrets.token_urlsafe(16)
# Define Gmail-specific scopes - request minimal necessary permissions
scope = "read:user read:data" # Replace with your required scopes
# Assemble Gmail-specific payload
params = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"redirect_uri": redirect_uri, # Dify generates this - DON'T modify
"scope": scope,
"response_type": "code", # Standard OAuth authorization code flow
"access_type": "offline", # Critical: gets refresh token (if supported)
"prompt": "consent", # Forces reauth when scopes change (if supported)
"state": state, # CSRF protection
}
return f"{self._AUTH_URL}?{urllib.parse.urlencode(params)}"
```
```python _oauth_get_credentials expandable theme={null}
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> ToolOAuthCredentials:
"""
Exchange authorization code for access token and refresh token. This is called
to create ONE credential set for one account connection.
"""
# Extract authorization code from OAuth callback
code = request.args.get("code")
if not code:
raise ToolProviderOAuthError("Authorization code not provided")
# Check for authorization errors from OAuth provider
error = request.args.get("error")
if error:
error_description = request.args.get("error_description", "")
raise ToolProviderOAuthError(f"OAuth authorization failed: {error} - {error_description}")
# Exchange authorization code for tokens using OAuth Client Setup credentials
# Assemble Gmail-specific payload
data = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"client_secret": system_credentials["client_secret"], # From OAuth Client Setup
"code": code, # From user's authorization
"grant_type": "authorization_code", # Standard OAuth flow type
"redirect_uri": redirect_uri, # Must exactly match authorization URL
}
headers = {"Content-Type": "application/x-www-form-urlencoded"}
try:
response = requests.post(
self._TOKEN_URL,
data=data,
headers=headers,
timeout=10
)
response.raise_for_status()
token_data = response.json()
# Handle OAuth provider errors in response
if "error" in token_data:
error_desc = token_data.get('error_description', token_data['error'])
raise ToolProviderOAuthError(f"Token exchange failed: {error_desc}")
access_token = token_data.get("access_token")
if not access_token:
raise ToolProviderOAuthError("No access token received from provider")
# Build credentials dict matching your credentials_schema
credentials = {
"access_token": access_token,
"token_type": token_data.get("token_type", "Bearer"),
}
# Include refresh token if provided (critical for long-term access)
refresh_token = token_data.get("refresh_token")
if refresh_token:
credentials["refresh_token"] = refresh_token
# Handle token expiration - some providers don't provide expires_in
expires_in = token_data.get("expires_in", 3600) # Default to 1 hour
expires_at = int(time.time()) + expires_in
return ToolOAuthCredentials(credentials=credentials, expires_at=expires_at)
except requests.RequestException as e:
raise ToolProviderOAuthError(f"Network error during token exchange: {str(e)}")
except Exception as e:
raise ToolProviderOAuthError(f"Failed to exchange authorization code: {str(e)}")
```
```python _oauth_refresh_credentials theme={null}
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> ToolOAuthCredentials:
"""
Refresh the credentials using the refresh token.
Dify calls this automatically when tokens expire.
"""
refresh_token = credentials.get("refresh_token")
if not refresh_token:
raise ToolProviderOAuthError("No refresh token available")
# Standard OAuth refresh token flow
data = {
"client_id": system_credentials["client_id"], # From OAuth Client Setup
"client_secret": system_credentials["client_secret"], # From OAuth Client Setup
"refresh_token": refresh_token, # From previous authorization
"grant_type": "refresh_token", # OAuth refresh flow
}
headers = {"Content-Type": "application/x-www-form-urlencoded"}
try:
response = requests.post(
self._TOKEN_URL,
data=data,
headers=headers,
timeout=10
)
response.raise_for_status()
token_data = response.json()
# Handle refresh errors
if "error" in token_data:
error_desc = token_data.get('error_description', token_data['error'])
raise ToolProviderOAuthError(f"Token refresh failed: {error_desc}")
access_token = token_data.get("access_token")
if not access_token:
raise ToolProviderOAuthError("No access token received from provider")
# Build new credentials, preserving existing refresh token
new_credentials = {
"access_token": access_token,
"token_type": token_data.get("token_type", "Bearer"),
"refresh_token": refresh_token, # Keep existing refresh token
}
# Handle token expiration
expires_in = token_data.get("expires_in", 3600)
# update refresh token if new one provided
new_refresh_token = token_data.get("refresh_token")
if new_refresh_token:
new_credentials["refresh_token"] = new_refresh_token
# Calculate new expiration timestamp for Dify's token management
expires_at = int(time.time()) + expires_in
return ToolOAuthCredentials(credentials=new_credentials, expires_at=expires_at)
except requests.RequestException as e:
raise ToolProviderOAuthError(f"Network error during token refresh: {str(e)}")
except Exception as e:
raise ToolProviderOAuthError(f"Failed to refresh credentials: {str(e)}")
```
</CodeGroup>
### 3. Access Tokens in Your Tools
Use OAuth credentials to make authenticated API calls in your `Tool` implementation:
```python theme={null}
class YourTool(BuiltinTool):
def _invoke(self, user_id: str, tool_parameters: dict[str, Any]) -> ToolInvokeMessage:
if self.runtime.credential_type == CredentialType.OAUTH:
access_token = self.runtime.credentials["access_token"]
response = requests.get("https://api.service.com/data",
headers={"Authorization": f"Bearer {access_token}"})
return self.create_text_message(response.text)
```
`self.runtime.credentials` automatically provides the current user's tokens. Dify handles refresh automatically.
For plugins that support both OAuth and `API_KEY` authentication, use `self.runtime.credential_type` to differentiate between the two authentication types.
### 4. Specify the Correct Versions
OAuth requires a recent SDK and Dify version. Pin the plugin SDK in `requirements.txt`:
```text theme={null}
dify_plugin>=0.5.0
```
In `manifest.yaml`, add the minimum Dify version:
```yaml theme={null}
meta:
version: 0.0.1
arch:
- amd64
- arm64
runner:
language: python
version: "3.12"
entrypoint: main
minimum_dify_version: 1.7.1
```
# Tool Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin
Develop a Dify tool plugin from initialization to packaging, using Google Search as a worked example
Tools are third-party services that Chatflow, Workflow, and Agent applications can call. They extend Dify applications with capabilities such as online search and image generation.
<Frame>

</Frame>
In this guide, a *tool plugin* is a complete project that includes tool provider files, functional code, and supporting structures. A tool provider can bundle multiple tools, each offering a distinct capability:
```text theme={null}
- Tool Provider
- Tool A
- Tool B
```
<Frame>

</Frame>
This guide uses Google Search as an example to walk through tool plugin development.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
To set up the scaffolding tool, see [Initializing Development Tools](/en/develop-plugin/getting-started/cli).
## Create a New Project
Run the scaffolding command line tool to create a new Dify plugin project.
```bash theme={null}
./dify-plugin-darwin-arm64 plugin init
```
If you have renamed the binary file to `dify` and copied it to the `/usr/local/bin` path, you can run the following command to create a new plugin project:
```bash theme={null}
dify plugin init
```
<Note>
The following examples use `dify` as the command. If you run into issues, replace `dify` with the path to your command-line tool.
</Note>
## Choose Plugin Type and Template
Each template in the scaffolding tool is a complete code project. For this example, select the `Tool` plugin.
<Tip>
If you are already familiar with plugin development and don't need a template, see the [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) guide to build any plugin type.
</Tip>
<Frame>

</Frame>
### Configure Plugin Permissions
The plugin also needs permissions to read from the Dify platform. Grant this example plugin the following permissions:
* Tools
* Apps
* Enable persistent storage, with the default storage size
* Allow registering Endpoints
<Tip>
In the terminal, use the arrow keys to select permissions and the Tab key to grant them.
</Tip>
After checking all permission items, press Enter to complete the plugin creation. The system generates the plugin project code automatically.
<Frame>

</Frame>
## Develop the Tool Plugin
### 1. Create the Tool Provider File
The tool provider file is a YAML file that serves as the plugin's base configuration, supplying the authorization information the tool needs.
In the plugin template project, go to the `/provider` directory and rename the YAML file to `google.yaml`. This file describes the tool provider: name, icon, author, and other details shown when the plugin is installed.
Example code:
```yaml theme={null}
identity: # Basic information about the tool provider
author: Your-name # Author
name: google # Unique name; must not duplicate another provider's name
label: # Label shown in the frontend
en_US: Google # English label
zh_Hans: Google # Chinese label
description: # Description shown in the frontend
en_US: Google # English description
zh_Hans: Google # Chinese description
icon: icon.svg # Tool icon; must be placed in the _assets folder
tags: # Tags shown in the frontend
- search
```
Make sure the file path is in the `/tools` directory, with the complete path as follows:
```yaml theme={null}
plugins:
tools:
- 'google.yaml'
```
`google.yaml` must be referenced by its absolute path within the plugin project; in this example, it sits in the project root directory. In the YAML file, `identity` holds the tool provider's basic information: author, name, label, description, and icon.
* The icon must be an attachment resource placed in the `_assets` folder in the project root directory.
* Tags help users find plugins by category. These are all the currently supported tags:
```python theme={null}
class ToolLabelEnum(Enum):
SEARCH = 'search'
IMAGE = 'image'
VIDEOS = 'videos'
WEATHER = 'weather'
FINANCE = 'finance'
DESIGN = 'design'
TRAVEL = 'travel'
SOCIAL = 'social'
NEWS = 'news'
MEDICAL = 'medical'
PRODUCTIVITY = 'productivity'
EDUCATION = 'education'
BUSINESS = 'business'
ENTERTAINMENT = 'entertainment'
UTILITIES = 'utilities'
OTHER = 'other'
```
### 2. Add Third-Party Service Credentials
For convenience, this example uses the Google Search API provided by the third-party service SerpApi. SerpApi requires an API key, so add a `credentials_for_provider` field to the YAML file.
The complete code:
```yaml theme={null}
identity:
author: Dify
name: google
label:
en_US: Google
zh_Hans: Google
pt_BR: Google
description:
en_US: Google
zh_Hans: GoogleSearch
pt_BR: Google
icon: icon.svg
tags:
- search
credentials_for_provider: # Add the credentials_for_provider field
serpapi_api_key:
type: secret-input
required: true
label:
en_US: SerpApi API key
zh_Hans: SerpApi API key
placeholder:
en_US: Please input your SerpApi API key
zh_Hans: Please enter your SerpApi API key
help:
en_US: Get your SerpApi API key from SerpApi
zh_Hans: Get your SerpApi API key from SerpApi
url: https://serpapi.com/manage-api-key
tools:
- tools/google_search.yaml
extra:
python:
source: google.py
```
* The sub-level structure of `credentials_for_provider` must meet the requirements in [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications).
* Specify which tools the provider includes. This example includes only one file, `tools/google_search.yaml`.
* Besides its basic information, a provider needs code logic, so specify its implementation file. This example uses `google.py`, but leave it unimplemented for now and write the `google_search` tool code first.
### 3. Fill in the Tool YAML File
A tool plugin can contain multiple tools, each described by its own YAML file covering basic information, parameters, and output.
Continuing with the `GoogleSearch` tool, create a new `google_search.yaml` file in the `/tools` folder.
```yaml theme={null}
identity:
name: google_search
author: Dify
label:
en_US: GoogleSearch
zh_Hans: Google Search
pt_BR: GoogleSearch
description:
human:
en_US: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
zh_Hans: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
pt_BR: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
llm: A tool for performing a Google SERP search and extracting snippets and webpages. Input should be a search query.
parameters:
- name: query
type: string
required: true
label:
en_US: Query string
zh_Hans: Query string
pt_BR: Query string
human_description:
en_US: used for searching
zh_Hans: used for searching web content
pt_BR: used for searching
llm_description: key words for searching
form: llm
extra:
python:
source: tools/google_search.py
```
* **`identity`**: Basic information about the tool, including name, author, label, and description.
* **`parameters`**: The parameter list.
* **`name`** (required): Parameter name; must be unique among the tool's parameters.
* **`type`** (required): Parameter type. Values fall into three groups:
* **Plain values**: `string`, `number`, `boolean`, `any`.
* **Choices**: `select` for a fixed dropdown built from `options`, `dynamic-select` for a dropdown whose options the plugin supplies at configuration time, and `checkbox`.
* **Pickers and uploads**:
* `secret-input` for sensitive values, which renders as an encrypted input box
* `file` and `files` for uploads
* `app-selector` and `model-selector` for choosing an app or a model from the workspace
* `date` for a single date, which renders as a date picker and is passed as a `YYYY-MM-DD` string
* `date-range` for a start and end date, which renders as a date range picker and is passed as an object with `start` and `end` date strings
Two further values, `array` and `object`, exist for MCP server tools rather than plugin-declared parameters, and `system-files` is deprecated.
* **`label`** (required): Parameter label, shown in the frontend.
* **`form`** (required): Form type, either `llm` or `form`.
* In Agent applications, `llm` means the LLM infers the parameter itself, while `form` means the parameter can be preset before using the tool.
* In Workflow applications, both `llm` and `form` parameters are filled in via the frontend, but `llm` parameters are used as input variables for the tool node.
* **`required`** (optional): Whether the parameter is required.
* In `llm` mode, a required parameter must be inferred by the Agent.
* In `form` mode, a required parameter must be filled in on the frontend before the conversation begins.
* **`options`** (optional): Parameter options.
* In `llm` mode, Dify passes all options to the LLM, which can infer based on them.
* In `form` mode, the frontend displays the options when `type` is `select`.
* **`multiple`** (optional): For `select` and `dynamic-select` parameters, set `true` to let users pick more than one option. The value is passed as a list of option values, and `default`, if set, must then be a list.
```yaml theme={null}
- name: formats
type: select
multiple: true
form: form
label:
en_US: Formats
options:
- label:
en_US: Markdown
value: markdown
- label:
en_US: Links
value: links
default:
- markdown
```
* **`default`** (optional): Default value.
* **`min`** (optional): Minimum value; applies when the parameter type is `number`.
* **`max`** (optional): Maximum value; applies when the parameter type is `number`.
* **`human_description`** (optional): Description shown in the frontend; supports multiple languages.
* **`placeholder`** (optional): Hint text for the input field; applies when the form type is `form` and the parameter type is `string`, `number`, or `secret-input`. Supports multiple languages.
* **`llm_description`** (optional): Description passed to the LLM. Write it in as much detail as possible so the LLM understands the parameter.
### 4. Write the Tool Code
With the tool configuration in place, write the code that implements the tool's logic. Create `google_search.py` in the `/tools` directory with the following content:
```python theme={null}
from collections.abc import Generator
from typing import Any
import requests
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
SERP_API_URL = "https://serpapi.com/search"
class GoogleSearchTool(Tool):
def _parse_response(self, response: dict) -> dict:
result = {}
if "knowledge_graph" in response:
result["title"] = response["knowledge_graph"].get("title", "")
result["description"] = response["knowledge_graph"].get("description", "")
if "organic_results" in response:
result["organic_results"] = [
{
"title": item.get("title", ""),
"link": item.get("link", ""),
"snippet": item.get("snippet", ""),
}
for item in response["organic_results"]
]
return result
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
params = {
"api_key": self.runtime.credentials["serpapi_api_key"],
"q": tool_parameters["query"],
"engine": "google",
"google_domain": "google.com",
"gl": "us",
"hl": "en",
}
response = requests.get(url=SERP_API_URL, params=params, timeout=5)
response.raise_for_status()
valuable_res = self._parse_response(response.json())
yield self.create_json_message(valuable_res)
```
This code sends a request to `serpapi` and uses `self.create_json_message` to return formatted JSON data. To learn more about return data types, see [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) and [Persistent Storage KV](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv).
### 5. Complete the Tool Provider Code
Finally, implement the provider's credential validation logic. If validation fails, the code raises a `ToolProviderCredentialValidationError` exception; once validation succeeds, the `google_search` tool service is requested correctly.
Create a `google.py` file in the `/provider` directory with the following content:
```python theme={null}
from typing import Any
from dify_plugin import ToolProvider
from dify_plugin.errors.tool import ToolProviderCredentialValidationError
from tools.google_search import GoogleSearchTool
class GoogleProvider(ToolProvider):
def _validate_credentials(self, credentials: dict[str, Any]) -> None:
try:
for _ in GoogleSearchTool.from_credentials(credentials).invoke(
tool_parameters={"query": "test", "result_type": "link"},
):
pass
except Exception as e:
raise ToolProviderCredentialValidationError(str(e))
```
## Debug the Plugin
After development, test whether the plugin works correctly. Dify provides remote debugging so you can quickly verify the plugin's functionality in a test environment.
Go to the [Plugin Management](https://cloud.dify.ai/plugins) page to get the remote server address and debug key.
<Frame>

</Frame>
Back in the plugin project, copy the `.env.example` file, rename it to `.env`, and fill in the remote server address and debug key.
`.env` file:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug.dify.ai:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
Run `python -m main` to start the plugin. On the **Plugins** page, you can see the plugin installed in the workspace, where other team members can also access it.
<Frame>

</Frame>
## Package the Plugin (Optional)
Once the plugin runs correctly, package and name it with the following command. It produces a `google.difypkg` file in the current folder—the final plugin package.
```bash theme={null}
# Replace ./google with the actual path of the plugin project
dify plugin package ./google
```
Congratulations—you've developed, debugged, and packaged a tool plugin!
## Publish the Plugin (Optional)
To publish the plugin to the Dify Marketplace, make sure it follows the specifications in [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace). After the review passes, the code is merged into the main branch and automatically released on the [Dify Marketplace](https://marketplace.dify.ai/).
For the full process, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Explore More
### Quick Start
* [Developing Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint)
* [Developing Model Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)
* [Bundle Plugins: Packaging Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
### Plugin Interface Documentation
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Manifest structure and tool specifications.
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint): Detailed Endpoint definition.
* [Reverse Invocation](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Reverse invocation of Dify capabilities.
* [Model Schema](/en/develop-plugin/features-and-specs/plugin-types/model-schema): Models.
* [Agent Plugins](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation): Extending Agent strategies.
## Next Steps
* [Remote Debugging Plugins](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin): Learn more advanced debugging techniques.
* [Persistent Storage](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv): Use data storage in plugins.
* [Slack Bot Plugin Development Example](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin): A more complex plugin development case.
* [Tool Plugin](/en/develop-plugin/features-and-specs/plugin-types/tool): Advanced features of tool plugins.
# Trigger Plugin
Source: https://docs.dify.ai/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin
Build a Dify 1.10.0+ trigger plugin that turns third-party webhook events into workflow start signals
## What Is a Trigger Plugin?
Triggers were introduced in Dify v1.10.0 as a new type of start node. Unlike functional nodes such as Code, Tool, or Knowledge Retrieval, a trigger **converts third-party events into an input format that Dify can recognize and process**.
<Frame>
<img alt="Trigger Plugin Intro" />
</Frame>
For example, if you configure Dify as the `new email` event receiver in Gmail, Gmail automatically sends an event to Dify every time you receive a new email, and that event can trigger a workflow. However:
* Gmail's original event format is not compatible with Dify's input format.
* There are thousands of platforms worldwide, each with its own unique event format.
Trigger plugins close this gap: they define and parse events from different platforms and unify them into an input format that Dify can accept.
## Technical Overview
Dify triggers are built on webhooks, a widely adopted mechanism across the web. Mainstream SaaS platforms such as GitHub, Slack, and Linear support webhooks and document them thoroughly.
A webhook is an HTTP-based event dispatcher: once you configure an event-receiving address, the platform automatically pushes event data to that address whenever a subscribed event occurs.
To handle webhook events from different platforms in a unified way, Dify defines two core concepts: **Subscription** and **Event**.
* **Subscription**: The configuration that registers Dify's network address as the target server in a third-party platform's developer console.
* **Event**: A platform may send multiple types of events (such as *email received*, *email deleted*, or *email marked as read*), all pushed to the registered address. A trigger plugin can handle multiple event types, and each event corresponds to a Plugin Trigger node in a Dify workflow.
## Plugin Development
Developing a trigger plugin follows the same process as other plugin types (Tool, Data Source, Model, and so on).
Create a development template with the `dify plugin init` command. The generated file structure follows the standard plugin format specification.
```text theme={null}
├── _assets
│ └── icon.svg
├── events
│ └── star
│ ├── star_created.py
│ └── star_created.yaml
├── main.py
├── manifest.yaml
├── provider
│ ├── github.py
│ └── github.yaml
├── README.md
├── PRIVACY.md
└── requirements.txt
```
* `manifest.yaml`: Describes the plugin's basic metadata.
* `provider` directory: Contains the provider's metadata, the code for creating subscriptions, and the code for classifying events after receiving webhook requests.
* `events` directory: Contains the code for event handling and filtering, which supports local event filtering at the node level. You can create subdirectories to group related events.
<Note>
For trigger plugins, set the minimum required Dify version to `1.10.0` and the SDK version to `>= 0.6.0`.
</Note>
The following sections use GitHub as an example to walk through the development process.
### Create a Subscription
Webhook configuration methods vary significantly across mainstream SaaS platforms:
* Some platforms (such as GitHub) support API-based webhook configuration. For these platforms, once OAuth authentication is completed, Dify can automatically set up the webhook.
* Other platforms (such as Notion) do not provide a webhook configuration API and may require users to perform manual authentication.
To accommodate these differences, we divide the subscription process into two parts: the **Subscription Constructor** and the **Subscription** itself.
For platforms like Notion, creating a subscription requires the user to manually copy the callback URL provided by Dify and paste it into their Notion workspace to complete the webhook setup. This process corresponds to the **Paste URL to create a new subscription** option in the Dify interface.
<Frame>
<img alt="Paste URL to Create a New Subscription" />
</Frame>
To support subscription creation via manual URL pasting, modify two files: `github.yaml` and `github.py`.
<Tabs>
<Tab title="github.yaml">
GitHub webhooks use an encryption mechanism, so a secret key is required to decrypt and validate incoming requests. Declare `webhook_secret` in `github.yaml`.
```yaml theme={null}
subscription_schema:
- name: "webhook_secret"
type: "secret-input"
required: false
label:
zh_Hans: "Webhook Secret"
en_US: "Webhook Secret"
ja_JP: "Webhookシークレット"
help:
en_US: "Optional webhook secret for validating GitHub webhook requests"
ja_JP: "GitHub Webhookリクエストの検証用のオプションのWebhookシークレット"
zh_Hans: "可选的用于验证 GitHub webhook 请求的 webhook 密钥"
```
</Tab>
<Tab title="github.py">
First, implement the `dispatch_event` interface. All requests sent to the callback URL are processed by this interface, and the processed events appear in the **Request Logs** section for debugging and verification.
<Frame>
<img alt="Manual Setup" />
</Frame>
In the code, you can retrieve the `webhook_secret` declared in `github.yaml` via `subscription.properties`.
The `dispatch_event` method determines the event type from the request content. In the example below, the `_dispatch_trigger_event` method handles this extraction.
<Tip>
For the complete code sample, see [Dify's GitHub trigger plugin](https://github.com/langgenius/dify-plugin-sdks/tree/main/python/examples/github_trigger).
</Tip>
```python theme={null}
class GithubTrigger(Trigger):
"""Handle GitHub webhook event dispatch."""
def _dispatch_event(self, subscription: Subscription, request: Request) -> EventDispatch:
webhook_secret = subscription.properties.get("webhook_secret")
if webhook_secret:
self._validate_signature(request=request, webhook_secret=webhook_secret)
event_type: str | None = request.headers.get("X-GitHub-Event")
if not event_type:
raise TriggerDispatchError("Missing GitHub event type header")
payload: Mapping[str, Any] = self._validate_payload(request)
response = Response(response='{"status": "ok"}', status=200, mimetype="application/json")
event: str = self._dispatch_trigger_event(event_type=event_type, payload=payload)
return EventDispatch(events=[event] if event else [], response=response)
```
</Tab>
</Tabs>
### Handle Events
Once an event is extracted, the corresponding implementation must filter the original HTTP request and transform it into an input format that Dify workflows can accept.
Taking the Issue event as an example, define the event in `events/issues/issues.yaml` and its implementation in `events/issues/issues.py`. Define the event's output in the `output_schema` section of `issues.yaml`, which follows the same JSON Schema specification as tool plugins.
<Tabs>
<Tab title="issues.yaml">
```yaml theme={null}
identity:
name: issues
author: langgenius
label:
en_US: Issues
zh_Hans: 议题
ja_JP: イシュー
description:
en_US: Unified issues event with actions filter
zh_Hans: 带 actions 过滤的统一 issues 事件
ja_JP: アクションフィルタ付きの統合イシューイベント
output_schema:
type: object
properties:
action:
type: string
issue:
type: object
description: The issue itself
extra:
python:
source: events/issues/issues.py
```
</Tab>
<Tab title="issues.py">
```python theme={null}
from collections.abc import Mapping
from typing import Any
from werkzeug import Request
from dify_plugin.entities.trigger import Variables
from dify_plugin.errors.trigger import EventIgnoreError
from dify_plugin.interfaces.trigger import Event
class IssuesUnifiedEvent(Event):
"""Unified Issues event. Filters by actions and common issue attributes."""
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
payload = request.get_json()
if not payload:
raise ValueError("No payload received")
allowed_actions = parameters.get("actions") or []
action = payload.get("action")
if allowed_actions and action not in allowed_actions:
raise EventIgnoreError()
issue = payload.get("issue")
if not isinstance(issue, Mapping):
raise ValueError("No issue in payload")
return Variables(variables={**payload})
```
</Tab>
</Tabs>
### Filter Events
To filter out certain events (for example, to focus only on Issue events with a specific label), add `parameters` to the event definition in `issues.yaml`. Then, in the `_on_event` method, raise an `EventIgnoreError` exception for events that don't meet the configured criteria.
<Tabs>
<Tab title="issues.yaml">
```yaml theme={null}
parameters:
- name: added_label
label:
en_US: Added Label
zh_Hans: 添加的标签
ja_JP: 追加されたラベル
type: string
required: false
description:
en_US: "Only trigger if these specific labels were added (e.g., critical, priority-high, security, comma-separated). Leave empty to trigger for any label addition."
zh_Hans: "仅当添加了这些特定标签时触发(例如:critical, priority-high, security,逗号分隔)。留空则对任何标签添加触发。"
ja_JP: "これらの特定のラベルが追加された場合のみトリガー(例: critical, priority-high, security,カンマ区切り)。空の場合は任意のラベル追加でトリガー。"
```
</Tab>
<Tab title="issues.py">
```python theme={null}
def _check_added_label(self, payload: Mapping[str, Any], added_label_param: str | None) -> None:
"""Check if the added label matches the allowed labels"""
if not added_label_param:
return
allowed_labels = [label.strip() for label in added_label_param.split(",") if label.strip()]
if not allowed_labels:
return
# The payload contains the label that was added
label = payload.get("label", {})
label_name = label.get("name", "")
if label_name not in allowed_labels:
raise EventIgnoreError()
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
# ...
# Apply all filters
self._check_added_label(payload, parameters.get("added_label"))
return Variables(variables={**payload})
```
</Tab>
</Tabs>
### Create Subscriptions via OAuth or API Key
To enable automatic subscription creation via OAuth or API key, modify the `github.yaml` and `github.py` files.
<Tabs>
<Tab title="github.yaml">
In `github.yaml`, add the following fields.
```yaml theme={null}
subscription_constructor:
parameters:
- name: "repository"
label:
en_US: "Repository"
zh_Hans: "仓库"
ja_JP: "リポジトリ"
type: "dynamic-select"
required: true
placeholder:
en_US: "owner/repo"
zh_Hans: "owner/repo"
ja_JP: "owner/repo"
help:
en_US: "GitHub repository in format owner/repo (e.g., microsoft/vscode)"
zh_Hans: "GitHub 仓库,格式为 owner/repo(例如:microsoft/vscode)"
ja_JP: "GitHubリポジトリは owner/repo 形式で入力してください(例: microsoft/vscode)"
credentials_schema:
access_tokens:
help:
en_US: Get your Access Tokens from GitHub
ja_JP: GitHub からアクセストークンを取得してください
zh_Hans: 从 GitHub 获取您的 Access Tokens
label:
en_US: Access Tokens
ja_JP: アクセストークン
zh_Hans: Access Tokens
placeholder:
en_US: Please input your GitHub Access Tokens
ja_JP: GitHub のアクセストークンを入力してください
zh_Hans: 请输入你的 GitHub Access Tokens
required: true
type: secret-input
url: https://github.com/settings/tokens?type=beta
extra:
python:
source: provider/github.py
```
`subscription_constructor` is a concept abstracted by Dify to define how a subscription is constructed. It includes the following fields:
* `parameters` (optional): Defines the parameters required to create a subscription, such as the event types to subscribe to or the target GitHub repository.
* `credentials_schema` (optional): Declares the credentials required to create a subscription with an API key or access token, such as `access_tokens` for GitHub.
* `oauth_schema` (optional): Required for subscription creation via OAuth. For details on how to define it, see [Add OAuth Support to Your Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-oauth).
</Tab>
<Tab title="github.py">
In `github.py`, create a `Constructor` class to implement the automatic subscription logic.
```python theme={null}
class GithubSubscriptionConstructor(TriggerSubscriptionConstructor):
"""Manage GitHub trigger subscriptions."""
def _validate_api_key(self, credentials: Mapping[str, Any]) -> None:
# ...
def _create_subscription(
self,
endpoint: str,
parameters: Mapping[str, Any],
credentials: Mapping[str, Any],
credential_type: CredentialType,
) -> Subscription:
repository = parameters.get("repository")
if not repository:
raise ValueError("repository is required (format: owner/repo)")
try:
owner, repo = repository.split("/")
except ValueError:
raise ValueError("repository must be in format 'owner/repo'") from None
events: list[str] = parameters.get("events", [])
webhook_secret = uuid.uuid4().hex
url = f"https://api.github.com/repos/{owner}/{repo}/hooks"
headers = {
"Authorization": f"Bearer {credentials.get('access_tokens')}",
"Accept": "application/vnd.github+json",
}
webhook_data = {
"name": "web",
"active": True,
"events": events,
"config": {"url": endpoint, "content_type": "json", "insecure_ssl": "0", "secret": webhook_secret},
}
try:
response = requests.post(url, json=webhook_data, headers=headers, timeout=10)
except requests.RequestException as exc:
raise SubscriptionError(f"Network error while creating webhook: {exc}", error_code="NETWORK_ERROR") from exc
if response.status_code == 201:
webhook = response.json()
return Subscription(
expires_at=int(time.time()) + self._WEBHOOK_TTL,
endpoint=endpoint,
parameters=parameters,
properties={
"external_id": str(webhook["id"]),
"repository": repository,
"events": events,
"webhook_secret": webhook_secret,
"active": webhook.get("active", True),
},
)
response_data: dict[str, Any] = response.json() if response.content else {}
error_msg = response_data.get("message", "Unknown error")
error_details = response_data.get("errors", [])
detailed_error = f"Failed to create GitHub webhook: {error_msg}"
if error_details:
detailed_error += f" Details: {error_details}"
raise SubscriptionError(
detailed_error,
error_code="WEBHOOK_CREATION_FAILED",
external_response=response_data,
)
```
</Tab>
</Tabs>
***
Once you have modified these two files, you'll see the **Create with API Key** option in the Dify interface.
The same `Constructor` class also supports automatic subscription creation via OAuth: add an `oauth_schema` field under `subscription_constructor` to enable OAuth authentication.
<Frame>
<img alt="OAuth & API Key Options" />
</Frame>
## Explore More
The interface definitions for the core classes in trigger plugin development are as follows.
### Trigger
```python theme={null}
class Trigger(ABC):
@abstractmethod
def _dispatch_event(self, subscription: Subscription, request: Request) -> EventDispatch:
"""
Internal method to implement event dispatch logic.
Subclasses must override this method to handle incoming webhook events.
Implementation checklist:
1. Validate the webhook request:
- Check the signature/HMAC using the properties stored in subscription.properties when the subscription was created
- Verify the request is from the expected source
2. Extract event information:
- Parse event type from headers or body
- Extract relevant payload data
3. Return EventDispatch with:
- events: List of Event names to invoke (can be single or multiple)
- response: Appropriate HTTP response for the webhook
Args:
subscription: The Subscription object with endpoint and properties fields
request: Incoming webhook HTTP request
Returns:
EventDispatch: Event dispatch routing information
Raises:
TriggerValidationError: For security validation failures
TriggerDispatchError: For parsing or routing errors
"""
raise NotImplementedError("This plugin should implement `_dispatch_event` method to enable event dispatch")
```
### TriggerSubscriptionConstructor
```python theme={null}
class TriggerSubscriptionConstructor(ABC, OAuthProviderProtocol):
# OPTIONAL
def _validate_api_key(self, credentials: Mapping[str, Any]) -> None:
raise NotImplementedError(
"This plugin should implement `_validate_api_key` method to enable credentials validation"
)
# OPTIONAL
def _oauth_get_authorization_url(self, redirect_uri: str, system_credentials: Mapping[str, Any]) -> str:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_get_authorization_url` method"
)
# OPTIONAL
def _oauth_get_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], request: Request
) -> TriggerOAuthCredentials:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_get_credentials` method"
)
# OPTIONAL
def _oauth_refresh_credentials(
self, redirect_uri: str, system_credentials: Mapping[str, Any], credentials: Mapping[str, Any]
) -> OAuthCredentials:
raise NotImplementedError(
"The trigger you are using does not support OAuth, please implement `_oauth_refresh_credentials` method"
)
@abstractmethod
def _create_subscription(
self,
endpoint: str,
parameters: Mapping[str, Any],
credentials: Mapping[str, Any],
credential_type: CredentialType,
) -> Subscription:
"""
Internal method to implement subscription logic.
Subclasses must override this method to handle subscription creation.
Implementation checklist:
1. Use the endpoint parameter provided by Dify
2. Register webhook with external service using their API
3. Store all necessary information in Subscription.properties for future operations (e.g., dispatch_event)
4. Return Subscription with:
- expires_at: Set appropriate expiration time
- endpoint: The webhook endpoint URL allocated by Dify for receiving events, same as the endpoint parameter
- parameters: The parameters of the subscription
- properties: All configuration and external IDs
Args:
endpoint: The webhook endpoint URL allocated by Dify for receiving events
parameters: Subscription creation parameters
credentials: Authentication credentials
credential_type: The type of the credentials, e.g., "api-key", "oauth2", "unauthorized"
Returns:
Subscription: Subscription details with metadata for future operations
Raises:
SubscriptionError: For operational failures (API errors, invalid credentials)
ValueError: For programming errors (missing required params)
"""
raise NotImplementedError(
"This plugin should implement `_create_subscription` method to enable event subscription"
)
@abstractmethod
def _delete_subscription(
self, subscription: Subscription, credentials: Mapping[str, Any], credential_type: CredentialType
) -> UnsubscribeResult:
"""
Internal method to implement unsubscription logic.
Subclasses must override this method to handle subscription removal.
Implementation guidelines:
1. Extract necessary IDs from subscription.properties (e.g., external_id)
2. Use credentials and credential_type to call external service API to delete the webhook
3. Handle common errors (not found, unauthorized, etc.)
4. Always return UnsubscribeResult with detailed status
5. Never raise exceptions for operational failures - use UnsubscribeResult.success=False
Args:
subscription: The Subscription object with endpoint and properties fields
Returns:
UnsubscribeResult: Always returns result, never raises for operational failures
"""
raise NotImplementedError(
"This plugin should implement `_delete_subscription` method to enable event unsubscription"
)
@abstractmethod
def _refresh_subscription(
self, subscription: Subscription, credentials: Mapping[str, Any], credential_type: CredentialType
) -> Subscription:
"""
Internal method to implement subscription refresh logic.
Subclasses must override this method to handle simple expiration extension.
Implementation patterns:
1. For webhooks without expiration (e.g., GitHub):
- Update the Subscription.expires_at=-1 then Dify will never call this method again
2. For lease-based subscriptions (e.g., Microsoft Graph):
- Use the information in Subscription.properties to call service's lease renewal API if available
- Handle renewal limits (some services limit renewal count)
- Update Subscription.properties and Subscription.expires_at for the next renewal if needed
Args:
subscription: Current subscription with properties
credential_type: The type of the credentials, e.g., "api-key", "oauth2", "unauthorized"
credentials: Current authentication credentials from credentials_schema.
For API key auth, according to `credentials_schema` defined in the YAML.
For OAuth auth, according to `oauth_schema.credentials_schema` defined in the YAML.
For unauthorized auth, there is no credentials.
Returns:
Subscription: Same subscription with extended expiration
or new properties and expires_at for the next renewal
Raises:
SubscriptionError: For operational failures (API errors, invalid credentials)
"""
raise NotImplementedError("This plugin should implement `_refresh` method to enable subscription refresh")
# OPTIONAL
def _fetch_parameter_options(
self, parameter: str, credentials: Mapping[str, Any], credential_type: CredentialType
) -> list[ParameterOption]:
"""
Fetch the parameter options of the trigger.
Implementation guidelines:
When you need to fetch parameter options from an external service, use the credentials
and credential_type to call the external service API, then return the options to Dify
for user selection.
Args:
parameter: The parameter name for which to fetch options
credentials: Authentication credentials for the external service
credential_type: The type of credentials (e.g., "api-key", "oauth2", "unauthorized")
Returns:
list[ParameterOption]: A list of available options for the parameter
Examples:
GitHub Repositories:
>>> result = provider.fetch_parameter_options(parameter="repository")
>>> print(result) # [ParameterOption(label="owner/repo", value="owner/repo")]
Slack Channels:
>>> result = provider.fetch_parameter_options(parameter="channel")
>>> print(result)
```
### Event
```python theme={null}
class Event(ABC):
@abstractmethod
def _on_event(self, request: Request, parameters: Mapping[str, Any], payload: Mapping[str, Any]) -> Variables:
"""
Transform the incoming webhook request into structured Variables.
This method should:
1. Parse the webhook payload from the request
2. Apply filtering logic based on parameters
3. Extract relevant data matching the output_schema
4. Return a structured Variables object
Args:
request: The incoming webhook HTTP request containing the raw payload.
Use request.get_json() to parse JSON body.
parameters: User-configured parameters for filtering and transformation
(e.g., label filters, regex patterns, threshold values).
These come from the subscription configuration.
payload: The decoded payload from previous step `Trigger.dispatch_event`.
It will be delivered into `_on_event` method.
Returns:
Variables: Structured variables matching the output_schema
defined in the event's YAML configuration.
Raises:
EventIgnoreError: When the event should be filtered out based on parameters
ValueError: When the payload is invalid or missing required fields
Example:
>>> def _on_event(self, request, parameters):
... payload = request.get_json()
...
... # Apply filters
... if not self._matches_filters(payload, parameters):
... raise EventIgnoreError()
...
... # Transform data
... return Variables(variables={
... "title": payload["issue"]["title"],
... "author": payload["issue"]["user"]["login"],
... "url": payload["issue"]["html_url"],
... })
"""
def _fetch_parameter_options(self, parameter: str) -> list[ParameterOption]:
"""
Fetch the parameter options of the trigger.
To be implemented by subclasses.
Implementing it is optional, which is why it's not an abstract method.
"""
raise NotImplementedError(
"This plugin should implement `_fetch_parameter_options` method to enable dynamic select parameter"
)
```
# Bundle Plugin Package
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/bundle
Package multiple plugins into a Bundle with Marketplace, GitHub, and Package dependencies
A Bundle plugin package is a collection of multiple plugins packaged together, so users can install them all in one step.
Use the Dify Plugin CLI to package multiple plugins into a Bundle. Bundle dependencies come in three types:
* **`Marketplace`**: Stores the plugin's ID and version. During import, Dify downloads the plugin package from the Dify Marketplace.
* **`GitHub`**: Stores the GitHub repository address, release version number, and asset filename. During import, Dify downloads the plugin package from the corresponding GitHub repository.
* **`Package`**: Stores the plugin package directly within the Bundle. No reference source is stored, but this can make the Bundle file larger.
## Prerequisites
* Dify plugin scaffolding tool
* Python environment (version 3.12)
To set up the plugin development scaffolding tool, see [Initialize Development Tools](/en/develop-plugin/getting-started/cli).
## Create a Bundle Project
In the current directory, run the scaffolding command-line tool to create a new plugin package project:
```bash theme={null}
./dify-plugin-darwin-arm64 bundle init
```
If you have renamed the binary to `dify` and copied it to `/usr/local/bin`, run:
```bash theme={null}
dify bundle init
```
### 1. Fill in Plugin Information
Follow the prompts to configure the plugin name, author information, and plugin description. If you are collaborating as a team, you can also enter the organization name as the author.
<Note>
The name must be 1–128 characters long and can only contain letters, numbers, hyphens, and underscores.
</Note>
<Frame>

</Frame>
Press Enter, and the Bundle plugin project directory is created automatically.
<Frame>

</Frame>
### 2. Add Dependencies
#### Marketplace
```bash theme={null}
dify-plugin bundle append marketplace . --marketplace_pattern=langgenius/openai:0.0.1
```
`marketplace_pattern` is the reference to the plugin in the Marketplace, in the format `organization_name/plugin_name:version_number`.
#### GitHub
```bash theme={null}
dify-plugin bundle append github . --repo_pattern=langgenius/openai:0.0.1/openai.difypkg
```
`repo_pattern` is the reference to the plugin on GitHub, in the format `organization_name/repository_name:release/asset_name`.
#### Package
```bash theme={null}
dify-plugin bundle append package . --package_path=./openai.difypkg
```
`package_path` is the path to the plugin package.
## Package the Bundle Project
Run the following command to package the Bundle plugin:
```bash theme={null}
dify-plugin bundle package ./bundle
```
This creates a `bundle.difybndl` file in the current directory—the final packaged result.
# Integrate Custom Models
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/customizable-model
Integrate a custom model into Dify, using Xinference as an example
A **custom model** is an LLM that you deploy or configure yourself. This guide uses [Xinference](https://inference.readthedocs.io/en/latest/) as an example to show how to integrate a custom model into your **model plugin**.
By default, a custom model automatically includes two parameters, its **model type** and **model name**, so the provider YAML file needs no additional definitions.
You do not need to implement `validate_provider_credential` in your provider configuration file. At runtime, Dify calls the corresponding model layer's `validate_credentials` method based on the model type and model name the user selects.
## Integrate a Custom Model Plugin
Integrating a custom model takes four steps:
1. **Create a model provider file**: Identify the model types your custom model will include.
2. **Create code files by model type**: Create separate code files for each model type (e.g., `llm` or `text_embedding`). Keeping each model type in its own logical layer simplifies maintenance and future expansion.
3. **Develop the model invocation logic**: Within each model-type module, create a Python file named for that model type (for example, `llm.py`). Define a class in the file that implements the model logic, conforming to the system's model interface specifications.
4. **Debug the plugin**: Write unit and integration tests for the new provider functionality, ensuring that all components work as intended.
### 1. Create the Model Provider File
In your plugin’s `/provider` directory, create a `xinference.yaml` file.
The `Xinference` family of models supports **LLM**, **Text Embedding**, and **Rerank** model types, so your `xinference.yaml` must include all three.
**Example**:
```yaml theme={null}
provider: xinference # Identifies the provider
label: # Display name; can set both en_US (English) and zh_Hans (Chinese). If zh_Hans is not set, en_US is used by default.
en_US: Xorbits Inference
icon_small: # Small icon; store in the _assets folder of this provider’s directory. The same multi-language logic applies as with label.
en_US: icon_s_en.svg
icon_large: # Large icon
en_US: icon_l_en.svg
help: # Help information
title:
en_US: How to deploy Xinference
zh_Hans: 如何部署 Xinference
url:
en_US: https://github.com/xorbitsai/inference
supported_model_types: # Model types Xinference supports: LLM/Text Embedding/Rerank
- llm
- text-embedding
- rerank
configurate_methods: # Xinference is locally deployed and does not offer predefined models. Refer to its documentation to learn which model to use. Thus, we choose a customizable-model approach.
- customizable-model
provider_credential_schema:
credential_form_schemas:
```
Next, define the `provider_credential_schema`. Since `Xinference` supports text-generation, embeddings, and reranking models, you can configure it as follows:
```yaml theme={null}
provider_credential_schema:
credential_form_schemas:
- variable: model_type
type: select
label:
en_US: Model type
zh_Hans: 模型类型
required: true
options:
- value: text-generation
label:
en_US: Language Model
zh_Hans: 语言模型
- value: embeddings
label:
en_US: Text Embedding
- value: reranking
label:
en_US: Rerank
```
Every model in Xinference requires a `model_name`:
```yaml theme={null}
- variable: model_name
type: text-input
label:
en_US: Model name
zh_Hans: 模型名称
required: true
placeholder:
zh_Hans: 填写模型名称
en_US: Input model name
```
Because Xinference is locally deployed, users must also supply the server address (`server_url`) and model UID:
```yaml theme={null}
- variable: server_url
label:
zh_Hans: 服务器 URL
en_US: Server url
type: text-input
required: true
placeholder:
zh_Hans: 在此输入 Xinference 的服务器地址,如 https://example.com/xxx
en_US: Enter the url of your Xinference, for example https://example.com/xxx
- variable: model_uid
label:
zh_Hans: 模型 UID
en_US: Model uid
type: text-input
required: true
placeholder:
zh_Hans: 在此输入你的 Model UID
en_US: Enter the model uid
```
This completes the YAML configuration for your custom model provider. Next, create the code files for each model defined in the configuration.
### 2. Develop the Model Code
Xinference supports `llm`, `rerank`, `speech2text`, and `tts`, so create a corresponding directory under `/models` for each type, each containing its feature code.
Below is an example for an `llm` type model. Create a file named `llm.py`, then define a class such as `XinferenceAILargeLanguageModel` that extends `__base.large_language_model.LargeLanguageModel`. The class must implement the following methods.
#### LLM Invocation
The core method for invoking the LLM, supporting both streaming and synchronous responses:
```python theme={null}
def _invoke(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
model_parameters: dict,
tools: Optional[list[PromptMessageTool]] = None,
stop: Optional[list[str]] = None,
stream: bool = True,
user: Optional[str] = None
) -> Union[LLMResult, Generator]:
"""
Invoke the large language model.
:param model: model name
:param credentials: model credentials
:param prompt_messages: prompt messages
:param model_parameters: model parameters
:param tools: tools for tool calling
:param stop: stop words
:param stream: determines if response is streamed
:param user: unique user id
:return: full response or a chunk generator
"""
```
Implement streaming and synchronous responses as separate functions. Python treats any function containing `yield` as a generator that returns `Generator`, so splitting them keeps the return types clean:
```python theme={null}
def _invoke(self, stream: bool, **kwargs) -> Union[LLMResult, Generator]:
if stream:
return self._handle_stream_response(**kwargs)
return self._handle_sync_response(**kwargs)
def _handle_stream_response(self, **kwargs) -> Generator:
for chunk in response:
yield chunk
def _handle_sync_response(self, **kwargs) -> LLMResult:
return LLMResult(**response)
```
#### Pre-calculate Input Tokens
If your model doesn't provide a token-counting interface, return `0`:
```python theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
tools: Optional[list[PromptMessageTool]] = None
) -> int:
"""
Get the number of tokens for the given prompt messages.
"""
return 0
```
Alternatively, you can call `self._get_num_tokens_by_gpt2(text: str)` from the `AIModel` base class, which uses a GPT-2 tokenizer. Remember this is an approximation and may not match your model exactly.
#### Validate Model Credentials
Similar to provider-level credential checks, but scoped to a single model:
```python theme={null}
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate model credentials.
"""
```
#### Dynamic Model Parameters Schema
Unlike [predefined models](/en/develop-plugin/features-and-specs/plugin-types/model-schema), no YAML file defines which parameters a model supports, so you must generate the parameter schema dynamically.
For example, Xinference supports `max_tokens`, `temperature`, and `top_p`. Other providers (e.g., `OpenLLM`) may support parameters like `top_k` only for certain models, so the schema must adapt to each model's capabilities:
```python theme={null}
def get_customizable_model_schema(self, model: str, credentials: dict) -> AIModelEntity | None:
"""
used to define customizable model schema
"""
rules = [
ParameterRule(
name='temperature', type=ParameterType.FLOAT,
use_template='temperature',
label=I18nObject(
zh_Hans='温度', en_US='Temperature'
)
),
ParameterRule(
name='top_p', type=ParameterType.FLOAT,
use_template='top_p',
label=I18nObject(
zh_Hans='Top P', en_US='Top P'
)
),
ParameterRule(
name='max_tokens', type=ParameterType.INT,
use_template='max_tokens',
min=1,
default=512,
label=I18nObject(
zh_Hans='最大生成长度', en_US='Max Tokens'
)
)
]
# if model is A, add top_k to rules
if model == 'A':
rules.append(
ParameterRule(
name='top_k', type=ParameterType.INT,
use_template='top_k',
min=1,
default=50,
label=I18nObject(
zh_Hans='Top K', en_US='Top K'
)
)
)
# ... additional ParameterRule entries omitted for brevity ...
entity = AIModelEntity(
model=model,
label=I18nObject(
en_US=model
),
fetch_from=FetchFrom.CUSTOMIZABLE_MODEL,
model_type=model_type,
model_properties={
ModelPropertyKey.MODE: ModelType.LLM,
},
parameter_rules=rules
)
return entity
```
#### Error Mapping
When an error occurs during model invocation, map it to one of the runtime's `InvokeError` types so Dify can handle different errors consistently:
* `InvokeConnectionError`
* `InvokeServerUnavailableError`
* `InvokeRateLimitError`
* `InvokeAuthorizationError`
* `InvokeBadRequestError`
```python theme={null}
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Map model invocation errors to unified error types.
The key is the error type thrown to the caller.
The value is the error type thrown by the model, which needs to be mapped to a
unified Dify error for consistent handling.
"""
# return {
# InvokeConnectionError: [requests.exceptions.ConnectionError],
# ...
# }
```
For more details on interface methods, see the [Model Documentation](https://docs.dify.ai/zh/develop-plugin/features-and-specs/plugin-types/model-schema).
For the complete code files discussed in this guide, see the [GitHub repository](https://github.com/langgenius/dify-official-plugins/tree/main/models/xinference).
### 3. Debug the Plugin
After development, test the plugin to make sure it runs correctly. For details, see:
<Card title="Debug Plugin" icon="link" href="/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet" />
### 4. Publish the Plugin
To list the plugin on the Dify Marketplace, see Publish to Dify Marketplace.
## Explore More
**Quick Start**:
* [Develop Extension Plugin](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
* [Develop Tool Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)
* [Bundle Plugins: Package Multiple Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle)
**Plugins Endpoint Docs**:
* [Manifest](/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest) Structure
* [Endpoint](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) Definitions
* [Reverse-Invocation of the Dify Service](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation)
* [Tools](/en/develop-plugin/features-and-specs/plugin-types/tool)
* [Models](/en/develop-plugin/features-and-specs/plugin-types/model-schema)
# Reverse Invocation of Dify Services
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation
Call App, Model, Tool, and Node services in the Dify platform from your plugin
Through reverse invocation, plugins can call services within the main Dify platform to extend their capabilities.
## Callable Dify Modules
* **[App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app)**: Access data from Apps within the Dify platform.
* **[Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model)**: Invoke LLM capabilities within the Dify platform, including all model types and functions such as TTS and Rerank.
* **[Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool)**: Call other tool-type plugins within the Dify platform.
* **[Node](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-node)**: Call nodes within a specific Chatflow/Workflow application in the Dify platform.
## Related Resources
* [Develop Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) - Learn how to develop plugins that integrate with external systems
* [Develop a Slack Bot Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) - An example of using reverse invocation to integrate with the Slack platform
* [Bundle Type Plugins](/en/develop-plugin/features-and-specs/advanced-development/bundle) - Learn how to package multiple plugins that use reverse invocation
* [Using Persistent Storage](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv) - Enhance plugin capabilities through KV storage
# App
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app
Call the Chat, Workflow, and Completion interfaces of Dify Apps from your plugin
A plugin can reverse invoke an App within Dify to access its data, with both streaming and non-streaming calls. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
**Interface Types**:
* **Chat Interface**: `Chatbot`, `Agent`, and `Chatflow` applications are all chat-based and share the same input and output parameter types, so they share this interface.
* **Workflow Interface**: Used by Workflow applications.
* **Completion Interface**: Used by Completion (text generation) applications.
Plugins can only access Apps within the Workspace where the plugin resides.
## Call the Chat Interface
### Entry Point
```python theme={null}
self.session.app.chat
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
query: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "streaming",
conversation_id: str | None = None,
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
When `response_mode` is `streaming`, this interface returns `Generator[dict]`; otherwise it returns `dict`. For the specific interface fields, see the return results of `ServiceApi`.
### Use Case
This example calls a Chat type App within an `Endpoint` and returns the result directly:
```python theme={null}
import json
from typing import Mapping
from werkzeug import Request, Response
from dify_plugin import Endpoint
class Duck(Endpoint):
def _invoke(self, r: Request, values: Mapping, settings: Mapping) -> Response:
"""
Invokes the endpoint with the given request.
"""
app_id = values["app_id"]
def generator():
response = self.session.app.chat.invoke(
app_id=app_id,
query="Hello from the plugin",
inputs={},
response_mode="streaming",
conversation_id="some-conversation-id",
)
for data in response:
yield f"{json.dumps(data)} <br>"
return Response(generator(), status=200, content_type="text/html")
```
## Call the Workflow Interface
### Entry Point
```python theme={null}
self.session.app.workflow
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "blocking",
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
## Call the Completion Interface
### Entry Point
```python theme={null}
self.session.app.completion
```
### Interface Specification
```python theme={null}
def invoke(
self,
app_id: str,
inputs: dict,
response_mode: Literal["streaming", "blocking"] = "blocking",
user: str | None = None,
) -> Generator[dict, None, None] | dict:
pass
```
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model) - Learn how to call model capabilities within the platform
* [Reverse Invocation Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool) - Learn how to call other plugins
* [Develop a Slack Bot Plugin](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) - A practical application case using reverse invocation
* [Develop Extension Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) - Learn how to develop extension plugins
# Reverse Invocation Model
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model
Invoke LLM, embedding, rerank, TTS, speech-to-text, and moderation models from your plugin
A plugin can reverse invoke Dify's internal LLM capabilities, including all model types and functions within the platform, such as TTS and Rerank. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
Every model invocation takes a `ModelConfig` type parameter. Its structure is defined in the [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) and varies slightly by model type.
For example, `LLM` type models also require `completion_params` and `mode` parameters. You can construct this structure manually or use `model-selector` type parameters or configurations.
## Invoke LLM
### Entry Point
```python theme={null}
self.session.model.llm
```
### Interface
```python theme={null}
def invoke(
self,
model_config: LLMModelConfig,
prompt_messages: list[PromptMessage],
tools: list[PromptMessageTool] | None = None,
stop: list[str] | None = None,
stream: bool = True,
) -> Generator[LLMResultChunk, None, None] | LLMResult:
pass
```
If the model you are invoking does not have `tool_call` capability, the `tools` passed here will not take effect.
### Use Case
This example invokes OpenAI's `gpt-4o-mini` model within a `Tool`:
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.model.llm import LLMModelConfig
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.model.message import SystemPromptMessage, UserPromptMessage
class LLMTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
response = self.session.model.llm.invoke(
model_config=LLMModelConfig(
provider='openai',
model='gpt-4o-mini',
mode='chat',
completion_params={}
),
prompt_messages=[
SystemPromptMessage(
content='you are a helpful assistant'
),
UserPromptMessage(
content=tool_parameters.get('query')
)
],
stream=True
)
for chunk in response:
if chunk.delta.message:
assert isinstance(chunk.delta.message.content, str)
yield self.create_text_message(text=chunk.delta.message.content)
```
Note that the code passes the `query` parameter from `tool_parameters`.
### Best Practice
Avoid constructing `LLMModelConfig` manually. Instead, let users select the model they want in the UI by adding a `model` parameter to the tool's parameter list:
```yaml theme={null}
identity:
name: llm
author: Dify
label:
en_US: LLM
zh_Hans: LLM
pt_BR: LLM
description:
human:
en_US: A tool for invoking a large language model
zh_Hans: 用于调用大型语言模型的工具
pt_BR: A tool for invoking a large language model
llm: A tool for invoking a large language model
parameters:
- name: prompt
type: string
required: true
label:
en_US: Prompt string
zh_Hans: 提示字符串
pt_BR: Prompt string
human_description:
en_US: used for searching
zh_Hans: 用于搜索网页内容
pt_BR: used for searching
llm_description: key words for searching
form: llm
- name: model
type: model-selector
scope: llm
required: true
label:
en_US: Model
zh_Hans: 使用的模型
pt_BR: Model
human_description:
en_US: Model
zh_Hans: 使用的模型
pt_BR: Model
llm_description: which Model to invoke
form: form
extra:
python:
source: tools/llm.py
```
Because the `scope` of the `model` parameter is `llm`, users can only select `llm` type models. The previous use case then becomes:
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.model.llm import LLMModelConfig
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.model.message import SystemPromptMessage, UserPromptMessage
class LLMTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
response = self.session.model.llm.invoke(
model_config=tool_parameters.get('model'),
prompt_messages=[
SystemPromptMessage(
content='you are a helpful assistant'
),
UserPromptMessage(
content=tool_parameters.get('prompt')
)
],
stream=True
)
for chunk in response:
if chunk.delta.message:
assert isinstance(chunk.delta.message.content, str)
yield self.create_text_message(text=chunk.delta.message.content)
```
## Invoke Summary
This interface summarizes a piece of text using the system model within your current workspace.
### Entry Point
```python theme={null}
self.session.model.summary
```
### Interface
```python theme={null}
def invoke(
self, text: str, instruction: str,
) -> str:
```
* **`text`**: The text to summarize.
* **`instruction`**: Additional instructions, letting you control the style of the summary.
## Invoke TextEmbedding
### Entry Point
```python theme={null}
self.session.model.text_embedding
```
### Interface
```python theme={null}
def invoke(
self,
model_config: TextEmbeddingModelConfig,
texts: list[str],
input_type: EmbeddingInputType = EmbeddingInputType.QUERY,
) -> TextEmbeddingResult:
pass
```
## Invoke Rerank
### Entry Point
```python theme={null}
self.session.model.rerank
```
### Interface
```python theme={null}
def invoke(
self, model_config: RerankModelConfig, docs: list[str], query: str
) -> RerankResult:
pass
```
## Invoke TTS
### Entry Point
```python theme={null}
self.session.model.tts
```
### Interface
```python theme={null}
def invoke(
self, model_config: TTSModelConfig, content_text: str
) -> Generator[bytes, None, None]:
pass
```
The `bytes` stream returned by the `tts` interface is an `mp3` audio byte stream, and each iteration returns a complete audio segment. For more in-depth processing, choose an appropriate audio library.
## Invoke Speech2Text
### Entry Point
```python theme={null}
self.session.model.speech2text
```
### Interface
```python theme={null}
def invoke(
self, model_config: Speech2TextModelConfig, file: IO[bytes]
) -> str:
pass
```
Here, `file` is an audio file encoded in `mp3` format.
## Invoke Moderation
### Entry Point
```python theme={null}
self.session.model.moderation
```
### Interface
```python theme={null}
def invoke(self, model_config: ModerationModelConfig, text: str) -> bool:
pass
```
A return value of `true` indicates that the `text` contains sensitive content.
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation of App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app) - Learn how to invoke Apps within the platform
* [Reverse Invocation of Tool](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool) - Learn how to invoke other plugins
* [Model Plugin Development Guide](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) - Learn how to develop custom model plugins
* [Model Designing Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) - Understand the design principles of model plugins
# Node
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-node
Invoke the Parameter Extractor and Question Classifier nodes from your plugin
A plugin can reverse invoke the capabilities of certain nodes within a Dify Chatflow/Workflow application.
Plugins can call the `ParameterExtractor` and `QuestionClassifier` nodes. Both encapsulate complex prompt and code logic, using LLMs to handle tasks that are difficult to solve with hardcoded rules.
## Call the Parameter Extractor Node
### Entry Point
```python theme={null}
self.session.workflow_node.parameter_extractor
```
### Interface
```python theme={null}
def invoke(
self,
parameters: list[ParameterConfig],
model: ModelConfig,
query: str,
instruction: str = "",
) -> NodeResponse
pass
```
* **`parameters`**: The list of parameters to extract.
* **`model`**: Conforms to the `LLMModelConfig` specification.
* **`query`**: The source text for parameter extraction.
* **`instruction`**: Any additional instructions the LLM might need.
For the structure of `NodeResponse`, see the [General Specifications Definition](/en/develop-plugin/features-and-specs/plugin-types/general-specifications#noderesponse).
### Use Case
This example extracts a person's name from a conversation:
```python theme={null}
from collections.abc import Generator
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
from dify_plugin.entities.workflow_node import ModelConfig, NodeResponse, ParameterConfig
class ParameterExtractorTool(Tool):
def _invoke(
self, tool_parameters: dict
) -> Generator[ToolInvokeMessage, None, None]:
response: NodeResponse = self.session.workflow_node.parameter_extractor.invoke(
parameters=[
ParameterConfig(
name="name",
description="name of the person",
required=True,
type="string",
)
],
model=ModelConfig(
provider="langgenius/openai/openai",
name="gpt-4o-mini",
completion_params={},
),
query="My name is John Doe",
instruction="Extract the name of the person",
)
extracted_name = response.outputs.get("name", "Name not found")
yield self.create_text_message(extracted_name)
```
`NodeResponse` is a Pydantic model defined in `dify_plugin.entities.workflow_node` with three dictionary fields: `process_data`, `inputs`, and `outputs`. Extracted values live under `response.outputs`.
## Call the Question Classifier Node
### Entry Point
```python theme={null}
self.session.workflow_node.question_classifier
```
### Interface
```python theme={null}
def invoke(
self,
classes: list[ClassConfig],
model: ModelConfig,
query: str,
instruction: str = "",
) -> NodeResponse:
pass
```
`ClassConfig` is also exported from `dify_plugin.entities.workflow_node`. The interface parameters match those of `ParameterExtractor`, and the final result is stored in `response.outputs["class_name"]`.
# Tool
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-tool
Call installed tools, Workflow as Tool, and custom tools from your plugin
A plugin can reverse invoke other tool-type plugins within the Dify platform. If you are unfamiliar with the basics of reverse invocation, first read [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation).
Consider the following scenarios:
* A tool-type plugin implements a function, but the result is not as expected and the data needs post-processing.
* A task requires a web scraper, and you want the flexibility to choose the scraping service.
* You need to aggregate results from multiple tools, which is difficult to handle in a Workflow application.
In these cases, your plugin needs to call other existing tools: tools from the marketplace, a self-built Workflow as a Tool, or a custom tool. All of them are available through the plugin's `self.session.tool` field.
## Call Installed Tools
Call any tool installed in the current Workspace, including other tool-type plugins.
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_builtin_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The plugin ID plus the tool provider name, formatted like `langgenius/google/google`.
* **`tool_name`**: The specific tool name.
* **`parameters`**: The arguments passed to the tool.
## Call Workflow as Tool
See the [Tool Plugin documentation](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) for more information on Workflow as Tool.
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_workflow_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The ID of this tool.
* **`tool_name`**: The name specified when the tool was created.
## Call Custom Tool
### Entry Point
```python theme={null}
self.session.tool
```
### Interface
```python theme={null}
def invoke_api_tool(
self, provider: str, tool_name: str, parameters: dict[str, Any]
) -> Generator[ToolInvokeMessage, None, None]:
pass
```
* **`provider`**: The ID of this tool.
* **`tool_name`**: The `operation_id` from the OpenAPI specification. If no `operation_id` exists, this is the `tool_name` automatically generated by Dify, which you can find on the tool management page.
## Related Resources
* [Reverse Invocation of Dify Services](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) - Understand the fundamental concepts of reverse invocation
* [Reverse Invocation App](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-app) - Learn how to call Apps within the platform
* [Reverse Invocation Model](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation-model) - Learn how to call model capabilities within the platform
* [Tool Plugin Development Guide](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) - Learn how to develop tool plugins
* [Advanced Tool Plugins](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) - Learn about advanced features like Workflow as Tool
# General Specs
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/general-specifications
Common data structures shared across plugin types, including I18nObject, ProviderConfig, ModelConfig, NodeResponse, and ToolSelector
This page covers structures common to all plugin types. Read it alongside [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin) and the [Developer Cheatsheet](/en/develop-plugin/getting-started/cli) for a picture of the overall architecture.
## Path Specifications
File paths in the manifest or any YAML file follow two rules, depending on the file type:
* Multimedia files such as images and videos (for example, the plugin's `icon`) go in the `_assets` folder under the plugin's root directory.
* Regular text files, such as `.py` or `.yaml` code files, are referenced by their absolute path within the plugin project.
## Common Structures
Some data structures are shared between tools, models, and Endpoints. They are defined here.
### I18nObject
`I18nObject` is an internationalization structure that conforms to the [IETF BCP 47](https://tools.ietf.org/html/bcp47) standard. Four languages are supported:
<ParamField type="string">
English (United States).
</ParamField>
<ParamField type="string">
Simplified Chinese.
</ParamField>
<ParamField type="string">
Japanese.
</ParamField>
<ParamField type="string">
Portuguese (Brazil).
</ParamField>
### ProviderConfig
`ProviderConfig` is a common provider form structure used by both `Tool` and `Endpoint`.
<ParamField type="string">
Form item name.
</ParamField>
<ParamField type="I18nObject">
Display labels, following the [IETF BCP 47](https://tools.ietf.org/html/bcp47) standard.
</ParamField>
<ParamField type="provider_config_type">
Form field type. Determines how the field is rendered in the UI.
</ParamField>
<ParamField type="provider_config_scope">
Optional range specification. Varies based on the value of `type`.
</ParamField>
<ParamField type="boolean">
Whether the field must not be empty.
</ParamField>
<ParamField type="any">
Default value. Only supports basic types: `float`, `int`, `string`.
</ParamField>
<ParamField type="array[provider_config_option]">
Available options. Only used when `type` is `select`.
</ParamField>
<ParamField type="object">
Help document link label, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
<ParamField type="string">
Help document link.
</ParamField>
<ParamField type="object">
Placeholder text in multiple languages, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
### ProviderConfigOption (object)
<ParamField type="string">
Option value.
</ParamField>
<ParamField type="object">
Option display label, following [IETF BCP 47](https://tools.ietf.org/html/bcp47).
</ParamField>
### ProviderConfigType (string)
<ParamField type="string">
Configuration information that will be encrypted.
</ParamField>
<ParamField type="string">
Plain text input field.
</ParamField>
<ParamField type="string">
Dropdown selection field.
</ParamField>
<ParamField type="boolean">
Switch/toggle control.
</ParamField>
<ParamField type="object">
Model configuration selector, including provider name, model name, and model parameters.
</ParamField>
<ParamField type="object">
Application ID selector.
</ParamField>
<ParamField type="object">
Tool configuration selector, including tool provider, name, and parameters.
</ParamField>
<ParamField type="string">
Dataset selector (TBD).
</ParamField>
### ProviderConfigScope (string)
When `type` is `model-selector`:
<ParamField type="string">
All model types.
</ParamField>
<ParamField type="string">
Large language models only.
</ParamField>
<ParamField type="string">
Text embedding models only.
</ParamField>
<ParamField type="string">
Reranking models only.
</ParamField>
<ParamField type="string">
Text-to-speech models only.
</ParamField>
<ParamField type="string">
Speech-to-text models only.
</ParamField>
<ParamField type="string">
Content moderation models only.
</ParamField>
<ParamField type="string">
Vision models only.
</ParamField>
When `type` is `app-selector`:
<ParamField type="string">
All application types.
</ParamField>
<ParamField type="string">
Chat applications only.
</ParamField>
<ParamField type="string">
Workflow applications only.
</ParamField>
<ParamField type="string">
Completion applications only.
</ParamField>
When `type` is `tool-selector`:
<ParamField type="string">
All tool types.
</ParamField>
<ParamField type="string">
Plugin tools only.
</ParamField>
<ParamField type="string">
API tools only.
</ParamField>
<ParamField type="string">
Workflow tools only.
</ParamField>
### ModelConfig
<ParamField type="string">
Model provider name containing the `plugin_id`, in the form `langgenius/openai/openai`.
</ParamField>
<ParamField type="string">
Specific model name.
</ParamField>
<ParamField type="enum">
Model type enumeration; see [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules#modeltype).
</ParamField>
### NodeResponse
<ParamField type="dict">
Variables ultimately passed into the node.
</ParamField>
<ParamField type="dict">
Output results of the node.
</ParamField>
<ParamField type="dict">
Data generated during node execution.
</ParamField>
### ToolSelector
<ParamField type="string">
Tool provider name.
</ParamField>
<ParamField type="string">
Tool name.
</ParamField>
<ParamField type="string">
Tool description.
</ParamField>
<ParamField type="dict[string, any]">
Tool configuration information.
</ParamField>
<ParamField type="dict[string, dict]">
Parameters that require LLM reasoning.
<ParamField type="string">
Parameter name.
</ParamField>
<ParamField type="string">
Parameter type.
</ParamField>
<ParamField type="boolean">
Whether the parameter is required.
</ParamField>
<ParamField type="string">
Parameter description.
</ParamField>
<ParamField type="any">
Default value.
</ParamField>
<ParamField type="array[string]">
Available options for the parameter.
</ParamField>
</ParamField>
## Related Resources
* [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin)—an overview of Dify plugin development
* [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet)—quick reference for common commands and concepts
* [Tool Plugin Development Details](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin)—defining plugin information and the tool plugin development process
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules)—standards for model configuration
# Model Specs
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules
Reference for the entities that define a Dify model plugin, including Provider, AIModelEntity, model types, configuration methods, parameter rules, and credential schemas
A model plugin describes itself with two entities: a [Provider](#provider) that handles authentication and lists supported models, and one [AIModelEntity](#aimodelentity) per model declaring its type, features, and parameters.
<Note>
All entities below are `Pydantic BaseModel` subclasses from the `dify_plugin.entities.model` module.
</Note>
## Quick Decision
<CardGroup>
<Card title="Authentication only: predefined models" icon="key">
User pastes an API key, gets your full model list. Set `configurate_methods: [predefined-model]` and define each model's AIModelEntity in YAML.
</Card>
<Card title="User-supplied models" icon="user-pen">
User configures their own model name and base URL (OpenAI-compatible endpoints, custom deployments). Use `configurate_methods: [customizable-model]` and see [Customizable Model](/en/develop-plugin/features-and-specs/advanced-development/customizable-model).
</Card>
<Card title="Mixed" icon="layer-group">
Built-in catalog plus user-added custom models. Combine both `configurate_methods` values.
</Card>
<Card title="Walkthrough" icon="route">
For an end-to-end example, see [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
</Card>
</CardGroup>
## Provider
<ParamField type="string">
Provider identifier, for example `openai`.
</ParamField>
<ParamField type="object">
Provider display name (i18n). Supports `en_US` (English) and `zh_Hans` (Chinese).
<ParamField type="string">
Chinese label. Falls back to `en_US` if not set.
</ParamField>
<ParamField type="string">
English label
</ParamField>
</ParamField>
<ParamField type="object">
Provider description (i18n).
<ParamField type="string">
Chinese description.
</ParamField>
<ParamField type="string">
English description.
</ParamField>
</ParamField>
<ParamField type="object">
Small provider icon, stored in the `_assets` directory under the provider implementation directory.
<ParamField type="string">
Chinese icon.
</ParamField>
<ParamField type="string">
English icon.
</ParamField>
</ParamField>
<ParamField type="object">
Large provider icon, stored in the `_assets` directory under the provider implementation directory.
<ParamField type="string">
Chinese icon.
</ParamField>
<ParamField type="string">
English icon.
</ParamField>
</ParamField>
<ParamField type="string">
Background color value, for example `#FFFFFF`. If empty, the frontend default color is used.
</ParamField>
<ParamField type="object">
Help information.
<ParamField type="object">
Help title (i18n).
<ParamField type="string">
Chinese title.
</ParamField>
<ParamField type="string">
English title.
</ParamField>
</ParamField>
<ParamField type="object">
Help link (i18n).
<ParamField type="string">
Chinese link.
</ParamField>
<ParamField type="string">
English link.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="array[ModelType]">
Supported model types.
</ParamField>
<ParamField type="array[ConfigurateMethod]">
Configuration methods.
</ParamField>
<ParamField type="ProviderCredentialSchema">
Provider credential specification.
</ParamField>
<ParamField type="ModelCredentialSchema">
Model credential specification.
</ParamField>
## AIModelEntity
<ParamField type="string">
Model identifier, for example `gpt-3.5-turbo`.
</ParamField>
<ParamField type="object">
Model display name (i18n). Supports `en_US` (English) and `zh_Hans` (Chinese).
<ParamField type="string">
Chinese label.
</ParamField>
<ParamField type="string">
English label.
</ParamField>
</ParamField>
<ParamField type="ModelType">
Model type.
</ParamField>
<ParamField type="array[ModelFeature]">
Supported features.
</ParamField>
<ParamField type="object">
Model properties.
<ParamField type="LLMMode">
Mode (model type `llm`).
</ParamField>
<ParamField type="integer">
Context size (model types `llm` and `text-embedding`).
</ParamField>
<ParamField type="integer">
Maximum number of chunks (model types `text-embedding` and `moderation`).
</ParamField>
<ParamField type="integer">
Maximum file upload size in MB (model type `speech2text`).
</ParamField>
<ParamField type="string">
Supported file extensions, for example `mp3,mp4` (model type `speech2text`).
</ParamField>
<ParamField type="string">
Default voice; one of `alloy`, `echo`, `fable`, `onyx`, `nova`, `shimmer` (model type `tts`).
</ParamField>
<ParamField type="array">
Available voices (model type `tts`).
<ParamField type="string">
Voice model.
</ParamField>
<ParamField type="string">
Voice model display name.
</ParamField>
<ParamField type="string">
Languages the voice model supports.
</ParamField>
</ParamField>
<ParamField type="integer">
Word limit per conversion; defaults to splitting by paragraph (model type `tts`).
</ParamField>
<ParamField type="string">
Supported audio file extensions, for example `mp3,wav` (model type `tts`).
</ParamField>
<ParamField type="integer">
Number of concurrent text-to-audio conversion tasks (model type `tts`).
</ParamField>
<ParamField type="integer">
Maximum characters per chunk (model type `moderation`).
</ParamField>
</ParamField>
<ParamField type="array[ParameterRule]">
Rules for model call parameters.
</ParamField>
<ParamField type="PriceConfig">
Pricing information.
</ParamField>
<ParamField type="boolean">
Whether the model is deprecated. Deprecated models no longer appear in the model list, but existing configurations keep working. Defaults to `False`.
</ParamField>
## ModelType
<ParamField type="string">
Text generation model.
</ParamField>
<ParamField type="string">
Text embedding model.
</ParamField>
<ParamField type="string">
Rerank model.
</ParamField>
<ParamField type="string">
Speech to text.
</ParamField>
<ParamField type="string">
Text to speech.
</ParamField>
<ParamField type="string">
Content moderation.
</ParamField>
## ConfigurateMethod
<ParamField type="string">
Predefined model. The user configures unified provider credentials once to use all predefined models under the provider.
</ParamField>
<ParamField type="string">
Customizable model. The user adds a credential configuration for each model.
</ParamField>
<ParamField type="string">
Fetch from remote. Like `predefined-model`, only unified provider credentials are needed, but the model list is fetched from the provider using those credentials.
</ParamField>
## ModelFeature
<ParamField type="string">
Agent reasoning. Generally, models over 70B have chain-of-thought capabilities.
</ParamField>
<ParamField type="string">
Vision (image understanding).
</ParamField>
<ParamField type="string">
Tool calling.
</ParamField>
<ParamField type="string">
Multiple tool calling.
</ParamField>
<ParamField type="string">
Streaming tool calling.
</ParamField>
## FetchFrom
<ParamField type="string">
Predefined model.
</ParamField>
<ParamField type="string">
Remote model.
</ParamField>
## LLMMode
<ParamField type="string">
Text completion.
</ParamField>
<ParamField type="string">
Chat.
</ParamField>
## ParameterRule
<ParamField type="string">
Actual parameter name used in the model call.
</ParamField>
<ParamField type="string">
Template to use.
</ParamField>
Five parameter templates are predefined:
* `temperature`
* `top_p`
* `frequency_penalty`
* `presence_penalty`
* `max_tokens`
Set one of these names in `use_template` to inherit the default configuration from `entities.defaults.PARAMETER_RULE_TEMPLATE`; you then only need `name` and `use_template`. Any additional parameters you set override the template defaults. See `openai/llm/gpt-3.5-turbo.yaml` and the examples in [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider).
<ParamField type="object">
Label (i18n).
<ParamField type="string">
Chinese label.
</ParamField>
<ParamField type="string">
English label.
</ParamField>
</ParamField>
<ParamField type="string">
Parameter type.
<ParamField type="string">
Integer.
</ParamField>
<ParamField type="string">
Floating point.
</ParamField>
<ParamField type="string">
String.
</ParamField>
<ParamField type="string">
Boolean.
</ParamField>
</ParamField>
<ParamField type="object">
Help information (i18n).
<ParamField type="string">
Chinese help text.
</ParamField>
<ParamField type="string">
English help text.
</ParamField>
</ParamField>
<ParamField type="boolean">
Whether the parameter is required. Defaults to `False`.
</ParamField>
<ParamField type="int/float/string/boolean">
Default value.
</ParamField>
<ParamField type="int/float">
Minimum value. Numeric types only.
</ParamField>
<ParamField type="int/float">
Maximum value. Numeric types only.
</ParamField>
<ParamField type="integer">
Number of decimal places to keep. Numeric types only.
</ParamField>
<ParamField type="array[string]">
Dropdown option values. Only applies when `type` is `string`. If not set or null, values are unrestricted.
</ParamField>
## PriceConfig
<ParamField type="float">
Input (prompt) unit price.
</ParamField>
<ParamField type="float">
Output (returned content) unit price.
</ParamField>
<ParamField type="float">
Price unit. For example, if pricing is per 1M tokens, the unit token count corresponding to the unit price is `0.000001`.
</ParamField>
<ParamField type="string">
Currency unit.
</ParamField>
## ProviderCredentialSchema
<ParamField type="array[CredentialFormSchema]">
Credential form specification.
</ParamField>
## ModelCredentialSchema
<ParamField type="object">
Model identifier. The default variable name is `model`.
<ParamField type="object">
Display name of the model form item.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="object">
Placeholder text for the model form item.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="array[CredentialFormSchema]">
Credential form specification.
</ParamField>
## CredentialFormSchema
<ParamField type="string">
Form item variable name.
</ParamField>
<ParamField type="object">
Form item label.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="FormType">
Form item type.
</ParamField>
<ParamField type="boolean">
Whether the form item is required.
</ParamField>
<ParamField type="string">
Default value.
</ParamField>
<ParamField type="array[FormOption]">
Dropdown content. Specific to the `select` and `radio` types.
</ParamField>
<ParamField type="object">
Form item placeholder. Specific to the `text-input` type.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="integer">
Maximum input length. Specific to the `text-input` type. `0` means no limit.
</ParamField>
<ParamField type="array[FormShowOnObject]">
Show this item only when other form item values meet the given conditions. Empty means always show.
</ParamField>
### FormType
<ParamField type="string">
Text input component.
</ParamField>
<ParamField type="string">
Password input component.
</ParamField>
<ParamField type="string">
Single-select dropdown.
</ParamField>
<ParamField type="string">
Radio component.
</ParamField>
<ParamField type="string">
Switch component. Only supports `true` and `false`.
</ParamField>
### FormOption
<ParamField type="object">
Label.
<ParamField type="string">
English.
</ParamField>
<ParamField type="string">
Chinese.
</ParamField>
</ParamField>
<ParamField type="string">
Dropdown option value.
</ParamField>
<ParamField type="array[FormShowOnObject]">
Show this option only when other form item values meet the given conditions. Empty means always show.
</ParamField>
### FormShowOnObject
<ParamField type="string">
Variable name of the other form item.
</ParamField>
<ParamField type="string">
Variable value of the other form item.
</ParamField>
## Related Resources
* [Model Architecture Details](/en/develop-plugin/features-and-specs/plugin-types/model-schema)—architecture specifications for model plugins
* [Quickly Integrate a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)—apply these rules to add new models
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)—plugin manifest configuration
* [Create a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider)—develop a new model provider plugin
# Model API Interface
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/model-schema
Interfaces and data structures for implementing Dify model plugins, covering LLM, TextEmbedding, Rerank, Speech2Text, Text2Speech, and Moderation models
## Introduction
This page is the technical reference for the interfaces and data structures you implement when integrating AI models with Dify through a model plugin.
<Note>
Before diving into this API reference, we recommend reading [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) for the conceptual model and [Creating a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) for a step-by-step walkthrough.
</Note>
### Quick Decision: Which Method Do I Implement?
| If your model is a... | Implement |
| :-------------------- | :---------------------------------------------- |
| Chat/completion LLM | `LargeLanguageModel._invoke`, `_get_num_tokens` |
| Embedding model | `TextEmbeddingModel._invoke`, `_get_num_tokens` |
| Rerank model | `RerankModel._invoke` |
| Speech-to-text | `Speech2TextModel._invoke` |
| Text-to-speech | `Text2SpeechModel._invoke` |
| Moderation | `ModerationModel._invoke` |
Every provider also implements `validate_provider_credentials` (provider-level auth) and, if the model is user-configurable, `validate_credentials` per model type.
<CardGroup>
<Card title="Provider Implementation" icon="plug" href="#model-provider">
Learn how to implement model provider classes for different AI service providers
</Card>
<Card title="Model Types" icon="layer-group" href="#models">
Implementation details for the five supported model types: LLM, Embedding, Rerank, Speech2Text, and Text2Speech
</Card>
<Card title="Data Structures" icon="database" href="#entities">
Comprehensive reference for all data structures used in the model API
</Card>
<Card title="Error Handling" icon="triangle-exclamation" href="#common-interfaces">
Guidelines for proper error mapping and exception handling
</Card>
</CardGroup>
## Model Provider
Every model provider must inherit from the `__base.model_provider.ModelProvider` base class and implement the credential validation interface.
### Provider Credential Validation
<CodeGroup>
```python Core Implementation theme={null}
def validate_provider_credentials(self, credentials: dict) -> None:
"""
Validate provider credentials by making a test API call
Parameters:
credentials: Provider credentials as defined in `provider_credential_schema`
Raises:
CredentialsValidateFailedError: If validation fails
"""
try:
# Example implementation: validate using an LLM model instance
model_instance = self.get_model_instance(ModelType.LLM)
model_instance.validate_credentials(
model="example-model",
credentials=credentials
)
except Exception as ex:
logger.exception(f"Credential validation failed")
raise CredentialsValidateFailedError(f"Invalid credentials: {str(ex)}")
```
```python Custom Model Provider theme={null}
class XinferenceProvider(Provider):
def validate_provider_credentials(self, credentials: dict) -> None:
"""
For custom-only model providers, a simple implementation is sufficient
as validation happens at the model level
"""
pass
```
</CodeGroup>
<ParamField type="dict">
Credential information as defined in the provider's YAML configuration under `provider_credential_schema`, typically fields such as `api_key` and `organization_id`.
</ParamField>
<Warning>
If validation fails, your implementation must raise a `CredentialsValidateFailedError` exception. This ensures proper error handling in the Dify UI.
</Warning>
<Tip>
For predefined model providers, implement a thorough validation method that verifies the credentials against your API. For custom model providers (where each model has its own credentials), a simplified implementation is sufficient.
</Tip>
## Models
Dify supports five distinct model types, each with its own interface. All model types share the common requirements below.
### Common Interfaces
Every model implementation, regardless of type, must implement these two fundamental methods:
#### 1. Model Credential Validation
<CodeGroup>
```python Implementation theme={null}
def validate_credentials(self, model: str, credentials: dict) -> None:
"""
Validate that the provided credentials work with the specified model
Parameters:
model: The specific model identifier (e.g., "gpt-4")
credentials: Authentication details for the model
Raises:
CredentialsValidateFailedError: If validation fails
"""
try:
# Make a lightweight API call to verify credentials
# Example: List available models or check account status
response = self._api_client.validate_api_key(credentials["api_key"])
# Verify the specific model is available if applicable
if model not in response.get("available_models", []):
raise CredentialsValidateFailedError(f"Model {model} is not available")
except ApiException as e:
raise CredentialsValidateFailedError(str(e))
```
</CodeGroup>
<ParamField type="string">
The specific model identifier to validate (e.g., "gpt-4", "claude-3-opus")
</ParamField>
<ParamField type="dict">
Credential information as defined in the provider's configuration
</ParamField>
#### 2. Error Mapping
<CodeGroup>
```python Implementation theme={null}
@property
def _invoke_error_mapping(self) -> dict[type[InvokeError], list[type[Exception]]]:
"""
Map provider-specific exceptions to standardized Dify error types
Returns:
Dictionary mapping Dify error types to lists of provider exception types
"""
return {
InvokeConnectionError: [
requests.exceptions.ConnectionError,
requests.exceptions.Timeout,
ConnectionRefusedError
],
InvokeServerUnavailableError: [
ServiceUnavailableError,
HTTPStatusError
],
InvokeRateLimitError: [
RateLimitExceededError,
QuotaExceededError
],
InvokeAuthorizationError: [
AuthenticationError,
InvalidAPIKeyError,
PermissionDeniedError
],
InvokeBadRequestError: [
InvalidRequestError,
ValidationError
]
}
```
</CodeGroup>
<Accordion title="Available Error Types">
<ParamField type="class">
Network connection failures, timeouts
</ParamField>
<ParamField type="class">
Service provider is down or unavailable
</ParamField>
<ParamField type="class">
Rate limits or quota limits reached
</ParamField>
<ParamField type="class">
Authentication or permission issues
</ParamField>
<ParamField type="class">
Invalid parameters or requests
</ParamField>
</Accordion>
<Tip>
You can alternatively raise these standardized error types directly in your code instead of relying on the error mapping. This approach gives you more control over error messages.
</Tip>
### LLM Implementation
To implement a Large Language Model provider, inherit from the `__base.large_language_model.LargeLanguageModel` base class and implement these methods:
#### 1. Model Invocation
This core method handles both streaming and non-streaming API calls to language models.
<CodeGroup>
```python Core Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
model_parameters: dict,
tools: Optional[list[PromptMessageTool]] = None,
stop: Optional[list[str]] = None,
stream: bool = True,
user: Optional[str] = None
) -> Union[LLMResult, Generator[LLMResultChunk, None, None]]:
"""
Invoke the language model
"""
# Prepare API parameters
api_params = self._prepare_api_parameters(
model,
credentials,
prompt_messages,
model_parameters,
tools,
stop
)
try:
# Choose between streaming and non-streaming implementation
if stream:
return self._invoke_stream(model, api_params, user)
else:
return self._invoke_sync(model, api_params, user)
except Exception as e:
# Map errors using the error mapping property
self._handle_api_error(e)
# Helper methods for streaming and non-streaming calls
def _invoke_stream(self, model, api_params, user):
# Implement streaming call and yield chunks
pass
def _invoke_sync(self, model, api_params, user):
# Implement synchronous call and return complete result
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Model identifier (e.g., "gpt-4", "claude-3")
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="list[PromptMessage]">
Message list in Dify's standardized format:
* For `completion` models: include a single `UserPromptMessage`.
* For `chat` models: include `SystemPromptMessage`, `UserPromptMessage`, `AssistantPromptMessage`, and `ToolPromptMessage` as needed.
</ParamField>
<ParamField type="dict">
Model-specific parameters (temperature, top\_p, etc.) as defined in the model's YAML configuration
</ParamField>
<ParamField type="list[PromptMessageTool]">
Tool definitions for function calling capabilities
</ParamField>
<ParamField type="list[string]">
Stop sequences that will halt model generation when encountered
</ParamField>
<ParamField type="boolean">
Whether to return a streaming response
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Values">
<ParamField type="Generator[LLMResultChunk, None, None]">
A generator yielding chunks of the response as they become available
</ParamField>
<ParamField type="LLMResult">
A complete response object with the full generated text
</ParamField>
</Accordion>
<Tip>
We recommend implementing separate helper methods for streaming and non-streaming calls to keep your code organized and maintainable.
</Tip>
#### 2. Token Counting
<CodeGroup>
```python Implementation theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
prompt_messages: list[PromptMessage],
tools: Optional[list[PromptMessageTool]] = None
) -> int:
"""
Calculate the number of tokens in the prompt
"""
# Convert prompt_messages to the format expected by the tokenizer
text = self._convert_messages_to_text(prompt_messages)
try:
# Use the appropriate tokenizer for this model
tokenizer = self._get_tokenizer(model)
return len(tokenizer.encode(text))
except Exception:
# Fall back to a generic tokenizer
return self._get_num_tokens_by_gpt2(text)
```
</CodeGroup>
<Info>
If the model doesn't provide a tokenizer, you can use the base class's `_get_num_tokens_by_gpt2(text)` method for a reasonable approximation.
</Info>
#### 3. Custom Model Schema (Optional)
<CodeGroup>
```python Implementation theme={null}
def get_customizable_model_schema(
self,
model: str,
credentials: dict
) -> Optional[AIModelEntity]:
"""
Get parameter schema for custom models
"""
# For fine-tuned models, you might return the base model's schema
if model.startswith("ft:"):
base_model = self._extract_base_model(model)
return self._get_predefined_model_schema(base_model)
# For standard models, return None to use the predefined schema
return None
```
</CodeGroup>
<Info>
This method is only necessary for providers that support custom models. It allows custom models to inherit parameter rules from base models.
</Info>
### TextEmbedding Implementation
<Info>
Text embedding models convert text into high-dimensional vectors that capture semantic meaning, which is useful for retrieval, similarity search, and classification.
</Info>
To implement a Text Embedding provider, inherit from the `__base.text_embedding_model.TextEmbeddingModel` base class:
#### 1. Core Embedding Method
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
texts: list[str],
user: Optional[str] = None
) -> TextEmbeddingResult:
"""
Generate embedding vectors for multiple texts
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Handle batching if needed
batch_size = self._get_batch_size(model)
all_embeddings = []
total_tokens = 0
start_time = time.time()
# Process in batches to avoid API limits
for i in range(0, len(texts), batch_size):
batch = texts[i:i+batch_size]
# Make API call to the embeddings endpoint
response = client.embeddings.create(
model=model,
input=batch,
user=user
)
# Extract embeddings from response
batch_embeddings = [item.embedding for item in response.data]
all_embeddings.extend(batch_embeddings)
# Track token usage
total_tokens += response.usage.total_tokens
# Calculate usage metrics
elapsed_time = time.time() - start_time
usage = self._create_embedding_usage(
model=model,
tokens=total_tokens,
latency=elapsed_time
)
return TextEmbeddingResult(
model=model,
embeddings=all_embeddings,
usage=usage
)
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Embedding model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the embedding service
</ParamField>
<ParamField type="list[string]">
List of text inputs to embed
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="object">
A structured response containing:
* `model`: The model used for embedding.
* `embeddings`: Embedding vectors in the same order as the input texts.
* `usage`: Metadata about token usage and costs.
</ParamField>
</Accordion>
#### 2. Token Counting Method
<CodeGroup>
```python Implementation theme={null}
def get_num_tokens(
self,
model: str,
credentials: dict,
texts: list[str]
) -> int:
"""
Calculate the number of tokens in the texts to be embedded
"""
# Join all texts to estimate token count
combined_text = " ".join(texts)
try:
# Use the appropriate tokenizer for this model
tokenizer = self._get_tokenizer(model)
return len(tokenizer.encode(combined_text))
except Exception:
# Fall back to a generic tokenizer
return self._get_num_tokens_by_gpt2(combined_text)
```
</CodeGroup>
<Tip>
For embedding models, accurate token counting is important for cost estimation, but not critical for functionality. The `_get_num_tokens_by_gpt2` method provides a reasonable approximation for most models.
</Tip>
### Rerank Implementation
<Info>
Reranking models help improve search quality by re-ordering a set of candidate documents based on their relevance to a query, typically after an initial retrieval phase.
</Info>
To implement a Reranking provider, inherit from the `__base.rerank_model.RerankModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
query: str,
docs: list[str],
score_threshold: Optional[float] = None,
top_n: Optional[int] = None,
user: Optional[str] = None
) -> RerankResult:
"""
Rerank documents based on relevance to the query
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Prepare request data
request_data = {
"query": query,
"documents": docs,
}
# Call reranking API endpoint
response = client.rerank(
model=model,
**request_data,
user=user
)
# Process results
ranked_results = []
for i, result in enumerate(response.results):
# Create RerankDocument for each result
doc = RerankDocument(
index=result.document_index, # Original index in docs list
text=docs[result.document_index], # Original text
score=result.relevance_score # Relevance score
)
ranked_results.append(doc)
# Sort by score in descending order
ranked_results.sort(key=lambda x: x.score, reverse=True)
# Apply score threshold filtering if specified
if score_threshold is not None:
ranked_results = [doc for doc in ranked_results if doc.score >= score_threshold]
# Apply top_n limit if specified
if top_n is not None and top_n > 0:
ranked_results = ranked_results[:top_n]
return RerankResult(
model=model,
docs=ranked_results
)
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Reranking model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
The search query text
</ParamField>
<ParamField type="list[string]">
List of document texts to be reranked
</ParamField>
<ParamField type="float">
Minimum score a document must reach to be included in the results
</ParamField>
<ParamField type="int">
Maximum number of results to return
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="object">
A structured response containing:
* `model`: The model used for reranking.
* `docs`: List of `RerankDocument` objects with index, text, and score.
</ParamField>
</Accordion>
<Warning>
Reranking can be computationally expensive, especially with large document sets. Implement batching for large document collections to avoid timeouts or excessive resource consumption.
</Warning>
### Speech2Text Implementation
<Info>
Speech-to-text models convert spoken language from audio files into written text, enabling applications like transcription services, voice commands, and accessibility features.
</Info>
To implement a Speech-to-Text provider, inherit from the `__base.speech2text_model.Speech2TextModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
file: IO[bytes],
user: Optional[str] = None
) -> str:
"""
Convert speech audio to text
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Determine the file format
file_format = self._detect_audio_format(file)
# Prepare the file for API submission
# Most APIs require either a file path or binary data
audio_data = file.read()
# Call the speech-to-text API
response = client.audio.transcriptions.create(
model=model,
file=("audio.mp3", audio_data), # Adjust filename based on actual format
user=user
)
# Extract and return the transcribed text
return response.text
except Exception as e:
# Map to appropriate error type
self._handle_api_error(e)
finally:
# Reset file pointer for potential reuse
file.seek(0)
```
```python Helper Methods theme={null}
def _detect_audio_format(self, file: IO[bytes]) -> str:
"""
Detect the audio format based on file header
"""
# Read the first few bytes to check the file signature
header = file.read(12)
file.seek(0) # Reset file pointer
# Check for common audio format signatures
if header.startswith(b'RIFF') and header[8:12] == b'WAVE':
return 'wav'
elif header.startswith(b'ID3') or header.startswith(b'\xFF\xFB'):
return 'mp3'
elif header.startswith(b'OggS'):
return 'ogg'
elif header.startswith(b'fLaC'):
return 'flac'
else:
# Default or additional format checks
return 'mp3' # Default assumption
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Speech-to-text model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="IO[bytes]">
Binary file object containing the audio to transcribe
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="string">
The transcribed text from the audio file
</ParamField>
</Accordion>
<Tip>
Audio format detection is important for proper handling of different file types. Consider implementing a helper method to detect the format from the file header as shown in the example.
</Tip>
<Warning>
Some speech-to-text APIs have file size limitations. Consider implementing chunking for large audio files if necessary.
</Warning>
### Text2Speech Implementation
<Info>
Text-to-speech models convert written text into natural-sounding speech, enabling applications such as voice assistants, screen readers, and audio content generation.
</Info>
To implement a Text-to-Speech provider, inherit from the `__base.text2speech_model.Text2SpeechModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
content_text: str,
streaming: bool,
user: Optional[str] = None
) -> Union[bytes, Generator[bytes, None, None]]:
"""
Convert text to speech audio
"""
# Set up API client with credentials
client = self._get_client(credentials)
# Get voice settings based on model
voice = self._get_voice_for_model(model)
try:
# Choose implementation based on streaming preference
if streaming:
return self._stream_audio(
client=client,
model=model,
text=content_text,
voice=voice,
user=user
)
else:
return self._generate_complete_audio(
client=client,
model=model,
text=content_text,
voice=voice,
user=user
)
except Exception as e:
self._handle_api_error(e)
```
```python Helper Methods theme={null}
def _stream_audio(self, client, model, text, voice, user=None):
"""
Implementation for streaming audio output
"""
# Make API request with stream=True
response = client.audio.speech.create(
model=model,
voice=voice,
input=text,
stream=True,
user=user
)
# Yield chunks as they arrive
for chunk in response:
if chunk:
yield chunk
def _generate_complete_audio(self, client, model, text, voice, user=None):
"""
Implementation for complete audio file generation
"""
# Make API request for complete audio
response = client.audio.speech.create(
model=model,
voice=voice,
input=text,
user=user
)
# Get audio data as bytes
audio_data = response.content
return audio_data
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Text-to-speech model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
Text content to be converted to speech
</ParamField>
<ParamField type="boolean">
Whether to return streaming audio or complete file
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="Generator[bytes, None, None]">
A generator yielding audio chunks as they become available
</ParamField>
<ParamField type="bytes">
Complete audio data as bytes
</ParamField>
</Accordion>
<Tip>
Most text-to-speech APIs require you to specify a voice along with the model. Consider implementing a mapping between Dify's model identifiers and the provider's voice options.
</Tip>
<Warning>
Long text inputs may need to be chunked for better speech synthesis quality. Consider implementing text preprocessing to handle punctuation, numbers, and special characters properly.
</Warning>
### Moderation Implementation
<Info>
Moderation models analyze content for potentially harmful, inappropriate, or unsafe material, helping maintain platform safety and content policies.
</Info>
To implement a Moderation provider, inherit from the `__base.moderation_model.ModerationModel` base class:
<CodeGroup>
```python Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
text: str,
user: Optional[str] = None
) -> bool:
"""
Analyze text for harmful content
Returns:
bool: False if the text is safe, True if it contains harmful content
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Call moderation API
response = client.moderations.create(
model=model,
input=text,
user=user
)
# Check if any categories were flagged
result = response.results[0]
# Return True if flagged in any category, False if safe
return result.flagged
except Exception as e:
# Log the error but default to safe if there's an API issue.
# This is a conservative approach; production systems might want
# different fallback behavior.
logger.error(f"Moderation API error: {str(e)}")
return False
```
```python Detailed Implementation theme={null}
def _invoke(
self,
model: str,
credentials: dict,
text: str,
user: Optional[str] = None
) -> bool:
"""
Analyze text for harmful content with detailed category checking
"""
# Set up API client with credentials
client = self._get_client(credentials)
try:
# Call moderation API
response = client.moderations.create(
model=model,
input=text,
user=user
)
# Get detailed category results
result = response.results[0]
categories = result.categories
# Check specific categories based on your application's needs
# For example, you might want to flag certain categories but not others
critical_violations = [
categories.harassment,
categories.hate,
categories.self_harm,
categories.sexual,
categories.violence
]
# Flag content if any critical category is violated
return any(critical_violations)
except Exception as e:
self._handle_api_error(e)
# Default to safe in case of error
return False
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Moderation model identifier
</ParamField>
<ParamField type="dict">
Authentication credentials for the API
</ParamField>
<ParamField type="string">
Text content to be analyzed
</ParamField>
<ParamField type="string">
User identifier for API monitoring
</ParamField>
</Accordion>
<Accordion title="Return Value">
<ParamField type="boolean">
Boolean indicating content safety:
* `False`: The content is safe.
* `True`: The content contains harmful material.
</ParamField>
</Accordion>
<Warning>
Moderation is often used as a safety mechanism. Consider the implications of false negatives (letting harmful content through) versus false positives (blocking safe content) when implementing your solution.
</Warning>
<Tip>
Many moderation APIs provide detailed category scores rather than just a binary result. Consider extending this implementation to return more detailed information about specific categories of harmful content if your application needs it.
</Tip>
## Entities
### PromptMessageRole
The role of a message in a conversation.
```python theme={null}
class PromptMessageRole(Enum):
"""
Enum class for prompt message.
"""
SYSTEM = "system"
USER = "user"
ASSISTANT = "assistant"
TOOL = "tool"
```
### PromptMessageContentType
The type of message content: plain text or image.
```python theme={null}
class PromptMessageContentType(Enum):
"""
Enum class for prompt message content type.
"""
TEXT = 'text'
IMAGE = 'image'
```
### PromptMessageContent
Base class for message content. It exists only for type declarations—do not instantiate it directly.
```python theme={null}
class PromptMessageContent(BaseModel):
"""
Model class for prompt message content.
"""
type: PromptMessageContentType
data: str # Content data
```
Content currently supports two types, text and image, and a single message can combine text with multiple images. Instantiate `TextPromptMessageContent` and `ImagePromptMessageContent` instead.
### TextPromptMessageContent
```python theme={null}
class TextPromptMessageContent(PromptMessageContent):
"""
Model class for text prompt message content.
"""
type: PromptMessageContentType = PromptMessageContentType.TEXT
```
When a message combines text and images, wrap the text in this entity and add it to the `content` list.
### ImagePromptMessageContent
```python theme={null}
class ImagePromptMessageContent(PromptMessageContent):
"""
Model class for image prompt message content.
"""
class DETAIL(Enum):
LOW = 'low'
HIGH = 'high'
type: PromptMessageContentType = PromptMessageContentType.IMAGE
detail: DETAIL = DETAIL.LOW # Resolution
```
When a message combines text and images, wrap each image in this entity and add it to the `content` list. `data` accepts an image URL or a base64-encoded image string.
### PromptMessage
Base class for all role-specific messages. It exists only for type declarations—do not instantiate it directly.
```python theme={null}
class PromptMessage(ABC, BaseModel):
"""
Model class for prompt message.
"""
role: PromptMessageRole # Message role
content: Optional[str | list[PromptMessageContent]] = None # Either a string or a content list; the list form supports multimodal input, see PromptMessageContent
name: Optional[str] = None # Optional name
```
### UserPromptMessage
Represents a user message.
```python theme={null}
class UserPromptMessage(PromptMessage):
"""
Model class for user prompt message.
"""
role: PromptMessageRole = PromptMessageRole.USER
```
### AssistantPromptMessage
Represents a model response, typically used for few-shot examples or chat history input.
```python theme={null}
class AssistantPromptMessage(PromptMessage):
"""
Model class for assistant prompt message.
"""
class ToolCall(BaseModel):
"""
Model class for assistant prompt message tool call.
"""
class ToolCallFunction(BaseModel):
"""
Model class for assistant prompt message tool call function.
"""
name: str # Tool name
arguments: str # Tool parameters
id: str # Tool call ID; only meaningful for OpenAI tool calls. Uniquely identifies one invocation, since the same tool can be called multiple times
type: str # Defaults to "function"
function: ToolCallFunction # Tool call information
role: PromptMessageRole = PromptMessageRole.ASSISTANT
tool_calls: list[ToolCall] = [] # Model's tool call results (only returned when tools are passed in and the model decides to call them)
```
`tool_calls` holds the tool calls the model returns when the request includes `tools`.
### SystemPromptMessage
Represents a system message, typically used to set system instructions for the model.
```python theme={null}
class SystemPromptMessage(PromptMessage):
"""
Model class for system prompt message.
"""
role: PromptMessageRole = PromptMessageRole.SYSTEM
```
### ToolPromptMessage
Represents a tool message, which passes a tool's execution result back to the model for next-step planning.
```python theme={null}
class ToolPromptMessage(PromptMessage):
"""
Model class for tool prompt message.
"""
role: PromptMessageRole = PromptMessageRole.TOOL
tool_call_id: str # Tool call ID; if the provider doesn't support OpenAI tool calls, you can pass the tool name instead
```
Pass the tool's execution result through the inherited `content` field.
### PromptMessageTool
```python theme={null}
class PromptMessageTool(BaseModel):
"""
Model class for prompt message tool.
"""
name: str # Tool name
description: str # Tool description
parameters: dict # Tool parameters dict
```
### LLMResult
```python theme={null}
class LLMResult(BaseModel):
"""
Model class for llm result.
"""
model: str # Model actually used
prompt_messages: list[PromptMessage] # Prompt message list
message: AssistantPromptMessage # Reply message
usage: LLMUsage # Token usage and cost information
system_fingerprint: Optional[str] = None # Request fingerprint; see OpenAI's parameter definition
```
### LLMResultChunkDelta
The incremental delta within each chunk of a streaming response.
```python theme={null}
class LLMResultChunkDelta(BaseModel):
"""
Model class for llm result chunk delta.
"""
index: int # Sequence number
message: AssistantPromptMessage # Reply message
usage: Optional[LLMUsage] = None # Token usage and cost information; only returned in the last chunk
finish_reason: Optional[str] = None # Completion reason; only returned in the last chunk
```
### LLMResultChunk
A single chunk in a streaming response.
```python theme={null}
class LLMResultChunk(BaseModel):
"""
Model class for llm result chunk.
"""
model: str # Model actually used
prompt_messages: list[PromptMessage] # Prompt message list
system_fingerprint: Optional[str] = None # Request fingerprint; see OpenAI's parameter definition
delta: LLMResultChunkDelta # Content changes in this chunk
```
### LLMUsage
```python theme={null}
class LLMUsage(ModelUsage):
"""
Model class for llm usage.
"""
prompt_tokens: int # Tokens used by the prompt
prompt_unit_price: Decimal # Prompt unit price
prompt_price_unit: Decimal # Prompt price unit, i.e., the number of tokens the unit price applies to
prompt_price: Decimal # Prompt cost
completion_tokens: int # Tokens used by the completion
completion_unit_price: Decimal # Completion unit price
completion_price_unit: Decimal # Completion price unit, i.e., the number of tokens the unit price applies to
completion_price: Decimal # Completion cost
total_tokens: int # Total tokens used
total_price: Decimal # Total cost
currency: str # Currency unit
latency: float # Request latency in seconds
```
### TextEmbeddingResult
```python theme={null}
class TextEmbeddingResult(BaseModel):
"""
Model class for text embedding result.
"""
model: str # Model actually used
embeddings: list[list[float]] # Embedding vectors, in the same order as the input texts
usage: EmbeddingUsage # Usage information
```
### EmbeddingUsage
```python theme={null}
class EmbeddingUsage(ModelUsage):
"""
Model class for embedding usage.
"""
tokens: int # Tokens used
total_tokens: int # Total tokens used
unit_price: Decimal # Unit price
price_unit: Decimal # Price unit, i.e., the number of tokens the unit price applies to
total_price: Decimal # Total cost
currency: str # Currency unit
latency: float # Request latency in seconds
```
### RerankResult
```python theme={null}
class RerankResult(BaseModel):
"""
Model class for rerank result.
"""
model: str # Model actually used
docs: list[RerankDocument] # List of reranked documents
```
### RerankDocument
```python theme={null}
class RerankDocument(BaseModel):
"""
Model class for rerank document.
"""
index: int # Index in the original docs list
text: str # Document text
score: float # Relevance score
```
## Related Resources
* [Model Design Rules](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): standards for model configuration.
* [Model Plugin Introduction](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules): core concepts of model plugins.
* [Quickly Integrate a New Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): add new models to existing providers.
* [Create a New Model Provider](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider): develop a new model provider from scratch.
# Multilingual README
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme
Add per-language README files so Dify Marketplace shows your plugin's documentation in each user's preferred language
A plugin's README is the first thing users read on the [Dify Marketplace](https://marketplace.dify.ai) detail page. Adding translations lets non-English users read your docs in their own language without losing the original.
## File Specifications
| Language | Required | Filename | Path |
| :------------------ | :------- | :------------------ | :---------- |
| English | Yes | `README.md` | Plugin root |
| Simplified Chinese | No | `README_zh_Hans.md` | `readme/` |
| Japanese | No | `README_ja_JP.md` | `readme/` |
| Portuguese (Brazil) | No | `README_pt_BR.md` | `readme/` |
All files must be UTF-8 encoded. The English `README.md` always stays in the plugin root; every other language goes inside a `readme/` subdirectory.
```text theme={null}
your_plugin/
├── README.md
├── readme/
│ ├── README_zh_Hans.md
│ ├── README_ja_JP.md
│ └── README_pt_BR.md
├── manifest.yaml
├── main.py
└── ...
```
## Recommended Structure
Keep READMEs concise, under \~500 words. The Marketplace detail page surfaces the README directly, so optimize it for someone evaluating whether to install:
```markdown theme={null}
# Plugin Name
One-sentence summary of what the plugin does.
## Features
- Key capability 1
- Key capability 2
- Key capability 3
## Setup
1. Where to get the credentials (link to the upstream service).
2. Where to paste them in Dify.
## Usage
A minimal example — for a tool, show the inputs and outputs. For a model
provider, show the model selector. Screenshots help.
## Privacy
Briefly describe what data the plugin sends to third parties. Link to your
PRIVACY.md.
```
Avoid putting a full API reference or development notes in the README; those belong in source comments or a separate docs site. The Marketplace audience is end users picking a plugin, not contributors reading your codebase.
## How the Marketplace Picks a Language
When a visitor opens your plugin's detail page, the Marketplace looks for a README matching their UI language. If a match exists in the `readme/` directory, it renders that file. Otherwise it falls back to the English `README.md`.
<Frame>
<img alt="Plugin Detail Page in English" />
</Frame>
<Note>
Language codes are matched exactly: `README_zh_Hans.md` serves Simplified Chinese only; Traditional Chinese users see the English fallback.
</Note>
# Persistent Storage
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv
Store data across plugin interactions with the built-in key-value storage
## Overview
Most plugin tools and endpoints operate in a stateless, single-round interaction model:
1. Receive a request
2. Process data
3. Return a response
4. End the interaction
However, many real-world applications require maintaining state across multiple interactions. This is where **persistent storage** becomes essential.
<Info>
Persistent storage lets plugins keep data within the same workspace across interactions, enabling stateful applications and memory features.
</Info>
Dify currently provides a key-value (KV) storage system for plugins; more flexible and powerful storage interfaces are planned based on developer needs.
## Access Storage
All storage operations are performed through the `storage` object available in your plugin's session:
```python theme={null}
# Access the storage interface
storage = self.session.storage
```
## Storage Operations
### Store Data
Store data with the `set` method:
```python theme={null}
def set(self, key: str, val: bytes) -> None:
"""
Store data in persistent storage
Parameters:
key: Unique identifier for your data
val: Binary data to store (bytes)
"""
pass
```
<Warning>
The value must be in `bytes` format. This provides flexibility to store various types of data, including files.
</Warning>
#### Example: Storing Different Data Types
```python theme={null}
# String data (must convert to bytes)
storage.set("user_name", "John Doe".encode('utf-8'))
# JSON data
import json
user_data = {"name": "John", "age": 30, "preferences": ["AI", "NLP"]}
storage.set("user_data", json.dumps(user_data).encode('utf-8'))
# File data
with open("image.jpg", "rb") as f:
image_data = f.read()
storage.set("profile_image", image_data)
```
### Retrieve Data
Retrieve stored data with the `get` method:
```python theme={null}
def get(self, key: str) -> bytes:
"""
Retrieve data from persistent storage
Parameters:
key: Unique identifier for your data
Returns:
The stored data as bytes, or None if key doesn't exist
"""
pass
```
#### Example: Retrieving and Converting Data
```python theme={null}
# Retrieving string data
name_bytes = storage.get("user_name")
if name_bytes:
name = name_bytes.decode('utf-8')
print(f"Retrieved name: {name}")
# Retrieving JSON data
import json
user_data_bytes = storage.get("user_data")
if user_data_bytes:
user_data = json.loads(user_data_bytes.decode('utf-8'))
print(f"User preferences: {user_data['preferences']}")
```
### Delete Data
Delete stored data with the `delete` method:
```python theme={null}
def delete(self, key: str) -> None:
"""
Delete data from persistent storage
Parameters:
key: Unique identifier for the data to delete
"""
pass
```
## Best Practices
<CardGroup>
<Card title="Use Descriptive Keys" icon="key">
Create a consistent naming scheme for your keys to avoid conflicts and make your code more maintainable.
</Card>
<Card title="Handle Missing Keys" icon="triangle-exclamation">
Always check if data exists before processing it, as the key might not be found.
</Card>
<Card title="Serialize Complex Data" icon="code">
Convert complex objects to JSON or other serialized formats before storing.
</Card>
<Card title="Implement Error Handling" icon="shield">
Wrap storage operations in try/except blocks to handle potential errors gracefully.
</Card>
</CardGroup>
## Common Use Cases
* **User preferences**: Store user settings and preferences between sessions.
* **Conversation history**: Maintain context from previous conversations.
* **API tokens**: Store authentication tokens securely.
* **Cached data**: Store frequently accessed data to reduce API calls.
* **File storage**: Store user-uploaded files or generated content.
# Manifest
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/plugin-info-by-manifest
YAML schema for the plugin manifest that declares name, author, runtime, resources, permissions, and which tools/models/endpoints the plugin ships
The manifest is a YAML file that defines a plugin's basic information: name, author, included tools and models, and more. If the file is malformed, plugin parsing and packaging fails.
For the overall plugin architecture, see [Basic Concepts of Plugin Development](/en/develop-plugin/getting-started/getting-started-dify-plugin) and the [Developer Cheatsheet](/en/develop-plugin/dev-guides-and-walkthroughs/cheatsheet).
## Code Example
Below is a simple manifest file; each field is explained in the Structure section that follows. For a real-world example, see the [Google tool plugin manifest](https://github.com/langgenius/dify-official-plugins/blob/main/tools/google/manifest.yaml).
```yaml theme={null}
version: 0.0.1
type: "plugin"
author: "Yeuoly"
name: "neko"
label:
en_US: "Neko"
created_at: "2024-07-12T08:03:44.658609186Z"
icon: "icon.svg"
resource:
memory: 1048576
permission:
tool:
enabled: true
model:
enabled: true
llm: true
endpoint:
enabled: true
app:
enabled: true
storage:
enabled: true
size: 1048576
plugins:
endpoints:
- "provider/neko.yaml"
meta:
version: 0.0.1
arch:
- "amd64"
- "arm64"
runner:
language: "python"
version: "3.12"
entrypoint: "main"
privacy: "./privacy.md"
```
## Structure
<ParamField type="version">
Plugin version.
</ParamField>
<ParamField type="string">
Plugin type. Currently only `plugin` is supported; `bundle` support is planned.
</ParamField>
<ParamField type="string">
Author, defined as the organization name in the Marketplace.
</ParamField>
<ParamField type="object">
Multilingual name.
</ParamField>
<ParamField type="RFC3339">
Creation time. The Marketplace requires this to be no later than the current time.
</ParamField>
<ParamField type="string">
Icon path.
</ParamField>
<ParamField type="object">
Resources the plugin requests.
<ParamField type="int64">
Maximum memory usage in bytes. Mainly relates to AWS Lambda resource allocation on Dify Cloud.
</ParamField>
<ParamField type="object">
Permissions the plugin requests.
<ParamField type="object">
Permission for reverse invocation of tools.
<ParamField type="boolean">
Whether to enable tool permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of models.
<ParamField type="boolean">
Whether to enable model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable large language model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable text embedding model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable rerank model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable text-to-speech model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable speech-to-text model permissions.
</ParamField>
<ParamField type="boolean">
Whether to enable content moderation model permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of nodes.
<ParamField type="boolean">
Whether to enable node permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission to register `endpoint`.
<ParamField type="boolean">
Whether to enable endpoint permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission for reverse invocation of `app`.
<ParamField type="boolean">
Whether to enable app permissions.
</ParamField>
</ParamField>
<ParamField type="object">
Permission to apply for persistent storage.
<ParamField type="boolean">
Whether to enable storage permissions.
</ParamField>
<ParamField type="int64">
Maximum allowed persistent storage size, in bytes.
</ParamField>
</ParamField>
</ParamField>
</ParamField>
<ParamField type="object">
Lists the YAML files for the capabilities the plugin extends, as absolute paths within the plugin package. For example, to extend a model, define a file such as `openai.yaml` and list its path here. The file must exist at that path, or packaging fails.
<Warning>
The following combinations are not allowed:
* Extending both tools and models.
* Extending both models and Endpoints.
* Having no extensions at all.
Currently, each extension type supports only one provider.
</Warning>
<ParamField type="array[string]">
Plugin extension for [Tool](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Model](/en/develop-plugin/features-and-specs/plugin-types/model-designing-rules) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Endpoints](/en/develop-plugin/dev-guides-and-walkthroughs/develop-a-slack-bot-plugin) providers.
</ParamField>
<ParamField type="array[string]">
Plugin extension for [Agent Strategy](/en/develop-plugin/features-and-specs/advanced-development/reverse-invocation) providers.
</ParamField>
</ParamField>
<ParamField type="object">
Metadata for the plugin.
<ParamField type="version">
Manifest format version. The initial version is `0.0.1`.
</ParamField>
<ParamField type="array[string]">
Supported architectures. Currently only `amd64` and `arm64` are supported.
</ParamField>
<ParamField type="object">
Runtime configuration.
<ParamField type="string">
Programming language. Currently only Python is supported.
</ParamField>
<ParamField type="string">
Language version. Currently only `3.12` is supported.
</ParamField>
<ParamField type="string">
Program entry point. For Python, this should be `main`.
</ParamField>
</ParamField>
</ParamField>
<ParamField type="string">
Relative path or URL of the plugin's privacy policy, for example `"./privacy.md"` or `"https://your-web/privacy"`. **Required for listing on the Dify Marketplace**, where plugins must clearly state how they use user data. For details, see the [Plugin Privacy Data Protection Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
</ParamField>
# Plugin Logging
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/plugin-logging
Emit logs from your plugin with the SDK's plugin_logger_handler, visible during remote debugging and in daemon container logs
While developing or debugging a plugin, you often want to log what your code is doing.
The plugin SDK provides a handler for Python's standard `logging` library. Add it to your logger to write any string to both the standard output during remote debugging and the plugin daemon container logs (Community Edition only).
## Example
Import `plugin_logger_handler` and add it to your logger. The following example shows a tool plugin.
```python theme={null}
from collections.abc import Generator
from typing import Any
from dify_plugin import Tool
from dify_plugin.entities.tool import ToolInvokeMessage
# Import logging and custom handler
import logging
from dify_plugin.config.logger_format import plugin_logger_handler
# Set up logging with the custom handler
logger = logging.getLogger(__name__)
logger.setLevel(logging.INFO)
logger.addHandler(plugin_logger_handler)
class LoggerDemoTool(Tool):
def _invoke(self, tool_parameters: dict[str, Any]) -> Generator[ToolInvokeMessage]:
# Log messages with different severity levels
logger.info("This is an INFO log message.")
logger.warning("This is a WARNING log message.")
logger.error("This is an ERROR log message.")
yield self.create_text_message("Hello, Dify!")
```
# Plugin Debugging
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin
Run your in-development plugin locally and attach it to a live Dify workspace for end-to-end testing, no packaging required
Remote debugging is the fastest way to iterate on a plugin. You run the plugin process on your laptop, and Dify treats it as if it were installed in the workspace. Save your edits and restart the process, and the changes take effect immediately.
## Prerequisites
* A Dify workspace where you can access **Plugins** in the top-right corner.
* A scaffolded plugin project (see [CLI](/en/develop-plugin/getting-started/cli) if you haven't created one yet).
* Python 3.12 and the plugin's dependencies installed (`pip install -r requirements.txt`).
## Step 1: Get the Debug URL and Key
Open the **Plugins** page in Dify and click the debug icon (the small bug icon next to **Install Plugin**). A dialog shows the **remote install host:port** and an **API key**.
<Frame>

</Frame>
<Tabs>
<Tab title="Dify Cloud">
The host is something like `debug-plugin.dify.dev:5003`. The key is unique to your workspace; anyone with the key can attach a plugin, so do not share it.
</Tab>
<Tab title="Self-hosted">
The host defaults to `127.0.0.1:5003` and is configured by `PLUGIN_REMOTE_INSTALLING_HOST` / `PLUGIN_REMOTE_INSTALLING_PORT` in the plugin daemon's environment. Make sure port `5003` is reachable from your dev machine. If Dify runs in Docker on the same host, use the daemon container's bridge IP (or expose the port).
</Tab>
</Tabs>
## Step 2: Configure the Plugin's `.env`
In your plugin project, copy `.env.example` to `.env` and fill in the values:
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
<Note>
`REMOTE_INSTALL_URL` is the combined `host:port` from Step 1, not two separate variables.
</Note>
## Step 3: Run the Plugin
From the plugin project directory:
```bash theme={null}
pip install -r requirements.txt
python -m main
```
The process stays in the foreground and logs incoming invocations. Edit your code and restart the process to apply changes.
## Step 4: Verify the Install
Go back to the Dify **Plugins** page. The plugin appears in the list, labeled with a debug marker. Other members of the workspace can also see and use it.
<Frame>

</Frame>
<Check>
The plugin tile shows a debug indicator and your local terminal logs the first registration handshake. You're attached.
</Check>
Trigger the plugin as you would any other: call it from a workflow node, run it as a tool inside an Agent, or hit an endpoint URL. Invocations land on your local process and you can attach a debugger.
## Troubleshooting
<AccordionGroup>
<Accordion title="Connection refused / cannot reach host">
The daemon is not listening on the address you put in `REMOTE_INSTALL_URL`. On self-hosted setups, confirm the daemon container has `PLUGIN_REMOTE_INSTALLING_ENABLED=true` and that port `5003` is exposed. On cloud, double-check you copied the host:port exactly as shown in the debug dialog.
</Accordion>
<Accordion title="Plugin starts but never appears in the Plugins list">
The most common cause is a stale or wrong `REMOTE_INSTALL_KEY`. Regenerate the key from the debug dialog and rerun `python -m main`. Also confirm the daemon log shows the incoming registration.
</Accordion>
<Accordion title="`plugin_unique_identifier is not valid`">
The `author` field in `manifest.yaml` or in `provider/*.yaml` doesn't match a value the daemon accepts. Set it to your GitHub handle, then restart.
</Accordion>
<Accordion title="Changes don't take effect">
The plugin process needs to restart after every edit; there's no hot reload. Stop with `Ctrl+C` and rerun `python -m main`.
</Accordion>
</AccordionGroup>
## Related Resources
* [CLI](/en/develop-plugin/getting-started/cli)—Scaffold a plugin and set up `.env`
* [Plugin Logging](/en/develop-plugin/features-and-specs/plugin-types/plugin-logging)—Emit structured logs from inside your plugin
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file)—Ship the plugin once debugging is done
# Tool Return
Source: https://docs.dify.ai/en/develop-plugin/features-and-specs/plugin-types/tool
How tool plugins return messages (text, links, images, files, JSON), create standard and streaming variables, and define output schemas for workflow references
## Overview
A tool returns its results as messages and variables. This page covers the message interfaces, variable creation, and output schema definitions.
<CardGroup>
<Card title="Message Types" icon="comment-dots" href="#message-return">
Return different types of messages such as text, links, images, and JSON
</Card>
<Card title="Variables" icon="code-branch" href="#variables">
Create and manipulate variables for workflow integration
</Card>
<Card title="Output Schema" icon="diagram-project" href="#custom-output-variables">
Define custom output variables for workflow references
</Card>
</CardGroup>
## Data Structure
### Message Return
Dify supports several message types—text, links, images, file blobs, and JSON—each returned through a dedicated interface.
By default, a tool's output in a workflow includes three fixed variables: `files`, `text`, and `json`. The methods below populate these variables.
<Tip>
While you can use methods like `create_image_message` to return an image, tools also support custom output variables, which make it easier to reference specific data in a workflow.
</Tip>
### Message Types
<CodeGroup>
```python Image URL theme={null}
def create_image_message(self, image: str) -> ToolInvokeMessage:
"""
Return an image URL message
Dify will automatically download the image from the provided URL
and display it to the user.
Args:
image: URL to an image file
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Link theme={null}
def create_link_message(self, link: str) -> ToolInvokeMessage:
"""
Return a clickable link message
Args:
link: URL to be displayed as a clickable link
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Text theme={null}
def create_text_message(self, text: str) -> ToolInvokeMessage:
"""
Return a text message
Args:
text: Text content to be displayed
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python File theme={null}
def create_blob_message(self, blob: bytes, meta: dict = None) -> ToolInvokeMessage:
"""
Return a file blob message
For returning raw file data such as images, audio, video,
or documents (PPT, Word, Excel, etc.)
Args:
blob: Raw file data in bytes
meta: File metadata dictionary. Include 'mime_type' to specify
the file type, otherwise 'octet/stream' will be used
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python JSON theme={null}
def create_json_message(self, json: dict) -> ToolInvokeMessage:
"""
Return a formatted JSON message
Useful for data transmission between workflow nodes.
In agent mode, most LLMs can read and understand JSON data.
Args:
json: Python dictionary to be serialized as JSON
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
URL to an image that will be downloaded and displayed.
</ParamField>
<ParamField type="string">
URL to display as a clickable link.
</ParamField>
<ParamField type="string">
Text content to display.
</ParamField>
<ParamField type="bytes">
Raw file data in bytes.
</ParamField>
<ParamField type="dict">
File metadata, including:
* `mime_type`: The MIME type of the file, for example `image/png`.
* Other metadata relevant to the file.
</ParamField>
<ParamField type="dict">
Python dictionary to serialize as JSON.
</ParamField>
</Accordion>
<Tip>
When working with file blobs, always specify the `mime_type` in the `meta` dictionary to ensure proper handling of the file. For example: `{"mime_type": "image/png"}`.
</Tip>
### Variables
<CodeGroup>
```python Standard Variable theme={null}
from typing import Any
def create_variable_message(self, variable_name: str, variable_value: Any) -> ToolInvokeMessage:
"""
Create a named variable for workflow integration
For non-streaming output variables. If multiple instances with the
same name are created, the latest one overrides previous values.
Args:
variable_name: Name of the variable to create
variable_value: Value of the variable (any Python data type)
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
```python Streaming Variable theme={null}
def create_stream_variable_message(
self, variable_name: str, variable_value: str
) -> ToolInvokeMessage:
"""
Create a streaming variable with typewriter effect
When referenced in an answer node in a Chatflow application,
the text will be output with a typewriter effect.
Args:
variable_name: Name of the variable to create
variable_value: String value to stream (only strings supported)
Returns:
ToolInvokeMessage: Message object for the tool response
"""
pass
```
</CodeGroup>
<Accordion title="Parameters">
<ParamField type="string">
Name of the variable to create or update.
</ParamField>
<ParamField type="Any/string">
Value to assign to the variable:
* Standard variables: any Python data type.
* Streaming variables: string data only.
</ParamField>
</Accordion>
<Warning>
`create_stream_variable_message` currently only supports string data. Complex data types cannot be streamed with the typewriter effect.
</Warning>
## Custom Output Variables
To reference a tool's output variables in a Workflow application, declare which variables the tool might output using [JSON Schema](https://json-schema.org/) in the tool's manifest.
### Define Output Schema
<CodeGroup>
```yaml Tool Manifest with Output Schema theme={null}
identity:
author: example_author
name: example_tool
label:
en_US: Example Tool
zh_Hans: 示例工具
ja_JP: ツール例
pt_BR: Ferramenta de exemplo
description:
human:
en_US: A simple tool that returns a name
zh_Hans: 返回名称的简单工具
ja_JP: 名前を返す簡単なツール
pt_BR: Uma ferramenta simples que retorna um nome
llm: A simple tool that returns a name variable
output_schema:
type: object
properties:
name:
type: string
description: "The name returned by the tool"
age:
type: integer
description: "The age returned by the tool"
profile:
type: object
properties:
interests:
type: array
items:
type: string
location:
type: string
```
</CodeGroup>
<Accordion title="Schema Structure">
<ParamField type="object">
Root object defining the tool's output schema.
</ParamField>
<ParamField type="string">
Must be `object` for tool output schemas.
</ParamField>
<ParamField type="object">
Dictionary of all possible output variables.
</ParamField>
<ParamField type="object">
Definition of each output variable, including its type and description.
</ParamField>
</Accordion>
<Warning>
Defining an output schema is not enough on its own: your implementation must still return each variable with `create_variable_message()`. Otherwise, the workflow receives `None` for that variable.
</Warning>
### Example Implementation
<CodeGroup>
```python Basic Variable Example theme={null}
def run(self, inputs):
# Process inputs and generate a name
generated_name = "Alice"
# Return the name as a variable that matches the output_schema
return self.create_variable_message("name", generated_name)
```
```python Complex Structure Example theme={null}
def run(self, inputs):
# Generate complex structured data
user_data = {
"name": "Bob",
"age": 30,
"profile": {
"interests": ["coding", "reading", "hiking"],
"location": "San Francisco"
}
}
# Return individual variables
self.create_variable_message("name", user_data["name"])
self.create_variable_message("age", user_data["age"])
self.create_variable_message("profile", user_data["profile"])
# Also return a text message for display
return self.create_text_message(f"User {user_data['name']} processed successfully")
```
</CodeGroup>
<Tip>
For complex workflows, you can define multiple output variables and return them all. This gives workflow designers more flexibility when using your tool.
</Tip>
## Examples
### Complete Tool Implementation
<CodeGroup>
```python Weather Forecast Tool theme={null}
import requests
from typing import Any
class WeatherForecastTool:
def run(self, inputs: dict) -> Any:
# Get location from inputs
location = inputs.get("location", "London")
try:
# Call weather API (example only)
weather_data = self._get_weather_data(location)
# Create variables for workflow use
self.create_variable_message("temperature", weather_data["temperature"])
self.create_variable_message("conditions", weather_data["conditions"])
self.create_variable_message("forecast", weather_data["forecast"])
# Create a JSON message for data transmission
self.create_json_message(weather_data)
# Create an image message for the weather map
self.create_image_message(weather_data["map_url"])
# Return a formatted text response
return self.create_text_message(
f"Weather in {location}: {weather_data['temperature']}°C, {weather_data['conditions']}. "
f"Forecast: {weather_data['forecast']}"
)
except Exception as e:
# Handle errors gracefully
return self.create_text_message(f"Error retrieving weather data: {str(e)}")
def _get_weather_data(self, location: str) -> dict:
# Mock implementation - in a real tool, this would call a weather API
return {
"location": location,
"temperature": 22,
"conditions": "Partly Cloudy",
"forecast": "Sunny with occasional showers tomorrow",
"map_url": "https://example.com/weather-map.png"
}
```
</CodeGroup>
<Tip>
When designing tools, consider both the direct output (what the user sees) and the variable output (what other workflow nodes can use). This separation provides flexibility in how your tool is used.
</Tip>
# Choose a Plugin Type
Source: https://docs.dify.ai/en/develop-plugin/getting-started/choose-plugin-type
A short decision guide for picking between Tool, Model, Agent Strategy, Extension, Datasource, and Trigger plugins
Dify supports several plugin types, each targeting a different extension point inside the platform. Pick the one that matches how your code will be invoked.
## Quick Decision
| You want to... | Build a... |
| :--------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------- |
| Add a callable action to Agents and Workflows (search, send email, transform data, etc.) | [Tool](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin) |
| Make a new LLM, embedding, rerank, TTS, STT, or moderation model selectable inside Dify | [Model](/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider) |
| Implement a custom reasoning loop for Agents (ReAct, Function Calling variant, etc.) | [Agent Strategy](/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin) |
| Expose an HTTP endpoint that external services can call to drive a Dify workflow | [Extension (Endpoint)](/en/develop-plugin/dev-guides-and-walkthroughs/endpoint) |
| Ingest documents from an external system into a knowledge base | [Datasource](/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin) |
| Start a workflow when something happens upstream (a webhook fires, a file lands) | [Trigger](/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin) |
## Common Questions
<AccordionGroup>
<Accordion title="Can one plugin combine multiple types?">
Yes. A Tool plugin can also expose endpoints. For example, a Discord bot plugin sends messages (tool) and receives webhooks (endpoint) in one package. Model plugins are stricter: they cannot bundle tools or endpoints.
</Accordion>
<Accordion title="Tool vs. Agent Strategy: what's the difference?">
A Tool is an individual capability the Agent decides to call (like "search the web"). An Agent Strategy is the *reasoning loop itself*: the policy that decides which tools to call, in what order, and when to stop. Build a tool unless you're replacing how Agents think.
</Accordion>
<Accordion title="Datasource vs. Trigger: both pull from external systems?">
Datasource brings documents into a knowledge base for retrieval. Trigger fires a workflow in real time on an upstream event. The same systems can power both, but the consumption pattern differs: indexing vs. event-driven execution.
</Accordion>
<Accordion title="Extension vs. Tool: when is a plain HTTP endpoint right?">
Extensions are for the other direction: an outside service calls *into* Dify. Tools are for Agents/Workflows calling *out* to a service. Build an Extension when your plugin is the entry point, not the action.
</Accordion>
</AccordionGroup>
## Next Steps
Once you've picked a type, set up the CLI and scaffold a project:
<CardGroup>
<Card title="Install the CLI" icon="rocket" href="/en/develop-plugin/getting-started/cli">
Get `dify` on your machine and run `dify plugin init`.
</Card>
<Card title="Read the manifest spec" icon="book" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Understand the YAML structure every plugin shares.
</Card>
</CardGroup>
# Dify Plugin CLI
Source: https://docs.dify.ai/en/develop-plugin/getting-started/cli
Install the Dify Plugin CLI, scaffold a new plugin project, and run it against a Dify instance for local development
The Dify Plugin CLI manages your plugin development workflow, from project initialization to packaging. This guide covers installing the CLI, scaffolding a plugin project, and running it against a Dify instance.
<Note>
This is the Dify Plugin CLI (the `dify` command) for building plugins. It is not the Dify CLI ([difyctl](/en/cli/overview)), which runs and manages Dify apps from the command line.
</Note>
## Prerequisites
Before you begin, make sure you have:
* Python 3.12
* Homebrew (macOS only, used to install the CLI)
## Install the CLI
<Tabs>
<Tab title="Mac">
```bash theme={null}
brew tap langgenius/dify
brew install dify
```
</Tab>
<Tab title="Linux">
Download the latest binary from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases). Pick `dify-plugin-linux-amd64` for x86\_64 hosts or `dify-plugin-linux-arm64` for ARM hosts.
```bash theme={null}
chmod +x dify-plugin-linux-amd64
sudo mv dify-plugin-linux-amd64 /usr/local/bin/dify
```
</Tab>
<Tab title="Windows">
Download `dify-plugin-windows-amd64.exe` (or `dify-plugin-windows-arm64.exe`) from the [Dify Plugin Daemon releases page](https://github.com/langgenius/dify-plugin-daemon/releases), rename it to `dify.exe`, and add its folder to your `PATH`.
</Tab>
</Tabs>
Verify the installation:
```bash theme={null}
dify version
```
## Create a Plugin Project
Create a new plugin project with:
```bash theme={null}
dify plugin init
```
Fill in the required fields when prompted:
```bash theme={null}
Edit profile of the plugin
Plugin name (press Enter to next step): hello-world
Author (press Enter to next step): langgenius
Description (press Enter to next step): hello world example
Repository URL (Optional) (press Enter to next step): Repository URL (Optional)
Enable multilingual README: [✔] English is required by default
Languages to generate:
English: [✔] (required)
→ 简体中文 (Simplified Chinese): [✔]
日本語 (Japanese): [✘]
Português (Portuguese - Brazil): [✘]
Controls:
↑/↓ Navigate • Space/Tab Toggle selection • Enter Next step
```
Choose `python` and press Enter to use the Python plugin template, then select the type of plugin you want to build:
```bash theme={null}
Select the type of plugin you want to create, and press `Enter` to continue
Before starting, here's some basic knowledge about Plugin types in Dify:
- Tool: Tool Providers like Google Search, Stable Diffusion, etc. Used to perform specific tasks.
- Model: Model Providers like OpenAI, Anthropic, etc. Use their models to enhance AI capabilities.
- Endpoint: Similar to Service API in Dify and Ingress in Kubernetes. Extend HTTP services as endpoints with custom logic.
- Trigger: Webhook-based providers that turn third-party platform events into workflow start signals.
- Agent Strategy: Implement your own agent strategies like Function Calling, ReAct, ToT, CoT, etc.
Based on the ability you want to extend, Plugins are divided into six types: Tool, Model, Extension, Agent Strategy, Datasource, and Trigger.
- Tool: A tool provider that can also implement endpoints. For example, building a Discord Bot requires both sending and receiving messages.
- Model: Strictly for model providers, no other extensions allowed.
- Extension: For simple HTTP services that extend functionality.
- Agent Strategy: Implement custom agent logic with a focused approach.
- Datasource: Provide datasource for Dify Knowledge Pipeline.
- Trigger: Build webhook integrations that emit events to kick off workflows.
We've provided templates to help you get started. Choose one of the options below:
-> tool
agent-strategy
llm
text-embedding
rerank
tts
speech2text
moderation
extension
datasource
trigger
```
When prompted for the minimal Dify version, leave it blank to use the latest version:
```bash theme={null}
Edit minimal Dify version requirement, leave it blank by default
Minimal Dify version (press Enter to next step):
```
The CLI creates a new directory named after your plugin and sets up the basic project structure. Move into it:
```bash theme={null}
cd hello-world
```
## Run the Plugin
From the `hello-world` directory, copy the example environment file:
```bash theme={null}
cp .env.example .env
```
Edit the `.env` file to set your plugin's environment variables, such as API keys or other configurations. To get the debugging credentials, log in to your Dify environment, click **Plugins** in the top-right corner, then click the debug icon. In the pop-up window, copy the **API Key** and **Host Address**.
```bash theme={null}
INSTALL_METHOD=remote
REMOTE_INSTALL_URL=debug-plugin.dify.dev:5003
REMOTE_INSTALL_KEY=********-****-****-****-************
```
<Note>
`REMOTE_INSTALL_URL` combines host and port in `host:port` form. The host and port are shown together in the **API Key** card on the Plugins page.
</Note>
Install the dependencies and run your plugin:
```bash theme={null}
pip install -r requirements.txt
python -m main
```
# Dify Plugin
Source: https://docs.dify.ai/en/develop-plugin/getting-started/getting-started-dify-plugin
Modular components that extend Dify AI applications with external services, custom logic, and specialized tools
Dify plugins are modular components that extend your Dify-built AI applications with external services, custom functions, and specialized tools.
<Frame>
<img alt="Marketplace" />
</Frame>
Through plugins, your AI applications can:
* Connect to external APIs
* Process different types of data
* Perform specialized calculations
* Execute real-world actions
## Start Here
<CardGroup>
<Card title="Choose a Plugin Type" icon="route" href="/en/develop-plugin/getting-started/choose-plugin-type">
A short decision guide for picking between Tool, Model, Agent Strategy, Extension, Datasource, and Trigger plugins.
</Card>
<Card title="Install the CLI" icon="rocket" href="/en/develop-plugin/getting-started/cli">
Set up `dify` on your machine and scaffold a new plugin project in minutes.
</Card>
</CardGroup>
## Types of Plugins
<AccordionGroup>
<Accordion title="Models" icon="microchip" href="/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider">
Package and manage AI models as plugins
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/creating-new-model-provider">Learn more</a>
</Accordion>
<Accordion title="Tools" icon="toolbox" href="/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin">
Build specialized capabilities for Agents and workflows
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin">Learn more</a>
</Accordion>
<Accordion title="Agent Strategies" icon="brain" href="/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin">
Create custom reasoning strategies for autonomous Agents
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/agent-strategy-plugin">Learn more</a>
</Accordion>
<Accordion title="Extensions" icon="puzzle-piece" href="/en/develop-plugin/dev-guides-and-walkthroughs/endpoint">
Integrate with external services through HTTP webhooks
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/endpoint">Learn more</a>
</Accordion>
<Accordion title="Datasources" icon="database" href="/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin">
Feed external content into Dify's Knowledge Pipeline
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/datasource-plugin">Learn more</a>
</Accordion>
<Accordion title="Triggers" icon="bolt" href="/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin">
Kick off workflows from third-party platform events received via webhooks
<a href="/en/develop-plugin/dev-guides-and-walkthroughs/trigger-plugin">Learn more</a>
</Accordion>
</AccordionGroup>
## Additional Resources
<CardGroup>
<Card title="Development & Debugging" icon="code" href="/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin">
Tools and techniques for efficient plugin development
</Card>
<Card title="Publishing & Marketplace" icon="shop" href="/en/develop-plugin/publishing/marketplace-listing/release-overview">
Package and share your plugins with the Dify community
</Card>
<Card title="API & SDK Reference" icon="book-open" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Technical specifications and documentation
</Card>
<Card title="Community & Contributions" icon="users" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
Communicate with other developers and contribute to the ecosystem
</Card>
</CardGroup>
# Frequently Asked Questions
Source: https://docs.dify.ai/en/develop-plugin/publishing/faq/faq
Common issues and fixes for building, packaging, debugging, and installing Dify plugins
## Package and Install
### Why does `dify plugin package` fail with `plugin_unique_identifier is not valid`?
The `author` field in `manifest.yaml` and any `provider/*.yaml` file must match your GitHub handle. Update it in every file, repackage with `dify plugin package`, and reinstall.
### Why am I seeing `plugin verification has been enabled, and the plugin you want to install has a bad signature`?
Self-hosted Dify enforces signature verification on plugin packages by default. You have two options:
1. **Recommended for production**: sign your package. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification).
2. **For development and trusted internal use**: disable verification. Add `FORCE_VERIFYING_SIGNATURE=false` to `docker/.env`, then restart:
```bash theme={null}
cd docker
docker compose down
docker compose up -d
```
This allows installing any unsigned plugin, including ones outside the Marketplace, so only do this in environments you control.
### Is there a maximum size for a `.difypkg` file?
Yes. The plugin daemon rejects packages over a configurable limit (default `50MB`). If you ship large model weights or static assets, host them externally and download on first use, or contact Dify support about raising the limit for marketplace plugins.
### My plugin needs Python 3.13. Can I change the runtime?
No. Plugins run inside a managed Python 3.12 environment. Pin your dependencies to versions compatible with 3.12. The daemon does not honor a different runtime version in `manifest.yaml`.
## Remote Debugging
### Why does my plugin start but never appear in the workspace?
Three things to check, in order: (1) the daemon log shows an incoming registration, (2) the `REMOTE_INSTALL_KEY` matches what's shown in the debug dialog, (3) `REMOTE_INSTALL_URL` uses the `host:port` format (not separate variables). See [Plugin Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) for the full troubleshooting list.
### Do my code changes hot-reload?
No. Stop the plugin process with `Ctrl+C` and rerun `python -m main` after every change.
## OAuth and Credentials
### What callback URL should I configure with the upstream OAuth provider?
Use `https://<your-dify-host>/console/api/oauth/plugin/<author>/<plugin-name>/tool/callback` for tool plugins, replacing `tool` with `datasource` or `trigger` for those plugin types. The exact pattern is shown in your plugin's OAuth setup card inside Dify.
### Why are my OAuth tokens not refreshing?
The plugin SDK refreshes tokens automatically when they expire, provided your provider implementation returns a valid `refresh_token` from the initial authorization. Confirm `OAuthCredentials.refresh_token` is populated, and that your `_oauth_refresh_credentials` method is implemented.
## Marketplace Publishing
### Why was my Marketplace PR rejected by the automated check?
The reviewer runs a 12-check pre-flight on every PR. The most common failures:
* **`author` in `manifest.yaml` contains `langgenius` or `dify`**: reserved for first-party plugins; use your own GitHub handle.
* **`dify_plugin` SDK pin is below `0.5.0`**: bump the pin in `requirements.txt`.
* **`README.md` contains Chinese characters**: move translations to `readme/README_zh_Hans.md` (see [Multilingual README](/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme)).
* **PR title or body contains Chinese**: only the bilingual notice line is allowlisted; everything else must be English.
* **Missing `PRIVACY.md` or `_assets/`**: both are required, and `PRIVACY.md` must be non-empty.
* **Version is already published**: bump `version` in `manifest.yaml` before re-submitting.
The full list of checks lives in [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace#reviewer-checklist).
### How long does the Marketplace review take?
PRs to `langgenius/dify-plugins` are typically reviewed within a few business days. PRs that haven't seen reviewer activity in 14–30 days are marked stale; respond on the PR to reset that timer.
### How do I publish an update for a plugin already on the Marketplace?
Bump `version` in `manifest.yaml`, open a new PR against `langgenius/dify-plugins` with the new package. The Marketplace shows the new version once merged. See [Auto-publish PR](/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr) for the GitHub Action that automates this.
### Can I monetize my plugin?
Not currently. The Marketplace only accepts free plugins. Future pricing policies will be announced separately.
## Storage and Limits
### Where do plugin logs go?
Self-hosted: container logs of the plugin daemon (`docker compose logs plugin_daemon`). Cloud: visible in the workspace's plugin debug panel during remote debugging only; persisted logs are not exposed in the UI. Use [Plugin Logging](/en/develop-plugin/features-and-specs/plugin-types/plugin-logging) for structured output.
### Is plugin storage scoped per workspace?
Yes. The KV storage API (`self.session.storage`) is isolated per workspace per plugin install. Two workspaces using the same plugin do not share keys. See [Persistent Storage (KV)](/en/develop-plugin/features-and-specs/plugin-types/persistent-storage-kv).
# Automatically Publish Plugins via PR
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr
Automate plugin packaging and Marketplace PR creation with a GitHub Actions workflow that runs on every push to main
## Background
Updating a plugin that others actively use is tedious by hand: modify the code, bump the version, push changes, create a branch, package the file, and open a PR—every release.
**Plugin Auto-PR** is a GitHub Actions workflow that automates the whole sequence. One push packages the plugin and opens the Marketplace PR, so you can focus on building.
## Concepts
### GitHub Actions
GitHub Actions automates development tasks in GitHub. When triggered (for example, by a code push), it runs your workflow in a cloud-based virtual machine, handling everything from build to deployment.
<Frame>

</Frame>
GitHub Actions usage limits:
* **Public repositories**: Unlimited.
* **Private repositories**: 2000 minutes per month.
### Plugin Auto-PR
The workflow runs these steps:
1. Triggers when you push code to the main branch of your plugin source repository.
2. Reads plugin information from the `manifest.yaml` file.
3. Packages the plugin as a `.difypkg` file.
4. Pushes the packaged file to your forked `dify-plugins` repository.
5. Creates a new branch and commits the changes.
6. Creates a PR to merge into the upstream repository.
## Prerequisites
### Repositories
* Your own plugin source code repository (e.g., `your-name/plugin-source`).
* Your own fork of the plugin repository (e.g., `your-name/dify-plugins`).
* The plugin directory structure already in place in your fork:
```text theme={null}
dify-plugins/
└── your-author-name
└── plugin-name
```
### Permissions
Create a GitHub Personal Access Token (PAT) that can push code to your forked repository and create PRs to the upstream repository.
## Parameters and Configuration
### Setup Requirements
Auto-publishing needs two things in place.
The `manifest.yaml` file drives the automation:
* **`name`**: Your plugin's name (affects package and branch names).
* **`version`**: Semantic version number (increment with each release).
* **`author`**: Your GitHub username (determines repository paths).
The `PLUGIN_ACTION` secret in your plugin source repository holds the credentials:
* **Value**: A Personal Access Token (PAT) with sufficient permissions.
* **Permissions**: Push branches to your forked repository and create PRs to the upstream repository.
### Automatically Generated Parameters
Once set up, the workflow derives these parameters for you:
* **GitHub username**: Read from the `author` field in `manifest.yaml`.
* **Author folder name**: Matches the `author` field.
* **Plugin name**: Read from the `name` field in `manifest.yaml`.
* **Branch name**: `bump-{plugin-name}-plugin-{version}`.
* **Package filename**: `{plugin-name}-{version}.difypkg`.
* **PR title and content**: Generated from the plugin name and version.
## Step-by-Step Guide
<Steps>
<Step title="Prepare Repositories">
Ensure you have forked the official `dify-plugins` repository and have your own plugin source repository.
</Step>
<Step title="Configure Secret">
In your plugin source repository, go to **Settings** > **Secrets and variables** > **Actions** > **New repository secret** and create a secret:
* **Name**: `PLUGIN_ACTION`
* **Value**: A GitHub Personal Access Token (PAT) with write permissions to the target repository (`your-name/dify-plugins`)
<Frame>

</Frame>
</Step>
<Step title="Create Workflow File">
Create a `.github/workflows/` directory in your repository, add a file named `plugin-publish.yml`, and paste in the workflow below.
At a high level, the workflow runs on every push to `main`, downloads the Dify Plugin CLI, packages the plugin from the manifest, checks out your `dify-plugins` fork, and opens a PR against `langgenius/dify-plugins` with the new `.difypkg`.
<Accordion title="Complete workflow YAML">
```yaml theme={null}
# .github/workflows/plugin-publish.yml
name: Auto Create PR on Main Push
on:
push:
branches: [ main ] # Trigger on push to main
workflow_dispatch: # Allow manual runs from the Actions tab
jobs:
create_pr: # Renamed job for clarity
runs-on: ubuntu-latest
steps:
- name: Checkout code
uses: actions/checkout@v3
- name: Print working directory # Kept for debugging
run: |
pwd
ls -la
- name: Download CLI tool
run: |
# Create bin directory in runner temp
mkdir -p $RUNNER_TEMP/bin
cd $RUNNER_TEMP/bin
# Download CLI tool
wget https://github.com/langgenius/dify-plugin-daemon/releases/latest/download/dify-plugin-linux-amd64
chmod +x dify-plugin-linux-amd64
# Show download location and file
echo "CLI tool location:"
pwd
ls -la dify-plugin-linux-amd64
- name: Get basic info from manifest # Changed step name and content
id: get_basic_info
run: |
PLUGIN_NAME=$(grep "^name:" manifest.yaml | cut -d' ' -f2)
echo "Plugin name: $PLUGIN_NAME"
echo "plugin_name=$PLUGIN_NAME" >> $GITHUB_OUTPUT
VERSION=$(grep "^version:" manifest.yaml | cut -d' ' -f2)
echo "Plugin version: $VERSION"
echo "version=$VERSION" >> $GITHUB_OUTPUT
# If the author's name is not your github username, you can change the author here
AUTHOR=$(grep "^author:" manifest.yaml | cut -d' ' -f2)
echo "Plugin author: $AUTHOR"
echo "author=$AUTHOR" >> $GITHUB_OUTPUT
- name: Package Plugin
id: package
run: |
# Use the downloaded CLI tool to package
cd $GITHUB_WORKSPACE
# Use variables for package name
PACKAGE_NAME="${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}.difypkg"
# Use CLI from runner temp
$RUNNER_TEMP/bin/dify-plugin-linux-amd64 plugin package . -o "$PACKAGE_NAME"
# Show packaging result
echo "Package result:"
ls -la "$PACKAGE_NAME"
echo "package_name=$PACKAGE_NAME" >> $GITHUB_OUTPUT
# Show full file path and directory structure (kept for debugging)
echo "\\nFull file path:"
pwd
echo "\\nDirectory structure:"
tree || ls -R
- name: Checkout target repo
uses: actions/checkout@v3
with:
# Use author variable for repository
repository: ${{steps.get_basic_info.outputs.author}}/dify-plugins
path: dify-plugins
token: ${{ secrets.PLUGIN_ACTION }}
fetch-depth: 1 # Fetch only the last commit to speed up checkout
persist-credentials: true # Persist credentials for subsequent git operations
- name: Prepare and create PR
run: |
# Debug info (kept)
echo "Debug: Current directory $(pwd)"
# Use variable for package name
PACKAGE_NAME="${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}.difypkg"
echo "Debug: Package name: $PACKAGE_NAME"
ls -la
# Move the packaged file to the target directory using variables
mkdir -p dify-plugins/${{ steps.get_basic_info.outputs.author }}/${{ steps.get_basic_info.outputs.plugin_name }}
mv "$PACKAGE_NAME" dify-plugins/${{ steps.get_basic_info.outputs.author }}/${{ steps.get_basic_info.outputs.plugin_name }}/
# Enter the target repository directory
cd dify-plugins
# Configure git
git config user.name "GitHub Actions"
git config user.email "actions@github.com"
# Ensure we are on the latest main branch
git fetch origin main
git checkout main
git pull origin main
# Create and switch to a new branch using variables and new naming convention
BRANCH_NAME="bump-${{ steps.get_basic_info.outputs.plugin_name }}-plugin-${{ steps.get_basic_info.outputs.version }}"
git checkout -b "$BRANCH_NAME"
# Add and commit changes (using git add .)
git add .
git status # for debugging
# Use variables in commit message
git commit -m "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin to version ${{ steps.get_basic_info.outputs.version }}"
# Push to remote (use force just in case the branch existed before from a failed run)
git push -u origin "$BRANCH_NAME" --force
# Confirm branch has been pushed and wait for sync (GitHub API might need a moment)
git branch -a
echo "Waiting for branch to sync..."
sleep 10 # Wait 10 seconds for branch sync
- name: Create PR via GitHub API
env:
GH_TOKEN: ${{ secrets.PLUGIN_ACTION }} # Use the provided token for authentication
run: |
gh pr create \
--repo langgenius/dify-plugins \
--head "${{ steps.get_basic_info.outputs.author }}:${{ steps.get_basic_info.outputs.plugin_name }}-${{ steps.get_basic_info.outputs.version }}" \
--base main \
--title "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin to version ${{ steps.get_basic_info.outputs.version }}" \
--body "bump ${{ steps.get_basic_info.outputs.plugin_name }} plugin package to version ${{ steps.get_basic_info.outputs.version }}
Changes:
- Updated plugin package file" || echo "PR already exists or creation skipped." # Handle cases where PR already exists
- name: Print environment info # Kept for debugging
run: |
echo "GITHUB_WORKSPACE: $GITHUB_WORKSPACE"
echo "Current directory contents:"
ls -R
```
</Accordion>
</Step>
<Step title="Update manifest.yaml">
Make sure these fields are set correctly:
```yaml theme={null}
version: 0.0.x # Version number
author: your-github-username # GitHub username/Author name
name: your-plugin-name # Plugin name
```
</Step>
</Steps>
## Usage Guide
### First-Time Setup
Before the first automated release, confirm that:
1. You have forked the official `dify-plugins` repository.
2. Your plugin source repository structure is correct.
3. The `PLUGIN_ACTION` secret is set in your plugin source repository.
4. The workflow file `.github/workflows/plugin-publish.yml` exists.
5. The `name` and `author` fields in `manifest.yaml` are configured correctly.
### Subsequent Updates
To publish new versions after setup:
1. Modify the code.
2. Update the `version` field in `manifest.yaml`.
<Frame>

</Frame>
3. Push all changes to the main branch.
4. Wait for GitHub Actions to complete packaging, branch creation, and PR submission.
## Outcome
When you push code to the main branch of your plugin source repository, GitHub Actions runs the publishing process automatically:
* Packages the plugin in `{plugin-name}-{version}.difypkg` format.
* Pushes the packaged file to the target repository.
* Creates a PR to merge into the fork repository.
<Frame>

</Frame>
## Example Repository
See the [example repository](https://github.com/Yevanchen/exa-in-dify) for a working configuration and best practices.
# Package as Local File and Share
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-by-file
Package a Dify plugin into a `.difypkg` file you can install directly or hand off to others, with no marketplace or GitHub release required
A `.difypkg` is the portable form of a Dify plugin. Once you have one, anyone can install it through the Plugins page by uploading the file. This is the right path for **private plugins**, **internal testing**, or **out-of-band distribution** to a small group.
For wider distribution, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Prerequisites
* The [Dify Plugin CLI](/en/develop-plugin/getting-started/cli) installed. Run `dify version` to confirm.
* A completed plugin project. If you haven't built one yet, start with the [Tool Plugin walkthrough](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
* The plugin tested with [remote debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin) before packaging.
<Note>
The `author` field in `manifest.yaml` and every `provider/*.yaml` must match your GitHub handle. Mismatches cause `plugin_unique_identifier is not valid` at install time. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the full manifest spec.
</Note>
## Package the Plugin
<Steps>
<Step title="Move above the project">
Navigate to the directory **above** your plugin project (so the project is a subdirectory of the current working directory).
</Step>
<Step title="Run the packager">
```bash theme={null}
dify plugin package ./your_plugin_project
```
The CLI produces a `your_plugin_project.difypkg` file in the current directory.
</Step>
</Steps>
<Frame>

</Frame>
## Install from the File
<Steps>
<Step title="Open the Plugins page">
In Dify, click the **Plugins** icon in the top-right corner.
</Step>
<Step title="Choose Install Plugin > Via Local File">
Or drag the `.difypkg` onto the empty area of the Plugins page.
</Step>
<Step title="Confirm the install">
Review the permissions the plugin requests, then click **Install**.
</Step>
</Steps>
<Frame>

</Frame>
<Check>
The plugin is now in the workspace and ready to use in Agents, Workflows, or Tools. No further action required.
</Check>
<Warning>
Self-hosted Dify enforces signature verification by default. Unsigned `.difypkg` files installed via Local File will be rejected unless you sign them or change the verification setting. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification).
</Warning>
## Share the File
Hand the `.difypkg` file to your users directly: over email, an internal file share, or any channel you control. They install it with the same flow above.
If you want broader distribution instead, consider:
<CardGroup>
<Card title="Publish on GitHub" icon="github" href="/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo">
Attach the `.difypkg` to a GitHub release; users install via repo URL.
</Card>
<Card title="Submit to Marketplace" icon="store" href="/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace">
Open a PR against `langgenius/dify-plugins` for the official catalog.
</Card>
</CardGroup>
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Dify Plugin CLI](/en/develop-plugin/getting-started/cli)
* [Remote Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin)
* [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification)
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
# Publish Plugins
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-overview
Three ways to distribute a Dify plugin (Marketplace, GitHub repository, or local file) and how to pick the right one
Dify supports three ways to distribute a plugin. They differ in how much vetting happens up front and how broad an audience the plugin reaches.
Before publishing, finish development and testing, and read the [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct).
## Choose a Method
<CardGroup>
<Card title="Marketplace" icon="store" href="/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace">
Official catalog. Reviewed, trusted, one-click install for every Dify user.
</Card>
<Card title="GitHub Repository" icon="github" href="/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo">
Self-hosted on GitHub. No review; users install via repo URL.
</Card>
<Card title="Local File" icon="file-zipper" href="/en/develop-plugin/publishing/marketplace-listing/release-by-file">
A `.difypkg` file you hand off directly. Right for private or internal plugins.
</Card>
</CardGroup>
## Compare
| | <Icon icon="store" /> Marketplace | <Icon icon="github" /> GitHub | <Icon icon="file-zipper" /> Local File |
| :--------------- | :----------------------------------------------- | :------------------------------------------------- | :----------------------------------------------------- |
| **Audience** | Every Dify user | Anyone with the repo URL | People you give the file to |
| **Review** | Yes: 12 automated checks + human review | None | None |
| **Install path** | One click from Marketplace UI | Install from GitHub dialog | Upload via Plugins page |
| **Versioning** | New PR per version, automated workflow available | GitHub releases with `.difypkg` asset | Repackage and redistribute |
| **Best for** | Polished, broadly useful plugins | Open-source projects, internal tools shared by URL | Private plugins, internal testing, ad-hoc distribution |
<Tip>
Many developers ship to **GitHub first** for fast iteration, then submit to the **Marketplace** once the plugin is stable. The same `.difypkg` works for all three methods; only the distribution channel differs.
</Tip>
## Quick Rules of Thumb
* **Want broad reach and review?** Use the **Marketplace**.
* **Want full control over releases and versioning?** Use **GitHub**.
* **Private or one-off use?** Use a **Local File**.
## Related Resources
<CardGroup>
<Card title="Plugin Development Guidelines" icon="clipboard-check" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
Quality bar for Marketplace submissions.
</Card>
<Card title="Privacy Guidelines" icon="shield-halved" href="/en/develop-plugin/publishing/standards/privacy-protection-guidelines">
`PRIVACY.md` and data-disclosure requirements.
</Card>
<Card title="General Specifications" icon="file-code" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Manifest fields every plugin must set.
</Card>
<Card title="Getting Started" icon="rocket" href="/en/develop-plugin/getting-started/getting-started-dify-plugin">
New to plugins? Start here.
</Card>
</CardGroup>
# Publish to Dify Marketplace
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace
Submit a plugin to the Dify Marketplace, from the pre-submission checklist and the 12 reviewer checks through the PR flow and what happens after approval
The Marketplace is the official catalog of community-built and partner-built Dify plugins. Submitting your plugin here puts it one click away from every Dify user.
Plugins are published by opening a Pull Request against [`langgenius/dify-plugins`](https://github.com/langgenius/dify-plugins). A reviewer (and a set of automated checks) walks through the PR, and on approval the plugin goes live on [marketplace.dify.ai](https://marketplace.dify.ai/) automatically.
If you have not built a plugin yet, start with the [Tool Plugin walkthrough](/en/develop-plugin/dev-guides-and-walkthroughs/tool-plugin).
## Before You Submit
The Dify reviewer runs an automated 12-check pre-flight on every PR. Most rejections are mechanical, and fixing them up front saves a review cycle.
<Tabs>
<Tab title="Project files">
Every plugin directory must contain:
| File / Folder | Purpose |
| :-------------- | :-------------------------------------------- |
| `manifest.yaml` | Plugin metadata (name, author, version, etc.) |
| `README.md` | English-only description, setup, usage |
| `PRIVACY.md` | Privacy policy (required, non-empty) |
| `_assets/` | Plugin icon and any other static assets |
See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for manifest fields and [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines) for the privacy policy.
</Tab>
<Tab title="Manifest rules">
* **Author** in `manifest.yaml` must not contain `langgenius` or `dify`; those are reserved for first-party plugins. Use your own GitHub handle.
* **Version** must be a new value. Submitting an already-published version is rejected.
* **Icon** must be an actual icon in `_assets/`, not a leftover template default.
</Tab>
<Tab title="Dependencies">
* `pip install -r requirements.txt` must succeed cleanly.
* The plugin SDK pin must be at least `dify_plugin>=0.5.0`.
* The plugin must install and package without errors against the current daemon (the reviewer runs `test-plugin-install.py` and `upload-package.py --test`).
</Tab>
<Tab title="Language">
* **PR title and body** must be in English. The bilingual notice line `【中文用户 & Non English User】请使用英语提交,否则会被关闭 :)` is the only allowlisted exception.
* **`README.md`** must contain no Chinese characters. Add translations as `readme/README_<lang>.md` instead. See [Multilingual README](/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme).
</Tab>
</Tabs>
## Reviewer Checklist
These are the exact checks the reviewer runs, in order. Treat this as your pre-flight before opening the PR.
| # | Check | Common cause of failure |
| :- | :----------------------- | :------------------------------------------------------------------------- |
| 1 | **Single `.difypkg`** | PR includes more than one packaged file, or none |
| 2 | **PR language** | CJK characters in title or body outside the allowlisted notice |
| 3 | **Project structure** | Missing `manifest.yaml`, `README.md`, `PRIVACY.md`, or `_assets/` |
| 4 | **Manifest author** | Author contains `langgenius` or `dify` |
| 5 | **Icon** | Default template icon left in place, or icon missing |
| 6 | **Version** | This version is already on the Marketplace |
| 7 | **README language** | Chinese characters in `README.md` (use `readme/README_zh_Hans.md` instead) |
| 8 | **PRIVACY.md** | Missing or empty |
| 9 | **Dependencies install** | `pip install -r requirements.txt` errors |
| 10 | **SDK version** | `dify_plugin` pinned below `0.5.0` |
| 11 | **Install test** | Plugin fails to install via the daemon |
| 12 | **Packaging test** | Plugin fails to repackage cleanly |
A failing check stops the review and posts a status table with `❌ Fail` rows and required fixes; you address them and push again.
## Submit the PR
<Steps>
<Step title="Read the Plugin Development Guidelines">
Skim the [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct). Reviewers use them to judge non-mechanical concerns: uniqueness, brand alignment, content quality, IP, and maintenance commitment.
</Step>
<Step title="Write your privacy policy">
Create `PRIVACY.md` in the plugin root (or host it and put the URL in the manifest). Follow [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines): declare what data the plugin and any third-party services it calls collect.
</Step>
<Step title="Package the plugin">
From the directory above your plugin project:
```bash theme={null}
dify plugin package ./your_plugin_project
```
This produces `your_plugin_project.difypkg`.
</Step>
<Step title="Fork and add your file">
Fork [`langgenius/dify-plugins`](https://github.com/langgenius/dify-plugins). Create a folder at `<your-author-name>/<your-plugin-name>/` and drop the `.difypkg` inside.
</Step>
<Step title="Open the PR">
Push to your fork, then open a PR against `main` using the repository's PR template. Title and body in English.
</Step>
<Step title="Respond to the review">
The automated checks post first, then a human reviewer follows up. Address feedback by pushing new commits; the checks rerun on each push.
</Step>
</Steps>
```mermaid theme={null}
flowchart LR
A[Build & test plugin] --> B[Package .difypkg]
B --> C[Fork langgenius/dify-plugins]
C --> D[Add file to author/plugin/]
D --> E[Open PR]
E --> F{Automated checks<br/>12 rules}
F -->|❌ Fail| G[Push fixes]
G --> F
F -->|✅ Pass| H[Human review]
H -->|Changes requested| G
H -->|Approve & merge| I[Live on Marketplace]
```
<Tip>
The first review usually lands within a week. If it takes longer, the reviewer leaves a comment explaining the delay.
</Tip>
<Check>
Once merged to `main`, the plugin appears on [marketplace.dify.ai](https://marketplace.dify.ai/) automatically, with no separate publishing step.
</Check>
## After Approval
You own the plugin from the merge onward:
* **Bug fixes and feature requests.** Triage issues from your users.
* **Compatibility updates.** When Dify ships a breaking API change, the team publishes migration notes; you update the plugin. Dify engineers can help if needed.
* **Versioning.** Bump `version` in `manifest.yaml`, repackage, open a new PR with the new `.difypkg`. The [Auto-publish PR workflow](/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr) automates this from a GitHub Action.
<Warning>
While the Marketplace is in public beta, avoid breaking changes to plugins already in use. Add new fields instead of renaming existing ones; deprecate before removing.
</Warning>
## PR Lifecycle
| Status | What it means | What to do |
| :------------------------ | :-------------------------------------------- | :----------------------------------------------------- |
| **Open, awaiting review** | Within the first \~7 days, no action needed | Wait |
| **Changes requested** | A check failed, or the reviewer left feedback | Push fixes; checks rerun automatically |
| **Stale (14 days idle)** | No response from you in two weeks | Reply on the PR to reset the timer; it can be reopened |
| **Closed (30 days idle)** | Closed for inactivity | Open a fresh PR; the closed one can't be reopened |
## Frequently Asked Questions
<AccordionGroup>
<Accordion title="How do I know if my plugin is too similar to an existing one?">
The Marketplace deduplicates by *function*, not by *integration*. A second Google-search plugin that only adds new translations is a duplicate. A Google-search plugin that adds batched queries, better error handling, or a meaningful new capability is fine; say so in the PR description.
</Accordion>
<Accordion title="My PR was marked stale or closed. What now?">
**Stale** PRs (14 days idle) can be reopened; reply on the PR or push a fix to restart the clock. **Closed** PRs (30 days idle) cannot be reopened; fix the feedback and open a fresh PR with the same package.
</Accordion>
<Accordion title="Can I update plugins during the public beta?">
Yes. Avoid breaking changes: add fields rather than rename, deprecate before removing.
</Accordion>
<Accordion title="Can I publish a paid plugin?">
Not currently. The Marketplace accepts free plugins only; monetization policies will be announced separately.
</Accordion>
<Accordion title="The PR body needs both English and Chinese for our team. Is that allowed?">
No. Only the single allowlisted bilingual notice line is permitted in the PR title/body. Put internal multilingual notes elsewhere (commit messages, internal docs).
</Accordion>
</AccordionGroup>
## Related Resources
<CardGroup>
<Card title="Publishing Overview" icon="signs-post" href="/en/develop-plugin/publishing/marketplace-listing/release-overview">
Compare Marketplace, GitHub, and local-file distribution.
</Card>
<Card title="Plugin Development Guidelines" icon="clipboard-check" href="/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct">
The full content and quality bar reviewers apply.
</Card>
<Card title="Privacy Guidelines" icon="shield-halved" href="/en/develop-plugin/publishing/standards/privacy-protection-guidelines">
How to write a `PRIVACY.md` that passes review.
</Card>
<Card title="Auto-publish PR Workflow" icon="robot" href="/en/develop-plugin/publishing/marketplace-listing/plugin-auto-publish-pr">
GitHub Action that packages and opens the PR for you on every push.
</Card>
<Card title="Multilingual README" icon="language" href="/en/develop-plugin/features-and-specs/plugin-types/multilingual-readme">
Add `readme/README_<lang>.md` files for non-English users.
</Card>
<Card title="General Specifications" icon="file-code" href="/en/develop-plugin/features-and-specs/plugin-types/general-specifications">
Manifest field reference.
</Card>
</CardGroup>
# Publish to Individual GitHub Repository
Source: https://docs.dify.ai/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo
Distribute a Dify plugin from your own GitHub repository so users can install it directly via repo URL, with no marketplace review required
Publishing through a personal GitHub repository lets you ship a plugin without going through Dify Marketplace review. Users install the plugin by entering your repo URL and selecting a release that contains a `.difypkg` asset.
This method fits when:
* You want full control over versioning and the release cadence.
* The plugin is open source and you want others to read, fork, or contribute to it.
* The plugin is for internal use within a team or org, but you still want one canonical install URL.
* Your plugin is awaiting marketplace review and you need an interim distribution channel.
For a comparison with other publishing methods, see the [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview).
## Prerequisites
* A packaged plugin (`.difypkg` file). If you don't have one yet, see [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file).
* A GitHub account.
* A Dify workspace where you (or your users) have permission to install plugins.
## Step 1: Create a GitHub Repository
<Steps>
<Step title="Create the repository">
On GitHub, create a new public repository. The name typically matches your plugin name (for example, `dify-plugin-flomo`).
</Step>
<Step title="Push your plugin source">
Initialize git in your plugin project and push the source code:
```bash theme={null}
cd your_plugin_project
git init
git add .
git commit -m "initial commit"
git branch -M main
git remote add origin https://github.com/<your-handle>/<repo-name>.git
git push -u origin main
```
</Step>
<Step title="Confirm the manifest">
The `author` field in `manifest.yaml` and in any `provider/*.yaml` must match your GitHub handle. Mismatches cause `plugin_unique_identifier is not valid` when users try to install. See the [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for manifest details.
</Step>
</Steps>
## Step 2: Build the Plugin Package
From the directory **above** your plugin project, run:
```bash theme={null}
dify plugin package ./your_plugin_project
```
This produces `your_plugin_project.difypkg` in the current directory.
## Step 3: Publish a GitHub Release
GitHub releases are how Dify discovers installable versions of your plugin.
<Steps>
<Step title="Tag a release">
On your repository page, click **Releases** > **Draft a new release**. Create a new tag using semantic versioning (for example, `v0.0.1`). The tag should match the `version` field in your `manifest.yaml`.
</Step>
<Step title="Attach the .difypkg file">
In the release form, drag the `.difypkg` file into the **Assets** area. Dify reads this asset when users install from your repo.
</Step>
<Step title="Publish">
Add release notes describing what changed, then click **Publish release**.
</Step>
</Steps>
<Tip>
Repeat Steps 2 and 3 for each new version. Bump the `version` in `manifest.yaml` first, repackage, then create a new tag and release.
</Tip>
## Step 4: Install from Your Repository
Share your repository URL with users. They install it in Dify as follows:
<Steps>
<Step title="Open the Plugins page">
In Dify, go to **Plugins** in the top-right corner.
</Step>
<Step title="Install from GitHub">
Click **Install Plugin** > **From GitHub**.
</Step>
<Step title="Enter repository details">
Paste the repository URL (for example, `https://github.com/<your-handle>/<repo-name>`), then select the version from the dropdown. Dify pulls the matching `.difypkg` asset from that release.
</Step>
<Step title="Confirm installation">
Review the permissions the plugin requests, then click **Install**.
</Step>
</Steps>
<Check>
The plugin appears on the user's Plugins page within seconds of clicking **Install**. Dify pulls the `.difypkg` from your GitHub release on demand.
</Check>
## Troubleshooting
* **`plugin_unique_identifier is not valid`**: The `author` field in `manifest.yaml` (and `provider/*.yaml`) doesn't match the GitHub handle that owns the repo. Update it, repackage, and re-release.
* **No versions appear in the install dialog**: The release has no `.difypkg` asset attached, or the repo has no releases yet. Open the release on GitHub and confirm the asset is listed under **Assets**.
* **Signature verification error**: Self-hosted Dify instances may have signature verification enabled. See [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification) to sign your release, or see the [FAQ](/en/develop-plugin/publishing/faq/faq) for the bypass option.
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview): Compare publishing methods.
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file): Build a `.difypkg` package.
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace): Submit through the official marketplace.
* [Third-Party Signature Verification](/en/develop-plugin/publishing/standards/third-party-signature-verification): Sign packages for verified installs.
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications): Manifest field reference.
# Plugin Development Guidelines
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct
Requirements every Dify Marketplace plugin must meet to pass review, covering quality, language, privacy, IP, maintenance, and prohibited content
By submitting a plugin to the Dify Marketplace, you agree to follow the requirements on this page. Meeting them up front gets your plugin through review faster and helps keep the Marketplace useful and trustworthy.
## Value and uniqueness
* **Generative AI focus.** The plugin's core capability should integrate models, tools, or services that meaningfully extend AI applications on Dify.
* **No functional duplicates.** Don't reskin an existing Marketplace plugin. Each plugin should be unique and stand on its own.
* **Meaningful updates.** New versions must add real capability, not just metadata bumps.
* **Explain new submissions.** In your PR description, say briefly why the plugin is needed and what gap it fills.
## Plugin checklist
Before opening the publish PR, confirm each item:
* **Unique name.** Search the Marketplace first.
* **Brand alignment.** The plugin name reflects what it actually is.
* **Works end-to-end.** Tested via [remote debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin); production-ready.
* **README in English** with setup steps, required credentials, and usage. No exaggerated claims, ads, self-promotion, offensive content, real user data in screenshots, or dead links.
* **Clear error messages** for required fields and failure modes.
* **Authentication steps documented in full**, with no skipped steps.
* **Privacy policy ready.** See [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
* **Credentials handled securely**, never hardcoded, never exposed.
* **Performance acceptable.** Does not noticeably degrade Dify itself.
## Language
English is the primary language for every user-facing string: plugin name, description, field labels, help text, error messages. Additional translations are welcome on top of English.
## Prohibited and restricted plugins
| Category | Reason |
| ------------------------------------------------ | -------------------------------------------------------------- |
| **Prohibited**: misleading or malicious behavior | spam, phishing, credential theft, deceiving the review process |
| **Prohibited**: offensive content | violence, hate speech, discrimination |
| **Prohibited**: financial transactions | payments, asset transfers, token transfers |
| **Restricted**: frequent defects | repeated submissions with critical bugs |
| **Restricted**: unnecessary splitting | multiple plugins for the same API/auth; bundle them instead |
| **Restricted**: duplicate submissions | re-submitting essentially the same plugin |
Prohibited plugins are rejected. Restricted plugins may be delayed or asked to consolidate.
## Monetization
**The Dify Marketplace currently accepts free plugins only.** Pricing policies, if introduced, will be announced separately.
## Trademarks and intellectual property
* **You must have the rights** to any logo, trademark, or copyrighted material you include. We may ask for proof for recognizable third-party brands.
* **Do not use Dify's logos** in your plugin assets.
* **Image quality** must be sharp and well-cropped. No misleading or offensive icons.
Dify may ask for changes or remove a plugin if a rights holder complains or if unauthorized use is found.
## Updates and versioning
* **Announce breaking changes** in the plugin description or via GitHub Release Notes before users hit them.
* **Update regularly** for bug fixes, Dify platform changes, security patches, and upstream-service changes.
* **Deprecation notice.** If retiring a plugin, give users time to migrate and suggest alternatives where possible.
## Maintenance and support
You own technical support for your plugin. Provide **at least one** support channel (GitHub repository or email) and keep it active.
If a plugin is left unmaintained and the owner doesn't respond after a reasonable notification, Dify may tag it as `Maintenance Lacking` or `Potential Risk`, restrict new installs, and eventually unpublish it.
## Privacy and data
You **must** declare whether your plugin collects personal data and, if so, what types. The full guidelines are in [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines).
Your privacy policy must state:
* What data is collected
* How it is used
* What is shared with third parties (with links to their privacy policies)
Plugins that handle sensitive data (health, finance, children's information) get extra scrutiny. Collecting or transmitting user data without consent is grounds for removal.
## Review and discretion
* Dify may reject or remove plugins that don't meet these requirements or that abuse the review process.
* Reviews aim to land within a reasonable window; turnaround depends on submission volume and complexity.
* Reviewers communicate via the support channel you provide; keep it monitored.
## Related resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace)
* [Privacy Guidelines](/en/develop-plugin/publishing/standards/privacy-protection-guidelines)
* [Remote Debugging](/en/develop-plugin/features-and-specs/plugin-types/remote-debug-a-plugin)
# Privacy Guidelines
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/privacy-protection-guidelines
How to declare data collection and write the privacy policy required for every plugin submitted to the Dify Marketplace
Every plugin submitted to the Dify Marketplace must be transparent about how it handles user data. This page tells you what to declare and how to write the policy reviewers expect.
The whole submission boils down to one question: does your plugin collect or transmit any user personal data, either directly or through a third-party service it calls?
If yes, list the data types and link a privacy policy. If no, say so explicitly.
<Note>
"Personal data" means any information that identifies a specific individual on its own or when combined with other data: anything that could locate, contact, or target a unique person.
</Note>
## Identify the Data Your Plugin Handles
Walk through the three categories below. Anything you collect, store, log, or send to a third party must be declared.
### Direct Identifiers
* Full name, first name, last name
* Email address
* Phone number
* Home address or other physical address
* Government IDs (passport, driver's license, Social Security number, etc.)
### Indirect Identifiers
* Device identifiers (IMEI, MAC address, device ID)
* IP address
* Location data (GPS coordinates, city, region)
* Online identifiers (cookies, advertising IDs)
* Usernames, profile pictures
* Biometric data (fingerprints, facial recognition)
* Browsing history, purchase history
* Health or financial information
### Combinable Data
Data that becomes identifying when joined with other data:
* Age, gender
* Occupation
* Interests
### Third-Party Services Count Too
Your plugin is responsible for what the services it calls collect. If your plugin uses Slack, you must reference [Slack's privacy policy](https://slack.com/trust/privacy/privacy-policy) and disclose what Slack receives.
Before submitting, read the privacy policy of every third-party API the plugin touches and make sure your declaration covers it.
## Write the Privacy Policy
Your policy, either a `PRIVACY.md` in the plugin repository or a hosted URL, must cover:
* **What** is collected (from the categories above).
* **How** it is used.
* **Where** it goes, including any third parties and links to their policies.
If you're unsure where to start, look at the privacy policy of any plugin published by the Dify team for a working template.
## Declare It in the Manifest
The privacy URL goes in the plugin manifest. See [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications) for the exact field.
## Common Questions
<AccordionGroup>
<Accordion title="What counts as 'collect and use' personal data?">
Any of: collecting, transmitting, storing, logging, sharing, or analyzing user data. Concrete examples:
* Forms that gather personally identifiable information
* Login or third-party-auth flows
* Capturing user input that may contain PII
* Analytics that track user behavior or usage patterns
* Storing messages, chat logs, or email addresses
* Accessing connected social-media profiles
* Collecting health or fitness data
* Storing search queries or browsing behavior
* Processing financial information (bank details, credit scores, transactions)
</Accordion>
<Accordion title="What if my plugin collects nothing?">
Say so explicitly in the privacy policy. Reviewers still expect a `PRIVACY.md` file or hosted URL; it just needs to state that no user data is collected, stored, or transmitted, including by any third-party services the plugin calls.
</Accordion>
<Accordion title="My plugin handles sensitive data: what changes?">
Plugins that touch health, finance, biometrics, or children's data get extra review. Be explicit about each data type, the legal basis for collecting it, retention period, and how users can request deletion.
</Accordion>
</AccordionGroup>
## Related Resources
* [Publishing Overview](/en/develop-plugin/publishing/marketplace-listing/release-overview)
* [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct)
* [Publish to Dify Marketplace](/en/develop-plugin/publishing/marketplace-listing/release-to-dify-marketplace)
* [General Specifications](/en/develop-plugin/features-and-specs/plugin-types/general-specifications)
# Sign Plugins for Third-Party Signature Verification
Source: https://docs.dify.ai/en/develop-plugin/publishing/standards/third-party-signature-verification
Enable signed `.difypkg` installation in Dify Community Edition without disabling signature verification entirely (generate keys, sign packages, distribute the public key)
<Warning>
Third-party signature verification is a **Dify Community Edition** feature. Dify Cloud manages signatures centrally and does not expose these controls.
</Warning>
Self-hosted Dify enforces signature verification by default. Third-party signature verification lets administrators safely install plugins that are not on the Marketplace without disabling verification entirely.
Two scenarios:
<CardGroup>
<Card title="Admin signs an approved plugin" icon="user-shield">
The admin reviews a `.difypkg` from a trusted developer and signs it with their own key before installing.
</Card>
<Card title="Developer ships a signed plugin" icon="key">
The developer signs the `.difypkg` and publishes the matching public key. Admins who trust the developer add that public key to the verification list.
</Card>
</CardGroup>
The mechanics are the same in both cases: generate a key pair, sign with the private key, verify with the public key.
## Generate a Key Pair
```bash theme={null}
dify signature generate -f your_key_pair
```
Two files appear in the current directory:
| File | Use |
| :-------------------------- | :--------------------------------- |
| `your_key_pair.private.pem` | Sign plugins (keep secret) |
| `your_key_pair.public.pem` | Verify signatures (share publicly) |
<Warning>
Guard the private key. Anyone who has it can sign plugins that pass verification on installations trusting your public key.
</Warning>
## Sign and Verify a Plugin
<Steps>
<Step title="Sign the package">
```bash theme={null}
dify signature sign your_plugin_project.difypkg -p your_key_pair.private.pem
```
Produces `your_plugin_project.signed.difypkg` in the same directory.
</Step>
<Step title="Verify the signed package">
```bash theme={null}
dify signature verify your_plugin_project.signed.difypkg -p your_key_pair.public.pem
```
Confirms the signature matches before you distribute or install.
</Step>
</Steps>
<Info>
If you omit `-p`, `dify signature verify` checks against the Dify Marketplace public key. Any plugin not signed by Dify will fail verification in that mode.
</Info>
## Enable Verification on the Daemon
Admins install signed plugins by giving the plugin daemon a list of trusted public keys.
<Steps>
<Step title="Place the public key">
Put the `.public.pem` file somewhere the daemon container can reach it. For Docker Compose installs:
```bash theme={null}
mkdir -p docker/volumes/plugin_daemon/public_keys
cp your_key_pair.public.pem docker/volumes/plugin_daemon/public_keys/
```
</Step>
<Step title="Configure the daemon environment">
Set these variables on the `plugin_daemon` service:
| Variable | Value |
| :----------------------------------------------- | :-------------------------------------------------------- |
| `FORCE_VERIFYING_SIGNATURE` | `true` |
| `THIRD_PARTY_SIGNATURE_VERIFICATION_ENABLED` | `true` |
| `THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS` | Comma-separated paths to public keys inside the container |
A `docker-compose.override.yaml` snippet:
```yaml theme={null}
services:
plugin_daemon:
environment:
FORCE_VERIFYING_SIGNATURE: true
THIRD_PARTY_SIGNATURE_VERIFICATION_ENABLED: true
THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS: /app/storage/public_keys/your_key_pair.public.pem
```
<Note>
`docker/volumes/plugin_daemon` mounts to `/app/storage` inside the container, so the path in `THIRD_PARTY_SIGNATURE_VERIFICATION_PUBLIC_KEYS` must use the in-container path.
</Note>
</Step>
<Step title="Restart Dify">
```bash theme={null}
cd docker
docker compose down
docker compose up -d
```
Verified installs are now enforced: signed `.difypkg` files matching the configured public keys install cleanly; unsigned or mismatched ones are rejected.
</Step>
</Steps>
## Related Resources
* [Package as Local File and Share](/en/develop-plugin/publishing/marketplace-listing/release-by-file)
* [Publish to Individual GitHub Repository](/en/develop-plugin/publishing/marketplace-listing/release-to-individual-github-repo)
* [Plugin Development Guidelines](/en/develop-plugin/publishing/standards/contributor-covenant-code-of-conduct)
* [Publishing FAQ](/en/develop-plugin/publishing/faq/faq)